 Login
New tool identifies the sources of fake videos
11 August 2026 at 07:00
Artificial intelligence can generate videos so realistic that distinguishing them from authentic footage is becoming increasingly difficult. But



A new study suggests that deep brain stimulation may do more than control movement disorders: it could also help repair social behavior disrupted by pain experienced early in life. In research published in Translational Psychiatry, Wan, Du, Yang and colleagues report that stimulating the brain’s anterior cingulate cortex alleviated social deficits associated with early-life pain. The proposed mechanism is a restoration of the balance between excitatory and inhibitory neural signals, a fundamental process that determines how brain circuits respond, adapt and communicate.
Early-life pain has effects that can extend far beyond the moment of injury or medical treatment. During development, the nervous system is rapidly building connections, refining sensory pathways and establishing the networks that support emotion and social behavior. Excessive or poorly regulated pain signals during this period may alter that process. Instead of remaining confined to pain-processing circuits, these changes can influence stress responses, emotional regulation and the ability to interact with other individuals later in life.
The anterior cingulate cortex, or ACC, is particularly important in this story. Located in the frontal region of the brain, it helps integrate emotional information with attention, motivation and decision-making. It is also involved in processing the unpleasantness of pain and in evaluating social experiences. Because the ACC sits at the intersection of pain, emotion and social behavior, disturbances in its activity could provide a neural explanation for why early-life pain is linked to later difficulties with social interaction.
At the cellular level, the brain depends on a delicate equilibrium between excitation and inhibition. Excitatory neurons generally increase the likelihood that neighboring cells will fire, while inhibitory neurons suppress or constrain that activity. This excitatory/inhibitory, or E/I, balance allows neural circuits to remain flexible without becoming either silent or excessively active. If excitation dominates, networks may become unstable and hypersensitive; if inhibition dominates, communication and behavioral responses may be weakened. The study connects social deficits after early-life pain with disruption of this balance in the ACC.
Deep brain stimulation offers a way to influence such malfunctioning circuits directly. The technique uses electrical pulses delivered through precisely positioned electrodes to modify activity in targeted brain regions. Although DBS is best known clinically for treating Parkinson’s disease, essential tremor and several other neurological conditions, researchers are increasingly investigating whether it can reshape circuits involved in mood, motivation and social behavior. The new findings place the ACC among the brain regions that may be responsive to this approach.
According to the study, stimulation of the ACC improved social abnormalities linked to early-life pain while also normalizing indicators of excitatory and inhibitory signaling. This is important because it suggests that the behavioral improvement was not simply a generalized effect of activating the brain. Instead, the intervention may have acted on a specific circuit-level disturbance. By bringing opposing neural forces back toward equilibrium, DBS could make the ACC more capable of processing social information and generating appropriate responses.
The result also highlights a shift in how scientists understand the consequences of pain during development. Pain is often treated as a temporary sensory event, but developing neural systems can interpret repeated or intense pain as an organizing signal. That signal may alter synaptic strength, neuronal excitability and communication between brain regions. Over time, these changes could become embedded in circuits that regulate social engagement. The study’s emphasis on E/I balance suggests that developmental pain may produce lasting behavioral effects through measurable changes in network physiology rather than through an unexplained psychological process.
The findings are likely to attract attention because social deficits are difficult to treat and can appear across many neurological and psychiatric conditions. However, DBS is an invasive therapy involving neurosurgical implantation, and the study does not mean that the treatment is ready for routine use in people affected by early-life pain. Translating a circuit-level discovery into a safe human therapy requires extensive work, including confirmation in independent models, determination of the most effective stimulation parameters and careful assessment of possible side effects. The ACC is involved in many functions, so altering its activity could influence emotion, attention or pain perception in unwanted ways.
Even with those limitations, the research offers a potentially powerful framework for future therapies. If social difficulties can be linked to a specific imbalance between excitation and inhibition, treatments might eventually be designed to correct that imbalance with greater precision. DBS is only one possibility. Noninvasive stimulation, pharmacological treatments that selectively influence inhibitory or excitatory signaling, and therapies combining behavioral training with neuromodulation could also emerge from the same biological insight.
The study’s central message is that the developing brain may retain a capacity for repair, even after early adverse experiences have changed its circuitry. By targeting the ACC and restoring the neural balance that supports its function, deep brain stimulation improved social behavior in the reported research. The work does not erase the complexity of developmental pain, but it identifies a concrete biological pathway connecting early injury, altered brain networks and later social difficulties. That connection could help move the field closer to treatments that address not only pain itself, but also the long-term social consequences it can leave behind.
Subject of Research: Deep brain stimulation, early-life pain, social deficits, and excitatory/inhibitory balance in the anterior cingulate cortex
Article Title: Deep brain stimulation ameliorates social deficits from early-life pain by restoring excitatory/inhibitory balance in the anterior cingulate cortex
Article References: Wan, X., Du, T., Yang, D. et al. Deep brain stimulation ameliorates social deficits from early-life pain by restoring excitatory/inhibitory balance in the anterior cingulate cortex. Transl Psychiatry (2026). https://doi.org/10.1038/s41398-026-04311-z
Image Credits: AI Generated
DOI: https://doi.org/10.1038/s41398-026-04311-z
Keywords: deep brain stimulation, early-life pain, social deficits, anterior cingulate cortex, excitatory/inhibitory balance, neuroscience, brain stimulation, developmental pain, social behavior
Apple Intelligence on-device processing remains Apple’s most convincing argument in artificial intelligence. Rivals may lead in public model rankings, chatbot adoption and the speed of releasing experimental features, but Apple is building AI inside devices people already use for their most personal work.
That distinction changes the definition of winning.
Apple does not need every iPhone owner to open a separate chatbot app. It can place intelligence inside Messages, Mail, Photos, Notes, Shortcuts, Siri and third-party apps. Local models can operate on private information without automatically transferring that information to an external server.
The strategy appeared slow while the AI market measured progress through chatbot launches and model size. It looks more competitive as the industry confronts cloud costs, privacy concerns, unreliable connectivity and the difficulty of turning general-purpose AI into useful daily actions.
In his video “Apple Lost the AI Race,” Marques Brownlee captures the contradiction in one concise line:
“Apple lost the AI race. Actually, Apple won the AI race.”
The apparent reversal describes Apple’s current position well. Apple may have lost the first race for public perception. It is increasingly prepared for the longer contest over where AI runs, how it reaches users and who controls the personal data required to make it useful.
Most popular generative AI products began as cloud services. A user sends a request to a remote model, the provider processes it in a data center and the answer returns through an app or browser.
That structure supports enormous models but creates dependence on internet access, server capacity and continuing infrastructure expense. It also means personal prompts leave the device, even when the provider uses strong security and privacy policies.
Apple Intelligence on-device begins from the opposite direction. The iPhone, iPad or Mac first attempts to handle the request locally using Apple Foundation Models optimized for Apple silicon.
That local model does not need to know everything available on the internet. It needs to understand the user’s request, work with relevant personal context and complete common tasks efficiently.
The difference is similar to owning a capable computer rather than renting every calculation from a distant server. Cloud systems remain useful for difficult workloads, but they no longer need to participate in every interaction.
For Apple, local processing is also a product advantage. The company controls the chip, operating system, model architecture, memory system and apps. Each layer can be designed around the others rather than assembled from unrelated services.
Technology companies frequently describe privacy as a policy. Apple is trying to make it part of the AI architecture.
When a request runs entirely on an iPhone, the associated data does not need to leave the device. A model can work with messages, appointments, photos or app content without uploading that personal context to a conventional cloud account.
That structure is especially relevant to Siri AI. A truly personal assistant needs access to information that users may never place willingly inside an ordinary chatbot: private conversations, travel plans, health-related details, work documents and relationships between people.
An assistant becomes more useful as it gains context. It also becomes more invasive when the same context is stored, analyzed or used for model training outside the device.
Apple Intelligence on-device allows Apple to expand personal context while maintaining a stronger boundary around it. The assistant can understand information locally, perform an action and discard temporary processing data without building a permanent advertising or training profile.
This is difficult for competitors whose businesses depend on cloud services, large-scale data collection or engagement inside separate AI products. Apple’s hardware business gives it different incentives.
Not every AI task can fit within the power and memory limits of an iPhone. Apple uses Private Cloud Compute when a request requires a larger model.
Private Cloud Compute is designed to extend the privacy architecture of Apple devices into the cloud. User information is processed only for the request, is not stored and is not made available to Apple for unrelated purposes.
Independent researchers can inspect software images used by the system, creating an unusual level of outside visibility into the cloud environment. Apple has also expanded the architecture while maintaining control over the software and privacy protections used for processing.
This creates a layered system rather than a simple choice between local and cloud AI.
Apple Intelligence first determines whether the device can handle the request. More complex work can move to Private Cloud Compute. External models may be offered separately when the user chooses to involve them.
The user does not need to understand the technical path behind every answer. The system chooses the smallest and most private environment capable of completing the task.
Apple’s control of its processors has become one of its largest advantages in the AI era.
The Neural Engine first appeared years before generative AI became a consumer obsession. It supported Face ID, photography, speech recognition and other machine-learning tasks. Apple continued expanding that hardware across the iPhone, iPad and Mac.
Those investments now provide a large installed base of devices designed to run machine-learning workloads locally. Recent Apple chips combine CPU, GPU, Neural Engine and unified memory in one architecture that can move information efficiently between different types of processing.
The same design helps foundation models run without requiring the power consumption or separate memory systems associated with conventional data-center hardware.
Apple also controls the operating systems that schedule those workloads. A model can be optimized for the exact processors, memory limits and energy behavior of supported devices.
Competitors can build excellent models, but they often need to support hardware from several manufacturers with inconsistent capabilities. Apple can decide that an AI feature requires a specific generation of silicon and design the complete experience around it.
The Foundation Models framework extends Apple Intelligence on-device beyond Apple’s own apps. Developers can use the system model through native Swift tools rather than shipping a separate large model or paying for every cloud request.
An app can generate structured content, interpret natural language or use tool calling while keeping supported processing on the device. Apple handles model delivery and system integration.
This can reduce operating costs for developers. A cloud-based AI feature creates an ongoing expense each time a user submits a request. Local inference uses hardware the customer already owns.
It can also improve reliability. Features may remain available without an internet connection and respond without waiting for a remote service.
The framework encourages a quieter form of AI adoption. Apps do not need to add a prominent chatbot tab or redesign themselves around a conversational interface. Intelligence can appear inside existing workflows as a useful capability.
That is where Apple’s strategy may reach scale. Millions of apps can incorporate small AI functions that users experience as normal software behavior rather than as visits to an AI destination.
The AI race is often discussed as a contest between models. Consumer adoption also depends on distribution.
Apple can deliver new intelligence features through operating-system updates across the iPhone, iPad, Mac and Vision Pro. Users do not need to create another account, choose a provider or transfer their personal information into a new service.
Siri already occupies the system interface. Apple Intelligence can work across first-party apps. Developers can connect their own features through Apple frameworks.
The scale is difficult to reproduce. A model provider may have stronger benchmark scores but still need users to download an app and consciously open it. Apple can introduce AI during actions people already perform: replying to a message, locating a photo, organizing a note or completing a shortcut.
This does not guarantee success. Apple must make Siri AI reliable, keep feature availability consistent and prove that local models can deliver enough capability to satisfy users accustomed to powerful cloud assistants.
The distribution advantage only becomes meaningful when the experience works.
Apple has made mistakes during its AI transition. Siri improvements arrived later than promised, regional regulations delayed features and competitors established powerful consumer brands before Apple completed its new system.
Those setbacks explain why the claim that Apple lost the AI race became persuasive.
They do not settle the outcome.
The first stage rewarded companies that released chatbots quickly and demonstrated increasingly large models. The next stage may reward systems that can integrate AI into ordinary life without demanding constant cloud access, high subscription costs or broad collection of personal information.
Apple Intelligence on-device is built for that stage. It uses hardware already in the user’s hand, protects more personal context locally and gives developers access to intelligence without requiring every interaction to become a server transaction.
Apple does not need to win every benchmark or release the most talkative assistant. It needs AI to become a reliable part of the devices people already trust.
Brownlee’s title works because both statements can be true. Apple lost the visible sprint that defined the early generative AI market. By concentrating on local processing, silicon, privacy and operating-system integration, it may already be positioning itself to win the race that follows.
The post Apple Intelligence On-Device Is Winning the AI Race appeared first on AppleMagazine.
Many observations of solar flares suffer from saturation and blooming, causing crucial information to be lost. Researchers recently validated a technique for retrieving information from saturated flare images, unlocking a treasure trove of powerful solar flares for examination.
Since 2010, the Atmospheric Imaging Assembly (AIA) on the Solar Dynamics Observatory (SDO) has been capturing nearly continuous extreme-ultraviolet images of the Sun’s disk, revealing our star’s dramatic high-energy behavior. Though SDO/AIA’s observations have transformed our understanding of the Sun’s activity, they have limitations: powerful solar flares can saturate the detector, spilling charge into nearby pixels.
This saturation and overflow compromises our ability to study the most energetic solar flares — but the “lost” information may actually be recoverable. When light from an intense flare enters SDO’s instruments, not all of it pools in the saturated region of the detector: some of the light is diffracted by the optics, and by mathematically inverting this pattern of diffracted light, researchers can attempt to extract the encoded information about the saturated region. Researchers have used this technique for more than a decade, but options for validating the results were limited until now.
Launched almost 10 years to the day after SDO, the Solar Orbiter spacecraft provides an excellent opportunity to test inversion techniques for recovering information from saturated solar images. Solar Orbiter’s Extreme Ultraviolet Imager snaps brief photos of the Sun at a rapid cadence, and its images remain unsaturated even when faced with energetic solar flares.
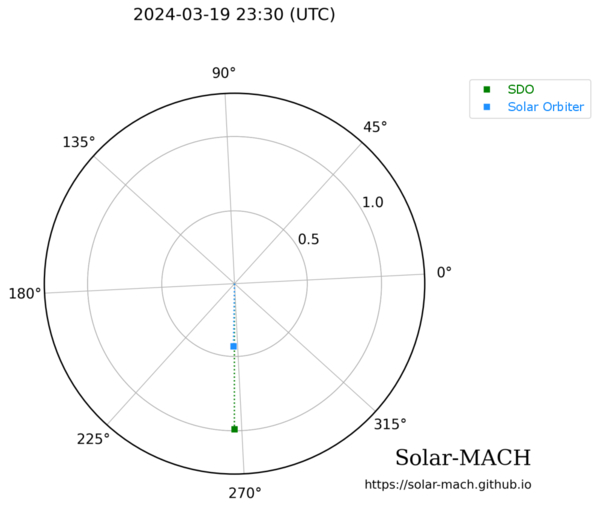
Positions of SDO (green) and Solar Orbiter (blue) during a solar flare on 19 March 2024. Click to enlarge. [Guastavino et al. 2026]
Guastavino’s team aligned and reprojected the data, accounting for the slightly different viewing angles of the two spacecraft, then applied an algorithm called Adaptive SE-DESAT to reconstruct the flux within the saturated portion of the SDO image. The team compared the desaturated SDO images to the unsaturated Solar Orbiter images over the course of the flare, finding the same flare morphology and similar time evolution between the two data sets.
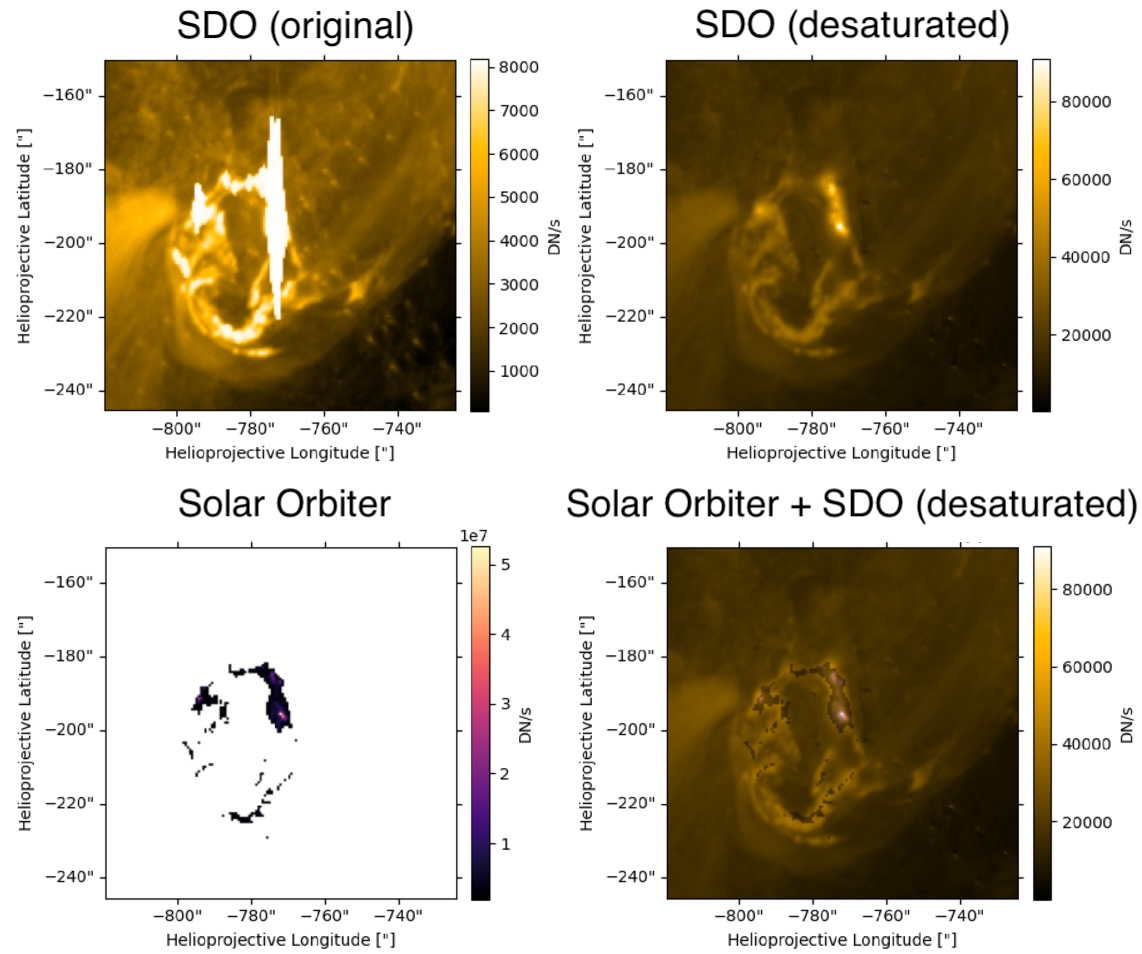
Example of unprocessed SDO data (top left), desaturated SDO data (top right), Solar Orbiter data (bottom left), and a combination of the two data sources (bottom right). Note that the Solar Orbiter observations have been clipped so that only the highest flare intensities were recorded. Click to enlarge. [Adapted from Guastavino et al. 2026]
Overall, these results demonstrate the effectiveness of the inversion technique, though Guastavino and coauthors noted that improvements could be made during the impulsive phase of the flare, when the emission is increasing. The team identified several reasons why the results may not match during this phase, including rapid evolution of the flare during individual exposures.
Despite these areas that require further attention, the validation of this technique unlocks 16 years of solar flare observations from SDO. This especially enhances our sample of powerful solar flares, increasing the available records of the most energetic solar flares by orders of magnitude.
“Validation of an Extreme-Ultraviolet Desaturation Technique for the Atmospheric Imaging Assembly on Board the Solar Dynamics Observatory Using Observations from the Extreme Ultraviolet Imager on Board Solar Orbiter,” Sabrina Guastavino et al 2026 ApJL 1005 L50. doi:10.3847/2041-8213/ae7d2e
The post When the Spacecraft Align: Rescuing Saturated Images of Solar Flares appeared first on AAS Nova.
Neuroscientists have long believed that language processing was only found in regions of the brain’s left hemisphere, including the well-known Broca’s area. However, new evidence suggests the brain’s language network is far more widespread than previously thought.
Researchers at the Massachusetts Institute of Technology (MIT) analyzed functional magnetic resonance imaging (fMRI) scans from 772 participants and identified 17 additional brain regions involved in language comprehension. These newly discovered areas are distributed across the brain, including the cerebellum, hippocampus, amygdala, and several regions of the cerebral cortex. In total, this accounts for five percent of the adult brain volume (roughly the size of a large strawberry).
“Even though there are all these distant components, it’s pretty restricted in terms of volume. You don’t need that much of the brain to do language,” says senior author Evelina Fedorenko, an MIT associate professor of brain and cognitive sciences and a member of MIT’s McGovern Institute for Brain Research, in a statement.
To find these hidden language-related regions in the brain, the researchers revisited years of brain imaging data collected since 2013. Additionally, participants completed a standard “language localizer” task, during which they read or listened to meaningful sentences and sequences of meaningless nonwords. By comparing brain activity between these two conditions, the research team identified regions that responded more strongly to language.
“When we initially started looking at language, in the first couple of papers, I tried to be comprehensive and include anything that seemed consistent across participants, and there was a huge amount of resistance,” said Fedorenko. “People would say things like, ‘Well, we know those are not language areas, so please focus on the language areas.’”
The team decided to adopt a more flexible statistical approach to detect weaker signals and identify previously overlooked language-sensitive regions beyond the classical language areas. They then compared these regions’ responses during a spatial working memory task to distinguish language-specific areas from those involved in what would be considered general cognitive functions.
Interestingly, five of the newly identified language regions are located in the cerebellum, a structure traditionally associated with movement and coordination. Some of these cerebellar regions were also active during non-language tasks, suggesting they may help integrate information across different brain systems rather than process language alone.
“It’s a very simple paradigm that lets you identify this core language system in individual brains,” says MIT postdoc Agata Wolna, the lead author of the paper.
Additional language-sensitive regions were identified in the hippocampus and amygdala, areas better known for their roles in memory and emotion. Their involvement suggests that understanding language may rely more on integrating memory, emotional context, and higher-order cognitive functions than previously understood in science.
“We always see this frontal temporal network, but there’s quite a lot of evidence that there are other regions that are also critical for language processing,” said Wolna. “By using a laxer threshold and zooming in on areas with weak MRI signal, we tried to maximize the chances of finding small and weakly responsive regions outside of this left frontal temporal system.”
The findings challenge long-held assumptions about the brain’s organization and can open new avenues for research into how language processing is understood in neuroscience.
The recent study was published in the Journal of Neuroscience.
Chrissy Newton is a PR professional and the founder of VOCAB Communications. She currently appears on The Discovery Channel and Max and hosts the Rebelliously Curious podcast, which can be found on YouTube and on all audio podcast streaming platforms. Follow her on X: @ChrissyNewton, Instagram: @BeingChrissyNewton, and chrissynewton.com. To contact Chrissy with a story, please email chrissy @ thedebrief.org.
Enzymes and other biomolecules are often anchored onto solid materials so they can be reused, purified more easily, and made more stable, a strategy biotechnology has relied on since industrial-scale immobilized enzymes first appeared in chemical manufacturing in the mid-twentieth century. Immobilized enzymes today drive processes from food and pharmaceutical production to biosensors and medical diagnostics. Fixing a biomolecule in place, however, is not as simple as gluing it down. The exact spot where it attaches, the direction it faces, and how much freedom it retains to move can all change how well it works. Testing every possible arrangement in the laboratory is slow and costly, which is why computer simulation has become such a valuable complement to experiments.
One of the main tools for this kind of study is molecular dynamics simulation, which calculates how atoms move over time by applying the basic laws of physics. Simulating every single atom of a protein, its surrounding water, and a supporting material gives rich detail, but is extremely demanding on computing power, especially when many attachment geometries need comparing. A widely used shortcut is coarse-grained modeling, in which small clusters of atoms are grouped into single, simplified particles. This keeps the essential physical behavior of the system while making the calculations far cheaper. The most established coarse-grained approach for biological molecules is the Martini force field, first developed in 2004 to describe fatty, membrane-forming molecules and later extended to proteins and, more recently, to a more accurate third generation of the model. Martini has since become a standard tool for simulating large biological assemblies that would otherwise be out of reach.
A team of researchers now introduces MartiniSurf 1, an open-source software package that automates the preparation of these coarse-grained simulations for biomolecules attached to surfaces. Building such a system by hand normally involves several separate programs and many manual steps, which makes it hard to reproduce results or compare different setups fairly. MartiniSurf instead combines the whole process into a single, streamlined workflow. Starting from the structure of a protein or a DNA strand, it converts the molecule into its coarse-grained form, builds a model of the supporting surface, positions the molecule in a chosen orientation, adds water and dissolved ions, and produces all the files needed to run the simulation with GROMACS, a molecular dynamics program that has been developed and refined for decades. Because every step is controlled by explicit settings rather than manual adjustments, two researchers using the same settings should obtain the same starting system, making comparisons across studies far more reliable.
A central feature of the software is its flexibility in representing how a biomolecule is attached. In one mode, selected regions of the molecule are held near the surface through simple restraining forces, without modeling the physical connector itself. In another mode, an explicit molecular linker is placed between the biomolecule and the surface, so that the linker’s own length and flexibility can influence the simulation. Because the properties of such linkers are known to affect how active and stable an attached enzyme remains, this second option offers a more realistic picture whenever the necessary coarse-grained description of the linker is available.
The supporting surfaces themselves can also be varied widely. The software can generate simple flat reference surfaces or draw on previously developed coarse-grained models of real materials such as graphene, graphite, carbon nanotubes, and agarose-like gels, the type of porous material commonly used to immobilize enzymes in the laboratory. Properties such as surface chemistry, electric charge, particle spacing, and added chemical groups can all be adjusted. Recent studies have shown that surfaces built without care can cause water molecules near the interface to line up in unrealistic, almost frozen patterns, an artifact rather than genuine physical behavior. The software includes options that let users introduce controlled irregularity into the surface to reduce this problem, while staying consistent with the wider Martini modeling framework.
To demonstrate how the approach works in practice, the study presents examples involving both proteins and DNA. For an enzyme attached to an agarose-like surface, the software reproduces several different attachment arrangements, including a complete system containing the enzyme together with its natural helper molecule and reaction substrate. These examples show how changing the attachment point or adding chemical groups to the surface can be explored systematically, without needing to reconstruct every model from scratch by hand.
The approach is also extended to DNA tethered to a graphene-like surface, comparing an electrically neutral surface with a positively charged one. The coarse-grained simulations reproduce the same general behavior previously reported in much more computationally demanding all-atom studies: the DNA strand remains mostly upright above the neutral surface but bends progressively toward the surface when it carries a positive charge, drawn in by electrostatic attraction. This comparison is not meant to reproduce exact experimental values, but rather to confirm that the automated setup captures the right physical trends, providing a check on the reliability of the workflow.
Every simulation generated by the software automatically records the settings, software versions, and modeling choices used to build it, so that another researcher can repeat or directly compare a given calculation later. Importantly, the software does not introduce new physical models or new force-field parameters of its own. Instead, it draws on already validated Martini tools and organizes them into a consistent, automated pipeline.
Overall, MartiniSurf addresses a practical bottleneck in computational chemistry rather than proposing a new simulation method. By automating the construction of surface-bound protein and DNA systems, it makes coarse-grained molecular dynamics studies faster to set up, easier to reproduce, and simpler to scale across many attachment geometries. This kind of tool should make it easier to systematically study how surface properties, attachment geometry, and molecular flexibility shape the behavior of immobilized biomolecules, supporting the design of better catalysts, biosensors, and other biotechnology applications.
Author: César Tomé López is a science writer and the editor of Mapping Ignorance
Disclaimer: Parts of this article may have been copied verbatim or almost verbatim from the referenced research paper/s.
The post Overcoming bottlenecks in bio-interface simulations: The MartiniSurf Approach appeared first on Mapping Ignorance.
