Un estudio identifica un aumento de la proteína meprin-beta en el cerebro y el líquido cefalorraquídeo de personas con alzhéimer.
Un equipo del laboratorio Mecanismos moleculares alterados en la enfermedad de Alzheimer y otras demencias, liderado por Javier S&aac ...
Unos científicos han constatado la elevación de 255 metros de la corteza de la vertiente atlántica de la cordillera vasco-cantábrica y la de 167 metros de la vertiente mediterránea, y han determinado sus causas.
El trabajo es obra de investigadores de los ...
Imaginemos una criatura de apenas 15 centímetros de largo, con un cuerpo alargado en forma de torpedo, ojos montados en los extremos de una barra rígida horizontal que atraviesa su cabeza, y una trompa larga y flexible que remata en una garra dentada. No es una descripción de un ...
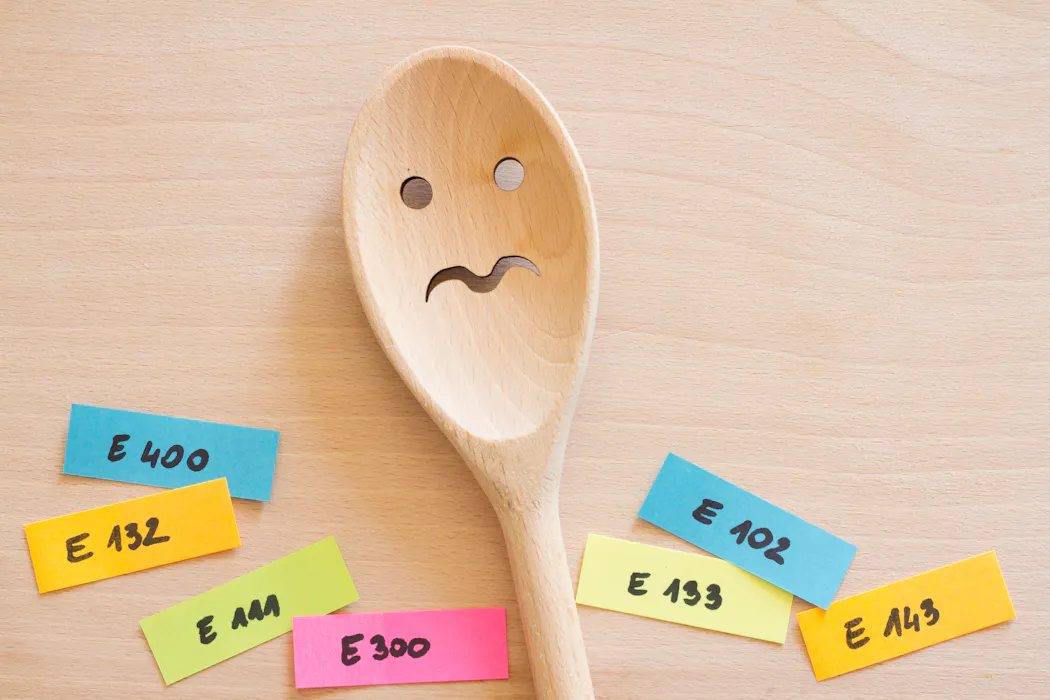
Battenberg cake is one of my favourite cakes. But when I tell people that one of the things I like most about this cake is its E-number, they tend to look at me strangely.
It contains the raising agent E541, acidic sodium aluminium phosphate, which is one of the most restricted food additives in the UK. This is due to health concerns about human exposure to aluminium.
According to the UK government regulations, E541 is permitted in almost nothing except “sponge cakes produced from contrasting coloured segments held together by jam or spreading jelly and encased by a flavoured sugar paste”.
The reason for this curious exception is that Battenberg manufacturers managed to persuade the authorities that the additive was essential for achieving the cake’s chequered pattern, and that aluminium exposure from such a niche product wasn’t a health risk.
This level of specificity in the regulations surprises most people, who assume that additives are loosely regulated, casually thrown into food by manufacturers cutting corners. It’s part of a massive counter-movement against additives, driven by fears over ultra-processed foods and a desire for “clean” labels. Though these concerns are understandable, my view of the scientific evidence is that the reality is a little different.
Additives, of course, are compounds used to enhance foods in different ways, but mainly they are about control. When you cook in your home kitchen, the results can be very variable – which is often part of the fun. No-one expects two homemade cakes to look or taste the same, while breads out of your kitchen oven can be very different if you make them from different batches of flour.
For commercial foods, it’s a different story: industrial production relies on predictability, while consumers expect consistency. Few of us would be happy if supermarket breads, biscuits or burgers varied from batch to batch. So commercial foods are usually standardised — and additives help to achieve that.
Welcome to our series exploring the cutting edge of food science. From the latest advances in meat alternatives to weird and wonderful new additives, science is transforming what we eat like never before. This series will bring you up to speed on all the latest and give you plenty of, er, food for thought.
Their number one role is preservation: extending shelf life, making it possible to produce foods further away, and often making them more affordable in the process.
Propionic acid (E280) stops bread from going stale and mouldy. Antioxidants like vitamin C (E300, aka ascorbic acid) and vitamin E (E306/tocopherol) prevent fats from oxidising and going rancid. Emulsifiers stabilise products such as mayonnaise which would otherwise quickly separate.
Creating a specific texture and flavour is also very important. Thickeners improve the creaminess of yoghurts and some cheeses. Emulsifiers also help to make ice-cream smooth and chocolate soft. Citric acid (E330) can help zing up a salad dressing, while also dialling down the earthiness in some plant-based milks.
Another use of additives is to overcome the problem of raw products of different quality. Wheat from a wet, cold year can behave very differently from the same variety in a dry, hot year. This can mean differences in protein content and gluten formation during baking, which can affect how much breads rise, for instance.
Ascorbic acid and synthetic fats (mono and diglycerides of fatty acids (E471) can compensate for this and ensure the quality of bread is consistent. Likewise, adding E500 (bicarbonate of soda) and E336 (cream of tartar) – in other words, baking powder – ensures cakes and muffins are light and fluffy.
In the same way, jam depends on the pectin content of fruits, which is affected by factors that can’t be controlled – extra sunlight during growing reduces it, for instance. So manufacturers add pectin (E440) during jam-making to ensure it gels properly.
Or take meat, whose water retention can be improved by adding phosphates like E451. This ensures that natural fluids don’t leak out in the supermarket chiller section (phosphates are also more dubiously used by some meat producers to enable them to add water to cheaper cuts so that they look more attractive to consumers). As for milk products, you can avoid the risk of separation by adding carrageenan (E407), a seaweed gum, which strengthens their protein network.
Indeed, whole product categories would barely exist without certain additives. Many low-fat spreads rely on gelling agents to mimic the texture of butter. Without sweeteners, there would be a much smaller selection of low calorie and low sugar foods.
Very little of this is about deceiving consumers — and it should not be. The need to ensure the consistent quality of produce using additives is probably much greater than most people realise.
The remarkably long history of additives
While we’ve only referred to them as additives for about a century, these compounds have been around a great deal longer. Findings from the Qesem Cave in Israel suggest ash was being used to preserve foods as much as 200,000 years ago.
In times when the food supply has been unreliable, meaning most of our history, preserving food was essential to human survival. Entire empires have been built on the trade of another vital preservative, salt, to be used either as brine for pickling or as crystals/powder for drying.
Nitrates (E251) and nitrites (E250) have also been used as additives for many hundreds of years. In Roman times they were used as a constituent of rock salt, both for preserving meat and to keep it nice and pink. With a little more chemical know-how, these compounds are still used today.
Another preservative in use since Roman times is sulphur dioxide (E220), both for wine and foods such as fruits. The Romans obtained it by mining brimstone and heating it into a liquid that could be made into sulphur candles. These could then be burned to produce sulphur dioxide gas in the presence of whatever was being preserved.
The Romans also used additives to make dull, bland food more palatable. Garum — the ubiquitous Roman fish sauce – provided salty and umami flavours by fermenting fish guts. Lead acetates, obtained from boiling grape juice in leaden pots and kettles, were used as a non-calorific sweetener – in wine, for example. It wasn’t until many centuries later that it was proven that this additive was poisonous.
Towards the end of the 18th century, we developed a better understanding of how additives work thanks to advances in food chemistry. It also became possible to extract these compounds in a laboratory, such as lecithin from egg yolk to be used as an emulsifier, pectin from apples, and agar, another gelling agent, from seaweed.
A few decades later, chemists started synthesising additives, which often proved cheaper and easier than obtaining them naturally. Salt of hartshorn – also known as Baker’s ammonia (E503) – could be made by heating ammonium sulphate obtained from soot in combination with limestone (calcium carbonate).
Previously extracted from deer antlers, this was used as a raising agent and preservative for things like digestive biscuits and lebkuchen, a German gingerbread. Much like making aspirin in a laboratory instead of extracting it from willow bark, or digoxin instead of foxglove tea (for heart problems), synthetic and purified additives allowed much better control over their use.
Scientists’ better understanding of chemical and physical mechanisms in the 19th century also allowed new additives to be developed to suit the food industry and consumer demand. These included dyes like aniline purple and martius yellow, both obtained from coal tar, and new flavours like amyl acetate, a byproduct from fermenting alcohol, which gives a sense of pear or banana. These were unveiled at the Great Exhibition in London in 1851 for the first time.
Artificial pear and banana sweets were unveiled at London’s Great Exhibition in 1851.Wikimedia
Other additives allowed the use of cheaper ingredients or extended shelf lives. Borax, also known as sodium borate, was harvested from lake beds starting in the late 19th century and added to sub-standard milk and butter to mask sour tastes and kill bacteria.
Additives also began to allow the development of new products that could be used as cheap alternatives, such as margarine. Though originally made from beef fat and skimmed milk in the 1870s, it became vegetarian around the turn of the century after chemists worked out how to make food oils solidify by forcing hydrogen into them at high temperatures (known as hydrogenation).
Margarine solved one problem – the affordability of butter – but food scientists realised a few years later that it created another: it lacks the vitamins naturally found in dairy. So from the 1920s onwards, manufacturers also started fortifying it with vitamins, as well as making it more attractive by incorporating emulsifiers, flavours and colours.
Elsewhere, the use of additives has put consumers at risk, often due to unscrupulous characters. They made bread whiter with chalk, for instance, at a time when many people were already suffering from malnutrition. They sweetened wine with lead salt long after it was known to be toxic. There have even been cases in more recent times of wine being sweetened with anti-freeze.
One other notorious case was the Bradford sweets poisoning of 1858. At the time, sugar was very expensive due to high taxes, so confectionery manufacturers would mix it with plaster of Paris to keep costs down. In the Bradford case, an apprentice muddled up plaster of Paris and arsenic, which led to around 20 people being killed from eating toxic peppermint lozenges.
The modern era
The 20th century brought massive changes to the food system: a rapidly growing population needed to be fed, scientific advances provided a better understanding of food processing, and the rise of synthetic chemistry made hundreds of new compounds available. The upheaval of two world wars accelerated these processes as new products such as canned meats, sliced cheeses and even packets of crisps were all made possible by additives.
The same goes for British sliced bread. The Chorleywood process, named after the village near London where it was invented in 1961, revolutionised production of the daily loaf. By adding lard, ascorbic acid and extra yeast to dough, then mixing it at high speeds, there was no more need to wait hours for the mixture to rise.
This allowed the mass production of bread, which was extremely helpful in meeting ever growing demand. It also allowed the use of British-grown flour, which often has a lower protein content, meaning its dough traditionally didn’t rise as well. In subsequent years, other additives have also become common ingredients in this mass-produced bread, including E471 (mono- and diglycerides of fatty acids) as emulsifiers to improve dough handling and E282 (calcium propionate) as a preservative to enhance shelf life.
The post-war decades saw dramatic societal changes: rising incomes, longer working hours, and more women entering the workforce. These all created demand for foods that saved time and preparation. Ready meals, packet soups, instant desserts and salad dressings all reached supermarket shelves for the first time. This wouldn’t have been possible without emulsifiers, stabilisers, gelling agents and preservatives – even if such details were quietly hidden on labels that often sought to make these products look as traditional as possible.
At the same time, synthetic coal-tar dyes made sweets vivid and soft drinks luminous. Artificial flavours like strawberry, banana, pineapple, sometimes not tasting remotely natural, could be added to almost anything at negligible cost. And artificial sweeteners made it possible to indulge without sin … or at least calories.
For several decades between the 1950s and 1970s, all these new products were seen as unambiguous progress. At a time when science was enabling everything from tower blocks to rocket ships to the pill, it made perfect sense that it was doing the same for our eating habits.
The backlash
The enthusiasm for this modern food was short lived. In 1973, Californian allergist Benjamin Feingold suggested that additives – in particular artificial dyes and flavourings – were responsible for hyperactivity in children. His book, Why Your Child is Hyperactive, became a bestseller. The so-called Feingold diet became popular among parents, eliminating artificial colours, flavours and other additives.
In Britain, Maurice Hanssen’s E for Additives (1984) was another major blow to this industry when it became a bestseller in the 1980s. It detailed the purpose and health risks of all the E-numbers, which were devised as a European mark of safety, so that only additives considered safe were allocated one. Now they became culturally inverted into a warning sign.
The case against additives wasn’t quite what many began to believe, however. There was little proof that Feingold’s diet could reduce hyperactivity, even after extensive research. This may have been because of the strong genetic component in the condition.
In 2007 the UK’s Food Standards Agency commissioned a research study to investigate the effect of some artificial food colourings on hyperactivity. Children in the study showed some increase in hyperactivity from consuming the compounds in question – tartrazine (E102), sunset yellow (E110), quinoline yellow (E104), carmoisine (E122), ponceau 4R (E124) and allura red (E129).
Yet the European Food Safety Authority decided there was sufficient uncertainty that there was no need to change the permitted use of these additives. Instead European lawmakers mandated that foods containing them carry the warning “may have an adverse effect on activity and attention in children”, which applies today in the UK and across the continent.
In parallel, the additives industry has tried to adapt to consumers’ concerns about the things that go into foods. For the past several decades, we have seen a plethora of products which claim to be free from “artificial colours and flavours” – and sometimes even “free from chemicals” (although that is impossible).
Much of this “clean-label” movement has been about replacing E-numbers with ingredients that sound more natural, though in many cases the manufacturers just replace additives with plant extracts that contain the same compounds.
Acerola extract contains vitamin C, for instance, but sounds better than E300. Seaweed extract sounds much more natural than E407 (carrageenan) and turmeric extract better than E100 (curcumin). Similarly, vegetable salts or celery extract in processed meat replace nitrite (E250). The nitrite in these compounds will still act — turning the meat more pink and killing bacteria – but the consumer is not always aware that this additive is even present.
In the EU and UK, whether something counts as an additive legally depends on what it does, not where it comes from. However, this often depends on interpretation. Acerola cherry extract, for example, is almost always added for its vitamin C content, which acts as an antioxidant. However, it usually appears on the label as a fruit ingredient rather than as ascorbic acid (E300). Clean labelling probably employs as many lawyers as food scientists.
One example of how this plays out is Naked Bacon, made by Northern Irish company Finnebrogue. The goal was to remove nitrite from bacon to make it healthier – not just create a nicer label. As an alternative to nitrite and nitrate, they used a proprietary fruit and spice extract called Natpre made by Spanish manufacturer Prosur. This was initially marketed as free from E-numbers. The Food Standards Agency, however, took the view that the ascorbic acid (vitamin C) in the mix was an additive that had to be declared. After a lengthy dispute the company agreed in 2018 to list “antioxidant: ascorbic acid” on the label. The remainder of the extract is still declared as “natural flavouring”.
As well as these kinds of uncertainties, there’s also a potential problem with plant extracts as alternatives to existing additives: a rigorously tested compound is being replaced by something less understood, and still potentially harmful, in the name of a cleaner label. They can contain natural toxins, for instance, while the levels of the additive can vary by batch.
The case for additives
Another part of the stigma against additives is that they enable industrially produced food, which has come to be seen by many as inherently unhealthy. This was abetted by the likes of US journalist Michael Pollan’s bestseller, In Defense of Food (2008), the documentary Food Inc (2008) and TV chefs like Jamie Oliver.
This mindset probably partly derives from all those unsavoury practices I mentioned in the early food industry, where chemicals were used to disguise spoilage, extend products or improve appearance.
Wrapped up in this is a romanticism of natural food, viewing chemical intervention with suspicion. Many people still see natural as better and healthier, though there is actually little evidence for this claim.
Whether industrially produced food is unhealthy depends very much on what is in the food. Foods high in fat, salt and sugar increase the risk of chronic disease, whether it is a home-baked cake or an industrially manufactured cookie. Sure enough, a recent study found no difference in health outcomes between processed and non-processed foods that meet current dietary guidelines.
With today’s focus on ultra-processed foods, it is true that certain industrial additives like emulsifiers and artificial colours and flavours are sometimes used as evidence that a product falls into this category. But the health impact of these foods is more tied to issues like high calorie-density and low fibre content than the toxicity of individual ingredients, so the additives are rarely the primary culprits.
It’s also worth emphasising that without additives, natural food can spoil much more quickly. Almost 20% of foods are lost to spoilage in retail, and more than 30 million years of healthy lives are lost every year to food-borne diseases. Without additives, this situation would be much worse. And at a time when the cost of living is such a burden for so many people, it’s hard to deny that additives make food much more affordable.
Regulatory issues
Unlike with pharmaceuticals, there is no formal system for checking whether additives are causing harm after they start being used in food manufacturing. Regulators rely on the scientific literature to keep them up to date on any risks, as well as commissioning research studies if there are reasons for concern.
The situation isn’t helped by the different classification frameworks that exist. A recent example is aspartame. In 2023 the International Agency for Research on Cancer (IARC) classified this sweetener as possibly carcinogenic to humans, causing a huge amount of concern.
Yet at the same time Jecfa, the Joint FAO/WHO Expert Committee on Food Additives, whose pronouncements influence food regulation around the world, reaffirmed aspartame’s accepted daily intake of 40mg per kg of body weight. It concluded that there was no convincing evidence of adverse effects at current consumption levels.
This sounds contradictory, but actually the IARC and Jecfa ask very different questions. The IARC asks about hazard: could this substance possibly cause cancer? Jecfa asks about risk: could this substance possibly cause cancer at the amount people eat? Both can be right. A substance can probably cause cancer, only not at the amounts people generally consume.
The IARC, for instance, classes the Sun as a group 1 carcinogen, meaning it’s known to cause cancer in humans. Yet we still recommend sun exposure so that our bodies produce vitamin D. We manage the risk by reducing exposure — either by looking for shade or using sunscreen. As for aspartame, it’s worth noting that the IARC classification put it in the same category as aloe vera and pickled vegetables.
Emulsifiers are another additive currently receiving a lot of attention. Some studies have shown that they can alter the human gut microbiome and disrupt the intestinal barrier. Whether this causes harm is obviously an important question, but there’s much that isn’t yet clear: we don’t know if these effects are harmful, or whether they’re transient or lasting.
The trouble is that changes in the gut microbiome are difficult to interpret. It can change in response to all sorts of alterations to someone’s diet, and while there is some good data on links between the microbiome and health, we do not yet have a clear framework for interpreting what specific changes mean.
To be clear, change in itself isn’t a negative: fermented foods and prebiotics are recommended especially for their ability to change the gut microbiome. Regulators in the UK and elsewhere are actively investigating how to incorporate microbiome data into safety assessments, but the science is not yet at a stage where firm conclusions can be drawn.
It might still seem appealing to ban emulsifiers in the meantime as a precaution, but that might have consequences that eclipse the intended benefits. For example they could be replaced by natural lecithins from sources like egg yolks and sunflower seeds, but these are much more expensive. The consumer would bear the brunt – and there is no evidence that these alternatives are better.
There is also a question of consumer choice. Provided a food is safe to consume within established guidelines, there is a strong argument that individuals should be free to make their own choices, rather than having them imposed on the basis of uncertain evidence.
Alcohol, for instance, is another product categorised by the IARC as a group 1 carcinogen, and there is overwhelming evidence that drinking it can harm your health in numerous other ways. Yet while there are regular calls for tighter regulation of additives with a much better risk profile, calls for a ban on champagne or claret are much rarer.
This isn’t to say that the need for proportionality should always justify inaction. Regulatory agencies should and do act to protect consumers when the evidence warrants it. In 2007 data emerged that red 2G (E128), used as a colouring in sausages and burgers, was potentially carcinogenic and toxic to people’s genes. This was rightly considered serious enough that it was swiftly withdrawn in Europe and elsewhere.
The future of additives
One current area of rapid development has been plant-based foods, where achieving the texture, appearance and mouthfeel of meat and dairy requires a specific set of additives. For example, to produce plant-free dairy products that melt and taste like the real thing, food scientists add synthetic wheys and caseins made using a technique called precision fermentation. This involves inserting synthetic copies of dairy DNA into yeasts or fungi.
The first large-scale application of precision fermentation was actually in medicine in the early 1980s, producing insulin using genetically modified E. coli. The food industry got onboard in the early 1990s, with chymosin, an enzyme essential for cheesemaking to separate the curds and whey. It became the first major precision-fermentation product, and is now used in many milk-based cheeses instead of traditional rennet from calves’ stomachs, producing more consistent results and also vegetarian products into the bargain.
In the last couple of years, companies are now offering the entire suite of dairy proteins including whey, casein and lactoglobulins made in a fermentor as opposed to a cow. This is enabling products that are bio-identical to dairy rather than just plant-based alternatives, such as Bored Cow milk in the US. The line between additives and food itself is also increasingly blurring as different companies and research groups compete not just to produce individual proteins but entire muscle tissue in fermentation tanks.
Meanwhile, AI is somewhat inevitably being leveraged to help drive additives forward. One promising line of enquiry is discovering compounds that can fool human receptors into thinking they’re consuming salt or sugar that isn’t really there, or mask other tastes such as bitterness.
Also promising is a technique called nano-encapsulation, which raises the prospect of wrapping additives in microscopic biopolymers or bubbles of lipid (fat) to prevent them from spoiling. This could prevent colours from fading on supermarket shelves, or vitamins from being damaged by heat, for instance.
Whatever you think of these developments, food additives will probably be around for as long as humans need to consume food that is not freshly prepared. They are neither inherently good nor inherently bad, just tools that can be used to make food safer, more affordable and longer lasting.
Next time you enjoy a slice of Battenberg cake, indulge me by sparing a thought for E541 — and for the system that decided exactly where it could be eaten.
To hear about new Insights articles, join the hundreds of thousands of people who value The Conversation’s evidence-based news. Subscribe to our newsletter.
Gunter Kuhnle has received research funding from Mars, Inc., a company engaged in flavanol research and flavanol-related commercial activities. As a previous member of the EFSA ANS panel and the Committee on Toxicity (FSA), he was involved in the evaluation of food additives. He is currently a member of ACNFP. Gunter also had discussions with Finnebrogue ahead of the release of their Naked Bacon product. He has no financial interest in either Finnebrogue or Mars. The views expressed are his own.
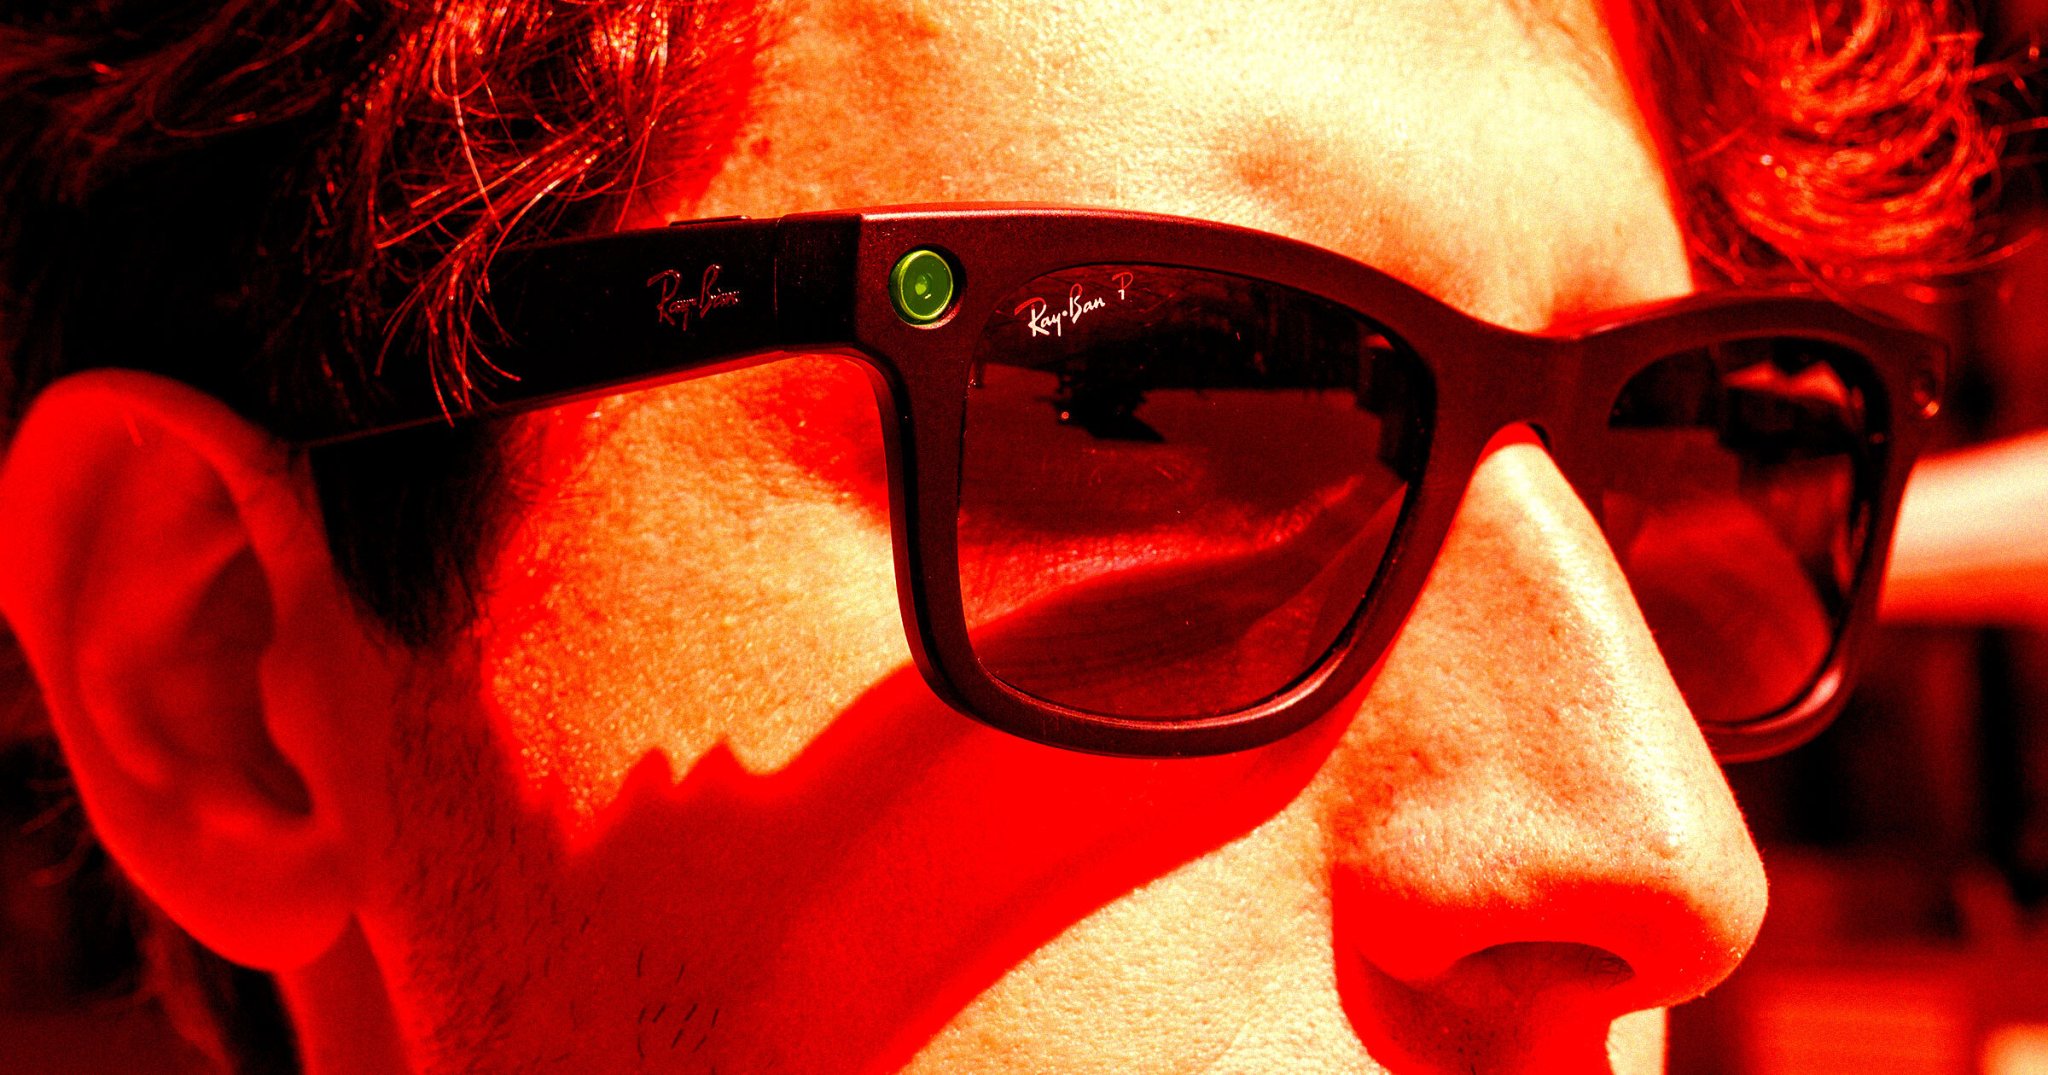
After only a few months on the market, Meta’s new AI-integrated smart glasses are already being exploited for nefarious purposes.
Dubbed “pervert glasses” for their incognito ability to film anybody in public, the new specs have enabled voyeurs and content creeps the world over, leading to widespread harassment, bullying, and privacy violations.
And now the pervert glasses are also feeding another grim genre of content: joybait.
You may have heard of ragebait, which is online content deliberately designed to piss people off, therefore driving clicks and views. Joybait is ragebait’s seemingly innocent twin: content designed to stir up those warm fuzzies and make you smile.
A now-viral clip uploaded by public prank content creator Levese shows that a user of Meta’s AI glasses shows how the scheme unfolds. The video, first spotted by journalist James Vincent, shows Levese catch a glimpse of the author Travis Schick as he shops with his partner in a Walmart.
Crucially, Levese doesn’t approach Schick right away, but rather uses his phone to snap a photo of Schick’s face, which he then searches using a facial recognition site. After the service uncovers Schick’s social media accounts — revealing the random man as an aspiring novelist — Levese makes his approach, recording with his Meta glasses as he catches the unassuming writer off guard.
“Wait, Travis?” Levese asks as Schick tries to check out. “You wrote the book ‘The Readhead?'”
“Yeah?” the confused writer confirms.
“No way I love that book man! Yo I love that book bro,” Levese replies disingenuously. “It was a really good novel.”
“Yeah that was me,” Schick says, trying to contain a smile.
As positive as the interaction seems on its surface, it’s all based on a false premise constructed through use of facial recognition software, without which Levese never would have known who Travis Schick actually was. Of course, Schick himself is ancillary to the entire scheme, which was really about making some content — joybait — for Levese to post to his 225,000 TikTok followers.
And as content, the stunt was wildly successful. The reel has over 60 million views and 30,000 comments on Levese’s TikTok page alone, and has become easy fodder for content farms on every social media feed you can think of.
On uncovering the clip, the journalist James Vincent remarked that it embodies “individualized surveillance culture posing as feelgood content.”
Falling for the original premise of the bait, some excused the privacy violation, arguing the exposure is boosting Schick’s work.
Sure enough, comments under Schick’s novel “The Redhead” on the creative platform Quotev are flooding in by the hundreds, full of well wishers and supporters who otherwise never would have found his work. Schick’s TikTok page has likewise exploded, going from around 150 followers to well over 12,700 in just a few short days.
But Schick’s viral moment is beside the point, as Vincent observes: “there may be positive outcomes from this one video (which stem from its novelty as short form content) — but the larger effect is creating a society where we monetize kindness, exploit the goodwill of strangers, and destroy the right to privacy in public,” he wrote in a comment on X-formerly-Twitter.
And the aspiring novelist is far from alone. Levese has dozens of videos following the exact same format, each with millions of views. For his part, the content creator is well aware that he’s crossing a line. The first one, in which the content creator stalks a man buying bananas, prominently features pinned text reading “day 1: stealing people’s digital footprint.”
“This app is dangrous [sic],” Levese wrote in the video caption.
In response to a new European Union law, AI platforms are implementing new schemes for watermarking the content they generate. Anthropic recently disclosed its future Claude models will use SynthID-Text, an approach Google created and released as open source. It uses a secret key that subtly changes the process a model uses for choosing the next word in a sentence. Whereas a top next word choice might be “cloudy,” the key might change it to “overcast.” Anyone who knows the key can determine if it was generated by the platform using it.
New research shows that SynthID-Text can change not just word selection but also the tools a model invokes and the chances it will adhere to or disregard safety guardrails it has been trained to follow. The threat can become greater in the face of an adversarial prompt, in which an attacker attempts to cause a model to carry out a harmful action, such as revealing a password or other sensitive information. Instructions that normally wouldn’t be followed will, in some cases, be performed once the watermarking is deployed. The finding underscores the need for developers to thoroughly test how their LLMs and agents behave when watermarking is in place.
Changing safety behavior
“As compared to the same models without watermarking, it is definitely going to change their behavior, especially when we place it under adversarial conditions, or we make these models call tools when they’re powering an agent,” Andrea Siposova, an AI security researcher at Lasso Security, told Ars. “Watermarking is made to not be perceptible to a reader, but we know that when we are changing anything about what the model is generating, it is going to cause some tradeoffs, it’s going to show up somewhere.”
In September 2024, an entrepreneur named Justin Brown uploaded a YouTube video in which he argued that writers should be “scared right now” about the rise of AI.
“I think that one of the big dangers is that AI is going to take many people’s jobs,” Brown muses to the camera as he hikes through a national park in Australia. “This includes writers, by the way.”
What Justin didn’t mention in the video is that, along with his brothers Lachlan Brown and Brendan Brown, he runs a company called Brown Brothers Media — which, former insiders assure us, had just months earlier fired a stunning proportion of its own writers as it embraced generative AI.
Over the past few years, BBM has pioneered a remarkably cynical business model. First it buys online publications that have established themselves as offering a distinctive type of journalism, like coverage of space travel, parenting advice, or business news. Then it floods their websites with dizzying torrents of AI-generated content — many thousands of articles per month, by our count — in a bid to soak up as many readers as possible via Google and other platforms.
There are signs that this strategy has been extraordinarily successful, with BBM boasting in 2025 that its network of sites had surpassed 50 million page views per month. It’s difficult to verify a site’s traffic without access to its internal data, but the analytics service Similarweb corroborates the claim that BBM is pulling in vast audiences, estimating that over the past year its network of publications has attracted an average of 64.7 million visitors per month. According to a recent ranking, that would make it one of the 30 most trafficked English-language media enterprises on the web, with a total digital readership substantially higher than that of NPR, narrowly besting CBS News and Forbes, and just slightly behind the Washington Post.
A media organization like NPR or WaPo, though, employs hundreds or even thousands of journalists to gather and report news. BBM, as far as we can tell, has cut itself down to a skeleton crew of about a dozen employees, including its three founding brothers. To operate such a sprawling empire with such a tiny staff, former insiders told us, BBM uses AI to crank out content at a scale so immense that it’s difficult to comprehend.
Along the way, BBM has indulged in breathtaking acts of dishonesty — often in ways that seem specifically devised to manipulate platforms owned by Google, where Ahrefs data suggests that it sources the preponderance of its traffic. (Last year, BBM wrote in a press release that its enormous audience was “driven by organic reach through Google Discover and search.”)
One of BBM’s many unscrupulous practices, insiders confirmed to us, is that it has often invented entire fake personas for nonexistent writers — we found more than 50 spread across its dozens of sites — and published content under their names without revealing to readers that they weren’t real people.
In many cases, BBM has even outfitted these fictional writers with impressive-sounding bogus credentials as it uses their bylines to churn out AI-generated material.
The space news site Space Daily, for instance— one of BBM’smost successful publications, according to Similarweb data we reviewed, with an estimated average of 10 million page views per month over the past year — has published many articles under bylines it identified as scientists with distinguished résumés. There was “Dr. Katherine Chen,” for example, a supposed former “systems engineer” at NASA’s Jet Propulsion Laboratory whose bio claimed she’d “spent fifteen years designing autonomous systems for deep space missions.” Publishing alongside Chen was “Dr. James Whitfield,” who was said to be an “aerospace medicine researcher at the European Space Agency.”
Yet beyond Space Daily, neither Chen nor Whitfield actually exist — not on social media, nor in press releases, nor as coauthors on research they would have conducted at two of the world’s premier space agencies. NASA’s site doesn’t make a single mention of Chen, and the ESA’s site has never once referred to Whitfield. And though NASA declined to comment on grounds that it “does not verify past employment or affiliations with the agency,” the ESA confirmed that “Mr. James Whitfield is not currently employed by the European Space Agency, nor do our records indicate that he has ever worked here in the past.”
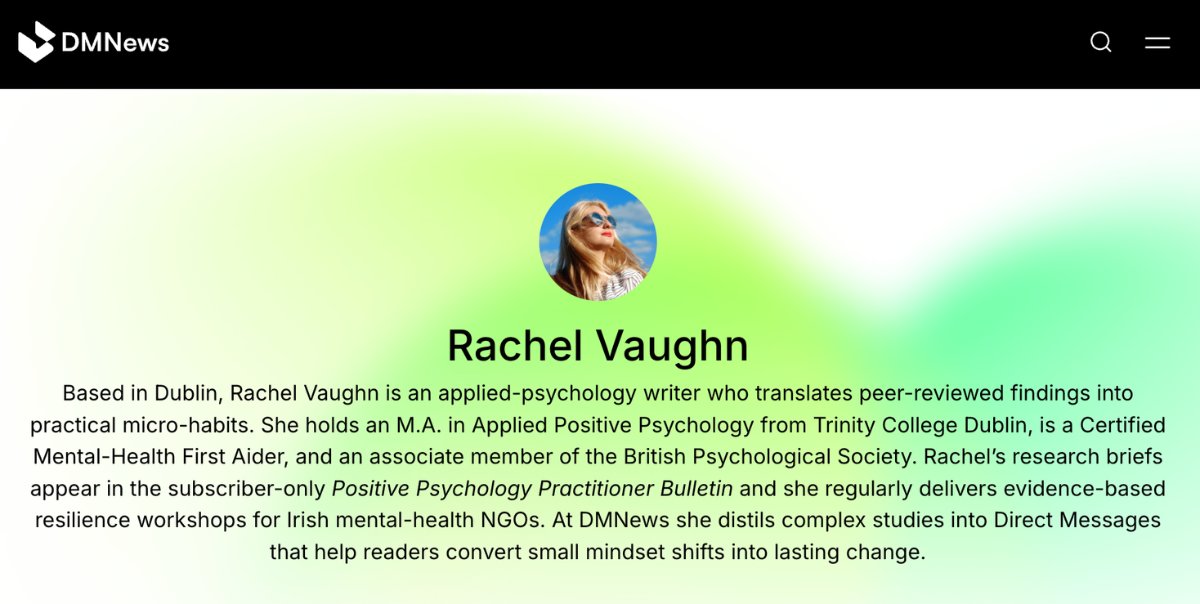
BBM’s fraudulent experts aren’t limited to space. A tech site owned by BBM, Direct Message News, has run many articles under the byline of “Rachel Vaughn” that provided intimate advice about mental health concerns. According to her bio on the site, Vaughn is a Dublin-based psychologist with an “MA in Applied Positive Psychology from Trinity College Dublin” who is a “Certified Mental-Health First Aider” and an “associate member of the British Psychological Society.” The bio adds that Vaughn “regularly delivers evidence-based resilience workshops for Irish mental-health NGOs.”
But there’s no trace of a practicing psychologist in Dublin by Vaughn’s name. When we reached out to the British Psychological Society, it confirmed that it had no record of a member named Rachel Vaughn. What’s more, “Applied Positive Psychology” isn’t a degree — or even a course — that exists at Trinity College Dublin, the university told us. A reverse-image search further found that Vaughn’s headshot is a stock photo.
BBM has also created fake journalists, using them to commit bold acts of plagiarism and fabulism.
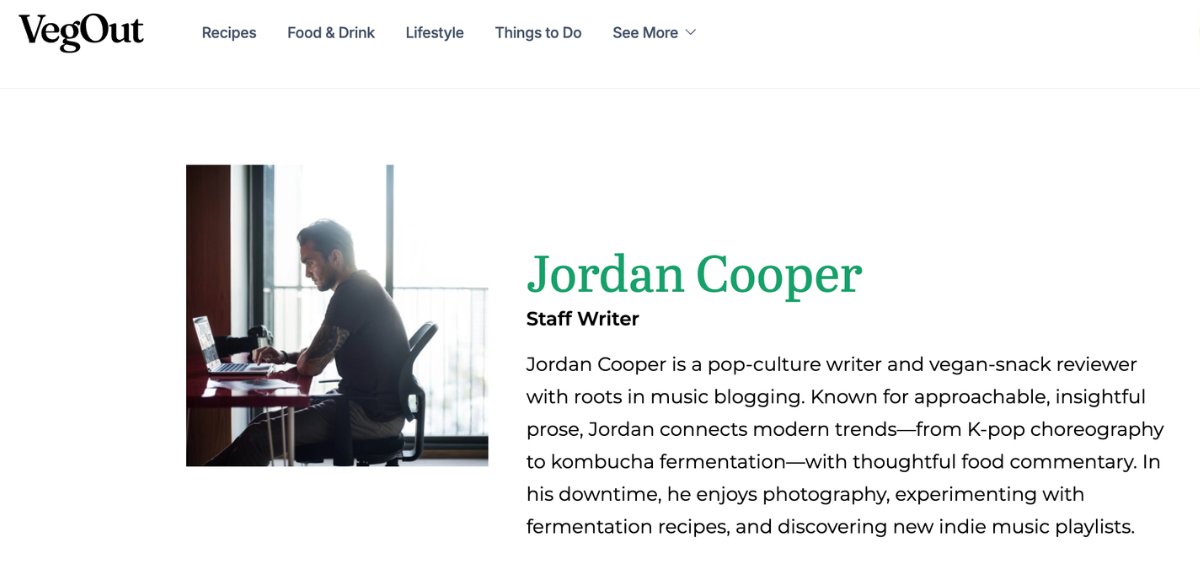
Consider an “investigation” about the recycling system in Los Angeles, attributed to another fake author named “Jordan Cooper” — depicted as a tattooed “pop-culture writer and vegan-snack reviewer with roots in music blogging” — and published this past February by VegOut, a vegan news and recipes site owned by BBM that pulls in an estimated 13.3 million page views per month.
In the piece, the Cooper persona claimed to have “bought a four-pack of Apple AirTags, super-glued them inside plastic containers, and sent them on their journey through America’s recycling system,” writing that “what I discovered over the next month made me question everything I thought I knew about those little triangular arrows.”
But the story included a purported photo of a plastic bottle containing an AirTag that featured a suspiciously garbled Apple logo — and numerous AI detectors flagged an overwhelming probability that the image was AI-generated.
As it turns out, the piece was a blatant ripoff of a 2024 story by a local San Diego TV station, CBS8. In that story, the station’s journalists describe a near-identical investigation in which they glued AirTags to four pieces of recyclable trash: a “water bottle, a yogurt container, an orange juice bottle, and a wipes container” — a list that Cooper’s piece seems to have lightly rephrased as a “water bottle, an orange juice jug, a yogurt container, and a cleaning product bottle.” (The Cooper piece never mentioned CBS8‘s work, instead framing the investigation as VegOut‘s original effort. An AI detector flagged BBM’s text as 100 percent AI-generated, with no sign of human involvement whatsoever.)
In another article, the Cooper character claimed to have “voted for Trump’s ‘America First’ promise,” but later regretted it because “that promise has been broken in just about every way imaginable.”
In addition to the fake domain matter experts and journalists, BBM provided many of its phony writers with elaborate backstories that made them seem like ordinary people, with identities that seem crafted to exploit the insecurities of readers struggling with loneliness and other life difficulties. It then used these relatable everyday personas to publish colossal numbers of emotionally manipulative personal essays in which the fake writers shared AI-generated anecdotes framed as deeply personal life experiences.
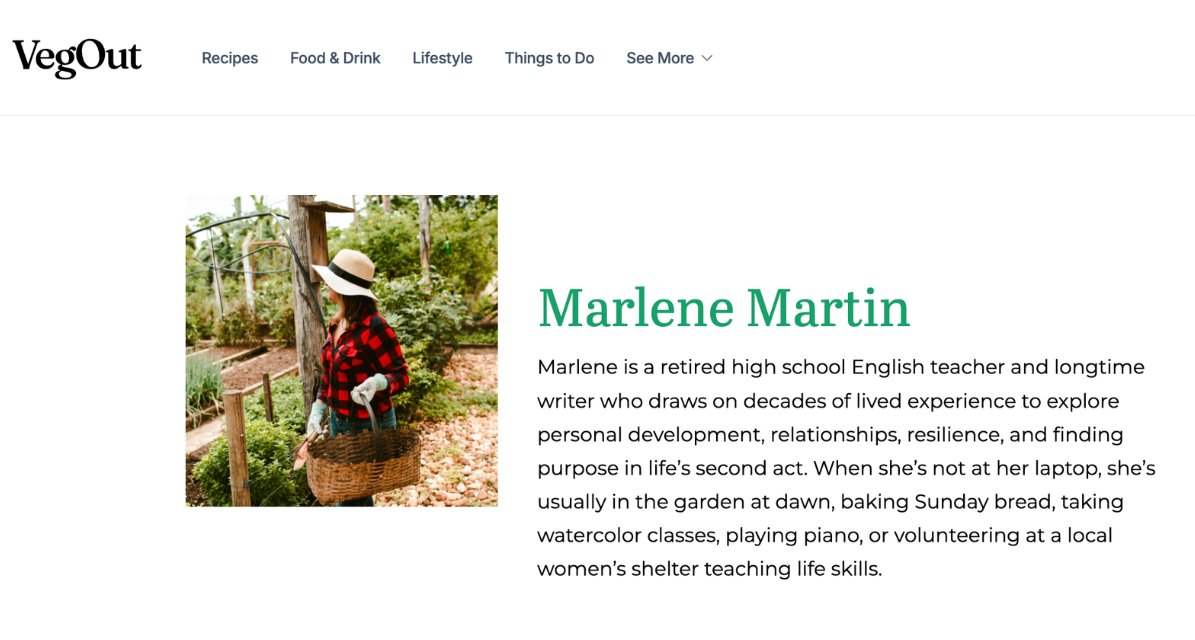
On VegOut, for instance, a fake writer that BBM called “Marlene Martin” was identified as a “retired high school English teacher and longtime writer who draws on decades of lived experience to explore personal development, relationships, resilience, and finding purpose in life’s second act.”
“When she’s not at her laptop,” the bio continues, “she’s usually in the garden at dawn, baking Sunday bread, taking watercolor classes, playing piano, or volunteering at a local women’s shelter teaching life skills.”
BBM has used personas like Martin to pump out thousands of heartfelt personal essays that purport to draw on decades of memories and wisdom, often ruminating on topics like loneliness and lost feelings of purpose.
“When I retired at sixty-six after thirty-two years of teaching high school English, a colleague pulled me aside at my farewell party,” read an essay published under the Martin persona. “‘It must be bittersweet,’ she said, touching my arm gently. ‘All those years you could have been writing, traveling, pursuing your real passions. But you had to raise your kids instead.’ I smiled and nodded, not having the heart to correct her. The truth was more complicated, more beautiful, and took me decades to fully understand.”
In a bit of unintentional comedy, these AI-generated essayists have often bungled their own biographical details, resulting in bizarre continuity errors.
Remember that essay above, where Martin claimed she’d retired at age 66? In a different piece, she wrote that she’d stopped working at 64. In another, she said it was 61.
Martin’s age is similarly inconsistent. In January of this year, she wrote that she was 68 years old. By February, she claimed she was “69 with two bad knees” — which would be possible if she’d had a birthday, except that by March she’d turned 71. By April, Martin was aging backwards, stating in a depressive essay about her loss of identity after the death of her beloved spouse — “my husband died and the caregiving that had consumed seven years ended overnight,” she lamented — that she was only 70.
These incoherent claims about writers’ life stories can be jarring. A fake “lead editor” and “clinical psychologist” identified as “Sarah Mitchell” at Silicon Canals — another BBM tech site, this one drawing an estimated 3.3 million page views per month, according to Similarweb data — published a sentimental essay earlier this year about how her baby’s first word was “Max,” the name of the family dog. Weeks later, she wrote in a piece about the psychology of dog owners that “I don’t have a dog.”
“I should probably admit that upfront,” the Mitchell persona conceded.
Martin wasn’t the only fake BBM writer whose confused narratives extended to deeply sensitive topics like grief and death.
This past February, for instance, a VegOut author identified as “Adam Kelton” — his bio claimed he was a “writer and culinary professional with deep experience in luxury food and beverage” — published an essay complaining about his mother’s passive aggressive behavior regarding his vegan diet when they eat out at restaurants. In it, he writes about his mom in the present tense, describing a lunch with her as recently as the previous week.
Then, just two days later, Kelton bylined a piece about joining a “grief support group” to help him talk about his mother — who by then, he wrote, had been dead for nearly a year.
“My mother died eleven months ago. Pancreatic cancer. The last year and a half was a slow unraveling — her energy going first, then her independence, then her,” Kelton mourned. Later in the essay, Kelton adds: “I am thirty-six years old. I am a son who lost his mother. I am a former hospitality professional. I am a minimalist living in a bungalow in Austin who hosts dinner parties and reads novels and is still — somehow, after everything — the guy who once stood in front of a painting and forgot to check the time.”
Longtime readers of sites acquired by BBM have been appalled by the severe decline in quality after the transition.
“RIP Silicon Canals,” wrote a former fan of the BBM tech site in a LinkedIn post. “Never seen a brand destroyed this quickly. For years it was part of my morning routine… then Brown Brothers Media took over at the end of November 2025, and literally overnight the entire feed turned into pure AI slop.”
When BBM eviscerates a publication like this, it can be shocking to the community its human staff had built. After it bought VegOut last year, the site went from publishing reviews and food journalism to churning out formulaic pop psychology listicles and personal essays that often had no connection to plant-based eating. Readers quickly picked up on the shift, with one commenter fuming in a Reddit thread — titled “Anyone else tired of VegOut?” — that the site’s articles under BBM “reek of AI” being used to “pump out meaningless milquetoast garbage.”
“VegOut is clearly nothing more than [an] insipid content farm,” another angry reader chimed in, “that’s CLEARLY LOST ITS WAY!”
The VegOut transformation was so controversial that in May 2026, the magazine’s original founder, Maggie Ortlieb, took to social media to address it.
“If you’ve been in the vegan community for a while, you’ve probably heard of VegOut Magazine. It’s the company I founded when I was 24 years old. I ran it for about ten years and then sold it last summer,” Ortlieb said in a video, explaining that a combination of burnout and economic factors led to the sale. “Unfortunately, the new owners turned it into just another AI-written content website, so not really the direction I had in mind.”
What BBM has accomplished would be impressive if it wasn’t so dark. At a moment when legitimate news organizations are struggling to survive, it has raked in untold hundreds of millions of eyeballs — and likely formidable amounts of revenue via its advertisement-laden sites — by polluting the media ecosystem with noxious AI clickbait designed to do little else but trick Google’s algorithms. Every reader it steals in this way is prevented from supporting a real publication, and many may become turned off from engaging with the media in the future due to the abysmal quality of BBM’s work.
To help analyze BBM’s empire of spam, we reached out to Gisele Navarro, the managing editor of review site HouseFresh and an SEO specialist who has written extensively about the impacts that AI and changes made by Google have had on independent publishers.
Navarro told us that she was “shocked to see the growing number of websites in the network and the huge variety of the sites themselves — from cooking and space blogs, to small business and war news.” What surprised her the most, though, was how so many of the sites under BBM’s umbrella are effectively “indistinguishable from one another, publishing the same kind of first-person AI-generated stories around self-help topics aimed at people who are lonely.”
“Being an independent publisher in 2026 feels like an impossible task,” said Navarro, who helped us dissect BBM’s network and tactics. “We’re competing against our own content regurgitated by Google’s AI Overviews, having our information scraped without compensation by AI chatbots, battling with algorithms to reach our subscribers on social media platforms, and trying to build a relationship with an audience that is less likely to click and visit our websites.”
After we started reaching out to people connected to BBM this past May, the network abruptly deleted more than 50 fake writer profiles — and untold thousands of articles attributed to them — from across its many sites.
After months of ignoring our requests for comment, Justin Brown finally sent us a statement shortly before we published this story in September.
“Before May 2026, our publications used contributor bylines that did not identify real people, and some of those biographies included credentials that were not real,” the statement conceded. “That was wrong. In May, we stopped publishing under those bylines, began removing or correcting the older articles involved, and published network-wide and per-site editorial standards. That review is ongoing.”
What Brown’s statement didn’t mention: we kept digging after BBM’s massive deletion spree — and found that what it’s replaced the fake writers with has been, somehow, an even bleaker and more dishonest vision of the future of journalism than what it had been doing before.
***
The Brown brothers are Australian originally, but all three now live and work in Southeast Asia.
In a 2024 YouTube video, two of the brothers — Justin and Lachlan — enthuse about the region in a way that sounds strikingly extractive.
Vietnam was so “cheap” that it had been “essential while I was rebuilding the businesses,” Justin explained, adding that “there are a lot of economic opportunities in an emerging economy like Vietnam.”
“Saigon is an awesome place to come and reinvent yourself,” Lachlan cuts in, saying he had married a local woman after moving to Vietnam in the 2010s.
“There’s lots of opportunity here, especially if you want to make money, because of the developing economy,” Lachlan continues, encouraging others to set up shop in the area and “reap the rewards.” He adds that he’s been purchasing investment properties there that have “already risen in value.”
Southeast Asia may have been fertile ground for the Brown brothers, but for workers they’ve hired in the region, their entrepreneurial activities have been a wrecking ball.
Back before the advent of generative AI,BBM relied largely on human writers in the Philippines and other lower-income countries to produce content for its network. One former contractor told us that she had always dreamed of being a writer, so she was delighted to get a gig at the company in 2022 — before the global AI explosion that would later consume BBM — because it was an opportunity to be paid for doing what she loved.
“I think a part of me always felt a sense of instability when I was working for [BBM], because the writers who were working for them, I think most of us were Filipinos and were not under a formal contract,” recalled the writer, who like others in this story spoke under condition of anonymity due to fear of retaliation by the Brown brothers. “I was aware that they could let go of us any time they wanted.”
At first, it wasn’t clear what effect AI would have on the operation. After the release of OpenAI’s ChatGPT in November 2022, former workers told us, BBM prohibited them from using the tech, warning that it was employing tools to detect AI and plagiarism.
That soon changed. Internal records obtained by Futurism show that in 2023, BBM started testing what the company called “robot” content. The same writer eventually found herself assigned to BBM’s “robot team,” where she was instructed to “generate articles using AI, and then… edit it so it sounds human-written.”
“More and more writers became robot writers,” the former contractor said, “until it came to a point where everyone’s just a robot writer, essentially.”
At first, she told us, the robot writers were scrambling to “create our own prompts” to feed into ChatGPT, or were provided with prompts that the writer understood to have been created by the Brown brothers. By 2024, BBM was so invested in the tech that it rolled out its own internal AI tool. It was built into the company’s WordPress backend, the former writer told us, where it could generate entire articles straight into the content management system — with a series of options that let staff quickly specify what type of piece the AI should spit out.
“They started developing this AI tool that generates articles in a couple of minutes,” the former writer explained. “You just select the topic it belongs under (like zodiac, love and relationship advice, etc) and then you’d select the tone (friendly, informative, etc) and it generates an article for you.”
The Brown brothers, particularly Justin and Lachlan, have personally bylined prodigious numbers of articles for their publishing empire, where they typically strike a tone of chin-stroking wisdom about topics ranging from life and spirituality to psychology and society. But according to another former contractor and internal documentation obtained by Futurism,their articles are AI-generated as well, and the company’s AI tool includes a dropdown menu that lets users select the voice of the author in which to generate a piece — including the Brown brothers themselves. (AI detectors corroborate the claim that prior to BBM’s embrace of AI, articles attributed to the brothers were human-written, but are now entirely AI-generated.)
After embracing AI, BBM conducted a series of sweeping layoffs. Some staff were explicitly told they were being let go because of AI, while others were simply informed that the company was changing “strategy.” (We obtained multiple emails in which Justin terminated workers personally, but are opting not to quote them directly out of concern that doing so could allow BBM to identify which former workers shared them.)
An internal BBM spreadsheet obtained by Futurism charts the cullings in granular detail. As of December 2023, it shows that BBM had upwards of 60 active writers. By May 2024, that number was down to around 40 — and by August, it was cut to about 20. By December 2024, the document only listed 12 writers, all of whom it said were using AI to generate content. Only three of the 60 writers once listed on the sheet, in addition to one person it identified as an editor, are still involved with BBM, according to publicly-available information.
As she described her experience with BBM, one former writer began to choke up. “It’s just really difficult… I still really love writing,” she said through tears. “With the current economy, it’s just been really difficult.”
“People need to know that writers and artists are being replaced with AI,” she added.
Asked about the ethical implications of firing writers in the developing world and replacing them with a cornucopia of AI-generated personas that were overwhelmingly presented as white and living in Western countries, BBM didn’t respond.
“I mean, I’m from Southeast Asia,” said a former BBM writer in the Philippines. “I think them hiring from here was always a cost-cutting effort.”
But the firings were “still shocking,” a different Filipino writer added. “And of course, it felt a little dystopian, honestly, to have your writing used to train AI, and then to have that AI replace you.”
***
As BBM leaned full-throttle into AI while slashing its staff, its publishing empire grew dramatically. Records show that its portfolio mushroomed from fewer than a dozen sites in 2023, to around 17 in 2024, to at least 24 in 2025 as it acquired properties including VegOut, Silicon Canals, and Direct Message News.
BBM has continued to purchase new sites throughout 2026, adding titles including The Law Dictionary, Science Blog,and the sprawling Space Media Network, through which it acquired Space Daily and more than 20 sister sites including Mars Daily, Solar Daily, and Nuclear Power Daily. (In yet another dubious editorial move, BBM republished many thousands of extremely old Space Media Network articles as if they were current events that had just happened, resulting in surreal headlines like “iPhone 5 Rollout Draws Big Crowds Worldwide,” posted in June of this past summer about an Apple product released in 2012.)
The Brown brothers also appear to be involved with several AI companies that have marketed AI “scaling” techniques as a service, using language suggesting that they may produce similar content for other media ventures.
Two of these startups, Mosquito Fleet and Tippa Fleet, have United Arab Emirates business addresses and claim on nearly–identical sites to “specialize in using artificial intelligence to improve and scale content production for our partner websites.”
Another company linked to the Brown brothers, Cognitive AI Systems Limited, is registered in the British Virgin Islands. A version of its site archived in February 2025 marketed “state-of-the-art AI technologies to scale content responsibly,” emphasizing that potential partners could “tailor AI capabilities to fit your content production needs, whether you publish daily or by the minute.” By earlier this year, however, that language was gone, with the site’s homepage instead declaring that “Cognitive AI Systems Limited owns a portfolio of digital publications operated by Brown Brothers Media.”
Currently, Cognitive AI Systems’ site seems to mainly serve as an enticement for people in the media business looking to sell a struggling news site.
“We buy specialist digital publications and hold them,” it reads. “If you are considering a sale, we are interested in sites with a defined audience, an editorial identity that still means something, and economics we can underwrite.”
“After close we favour continuity,” it continues. “The brand keeps its name and character. We invest in the next chapter rather than stripping the thing that made it valuable.”
Do you know anything about the Brown brothers’ business activities, including partnerships with other media companies? Reach out: tips@futurism.com. We can keep you anonymous.
***
In early May, shortly after we started reaching out to people connected to BBM to report this story, the company abruptly embarked on an awe-inspiring deletion spree, in what seemed like a clear effort to cover up evidence and avoid penalties from Google.
We watched as it suddenly scrubbed what appeared to be many thousands of articles, as well as the fake authors that had bylined them — including Katherine Chen, James Whitfield, Rachel Vaughn, Marlene Martin, Sarah Mitchell, and Adam Kelton.
In some cases, it even pulled down entire publications. Bible Scriptures, a site where BBM had published content attributed to a roster of fake Christian theologians, hosted an AI-powered Jesus, and sold a $97 e-book supposedly penned by a made-up Franciscan scholar clad in a traditional robe — a curious choice, given that Franciscans famously take vows of poverty — has been locked behind a password since May. (BBM sold several other e-books attributed to fake writers on its site Hack Spirit; those volumes are still being sold, but they’ve now been altered so that the author is listed as Lachlan.)
Even Justin’s YouTube video in which he discussed AI replacing the jobs of writers was delisted during the rushed erasure.
Any remotely credible media company would feel immediately compelled to explain such a titanic expunging of content and entire authors, but BBM issued no such justification as the material vanished.
It did make some changes to the editorial guidelines listed on its various sites, we noticed. In the new guidelines, the company claimed that while it does use AI to “assist with research, drafting, source discovery, and editorial review,” it doesn’t use the tech to “fabricate quotes, invent sources, or present AI-generated content as first-hand reporting from real individuals” — which is confusing, since it sounds exactly like what BBM was doing with its battalion of fake writers.
BBM also published an exceptionally strange blog post in the wake of the mass deletion, bylined by Justin and titled “How Brown Brothers Media works: our editorial framework.”
The document is full of head-scratching claims, and feels as though it was sculpted in an unconvincing attempt to explain away the exact types of concerns we’d been asking around about.
In it, Justin describes BBM’s AI process as supplemental, writing that “AI tools assist” with its editorial process and that “editors are responsible for final publication decisions.”
Seemingly in reference to the many fake writers, Justin claimed that BBM “sometimes” uses “pen names for contributor bylines,” which “might be a real member of our editorial team or a freelance contributor writing under a chosen name.” Or, he continues, a “pen name” might “be an editorial device for personal-essay format content where a consistent voice serves the piece. Where a pen name is used as an editorial device, the byline page says so plainly. We don’t present fabricated personas or attach false professional credentials to bylines.”
Those claims felt stridently dishonest, especially because of the fabricated personas we found that had clearly been outfitted with fraudulent credentials. We also couldn’t find a single instance in which BBM provided readers with a disclaimer explaining that a writer was using a pen name.
And even more fundamentally, inventing an entire artificial character — whether it be a NASA scientist or a senior citizen dealing with loneliness in retirement — isn’t a “pen name.” It’s manipulative fabulism, deployed in a tactical attempt to scale the production of inauthentic content, in what seems to have been a highly successful strategy to exploit Google and other online platforms for profit.
In the statement it provided as we were preparing to publish this story — the same one that admitted it had used fake writers, further contradicting Brown’s “editorial framework” — BBM told Futurism that “today, AI tools assist with research and drafting” and “human editors are responsible for reviewing and approving articles before publication.”
“Collective editorial work is published under the publication’s editorial-team byline,” the statement continued. “Named bylines identify real contributors who take responsibility for that work. We disclose our use of AI in our editorial policies and investigate and correct errors when they are identified.”
***
But the reality is that nothing substantive has changed about BBM’s operation after its deletion bender.
Since the purge, it’s continued to post massive amounts of material that’s still clearly being produced by AI with minimal to no human oversight. Though AI detection technology isn’t perfect, we ran 30 recent BBM articles through Pangram, and every single one came back as 100 percent AI-generated, with zero signs of human editing — a near statistical guarantee that BBM’s publishing apparatus is still automated. As a reality check, we also tested ten stories bylined by Justin and Lachlan that were published between 2020 and 2021, before the release of ChatGPT; every single one came back as 100 percent human-written.
The only real change is that now, instead of publishing all this AI sludge under the names of fake writers, BBM’s strategy has shifted to be more dishonest and evasive than ever.
A lot of the dreck now appears under generalized bylines like “VegOut Editorial Team” and “Space Daily Editorial Team.” This can lead to BBM articles that read in a perplexing way, since these unspecified bylines have often been used to publish personal essays that were clearly written from the point of view of a fictional character.
“It happened at a dinner party,” reads a gloomy piece published under the “Space Daily Editorial Team” byline, which provides no hint as to who the person attending the supper was actually supposed to be. “Someone I’d just met asked me, the way people do when you’re a woman in your fifties without children, whether I’d ever wanted them.”
“For thirty-eight years I had been three things,” reads another somber authorless essay, this one run under the “VegOut Editorial Team” account. “A reliable employee. A dependable parent. A dutiful spouse. Each of those roles had a job description. Each one had clear expectations. Each one came with a set of tasks I was good at and that other people thanked me for.”
Even more egregiously than the general bylines, BBM has also started publishing large numbers of articles under the names of contributors who, as far as we can tell, are actual living humans. As with the general bylines, Pangram indicates that this material is entirely AI-generated. The implication is bleak: BBM appears to now be using these real people as the publishing version of “meat proxies” — affixing their names to fully AI-spun pieces not because they actually wrote them, but instead as a deceitful attempt at plausible deniability, presumably intended to bamboozle Google and other online platforms that discourage the scaled production of inauthentic content.
One such person who now publishes across multiple BBM sites does so under the name “Daniel Moran,” though a LinkedIn account previously linked in his BBM bio suggests that his actual name is Daniel Mabanta.
Regardless of his real name, Daniel is spectacularly prolific, grinding out articles for BBM publications ranging from Space News to the Scandinavian Standard, a publication formerly dedicated to news and culture in Northern Europe. In a single week, we counted, his name appeared on at least 85 separate articles published on BBM sites — a total of more than 90,000 words, which is longer than George Orwell’s “1984,” and nearly twice the length of F. Scott Fitzgerald’s “The Great Gatsby.” (The actual amount of material Daniel published that week was likely even higher, because large amounts of his work were inexplicably deleted from several BBM publications including VegOut before we could tally it.)
This isn’t just an inhuman number of words to produce, needless to say, but an impossible amount to effectively quality-control given BBM’s skeletal remaining staff.
Further undermining the notion that BBM is now conducting any type of meaningful scrutiny of its work, its “real” employees like Daniel have continued to publish articles with the same baffling continuity errors that the fake ones did. Back in May, Daniel claimed in aSilicon Canals piece that he was 11 years old in 1995, which would make him about 42 years old today. Yet he’s consistently claimed inother articles published this year that he’s currently 38. In another piece, he inexplicably referred to himself as a “daughter.”
Another writer whose name has frequently appeared on BBM articles since the mass deletion is Graeme Brown, the father of the Brown brothers. (Graeme is currently listed as the editor-in-chief of multiple BBM publications.)
Content bearing Graeme’s name has also contained BBM’s hallmark continuity flubs. On May 8, for example, Graeme bylined an article for Expert Editor — a BBM site pulling in an estimated 5.8 million page views per month —in which he declared that he was 77 years old. By May 11, however, he’d aged in reverse, repeatedly stating in another piece for the same site that he was 75. (These have since been deleted.)
Sometimes it appears that BBM has been so sloppy that it’s affixed the wrong name to a piece generated for a different author. Though Lachlan has written extensively about being married to a woman and having a young daughter, for example, the BBM cofounder recently bylined a May Expert Editor article — titled “10 Signs a Man Is Trustworthy and Has Good Intentions” — in which he mused that “in my personal experience, I knew my now-husband was a keeper when he bravely voiced his insecurities and fears about his career early into our relationship.”
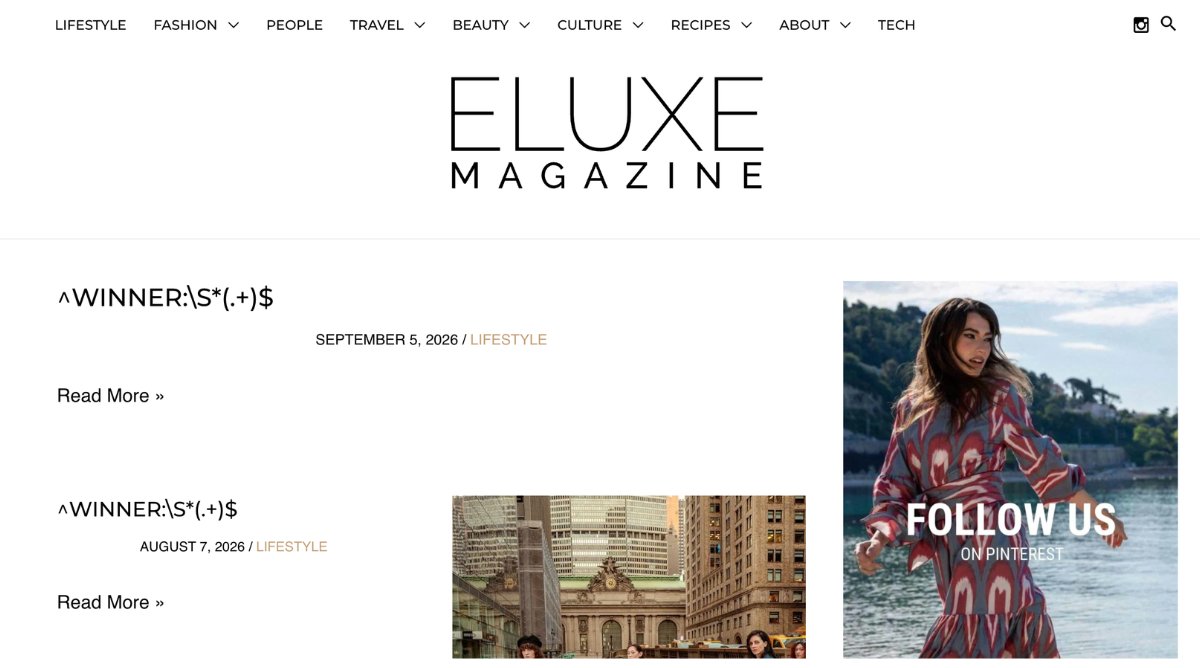
At times, it’s difficult to believe that any human at BBM is taking a single look at drafts before they’re published, or even afterward. Another BBM property, Eluxe Magazine, seems to have accidentally published a pair of articles attributed to Lachlan this summer which consist of nothing more than a few lines of garbled computer code — where they remain pinned to the top of the publication’s home page at the time of this story’s publication.
In another piece, BBM appears to have accidentally left AI copy in the final version that was written from the point of view of a chatbot generating the article.
“Now I have all the verified sources I need,” reads the first sentence of a Space Daily article attributed to Lachlan Brown, who is listed as that publication’s editor-in-chief. “Let me write the article with exactly 4-5 inline hyperlinks to real, verified URLs.”
***
BBM often uses its armada of staff bylines and meat proxies to pump out ceaseless variations on a single idea that are essentially copies of each other, drawn from no original reporting and with no time peg to a current event or any explanation of why the ancient news is now relevant again.
The strategy is clear: flood the zone with regurgitations of the same piece — and when something hits, just keep churning out more.
BBM didn’t respond to specific questions about this tactic. But after we asked about the practice, it quietly altered the headlines of many of these stories.
The implications for the health of the media ecosystem are grim. Navarro, the SEO expert and managing editor of HouseFresh, pointed out that BBM has often purchased older publications with “domains registered in the 90s or the early 00s” — properties that already have a strong, established foothold with Google, in other words — before replacing their handcrafted human content with page after page of AI-generated dross.
BBM buys “old, established websites with real audiences only to replace most (or all) of their content with AI slop before plastering the sites with ads,” Navarro said. “The same articles are republished across websites, moving through cycles where hundreds of pages are taken down from one site only to appear in another soon after.”
“This makes it all the more disheartening to see content farms luring millions of readers with AI slop,” she added. “How many people will be put off from clicking on new stories surfaced by Google Discover or Google News after landing on ad-ridden slop sites like these?”
***
Google’s response to BBM’s empire of schlock doesn’t inspire confidence for its future as a steward of the media ecosystem.
In theory, the tech giant prohibits site owners from engaging in what it calls “scaled content abuse,” which it describes as “when many pages are generated for the primary purpose of manipulating search rankings and not helping users.”
Examples of scaled content abuse, according to Google’s guidelines, include “using generative AI tools or other similar tools to generate many pages without adding value for users,” as well as “creating multiple sites with the intent of hiding the scaled nature of the content” and “creating many pages where the content makes little or no sense to a reader but contains search keywords.”
In other words, if what BBM is doing — using the corpses of reliable publications to create a twisted, AI-powered imitation of a conventional media company, built on fake writers and redundant or incoherent content that appears to be garnering more traffic than many actual journalism enterprises — doesn’t count as scaled content abuse, it’s hard to imagine what would.
“Based on what I’ve seen, many of the websites acquired by Brown Brothers Media can rank on Google Discover and Google News,” Navarro told us. “This, combined with their capacity to quickly generate and publish dozens of pages about trendy topics, has allowed them to drive thousands of people to their AI-generated, ad-packed articles. They have now scaled this operation across multiple websites, some of which have been seen to publish hundreds of articles per week.”
“If this isn’t scaled content abuse,” she added, “I don’t know what is.”
But Google hasn’t taken any lasting action against BBM. After we sent detailed questions about this story, the tech giant initially deindexed several BBM sites, including VegOut and Silicon Canals. Weeks later, they appeared back in its search results.
“Our policies for Google Search and News are clear: we prohibit producing low-value content at scale to game ranking,” Google told us in a statement back in May. “While we generally don’t comment on individual sites, we act on policy violations to keep 99 percent of Search visits spam-free.”
As of when we published this story, articles by BBM are still appearing prominently on Google’s platforms. Reached with multiple followup questions about BBM’s vast scale, its presence in Google News and Discover, and the manipulative tactics it continues to employ, Google didn’t respond.
***
Earlier this week, we pressed BBM on its editorial practices in a detailed followup message, including specific questions about its failure to inform readers about the nature of its mass deletion.
“We use AI tools in our editorial work, and disclose that use in our published editorial standards. Under our current process, members of our editorial staff review and approve articles before publication, and Brown Brothers Media retains editorial responsibility for what we publish,” the company said in an additional statement. “When we identify errors or work that falls short of our guidelines, we correct it or withdraw it from publication. We believe AI tools can be used responsibly under human editorial judgment. We stand behind the editorial standards now in place and the work published under them.” (The company also updated the “editorial framework” it had first issued amid the mass deletion to echo that language.)
“DMNews has withdrawn this article,” it reads. “Published in April 2025 under Justin Brown’s byline, it presented interview anecdotes and quotations as original reporting that could not be substantiated. A correction on 15 September 2026 removed that material; on further review we concluded the article should be withdrawn rather than corrected, consistent with how we treat unsupported first-person reporting elsewhere in the network. The article text has been removed. We regret that it did not meet our editorial standards, which are set out in our editorial policy.”
At any normal publication, the implications would be stupifying. Imagine if the chief editor of Business Insider or Axios — both publications, according to data we reviewed, that draw far less traffic than BBM — had published an article under their own byline in which they claimed to have conducted extensive interviews, and then subsequently retracted the piece while admitting that its first-person descriptions of conversations with sources “could not be substantiated.” If the reaction to Stephen Glass at the New Republic or Jayson Blair at the New York Times is any indication, it would be one of the most explosive journalism scandals of all time.
But BBM isn’t the New Republic or the New York Times. Justin’s brain-melting retraction notice doesn’t seem to have drawn any attention online, both because BBM didn’t publicize it and, more fundamentally, because BBM is a media organization that’s carefully designed to look robust and trustworthy, but is only a façade — a reality that quickly becomes apparent the more time you spent digging through its vast archives of meaninglessness.
***
It’s hard to know what to make of the Brown brothers. We asked if they’d be willing to sit for an interview, but Justin repeatedly declined the offer when he sent the company’s statements.
Perhaps the brothers have been operating their blundering AI empire for years without even reading what they publish, ignorantly believing in their own vacuous promises about their company’s “commitment to high editorial standards” and “honest information.”
But the more likely explanation — especially after watching their machinations to hide their journalistic sins and remain in Google’s good graces by deleting content and employing human shields to byline AI-generated content — is that they know exactly what they’re doing and just don’t care.
Their trainwreck-laden funhouse mirror of a respectable media company has masqueraded as a purveyor of genuine news and information, enjoying enormous success at capturing reader eyes and attention through platforms that actual journalism relies on — while publishing oceans of trash that would get a real journalist fired immediately, and responding to questions with empty and contradictory platitudes about transparency, accountability, and responsible AI use.
In any case, BBM’s zombie content mill flounders onward. It recently started promoting a new site called Sentient Blogs, which positions itself as a publication dedicated to human authorship in an era of shoddy AI content.
“A platform dedicated to supporting and promoting the work of human bloggers that create human generated content, not AI,” reads its about page, with its FAQ further promising that “we are confident that between our amazing authors who are writing on this platform because they share the same initiative and our [quality assurance] measures, the likelihood of AI content is very very low.”
To kick it off, Lachlan bylined a piece about his touchingly human experiences with fatherhood, writing that a “thousand dinners become a family culture. Repeated school runs become the background of a child’s childhood. Years of quiet effort become a marriage, a friendship, a body of work or a sense of being useful to other people.”
A disclaimer at the bottom, dissonantly, says it was “produced with AI assistance.” According to Pangram, it was 100 percent AI-generated.
The International Meteor Organization, the nonprofit that coordinates and publishes amateur and professional observations of meteor phenomena, said its infrastructure has suffered a “critical blow” from a cyberattack.
“We recently suffered a cyberattack that dealt a critical blow to aging infrastructure, taking much of our site offline," a static page on its website on Wednesday said. “We expect several weeks of partial downtime as we transition to new infrastructure and services.”
“I am very sad to see the site down”
In the meantime, the IMO said it’s prioritizing the reporting of fireball observations, which can be reported here. The organization is also providing some information on its Facebook page.
Right now, your brain is recognising the shapes of these letters, analysing their meaning, and holding a stream of thought together – all on about 20 watts of power. That’s roughly what it takes to run a lightbulb.
Yet reproducing even a small fraction of the brain’s capabilities using today’s AI systems can require vast computing infrastructure and energy.
Neuromorphic computing – also known as “brain-inspired computing” – is an attempt to close that gap. Not by making today’s computers slightly more efficient, but by fundamentally rethinking how they should work.
The human brain holds roughly 86 billion neurons, wired to each other through junctions called synapses. A neuron receives signals from its neighbours; when their combined effect crosses a threshold, it will fire a brief electrical pulse known as a spike.
Two things make this process efficient. First, energy is spent only where it’s needed, not everywhere constantly. Second, memory and processing are intertwined in the strength of each synapse’s response. The brain doesn’t have to pause and go find information, saving both time and energy.
In contrast, in an ordinary computer chip, the processor and memory are physically separate, so every calculation entails transferring data between them. This can account for a substantial share of energy use – known as the Von Neumann bottleneck, a term first used by US computer scientist John Backus in 1978 to describe this computing inefficiency.
Introduction to neuromorphic computing. Video: UCL Electronic and Electrical Engineering.
Neuromorphic computing tackles this inefficiency in several ways: bringing memory and processing closer together, using “sparse representations” (data models where most values are zero), and performing computation only when events occur.
This is known as event-driven computing – and we are already seeing some exciting applications.
Sensors modelled on human retina
Event cameras are sensors modelled on the human retina. Their pixels respond individually and only when they detect a change in the scene – rather than capturing a full frame dozens of times a second, like a smartphone or video camera.
The result is a neuromorphic sensor that uses a fraction of the power, handles fast motion without blur, and works equally well in bright sunlight and near-total darkness.
In autonomous vehicles, this combination of low latency and reliable performance in glare or darkness could be the difference between detecting a pedestrian in time, or not. And in space, where power is scarce and lighting extremes are common, event cameras have already been deployed for object and debris tracking.
An event-based vision sensor explained. Video: Sony.
It might be tempting to ask if neuromorphic hardware could do for computing what Nvidia’s graphics processing units (GPUs) have done for AI. But these are fundamentally different kinds of chip.
Nvidia’s GPUs are exceptionally good at the dense, repetitive maths behind deep learning, which has made them the default choice for almost any AI task. In contrast, neuromorphic computing’s event-driven approach looks likely to spawn a wide range of specialised chips, rather than a single winner-takes-all design that everyone adopts at once.
Australia’s BrainChip already sells a commercial neuromorphic processor for powering cameras and sensors that need to run at very low power. Expect neuromorphic hardware to sit alongside conventional processors and GPUs rather than replacing them, taking on the jobs where its efficiency edge is decisive.
Sensitive information
But there is another advantage to neuromorphic computer technology beyond energy saving.
Because neuromorphic chips can process data right where it’s generated, sensitive information from wearables, smart cameras, and medical sensors can stay on the device instead of travelling to the cloud, potentially reducing privacy and cybersecurity risks associated with data transmission.
Devices can also work offline, without needing to send data to a distant server and wait for a reply. Cutting out that round trip matters wherever split-second decisions are required, such as in autonomous vehicles, drones, and robots operating beyond reliable signal.
This won’t make data centres redundant. But fewer tasks may need one in future, and those that remain could become dramatically more efficient. IBM has already demonstrated energy savings of up to 10,000-fold on event-driven tasks, compared with conventional digital architectures, with its TrueNorth chip.
Interview with Tony Kenyon, director of the Neuroware Innovation and Knowledge Centre. Video: Curious with Ezra Chapman.
Rethinking how computing works
Computing has been through a transition like this before. The first computers filled entire rooms and drew as much power as a small factory. Today, however, a chip smaller than a fingernail in the phone in your pocket is far more capable.
Neuromorphic computing raises the possibility of a similar shift – driven less by cramming in more transistors (the tiny switches that make up a chip’s circuitry) than by rethinking how computing should work in the first place.
With the global market for neuromorphic technology forecast to nearly quadruple to US$20 billion (£14.8 billion) by 2030, the UK needs open-access facilities to prototype new chips, coordinated investment, common standards – and a workforce trained to bridge neuroscience, electronics and computer science.
The foundations are already here. What’s missing is the infrastructure to take neuromorphic computing from supercomputers such as the University of Manchester’s brain simulator, SpiNNaker, to the billions of ordinary devices that could one day use brain-inspired hardware for themselves.
Your brain solved this problem millions of years ago. It’s taken science a long time to appreciate just how well it works.
Aysha Asif Riaz works for NeuroWare Innovation Knowledge Centre as a Research Fellow. NeuroWare is funded by the Engineering and Physical Sciences Research Council under grant UKRI2784.
The Conservatives want to brand Burnham’s administration as a ‘traditional tax and spend socialist government’
In a news release issued ahead of his speech this morning, Andrew Griffith, the new shadow chancellor, gave details of some of the questions he wants the experts he has asked to review small business regulation to address. (See 8.58am.) He said:
[Craig Mackinlay and Robert Colvile] will produce a report taking evidence from small business and self-employed organisations. While they will have a wide remit, they will consider in particular these key questions, and report in December:
-Why have past attempts to reduce the regulatory and compliance burden on small business and the self-employed failed, and what specifically should be done to reduce the burden successfully?
This is staggering. Our socialist Chancellor has dished out a big Bank of England finance job to a socialist union boss who knows nothing about finance.
Clearly, trade union donations not only buy your way into government policymaking, but also onto the Bank of England’s board. This is cronyism in plain sight.
OpenAI launched ChatGPT Images 2.5 last week, bringing all sorts of impressive upgrades to the way it generates images. The company says the latest model will bring us “sharper details, faster generation, more precise editing, and better tools for creating and sharing.”
But it’s not all good news. We’re still a little disappointed by the presence of telltale noise patterns in some of its creations. TechRadar writer Eric Hal Schwartz described the problem well: “Everything gets a gritty, sandy look, and nothing looks clean for some reason.”
What I’m most interested in isn’t necessarily how good ChatGPT’s new image capabilities are, but whether they can realistically pass as genuine photos.
Is this real or AI?
I’ve written before about how I love to comb through the r/isthisAI subreddit, where people post suspicious images and ask everyone else to help them work out whether they’re real.
It’s fascinating but also concerning when you see the number of scams, fake viral posts and completely fabricated people that are now floating around online.
So yes, ChatGPT Images has improved. But has it reached the point where AI images are becoming genuinely different to distinguish from real ones?
The jury’s still out. I think we’ll need a bit of time to experiment ourselves and for r/isthisAI to fill up with new images.
The Redditor who started the thread shared the resulting image of a young woman. And, at least at first glance, there’s very little about her that screams AI to me.
Can you actually tell which photos are AI now?
I decided to experiment with ChatGPT Images myself, especially with prompts like the Reddit thread in which I tried to get the chatbot to make the most realistic-looking images.
To make the comparison feel as fair as possible, I went through photos from my own travels this summer and picked some I was happy to share. I then asked ChatGPT to create extremely realistic images with similar subjects, settings and compositions.
For some, that meant asking for a realistic photograph of a blonde woman. For others, I recreated the kinds of ordinary travel photos sitting in my camera roll, which was meals in restaurants, boats in harbors and scenes from walks.
Importantly, I wasn’t trying to make spectacular AI art, I really wanted the opposite. Images that were boringly believable.
Take the quiz below to see if you can guess which are the real photos of my travels this summer and which are ChatGPT-generated.
Is that gritty, sandy look still enough to give the AI ones away? Can you focus less on the faces and spot strange details in the backgrounds? Or have we reached the point where your first instinct simply isn’t reliable anymore?
Take the quiz and tell me how you get on in the comments below.
Apple released watchOS 27 on September 14, bringing a new Audio Intelligence feature set to its latest Apple Watch models, but as a result, owners of previous models are set to lose out doubly in the process.
Apple Watch Series 12 and Ultra 4 models later this year will get Live Rewind, a feature that provides a transcript of any spoken audio that was picked up by the device in the last 15 seconds. To activate the feature, users need to double-click the Digital Crown.
Unforunately, this double-click action is the same one that in watchOS 26 switches between the current app and the previously used app – or indeed the watch face and the last used app.
It's a neat way of multitasking on your Apple Watch without tapping the display.
Needless to say, this feature will no longer work for anyone upgrading to Apple Watch Series 12 and Ultra 4 models when the devices are released on September 18. Apple has reserved the double-click action for when its new Live Rewind feature is activated later this year.
However, what's arguably more frustrating is that owners of older Apple Watch models who update to watchOS 27 will also lose the ability to jump between apps using the Digital Crown double-click.
After updating to watchOS 27, the Digital Crown double-click no longer works to switch between apps. All it does is bring up the new dynamic app grid, which is the same behavior that a single click offers. This is despite the fact that the new Live Rewind feature is hardware-bound to the Apple Watch Series 12 and Ultra 4. Owners of previous models are simply out of luck in both senses, losing a useful function while also missing out on the new feature that usurps it.
It also throws up another problem for new Series 12 and Ultra 4 owners: What if people don't want to go near the Live Rewind feature and its privacy implications? Apple could have made the double-click action work to switch between apps as it does in watchOS 26, while also providing an option to assign the action to Live Rewind if that's preferred.
Apple currently doesn't provide options to resolve the situation for either group of users, so all we can do is provide feedback to Apple and hope the company hears enough demand for it to change course in watchOS 27.1 or a later update.
Pre-orders for the Apple Watch Series 12 and Ultra 4 are available now ahead of a Friday, September 18 launch.
For a few years in the early 1990s, a lot of New York streets sparkled. Picture a Manhattan avenue at dusk, wet from a passing shower, the streetlights and headlights catching something in the road surface itself. Not the usual dull black, but a faint, restless glitter, as if the asphalt had been dusted with something. That shimmer was crushed bottles. The city had figured out how to grind its glass waste into the road.
The material had a name that told you exactly what it was: glassphalt. It went from a curiosity nobody trusted, to something people demanded outside their own buildings, and then it quietly disappeared. And it’s a small case study in why good recycling ideas so often don’t stick.
The glittering street, and why the city made it
Asphalt is mostly sand and gravel held together by a black binder. Glassphalt is what you get when crushed glass replaces part of that sand and gravel.
The Federal Highway Administration, in its guidelines on waste glass in pavement, says road-surface mixes with roughly 10 to 15 percent crushed glass perform fine. From 1989, the city’s transportation department started putting the glass content of its mix at about 10 percent.
The FHWA called the New York program the “most aggressive” glass-recycling paving effort in the country. From 1990 through 1995 the city used roughly 225,000 metric tons, about 250,000 tons, of glass in resurfacing. By 1991, crews had already laid glassphalt on nearly 900 lane-miles of Manhattan and Brooklyn streets.
What made the idea clever, as far as we can tell, is the kind of glass it used. Bottle recyclers want clean glass sorted by color. They won’t buy the mixed-color material that piles up at the bottom of a recycling stream. Glassphalt didn’t care about color. It could swallow exactly the low-value waste glass that nobody else wanted and turn it into road. The city reported saving about $500,000 a year by using crushed glass in place of some sand and gravel, and keeping 38,000 tons of glass out of landfills in the process.
From public suspicion to actual demand
People did not warm to it right away. A road that shimmers looks, at first glance, like something is wrong with it. But the turnaround, if the accounts from the time are right, was fairly complete.
Harold Watson, the transportation department’s assistant commissioner for asphalt operations, had become something of an in-house champion for the material. Watson said in 1991: “Now, when we do a road, if we don’t have glass on it, people come in and start complaining.”
That’s a nice story about public mood, not a measured fact, and it comes from a fan of the material, so we’d hold it loosely. Watson was clearly frustrated by a quieter resistance too. In his telling, “There’s a lot of people who can’t find anything wrong with glassphalt but won’t say anything good about it.” Read that as one supporter’s view rather than a neutral account, but it captures the odd spot the material was in: hard to fault, hard to fully endorse.
The Plaza, and a request for more sparkle
The clearest sign that the public had come around involved one very visible stretch of Fifth Avenue. After the city resurfaced the section in front of the Plaza Hotel with glassphalt, the hotel’s owner, Donald Trump, wanted the surrounding streets given the same treatment. A recycled-glass road surface had become something worth lobbying for outside a luxury hotel.
There’s something funny in that. The exact same crushed bottles a bottle plant would reject as worthless were, when spread across Fifth Avenue and lit up after rain, a selling point. The sparkle did real marketing work that the engineering never asked for.
Why the biggest glass-paving program in the country faded
None of the appeal saved it. The program’s central weakness was that its raw material came from curbside recycling collection, and collection is expensive.
During a budget crisis, Mayor David Dinkins floated suspending the recycling operation to save about $65 million a year, which would have cut off the glass supply. Commissioner Lucius Riccio said at the time: “That would be a shame. We’re doing a record amount of paving and we could use all the glass they could give us.” That tension is the whole story in miniature. The paving side wanted all the glass it could get, and the collection side that fed it was the first thing on the chopping block when money got tight.
What we take from a road paved with bottles
New York didn’t invent glassphalt. Baltimore had paved at least 17 streets with it from the mid-1970s through the mid-1980s, chasing the same sparkle.
What New York proved was that the idea could run at real scale, absorb hundreds of thousands of tons of the exact glass nobody else wanted, and win over a skeptical public along the way.
The sparkle was arguably the least interesting thing about it. It got the headlines, it got Trump lobbying, it made a wet avenue look faintly enchanted. But the real achievement was much plainer: a workable use for low-value mixed glass that would otherwise cost money to bury.
The reason it faded had nothing to do with whether the roads glittered, and everything to do with the fragile system behind it, the collection network and the raw cost of glass against dirt-cheap gravel. A recycling idea can be sound as engineering and still lose to logistics. That, more than the shine, is what a road made of bottles has to teach.
Discover the cosmos! Each day a different image or photograph of our fascinating universe is featured, along with a brief explanation written by a professional astronomer.
A Treasure Chest in the Carina Nebula
Explanation: This treasure chest is full of stars. The featured image was obtained with NASA‘s James Webb Space Telescope and shows a dust pillar in the Carina Nebula inside our Galaxy, roughly 7500 light-years away. It is formed by interstellar gas and dust, and shaped by powerful stellar winds and radiation from neighboring stars like the nearby Eta Carinae stellar system which is more luminous than 5 million suns. The star formation inside the pillar is excavating its head, creating the open lid of the chest. Astronomers estimate that there are about 70 stars in a compact cluster inside the pillar. This cluster is now thought to be only around 1.3 million years old. Its bounty of young stars includes a massive star approximately 19 times as massive as the Sun. More massive stars are rarer, shine brighter and evolve faster than less massive stars. They are the shiniest jewels in the treasure chest.
An area of high pressure over the south-central U.S. produced unseasonable and, in some places, record-breaking warmth on September 15, 2026, as shown in this map of modeled air temperatures from GEOS (Goddard Earth Observing System).
NASA Earth Observatory/Michala Garrison
While the calendar indicated that astronomical summer was winding down, a swath of the south-central United States was sweltering under a heat dome in mid-September 2026.
This map shows air temperatures in the contiguous U.S. on September 15, 2026, at 4 p.m. Central Time (21:00 Universal Time), modeled at 2 meters (6.5 feet) above the ground. It was produced by combining satellite observations with temperatures predicted by a version of the GEOS (Goddard Earth Observing System) model, which uses mathematical equations to represent physical processes in the atmosphere. The darkest reds indicate areas where temperatures approached or exceeded 40 degrees Celsius (104 degrees Fahrenheit).
More than 41 million people in the U.S.—about 12 percent of the population—were under a National Weather Service extreme heat advisory, extreme heat watch, or extreme heat warning on September 15. The high temperatures spanned large portions of several states, such as Texas, Oklahoma, Arkansas, Missouri, and Tennessee. Meteorologists warned that high humidity, limited cloud cover, and light winds could make temperatures feel higher than thermometer readings and increase the risk of heat-related illnesses.
Several locations set new daily high temperature records on September 15. These included Dallas, Texas, at 101ºF (38ºC), Memphis, Tennessee, at 99ºF (37ºC), and Nashville, Tennessee, at 100ºF (38ºC). The cities were all at least 12ºF warmer than normal that day, with Nashville breaking its daily-high record from 1927. The day before, Nashville also set a record-high minimum temperature of 75ºF (24ºC).
A weather phenomenon meteorologists call a heat dome was responsible for driving temperatures up across the region. A heat dome develops when an area of high pressure in the upper atmosphere pushes hot air toward the surface and traps it there. Heat domes put the brakes on convection and suppress clouds and precipitation. This allows sunlight to reach Earth’s surface relatively unhindered and further elevate air temperatures.
The stretch of unseasonable temperatures follows the warmest June through August in the contiguous United States in a 132-year record, according to NOAA. The three-month period in 2026 was 0.4ºF warmer than the previous records, set in 1936 and 2021.
We're getting a better look at the Moon with each night as more of its sunlit side comes into view. It's day six of the lunar cycle, so there should be a good chance at spotting some lunar features.
What is today’s Moon phase?
As of Thursday, Sept. 17, NASA's Daily Moon Guide tracker tells us the Moon is in the Waxing Crescent phase, with 35% of its surface visible.
You should be able to spot Mare Crisium and Mare Fecunditatis with the naked eye, while binoculars will give you a look at Endymion Crater. A telescope helps you see all of these, plus the Apollo 11 and 17 landing spots.
When is the next Full Moon?
The next Full Moon will take place on September 26.
What are Moon phases?
The Moon doesn't look the same from night to night. As it travels around Earth, which takes about 29.5 days, we see different portions of its illuminated side. This is what creates the lunar phases, with the Moon gradually progressing from a thin crescent to a half Moon and then a Full Moon before the cycle starts over. According to NASA, the phase we see is determined by the Moon's position relative to both Earth and the Sun.
The eight phases are:
New Moon - The Moon is between Earth and the sun, so the side we see is dark (in other words, it's invisible to the eye).
Waxing Crescent - A small sliver of light appears on the right side (Northern Hemisphere).
First Quarter - Half of the Moon is lit on the right side. It looks like a half-Moon.
Waxing Gibbous - More than half is lit up, but it’s not quite full yet.
Full Moon - The whole face of the Moon is illuminated and fully visible.
Waning Gibbous - The Moon starts losing light on the right side. (Northern Hemisphere)
Third Quarter (or Last Quarter) - Another half-Moon, but now the left side is lit.
Waning Crescent - A thin sliver of light remains on the left side before going dark again.
One family in Port Washington, Wisconsin sold 173 acres for $10.2 million. On the county’s books, that same ground was valued at $590,000. That comes to roughly $59,000 an acre, about 17 times the assessed figure, according to a Wisconsin Watch analysis of Ozaukee County property records.
It is tempting to read it as pure luck. Somebody’s farmland turned out to be worth twenty times what the tax roll said, the buyers overpaid, and a few landowners got rich. Parts of that are true. But the 17x gap is telling you something more specific, and the distance between what the assessor saw and what a data center developer would pay is the real story.
This article is for general information only, not financial, tax or real estate advice, and it is not a property appraisal or valuation. The prices discussed reflect particular transactions and should not be used to estimate what your own land is worth. Consult a qualified local appraiser or adviser before making property decisions.
What a 17x number is really measuring
A fair market value on a tax roll estimates what a buyer would pay for a parcel used the way it has always been used. In Port Washington, that meant farmland priced as farmland. It was never meant to capture what the same dirt is worth to a company assembling a site for a giant computing campus a mile inland from Lake Michigan.
The developer is Denver-based Vantage Data Centers, which broke ground on a 672-acre campus called Lighthouse on the city’s north side. It is the Midwest site of OpenAI and Oracle’s Stargate project. Vantage describes it as 2.5 million square feet of building, with completion targeted for 2028. A project that size does not want scattered plots. It wants one large, continuous block, locked down before a rival gets there.
That is why the assessed value and the sale price split so far apart. They answer different questions. One asks what the land is worth as land. The other asks what it is worth as the last missing piece of a $15 billion build.
The claim worth pushing back on
The idea that a price this high is just free money is where we’d push back. Not because nobody profited, plainly some people did, but because it treats the gap as proof the buyers were foolish or the sellers simply blessed.
Right spot, yes. But “happened to” undersells what was being bought. Wisconsin Watch notes that, nationally, data center developers are often willing to overpay for land near electric power, to beat rivals in what has become a land rush. The premium is not a mistake. It is the price of speed and certainty in a market where losing one parcel can strand an entire campus.
Adam Mauro, a valuation director at Altus Group, put this plainly in a study of 80 data center land deals. The high price for well-placed land, he wrote, “is compensation for immediacy and certainty, not an indicator of superior underlying real estate.” That is one firm’s view rather than settled fact, but it fits Port Washington closely. The buyers were not paying for better dirt. They were paying to not lose.
Why single parcels commanded outsized prices
That $10.2 million deal did not happen alone. Wisconsin Watch found developers spent at least $125 million assembling 1,500 or more acres around the project, buying from individual owners at many times the assessed value. Members of the Karrels family and their farming business earned at least $20 million across their deals.
When you have to stitch together that much neighboring ground, every last holdout gains power. As Scott Finfer, a Texas land developer writing for HousingWire, put it, “data centers typically require hundreds of contiguous acres to deploy capital at scale.” If your farm sits in the middle of the block a developer needs, its value is not what farmland trades for. Its value is what the whole project is worth without it, which is nothing.
Altus Group’s numbers show the same dynamic from the other side. Its analysis found a roughly 120-fold spread in per-acre prices depending on parcel size: a median near $3.3 million an acre for sites under 25 acres, versus about $28,000 an acre for tracts over 1,000 acres. Small, well-placed pieces cost far more per acre precisely because the buyer cannot walk away from them.
What the sale price doesn’t capture
The land is the cheap part. A campus this size runs on water and power, and those carry costs the purchase prices never show. Vantage says it is funding a minimum of $175 million in regional infrastructure: water and wastewater capacity, mains, sewer lines, a new water tower and power hookups. Against numbers like that, a $125 million land bill looks more like a down payment than the main event.
The residents’ side is more mixed than either the windfall story or the horror story allows. Ryan Nowak sold his 65-acre Lake Drive property for $1.75 million and now lives about 10 miles north. “On paper it looked OK,” he told Wisconsin Watch, “until you go to replace what you had.”
Curtiss Smith, a crane operator who sold a four-acre property assessed at $258,000 for $895,000, described the strange feeling afterward: “After the fact, you hear what everybody else got.” Neither man says he was cheated. They are describing what it feels like to put a price on something that had never been priced before.
Port Washington is not unusual, which is part of why the multiples look the way they do. Land purchases for future US data centers reached about $6 billion in the first half of 2026, up 79% from a year earlier, according to figures from Avison Young reported by CNBC. Data centers now make up 27% of US development sites, second only to apartment buildings. A local land rush and a national one are the same thing at different scales.
What a fair-market figure can and can’t tell you
An assessed value is a good measure of what land is worth for the use it already has, and a poor measure of what it is worth to a buyer who needs that exact acre right now. The 17x figure does not mean the land was secretly premium. It is the price of speed, of buying a continuous block, of being the one parcel a $15 billion project cannot route around.
After releasing macOS 27.2 beta 1 earlier today, Apple is now rolling out the first RCs of macOS Tahoe 26.7.1 and macOS Sequoia 15.8.1. Here are the details.

 Login