❌

Reading view

Seismocardiography Estimates Cardiorespiratory Fitness in Elderly

In a groundbreaking advancement for geriatric health assessment, researchers have unveiled a novel nonexercise approach to estimate cardiorespiratory fitness in older adults by utilizing seismocardiography (SCG). This innovative technology harnesses the subtle vibrations produced by cardiac activity, enabling precise monitoring of cardiovascular function without the need for physical exertion. As aging populations increase globally, the demand for accessible and reliable methods to evaluate heart and lung fitness has never been higher, making this development not only timely but also revolutionary.

Cardiorespiratory fitness traditionally requires exercise testing, involving treadmill or bicycle protocols that may pose risks or be impractical for elderly individuals with limited mobility or chronic conditions. The novel system employing SCG bypasses these challenges, offering a safe and feasible alternative that significantly minimizes patient burden. SCG captures micro-vibrations generated by the heart during each beat using sensitive accelerometers placed on the chest, translating mechanical cardiac events into quantitative data reflective of cardiovascular performance.

The study, led by Sundberg, Gates, and Boraxbekk among others, meticulously validated the use of SCG signals against established measures of cardiorespiratory fitness, such as VO2 max testing, across a diverse cohort of older adults. Their results demonstrated remarkable correlation, confirming that SCG can serve as a reliable proxy for exercise-based evaluations. This breakthrough is poised to transform clinical practice by facilitating widespread cardiovascular screening and monitoring in geriatric populations without exposing them to physical strain.

One of the pivotal technological advances underpinning this approach is the enhancement of signal processing algorithms that can accurately decipher the complex mechanical patterns of heart activity from SCG data. These algorithms filter noise and artifacts, isolating key features such as timing intervals between cardiac events that are indicative of cardiac output and fitness levels. By employing machine learning techniques, the research team optimized predictive models that link SCG metrics with cardiorespiratory capacity.

Beyond the impressive technical accomplishments, the application of SCG for fitness estimation aligns perfectly with the principles of personalized medicine. By providing continuous, noninvasive monitoring methods, clinicians can tailor interventions and lifestyle recommendations based on real-time fitness metrics, facilitating proactive management of cardiovascular health. This could substantially reduce the incidence of cardiovascular events, improve quality of life, and enhance longevity in aging adults.

Importantly, this methodology opens new avenues for remote health monitoring. The compact sensors utilized for SCG are lightweight, unobtrusive, and capable of wireless transmission, enabling integration with mobile health platforms. This may empower elderly individuals to measure their cardiorespiratory fitness regularly from the comfort of their homes. Such democratization of health data can lead to earlier detection of functional decline, prompt clinical interventions, and reduced healthcare costs.

From a physiological perspective, seismocardiography reveals intricate interactions governing heart mechanics, including myocardial contractility and valve function, which are directly tied to oxygen delivery and utilization — the cornerstone of cardiorespiratory fitness. This depth of insight surpasses conventional pulse or blood pressure monitoring, offering a richer dataset for comprehensive cardiovascular assessment. The capacity to obtain these insights passively without exercise expends minimal energy, crucial for frail patients.

The research also emphasizes the feasibility of SCG in monitoring dynamic changes in fitness over time. Whereas exercise-based testing reflects a snapshot requiring considerable effort and clinical resources, SCG’s accessibility permits serial measurements that track progression or regression in cardiorespiratory health. This longitudinal view enhances clinicians’ ability to evaluate treatment efficacy and adjust care plans appropriately.

Moreover, SCG technology exemplifies the convergence of biomechanics, biomedical engineering, and data science, epitomizing modern healthcare innovation. The fusion of robust sensors with advanced computational methods has produced a tool that transcends standard diagnostic modalities, offering a more comprehensive and patient-friendly option. This interdisciplinary synergy highlights the potential for future wearable technologies to expand their role in chronic disease management.

Addressing limitations, the study carefully acknowledges challenges such as variability in SCG signal quality due to anatomical differences and external factors. However, by employing adaptive algorithms and calibration protocols, the researchers have mitigated many of these issues, ensuring consistent performance across diverse patient profiles. Ongoing refinements aim to further enhance accuracy and user-friendliness, making broad clinical adoption realistic.

The implications of this research extend beyond geriatric cardiology, potentially influencing rehabilitation programs, sports science, and preventive medicine. With further validation, SCG could monitor athletes’ fitness without exhaustive testing or assist in evaluating pulmonary function in respiratory diseases. Its versatility underscores the broad applicability of biomechanical sensing in health monitoring paradigms.

In conclusion, the integration of seismocardiography for the nonexercise estimation of cardiorespiratory fitness in older adults marks a paradigm shift in cardiovascular health assessment. By circumventing the constraints of traditional exercise testing, this technology enables safe, efficient, and insightful evaluations that can be performed repeatedly and remotely. As the elderly demographic surges worldwide, the deployment of such innovative methods will be pivotal in optimizing healthcare delivery and promoting healthier aging.

The promise of SCG transcends mere technological novelty; it represents a compassionate approach to health evaluation that respects the physical limitations and safety of vulnerable populations. Empowering healthcare providers with precise, noninvasive tools enriches clinical decision-making and enhances patient outcomes. Looking ahead, continued research and integration with digital health ecosystems will likely establish seismocardiography as a cornerstone in the management of cardiovascular fitness.

Ultimately, the study spearheaded by Sundberg and colleagues not only broadens scientific understanding but also provides a tangible blueprint for implementing cutting-edge sensing technologies in everyday clinical practice. The synergy of engineering excellence, clinical insight, and patient-centric design encapsulates the future of medical innovation — one that prioritizes accessibility, safety, and actionable intelligence for all.


Subject of Research: Nonexercise estimation of cardiorespiratory fitness in older adults using seismocardiography.

Article Title: Seismocardiography for nonexercise estimation of cardiorespiratory fitness in older adults.

Article References:
Sundberg, M., Gates, A.T., Boraxbekk, C.J., et al. Seismocardiography for nonexercise estimation of cardiorespiratory fitness in older adults. BMC Geriatr (2026). https://doi.org/10.1186/s12877-026-07771-6

Image Credits: AI Generated

  •  

Postnatal Bilirubin Rise Predicts Newborn Health

In the ever-evolving landscape of neonatal medicine, a groundbreaking study has reaffirmed the enduring predictive power of a critical early indicator: the rate at which total bilirubin levels rise postnatally. This development promises to refine the way clinicians anticipate and manage the risks associated with neonatal jaundice, a common yet potentially severe condition affecting newborns worldwide. For decades, the focus has been on absolute bilirubin levels at specific times, but the latest research shifts attention to the kinetics of bilirubin elevation, offering a more dynamic and perhaps more accurate prognostic tool.

Neonatal jaundice arises from elevated bilirubin in the bloodstream, a byproduct of the normal breakdown of red blood cells. While most cases resolve spontaneously without complication, a subset of infants develop dangerously high bilirubin levels, leading to a risk of bilirubin-induced neurological damage. Early identification of these infants is vital to intervene promptly, thus sparking intense research into more reliable predictive markers. The recent study not only confirms the relevance of the bilirubin rate of rise (ROR) but also presents robust data supporting its consistent predictive ability regardless of demographic or clinical variations.

The authors utilized comprehensive longitudinal data spanning several neonatal cohorts to characterize the nuanced relationship between bilirubin kinetics and subsequent clinical outcomes. The analysis employed advanced statistical modeling to parse out temporal trends from confounding variables, yielding more precise thresholds and timelines. These findings validate the utility of monitoring bilirubin’s ROR within the first hours to days after birth as an essential tool for neonatal surveillance and risk stratification, potentially more informative than single bilirubin measurements taken in isolation.

What distinguishes this work is its methodological rigor and expansive dataset that incorporates contemporary postnatal care realities, including early discharge practices and the prevalence of phototherapy. The investigators found that infants demonstrating a rapid bilirubin increase within the initial 24 to 48 hours required closer monitoring as they displayed a heightened probability of developing severe hyperbilirubinemia. Importantly, these infants could be identified before reaching conventionally alarming absolute bilirubin thresholds, which often occur later.

This focus on the dynamic parameter of bilirubin ROR complements traditional nomograms and guidelines currently used to guide clinical interventions such as phototherapy and exchange transfusions. By integrating rate of change data, clinicians are empowered with a forward-looking perspective reflective of the physiological trajectory rather than retrospective static points. This reframing facilitates earlier and more nuanced clinical decision-making, possibly translating to better neonatal outcomes and less invasive treatments.

Moreover, the findings address longstanding uncertainties about the variation in bilirubin metabolism among diverse populations. The authors report that the ROR metric remains consistently predictive across a spectrum of ethnic backgrounds, gestational ages, and birth weights. This universality enhances its appeal as a standard clinical parameter, offering equitable risk assessment where traditional bilirubin charts might underperform due to population biases.

The study further elaborates on the biochemical mechanisms underpinning bilirubin’s postnatal surge, connecting these processes to hepatic enzyme maturation and erythrocyte turnover rates. By contextualizing the observed clinical patterns with molecular insights, the research bridges the gap between laboratory science and bedside care. This integrative approach paves the way for future explorations targeting molecular interventions that could modulate bilirubin dynamics at an even earlier stage.

Critically, the reassessment of bilirubin kinetics arrives at a moment when neonatal care protocols face increasing pressures from early hospital discharges and outpatient jaundice surveillance challenges. The identification of reliable predictors that can be captured with non-invasive serum tests or even transcutaneous monitoring devices holds promise for streamlining care pathways. The emphasis on ROR could reduce reliance on repeated blood draws, alleviating infant distress and healthcare burdens alike.

Another important implication of this research lies in its potential to influence healthcare policy and parental counseling practices. Clear evidence supporting the significance of the bilirubin rate of rise equips healthcare providers with stronger tools to communicate risks effectively. This clarity is crucial to assuage parental anxieties and to promote adherence to follow-up schedules essential for timely interventions while avoiding unnecessary overtreatment.

The adoption of bilirubin ROR as a standard metric will, however, require integration into established workflows and electronic health record algorithms to automate risk alerting. The study’s supplementary data describes pilot implementations where this integration enhanced workflow efficiency and prompted earlier therapeutic action, underscoring the practical applicability of these findings beyond academic settings.

In conclusion, this pivotal research revitalizes the concept that not just the magnitude but the velocity of bilirubin increase after birth carries substantial prognostic weight. It suggests a paradigm shift towards kinetic monitoring as a cornerstone of neonatal jaundice management, urging continuous vigilance and adaptation of clinical protocols to include rate-focused assessments. Such a paradigm promises to safeguard vulnerable neonates worldwide from bilirubin-associated harm more effectively than ever before.

Future research is anticipated to delve deeper into the interplay of genetic factors affecting bilirubin metabolism with the observed kinetic patterns. Coupled with advancements in point-of-care devices, these insights might eventually enable personalized jaundice management, tailored precisely to each newborn’s metabolic profile and risk trajectory.

As the medical community embraces this enhanced predictive capacity, the ultimate beneficiaries will be the families and infants navigating the fragile early days of life. By preempting severe jaundice through refined monitoring of the bilirubin rate of rise, clinicians can deliver more timely care, minimize complications, and ensure that neonatal jaundice remains a manageable, rather than perilous, condition in modern pediatrics.


Subject of Research: Predictive metrics for neonatal jaundice severity focusing on the postnatal total bilirubin rate of rise.

Article Title: Predictive ability of postnatal total bilirubin rate of rise endures.

Article References:
Bhutani, V.K. Predictive ability of postnatal total bilirubin rate of rise endures. Pediatr Res (2026). https://doi.org/10.1038/s41390-026-05246-3

Image Credits: AI Generated

DOI: https://doi.org/10.1038/s41390-026-05246-3

  •  

New wearable glove lets people feel their data through heat and touch

Most of us experience data by looking at screens filled with charts, graphs and numbers. But what if you could actually feel your data instead of just seeing it? Researchers at the University of Adelaide have developed an experimental wearable glove called ThermoPhy that turns information into physical sensations. The glove uses heat, touch and […]

The post New wearable glove lets people feel their data through heat and touch appeared first on Knowridge Science Report.

  •  
  •  

Insights from 173,303 Pakistan Genome Analyses

A groundbreaking analysis of 173,303 exomes and genomes from the Pakistan Genome Resource (PGR) has unveiled compelling insights into the genetic architecture of human diseases and the therapeutic potential of loss-of-function (LoF) variants. This expansive dataset offers unprecedented resolution into homozygous loss-of-function (homLoF) mutations across diverse genes, providing critical human biological data that challenge and refine preclinical models. The ramifications for drug discovery are profound, underscoring the value of population-based genomic studies in elucidating gene function and safety profiles of potential therapeutics.

The PGR study corroborated previously established phenotypic associations for numerous homLoF variants. For instance, homozygous LoF mutations in LDLR were linked to hypercholesterolemia, while variants in LPL were associated with elevated triglyceride levels. Similarly, ANGPTL3 and APOB homLoF carriers exhibited notably reduced cholesterol and triglyceride profiles, whereas variants in ADCY3, POMC, MC4R, and MRAP2 were implicated in obesity phenotypes. These observations not only validate the penetrance of key metabolic genes but also affirm the rigorous phenotyping framework employed by the PGR.

Delving into therapeutically relevant homLoF variants, the study sheds light on the nuanced interplay between genotype and phenotype in neurodegeneration. LRRK2, a well-known protein kinase whose gain-of-function variants increase Parkinson’s disease risk, was examined in the context of loss-of-function. Notably, two PGR participants harboring homozygous LRRK2 pLoF variants exhibited early-stage kidney disease, a phenotype absent in heterozygous carriers. This human evidence mirrors renal dysfunction observed in LRRK2 knockout rodent models and preclinical trials with LRRK2 inhibitors in primates, suggesting a need for vigilant renal monitoring in therapeutic contexts targeting LRRK2.

In the realm of metabolic disease, a participant with a homLoF variant in SLC2A4—the gene encoding GLUT4—demonstrated type 2 diabetes, aligning with experimental models where GLUT4 deficiency impairs glucose homeostasis. Contrastingly, homLoF variants in DENND1B, previously linked to obesity and implicated in MC4R signaling pathways, did not confer obesity phenotypes in the cohort. This could indicate a lack of functional penetrance of DENND1B in human energy balance, differing substantially from prior murine models. Moreover, carriers of homLoF mutations in POMC, MC4R, and MRAP2 exhibited elevated BMI, reinforcing their contributory role to obesity.

Cardiovascular research insights emerged with RXFP1, a gene encoding a receptor extensively studied for its role in fertility, fibrosis, and cardiac function. Despite the gene’s pivotal role in murine reproductive and cardiovascular models—where its absence causes pronounced phenotypes—16 PGR individuals with RXFP1 homLoF variants spanned ages 30 to 73 years with no consistent deficits. Subtle associations with reduced waist-to-hip ratio and myocardial infarction risk were noted, and echocardiographic evaluations revealed mild variations in cardiac function among some homozygotes. Such findings suggest that the translational relevance of RXFP1 as a therapeutic target may be overestimated from rodent data, urging a recalibration of expectations for RXFP1 agonist therapies.

The hepatoprotective potential of CIDEB inhibition also gained support from PGR findings. Fourteen individuals homozygous for CIDEB loss-of-function variants displayed no liver disease, and burden analyses correlated CIDEB deficiency with decreased levels of liver enzymes ALT and AST and a reduced risk of non-alcoholic fatty liver disease. This human genetic evidence bolsters the rationale for targeting CIDEB therapeutically with siRNA or other modalities, highlighting an encouraging safety profile for chronic intervention.

Surprising evolutionary biology insights were uncovered in the reproductive gene PRDM9, a histone methyltransferase essential for meiotic recombination hotspot determination. While Prdm9 knockout mice exhibit infertility, PGR identified multiple human homLoF variant carriers of PRDM9 with proven fertility and successful reproduction. This stark species divergence reveals that PRDM9’s indispensability in meiosis is not conserved in humans, emphasizing the complexity of translating mouse genetic models to human biology.

Sensory gene analyses revealed functionally impactful homLoF mutations in TRPM8, an ion channel activated by cold stimuli. RBG cohort phenotyping demonstrated that carriers exhibited delayed cold-induced pain sensitivity and increased tolerance to cold-related discomfort, aligning with murine knockout models. Intriguingly, genome-wide association studies link TRPM8 variants to migraine susceptibility, positing TRPM8 inhibition as a promising therapeutic avenue. The PGR data indicate that complete loss of TRPM8 is generally well-tolerated, mitigating safety concerns for pharmacological antagonism targeting migraine prevention.

Collectively, these results highlight the critical importance of integrating large-scale human genomic data with functional assays to delineate gene-disease relationships and therapeutic potential. The PGR exemplifies how comprehensive population-based sequencing can validate, refine, or refute biological assumptions derived from animal models, fostering a more precise paradigm for drug target validation. By profiling rare homLoF variants and linking them with detailed phenotypic data, the study provides invaluable resources for developing safer, more effective genetic-driven therapies.

This study also accentuates the value of consanguineous populations, such as the Pakistani cohort, which enrich for homozygous rare variants and enable the detection of recessive phenotypes difficult to observe in outbred populations. Such datasets maximize the discovery power for identifying natural human knockouts, thereby informing on both the efficacy and potential deleterious effects of gene inactivation.

Beyond specific gene findings, the broader implication is a caution against uncritical extrapolation from model organisms to human physiology. While murine models remain indispensable, discrepancies evidenced in PRDM9 and RXFP1 underscore that human genetic data are indispensable for accurate target validation and safety assessment. This alignment between genotype, phenotype, and therapeutic action forms the cornerstone of precision medicine.

As the PGR and similar initiatives continue to expand, the integration of genomics with phenotypic and clinical data will catalyze a new era of therapeutic development truly grounded in human biology. The promise of harnessing human loss-of-function variants lies not only in uncovering disease mechanisms but also in guiding drug discovery toward targets with validated human safety and efficacy profiles, ultimately accelerating the path from bench to bedside.

This landmark study published in Nature offers a crucial template for leveraging population genomics in drug development, emphasizing the necessity of human genetic evidence to underpin the next generation of therapies. The insights gleaned provide a roadmap for more rational, genetics-informed clinical decision-making, heralding a future where personalized medicine and pharmacogenomics converge to transform healthcare.


Subject of Research: Genomic analysis of homozygous loss-of-function variants in the Pakistan Genome Resource and their implications for human disease and drug target validation.

Article Title: Analysis of 173,303 exomes and genomes in the Pakistan Genome Resource.

Article References:
Koch, C., Khalid, S., Khan, M.Z. et al. Analysis of 173,303 exomes and genomes in the Pakistan Genome Resource. Nature (2026). https://doi.org/10.1038/s41586-026-10667-5

Image Credits: AI Generated

DOI: https://doi.org/10.1038/s41586-026-10667-5

  •  

IRB Barcelona Leads MD4SB Project to Advance Dynamic Representation in Structural Biology

In the ever-evolving landscape of biomedical research, the advent of molecular dynamics simulations has heralded a new era of insight into the dynamic behavior of biological macromolecules. Yet, despite the immense volumes of data generated by these simulations, much remains untapped due to the lack of adequate infrastructure for storage, sharing, and reuse. Addressing this critical gap, the MD4SB (Molecular Dynamics for Structure-based Biology) project emerges as a visionary initiative poised to revolutionize how molecular dynamics data is integrated, managed, and exploited across Europe.

Set to launch in September 2026, MD4SB is a collaborative endeavor funded with €10 million under the Horizon Europe program and coordinated by the Institute for Research in Biomedicine (IRB Barcelona). The project unites 25 partners spanning eight countries, encompassing academic institutions, European research infrastructures, supercomputing centers, as well as biotech and pharmaceutical companies. By doing so, it offers a multidisciplinary approach aimed at transforming fragmented computational efforts into a coherent, accessible, and reusable resource for the scientific community.

At the core of MD4SB is the establishment of an innovative infrastructure designed to dynamically describe biological macromolecules through molecular dynamics data. Unlike traditional structural biology methods that primarily capture static snapshots of molecules, molecular dynamics simulations reveal the conformational flexibility and temporal evolution of proteins and nucleic acids. This dynamic information is crucial for fully understanding molecular function, interaction mechanisms, and especially drug binding processes, thus providing a more nuanced picture for drug discovery initiatives.

MD4SB builds on the foundations laid by the Molecular Dynamics Data Bank (MDDB), which pioneered a distributed platform adhering to the FAIR principles—making data Findable, Accessible, Interoperable, and Reusable. The project advances this concept by integrating molecular dynamics data within three major European Research Infrastructures: Instruct-ERIC, which specializes in structural biology; ELIXIR, focused on life sciences data management; and EU-OPENSCREEN ERIC, a chemical biology and compound screening infrastructure. This integration ensures that molecular dynamics data becomes a shared asset rather than an isolated entity confined to individual laboratories.

Leveraging the capabilities of Europe’s largest supercomputing centers—specifically the Barcelona Supercomputing Center (BSC-CNS), CINECA in Italy, and the Jülich Supercomputing Centre (JSC)—MD4SB provides the computational muscle necessary for processing, storing, and analyzing massive datasets. These centers, combined with emerging AI Factories, will enable cutting-edge analysis pipelines that augment traditional molecular dynamics approaches with artificial intelligence, thus enhancing the extraction of biologically meaningful patterns from complex simulations.

One of the landmark objectives of MD4SB is to catalyze early drug discovery by enabling scientists to visualize the dynamic movements of proteins and other biomolecules that are often invisible in static crystal structures. Molecular dynamics simulations can reveal transient binding pockets and allosteric sites, which are pivotal for designing new therapeutic compounds with higher specificity and efficacy. By facilitating access to these insights within existing infrastructures, MD4SB aims to speed up the identification of drug candidates and reduce costly experimental failures.

Industry engagement lies at the heart of MD4SB’s strategy. Leading pharmaceutical companies such as Almirall and Sanofi are involved as associate partners, providing critical feedback to ensure that the developed platform not only serves academic research but also aligns with industrial requirements. The involvement of Nostrum Biodiscovery—a biotech spin-off from IRB Barcelona and BSC-CNS—further exemplifies the project’s commitment to bridging the gap between fundamental research and commercial application by easing the transition of innovations into practical tools.

Dr. Modesto Orozco, coordinator of MD4SB and head of the Molecular Modelling and Bioinformatics laboratory at IRB Barcelona, highlights the transformative potential of this initiative: “For the first time on a European scale, MD4SB will merge structural biology, molecular dynamics, artificial intelligence, and drug discovery into a seamless ecosystem. Our vision is to democratize molecular dynamics, making it a common capability accessible to researchers across disciplines.”

The strategic approach of MD4SB entails the seamless coupling of three complementary research infrastructures, encompassing the full spectrum of biomedical research phases: from structural protein characterization, data stewardship and interoperability, to chemical biology screening for therapeutic potentials. This holistic integration enables unprecedented collaborative workflows, where data generated in one context can be analyzed, reanalyzed, and repurposed across diverse scientific domains.

Central to the success of MD4SB will be its adherence to data standards and protocols that guarantee FAIR compliance, ensuring that the vast repositories of molecular dynamics simulations remain discoverable and usable well beyond the lifespan of individual projects. This commitment is indispensable in preventing the loss of valuable computational endeavors, promoting reproducibility, and fostering innovation driven by shared resources.

By significantly expanding the accessibility and applications of molecular dynamics data, MD4SB promises to address a longstanding bottleneck in the life sciences: the disconnect between data generation and data reuse. The project envisions a future where high-quality, large-scale molecular simulations are no longer restricted to elite research groups but are a universally available asset, fueling discoveries in biology, chemistry, and medicine.

The timeline for MD4SB spans four years, during which it will not only develop and deploy the integration platform but also benchmark its utility through real-world case studies involving both academic and industry partners. Through this collaborative validation process, the project expects to establish best practices, refine analytical tools, and build a sustainable infrastructure that institutionalizes molecular dynamics as a pillar of modern biomedical research.

In conclusion, MD4SB heralds a transformative chapter for the European research ecosystem by converging molecular dynamics with cutting-edge computational resources and artificial intelligence within a unified framework. Its success will empower scientists to decode the dynamic complexity of biological molecules at an unprecedented scale, accelerating drug discovery pipelines and fostering interdisciplinary collaboration in the era of data-driven bioscience.


Subject of Research: Molecular dynamics integration and infrastructure for structure-based biology, drug discovery, and biomedical research.

Article Title: MD4SB: Revolutionizing Molecular Dynamics Data Sharing and Integration Across Europe

News Publication Date: June 17, 2026

Web References:

Image Credits: IRB Barcelona

Keywords: Molecular dynamics, Structural biology, Supercomputing, Artificial intelligence, Drug discovery, Data infrastructure, FAIR data, Biomedical research, European Research Infrastructures, Computational biology

  •  

PLSaoNET: Revolutionizing Industrial Network Training with a Deterministic Approach

In recent years, the evolution of industrial sensing technologies has been pivotal to the advancement of intelligent manufacturing systems. Among various approaches, artificial neural networks (ANNs) have garnered immense attention due to their remarkable capability to model complex data relationships. However, applying these networks effectively in real-world industrial environments remains a formidable challenge, primarily due to the noisy, nonlinear, and often limited datasets encountered in such settings. Recognizing these constraints, a team of researchers led by Professor Lanxiang Sun at the Shenyang Institute of Automation, Chinese Academy of Sciences, has forged a transformative approach. Their groundbreaking solution, known as the Partial Least Squares-assisted Optimization Network (PLSaoNET), promises to redefine the application of neural networks in industrial sensing by embedding statistical interpretability into the heart of deep learning models.

Traditional neural networks typically commence training through random initialization of weights—a process that, while standard, lacks any guiding framework grounded in data characteristics. This randomness poses inherent limitations, especially when the amount of training data is limited or when the data exhibits high noise levels and nonlinear relationships, both common in industrial scenarios. Such conditions often result in poor generalization and unstable predictive outcomes, thereby hindering practical deployment. The innovation from Professor Sun’s team circumvents these issues through a statistical method known as Partial Least Squares (PLS), a classic tool renowned for its interpretability and robustness in linear regression tasks.

PLS works by extracting latent variables that capture the fundamental relationships between independent variables (input features) and dependent variables (output targets), offering a transparent statistical framework. While PLS excels in linear modeling, it lacks the capability to model complex nonlinear dynamics. The research team ingeniously leveraged the strengths of PLS by integrating its solutions as the initial conditions within a neural network architecture. Specifically, the number of PLS latent variables dictates the number of neurons in the network’s hidden layer, and the PLS-derived weight matrix initializes the neural connections. This initialization endows the neural network with a statistically meaningful starting point, effectively eliminating the guesswork inherent in random weight assignments.

Such a well-founded initialization transforms the learning process from an unfocused blind search into a systematic refinement of the PLS solution, integrating nonlinear modeling capabilities while preserving interpretability. This fusion of statistical rigor and deep learning adaptability addresses one of the fundamental bottlenecks in industrial data modeling, enabling the network to capture both the global trends identified by PLS and the nuanced nonlinear interactions vital for accurate predictions.

Moreover, industrial datasets frequently suffer from uneven label distributions, posing significant challenges during the training of neural networks using stochastic gradient descent. Fluctuations in loss values caused by biased mini-batch samples can lead to instability and degrade the overall learning process. To counter this, the researchers implemented a stratified sampling-based training strategy. In this approach, the entire dataset is divided into strata based on label value ranges, ensuring that each mini-batch during training samples from each stratum proportionally. This methodology smooths gradient updates, fortifying the network’s robustness against skewed data distributions and enhancing training stability substantially.

Professor Sun has emphasized that the primary motivation behind PLSaoNET is not to pursue architectural complexity but to advocate for models that produce stable, reliable outputs even when faced with small, noisy datasets that typify industrial environments. By embedding PLS’s statistical solutions into neural network training, the model’s learning trajectory gains a trustworthy, transparent foundation from which to build more complex representations.

To validate the efficacy of PLSaoNET, the research team conducted comprehensive experiments in two realistic industrial applications: the online monitoring of iron ore concentrate slurry grade using laser-induced breakdown spectroscopy (LIBS), and diesel fuel quality assessment with near-infrared (NIR) spectroscopy. Both cases involve complex spectral data with significant noise and nonlinear characteristics—ideal testbeds to showcase the robustness of PLSaoNET. Results consistently demonstrated superior prediction accuracy and generalization capabilities over traditional PLS regression and conventionally initialized backpropagation neural networks.

A particularly revealing insight emerged from the visualization and analysis of hidden layer weights in the LIBS slurry model. While the PLS model alone lacked precision, the dominant latent variables it extracted aligned clearly with known spectral emission lines from key mineral elements like silicon, magnesium, and iron, reflecting true physical relevance. In contrast, networks initialized randomly exhibited neuron weights that failed to selectively identify meaningful spectral features, resulting in noisy, uninterpretable representations. The PLSaoNET model, however, preserved the interpretability inherent to PLS by focusing attention on these dominant spectral features while simultaneously allowing fine-tuned retraining that accentuated secondary information related to elements like calcium and aluminum. This balance effectively suppresses overfitting and elevates model reliability.

Not content with theoretical validation alone, the team successfully deployed PLSaoNET within a live LIBS slurry analyzer at a mineral processing plant for real-time iron ore concentrate grade monitoring. This real-world application underscores PLSaoNET’s practical value in lowering the barriers to widespread adoption of artificial neural networks in industrial contexts. By anchoring the initial network parameters in statistically meaningful solutions and employing thoughtful training strategies, PLSaoNET represents a crucial step toward integrating cutting-edge AI models into complex, noise-prone industrial environments where data scarcity and variability have historically impeded progress.

Looking beyond its immediate applications, PLSaoNET delivers a broader paradigm shift, suggesting that harmonizing classical statistical techniques with modern deep learning can unlock new frontiers in intelligent industrial sensing. As manufacturing systems increasingly embrace digital transformation, methods like PLSaoNET that offer interpretability, stability, and adaptability will become indispensable tools for building resilient, data-driven infrastructures.

In conclusion, the work by Professor Lanxiang Sun and colleagues embodies a fusion of statistical principled approaches and adaptive machine learning techniques, producing an ANN model that addresses longstanding challenges in industrial data analysis. With its innovative PLS-based initialization and stratified sampling training, PLSaoNET not only enhances predictive performance but also paves the way for more interpretable, reliable AI systems in industrial manufacturing. As industries worldwide continue to seek intelligent sensing solutions that function robustly under real-world constraints, PLSaoNET stands out as a promising, practical breakthrough.


Subject of Research: Advanced artificial neural network design for improved industrial sensing under constraints of small, noisy, and nonlinear datasets.

Article Title: PLSaoNET: A Generalized ANN Model Under PLS Statistical Constraints for Industrial Sensing

News Publication Date: 5-May-2026

Web References:
http://dx.doi.org/10.1016/j.eng.2026.01.032

Image Credits: Lanxiang Sun


Keywords

Industrial sensing, artificial neural networks, partial least squares, PLSaoNET, stratified sampling, nonlinear modeling, intelligent manufacturing, spectral analysis, laser-induced breakdown spectroscopy, near-infrared spectroscopy, deep learning initialization, model interpretability, industrial data analytics

  •  

Synthetic Data: Challenges and Insights in Gastrointestinal Medicine

In recent years, the advent of artificial intelligence (AI) has reshaped the landscape of medical research and clinical practice, ushering in an era where machines replicate—and increasingly surpass—human cognitive abilities in various domains. Among the most intriguing developments is the capability of AI systems to assimilate vast troves of real-world data, allowing algorithms to accurately recognize complex patterns within clinical environments. This includes the identification of intricate pathological features, accurate labeling of disease states, and support in making critical healthcare decisions. Central to this revolution is the notion of synthetic data generation, a cutting-edge technology poised to tackle longstanding barriers impeding medical innovation, particularly in the realm of gastrointestinal (GI) medicine.

Synthetic data generation refers to the process through which artificial datasets are created by AI algorithms, mimicking the statistical properties and underlying structures of real-world clinical data without exposing sensitive patient information. This technique promises to solve two critical challenges: preserving patient privacy and reducing the often exorbitant costs and logistical complexities associated with curating and annotating healthcare datasets. By producing realistic, unbiased, and privacy-preserving synthetic data, researchers and clinicians could unlock unprecedented opportunities for training sophisticated AI models and improving clinical decision support systems tailored to gastrointestinal health.

In the context of gastrointestinal diseases, where early detection and precise diagnosis are often paramount, synthetic data offers a transformative potential. GI disorders encompass a broad spectrum of conditions, such as inflammatory bowel disease, colorectal cancer, and liver cirrhosis, each demanding nuanced understanding and timely intervention. Traditional approaches to gathering data for AI training encounter significant roadblocks, including patient consent restrictions, heterogeneous data quality, and the inherent rarity of some disease presentations. Generating synthetic equivalents of such data not only bridges these gaps but also enables the continuous refinement of diagnostic algorithms through virtually unlimited and diverse data augmentation.

From a technical standpoint, generating high-fidelity synthetic GI data entails leveraging advanced generative models, such as Generative Adversarial Networks (GANs), Variational Autoencoders (VAEs), and diffusion models. GANs, for example, pit two neural networks against each other in a zero-sum game—the generator strives to create realistic data indistinguishable from original datasets, while the discriminator attempts to detect artificiality. This adversarial process gradually improves the quality of synthetic outputs, rendering them increasingly suitable for downstream clinical applications. However, the GI domain presents unique challenges due to the complexity and variability inherent in endoscopic images, histopathological slides, and multi-omics data.

A profound technical hurdle lies in ensuring that synthetic gastrointestinal datasets retain clinical validity and biological relevance. Unlike generic image synthesis, medical data synthesis must preserve subtle yet critical diagnostic details, such as mucosal texture alterations, microvascular patterns, and lesion morphology. Obtaining this level of fidelity mandates incorporating domain-specific constraints and annotation-guided synthesis protocols. Furthermore, the synthetic data must demonstrate robustness to common sources of variability: differences in imaging devices, procedural inconsistencies, and patient-specific anatomical variations. Without these safeguards, downstream AI models risk being trained on data that poorly represents true clinical scenarios and yield unreliable predictions.

Another pivotal aspect of using synthetic data in gastrointestinal medicine is its contribution to overcoming privacy legislation hurdles like HIPAA or GDPR. Traditional anonymization methods risk compromising data utility or may be insufficient in preventing re-identification attacks. Conversely, by training generative models on real patient data and producing artificial yet representative datasets, synthetic data generation preserves privacy inherently, as no direct personal identifiers or actual patient samples are included. This feature fosters a more open collaboration across institutions and research groups, catalyzing the development of multipurpose AI-driven tools capable of detecting early-stage GI malignancies, monitoring disease progression, and predicting therapeutic responses.

Despite the tremendous promise of synthetic data, translating this innovation from research laboratories to clinical workflows demands meticulous validation and regulatory compliance. Clinical decision support systems powered by synthetic data-driven AI must undergo rigorous testing against gold standards to verify their safety and effectiveness. Interpretability also remains a significant concern, as clinicians must trust and understand AI recommendations to incorporate them confidently in patient care. Efforts to integrate synthetic data into regulatory frameworks, combined with transparent reporting of generative model performance metrics, will be crucial to achieving widespread clinical acceptance.

Synthetic data not only enhances diagnostic AI but opens new frontiers for medical education and professional training in gastroenterology. Trainees often face limited exposure to rare or complex cases, which impedes skill acquisition and confidence-building. High-quality synthetic datasets can provide diverse and unlimited case simulations, including pathologies that might be encountered infrequently but require high diagnostic acumen. This approach supports immersive, hands-on learning without compromising patient safety or privacy, helping to shape the next generation of gastroenterologists equipped with AI-enhanced diagnostic abilities.

Moreover, the adoption of synthetic data dovetails with the broader trend of precision medicine and personalized healthcare. By complementing real patient data with synthetic counterparts generated under controlled conditions, AI models can better capture the heterogeneity of gastrointestinal diseases, including genetic, environmental and lifestyle factors. This richer informational substrate empowers clinicians to tailor interventions more precisely, leading to improved patient outcomes, reduced adverse effects, and optimized resource utilization. Synthetic data thus acts as a cornerstone technology in enabling AI systems to realize their full potential in individualized care pathways.

Nevertheless, emerging research highlights several critical challenges that warrant attention for synthetic data to reach its full utility. One major issue is preventing the inadvertent introduction of bias during data synthesis, which could propagate and amplify healthcare disparities if not carefully addressed. Ensuring equitable representation across demographics, comorbidities, and clinical settings is imperative. Additionally, synthetic data generation must grapple with the potential for overfitting or hallucination, where models produce plausible yet clinically inaccurate artifacts. Developing rigorous validation metrics, cross-institutional benchmarking, and consensus guidelines will be necessary steps to mitigate these risks effectively.

In parallel, fostering multidisciplinary collaboration among clinicians, computer scientists, data privacy experts, and ethicists will accelerate the adoption of synthetic data paradigms. This convergence of expertise will enable the design of sophisticated pipelines that uphold ethical standards, comply with legal mandates, and optimize clinical relevance. It will also stimulate innovation in enhancing generative model architectures, integrating multi-modal data sources, and streamlining model deployment within real-time endoscopy or pathology workflows.

Reflecting on the current trajectory, the era of synthetic data in gastrointestinal medicine signals a paradigm shift from data scarcity and privacy constraints toward unprecedented data abundance and accessibility. As AI algorithms evolve and healthcare systems embrace digital transformation, synthetic data will be pivotal in democratizing access to high-quality datasets, unleashing creativity in algorithm development, and fostering robust, scalable solutions for early disease detection and personalized treatment. The implications extend beyond GI diseases, serving as a blueprint for AI-driven clinical innovation across medical specialties.

In conclusion, the synthesis of artificial yet clinically meaningful datasets represents one of the most promising frontiers in AI and medicine. While significant challenges remain—technical, ethical, and regulatory—the momentum and early successes within gastrointestinal medicine are compelling. Future research should focus on refining generative approaches, validating AI models trained on synthetic data across diverse populations, and embedding these technologies seamlessly into clinical practice. Ultimately, the judicious application of synthetic data holds the key to unlocking the full transformative power of artificial intelligence for improved patient care and health system efficiency worldwide.


Subject of Research: Synthetic data generation and its application in gastrointestinal medicine.

Article Title: Synthetic data generation: challenges and perspectives for gastrointestinal medicine.

Article References:
Gatoula, P., Iakovidis, D.K., Diamantis, D.E. et al. Synthetic data generation: challenges and perspectives for gastrointestinal medicine. Nat Rev Gastroenterol Hepatol (2026). https://doi.org/10.1038/s41575-026-01216-6

Image Credits: AI Generated

  •  

Consumo de energia dos centros de dados vai triplicar até 2030. China prepara-se para liderar o mercado

Um relatório da Global Data prevê que a China vai ultrapassar os Estados Unidos na corrida dos centros de dados. Segundo os especialistas, a energia vai tornar-se o novo “ouro digital”.

The post Consumo de energia dos centros de dados vai triplicar até 2030. China prepara-se para liderar o mercado appeared first on Tek Notícias.

  •  

Scientists Develop New Technique to Protect Privacy of Electrocardiogram Data

In a groundbreaking development addressing the burgeoning concern of privacy in modern medical technology, researchers at the University of Kansas have unveiled a transformative artificial intelligence (AI) model designed specifically to safeguard sensitive biometric data embedded within electrocardiograms (ECGs). This innovation is poised to reshape how medical institutions share and analyze vital cardiovascular data without compromising patient confidentiality. Electrocardiograms have long been renowned for their role in capturing the heart’s electrical activity to diagnose and monitor cardiac health; however, as AI integration deepens, these signals inadvertently reveal more than just clinical information — exposing personal attributes such as sex, age, race, and even uniquely identifiable biometric markers.

The research team at Kansas, led by doctoral candidate Fairuz Shadmani Shishir in collaboration with the KU Medical Center, has pioneered the privacy-preserving variational autoencoder (PP-VAE). This novel AI architecture is specially engineered to retain the clinical utility of ECG data while systematically obfuscating sensitive biometric features that might otherwise be inferred through advanced AI analysis. The dual objective of PP-VAE is both technically sophisticated and ethically imperative, ensuring that predictive diagnostic accuracy remains uncompromised while minimizing the risk of privacy breaches inherent in sharing raw biomedical signals.

Electrocardiograms, traditionally viewed as a straightforward diagnostic tool, have grown in complexity with modern AI techniques that can extrapolate a multiplicity of patient traits beyond the cardiovascular parameters they were designed to measure. Shishir notes that these advanced systems can uncover “soft biometrics” such as demographic information, which raises pressing data governance and patient privacy challenges. By developing PP-VAE, the researchers aim to reimagine ECG data processing whereby sensitive attributes are masked without degrading the signal quality necessary for important medical prognoses, such as identifying patients at risk of left ventricular ejection fraction (LVEF) abnormalities, a critical indicator linked to heart failure and mortality risk.

The technical underpinning of PP-VAE involves training independent convolutional neural networks to disentangle and suppress identifiable biometric markers while preserving clinically relevant features within the ECG signal. This balancing act required careful engineering to ensure that the encoded ECG data remained diagnostically rich, capable of supporting predictions related to conditions such as left ventricular hypertrophy and forecasting five-year mortality risk. The research showcased that their method consistently outperformed or competed with other state-of-the-art AI models, marking a significant stride in machine learning’s ability to harmonize privacy with clinical efficacy.

Importance of such privacy-preserving strategies becomes particularly clear against the backdrop of the healthcare industry’s increasing reliance on data sharing for collaborative research, AI model development, and multi-institutional patient care coordination. The KU team articulates that unrestricted data sharing without privacy controls introduces tangible risk vectors for patient re-identification and misuse. PP-VAE proposes a scalable approach toward enabling secure exchange of ECG data, thus fostering innovation and improving medical outcomes while staunchly protecting individual privacy rights.

This research also touches on the profound issue of bias within AI-driven medical diagnostics, which has historically contributed to disparities in healthcare delivery among marginalized populations. The team consciously incorporated balanced datasets reflective of gender and racial diversity in their model training to mitigate bias and improve generalized performance across varied demographic groups. While initial validations were primarily conducted using data from KU Medical Center and publicly available datasets, future work is projected to expand this cross-regional training, enhancing the robustness and impartiality of the model when applied globally.

Another compelling facet of this breakthrough is the planned public release of the PP-VAE model, reflecting the researchers’ commitment to transparency, collaboration, and democratization of AI tools in medicine. By allowing institutions worldwide to access and further refine the model with local datasets, the innovation promises to catalyze a new era of secure, privacy-conscious healthcare analytics. Adoption of PP-VAE could alleviate prevalent trust issues among patients concerned about the confidentiality of their biometric health information—a critical barrier to broader acceptance of AI-driven healthcare technologies.

Furthermore, the researchers discuss the broader implications for data-driven diagnosis, illustrating how balancing the protection of sensitive attributes with clinical utility could become a standard principle in biomedical AI applications beyond cardiology. This approach offers a blueprint for addressing ethical and privacy challenges that increasingly pervade the intersection of health data science and artificial intelligence.

The University of Kansas team’s work is also distinguished by its multidisciplinary nature, featuring collaboration between electrical engineering, computer science, and cardiovascular medicine experts. Such an integrated approach enabled the synthesis of advanced machine learning expertise with intimate clinical insight, culminating in a pragmatic solution tailored precisely to real-world healthcare needs.

This pioneering study was recently published in Scientific Reports, showcasing detailed methodology, experimental evaluations, and comparative performance analyses that underscore the efficacy and potential transformative impact of PP-VAE. Supported by the American Heart Association, this research is an exemplar of innovative technological stewardship addressing one of the most pressing challenges in digital health.

As AI continues to proliferate across medical diagnostics, models like PP-VAE will undeniably play a critical role in shaping ethical frameworks and technological architectures for future patient data management. By protecting sensitive biometric identifiers embedded in ECG data, the model not only preserves patient autonomy but also enhances the potential for AI-driven insights to be safely harnessed for better clinical outcomes worldwide.

The journey ahead involves validating and deploying this technology in diverse healthcare environments globally to ensure scalability, efficacy, and fairness remain intact as data heterogeneity increases. Yet, with the foundational work from the University of Kansas, a robust and privacy-conscious approach to ECG analysis and beyond appears well within reach, heralding a new era of secure AI-driven cardiovascular care.


Subject of Research: Privacy-preserving AI models for electrocardiogram data analysis
Article Title: Safeguarding Patient Privacy in Electrocardiogram Analysis with AI-driven Models
Web References: Scientific Reports Article
Image Credits: Fairuz Shadmani Shishir / University of Kansas

Keywords

Privacy-preserving AI, Electrocardiogram (ECG), Variational Autoencoder, Convolutional Neural Networks, Biomedical Data Security, Cardiovascular Diagnostics, Left Ventricular Ejection Fraction, Patient Privacy, Machine Learning Bias, Medical Data Sharing, Artificial Intelligence in Healthcare, Clinical Decision Support

  •  

Apenas 14% das empresas estão preparadas para tirar máximo partido da cloud na era da IA

Num momento em que quase todos reconhecem a cloud como peça central das estratégias digitais, um novo estudo aponta uma contradição relevante: o investimento e a ambição em torno da IA estão a crescer mais depressa do que a maturidade tecnológica necessária para os suportar.

The post Apenas 14% das empresas estão preparadas para tirar máximo partido da cloud na era da IA appeared first on Tek Notícias.

  •  

Earthquake Experts Modeled 1,000 Years of Activity in California—What They Found Now Has Scientists Concerned

California could be due for a major earthquake in the near future, according to concerning new models based on data comprising 1,000 years of quake activity on the West Coast.

According to recent findings, tectonic stress has quietly been building in California to levels not seen since the last major earthquake in the region, which bore a magnitude of 7.9 and struck the West Coast nearly 170 years ago.

That event, known as the Fort Tejon earthquake, affected the greater Los Angeles area, and since the time of those historic rumblings, researchers have grown increasingly concerned about a period of seismic silence that could point to the likelihood of an event of similar magnitude at some point in the future.

The potentially concerning new forecast was detailed in a recent study by an international team of researchers led by Dr. Liliane Burkhard of the Division of Space Research and Planetary Sciences (WP) at the Physics Institute of the University of Bern, which focused on historic earthquake data as a means of gauging current stress loading at Cajon Pass.

The study, published in the Journal of Geophysical Research: Solid Earth, indicates tectonic stress levels that are now believed to exceed the highest seen during the years the team surveyed.

The “Earthquake Gate” at Cajon Pass

The researchers aimed to investigate stress that has slowly built along the San Andreas and San Jacinto faults and incorporated what they likened to an “earthquake gate” at Cajon Pass, which, in their models, functioned like a point of control that governed the size of earthquakes and whether they could spread to both systems.

For their research, they used a four-dimensional earthquake cycle model that allowed them to replicate certain processes both in spatial dimensions and across time.

Using a millennium of reconstructed earthquake data from the region based on geological information such as radiocarbon dates, unusual events recorded in dendrochronological data (i.e., information obtained from tree rings), and historical information sources, the team gave this to the model they devised.

Dr. Burkhard said the team’s simulation offered them a unique opportunity to better understand the ways stresses in the fault system build up over long periods of several centuries.

“By running the earthquake history of Southern California as a simulation, we can estimate the extent to which the fault system is already under stress today,” Dr. Burkhard said. The results of those simulations weren’t particularly promising either: according to Burkhard, current stress levels in the region are the highest they have been in 1,000 years, based on the data.

Concerning New Earthquake Data

The team also identified significant new information regarding the function of the so-called “earthquake gate” at Cajon Pass.

“The earthquake gate concept captures something important about how fault junctions work,” Burkhard said in a recent statement. “Cajon Pass doesn’t simply block or channel earthquakes: It responds to stress conditions, and those conditions change over centuries.”

Not only this, but Burkhard and her team also determined that a key element to these quakes involves not only the level of stress that accumulates at a single fault, but perhaps more significantly, the way stress between two systems can align. This is because, as the stress across a pair of faults rises together over longer periods, this appears to be most conducive to a large joint rupture comparable to the 1857 Fort Tejon earthquake.

Conversely, if stress levels are not in concert as they evolve, the team determined that this causes quakes that probably will not propagate beyond the junction.

In short, a more severe earthquake event today would entail a joint rupture that crosses the Cajon Pass, as opposed to one constrained either to the San Andreas or the San Jacinto Fault alone. Should such an event occur, it would likely impact one of the largest population centers, as well as a crucial infrastructure system that supplies energy and transportation to surrounding areas.

For Burkhard, “The question of when and how the next major earthquake will occur in this region is one of the most pressing problems in applied geoscience.” Based on the team’s findings, they say that their new modeling hopes to provide a much more complete picture of the science behind the factors that could lead to a major quake—conditions that could apply equally to other parts of the world as they do to California.

Burkhard adds that her team’s study is not intended merely as a prediction for when the next major earthquake could potentially occur, but also as a means of preparing for future quakes and mitigating their effects.

“What we can say is that the system is critically stressed and that physics-based models like ours give a clearer picture of the range of scenarios we should be prepared for,” Burkhard says. “This information is important for hazard assessment, infrastructure planning, and emergency preparedness.”

The team’s study, “Cajon Pass and the Southern San Andreas Fault System: Earthquake Cycle Stress Accumulation and Present‐Day Loading,” appeared in the Journal of Geophysical Research: Solid Earth.

Micah Hanks is the Editor-in-Chief and Co-Founder of The Debrief. A longtime reporter on science, defense, and technology with a focus on space and astronomy, he can be reached at micah@thedebrief.org. Follow him on X @MicahHanks, and at micahhanks.com.

  •  

A New View of the Spectroscopic Universe

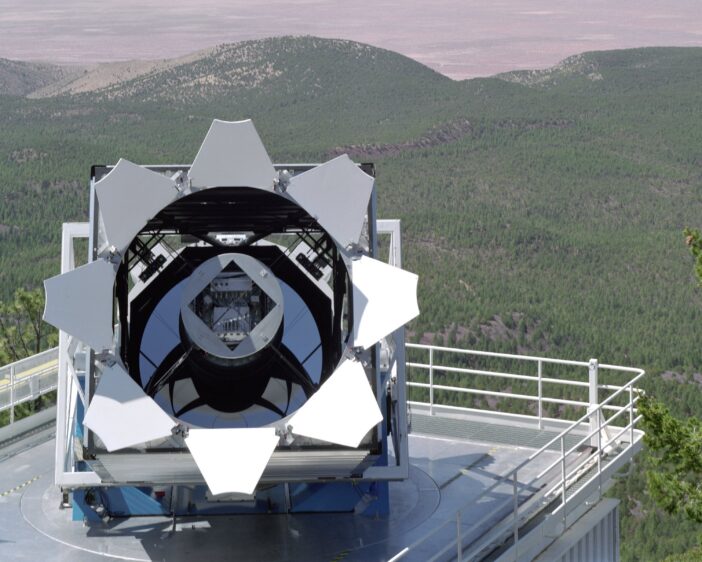
A photograph of a telescope opened at dusk.

The Sloan Digital Sky Survey (SDSS) fundamentally changed the way modern astronomy research is done. This “grand and bold thing” is not frozen in a museum exhibit, however: instead, the SDSS telescopes and team have continued to iterate. The collaboration recently described the fifth generation of this groundbreaking survey in The Astronomical Journal.

Roots in History

Astronomy is now without question a “big data” science. While a lucky few researchers still occasionally travel to distant mountaintops to sojourn with the stars, most astronomers who can describe their work as “observational” rarely ever leave their laptops. Petabytes of historical data, including images, spectra, enormous simulation archives, and more, are available the instant one’s fingers touch a keyboard. As a result, the speed of discovery has increased exponentially, and the barriers to cutting-edge research have dramatically shrunk.

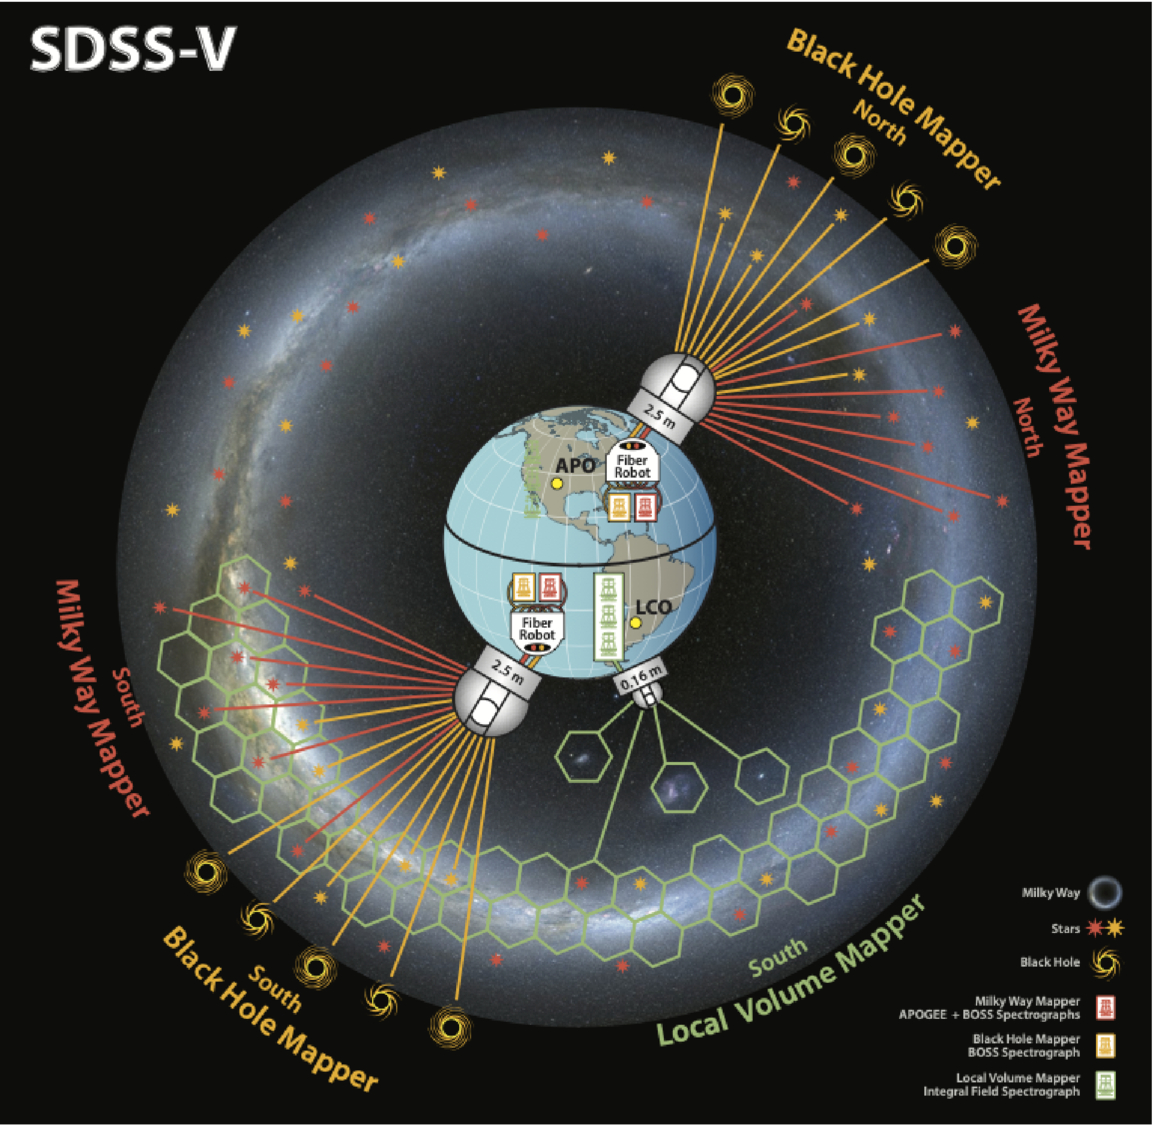
A cartoon of the Earth with three telescopes roughly geographically distributed as they are for the SDSS V survey.

A schematic of the SDSS-V survey facilities and targets. Click to enlarge. [Kollmeier et al. 2026]

While no paradigm shift can be pinned to an exact date, astronomy’s turn towards the data-rich era arguably began in 1998 when SDSS first began collecting data. This was among the first of the “industrial” surveys that observed large swaths of the sky with electronic detectors and used automated pipelines for bulk data processing. In the years since, larger robotic telescopes have begun to mimic the SDSS strategy of “mowing the sky.” The latest of these successors, which itself may usher in another paradigm shift in terms of data volume and availability, is the soon-to-begin Legacy Survey of Space and Time at the Vera C. Rubin Observatory.

While SDSS’s twin 2.5-meter telescopes (one in New Mexico and one in Chile, allowing the survey to observe the entire sky) are dwarfed by Rubin’s 8-meter mirror, there is still thrilling science to be done with these moderate-sized observatories. This is especially true after a series of upgrades to the spectrographs and thanks to a deep expertise in not only survey-style science, but also in project management and survey planning. In 2021, in the middle of COVID-19 delays and distancing requirements, the team began upgrades to their existing facilities and construction of a brand new telescope to kick off the latest survey, SDSS-V.

The Next Generation

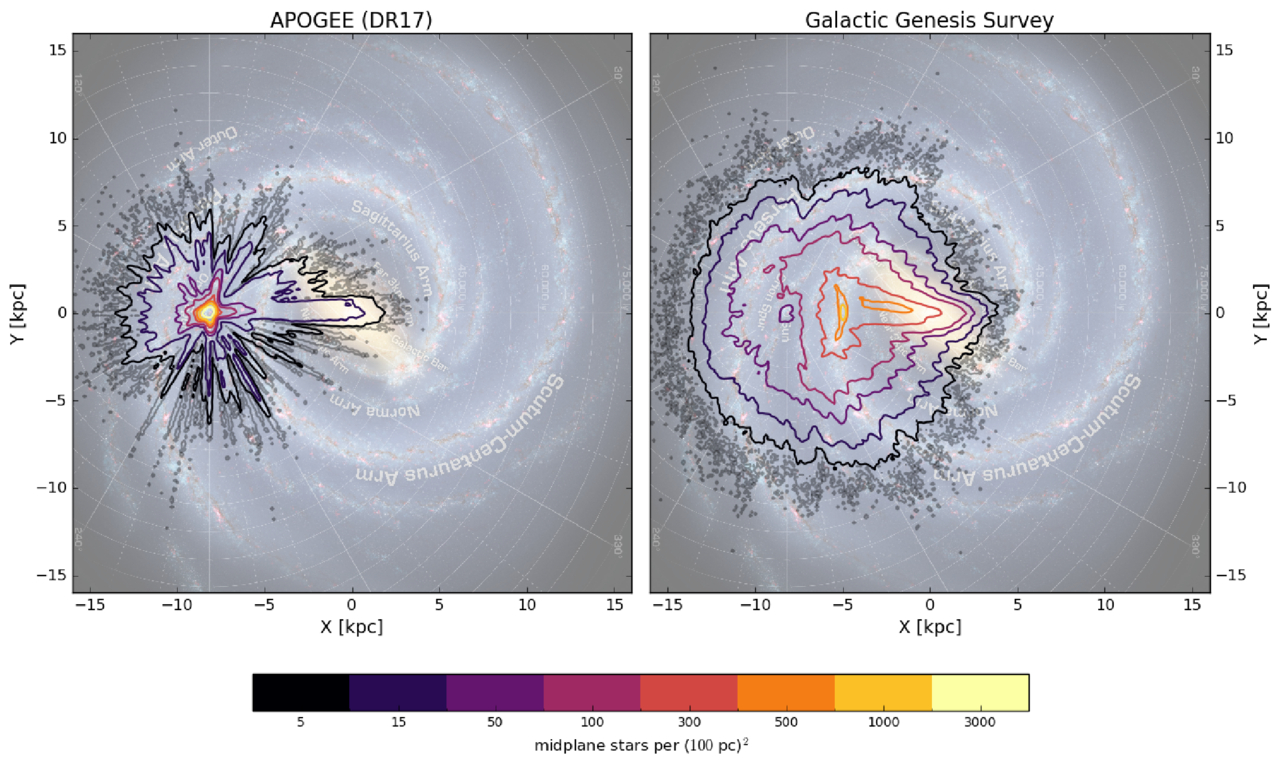
A two-panel figure showing top-down views of the milky way galaxy with different density contours overlaid.

The density of target stars for the SDSS-V survey compared to a previous spectroscopic survey. Click to enlarge. [Kollmeier et al. 2026]

In a wide-ranging publication that references not only astronomy research articles but also Plato, the Bhagavad Gita, an Egyptian tomb, and Tolstoy, the large collaboration describes that this latest survey is divided into three parts: the Milky Way Mapper, the Black Hole Mapper, and the Local Volume Mapper. The preexisting telescopes, which are outfitted with hundreds of tiny robots that can swivel fiber optic cables into place to collect spectra of up to 500 objects at a time, will handle the first two of these “mappers.” A brand-new facility in Chile that’s specifically designed to map the structure of nearby gas will handle the last mapper. Instead of aiming the fibers at a known star or galaxy, this telescope will instead collect a spectrum for every point across an area the size of the full Moon with every exposure.

By the end of the survey, SDSS-V will have collected optical and near-infrared spectra for roughly 6 million objects spread across the whole sky, as well as time-series spectra from about a million of these sources. This dataset, which is unprecedented in both its spatial and temporal coverage, will allow researchers to probe questions ranging from how quasars evolve over time to how commonly young stars have brown-dwarf companions. Long since SDSS initiated the era of industrial survey astronomy, this latest publication shows how the survey continues to lead the way.

Citation

“Sloan Digital Sky Survey. V. Pioneering Panoptic Spectroscopy,” Juna A. Kollmeier et al 2026 AJ 171 52. doi:10.3847/1538-3881/ae0576

The post A New View of the Spectroscopic Universe appeared first on AAS Nova.

  •  

Minding the Gaps in Solar Wind Data

solar wind

Spacecraft scattered throughout the solar system keep tabs on the solar wind, but the measurements are dotted with data gaps. How can scientists prevent these gaps from biasing their studies of the solar wind?

Sampling the Solar Wind

intracluster medium

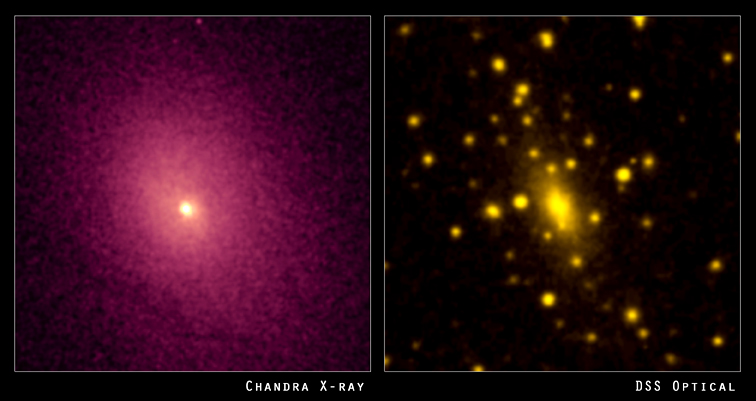
Left: the distribution of hot gas between the galaxies in the cluster Abell 2029. Right: the visible light from the galaxies in the cluster. [X-ray: NASA/CXC/UCI/A.Lewis et al. Optical: Pal.Obs. DSS]

The solar wind is a tenuous, fast-moving, turbulent plasma that constantly streams out from the Sun. Studying the solar wind is important for understanding how potentially damaging space weather events like coronal mass ejections travel through the solar system. Solar wind studies also have far-reaching implications, since solar-wind-like plasmas exist throughout the universe, such as in the sparse medium between galaxies in a cluster.

Luckily, there are many spacecraft that sample the solar wind from various locations within our solar system. Unluckily, many of these spacecraft do not continuously monitor the solar wind. For example, when a spacecraft orbiting a planet dips into the planet’s atmosphere, this detour creates an hours-long gap in solar wind monitoring.

The Impact of Data Gaps

How do these data gaps affect studies of the solar wind? In a recent research article, Daniel Wrench and Tulasi Parashar (Victoria University of Wellington) approached this question in terms of how gaps affect the structure function: a mathematical description of how the solar wind fluctuates over different length or time scales.

Wrench and Parashar introduced random artificial gaps into data from the Parker Solar Probe, which monitors the solar wind continuously, and compared the structure functions calculated from the continuous and interrupted data sets. They used the difference between the true structure function — calculated from the continuous data set — and the structure functions from the artificially gapped data sets to develop a correction factor.

bar plot of correction method performance

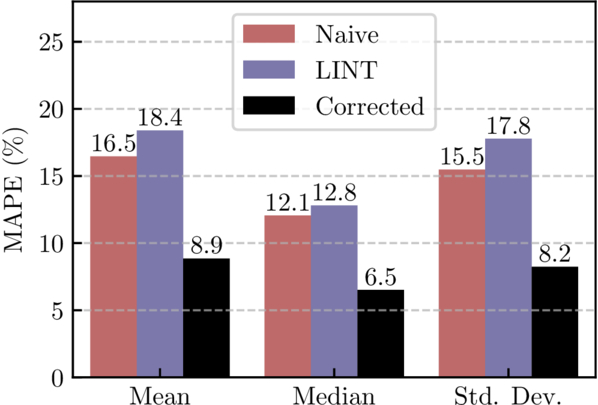
Performance of the correction factor method (black) compared to the uncorrected, gapped data (red) or gaps filled using linear interpolation (blue). MAPE is the mean absolute percentage error. [Wrench & Parashar 2025]

The team then tested their correction factor using data from the Wind spacecraft, which continuously monitors the solar wind from the L1 Lagrange point. The team calculated the structure function from 1) the continuous data set, 2) the artificially gapped data, 3) the gapped data with linear interpolation used to fill the gaps, and 4) the gapped data with the correction factor applied. This test showed that the correction factor performs better than other commonly used gap-handling methods, such as linear interpolation, which can systematically underestimate the structure function. Using the correction factor, the error in the structure function remained below 50% even when 95% of the data were missing.
plot of structure function from Voyager 1 data

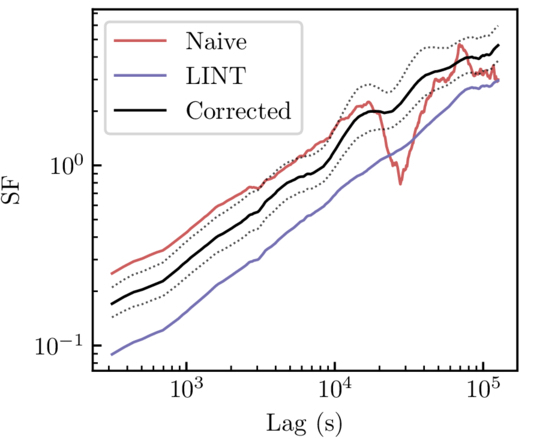
Structure function calculated from uncorrected Voyager 1 data (red), linearly interpolated data (blue), and corrected data (black). Both the linear interpolation method and the correction factor method remove the artifact around a lag of 3×10⁴ seconds, but the correction factor method does not suppress the signal like the linear interpolation method does. [Adapted from Wrench & Parashar 2025]

Correcting Voyager 1

Finally, the authors applied their validated method to data from Voyager 1. Data from the two Voyager spacecraft are extremely scientifically valuable — no other spacecraft have ventured as far from the Sun and can measure the solar wind at such large distances. The data are also extremely sparse; one segment used in this work was missing 85% of the data. This means that an effective method of correcting these data has potentially huge scientific significance.

Wrench and Parashar applied their correction factor to the Voyager 1 data, showing that this method handily removes artifacts while avoiding the underestimation introduced by linear interpolation. While the authors saved the interpretation of the newly corrected Voyager 1 data for future research, this study makes it clear that even large data gaps needn’t hinder studies of the solar wind.

Citation

“Debiasing Structure Function Estimates from Sparse Time Series of the Solar Wind: A Data-Driven Approach,” Daniel Wrench and Tulasi N. Parashar 2025 ApJ 987 28. doi:10.3847/1538-4357/addc6a

The post Minding the Gaps in Solar Wind Data appeared first on AAS Nova.

  •  

Citizen Science Born in the Pandemic: The Hubble Image Similarity Project

images from the Hubble Image Similarity Project

Motivated by a desire to support community members financially during the coronavirus pandemic, researchers employed 30 local citizen scientists in the Hubble Image Similarity Project. This project quantified the similarities between astronomical images, providing a way to test the results of image-search algorithms.

Seeking Similarities

Eagle Nebula

The Eagle Nebula, pictured here in an image from Kitt Peak National Observatory, is a star-forming region in the Milky Way. [T.A.Rector (NRAO/AUI/NSF and NOIRLab/NSF/AURA) and B.A.Wolpa (NOIRLab/NSF/AURA); CC BY 4.0]

Say you have an image of a star-forming region, featuring eye-catching gas clouds, dense and dusty knots, and newborn stars. How would you go about finding other images that resemble yours?

You might start your search with an astronomical image database, using filters for object type or instrument to sift through thousands and thousands of options. But even filtering out everything but star-forming regions might yield vastly different results, given the widely varying shapes, colors, and sizes of these regions.

Or maybe you’ll feed your image into a neural network that has been trained to spot similar images. The results may seem promising, but how can you tell whether the algorithm has found the images that are the most similar? Would another algorithm do better?

The Hubble Image Similarity Project

Astronomical image collections rarely contain information about similarities between images in their metadata, and while neural networks appear to excel at gathering similar images, the results of these models are generally unverified. The Hubble Image Similarity Project, led by Richard White (Space Telescope Science Institute) and Josh Peek (Space Telescope Science Institute and Johns Hopkins University), addressed these issues with a team of citizen scientists who generated similarity information for astronomical images, providing a quantitative means to test the results of neural networks.

example of how the Hubble Image Similarity Project selects image cutouts for study

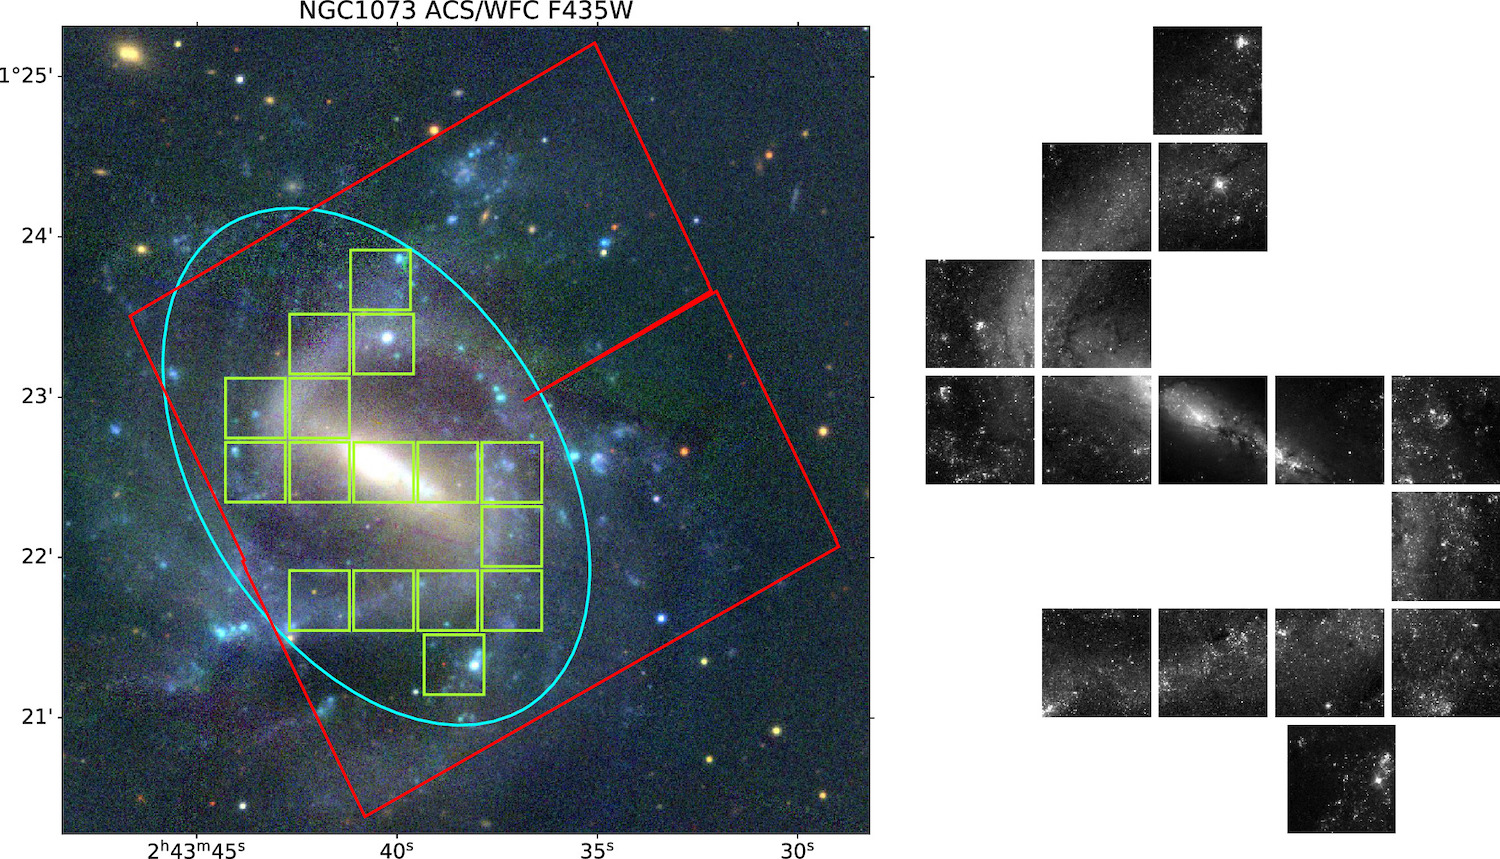
An example of individual test images (green squares) extracted from a Hubble Legacy Archive image (red square). Low-contrast areas have been excluded, leaving the galaxy’s spiral arms for analysis. Click to enlarge. [White & Peek 2025]

White and Peek began by amassing a sample of images from the Hubble Legacy Archive. This sample included many different object types, such as galaxies, planetary nebulae, star-forming regions, and star clusters. After trimming and binning the images, converting them to 8-bit grayscale, filtering out low-contrast images, and eliminating satellite trails, image artifacts, and repeated observations of the same patch of sky, 2,098 images of 666 objects remained.

Citizen Scientists, Assemble

White and Peek recruited 30 members of the community within walking distance of the Space Telescope Science Institute to identify similar astronomical images, and the reviewers were paid for their work. In the three phases of the project, reviewers considered test images one at a time and 1) selected all similar images from a set of 15 comparison images, 2) selected the most similar image from a narrowed-down set of 6 comparison images, and finally 3) selected the most similar image from a set of 3 comparison images.

similar images from the Hubble Image Similarity Project and a visualization of the data

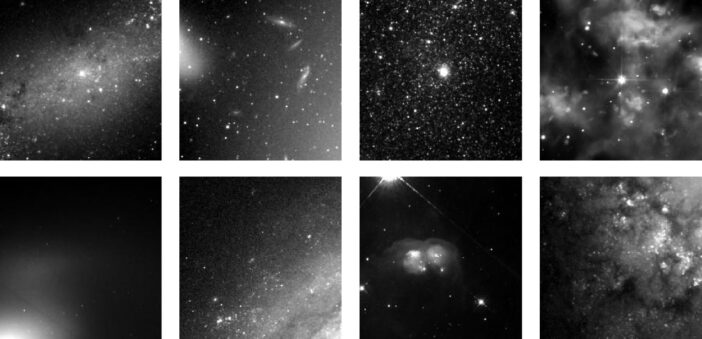
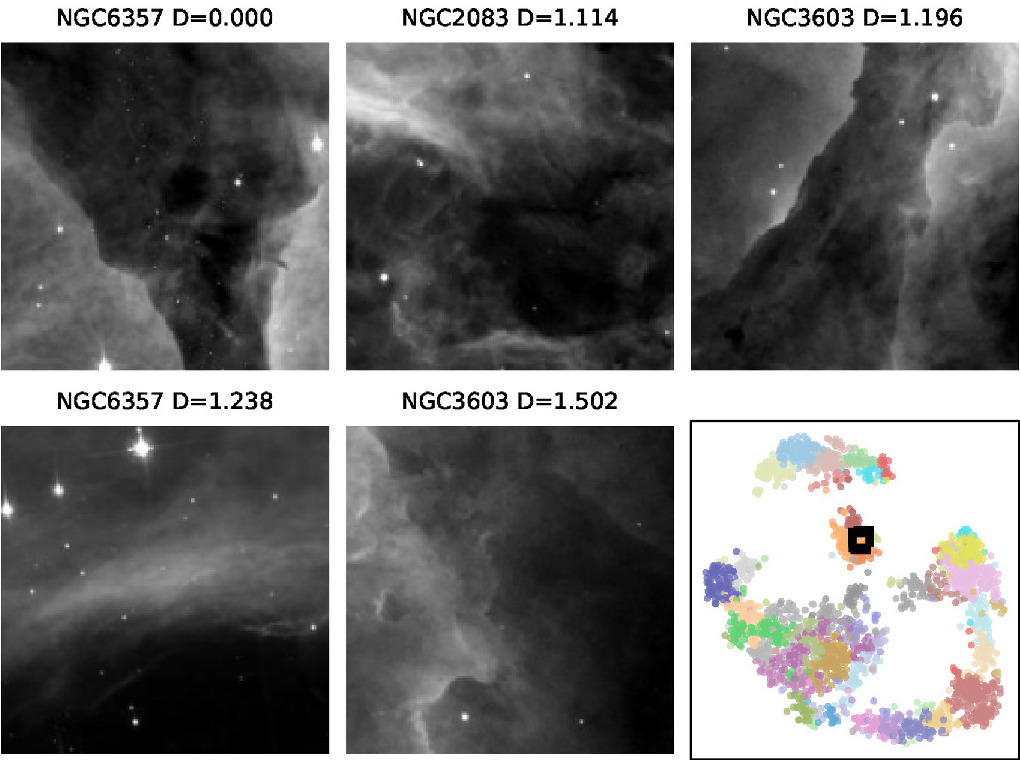
Examples of similar images according to the image similarity matrix. In the lower-right corner is a visualization of the similarity data. The semicircle of data points in the bottom half of this visualization represents galaxies, while star clusters occupy the small arc near the top and nebulae sit in the island in the center of the plot. Click to enlarge. [Adapted from White & Peek 2025]

The citizen science team ultimately compared 5.4 million pairs of images, and White and Peek used these comparisons to produce an image similarity matrix. The matrix describes the metaphorical “distance” between the images, with the most similar images being the smallest distance apart.

Similar images resemble one another in terms of structure, texture, and other factors that White and Peek say are “difficult even to describe in words” — for example, the diffuse glow of a galaxy interrupted by a bright star with diffraction spikes, or a nebula speckled with stars and dense dusty clumps. The similarity data from this study are available online and can be used to test the performance of image-search algorithms. In future work, the authors plan to carry out a similar project using images of the Martian landscape.

Citation

“The Hubble Image Similarity Project,” Richard L. White and J. E. G. Peek 2025 AJ 169 306. doi:10.3847/1538-3881/adcb43

The post Citizen Science Born in the Pandemic: The Hubble Image Similarity Project appeared first on AAS Nova.

  •  

New Species of Fossil Axolotl Unearthed in Mexico

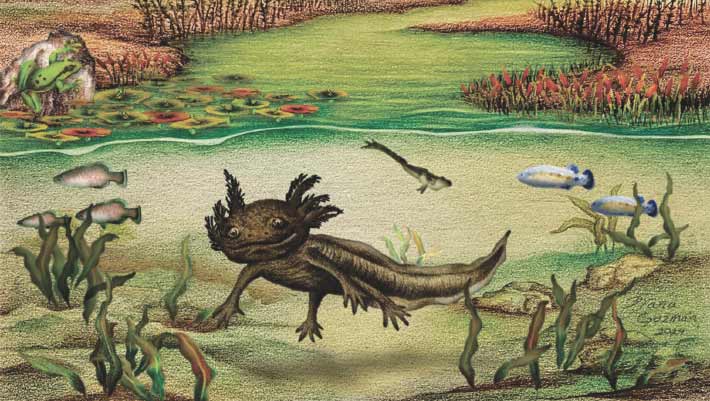
Reconstruction of the Santa María Amajac paleolake during the Late Pliocene; the paleobiodiveristy of the paleolake included microvertebrates such as the ambystomatid salamander Ambystoma quetzalcoatli, Paleocharacodon guzmanae and Goodea-like fishes, anurans and numerous species of terrestrial and aquatic plants such as Nymphaea sp., Scirpus sp., Typha sp. Image credit: Diana Guzmán-Madrid.

Paleontologists have identified a new species of the axolotl genus Ambystoma from several fossilized specimens found deep in the rocky outcrops of the Mexican state of Hidalgo.

The post New Species of Fossil Axolotl Unearthed in Mexico appeared first on Sci.News: Breaking Science News.

  •  
❌