❌

Reading view

Scientists Develop New Technique to Protect Privacy of Electrocardiogram Data

In a groundbreaking development addressing the burgeoning concern of privacy in modern medical technology, researchers at the University of Kansas have unveiled a transformative artificial intelligence (AI) model designed specifically to safeguard sensitive biometric data embedded within electrocardiograms (ECGs). This innovation is poised to reshape how medical institutions share and analyze vital cardiovascular data without compromising patient confidentiality. Electrocardiograms have long been renowned for their role in capturing the heart’s electrical activity to diagnose and monitor cardiac health; however, as AI integration deepens, these signals inadvertently reveal more than just clinical information — exposing personal attributes such as sex, age, race, and even uniquely identifiable biometric markers.

The research team at Kansas, led by doctoral candidate Fairuz Shadmani Shishir in collaboration with the KU Medical Center, has pioneered the privacy-preserving variational autoencoder (PP-VAE). This novel AI architecture is specially engineered to retain the clinical utility of ECG data while systematically obfuscating sensitive biometric features that might otherwise be inferred through advanced AI analysis. The dual objective of PP-VAE is both technically sophisticated and ethically imperative, ensuring that predictive diagnostic accuracy remains uncompromised while minimizing the risk of privacy breaches inherent in sharing raw biomedical signals.

Electrocardiograms, traditionally viewed as a straightforward diagnostic tool, have grown in complexity with modern AI techniques that can extrapolate a multiplicity of patient traits beyond the cardiovascular parameters they were designed to measure. Shishir notes that these advanced systems can uncover “soft biometrics” such as demographic information, which raises pressing data governance and patient privacy challenges. By developing PP-VAE, the researchers aim to reimagine ECG data processing whereby sensitive attributes are masked without degrading the signal quality necessary for important medical prognoses, such as identifying patients at risk of left ventricular ejection fraction (LVEF) abnormalities, a critical indicator linked to heart failure and mortality risk.

The technical underpinning of PP-VAE involves training independent convolutional neural networks to disentangle and suppress identifiable biometric markers while preserving clinically relevant features within the ECG signal. This balancing act required careful engineering to ensure that the encoded ECG data remained diagnostically rich, capable of supporting predictions related to conditions such as left ventricular hypertrophy and forecasting five-year mortality risk. The research showcased that their method consistently outperformed or competed with other state-of-the-art AI models, marking a significant stride in machine learning’s ability to harmonize privacy with clinical efficacy.

Importance of such privacy-preserving strategies becomes particularly clear against the backdrop of the healthcare industry’s increasing reliance on data sharing for collaborative research, AI model development, and multi-institutional patient care coordination. The KU team articulates that unrestricted data sharing without privacy controls introduces tangible risk vectors for patient re-identification and misuse. PP-VAE proposes a scalable approach toward enabling secure exchange of ECG data, thus fostering innovation and improving medical outcomes while staunchly protecting individual privacy rights.

This research also touches on the profound issue of bias within AI-driven medical diagnostics, which has historically contributed to disparities in healthcare delivery among marginalized populations. The team consciously incorporated balanced datasets reflective of gender and racial diversity in their model training to mitigate bias and improve generalized performance across varied demographic groups. While initial validations were primarily conducted using data from KU Medical Center and publicly available datasets, future work is projected to expand this cross-regional training, enhancing the robustness and impartiality of the model when applied globally.

Another compelling facet of this breakthrough is the planned public release of the PP-VAE model, reflecting the researchers’ commitment to transparency, collaboration, and democratization of AI tools in medicine. By allowing institutions worldwide to access and further refine the model with local datasets, the innovation promises to catalyze a new era of secure, privacy-conscious healthcare analytics. Adoption of PP-VAE could alleviate prevalent trust issues among patients concerned about the confidentiality of their biometric health information—a critical barrier to broader acceptance of AI-driven healthcare technologies.

Furthermore, the researchers discuss the broader implications for data-driven diagnosis, illustrating how balancing the protection of sensitive attributes with clinical utility could become a standard principle in biomedical AI applications beyond cardiology. This approach offers a blueprint for addressing ethical and privacy challenges that increasingly pervade the intersection of health data science and artificial intelligence.

The University of Kansas team’s work is also distinguished by its multidisciplinary nature, featuring collaboration between electrical engineering, computer science, and cardiovascular medicine experts. Such an integrated approach enabled the synthesis of advanced machine learning expertise with intimate clinical insight, culminating in a pragmatic solution tailored precisely to real-world healthcare needs.

This pioneering study was recently published in Scientific Reports, showcasing detailed methodology, experimental evaluations, and comparative performance analyses that underscore the efficacy and potential transformative impact of PP-VAE. Supported by the American Heart Association, this research is an exemplar of innovative technological stewardship addressing one of the most pressing challenges in digital health.

As AI continues to proliferate across medical diagnostics, models like PP-VAE will undeniably play a critical role in shaping ethical frameworks and technological architectures for future patient data management. By protecting sensitive biometric identifiers embedded in ECG data, the model not only preserves patient autonomy but also enhances the potential for AI-driven insights to be safely harnessed for better clinical outcomes worldwide.

The journey ahead involves validating and deploying this technology in diverse healthcare environments globally to ensure scalability, efficacy, and fairness remain intact as data heterogeneity increases. Yet, with the foundational work from the University of Kansas, a robust and privacy-conscious approach to ECG analysis and beyond appears well within reach, heralding a new era of secure AI-driven cardiovascular care.


Subject of Research: Privacy-preserving AI models for electrocardiogram data analysis
Article Title: Safeguarding Patient Privacy in Electrocardiogram Analysis with AI-driven Models
Web References: Scientific Reports Article
Image Credits: Fairuz Shadmani Shishir / University of Kansas

Keywords

Privacy-preserving AI, Electrocardiogram (ECG), Variational Autoencoder, Convolutional Neural Networks, Biomedical Data Security, Cardiovascular Diagnostics, Left Ventricular Ejection Fraction, Patient Privacy, Machine Learning Bias, Medical Data Sharing, Artificial Intelligence in Healthcare, Clinical Decision Support
  •  

Apenas 14% das empresas estão preparadas para tirar máximo partido da cloud na era da IA

Num momento em que quase todos reconhecem a cloud como peça central das estratégias digitais, um novo estudo aponta uma contradição relevante: o investimento e a ambição em torno da IA estão a crescer mais depressa do que a maturidade tecnológica necessária para os suportar.

The post Apenas 14% das empresas estão preparadas para tirar máximo partido da cloud na era da IA appeared first on Tek Notícias.

  •  

Earthquake Experts Modeled 1,000 Years of Activity in California—What They Found Now Has Scientists Concerned

California could be due for a major earthquake in the near future, according to concerning new models based on data comprising 1,000 years of quake activity on the West Coast.

According to recent findings, tectonic stress has quietly been building in California to levels not seen since the last major earthquake in the region, which bore a magnitude of 7.9 and struck the West Coast nearly 170 years ago.

That event, known as the Fort Tejon earthquake, affected the greater Los Angeles area, and since the time of those historic rumblings, researchers have grown increasingly concerned about a period of seismic silence that could point to the likelihood of an event of similar magnitude at some point in the future.

The potentially concerning new forecast was detailed in a recent study by an international team of researchers led by Dr. Liliane Burkhard of the Division of Space Research and Planetary Sciences (WP) at the Physics Institute of the University of Bern, which focused on historic earthquake data as a means of gauging current stress loading at Cajon Pass.

The study, published in the Journal of Geophysical Research: Solid Earth, indicates tectonic stress levels that are now believed to exceed the highest seen during the years the team surveyed.

The “Earthquake Gate” at Cajon Pass

The researchers aimed to investigate stress that has slowly built along the San Andreas and San Jacinto faults and incorporated what they likened to an “earthquake gate” at Cajon Pass, which, in their models, functioned like a point of control that governed the size of earthquakes and whether they could spread to both systems.

For their research, they used a four-dimensional earthquake cycle model that allowed them to replicate certain processes both in spatial dimensions and across time.

Using a millennium of reconstructed earthquake data from the region based on geological information such as radiocarbon dates, unusual events recorded in dendrochronological data (i.e., information obtained from tree rings), and historical information sources, the team gave this to the model they devised.

Dr. Burkhard said the team’s simulation offered them a unique opportunity to better understand the ways stresses in the fault system build up over long periods of several centuries.

“By running the earthquake history of Southern California as a simulation, we can estimate the extent to which the fault system is already under stress today,” Dr. Burkhard said. The results of those simulations weren’t particularly promising either: according to Burkhard, current stress levels in the region are the highest they have been in 1,000 years, based on the data.

Concerning New Earthquake Data

The team also identified significant new information regarding the function of the so-called “earthquake gate” at Cajon Pass.

“The earthquake gate concept captures something important about how fault junctions work,” Burkhard said in a recent statement. “Cajon Pass doesn’t simply block or channel earthquakes: It responds to stress conditions, and those conditions change over centuries.”

Not only this, but Burkhard and her team also determined that a key element to these quakes involves not only the level of stress that accumulates at a single fault, but perhaps more significantly, the way stress between two systems can align. This is because, as the stress across a pair of faults rises together over longer periods, this appears to be most conducive to a large joint rupture comparable to the 1857 Fort Tejon earthquake.

Conversely, if stress levels are not in concert as they evolve, the team determined that this causes quakes that probably will not propagate beyond the junction.

In short, a more severe earthquake event today would entail a joint rupture that crosses the Cajon Pass, as opposed to one constrained either to the San Andreas or the San Jacinto Fault alone. Should such an event occur, it would likely impact one of the largest population centers, as well as a crucial infrastructure system that supplies energy and transportation to surrounding areas.

For Burkhard, “The question of when and how the next major earthquake will occur in this region is one of the most pressing problems in applied geoscience.” Based on the team’s findings, they say that their new modeling hopes to provide a much more complete picture of the science behind the factors that could lead to a major quake—conditions that could apply equally to other parts of the world as they do to California.

Burkhard adds that her team’s study is not intended merely as a prediction for when the next major earthquake could potentially occur, but also as a means of preparing for future quakes and mitigating their effects.

“What we can say is that the system is critically stressed and that physics-based models like ours give a clearer picture of the range of scenarios we should be prepared for,” Burkhard says. “This information is important for hazard assessment, infrastructure planning, and emergency preparedness.”

The team’s study, “Cajon Pass and the Southern San Andreas Fault System: Earthquake Cycle Stress Accumulation and Present‐Day Loading,” appeared in the Journal of Geophysical Research: Solid Earth.

Micah Hanks is the Editor-in-Chief and Co-Founder of The Debrief. A longtime reporter on science, defense, and technology with a focus on space and astronomy, he can be reached at micah@thedebrief.org. Follow him on X @MicahHanks, and at micahhanks.com.

  •  

A New View of the Spectroscopic Universe

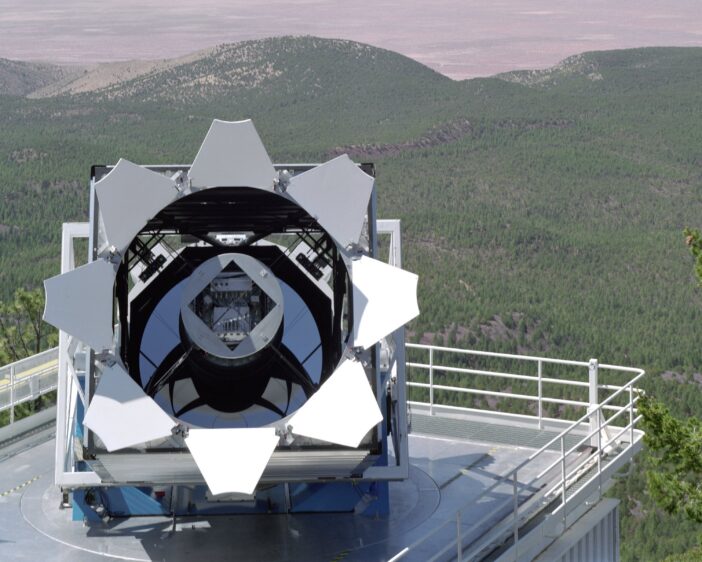
A photograph of a telescope opened at dusk.

The Sloan Digital Sky Survey (SDSS) fundamentally changed the way modern astronomy research is done. This “grand and bold thing” is not frozen in a museum exhibit, however: instead, the SDSS telescopes and team have continued to iterate. The collaboration recently described the fifth generation of this groundbreaking survey in The Astronomical Journal.

Roots in History

Astronomy is now without question a “big data” science. While a lucky few researchers still occasionally travel to distant mountaintops to sojourn with the stars, most astronomers who can describe their work as “observational” rarely ever leave their laptops. Petabytes of historical data, including images, spectra, enormous simulation archives, and more, are available the instant one’s fingers touch a keyboard. As a result, the speed of discovery has increased exponentially, and the barriers to cutting-edge research have dramatically shrunk.

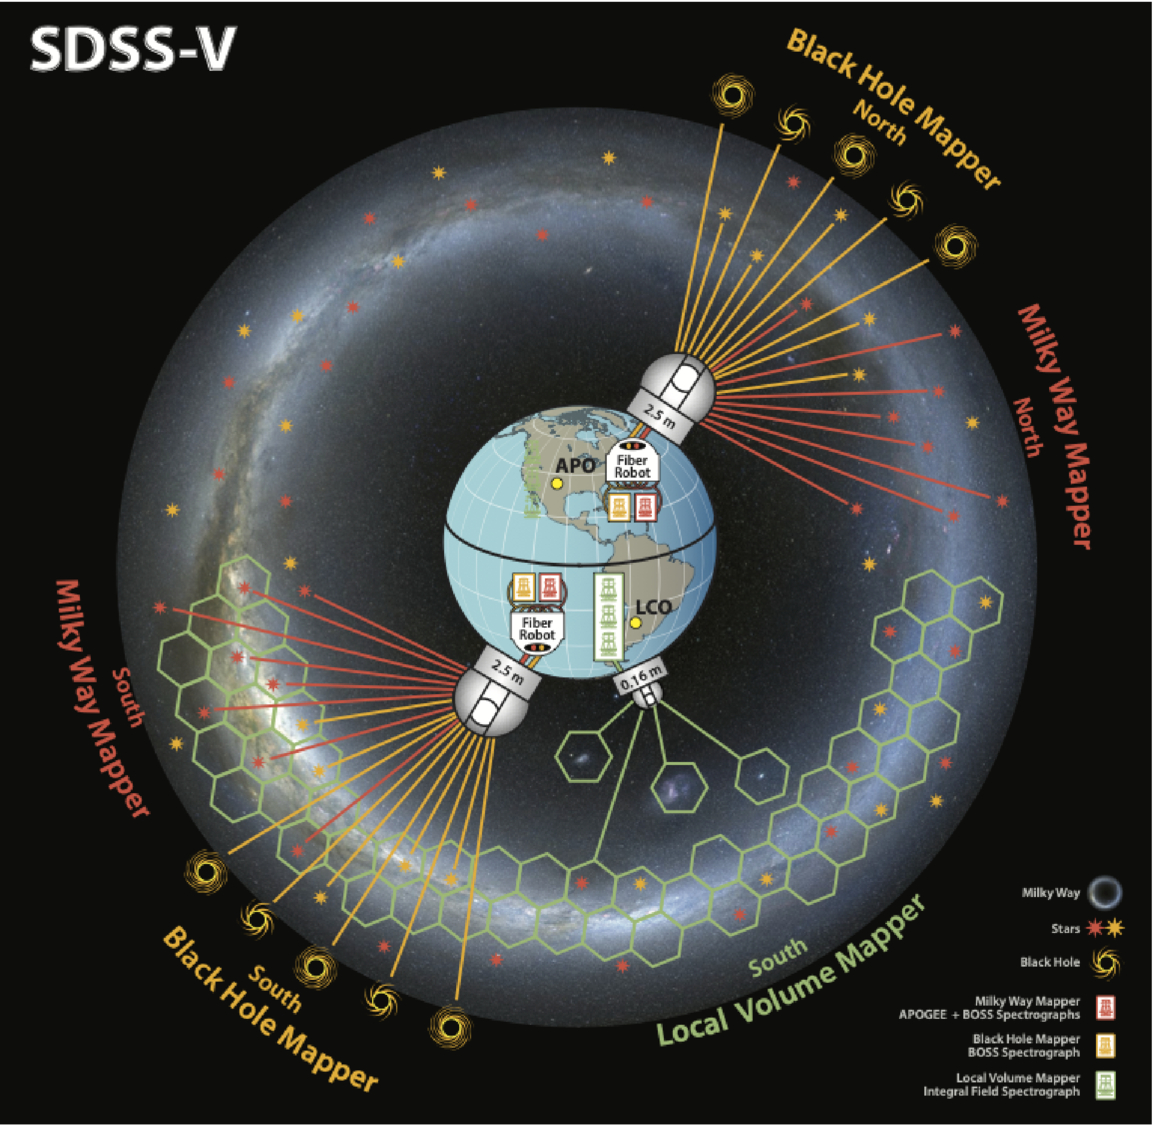
A cartoon of the Earth with three telescopes roughly geographically distributed as they are for the SDSS V survey.

A schematic of the SDSS-V survey facilities and targets. Click to enlarge. [Kollmeier et al. 2026]

While no paradigm shift can be pinned to an exact date, astronomy’s turn towards the data-rich era arguably began in 1998 when SDSS first began collecting data. This was among the first of the “industrial” surveys that observed large swaths of the sky with electronic detectors and used automated pipelines for bulk data processing. In the years since, larger robotic telescopes have begun to mimic the SDSS strategy of “mowing the sky.” The latest of these successors, which itself may usher in another paradigm shift in terms of data volume and availability, is the soon-to-begin Legacy Survey of Space and Time at the Vera C. Rubin Observatory.

While SDSS’s twin 2.5-meter telescopes (one in New Mexico and one in Chile, allowing the survey to observe the entire sky) are dwarfed by Rubin’s 8-meter mirror, there is still thrilling science to be done with these moderate-sized observatories. This is especially true after a series of upgrades to the spectrographs and thanks to a deep expertise in not only survey-style science, but also in project management and survey planning. In 2021, in the middle of COVID-19 delays and distancing requirements, the team began upgrades to their existing facilities and construction of a brand new telescope to kick off the latest survey, SDSS-V.

The Next Generation

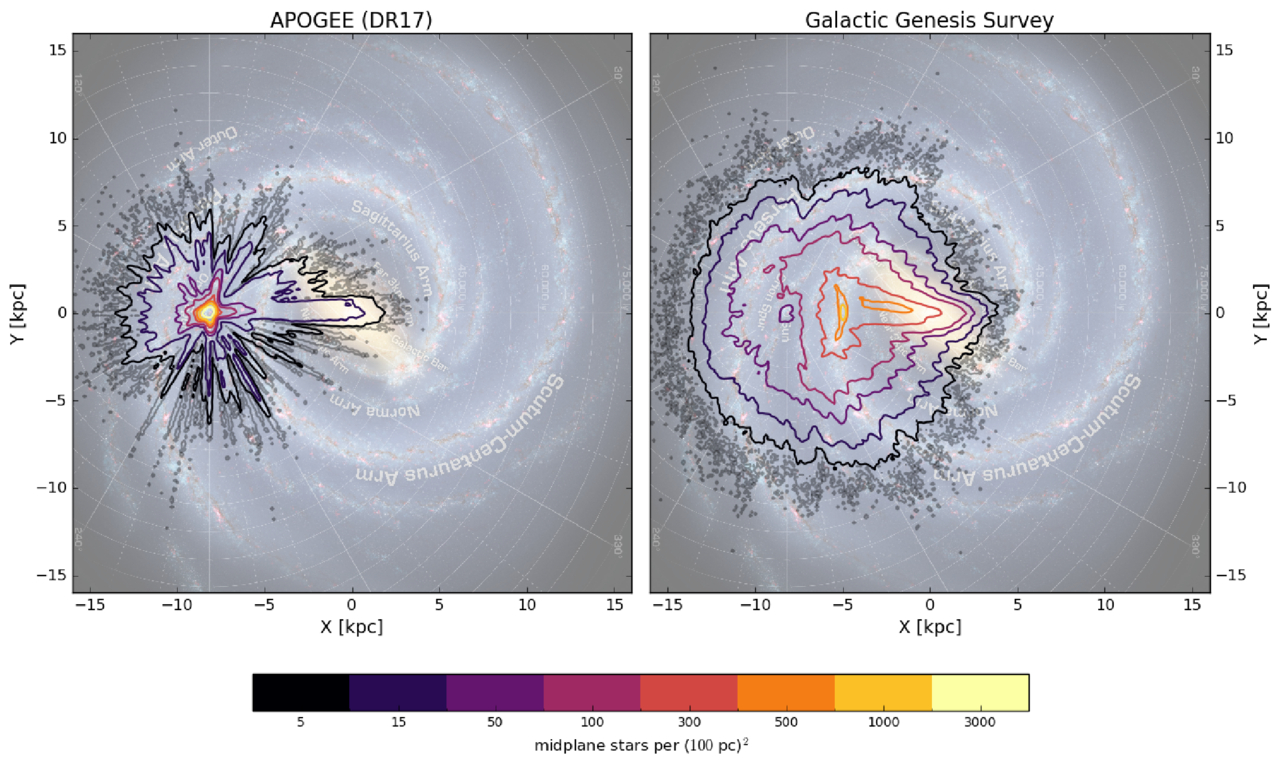
A two-panel figure showing top-down views of the milky way galaxy with different density contours overlaid.

The density of target stars for the SDSS-V survey compared to a previous spectroscopic survey. Click to enlarge. [Kollmeier et al. 2026]

In a wide-ranging publication that references not only astronomy research articles but also Plato, the Bhagavad Gita, an Egyptian tomb, and Tolstoy, the large collaboration describes that this latest survey is divided into three parts: the Milky Way Mapper, the Black Hole Mapper, and the Local Volume Mapper. The preexisting telescopes, which are outfitted with hundreds of tiny robots that can swivel fiber optic cables into place to collect spectra of up to 500 objects at a time, will handle the first two of these “mappers.” A brand-new facility in Chile that’s specifically designed to map the structure of nearby gas will handle the last mapper. Instead of aiming the fibers at a known star or galaxy, this telescope will instead collect a spectrum for every point across an area the size of the full Moon with every exposure.

By the end of the survey, SDSS-V will have collected optical and near-infrared spectra for roughly 6 million objects spread across the whole sky, as well as time-series spectra from about a million of these sources. This dataset, which is unprecedented in both its spatial and temporal coverage, will allow researchers to probe questions ranging from how quasars evolve over time to how commonly young stars have brown-dwarf companions. Long since SDSS initiated the era of industrial survey astronomy, this latest publication shows how the survey continues to lead the way.

Citation

“Sloan Digital Sky Survey. V. Pioneering Panoptic Spectroscopy,” Juna A. Kollmeier et al 2026 AJ 171 52. doi:10.3847/1538-3881/ae0576

The post A New View of the Spectroscopic Universe appeared first on AAS Nova.

  •  

Minding the Gaps in Solar Wind Data

solar wind

Spacecraft scattered throughout the solar system keep tabs on the solar wind, but the measurements are dotted with data gaps. How can scientists prevent these gaps from biasing their studies of the solar wind?

Sampling the Solar Wind

intracluster medium

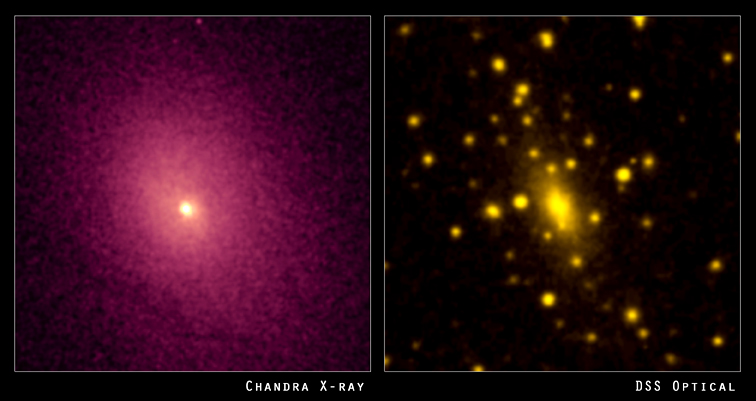
Left: the distribution of hot gas between the galaxies in the cluster Abell 2029. Right: the visible light from the galaxies in the cluster. [X-ray: NASA/CXC/UCI/A.Lewis et al. Optical: Pal.Obs. DSS]

The solar wind is a tenuous, fast-moving, turbulent plasma that constantly streams out from the Sun. Studying the solar wind is important for understanding how potentially damaging space weather events like coronal mass ejections travel through the solar system. Solar wind studies also have far-reaching implications, since solar-wind-like plasmas exist throughout the universe, such as in the sparse medium between galaxies in a cluster.

Luckily, there are many spacecraft that sample the solar wind from various locations within our solar system. Unluckily, many of these spacecraft do not continuously monitor the solar wind. For example, when a spacecraft orbiting a planet dips into the planet’s atmosphere, this detour creates an hours-long gap in solar wind monitoring.

The Impact of Data Gaps

How do these data gaps affect studies of the solar wind? In a recent research article, Daniel Wrench and Tulasi Parashar (Victoria University of Wellington) approached this question in terms of how gaps affect the structure function: a mathematical description of how the solar wind fluctuates over different length or time scales.

Wrench and Parashar introduced random artificial gaps into data from the Parker Solar Probe, which monitors the solar wind continuously, and compared the structure functions calculated from the continuous and interrupted data sets. They used the difference between the true structure function — calculated from the continuous data set — and the structure functions from the artificially gapped data sets to develop a correction factor.

bar plot of correction method performance

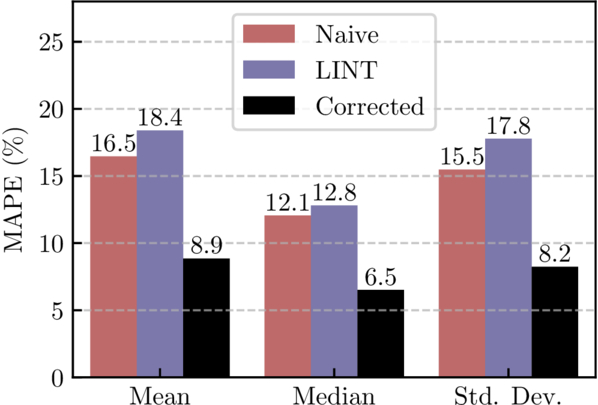
Performance of the correction factor method (black) compared to the uncorrected, gapped data (red) or gaps filled using linear interpolation (blue). MAPE is the mean absolute percentage error. [Wrench & Parashar 2025]

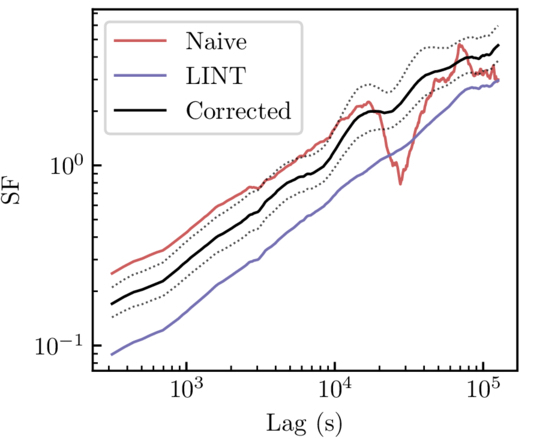
The team then tested their correction factor using data from the Wind spacecraft, which continuously monitors the solar wind from the L1 Lagrange point. The team calculated the structure function from 1) the continuous data set, 2) the artificially gapped data, 3) the gapped data with linear interpolation used to fill the gaps, and 4) the gapped data with the correction factor applied. This test showed that the correction factor performs better than other commonly used gap-handling methods, such as linear interpolation, which can systematically underestimate the structure function. Using the correction factor, the error in the structure function remained below 50% even when 95% of the data were missing.
plot of structure function from Voyager 1 data

Structure function calculated from uncorrected Voyager 1 data (red), linearly interpolated data (blue), and corrected data (black). Both the linear interpolation method and the correction factor method remove the artifact around a lag of 3×10⁴ seconds, but the correction factor method does not suppress the signal like the linear interpolation method does. [Adapted from Wrench & Parashar 2025]

Correcting Voyager 1

Finally, the authors applied their validated method to data from Voyager 1. Data from the two Voyager spacecraft are extremely scientifically valuable — no other spacecraft have ventured as far from the Sun and can measure the solar wind at such large distances. The data are also extremely sparse; one segment used in this work was missing 85% of the data. This means that an effective method of correcting these data has potentially huge scientific significance.

Wrench and Parashar applied their correction factor to the Voyager 1 data, showing that this method handily removes artifacts while avoiding the underestimation introduced by linear interpolation. While the authors saved the interpretation of the newly corrected Voyager 1 data for future research, this study makes it clear that even large data gaps needn’t hinder studies of the solar wind.

Citation

“Debiasing Structure Function Estimates from Sparse Time Series of the Solar Wind: A Data-Driven Approach,” Daniel Wrench and Tulasi N. Parashar 2025 ApJ 987 28. doi:10.3847/1538-4357/addc6a

The post Minding the Gaps in Solar Wind Data appeared first on AAS Nova.

  •  

Citizen Science Born in the Pandemic: The Hubble Image Similarity Project

images from the Hubble Image Similarity Project

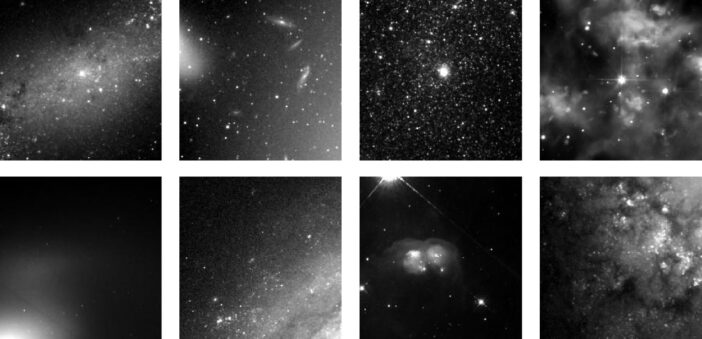
Motivated by a desire to support community members financially during the coronavirus pandemic, researchers employed 30 local citizen scientists in the Hubble Image Similarity Project. This project quantified the similarities between astronomical images, providing a way to test the results of image-search algorithms.

Seeking Similarities

Eagle Nebula

The Eagle Nebula, pictured here in an image from Kitt Peak National Observatory, is a star-forming region in the Milky Way. [T.A.Rector (NRAO/AUI/NSF and NOIRLab/NSF/AURA) and B.A.Wolpa (NOIRLab/NSF/AURA); CC BY 4.0]

Say you have an image of a star-forming region, featuring eye-catching gas clouds, dense and dusty knots, and newborn stars. How would you go about finding other images that resemble yours?

You might start your search with an astronomical image database, using filters for object type or instrument to sift through thousands and thousands of options. But even filtering out everything but star-forming regions might yield vastly different results, given the widely varying shapes, colors, and sizes of these regions.

Or maybe you’ll feed your image into a neural network that has been trained to spot similar images. The results may seem promising, but how can you tell whether the algorithm has found the images that are the most similar? Would another algorithm do better?

The Hubble Image Similarity Project

Astronomical image collections rarely contain information about similarities between images in their metadata, and while neural networks appear to excel at gathering similar images, the results of these models are generally unverified. The Hubble Image Similarity Project, led by Richard White (Space Telescope Science Institute) and Josh Peek (Space Telescope Science Institute and Johns Hopkins University), addressed these issues with a team of citizen scientists who generated similarity information for astronomical images, providing a quantitative means to test the results of neural networks.

example of how the Hubble Image Similarity Project selects image cutouts for study

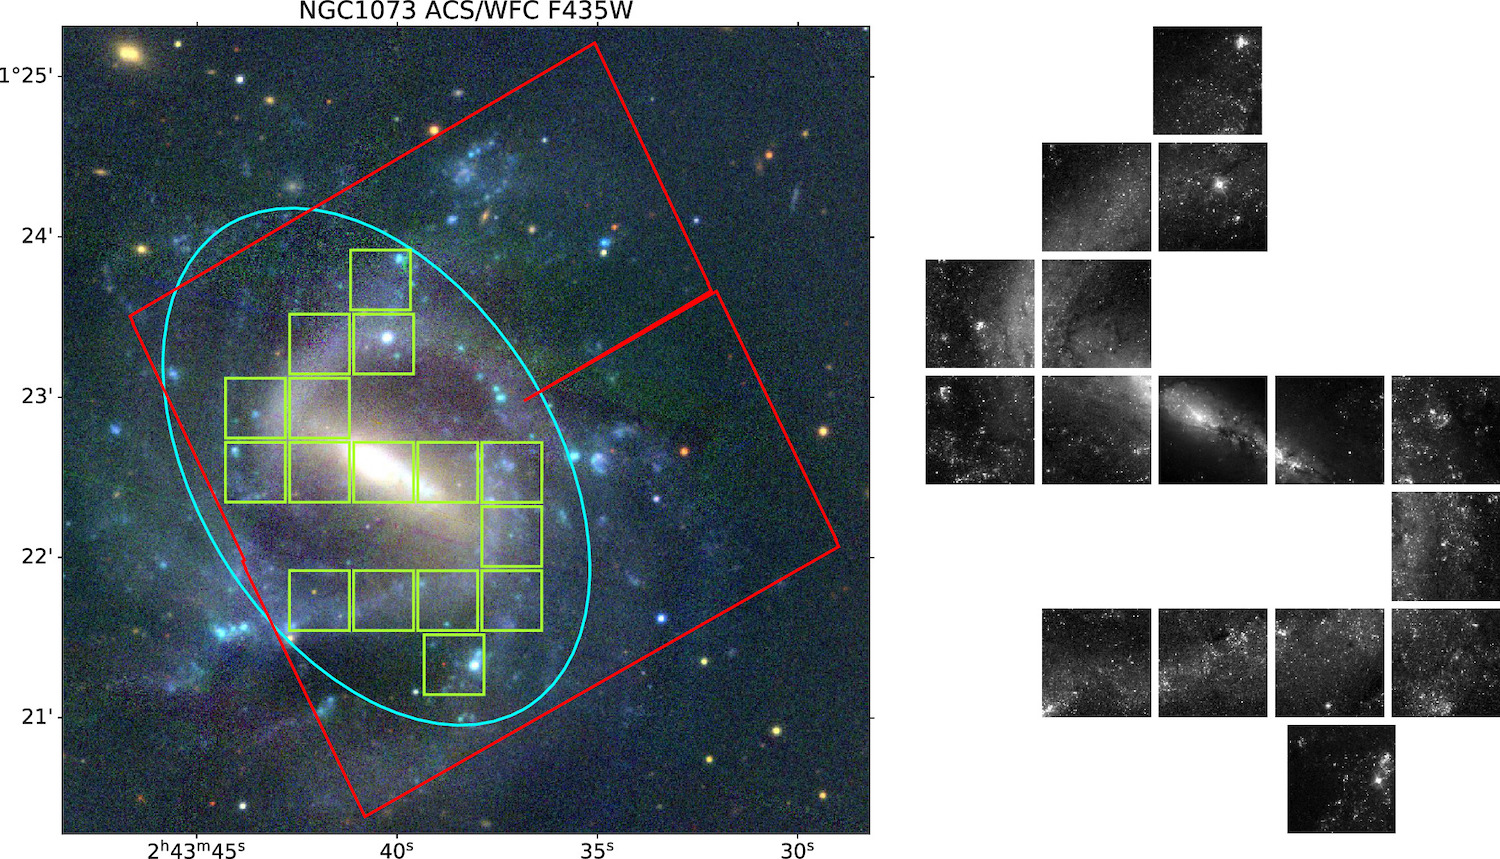
An example of individual test images (green squares) extracted from a Hubble Legacy Archive image (red square). Low-contrast areas have been excluded, leaving the galaxy’s spiral arms for analysis. Click to enlarge. [White & Peek 2025]

White and Peek began by amassing a sample of images from the Hubble Legacy Archive. This sample included many different object types, such as galaxies, planetary nebulae, star-forming regions, and star clusters. After trimming and binning the images, converting them to 8-bit grayscale, filtering out low-contrast images, and eliminating satellite trails, image artifacts, and repeated observations of the same patch of sky, 2,098 images of 666 objects remained.

Citizen Scientists, Assemble

White and Peek recruited 30 members of the community within walking distance of the Space Telescope Science Institute to identify similar astronomical images, and the reviewers were paid for their work. In the three phases of the project, reviewers considered test images one at a time and 1) selected all similar images from a set of 15 comparison images, 2) selected the most similar image from a narrowed-down set of 6 comparison images, and finally 3) selected the most similar image from a set of 3 comparison images.

similar images from the Hubble Image Similarity Project and a visualization of the data

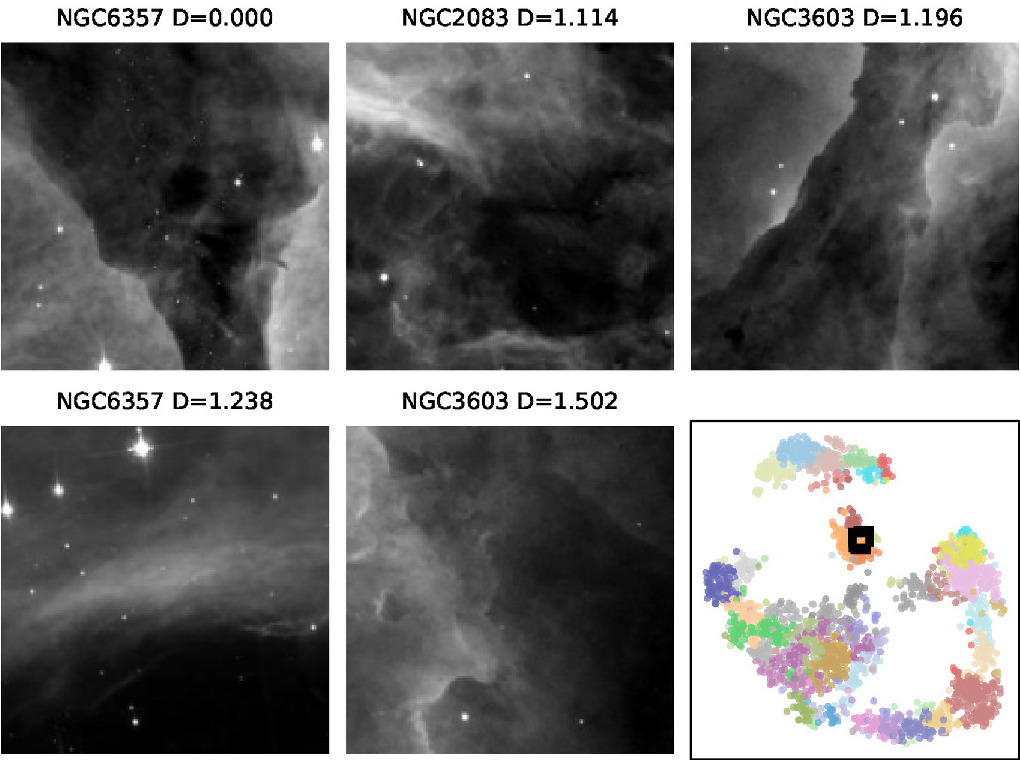
Examples of similar images according to the image similarity matrix. In the lower-right corner is a visualization of the similarity data. The semicircle of data points in the bottom half of this visualization represents galaxies, while star clusters occupy the small arc near the top and nebulae sit in the island in the center of the plot. Click to enlarge. [Adapted from White & Peek 2025]

The citizen science team ultimately compared 5.4 million pairs of images, and White and Peek used these comparisons to produce an image similarity matrix. The matrix describes the metaphorical “distance” between the images, with the most similar images being the smallest distance apart.

Similar images resemble one another in terms of structure, texture, and other factors that White and Peek say are “difficult even to describe in words” — for example, the diffuse glow of a galaxy interrupted by a bright star with diffraction spikes, or a nebula speckled with stars and dense dusty clumps. The similarity data from this study are available online and can be used to test the performance of image-search algorithms. In future work, the authors plan to carry out a similar project using images of the Martian landscape.

Citation

“The Hubble Image Similarity Project,” Richard L. White and J. E. G. Peek 2025 AJ 169 306. doi:10.3847/1538-3881/adcb43

The post Citizen Science Born in the Pandemic: The Hubble Image Similarity Project appeared first on AAS Nova.

  •  

New Species of Fossil Axolotl Unearthed in Mexico

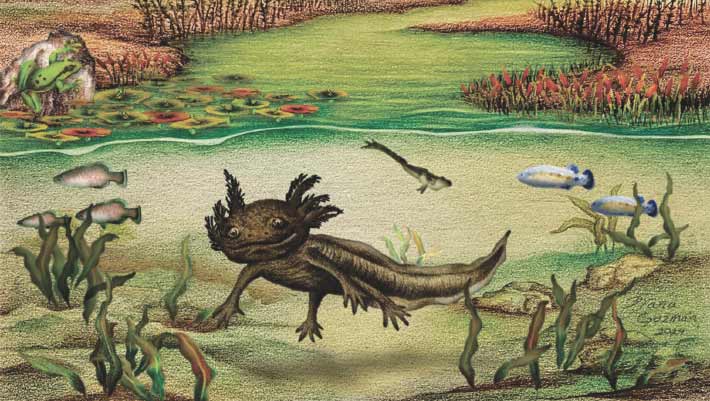
Reconstruction of the Santa María Amajac paleolake during the Late Pliocene; the paleobiodiveristy of the paleolake included microvertebrates such as the ambystomatid salamander Ambystoma quetzalcoatli, Paleocharacodon guzmanae and Goodea-like fishes, anurans and numerous species of terrestrial and aquatic plants such as Nymphaea sp., Scirpus sp., Typha sp. Image credit: Diana Guzmán-Madrid.

Paleontologists have identified a new species of the axolotl genus Ambystoma from several fossilized specimens found deep in the rocky outcrops of the Mexican state of Hidalgo.

The post New Species of Fossil Axolotl Unearthed in Mexico appeared first on Sci.News: Breaking Science News.

  •  
❌