❌

Normal view

AWS targets a longtime cloud migration blocker with SQL Server license portability

6 June 2026 at 00:29

Licensing can be complicated, particularly when enterprises are forced to double-pay because the software they already own is only licensed for a specific environment, and moving it requires a whole different licensing model. Without proper portability rights, they need to make additional financial investments to run the same workloads in a different home.

AWS says its new Bring Your Own Media (BYOM) service eliminates this duplication. Customers can now reuse their existing Microsoft SQL Server media and licenses on Amazon Relational Database Service (RDS) with no additional licensing fees.

This means enterprises no longer have to justify workload migrations to the cloud against existing licensing commitments and infrastructure investments, AWS said.

“What used to be a licensing barrier between operational SQL Server data and agentic AI is now gone,” AWS data engineer Srikanth Katakam and product marketing manager Colleen Betik wrote in a blog post announcing the service.

Avoiding the double-licensing problem

To drive true value, agentic AI apps must have access to elastic GPU capacity as well as direct, low-latency access to the data they need to reason and make decisions. But, AWS argued, that can be difficult in self-managed data centers and on premises infrastructure with limited access to agentic AI cloud-native services. But a lot of enterprise data lives in Microsoft SQL Server, and until now customers have had to pay for a second license to use a fully managed cloud service like RDS.

Now, with BYOM on Amazon RDS for SQL Server, enterprises can reuse their existing SQL Server Enterprise Edition or Standard Edition licenses through a “lift-and-shift” model. This brings their data into a fully-managed environment.

According to the licensing distribution terms, enterprises must provide their licensed SQL Server Release to Manufacturing (RTM) media to Amazon RDS. They can then upload that media to Amazon S3 and launch BYOM instances. Enterprises must configure AWS License Manager to perform automatic instance tracking.

From there, RDS automates patching, backups, high availability, and monitoring, while providing direct access to agentic AI and analytics services native to AWS. The platform also reports vCPU usage to provide visibility into SQL Server license usage, Katakam and Betik wrote.

“You do not need to choose between protecting your SQL Server licensing investments and giving your data a path to the AWS analytics and agentic AI services redefining what’s possible in the cloud,” they said. 

It’s important to note that this service is only available to enterprises with Microsoft Software Assurance (SA), an add-on which supports mobility and rehosting of existing licenses. Enterprises must verify that their SQL Server licenses comply with Microsoft’s licensing agreement, and that they have a SQL Server License (Standard or Enterprise) with SA. They also must submit a License Mobility Verification Form to Microsoft; it, in turn, will notify AWS once verification is complete.

AWS emphasized that enterprises remain responsible for compliance; it does not block operations if license limits are exceeded.

More control over workloads, loosening Microsoft’s grip

The advantage of this service, explained Mike Leone, principal analyst at Moor Insights & Strategy, is that enterprises can get a Microsoft SQL Server workload onto a managed AWS service without rewriting it for Aurora or paying for the license twice. This means they can modernize on their own schedule rather than being forced into rewrites before they’re ready.

“For a lot of shops, that control over timing is worth more than the license saving itself,” Leone said.

This also loosens Microsoft’s grip on enterprise workloads, because organizations finally have somewhere else to run SQL Server using licenses they already own, he noted. Realistically, their dependency shifts to AWS rather than disappearing entirely, as their data ends up living next to AWS’s AI services.

“For a lot of teams, that’s a trade they’re glad to make for the managed infrastructure and the AI tooling they get in return,” Leone said.

Yaz Palanichamy, a senior advisory analyst at Info-Tech Research Group, also pointed to significant improvements stemming from the migration. Notably, it allows organizations to transition away from static, linear, or reactive storage capabilities towards more dynamically intelligent environments.

“The key is to balance the unification of transactional data towards managed AI and machine learning pipelines,” he said.

Enterprises take on new responsibilities

The catch? Leone noted that enterprises now own the task of licensing compliance. Staying current on SA, the Microsoft maintenance contract that makes any of this legal, and the license mobility rules, “become your headache instead of something baked into the bill,” he said.

Furthermore, he added, lift-and-shift has a way of turning into “lift-and-forget” when enterprises move SQL Server as-is and never actually modernize, “so you end up carrying all the old baggage onto a shinier platform.”

Palanichamy also pointed to skyrocketing AWS costs, since operationalizing AI agents requires a considerable amount of data ingestion and querying. This can potentially be cost prohibitive on RDS for SQL Server.

“One aspect to consider would be the relative time to production value, so that enterprises can better handle the management of volatile AI workloads,” he said.

Just one challenge in the AI race

Although AWS frames licensing complexity as a roadblock to agentic AI, analysts say it’s really just one piece of the puzzle.

Organizations are not in an AI-ready state due to a number of factors, Palanichamy noted. This could be total cost of ownership (TCO)-related, a lack of appropriate acceptable use policies (AUPs), or concerns around security and compliance.

If and when enterprises are ready to adopt AI, they must perform thorough needs analysis/process optimization benchmarking exercises to determine what workflows could benefit from the technology, he said, and, conversely, flag workflows where AI could prove “an impediment or potential disservice.”

Leone also pointed out that moving SQL Server onto RDS doesn’t “magically make your data agent-ready,” nor does it make it smarter. The data proximity and managed plumbing are what actually support agents. Sitting data next to Bedrock and the rest of AWS’s AI services means builders “stop wasting time shipping the data around or building one-off integrations every time an agent needs it.”

Ultimately, though, licensing isn’t the real issue when it comes to AI; it’s more of a migration problem. The real roadblocks are messy data, questionable governance, and teams that aren’t ready to run it in production, and, Leone said, “no change to a license bill touches a single one of them.”

Embedding pipelines are the new ETL

5 June 2026 at 10:00

I’ve seen a lot of promising AI prototypes fall apart after launch. And it’s rarely because the model was bad. More often, the problem starts much earlier; teams treat the data layer like something they can figure out later.

They’ll spend weeks fine-tuning prompts, testing models and debating evaluation scores, then throw together the retrieval pipeline over a weekend and move on. At first, everything looks great in demos. But a few months later, the system gives outdated answers; the embeddings no longer match the source documents, and nobody fully understands what changed.

What started as an impressive prototype slowly becomes difficult to trust in production. The teams that avoid this tend to realize one thing early: Embedding pipelines are fundamentally a data engineering problem, not an entirely new AI discipline. It’s still ETL (Extract, Load, Transform) at its core, but with embeddings and vector stores as the destination instead of a warehouse.

Once you start looking at it that way, a lot of things become clearer. Problems like versioning, data freshness, lineage and retries stop feeling “AI-specific.” They’re data infrastructure problems we’ve already spent years learning how to solve.

Why do we need embedding pipelines?

Large language models are extraordinary reasoners trapped inside a time capsule. When training ends, the model’s knowledge is sealed. It does not know what your team decided in last quarter’s strategy review. It has never read the support ticket that came in this morning. It cannot find the clause buried on page 47 of your master service agreement. It’s brilliant, but blind to anything specific to your organization.

Layer on top of that a hard context window limit, a ceiling on how much text the model can process in a single interaction, and you have a clear problem: you cannot just hand it everything you own.

The answer the industry converged on is retrieval-augmented generation, or RAG. Instead of stuffing everything into the context window, you build a retrieval layer that fetches only the most relevant pieces of information at the moment a question is asked and passes just those to the model. That retrieval layer is powered by a vector database, and the process that populates it, which is taking raw documents and transforming them into searchable semantic representations, is what I mean when I say embedding pipeline.

Every team building an internal AI assistant, a smarter enterprise search tool, an automated customer support agent or a document Q&A system needs one. The question is not whether to build it. The question is whether you build it like a prototype or like infrastructure.

How an embedding pipeline works

An embedding pipeline has three stages: ingestion, chunking and indexing. Here is what each one means and how I relate them to a typical ETL process.

Ingestion is extraction

Getting your raw content, PDFs, wiki pages, Word documents, database records, transcripts, out of wherever it lives and into the pipeline. This is ETL’s extract stage, almost verbatim.

I see teams cut corners here more than anywhere else, and it’s often where production systems first start to fail. A document gets updated, but the pipeline doesn’t pick it up. A file gets deleted, but its chunks remain in the index, still returning outdated answers months later. And because there’s no obvious error, no one reports it.

The fix is Change Data Capture (CDC). This maintains a manifest of every document you have ingested, a content hash and a timestamp. On each run, we compare sources against that manifest, re-ingest what changed, delete what is gone and treat your document the way you would treat any source table you are syncing incrementally.

Chunking is transformation

Once your documents are in the pipeline, you cannot embed them whole. A 30-page technical report is too long to represent meaningfully as a single vector, and even if it were not, returning the entire report in response to a narrow question would bury the model in irrelevant context.

Chunking is the process of breaking each document into smaller pieces that are focused enough to embed accurately and retrieve precisely. This is ETL’s transform stage, and it deserves the same level of design discipline.

The most common mistake I see is treating chunk size as a default configuration option rather than a product decision. It is not. The right chunk size depends entirely on the nature of your content and the nature of your queries. Dense technical documentation needs finer granularity than a collection of FAQs. A legal contract with clause-level logic needs different treatment than a set of onboarding emails. What works for one document will actively degrade retrieval quality on another.

My strong preference is to treat your chunking configuration as a versioned pipeline parameter, not hardcoded logic. When you change it, and trust me, you will. You need to re-chunk in a controlled, observable way, compare retrieval quality before and after, and roll back if it degrades. That is just good transform-layer hygiene. It is no different from versioning a data cleaning rule or a field mapping.

Indexing is the load

The final stage is where chunked text gets converted into vectors and stored in a vector database where it can be searched by semantic similarity rather than keyword match.

In the conversion step, embedding is handled by a model specifically trained to turn text into dense numerical representations that encode meaning. Two chunks expressing the same idea in different words will produce vectors that cluster close together in that mathematical space. Two chunks discussing entirely different topics will sit far apart. When a user asks a question, the system embeds that question the same way, finds the chunks whose vectors are nearest, and returns them as context for the model to reason over.

That is a genuinely new capability. But the discipline around indexing is not. One data engineering principle I keep coming back to is versioning.

In embedding pipelines, every chunk in your index should be tagged with the embedding model name and version used to generate it, this is non-negotiable. Embedding models evolve, and vectors produced by different versions are not comparable in a reliable way. You cannot safely search across them as if they are interchangeable.

This exact problem shows up when teams upgrade embedding models mid-pipeline without a proper migration plan. You end up mixing vectors from different generations in the same index, and retrieval starts to degrade in ways that are hard to detect. The system just quietly begins returning subtly wrong answers.

I treat an embedding model upgrade the same way I treat a schema migration: Plan it explicitly, execute it in full and validate retrieval quality on a representative query set. The stakes are the same as any breaking change to your data model.

Pipeline observability is not optional

Once an embedding pipeline is running in production, the question shifts from “did it run” to “did it run correctly.” That distinction matters more here than in most pipelines, because failures are rarely loud because the index looks fine, queries return without errors and the system quietly surfaces wrong answers until someone notices the AI has stopped being useful.

The same observability discipline that makes any data pipeline trustworthy applies directly here. Once you treat embedding pipelines as production systems, you stop thinking in isolated steps and start thinking in signals. For example, chunk counts per document become a simple but powerful health check, a sudden drop is usually not a model issue, but a sign of broken ingestion or upstream parsing failures.

You also need a “golden set” of queries with known-good outputs. This runs after every pipeline change, much like data quality checks after a transformation. This is how you catch regressions that don’t show up as explicit failures.

On top of that, you can track lineage: Which embedding model version produced which chunks, and when each document was last ingested. That makes it possible to trace retrieval issues back to specific changes instead of guessing.

And finally, freshness becomes a first-class signal. If documents start going stale beyond an acceptable threshold, that should surface in monitoring long before users experience degraded results.

The metric that ties it all together is retrieval quality over time. Treat it like any other pipeline SLA, measured, tracked and owned.

Summary

Embedding pipelines definitely come with a lot of new language, new tools and a genuinely different capability in the semantic layer. But the funny thing is, the principles that actually make them reliable in production are not new at all.

We have versioning, freshness, quality checks and monitoring. These are problems data engineering has already spent years solving.

The real work is taking that same discipline and applying it to a pipeline that just happens to output vectors instead of rows in a table. Once you start seeing it that way, a lot of the chaos around AI systems becomes much easier to reason about.

That’s the difference between building a cool AI demo and building something people can actually depend on. One is a prototype, whereas the other is infrastructure.

This article is published as part of the Foundry Expert Contributor Network.
Want to join?

The next AI breakthrough won’t come from bigger models, but from better data

4 June 2026 at 10:00

Artificial intelligence does not advance at the same pace across industries. It presses forward in some directions while lagging behind in others.

Spend time with today’s most advanced AI applications, and this contrast becomes obvious. In software development, AI is quickly becoming ubiquitous. It writes production-ready code, explains obscure libraries, and iterates at a pace human teams have difficulty matching.

But place that same AI model inside a complex customer support workflow or ask it to reason through a nuanced clinical scenario, and the cracks begin to show. Multi-step reasoning falters. Context gets lost. Performance drops in ways that can seem inconsistent with the model’s strengths elsewhere.

These AI models are often similar. They run on similar hardware and are often trained in similar ways. So why the mismatch in performance across tasks? The simplest explanation is also the most overlooked: data.

Software engineering benefits from an immense, structured, and highly visible digital record. Code is written in standardized languages, benefits from robust documentation, is reviewed in public forums, and is discussed at scale. That ecosystem has generated a robust and massively useful pool of training material.

Other fields often do not. For example, healthcare data is scattered across institutions, wrapped in privacy constraints, expressed in multiple modalities, and rarely ready out-of-the-box for AI training. Enterprise workflows are captured in internal systems that were never designed for training AI. Multilingual speech data varies widely in quality and representation.

This imbalance creates what I describe as “the data gap.” This is the distance between what models are capable of in theory and what they can achieve in practice, because the right data does not yet exist in usable form. Closing this data gap may be the most important—and least glamorous—challenge in AI today.

The missing pillar of AI progress

Three forces are driving the recent advances in AI: the models, the chips, and the data.

On the AI models, the field has invested heavily. Major research organizations employ thousands of researchers and scientists who are actively refining architectures, training techniques, and evaluation methods. Breakthroughs are measured in benchmark scores, conference papers, and model performance on human tasks. On the computing chips, the investment has been equally intense. Hardware manufacturers and infrastructure providers are pouring billions of dollars into building and supporting data centers that deliver faster results via large-scale training.

Yet data has not received the same institutional focus for AI development. Conversations with researchers at frontier AI labs share a similar frustration that today’s model capabilities in key use cases, such as healthcare, are limited less by architectural imagination and more by the availability of high-quality, domain-specific data. The bottleneck is not always a lack of ideas, but a lack of reliable inputs.

We are long past scraping the internet for useful data, and this path does not scale. Progress depends on building and curating datasets that reflect the complexity of true lived experience and organizational processes. That work requires both scientific rigor and research specialization in the field of data for AI.

The dataset behind every leap

The history of AI reinforces a consistent lesson: major leaps in model capability follow major leaps in the availability of quality data. From early vision systems that relied on clearly labeled images to today’s language models trained on massive text collections, each major leap has depended on access to more high-quality data.

Architectural innovation alone is rarely enough. The value of these new approaches only emerges when paired with large, structured, and representative datasets that reveal what the models can actually do in practice. Whether in vision or language, progress has depended on the painstaking work of collecting, organizing, and validating the underlying data.

Large language models illustrate this clearly. Their emergence was not just the result of better training techniques, but of access to an unprecedented volume of data. The models did not generate that data. They relied on it. That pattern raises a pressing question for the present: who is building the next generation of foundational datasets?

Across domains ranging from healthcare to audio to agentic task performance, there is no widely accepted blueprint. What constitutes a gold-standard dataset for training an AI agent to handle complex enterprise tasks? What does a clinically meaningful evaluation look like for a model that will assist in medical decision-making? How should multilingual speech data be curated to ensure broad representation and reliable performance?

These are not simple sourcing problems. They are fundamental research challenges that need to be solved.

When data is treated as a commodity

Too often, consequential data decisions are handled like procurement exercises. An organization requests “medical conversations” or “wildlife scenes,” and the request is routed to internal procurement or data sourcing teams, or to external data vendors, who assemble data that appears to match the description. The implicit assumption is that data is interchangeable, that one dataset is as good as another so long as it meets a basic specification.

Actual application suggests otherwise. Seemingly small choices about factors such as inclusion criteria, annotation standards, filtering rules, and validation protocols can dramatically alter downstream performance. Data design shapes model behavior as much as architecture does.

Three structural issues compound the problem:

  • Capacity: There are relatively few specialized teams dedicated to building domain-specific datasets at the highest level of rigor. Talent and funding have gravitated toward model development and hardware innovation. Data work often operates in the background, even though it underpins both.
  • Design: Constructing a dataset is a distinct discipline from designing a neural network. It requires expertise in experimental design, domain knowledge, and statistical validation. Expecting model researchers to simultaneously shoulder the full burden of data research, while also training and evaluating the models, overlooks the complexity of the upstream task.
  • Translation: The researchers who are requesting specific data sources to improve the models are often not the same people responsible for sourcing that data. As a result, nuances and research-backed expertise can often be missing or diluted as requests pass through layers of procurement and vendor relationships. The result can be data that meets the specification sheet, but in fact fails to advance model performance.

The rise of annotation providers and reinforcement learning services has addressed part of the need. Rating model outputs, labeling text, and evaluating structured information are essential for many optimization tasks. But these activities generate data that is carefully constructed for specific, bounded purposes.

The frontier challenges in AI require more. They demand datasets derived from real human activity and organic organizational processes. Such data is complex, multimodal, and sensitive. It is rarely AI-ready by default. And converting it into reliable training and evaluation material is a scientific undertaking.

The need for scientific rigor for the AI data layer

If high-quality data is a central bottleneck, then scientific rigor is part of the solution. Just as leading model-builders have dedicated research labs and hardware has dedicated development ecosystems, the data layer for AI requires focused, scientifically-grounded institutions.

This means engaging directly with core questions like dataset design, evaluation methodology, and quality control. The conversation cannot end at volume; it must address data structure, representativeness, and expert validation.

Dataset construction must be approached as experimental design. Protocols must be documented and validated. Evaluation frameworks must test whether the dataset truly reflects the intended applications.

The field also requires standards and benchmarks that reflect real-world complexity, not simplified proxies. In healthcare, for instance, evaluating a system intended for clinical assistance with generic question-and-answer tests is insufficient. Real-world clinical environments involve multimodal inputs and contextual judgment. Benchmarks must reflect that reality if they are to function as meaningful gates before deployment.

Quality measurement is another crucial frontier. Finance relies on standardized metrics such as credit scores to assess risk. AI lacks an equivalent for datasets and benchmarks. Developing clear methodology to quantify dataset quality and evaluation reliability brings clarity to model assessment.

The criteria for evaluating a multilingual audio library will differ from those of a multimodal oncology dataset. Yet the underlying principle remains constant. Better models require better-defined, better-measured data.

The risks of getting it wrong

As AI systems move closer to high-stakes deployment, weak data practices carry tangible risks.

Benchmarks cannot be created with the same data that is used for training—that’s giving the test answers to the model ahead of time. Scaling data volume without prioritizing data quality and selection diminishes model performance gains, and can even bias against or omit underrepresented populations. These are methodological challenges, and ones that must be solved.

The rigor required at the data layer may not attract headlines. It does not typically lend itself to dramatic product launches. Yet the data layer for AI is foundational to trust, safety, and sustained progress for all AI progress.

An ecosystem for the data era

No single organization can resolve the data gap alone. What is needed is an ecosystem of AI data labs and research groups, each focused on different domains and challenges but united by a commitment to scientific discipline. These institutions would collaborate with model researchers and domain experts who would tackle challenges such as dataset contamination, factuality, groundedness, de-identification, international representation, and bias. They would design benchmarks that mirror real-world complexity rather than simplified abstractions.

AI’s trajectory will not be determined solely by larger models or faster chips. It will be shaped by the datasets we construct, the standards we adopt, and the rigor we apply at the foundation. The uneven frontier we see today reflects an uneven data landscape. Bridging the gap requires deliberate, research-driven dataset design.

If we want AI systems capable of operating reliably in clinical contexts, navigating enterprise workflows, and functioning responsibly across languages and cultures, we must treat data for AI as a first-class scientific endeavor.

AI models have their research labs. AI chip-builders have their fabrication plants. AI data needs institutions of equal seriousness and ambition.

—

New Tech Forum provides a venue for technology leaders—including vendors and other outside contributors—to explore and discuss emerging enterprise technology in unprecedented depth and breadth. The selection is subjective, based on our pick of the technologies we believe to be important and of greatest interest to InfoWorld readers. InfoWorld does not accept marketing collateral for publication and reserves the right to edit all contributed content. Send all inquiries to doug_dineley@foundryco.com.

OpenAI fixed a visibility problem; the governance problem remains.

4 June 2026 at 03:32

AI governance is an ongoing game of catch-up for enterprises. Model updates and iterations are rolling out at a rapid clip, often making governance frameworks obsolete before they’re battle-tested.

To evolve beyond this paradigm, OpenAI is introducing Active sessions. This new ChatGPT security feature allows users to review and log out of one or more sessions through a simple interface. The feature is now available across all ChatGPT accounts and workspace types, including personal and managed workspaces. Experts call it an important development for the model provider, which currently has 1 billion monthly active users.

Previously, organizations often had limited visibility into where users were logged in, and simply relied on password resets or broad account actions to force re-authentication, noted Ensar Seker, CISO at SOCRadar. “Granular session control is a more efficient and less disruptive approach. From a governance perspective, session transparency improves accountability and supports investigations,” he explained.

A holistic view across session activity

Active sessions allows admins to see known browser and app sessions across ChatGPT, Codex, and API Platform. Specifically, they are able to view device and browser information, approximate location, sign-in date and time, whether a device is trusted, and whether the session is current.

To access the feature, users can go to ‘Settings’ > ‘Security’ > ‘Active sessions.’ They can then log out of specific sessions and remove devices from trusted services. They also have the ability to log out of all sessions (thus ending sessions across devices), however, this action can take up to 30 minutes to complete.

However, OpenAI emphasizes that session details may be “approximate or incomplete,” and that the feature has limits. It does not show or manage connected apps or third-party app sessions, sign-ins through third-party services, Codex CLI sessions, or recently signed-out sessions.

Further, Active sessions cannot be used with accounts linked to an enterprise’s single sign-on (SSO), including security assertion markup language (SAML) and OpenID Connect (OIDC).

Better late than never

While Active sessions is an important security and governance development, experts note that the feature is basic, and was a long time coming.

“The reality of OpenAI offering the ability to end active sessions on ChatGPT by administrators is that it’s something that exists in lots of platforms,” said David Shipley of Beauceron Security. “They should’ve had it sooner, but better late than never.”

From a security standpoint, he noted, OpenAI could do a better job policing ChatGPT to prevent it being used by threat actors to host malware, which is the latest threat to enterprises.

SOCRadar’s Seker also pointed out that this type of visibility and oversight is something that enterprises have expected from SaaS platforms for years. “It allows administrators and users to quickly identify unauthorized access, terminate stale sessions, and reduce the risk of account compromise persisting undetected.”

Iterative upgrades disrupt governance

Last week, OpenAI updated GPT-5.5 Instant in both the ChatGPT app and API to “improve response style and quality,” the company said. It had rolled out GPT-5.5 Instant earlier in May as a successor to GPT‑5.3 Instant, calling it “generally smarter” and prone to fewer hallucinations.

According to OpenAI, the update makes GPT-5.5 Instant “easier to read, more natural in everyday conversations, and better paced in practical help tasks, with fewer overly long or bullet-heavy responses.”

But even with tools like Active sessions, enterprises continue to struggle with governance amidst seemingly continuous iterative model updates. It’s simply not sustainable, said Beauceron’s Shipley: “How do you build an appropriate testing plan with a nondeterministic system?”

SOCRadar’s Seker pointed out that many organizations perform security, compliance, and business validation testing before approving a model for production use. But, “when model behavior changes under the same version family, previously documented assumptions may no longer fully reflect actual performance,” he noted.

“The biggest governance challenge in AI is not model adoption, it’s model change,” Seker said. “Most organizations can evaluate a model once. Far fewer are prepared to continuously evaluate how that model evolves over time.”

This particularly creates challenges for regulated industries where auditability, repeatability, and change management are critical, he said. Even beneficial improvements can introduce governance concerns if organizations are not clearly informed about what changed and when.

Valence Howden, advisory fellow at Info-Tech Research Group, noted that organizations often can’t assess the implications of model iterations against their boundaries, and, worse, are often unaware of them.

While the biggest enterprise challenge was initially tied to which AI model was being used, what that model did, and who owned it, iterative updates can muddy those waters and increase reliance on third party practices and tools that organizations often don’t have the resources for, he noted. 

“Without the ability to opt out [of an update] before it’s incorporated, [enterprises] are basically red-teaming the updates with their clients,” said Howden.

The ongoing game

Security teams today are pushed to their limits because they are expected to manage rapidly evolving models, new features, and changing behaviors, while maintaining compliance, risk management, and business continuity, said SOCRadar’s Seker.

“Governance is difficult because organizations are no longer evaluating a static product,” he said. Rather, they are managing a “continuously evolving service” where capabilities, integrations, and user behaviors can change far faster than can traditional security review cycles.

Info-Tech’s Howden agreed, saying that enterprises’ existing governance practices, especially accountability, are poor, as are their risk practices.

“It’s hard to suddenly become good at things they’re already poor at doing,” he said. “They are also incentivized for speed and innovation, so they ignore governance as a constraint, or don’t want to do it at all.”

How enterprises should respond

Seker advised that, ultimately, organizations should treat AI models as living systems rather than fixed software releases.

Security and governance programs should include continuous validation, monitoring, and periodic re-assessment instead of sole reliance on one-time approval processes, he said. Enterprises should also establish clear vendor change management expectations, including requiring transparency around model updates, behavioral changes, and potential impacts to existing workflows.

“Effective AI governance increasingly depends on visibility into change, not just visibility into risk,” Seker said.

Snowflake’s Horizon Context aims to give AI agents a common understanding of the business

2 June 2026 at 19:06

As enterprises move from AI experimentation to production deployments, one challenge is becoming increasingly apparent: AI systems are only as reliable as the business context they operate in.

Snowflake is attempting to address that problem with Horizon Context, a new set of semantic and metadata-management capabilities, currently in preview, that it unveiled Tuesday at its annual Snowflake Summit conference.

Artin Avanes, head of core data platform at Snowflake, said that the offering, launched as part of Horizon Catalog, the company’s existing data discovery, management and governance suite, collects metadata from across an enterprise’s data estate, enriches it with business definitions, relationships, lineage, and governance information, and makes that context available across AI and analytics systems.

These capabilities, according to Avanes, build on Snowflake’s acquisition last year of Select Star, a metadata management startup known for its integrations with database systems such as PostgreSQL and MySQL, business intelligence tools like Tableau and Power BI, and data pipeline/orchestration tools such as dbt and Airflow.

Reducing operational complexity of agentic workflows

For CIOs, Horizon Context should reduce operational complexity because it will provide a governed map of their organization’s data estate, said Stephanie Walter, practice lead of the AI Stack at HyperFRAME Research.

“The value is not simply cataloging where data lives; it is giving AI systems the metadata, lineage, permissions, and business context needed to retrieve the right data safely,” Walter said.

In fact, according to Robert Kramer, managing partner at KramerERP, the challenge of missing context for analytics and reporting is not new for enterprises.

“Most enterprises were stitching together catalogs, BI semantic layers, governance tools, lineage, access controls, dbt models, security policies, and custom integrations. The issue was not that these pieces did not exist. The issue was that they were fragmented,” he said.

That duct-taping together of different pieces, said Mike Leone, principal analyst at Moor Insights & Strategy, is the actual reason why most teams in an enterprise would end up with slightly different versions of a business metric, such as monthly active users, resulting in AI agents also being inconsistent downstream.

But, said Walter, the stitching together of different catalogs and semantic layers only works for semi-autonomous workflows. “What changed with AI agents is that those systems increasingly need access to context at runtime rather than through documentation and human interpretation,” she said. “Snowflake is trying to pull those pieces closer to the data platform, so context, semantics, access control, and execution are part of the same operating environment”

Automatically maintaining business context for AI agents

To supplement Horizon Context, Snowflake is also adding Semantic Studio, currently in private preview, to help enterprises reduce the effort required to build and maintain business context for agents and agentic workflows.

“Semantic Studio is a core part of the Enrich layer of Horizon Context, providing the AI-assisted workspace where teams define, test, and publish that business logic,” Avanes said.

The Enrich layer itself, which consists of companion capabilities like the Semantic View Autopilot, automatically layers intelligence on data assets, providing insights such as which assets are most trusted, how they connect, what they mean, and how to correctly calculate metrics, Avanes added.

According to Leone, Semantic Studio solves a critical challenge: “It will reduce the burden of SQL-savvy data engineers and let business owners author the shared definitions. That’s where most semantic-layer projects die today.”

For Walter though, there is still a caveat to these offerings.

“While these offerings reduce complexity, they do not remove the work. Someone still has to decide which metrics are authoritative, which data products are trusted, and who owns the business definitions,” she said.

Addressing security and governance concerns

Alongside these updates, Snowflake is also trying to address security concerns around agentic workflows with new capabilities inside Horizon Catalog’s Trust Center.

These capabilities, which are focused on AI Security Posture Management (SPM), include a new agent identity capability that enables enterprises to distinguish between human activity within a session and actions taken by an AI agent operating on a user’s behalf, Avanes said.

“This should provide greater transparency and auditability for agents, while also enabling enterprises to apply existing data access controls, such as dynamic masking and row access policies, on an agent-by-agent basis,” he said.

Another new capability, data exfiltration policies, currently in private preview, will help enterprises prevent unauthorized movement of sensitive data. These policies are part of Horizon Catalog’s broader governance framework, and will allow enterprises to define controls around how data can be accessed, shared, and moved across systems, Avanes said.

For enterprises, Walter noted, these capabilities could help address one of the biggest barriers to deploying AI agents in production: governance.

“Data exfiltration controls, AI Security Posture Management, and other centralized AI controls help CIOs move from experimentation to production by giving security teams a way to see and govern how AI workloads interact with enterprise data,” she said.

Echoing Walter, Leone pointed out that the “security story” is the gating issue for almost every agent deployment that Moor Insights & Strategy is currently tracking.

“Features such as data exfiltration policies and AI SPM are what convert a CISO from a ‘no’ to a ‘yes’ on moving an agent deployment into production,” he added.

This article originally appeared on CIO.com.

Fighting Fire With Fire

5 June 2026 at 05:01
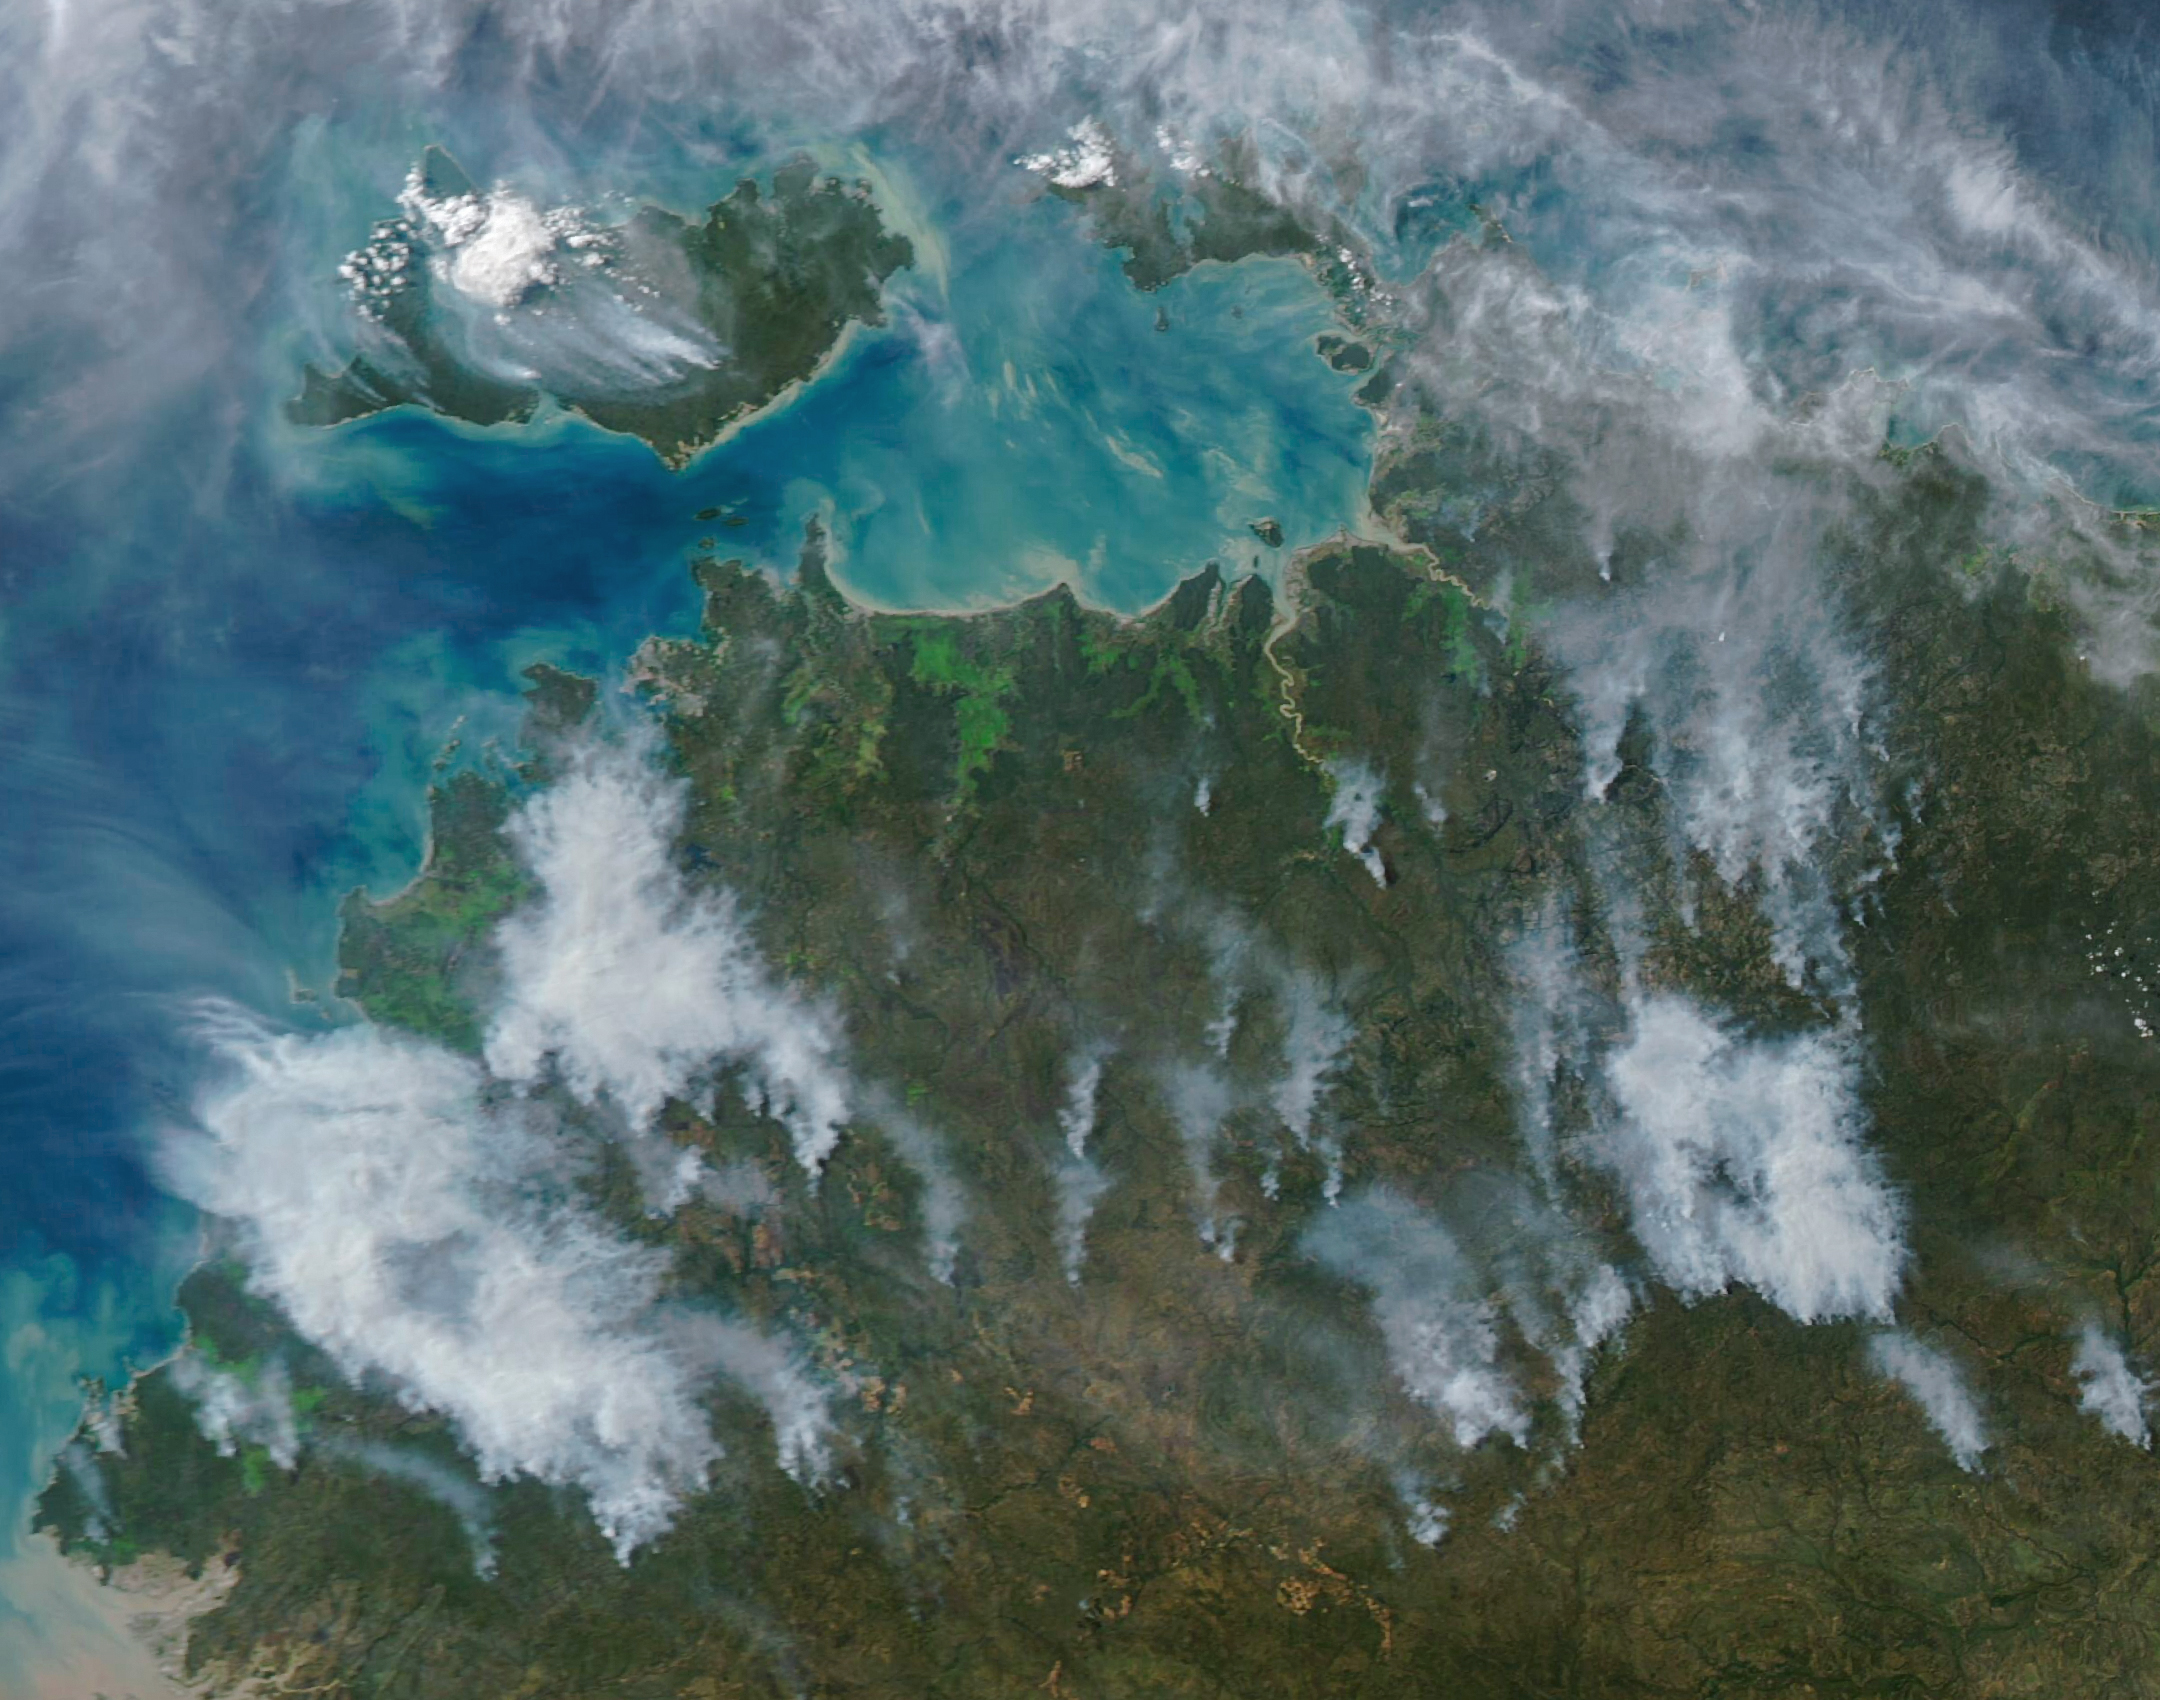
Several gray smoke plumes are visible drifting over a green landscape.
Smoke streams from fires in Australia’s Northern Territory in an image captured by the MODIS (Moderate Resolution Imaging Spectroradiometer) on NASA’s Aqua satellite on May 28, 2026.
NASA Earth Observatory/Michala Garrison

In May and June of most years, NASA satellites typically begin to detect large numbers of wildland fires throughout the Top End and Arnhem Land regions of Australia’s Northern Territory. On some days, especially in the afternoon, the blazes can resemble sizable wildfires in satellite imagery, spreading widely and producing expansive smoke plumes.

That was the case when NASA’s Aqua satellite acquired this image of smoke and fires on the afternoon of May 28, 2026. Often, however, fires burning in this area look smaller and less imposing. In the mornings just a few days earlier and later, for instance, NASA satellites detected little smoke despite observing many thermal anomalies, or hotspots, that indicated fire activity.

The pattern of burning, location, and timing are consistent with prescribed fires lit intentionally to manage the landscape. Land managers tend to light fires in the morning, and smoke builds over the course of the day. The process sometimes creates sizable plumes when there are updrafts and winds of moderate strength that carry smoke away from the fires, as happened on May 28 and again on June 2. The fires typically burn through the fire-adapted grasses, underbrush, and scattered trees in the region’s tropical savanna ecosystems.

Over the past few decades, the region’s land managers have combined deep-rooted Indigenous land management practices and modern technologies to establish large-scale landscape management programs such as the West Arnhem Land Fire Abatement project and Arnhem Land Fire Abatement. The goal of such efforts is to intentionally burn some of the savanna underbrush to create firebreaks and reduce fuel loads early in the dry season, reducing more destructive and emissions-intensive fires later in the season. The dry season generally begins in May and extends through September, according to Australia’s Bureau of Meteorology.

While research is ongoing, there are signs that the prescribed burning efforts are having the intended effect. Analysis of satellite observations of the fires suggests that prescribed burning efforts have shifted fire activity from late to early in the dry season, leading to a reduction in high-intensity fires and emissions.

NASA Earth Observatory image by Michala Garrison, using MODIS data from NASA EOSDIS LANCE and GIBS/Worldview. Story by Adam Voiland.

Downloads

Several gray smoke plumes are visible drifting over a green landscape.

May 28, 2026

JPEG (1.82 MB)

References & Resources

You may also be interested in:

Stay up-to-date with the latest content from NASA as we explore the universe and discover more about our home planet.

Fires Tear Through Nebraska Grasslands

3 min read

Dry, warm, and windy conditions across the U.S. Great Plains led to extreme fire activity in March 2026.

Article

Fires Rage in Georgia

3 min read

Firefighters are battling two destructive blazes in the southern part of the state as drought grips the U.S. Southeast.

Article

Fire’s Footprint on Santa Rosa Island

3 min read

A wildland fire charred grassland, coastal sage scrub, and chaparral across one-third of the island, the second largest of the…

Article

AI saves workers a day a week, but they don’t know what to do with it

4 June 2026 at 04:59

A report released Wednesday by Boston Consulting Group (BCG) indicates that many organizations are having difficulty converting efficiency gains that are AI-driven into any sort of measurable value.

The fourth edition of the consultancy’s annual Global AI at Work Survey reveals 42% of frontline employees who use AI on a regular basis save upwards of a full day each week; however, 66% are not given guidance on what to do with time they save, and “more than half don’t redirect it to strategic work.”

The report, AI at Work: Strategy Matters More Than Tools, is based on a global survey of 11,749 employees in 14 markets, from industries ranging from financial services to the healthcare sector.

David Martin, global leader of people and organization work at BCG, and the report’s lead author, said via email that the number of employees lacking the required guidance is surprising, “but it also tracks with what we see in many AI transformations. Companies have moved quickly to give people tools, but many have not yet redesigned the work around those tools.”

Saved time, he added, does not automatically become value. If a frontline employee saves a few hours a week, but has no direction on whether to use that time for customer service, quality improvement, innovation, or faster execution, “that value can simply leak out of the organization”

The fix is for leaders to change the scoreboard, Martin said: “Don’t just measure AI adoption or hours saved. Decide where that time should go, measure whether it is being reinvested, and give managers clear guidance on how to help teams use it. This is where AI transformation becomes a management challenge, not just a technology rollout.”

In fact, said Vinciane Beauchene, a managing director and partner at BCG and one of the report’s five co-authors, “the first wave of AI focused on individual productivity. The coming wave will need to transform collective work.”

“Everyone is talking about AI replacing work,” she said, “but it is in fact really about rethinking the human value-add inside.”

A managerial revolution underway

According to Beauchene, “this is the role of leaders. Our survey reveals a true managerial revolution in the age of AI; 65% of managers and leaders now believe agents will take over at least half of their job in the next three years, and frontline workers see their jobs evolving towards more managing and directing AI.”

A BCG release stated that the survey also highlights the continued emergence and maturity of AI agents, with 30% of respondents saying that agents are already integrated into workflows, more than double the number from last year’s report (13%).

Other key findings revealed that AI adoption among frontline workers has surged, with 74% saying they now use it daily or a few times a week, which is up 23 percentage points from a year ago. In addition, six out of 10 people believe that, within the next three years, AI agents could do at least half of their jobs.

And a survey slideshow released by the company pointed out, “the AI ‘honeymoon’ won’t last unless leaders bring strategic clarity driving sustained impact AI’s novelty and cognitive stretch fuel enjoyment early on. But sustained joy comes from strategic clarity. Employees thrive when the direction is real and the message reaches them with strong CEO involvement.”

Strategic clarity is a key differentiator

The report suggests that CEOs take a holistic approach to AI transformations by focusing on business outcomes as opposed to AI usage, investing in “redesigning work end-to-end, not in more tools,” placing people at the heart of that redesign, and governing AI not as a one-off program, but as a moving target.

Overall, BCG says that strategic clarity, “more broadly emerges from the survey as the most crucial differentiator in sustaining AI’s impact over time as organizations are moving past simply implementing AI tools in use case deployment initiatives.”

Increasingly, it adds, “the focus is shifting to redesigning end-to-end workflows and processes to reimagine functions, as well as to building and innovating new business models and products to drive growth, which have nearly doubled year-over-year.”

Global leader of BCG’s tech build and design unit BCG X Sylvain Duranton, also a report co-author, added, “employees don’t push back on AI intensity; they thrive when the strategy is clear, the direction is real, and the message reaches them.”

He added, “Business value and employee enjoyment aren’t trade-offs. The organizations capturing the greatest business value are the same ones where employees enjoy work the most.”

Despite the opportunity, the report notes that only one-third of frontline employees say that leadership’s communications about AI are clear, and only 28% “see a strong connection between what leaders say and what the organization actually does.”

However, Martin said, management can’t deal with this situation on its own. “CIOs have a critical role, but this is not a problem they can solve alone, and I would not frame it as something IT created by itself,” he noted.

Many organizations, he said, “started with the natural first step of getting tools into people’s hands safely and at scale. That was necessary, but it is not sufficient.”

The next phase “has to be much more cross-functional,” he said. “CIOs should help set the technology foundation, governance, data model, and measurement systems, but they also have an important role in creating strategic clarity. Employees need to understand why the organization is using AI, where it is meant to create value, and how it should change the work.”

Martin pointed out that CIOs should also pay close attention to cognitive load, especially on technology teams, as those teams are often the heaviest AI users.

“This means they may be among the most exposed to the mental strain that can come with reviewing outputs, managing AI tools, and keeping up with constant change,” he observed. The biggest gains come when technology strategy, workforce strategy, and employee experience move together. If AI remains only an IT program, companies will “undercapture” the value.

New expectations

The abundance of AI activity is also having another effect, in that 60% of respondents say the bar for work that counts as ‘good enough’ is now higher.

That, said Martin, is because AI is changing expectations. “If a tool can produce a first draft, summarize research, generate options, or automate a routine task, then ‘good enough’ moves up the value chain,” he said. “People are being asked to spend less time producing basic output and more time exercising judgment like checking quality, improving the answer, making decisions, and applying context.”

While that can be a good thing, he said, because it can make work more interesting and more valuable, “it also explains why employees are feeling more mental strain. The work that remains is often more complex. Leaders need to recognize that AI does not just make people faster, it changes what excellence looks like. That means companies need to update training, performance expectations, and management support accordingly.”

This article originally appeared on CIO.com.

Enterprise Spotlight: Rethinking cloud strategy in the age of AI

3 June 2026 at 07:00

Cloud computing has reached a crossroads. The high cost and data sensitivity of AI workloads are raising the appeal of private clouds, even as neoclouds and sovereign clouds shake up the cloud provider landscape. New cyberthreats, shifting compute requirements, and management complexity are adding to cloud complications.

Download the June 2026 issue of the Enterprise Spotlight from the editors of CIO, Computerworld, CSO, InfoWorld, and Network World, and learn how to navigate the latest cloud strategy developments.

The importance of determining an equilibrium state for space traffic management

2 June 2026 at 14:00

The rapid expansion of human and robotic activity in low Earth orbit makes critically important the need to implement effective space traffic management (STM). This will be one of the […]

The post The importance of determining an equilibrium state for space traffic management appeared first on SpaceNews.

AI hiring monoculture is delivering racial bias at scale

29 May 2026 at 16:49

A research project examining AI-driven recruitment hires across the US has revealed a systemic racial bias.

Researchers from Stanford University found a startling pattern of racial disparities when looking at the interview offers resulting from 4 million job applications submitted to 156 employers. The situation is aggravated by the “monoculture” in AI hiring software: More than 90% of US employers are screening job applicants with software, with 60% of Fortune 500 companies using the same tool, HireVue, the researchers found.

Applicants who applied to multiple companies using AI had all their applications rejected more often than would be expected if each company’s screening methods were independent. They calculated that Black and Asian candidates were rejected in greater numbers than baseline figures would suggest. According to the survey, 29,000 more Asians would have been interviewed if AI had not been deployed.

The researchers are concerned about the way in which AI is being used. “AI screening tools bring together three properties that should not co-exist in high-stakes decision-making: They are pervasively adopted, highly consequential, and opaque to the public,” they said in a news release presenting their work.

The effect of this will lead to workplaces dominated by a monoculture which may not be beneficial for companies going forward.

This article first appeared on CIO.

❌