❌

Reading view

Google unveils DiffusionGemma, an AI model that breaks free of left-to-right processing

Extremely powerful large language models (LLMs) still operate as though they’re typing on a keyboard, processing workloads in a simple left-to-right fashion. But in locally-run, single-user scenarios, this sequential processing can leave graphics processing units (GPUs) and tensor processing units (TPUs) underutilized.

Google is betting that DiffusionGemma can get around this bottleneck. The new experimental open model generates text “exceptionally fast,” creating entire blocks of text simultaneously through diffusion techniques rather than through token-by-token processing. The company says this technique results in 4x faster inference compared to auto-regressive models that rely on sequential processing.

It can also save users money. Technology analyst Carmi Levy noted that existing pay-per-token monetization models “penalize the use of less than optimally efficient AI solutions.”

But DiffusionGemma “could herald a new generation of task-defined, efficient solutions that can enable expanded compute capacity without draining the operations budget,” he said.

A contrast to left-to-right processing

Built on Google’s Gemma 4 family and its Gemini Diffusion research, DiffusionGemma is a 26B mixture-of-experts (MoE) model designed to maximize text output generation.

It essentially shifts how models use hardware, giving processors a larger hunk of work each cycle so it can draft full 256-token paragraphs in sequence. This allows the model to generate text up to 4x faster on GPUs, Google claims. It activates only 3.8B parameters during inference, and, when quantized, can fit within 18GB VRAM on high-end consumer GPUs like Nvidia RTX 5090.

“It upgrades your model inference from a single, sequential typewriter to a massive printing press that stamps the entire block of text simultaneously,” Google research scientists Brendan O’Donoghue and Sebastian Flennerhag wrote in a blog post.

AI image generators begin with pure, random ‘visual noise’ and iteratively refine that into a finalized picture (what’s known as ‘diffusion’); DiffusionGemma applies this same process to text. It does not generate tokens in order, but begins with a “canvas of random placeholder tokens” that it processes in multiple passes, identifying the context tokens it feels are most relevant and using those to refine the rest.

The model has the ability to self-correct, using confidence scoring to re-evaluate tokens in the next pass. “The model iteratively refines its own output, allowing it to evaluate the entire text block at once to fix mistakes in real-time,” O’Donoghue and Flennerhag explained.

DiffusionGemma also has bidirectional attention, they wrote. “Generating 256 tokens in parallel with each forward pass allows every token to attend to all others.” This can be particularly helpful in domains that are non-linear in nature, such as mathematical graphs, code infilling, and in-line editing, they said.

DiffusionGemma is optimized across Nvidia’s hardware stack, making it compatible with consumer setups as well as with high-performance enterprise systems like Hopper and Blackwell.

Because it is released under the Apache 2.0 license, developers can freely use, modify, distribute, and commercialize the software using their preferred tools. It can be run on GPUs or in the cloud through Google Cloud Model Garden or Nvidia NIM, and is available on Hugging Face, GitHub, and vLLM, with support for the open-source library llama.cpp coming soon.

Key use cases

The model is particularly useful in local workflows that are “speed critical,” such as generation of non-linear text structures, and unlocks what Google calls “new patterns of model behavior” like multimodal understanding and generating and rendering code in near real-time.

Levy explained, “DiffusionGemma is particularly well suited for interactive coding and editing where its efficiency allows rapid processing and iterations,” noting that its ability to fit within 18GB of VRAM and its deployability on commonly available local GPUs can potentially benefit customer service-related workloads that lean heavily on real-time interaction and local processing.

“DiffusionGemma also incorporates a thinking mode that is especially adept at problem solving,” he said. For instance, the model was fine-tuned to play Sudoku, a typically challenging task for autoregressive models because each token depends on future tokens. This “rather handily” illustrates the model’s capability to solve more complex problems, Levy noted.

Limitations

Google freely admits that DiffusionGemma is geared to specific workflows, and there are “key trade-offs.”

The model is engineered for small batch size inferencing and low-latency, high-speed generation low-to-medium batch sizes on a “single capable accelerator.”

In high-QPS cloud serving environments, (where infrastructure is designed to handle tens or hundreds of thousands of requests per second with ultra-low latency), DiffusionGemma’s parallel coding “offers diminishing returns,” and can even result in higher serving costs, Google conceded. In addition, its overall output quality is lower than that of standard Gemma 4, which is built for apps demanding maximum quality.

However, Levy noted that while DiffusionGemma “can be less precise than other models in certain workloads,” subsequent refinement cycles could overcome this limitation.

While Google isn’t sharing runtime costs, it’s clear that this is an efficiency play, he added. “When deployed across the kinds of workloads that would optimally benefit from its architecture, DiffusionGemma seems to have the potential to reduce processing overhead and related costs,” he said.

This article originally appeared on InfoWorld.

  •  

Google unveils DiffusionGemma, an AI model that breaks free of left-to-right processing

Extremely powerful large language models (LLMs) still operate as though they’re typing on a keyboard, processing workloads in a simple left-to-right fashion. But in locally-run, single-user scenarios, this sequential processing can leave graphics processing units (GPUs) and tensor processing units (TPUs) underutilized.

Google is betting that DiffusionGemma can get around this bottleneck. The new experimental open model generates text “exceptionally fast,” creating entire blocks of text simultaneously through diffusion techniques rather than through token-by-token processing. The company says this technique results in 4x faster inference compared to auto-regressive models that rely on sequential processing.

It can also save users money. Technology analyst Carmi Levy noted that existing pay-per-token monetization models “penalize the use of less than optimally efficient AI solutions.”

But DiffusionGemma “could herald a new generation of task-defined, efficient solutions that can enable expanded compute capacity without draining the operations budget,” he said.

A contrast to left-to-right processing

Built on Google’s Gemma 4 family and its Gemini Diffusion research, DiffusionGemma is a 26B mixture-of-experts (MoE) model designed to maximize text output generation.

It essentially shifts how models use hardware, giving processors a larger hunk of work each cycle so it can draft full 256-token paragraphs in sequence. This allows the model to generate text up to 4x faster on GPUs, Google claims. It activates only 3.8B parameters during inference, and, when quantized, can fit within 18GB VRAM on high-end consumer GPUs like Nvidia RTX 5090.

“It upgrades your model inference from a single, sequential typewriter to a massive printing press that stamps the entire block of text simultaneously,” Google research scientists Brendan O’Donoghue and Sebastian Flennerhag wrote in a blog post.

AI image generators begin with pure, random ‘visual noise’ and iteratively refine that into a finalized picture (what’s known as ‘diffusion’); DiffusionGemma applies this same process to text. It does not generate tokens in order, but begins with a “canvas of random placeholder tokens” that it processes in multiple passes, identifying the context tokens it feels are most relevant and using those to refine the rest.

The model has the ability to self-correct, using confidence scoring to re-evaluate tokens in the next pass. “The model iteratively refines its own output, allowing it to evaluate the entire text block at once to fix mistakes in real-time,” O’Donoghue and Flennerhag explained.

DiffusionGemma also has bidirectional attention, they wrote. “Generating 256 tokens in parallel with each forward pass allows every token to attend to all others.” This can be particularly helpful in domains that are non-linear in nature, such as mathematical graphs, code infilling, and in-line editing, they said.

DiffusionGemma is optimized across Nvidia’s hardware stack, making it compatible with consumer setups as well as with high-performance enterprise systems like Hopper and Blackwell.

Because it is released under the Apache 2.0 license, developers can freely use, modify, distribute, and commercialize the software using their preferred tools. It can be run on GPUs or in the cloud through Google Cloud Model Garden or Nvidia NIM, and is available on Hugging Face, GitHub, and vLLM, with support for the open-source library llama.cpp coming soon.

Key use cases

The model is particularly useful in local workflows that are “speed critical,” such as generation of non-linear text structures, and unlocks what Google calls “new patterns of model behavior” like multimodal understanding and generating and rendering code in near real-time.

Levy explained, “DiffusionGemma is particularly well suited for interactive coding and editing where its efficiency allows rapid processing and iterations,” noting that its ability to fit within 18GB of VRAM and its deployability on commonly available local GPUs can potentially benefit customer service-related workloads that lean heavily on real-time interaction and local processing.

“DiffusionGemma also incorporates a thinking mode that is especially adept at problem solving,” he said. For instance, the model was fine-tuned to play Sudoku, a typically challenging task for autoregressive models because each token depends on future tokens. This “rather handily” illustrates the model’s capability to solve more complex problems, Levy noted.

Limitations

Google freely admits that DiffusionGemma is geared to specific workflows, and there are “key trade-offs.”

The model is engineered for small batch size inferencing and low-latency, high-speed generation low-to-medium batch sizes on a “single capable accelerator.”

In high-QPS cloud serving environments, (where infrastructure is designed to handle tens or hundreds of thousands of requests per second with ultra-low latency), DiffusionGemma’s parallel coding “offers diminishing returns,” and can even result in higher serving costs, Google conceded. In addition, its overall output quality is lower than that of standard Gemma 4, which is built for apps demanding maximum quality.

However, Levy noted that while DiffusionGemma “can be less precise than other models in certain workloads,” subsequent refinement cycles could overcome this limitation.

While Google isn’t sharing runtime costs, it’s clear that this is an efficiency play, he added. “When deployed across the kinds of workloads that would optimally benefit from its architecture, DiffusionGemma seems to have the potential to reduce processing overhead and related costs,” he said.

  •  

Inside the coming war over face cameras

Several trends are now converging that threaten to pit tech companies against the general public. 

Miniaturization has finally enabled companies to build AI glasses that look and function like normal glasses, but with microphones and cameras. People are increasingly talking to AI, rather than typing. And multimodal input, especially video, is on the rise. 

Put all of these trends together and you get a nascent industry pushing toward all-day, everyday AI glasses with cameras — and a worried public already pushing back at  the idea.

Let’s look at how we got here.

Meta started it with a surprise hit: its second-generation Ray-Ban Meta glasses, which later gained multimodal AI capability. Its Meta Ray-Ban Display glasses add one in-lens screen — but both versions of the glasses have cameras. (The company is working on a third generation that will probably ship next year.)

Google provides the AI and software platform through Android XR and Gemini, partnering with hardware makers to put its AI on other companies’ glasses. At Google I/O last month, Google unveiled frames from Gentle Monster and Warby Parker running Android XR with Gemini AI; they’re scheduled to launch this fall. Google is working on two types of AI glasses, one with screens and one that is audio-focused. Both types have cameras, though. 

Samsung is working to launch AI-powered smart glasses, too, code-named “Jinju.” The company offered up details at Google I/O alongside Google. The glasses feature a 12-megapixel camera with autofocus; run on Android XR with Gemini AI; are co-designed with Gentle Monster and Warby Parker; and are slated to launch in July at the Samsung Unpacked event. 

(As with Meta and Google, Samsung is working on AI glasses with and without screens, but both of its models have cameras.)

Tech giant Apple is also on the glasses train, based on reporting from anonymous insiders. Codenamed N50, the Apple glasses could have two cameras, one for pictures and videos, the other for multimodal AI input and hand-gesture control. (Apple is also working on a pendant and next-gen AirPods, both of which have cameras.) 

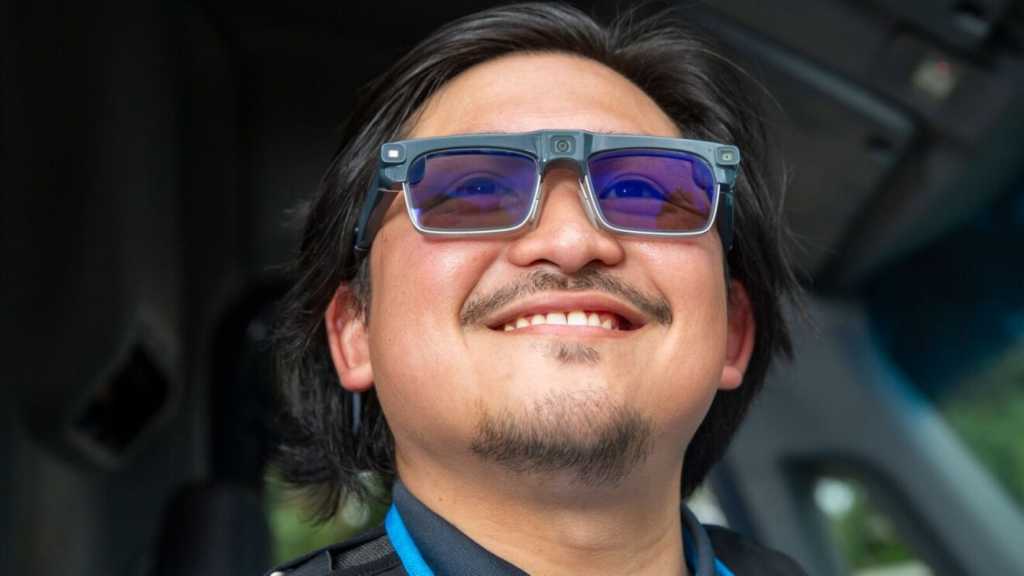
There’s Amazon, which is reportedly developing a new line of consumer AI glasses with a camera after its earlier, camera-less Echo Frames and Carrera Smart Glasses lines failed. (My guess is the problem was Alexa, not the lack of cameras.) Although its Echo Frames have been effectively discontinued — displayed as sold out online — the company is already testing AI glasses with cameras for enterprise use on hundreds of US-based Amazon drivers. 

Amazon Smart Delivery Glasses

Amazon Smart Delivery Glasses

Amazon

Huawei in April launched its AI Glasses for the Chinese market — the lightweight glasses sport a dual-engine AI architecture and integration with its HarmonyOS ecosystem. It’s joined there by Xiaomi’s AI Smart Glasses, which are powered by the company’s HyperOS ecosystem and have cameras for photos and videos and for for reading QR codes. 

Beyond those well-known firms, other companies are making daily-wear AI glasses with cameras in them, including XREAL, Rokid, TCL, Solos, and Brilliant Labs.  

A minority of other companies is focused on glasses without cameras, including Even Realities (G1 and G2); MIRA (MIRA glasses); Dymesty (Dymesty AI glasses); Lucyd (Lucyd Lyte); and Huawei (Eyewear 2).

Get the picture?

Clearly, by the end of the year, the market will be flooded with all manner of AI glasses designed for everywhere, everyday wear. They can use prescription lenses or serve as sunglasses — and most of them will have cameras built in for photos, videos and multimodal AI. 

There’s just one problem: The public hates AI glasses with cameras.

Return of the ‘Glassholes’?

As we learned from Google Glass, a lot of people feel uncomfortable with a camera pointed at them while they’re talking to someone. And that backlash is back with the current generation of AI glasses. 

Because Meta is the market leader in the US, its Ray-Ban Meta glasses have borne the brunt of early disaffection. 

Texas Attorney General Ken Paxton recently launched a formal investigation into Meta’s AI glasses, calling them “a privacy nightmare for Texans,” claiming the devices “can easily invade personal privacy by collecting biometric data and recording Texans without their knowledge or consent.” 

Paxton also claimed the LED light on the glasses, which is designed to alert others that the camera is taking pictures or videos, can be easily defeated. In fact, some modders-for-hire charge up to $100 to physically destroy the LED and TikTok videos describe how to disable or cover the light. 

The pushback is happening elsewhere. Philadelphia courts banned smart Meta AI glasses with recording features from city courthouses and a petition is circulating to ban them from New York City bars and restaurants. MSC Cruise Line banned smart glasses in all public areas. And restaurants, gyms, and workplaces have begun banning smart glasses because of the camera. 

Uncertainty drives some of the concern. People don’t know whether they’re being recorded, and if they are, they don’t know who will see the video. It turns out, those  suspicions might be warranted. 

In February, Swedish publications Svenska Dagbladet and Göteborgs-Posten published an investigation that found Meta contractors in Kenya were reviewing footage from Ray-Ban Meta smart glasses — including “bank details, sex and naked people who seem unaware they are being recorded.” 

The New York Times published an internal Meta memo in February describing plans to add facial recognition (“Name Tag”) to Ray-Ban Meta glasses. The memo said the “political tumult in the United States would distract critics from the feature’s release.”

Then earlier this month, WIRED discovered dormant facial-recognition code called “NameTag” hidden inside Meta’s AI companion app. The code would let Ray-Ban Meta glasses identify strangers by face, a feature Meta publicly claimed “does not exist.” Meta quietly erased the code with an update one day after the exposé was published.

A coalition of civil society organizations wrote Congress to demand that Meta abandon its Name Tag facial recognition plans, calling it a “creepy and unacceptable escalation of surveillance.” The letter warned the technology could be adopted by law enforcement to surveil immigrants, people of color, and nonviolent protesters.

Finally, a range of reports involving AI glasses with cameras in them has emerged in recent months involving secret recording, harassment and extortion. 

The coming conflict over face cams

On one hand, all the biggest consumer electronics companies are either shipping AI glasses with cameras in them or planning to do so — and many smaller companies are looking to do the same. The industry expects AI glasses with cameras to go totally mainstream. 

On the other hand, a growing public, legal and legislative backlash has erupted in opposition to AI glasses with cameras in them. 

One possible outcome is that the public disdain for the cameras will fade, overwhelmed by widespread enthusiasm for the benefits they offer. A new social norm might emerge that mirrors the broad acceptance of everybody having cameras in their phones and pointing them in random directions. 

Another possibility is that companies will be forced by consumer disdain and legal action to abandon cameras in glasses and focus instead on AI glasses that can’t take pictures or use video for multimodal AI input. 

Either way, the war is surely coming. 

  •  
❌