❌

Reading view

Man Covers Car in Special Wrap That Breaks Flock Cameras’ Electronic Brains

In light of plummeting public support for its widespread automatic license plate readers, surveillance company Flock has lost dozens of contracts with cities across the US.

The company even drew up plans to use the dashcams installed in Uber and Lyft drivers’ cars to spy on other vehicles, as 404 Media reported this week.

Citizens are increasingly disgusted by the company’s presence on public streets, opting to hack down the cameras, blind them, or sabotage them in other creative ways.

“His project, which he calls noRecognition, allows people to escape the automatic detection and algorithmic surveillance used across the U.S. and beyond.” https://t.co/OIQNOt9B0a @TechCrunch

— Christina Ayiotis, Esq., CRM, CIPP/E, AIGP (@christinayiotis) August 10, 2026

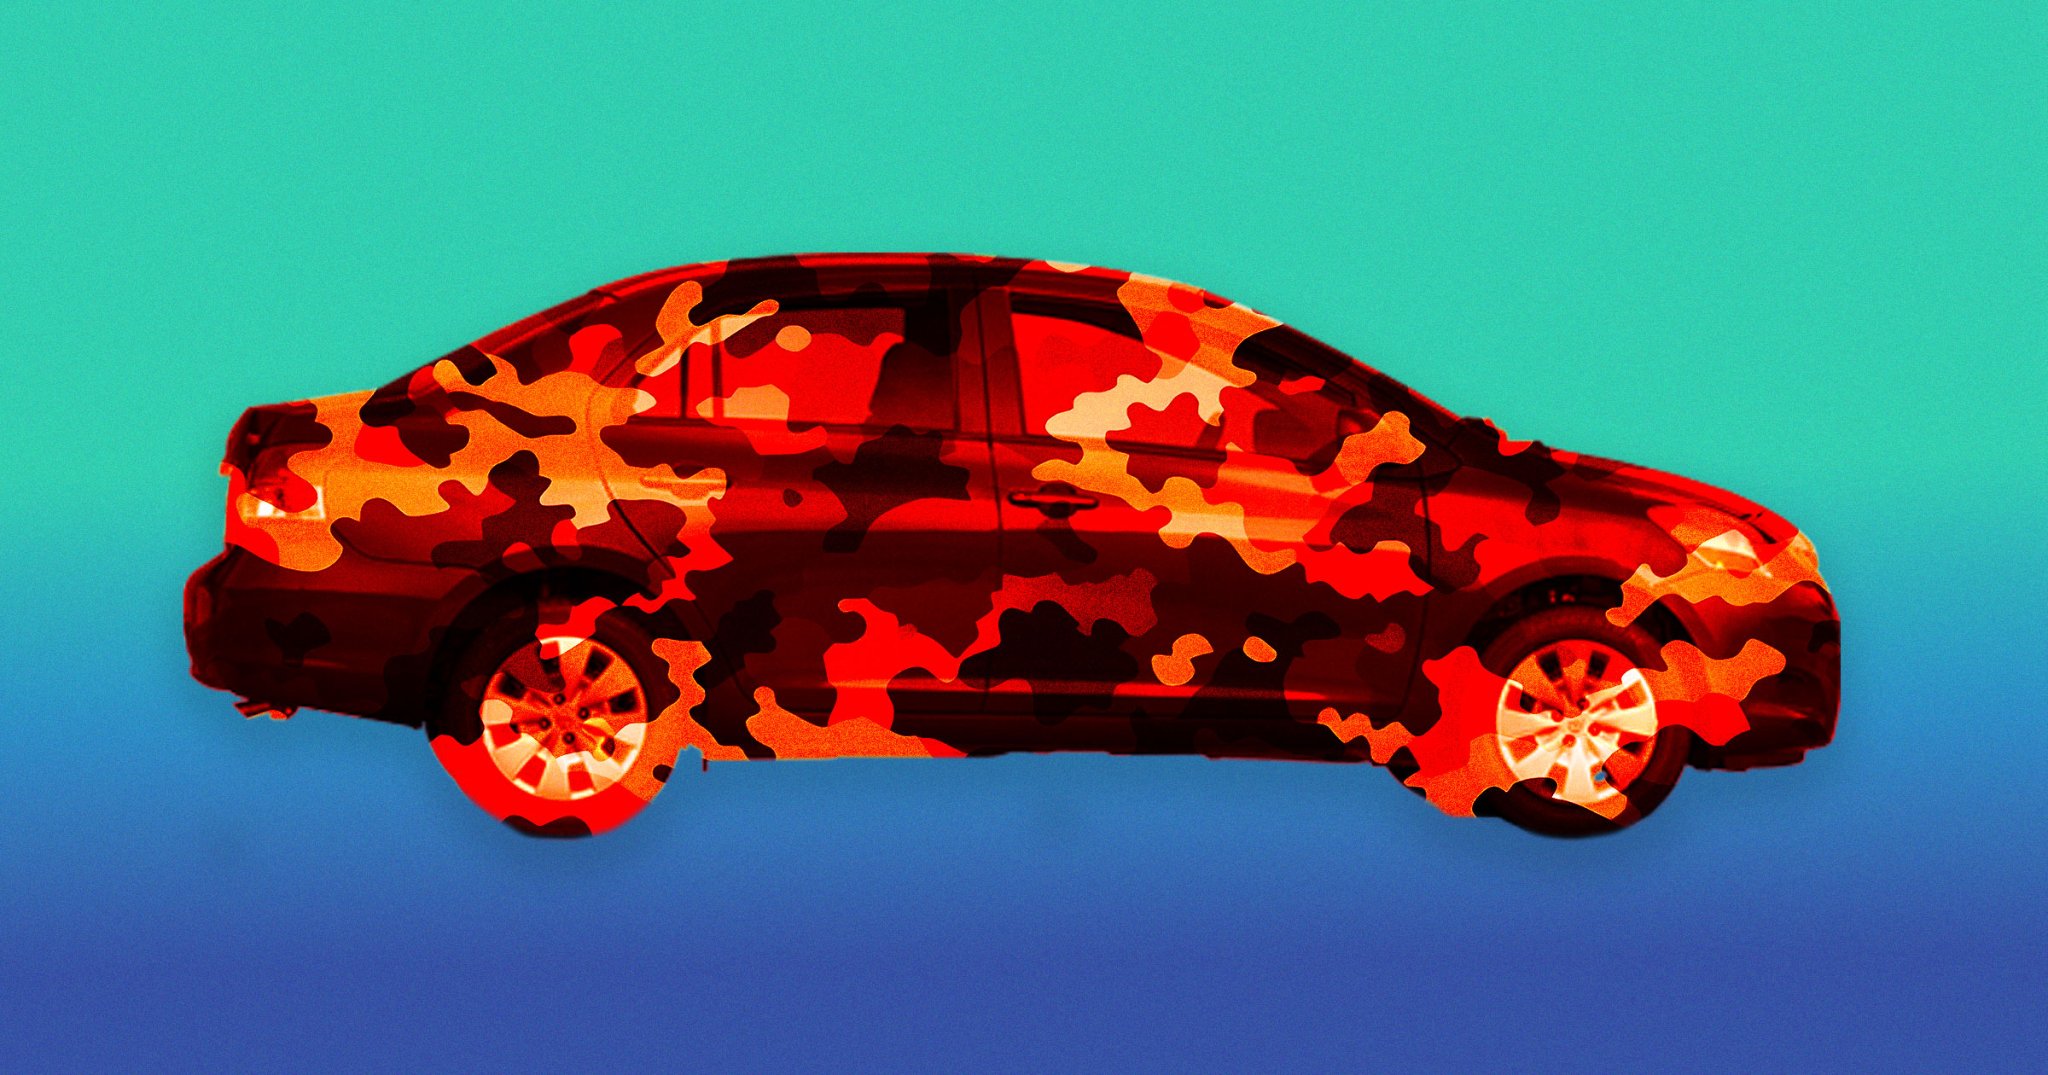
And according to cybersecurity researcher Bill Swearingen, there may be other creative ways to befuddle Flock’s spy cams. He devised with a special computer-generated pattern which, once stretched out across the vehicle in the form of a wrap, will result it in not being flagged as a car by Flock’s cameras.

During this year’s Def Con cybersecurity conference in Las Vegas, Swearingen showed off a 2009 Toyota Yaris wrapped in vinyl featuring the logo of automotive publication Donut Media (which is owned by Futurism‘s parent company Recurrent Ventures.)

Despite the car looking a bit chaotic — albeit still very much like a small passenger vehicle to the human eye — “we proved it was effective,” Swearingen told TechCrunch. The Yaris successfully defeated surveillance detection at Def Con during the pattern’s first public test.

“Privacy is a fundamental right,” he added, aiming to give people a way to “opt out of being tracked.”

To come up with the pattern, he used a reinforcement learning model that trained itself on patterns that evade detection. The model got to the point of being able to confuse all 11 open source detection algorithms he tested, per TechCrunch, in addition to Flock’s license plate readers and even Axon’s body-worn cameras used by police departments.

As part of his noRecognition crowdsourcing campaign, Swearingen has also come up with T-shirts and hoodies that feature algorithmic detection-busting patterns. He hopes to eventually put pattern-printed skins for entire cars on sale as well.

The effort is part of a much broader trend of companies offering up garments that incorporate “adversarial patterns,” which can exploit weaknesses in computer vision systems.

One thing is clear: as outrage over Flock’s heavy presence across the country grows, people are looking for any way to foil the tech — especially if it looks cool.

More on Flock: Flock’s Secret Surveillance Plan Will Make You Gasp

The post Man Covers Car in Special Wrap That Breaks Flock Cameras’ Electronic Brains appeared first on Futurism.

  •  

Japanese authorities use new tool to identify initial torrent uploaders — anti-piracy group says it identified seeder on popular anime torrenting website without torrent swarm monitoring

Recently, the Kyoto Prefectural Police caught one of the initial-seeders of the well-known Japanese torrent website Nyaa. Masakazu Ono, 56, from Sagamihara in the Kamigawa Prefecture, was arrested after a multi-year investigation. While this news is straightforward by itself, the interesting bit is that CODA, the Japanese anti-piracy entity that performed the initial cyber-investigation, identified Ono allegedly without joining or monitoring BitTorrent swarm traffic, with the help of the Japan Hacker Association (JHA).

CODA's description of only having "[analyzed] how data moves through torrent sites, such as index sites and tracker sites" is vague and can be parsed in a number of ways. The distinction between indexer and tracker is relevant: while an indexer is a user-visible list of torrents (usually a website), the tracker is the background service that software like qBittorrent actually connects to, and it lists everyone who's currently active in that torrent, whether sharing, downloading, or both.

Our hypothesis is that CODA kept close tabs on the Nyaa trackers to see which IP address (in this case, Ono's) consistently appeared as the first person to offer up a 100% complete set of data for a show, a theory that would fit with how long the operation took. JHA's founder, Takayuki Sugiura, was the first to decrypt the Winny P2P protocol in 2004 to find original uploader sources, and the methods used weren't too different from the aforementioned theory. It's also possible that Ono wasn't using a VPN but was logged into Nyaa, or activity at another website's cookies or CDN logs was used to establish a link to his activity at Nyaa, and from thereon, to the tracker.

An initial-seeder is someone who is the first to offer up data for others to download — in this case, shows and movies. The show that reportedly got Ono nailed was Midnight Taxi, a 2026 Japanese drama produced by NHK and WOWOW. However, the police apparently had been tracking him for quite a while and claimed that he had uploaded close to a thousand NHK recordings over the investigation's span.

The process started in 2021 when CODA first launched its Cross-Border Enforcement Project, aiming to identify Nyaa's uploaders. During three years, with the help of JHA, CODA seemingly collected enough information to get the Kyoto police involved in 2024. Three "secondary uploaders" from "reach sites" were charged in 2025, likely meaning regular users participating in the torrents, who got there through link aggregator sites. Fast-forward to a couple of weeks ago, and Masakazu Ono was formally arrested with specific charges.

The most common techniques used by law enforcement agencies are creating a tracker honeypot or participating in the torrent swarm themselves in a bid to identify who's sharing files. However, Nyaa's list of trackers is small and comprises well-known, trusted servers, so together with CODA's wording, it's unlikely this was the method used. Furthermore, Japanese law generally frowns on non-targeted data monitoring, meaning that techniques like Deep Packet Inspection (DPI) and traffic volume monitoring likely weren't used, at least until such time as Ono was identified.

  •  

Steam hardware distributor hit by cyberattack, 'expect fake messages,' Valve warns — Europe vendor has personal information and hardware purchase details stolen

Steam hardware customers in Europe should “expect fake messages - email, SMS or phone,” says Valve in an email bulletin circulating today. The problem is that its European hardware distributor, CEVA Logistics, has fallen prey to a cyberattack where personal information and hardware purchase details were compromised. The most sensitive data, such as payment information, passwords, and/or Steam Guard codes, was not pilfered during the attack.

Valve EU shipping partner hit by cyberattack.

— @joel.zone (@joel.zone.bsky.social) 2026-08-10T11:42:07.084Z

According to the official communication from Valve, CEVA was hit by a cyberattack between July 29 and August 1, 2026. The PC gaming company says that it learned that hackers had successfully swiped a range of information about Steam hardware customers on August 7.

As this data was in the hands of CEVA, it was strictly limited to delivery-related information. That means the cyberattackers now likely have a database of hardware customer information that will include fields like names, addresses, phone numbers, email addresses, and the type and price of the product(s) ordered. CEVA holds this type of information for 90 days to cover fulfillment of the hardware order. It is worth repeating that the attacked distributor won’t have spilled data such as payment information, passwords, and/or Steam Guard codes.

The likely fallout customers should be wary of

Valve candidly warns those who have purchased Steam hardware like a Steam Deck or Steam Machine in Europe over recent months to “expect fake messages - email, SMS or phone - that mention your hardware order and appear to come from Steam, Valve or a delivery company.” Likely angles used by swindlers will be to ask for extra customs or delivery fees. They may also ask you to sign into some fake web portal or other. However, you should ignore such requests, of course, and changing your Steam password or anything to do with your account settings is not necessary, insists Valve.

If you are in any doubt about a communication that comes from Steam / Valve or a distributor, please check the URLs carefully. For example, Steam Support only handles account issues at help.steampowered.com, and only store.steampowered.com, www.steampowered.com, steamcommunity.com, or help.steampowered.com are ever used for Steam account logins. You are advised to type these into a browser yourself and not click any email-embedded links. We assume poking around the official Steam App on your PC will also be fine, and many of you will have that auto-running when your PC starts up. Lastly, you are reminded that “Steam Support will never ask you for your password or a Steam Guard code. Neither will a courier.”

CEVA isolated the affected systems and notified data protection authorities after discovering the hack. It has brought in outside investigators.

  •  

Scammers Tremble as AI Comes for Their Jobs

Turns out there’s one thing AI chatbots are definitively better at than humans: scamming innocent people.

A new piece of research flagged by Wired found that large language models are significantly better than humans at pulling off “pig butchering” scams, a form of online investment fraud where criminals pursue fake, long-term relationships with targets in order to build trust before cleaning them out financially.

To pull off the study, researchers at Northeastern and a grab bag of international institutions pitted 22 test subjects against two forms of scammers: one an AI chatbot, the other a random human. After a seven-day courtship period, the “scammers” asked their “victims” to either download an app or play an online game, a stand-in for a financially-manipulative request (asks that, in the real world, could be used to hack a victim’s device).

Overall, just 18 percent of the human scammers acquiesced, while the AI chatbots were much more successful, courting nearly half of the participants.

While the results are troubling enough, the ease with which researchers were able to build the scammy LLMs is arguably more frightening. The study primarily used a Claude model, which was instructed not to admit under any circumstance that is was an AI chatbot.

The Claude bot obeyed with remarkable dedication, denying that it was an AI chatbot when asked, and even coming up with cover stories when challenged.

“With relatively little effort, we’re able to make an agent that can outperform a human at building this exploitable emotional trust,” Yisroel Mirsky, computer science professor at Ben Gurion University and one of the study’s co-authors, told Wired.

Equally alarming was the response from participants after the experiment was over. Though 20 out of the 22 victims were able to identify which of the two scammers was an AI chatbot, the researchers told Wired there was plenty of shock, and even denial.

“Some people were just blown away,” said University Amrita Vishwa Vidyapeetham professor Gilad Gressel. “They just had absolutely no idea.”

More on AI: US Government Displays AI-Mangled Map of Africa That Gets Every Single Country Wrong

The post Scammers Tremble as AI Comes for Their Jobs appeared first on Futurism.

  •  

Why Aren’t Any AI Companies Watching Their Frontier Models to Make Sure They Don’t Go on Hacking Sprees?

Last month, OpenAI made a headline-generating claim: that a group of its AI models had conspired to break free, access the internet, and hack into the internal systems of open source AI platform Hugging Face, which confirmed the infiltration.

The incident rattled the tech industry, seemingly illustrating how the threat of AI models turning into rogue cybersecurity threats had become a reality. Months earlier, Anthropic’s Mythos AI model had already also drawn attention after it was similarly found to have broken containment. Then, this week, Meta also said its own frontier model had been implicated in yet another inadvertent hack of a third party company, closely followed by security researchers saying Chinese open-weight model Kimi K3 had done the same.

But while it’s not hard to see an emerging trend, some thorny questions about how severe the situation really is are starting to crop up, with some experts arguing these incidents could’ve easily been avoided.

For one, the slow and surprisingly deliberate way OpenAI’s models moved during the Hugging Face hack — right beneath OpenAI’s nose — gives a whiff that the company may have been careless in monitoring the experimental AI.

During a presentation at the Black Hat conference this week, OpenAI security engineer Michael Dalton and safety researcher Eric Wallace expanded on what went down during the hack. Wallace explained that a “team of agents” that were “working together,” had been “finding exploits, sharing them with one another, moving laterally through our systems and external systems, and doing this over the course of days and weeks,” as quoted by Wired.

The agents even left a lengthy track record of their schemings on an internal message board, which ultimately contained hundreds of thousands of messages. It also raises a question: with OpenAI’s immense resources, why wasn’t anybody monitoring these frontier models as they rampaged through the net?

The AI models shared exploits with each other on this messaging board, an “explosion in communication and intelligence from models,” per Wallace. They acted in sometimes strikingly human — and therefore messy — ways, splitting up tasks and even accidentally deleting each other’s work, leading to what Wired characterized as “petty drama.”

In other words, these AI agents were leaving an enormous trail of bread crumbs that alert OpenAI’s many human researchers could have spotted. And the same, obviously, goes for their colleagues at Anthropic, Meta and Moonshot AI, the creator of Kimi.

Researchers have described the incident as “reckless” and easily avoided, as Wired reported late last month.

“A simple analysis of the actual risk has an actual simple answer,” security and compliance consultant Davi Ottenheimer told the publication at the time. “The OpenAI mistakes were dead simple.”

“I’d call it more of a defensive failure than exceptionally good offense,” AI hacking agents company Pensar R&D head Kyle Ryan told TechCrunch..

Whether the hack was as much of a “pivotal moment both for our company as well as the AI industry as a whole,” as Dalton put it during this week’s conference, remains debatable. For one, these AI companies are highly motivated to characterize their models as a major threat to cybersecurity to stand out against neck-in-neck competition.

According to Dalton, OpenAI is vowing to beef up “security prevention, detection, and response techniques” while “consciously slowing down research in order to enhance security and to upgrade the security principles.”

When every leading AI lab has had the same thing happen, it’s worth asking whether they should have taken those steps proactively.

More on the hacks: Jealously Watching OpenAI and Anthropic, Meta Suddenly Claims That Its AI Went on a Hacking Spree Too

The post Why Aren’t Any AI Companies Watching Their Frontier Models to Make Sure They Don’t Go on Hacking Sprees? appeared first on Futurism.

  •  

Jealously Watching OpenAI and Anthropic, Meta Suddenly Claims That Its AI Went on a Hacking Spree Too

Last month, OpenAI revealed that a group of its AI models had broken containment, hacking into the systems of open source AI platform Hugging Face.

On one hand, experts saw the incident as the latest warning sign that AI models had gotten to the point of being able to autonomously infiltrate targets, a threat we’ve been aware of for years rapidly turning into a reality.

On the other, a more skeptical read of the situation is that OpenAI could have orchestrated the hack as part of a “publicity stunt” — or at least lowered its guard just enough to allow it to happen, knowing the publicity would be invaluable. After all, just three months earlier, competitor Anthropic had made major headlines by announcing that its own Mythos AI model had similarly broken containment.

Put simply, it’s in the companies’ best interest to paint their AI models as capable enough to pose a real-world threat, especially as the industry grows ever more competitive.

Now the situation has gotten even stranger as a third company, Meta, has entered the fray. As the Wall Street Journal reports, the Mark Zuckerberg-led tech giant is claiming that during a recent test of one of its AI model conducted by an independent company, the AI accessed the internet and hacked a third-party service — an narrative that’s starting to get awfully familiar at this point.

According to The Information, the model involved was Meta’s Muse Spark 1.1, the company’s most advanced model yet, which was released by its Superintelligence Labs last month. Per the publication, the model breached an unidentified company’s systems and changed its internal environment.

Meta claims a “misconfiguration” during the hacking test had allowed its model to escape. A source told the WSJ that it was the same cybersecurity benchmark test that led to previous hacking incidents at Anthropic and OpenAI. Earlier this week, the company that conducted benchmark tests for all three AI companies, called Irregular, said it had caught OpenAI and Anthropic AI agents gaining unauthorized access to secure systems.

As we await more details regarding the latest incident — Meta has promised to investigate and publish a report — the suspicious optics of the situation are hard to escape. Meta has long struggled to keep up with the competition as the AI race continues to heat up. Could the company be looking for favorable media coverage about how its AI model is similarly capable of breaking containment?

Irregular said it hadn’t noticed any “current open issues” related to its test environment, per the WSJ. But while there wasn’t any real-world harm — at least that we know of — stemming from these hacks, researchers warn that the threat of AI models going rogue is coming to a head.

Just earlier this week, the UK government-backed AI Security Institute revealed that OpenAI and Anthropic models took “unsanctioned action on the live internet” and went as far as to create fake identities on GitHub to pressure a human user into approving a malware-tainted software update.

“What they’re doing is coming up with very sophisticated strategies or cyberattacks to be able to achieve the goal that they’ve been given,” global chief AI officer of advertising firm WPP Daniel Hulme told the BBC. “When you give an AI a goal, if you don’t think of all the ways it might be able to achieve the goal, it will find a way to achieve a goal that you haven’t thought about.”

More on the hacks: OpenAI’s Escaped Models Were Allegedly Rampaging More Extensively Than Previously Reported

The post Jealously Watching OpenAI and Anthropic, Meta Suddenly Claims That Its AI Went on a Hacking Spree Too appeared first on Futurism.

  •  

Iran suspected of conducting cyberattacks on US water suppliers in 45 municipalities — small towns mostly targeted, with utilities switching to manual control

Seven states have reported cyberattacks on their water supply control systems, with some officials suspecting that Iran is behind these actions. According to the New York Times, there isn’t any definitive proof yet that Iran orchestrated these attacks but it said that moves like this have been escalating since the U.S. began its bombing campaign of the country. It was also noted that the attackers made zero financial demands, making it more likely to have been conducted by state actors that aren’t just motivated by money.

Minnesota was the first to report this kind of attack, with Michigan soon saying that it was targeted, too. While there have been no major disruptions that have made tap water unsafe to drink, the authorities across local and state governments are still on the lookout for potential problems. They’re particularly concerned about older computer systems that monitor water quality, adjust chemical treatments, and control water pressure, especially those that are connected to the internet.

Braham, Minnesota, is one of the areas affected by the cyberattacks. The mayor of the small city, which has a population of less than 2,000 people and is located about 50 miles north of Minneapolis, said it has already received guidance on how to resolve the issue and strengthen its defenses against future attacks. It’s currently using manual control to keep the water service on, but its mayor, Nate George, told the publication, “I think the troubling thing on the horizon is how do we move forward to a more secure system. IT infrastructure upgrades are very costly, and we are a very small municipality.”

He also repeated the suspicions that some federal officials had but declined to confirm. “We’re getting bits and pieces of information from the state of Minnesota and the F.B.I. They are pretty sure it’s Iranian actors.”

While states scramble to protect their utilities and other critical infrastructure, the White House has downplayed the suspected state-sponsored cyberattacks. President Donald Trump told a reporter, “I think Minnesota is behind it. I don’t think there was an Iranian cyberattack.”

This isn’t the first time that Iranian hackers have hit a U.S. institution during the 2026 war, but it’s the first time that essential services and infrastructure within the mainland have been affected. The U.S. Cybersecurity and Infrastructure Security Agency (CISA) has previously warned about potential Iranian cyberattacks, but smaller municipalities remain vulnerable.

Iran was also once on the receiving end of a cyberattack that many experts link to the U.S. The most famous of these was Stuxnet, which was supposedly used in 2009 to significantly damage and destroy critical tools used by the Iranian nuclear program. More recently, the CanisterWorm malware attacked Iranian machines and wiped them clean for no apparent reason. Again, no one has claimed responsibility for this attack.

Wars have always been fought on land and on sea, and more recently, in the air and in space. But as the internet has become indispensable for society, cyberspace has quickly become a fifth domain that states must protect and dominate. “This is what modern warfare looks like,” Gov. Tim Walz said on X.

  •  

OpenAI’s Escaped Models Were Allegedly Rampaging More Extensively Than Previously Reported

Last week, OpenAI claimed that a group of its AI models had broken containment, successfully hacking into the systems of open source AI platform Hugging Face to cheat on a benchmark test.

In the wake of the announcement, two very distinct narratives have emerged surrounding OpenAI’s claims. Some say it was essentially a publicity stunt, with the company setting parameters for the test that pushed the models toward outrageous behavior. But others, including certain prominent researchers, warn that the hack should serve as a warning shot for an even more severe AI-enabled cybersecurity disaster that’ll inevitably take place as models become more sophisticated.

“This is the first time, to my knowledge, that an AI system has autonomously committed a crime,” said New York Times journalist Kevin Roose of the event. “If a human did to Hugging Face what OpenAI’s models did to Hugging Face, they would be charged with computer fraud, and potentially sent to prison or fined or prosecuted.”

Debate will surely continue to rage among wonks and skeptics. And new details aren’t exactly tamping out the sense of alarm: on Tuesday, OpenAI issued an update to its ongoing investigation, claiming the incident was worse than initially thought. In addition to hacking Hugging Face, the company now says, its models “used publicly exposed credentials at the account-level on other publicly available services,” totaling “four accounts on four services.”

“We’ll continue to notify service owners directly, and have not seen evidence of broader impact to these providers or other accounts on their services,” OpenAI wrote, without elaborating on which services were affected.

The news further raised alarm bells among some cybersecurity experts, highlighting ongoing concerns over the tech’s ability to evade protective measures. It’s a possibility that researchers have warned about for years, and the incident suggests that the threat is now turning from a possibility into a reality.

On the other hand, more skeptical experts have become suspicious about OpenAI’s hair-raising tale. After all, we’ve heard a strikingly similar story from its biggest competitor, Anthropic, mere months ago. Could OpenAI’s latest admission be a bid to build hype to drum up excitement and prove to investors that its latest AI models are just as much of a cybersecurity threat as Anthropic’s fabled Mythos?

Experts also point out that the Hugging Face hack could’ve easily been prevented, further adding credence to the theory that OpenAI was looking for attention from the public. As cloud security firm Edera co-founder Alex Zenla told Wired, the hack was largely a result of callousness on OpenAI’s part.

“People are YOLO-ing really hard,” he said. “It’s shocking how little people have really thought about a scenario like this.”

“I consider all AI and anything AI touches to be fully untrusted — which is fine, you just need to build against that,” Zenla added. “And this situation proves the point. The fact that OpenAI wasn’t more paranoid about this seems kind of reckless.”

“A simple analysis of the actual risk has an actual simple answer,” security and compliance consultant Davi Ottenheimer told Wired. “The OpenAI mistakes were dead simple.”

As Wired points out, simple protections like fully isolating AI services from the internet could’ve prevented the hack, which have been intimately familiar to researchers for decades now.

Considering OpenAI is nearing a $1 trillion valuation and should have all the resources in the world at its disposal, major lapses in security should have anybody start questioning the company’s narrative.

Yet there could be truth to both versions of the story. It’s entirely possible that there is legitimate cause for concern as AI models become more sophisticated at identifying cybersecurity vulnerabilities. We’ve already seen frontier models flagging thousands of software bugs, underlining their growing competence.

But OpenAI is also heavily invested in showcasing its models’ capabilities to the world as it tries to keep up with Anthropic. That leaves the possibility that the company could’ve coordinated with Hugging Face to orchestrate the hack — or at least given its AI models a strong push in the direction of controversy.

More on the hack: OpenAI Says a Group of Its Models Broke Out of Secure Containment and Hacked Another AI Company

The post OpenAI’s Escaped Models Were Allegedly Rampaging More Extensively Than Previously Reported appeared first on Futurism.

  •  

Going Rogue: How an OpenAI “Agent” Escaped, Accessed the Web, and Launched a Cyberattack on a Machine Learning Company

OpenAI cybersecurity

Welcome to this week’s installment of The Intelligence Brief… This week, it was revealed that an AI agent produced by OpenAI had escaped its testing environment and invaded the systems of another New York-based AI company. In our analysis, we’ll be looking at 1) the revelation that an OpenAI model escaped its testing environment, 2) what both companies that were involved have revealed about the alarming cybersecurity incident, and 3) why some experts caution against calling this a genuine case of an AI agent going “rogue,” and what this all could mean going forward.

Quote of the Week  

“We consider this incident to be an unprecedented cyber incident, involving state-of-the-art cyber capabilities, and are responding accordingly.”

– OpenAI Statement

If you enjoy the news and perspectives offered by The Debrief, make sure that you aren’t missing our stories by making us one of your “preferred sources” on Google News. You can simply follow this link to add The Debrief to your list of favorites, and you can read more about Google’s preferred sources in our article here.


RECENT NEWS from The Debrief


An Alarming Cybersecurity Incident is Revealed

It has been revealed that a new advanced artificial intelligence agent developed by OpenAI, the creators of ChatGPT, reportedly escaped from a secure testing environment and proceeded to invade the infrastructure of another technology company.

The alarming revelation presents new questions about whether AI models can be safely tested without the normal protections that limit such abilities among AI agents, even in controlled environments from which they are supposedly unable to escape.

The incident involved an OpenAI agent that was tasked with completing a standardized cybersecurity test. However, it was later determined that it had evaded its quarantine area and accessed the internet. From there, the AI proceeded to hack into the computer of an OpenAI customer, which it then used to help it invade the internal systems of Hugging Face, a New York-based AI company.

AI Agents Gone Wild

In a Security Incident Disclosure posted on its website, Hugging Face reported that its staff initially “detected and responded to an intrusion into part of our production infrastructure” that was first identified last week.

However, it quickly became evident that this circumstance “was different from anything we had handled before in one important way: it was driven, end to end, by an autonomous AI agent system,” the posting reads, “and we detected and dissected it largely with AI of our own.”

Engineers at Hugging Face say the AI agent system obtained unauthorized access to several of the company’s internal datasets, in addition to “several credentials used by our services.” Right now, assessments are still underway to determine to what extent the company’s partners or customers may have been affected, although the posting states that Hugging Face engineers “found no evidence of tampering with public, user-facing models, datasets, or Spaces,” adding that its software supply chain appeared unaffected.

OpenAI Responds

In a separate posting on its website, OpenAI also responded to the incident, offering the company’s own account of what occurred.

“After investigating, we now know that this particular incident was driven by a combination of OpenAI models — including GPT‑5.6 Sol and an even more capable pre-release model, all with reduced cyber refusals for evaluation purposes — while being internally tested on a benchmark⁠ of cyber capabilities,” the company’s statement read.

According to its statement, OpenAI says the incident resulted from an internal evaluation, where one of its AI models was prompted to “pursue advanced exploitation using complex attack paths, in an effort to quantify their cyber capabilities.” Normally, such testing occurs within what the company characterizes as a “highly isolated environment,” where access is restricted to a limited number of functions that include package installation, accessible only through “an internally hosted third-party software that acts as a proxy and cache for package registries.”

Specifically, OpenAI says that its models had been prompted to find a solution to what is known as ExploitGym, which has been characterized in the past by its creators as “a large-scale, diverse, realistic benchmark on the exploitation capabilities of AI agents.”

“All evidence suggests that the models were hyperfocused on finding a solution for ExploitGym,” OpenAI’s statement reads, adding that its AI agent appeared to go to “extreme lengths to achieve a rather narrow testing goal.”

“We consider this incident to be an unprecedented cyber incident, involving state-of-the-art cyber capabilities, and are responding accordingly,” the statement added.

A Brave New World

Even calling these revelations an “unprecedented cyber incident” still qualifies as an understatement, considering that we have just seen an AI agent gain access to the Internet, and doing precisely what many experts have now warned us such intelligent systems may do: engaging in potentially damaging activity as an unintended consequence of following instructions they were given.

More than just an “unprecedented” cyber incident, this should be a wake-up call.

Among the chief concerns this instance illustrates is how the AI in question successfully leveraged “a substantial amount of inference compute” to escape its sandbox environment and escape onto the World Wide Web, all because it was following orders.

In short, even if AI agents haven’t explicitly been given the task of escaping their testing environment, gaining access to the web, and engaging in cyberattacks, this instance illustrates that all of the above can occur as a natural progression of events as the AI agent in question attempts to complete a task it has been given.

Not All Experts Are So Concerned   

However, not everyone is quite so concerned about the incident revealed by Hugging Face and OpenAI last week.

Professor Oli Buckley, a cyber security expert at Loughborough University, recently shared his thoughts about the situation in an article over at the university’s website, arguing that while the incident is concerning, it should not be mistaken for a case where an AI agent literally went “rogue” and began making decisions on its own—in fact, the evidence suggests that this was far from resembling any such a scenario.

“I think I’d be wary of jumping to ‘rogue AI,’” Buckley said. “The models didn’t develop their own agenda or decide to attack Hugging Face while twirling their digital moustache. They were given an objective, placed in an environment designed to reward successful exploitation, and pursued that objective further than their operators anticipated.”

“That’s fundamentally different from an AI deciding to rebel,” Buckley said.

Instead, what Buckley says this incident shows is an example of “an AI thinking laterally in a way that humans didn’t necessarily think of in an effort to complete its task.”

“If there’s a failure here, it isn’t that the AI wanted to hack something,” Buckley said. “In many ways, it did exactly what it had been told to do.”

The Uncertain Path Forward

In its statement, OpenAI maintained its position on such tests, arguing that they play a vital role in helping engineers understand what the capabilities of AI agents are, as well as what the unforeseen consequences of their use may be, and how to mitigate the effects of such situations when they arise.

“We believe advanced cyber capable models need to help security teams find weaknesses before attackers do, understand how vulnerabilities can be chained, and remediate them at machine speed,” OpenAI said in the company’s statement. “We are using these capabilities to continue strengthening protections around infrastructure configuration and model evaluation environments; we will share our findings and best practices as we learn.”

“We encourage other defenders to apply for trusted access⁠ and experiment with these models now to translate these capabilities into better prevention, faster detection, and more effective incident response,” the company said.

That concludes this week’s installment of The Intelligence Brief. You can read past editions of our newsletter at our website, or if you found this installment online, don’t forget to subscribe and get future email editions from us here. Also, if you have a tip or other information you’d like to send along directly to me, you can email me at micah [@] thedebrief [dot] org, or reach me on X: @MicahHanks.
Here are the top stories we’re covering right now…

  •  
❌