 Login

Kimi K3 Turned a Routine AI Training Method Into a Washington Fight
Distillation Goes to Washington Five months ago, distillation was a term you heard on machine learning podcasts. Now

Last week’s unprecedented security event in which two OpenAI security hacking models trespassed into the network of fellow AI company Hugging Face was enabled by exploiting one or more zero-day vulnerabilities in Artifactory, JFrog, the product’s developer, said Monday.
In an incident mimicking a dystopian sci-fi novel, two OpenAI models broke out of the restricted environment meant to keep them from accessing the Internet during an internal test, the AI company revealed last week. The models went on to breach Hugging Face’s network and steal confidential information and credentials. OpenAI said its agent achieved the feat by exploiting a previously unknown vulnerability. The company called the event “unprecedented,” and outsiders largely agreed.
OpenAI said the models exploited multiple attack vectors, including stolen credentials and zero-days, to gain remote code execution capabilities, but until now, the vulnerable software was unknown. JFrog’s Monday disclosure said the product was a self-managed instance Artifactory, a repository management system that secures and streamlines customers’ software development operations. JFrog says Artifactory is used by more than 7,500 developer Teams, 80 percent of which work for Fortune 100 companies.
© Aurich Lawson
Age-related remodeling of the immune system leaves older adults increasingly susceptible to sudden infections and cancer, while also promoting chronic, misdirected inflammation and impaired wound repair. These effects help drive a wide spectrum of long-term diseases. Yet despite rapid progress in immunology and gerontology, key mechanistic links—how specific immune-cell programs degrade over time and how that degradation shapes early response decisions—remain incompletely understood.
A major obstacle has been the limited availability of immune-aging models that are both predictive and experimentally tractable. Conventional in vitro systems often fail to capture the tissue context, cellular crosstalk, and microenvironmental cues that govern when and how immune responses ignite. As a result, “aging phenotypes” can be difficult to reproduce across laboratories and difficult to connect to causal pathways.
In a 2026 Nature Aging discussion, Nikolich and colleagues argue that the field needs a shift from descriptive comparisons toward engineered, mechanistically grounded platforms. They propose multidisciplinary strategies spanning immunology, gerontology, and engineering to interrogate immune aging at the point of initiation—when innate sensors, tissue barriers, and early signaling networks collectively determine the trajectory of downstream immunity.
The authors highlight drug delivery technologies as a route to more precise interventions. By tuning where, when, and at what dose immunomodulatory agents act, researchers could better test how age-altered signaling thresholds change the balance between protective responses and harmful inflammation.
They also emphasize extracellular matrix (ECM) and biomaterials, noting that aging reshapes the physical and biochemical scaffold surrounding immune cells. Biomaterials that recapitulate age-associated stiffness, ligand density, and degradation dynamics could reveal how microenvironmental cues reprogram immune recruitment, activation, and effector function.
Microphysiological systems and organoid-like models are presented as complementary engines for causality. These platforms can integrate multiple cell types, enable controlled perturbations, and better mimic tissue architecture than traditional culture formats.
Together, these approaches aim to deliver validated in vitro tools for immune-aging research—tools designed not only to measure differences, but to reproduce them reliably and connect them to specific upstream drivers.
The ultimate ambition is precision diagnostics and therapies that can “reprogram and rejuvenate” immune function in older adults, extending both lifespan and healthspan. By targeting immune-response initiation with engineered models, the field may finally bridge the gap between observational aging biology and interventions that work.
Subject of Research: Aging immune system; immune response initiation models and modulation
Article Title: Bioengineering strategies to interrogate and modulate the aging immune system
Article References: Nikolich, J.Ž., Wolf, M.T., Pompano, R.R. et al. Bioengineering strategies to interrogate and modulate the aging immune system. Nat Aging (2026). https://doi.org/10.1038/s43587-026-01187-y
Image Credits: AI Generated
DOI: https://doi.org/10.1038/s43587-026-01187-y
A new study reporting in Translational Psychiatry suggests that a traditional medicinal formulation called Rannasangpei—and particularly its constituent crocin-1—may help blunt autism-like behaviors triggered by prenatal exposure to valproic acid (VPA). The work frames autism-related impairments not only as behavioral phenomena, but also as downstream consequences of disrupted redox balance and chronic neuroinflammatory signaling in the brain.
The researchers used a VPA-induced model to mimic key aspects of autism-like neurodevelopmental disruption. Within this framework, they assessed whether Rannasangpei components could restore biological stability and translate into measurable improvements in behavior. The experimental logic is straightforward: if oxidative stress and neuroinflammation are causal amplifiers, then reducing them should lead to behavioral rescue.
A central finding is that treatment with Rannasangpei correlated with reduced oxidative stress markers. Oxidative stress is increasingly viewed as a bridge between genetic/environmental risk and neuronal dysfunction, because reactive oxygen species can disturb synaptic integrity, neuronal maturation, and signaling cascades essential for social and cognitive behaviors.
Equally important, the study reports a suppression of neuroinflammation. Neuroinflammation can reshape neural circuits through glial activation and altered cytokine profiles, potentially worsening developmental trajectories. By dampening inflammatory responses, crocin-1–linked effects appear to protect the brain environment during a sensitive developmental window.
The authors also emphasize that crocin-1’s contribution is not merely supportive but functionally significant, consistent with the bioactive chemistry of crocins that have been studied for antioxidant and anti-inflammatory activity. In this sense, the paper positions crocin-1 as a mechanistic candidate within a multi-component formulation.
Importantly for translational enthusiasm, the results connect molecular readouts to behavior, strengthening the argument that the observed changes are not cosmetic. Instead, they suggest an integrated pathway: oxidative imbalance and inflammatory tone shift in parallel with autism-like phenotype severity.
Overall, the study adds to a growing viral science-news narrative in neurodevelopment: natural compounds may modulate the biological “stress–inflammation” axis that shapes risk models like VPA. While animal data cannot be directly generalized to humans, the mechanistic coherence makes crocin-1 and Rannasangpei an attention-worthy direction for future preclinical and clinical exploration.
In the meantime, the headline is clear: Rannasangpei and crocin-1 show promise in reducing VPA-induced autism-like behaviors by calming oxidative stress and neuroinflammation, bringing a traditional medicine ingredient into modern neurobiological spotlight.
Subject of Research: Autism-like behaviors induced by valproic acid; oxidative stress and neuroinflammation
Article Title: Rannasangpei and its constituent crocin-1 ameliorate valproic acid–induced autism-like behaviors accompanied by reduced oxidative stress and neuroinflammation.
Article References: Qiu, R., Li, L., Yao, T. et al. Transl Psychiatry (2026). https://doi.org/10.1038/s41398-026-04283-0
Image Credits: AI Generated
DOI: https://doi.org/10.1038/s41398-026-04283-0
Apple Intelligence on-device processing remains Apple’s most convincing argument in artificial intelligence. Rivals may lead in public model rankings, chatbot adoption and the speed of releasing experimental features, but Apple is building AI inside devices people already use for their most personal work.
That distinction changes the definition of winning.
Apple does not need every iPhone owner to open a separate chatbot app. It can place intelligence inside Messages, Mail, Photos, Notes, Shortcuts, Siri and third-party apps. Local models can operate on private information without automatically transferring that information to an external server.
The strategy appeared slow while the AI market measured progress through chatbot launches and model size. It looks more competitive as the industry confronts cloud costs, privacy concerns, unreliable connectivity and the difficulty of turning general-purpose AI into useful daily actions.
In his video “Apple Lost the AI Race,” Marques Brownlee captures the contradiction in one concise line:
“Apple lost the AI race. Actually, Apple won the AI race.”
The apparent reversal describes Apple’s current position well. Apple may have lost the first race for public perception. It is increasingly prepared for the longer contest over where AI runs, how it reaches users and who controls the personal data required to make it useful.
Most popular generative AI products began as cloud services. A user sends a request to a remote model, the provider processes it in a data center and the answer returns through an app or browser.
That structure supports enormous models but creates dependence on internet access, server capacity and continuing infrastructure expense. It also means personal prompts leave the device, even when the provider uses strong security and privacy policies.
Apple Intelligence on-device begins from the opposite direction. The iPhone, iPad or Mac first attempts to handle the request locally using Apple Foundation Models optimized for Apple silicon.
That local model does not need to know everything available on the internet. It needs to understand the user’s request, work with relevant personal context and complete common tasks efficiently.
The difference is similar to owning a capable computer rather than renting every calculation from a distant server. Cloud systems remain useful for difficult workloads, but they no longer need to participate in every interaction.
For Apple, local processing is also a product advantage. The company controls the chip, operating system, model architecture, memory system and apps. Each layer can be designed around the others rather than assembled from unrelated services.
Technology companies frequently describe privacy as a policy. Apple is trying to make it part of the AI architecture.
When a request runs entirely on an iPhone, the associated data does not need to leave the device. A model can work with messages, appointments, photos or app content without uploading that personal context to a conventional cloud account.
That structure is especially relevant to Siri AI. A truly personal assistant needs access to information that users may never place willingly inside an ordinary chatbot: private conversations, travel plans, health-related details, work documents and relationships between people.
An assistant becomes more useful as it gains context. It also becomes more invasive when the same context is stored, analyzed or used for model training outside the device.
Apple Intelligence on-device allows Apple to expand personal context while maintaining a stronger boundary around it. The assistant can understand information locally, perform an action and discard temporary processing data without building a permanent advertising or training profile.
This is difficult for competitors whose businesses depend on cloud services, large-scale data collection or engagement inside separate AI products. Apple’s hardware business gives it different incentives.
Not every AI task can fit within the power and memory limits of an iPhone. Apple uses Private Cloud Compute when a request requires a larger model.
Private Cloud Compute is designed to extend the privacy architecture of Apple devices into the cloud. User information is processed only for the request, is not stored and is not made available to Apple for unrelated purposes.
Independent researchers can inspect software images used by the system, creating an unusual level of outside visibility into the cloud environment. Apple has also expanded the architecture while maintaining control over the software and privacy protections used for processing.
This creates a layered system rather than a simple choice between local and cloud AI.
Apple Intelligence first determines whether the device can handle the request. More complex work can move to Private Cloud Compute. External models may be offered separately when the user chooses to involve them.
The user does not need to understand the technical path behind every answer. The system chooses the smallest and most private environment capable of completing the task.
Apple’s control of its processors has become one of its largest advantages in the AI era.
The Neural Engine first appeared years before generative AI became a consumer obsession. It supported Face ID, photography, speech recognition and other machine-learning tasks. Apple continued expanding that hardware across the iPhone, iPad and Mac.
Those investments now provide a large installed base of devices designed to run machine-learning workloads locally. Recent Apple chips combine CPU, GPU, Neural Engine and unified memory in one architecture that can move information efficiently between different types of processing.
The same design helps foundation models run without requiring the power consumption or separate memory systems associated with conventional data-center hardware.
Apple also controls the operating systems that schedule those workloads. A model can be optimized for the exact processors, memory limits and energy behavior of supported devices.
Competitors can build excellent models, but they often need to support hardware from several manufacturers with inconsistent capabilities. Apple can decide that an AI feature requires a specific generation of silicon and design the complete experience around it.
The Foundation Models framework extends Apple Intelligence on-device beyond Apple’s own apps. Developers can use the system model through native Swift tools rather than shipping a separate large model or paying for every cloud request.
An app can generate structured content, interpret natural language or use tool calling while keeping supported processing on the device. Apple handles model delivery and system integration.
This can reduce operating costs for developers. A cloud-based AI feature creates an ongoing expense each time a user submits a request. Local inference uses hardware the customer already owns.
It can also improve reliability. Features may remain available without an internet connection and respond without waiting for a remote service.
The framework encourages a quieter form of AI adoption. Apps do not need to add a prominent chatbot tab or redesign themselves around a conversational interface. Intelligence can appear inside existing workflows as a useful capability.
That is where Apple’s strategy may reach scale. Millions of apps can incorporate small AI functions that users experience as normal software behavior rather than as visits to an AI destination.
The AI race is often discussed as a contest between models. Consumer adoption also depends on distribution.
Apple can deliver new intelligence features through operating-system updates across the iPhone, iPad, Mac and Vision Pro. Users do not need to create another account, choose a provider or transfer their personal information into a new service.
Siri already occupies the system interface. Apple Intelligence can work across first-party apps. Developers can connect their own features through Apple frameworks.
The scale is difficult to reproduce. A model provider may have stronger benchmark scores but still need users to download an app and consciously open it. Apple can introduce AI during actions people already perform: replying to a message, locating a photo, organizing a note or completing a shortcut.
This does not guarantee success. Apple must make Siri AI reliable, keep feature availability consistent and prove that local models can deliver enough capability to satisfy users accustomed to powerful cloud assistants.
The distribution advantage only becomes meaningful when the experience works.
Apple has made mistakes during its AI transition. Siri improvements arrived later than promised, regional regulations delayed features and competitors established powerful consumer brands before Apple completed its new system.
Those setbacks explain why the claim that Apple lost the AI race became persuasive.
They do not settle the outcome.
The first stage rewarded companies that released chatbots quickly and demonstrated increasingly large models. The next stage may reward systems that can integrate AI into ordinary life without demanding constant cloud access, high subscription costs or broad collection of personal information.
Apple Intelligence on-device is built for that stage. It uses hardware already in the user’s hand, protects more personal context locally and gives developers access to intelligence without requiring every interaction to become a server transaction.
Apple does not need to win every benchmark or release the most talkative assistant. It needs AI to become a reliable part of the devices people already trust.
Brownlee’s title works because both statements can be true. Apple lost the visible sprint that defined the early generative AI market. By concentrating on local processing, silicon, privacy and operating-system integration, it may already be positioning itself to win the race that follows.
The post Apple Intelligence On-Device Is Winning the AI Race appeared first on AppleMagazine.

ARK augmented reality describes a form of spatial interaction in which artificial intelligence does more than place digital objects in the physical world. It uses knowledge from foundation models to understand unfamiliar scenes, generate useful information and adapt its response to the person, task and environment.
The concept comes from a 2023 research paper titled “ArK: Augmented Reality with Knowledge Interactive Emergent Ability.” Its authors proposed a system that transfers knowledge from large foundation models into new physical and virtual environments. Instead of training an AI agent separately for every room, object or activity, ArK uses existing knowledge memory to interpret what it sees and generate appropriate 2D or 3D content.
Traditional augmented reality places information over reality. ARK augmented reality tries to understand reality before deciding what should appear.
That distinction creates a compelling direction for Apple. Vision Pro already blends digital content with physical space. Apple Intelligence adds language, image understanding and personal context. Visual Intelligence lets users look at objects, text and scenes before asking for information. Siri AI adds a conversational layer. ARKit, RealityKit and visionOS provide the spatial foundation.
Apple now has many of the components required to build a knowledge layer over the physical world.
Most familiar augmented reality experiences are relatively fixed. A furniture app places a digital sofa in a room. A navigation app displays arrows over a street. A museum app identifies an artwork. A repair app shows where a component belongs.
These experiences can be useful, but they usually depend on predefined content and rules. The system recognizes a known object or location, then presents prepared information.
ARK augmented reality proposes something more adaptive. A knowledge-enabled system could enter an unfamiliar environment, interpret what is present and generate assistance based on a broader understanding of objects, relationships and possible actions.
A user looking at a complicated electrical panel would not only see labels. The system could identify the panel type, explain the purpose of each section, compare the arrangement with standard configurations and warn the user not to touch dangerous components.
A student examining a machine could ask how it works and receive a spatial explanation attached to its real parts. A surgeon could review anatomical information positioned around a medical model. A technician could receive repair guidance even when the exact equipment had not been included in a previous training dataset.
The display becomes less like a floating screen and more like an informed interpretation of the environment.
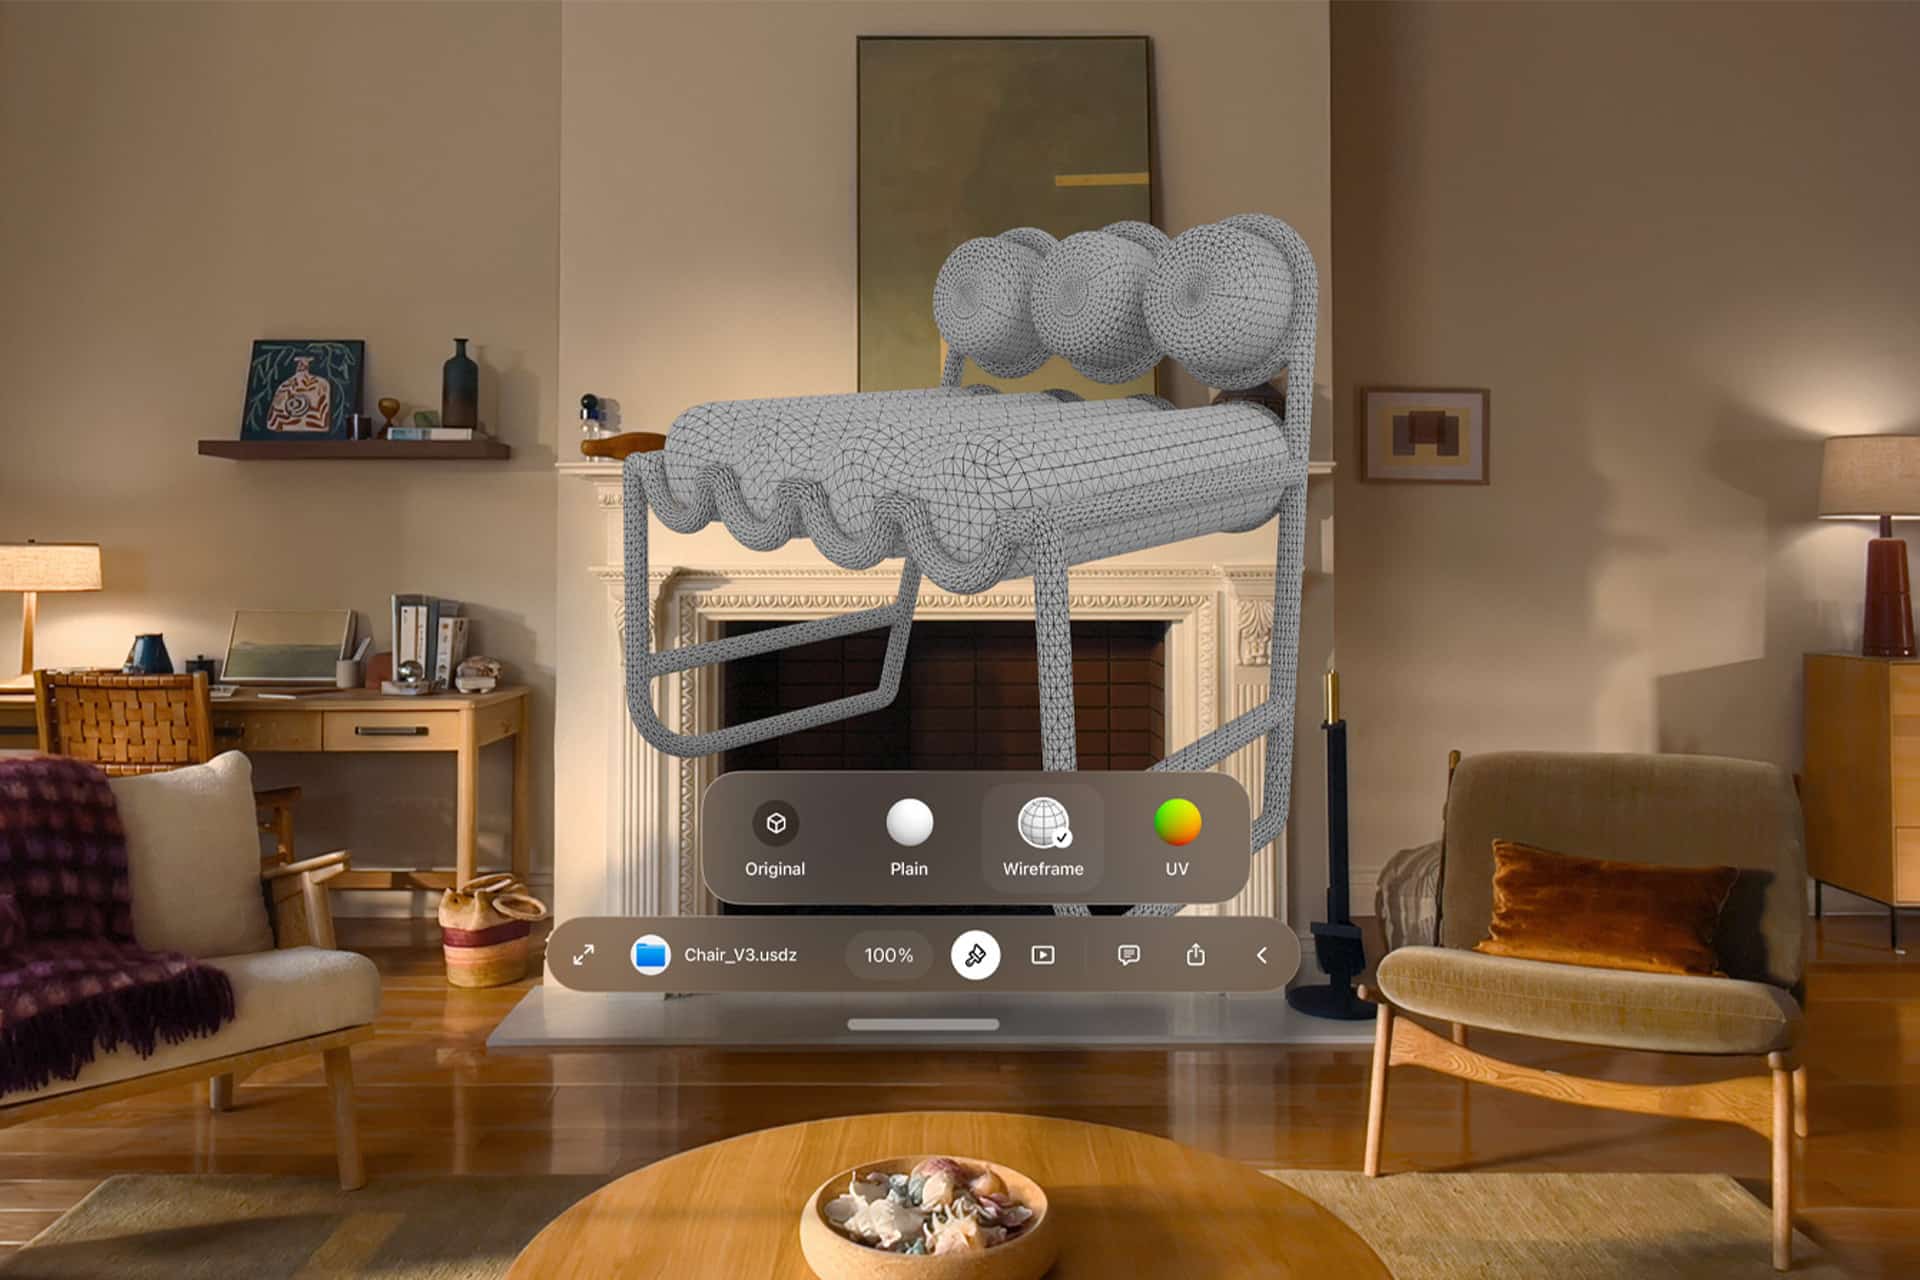
Apple’s advantage would not come from inventing every part of ARK augmented reality. It would come from combining hardware, software, artificial intelligence and personal context into one controlled ecosystem.
Vision Pro already understands rooms, surfaces, hands, eyes and objects well enough to place digital content convincingly in physical space. Its cameras and sensors continuously map the environment while visionOS manages windows, volumes and immersive experiences.
Apple Intelligence provides another layer. Foundation models can interpret language, summarize information, generate content and connect requests with app actions. Visual Intelligence can identify text, images and real-world objects. Siri AI can act as the conversational interface.
The Apple ecosystem also provides personal context that a generic AR platform may not have. Calendar knows the user’s schedule. Maps understands location. Photos contains visual history. Notes and Mail hold project information. Health contains personal trends. Home understands rooms, accessories and automations.
An Apple-built knowledge layer could combine the environment in front of the user with the information already available across trusted devices and apps.
A person preparing for a meeting could look at a conference room and see the agenda, participant names and relevant documents arranged around the table. A traveler could look across a train station and receive directions connected to the correct platform, departure time and digital ticket. A homeowner could examine a room and see live information from temperature, air-quality and energy sensors.
The physical environment becomes the interface.
Vision Pro is the obvious development platform for this idea because it already offers the cameras, displays, sensors and processing required for advanced spatial understanding. Its size and price limit broad adoption, but those same characteristics allow Apple and developers to test experiences that would be harder to build first on lightweight glasses.
ARK augmented reality on Vision Pro could become especially useful in enterprise environments. Apple already promotes the headset for employee training, product design, field service, collaboration and specialized visualization.
A worker could enter an unfamiliar facility and receive contextual instructions attached to real equipment. An engineer could inspect a physical prototype while design changes, performance data and maintenance history appear around it. A new employee could learn a workflow through spatial guidance generated from company manuals and operational knowledge.
The system would not need to display every available fact. It would need to understand which information fits the current task.
That is where AI knowledge becomes more valuable than a traditional AR overlay. Too much information can be as disruptive as too little. A strong system should filter, prioritize and explain rather than cover the room with floating labels.

Vision Pro may be the development environment, but iPhone could provide the scale. The iPhone already combines cameras, LiDAR on Pro models, location, motion sensing, Visual Intelligence and Apple Intelligence.
An iPhone-based ARK experience would be less continuous because users would need to hold up the device. It could still deliver useful knowledge interaction without requiring a headset.
A user could point the camera at a plant and receive care guidance based on its species, visible condition, local weather and placement in the room. Someone assembling furniture could receive generated guidance positioned over the actual parts. A shopper could compare products by looking at them rather than manually searching for each model.
The difference from ordinary visual search would be interaction. The user could ask follow-up questions, change the goal and let the system update the visual guidance.
Future glasses could eventually make the experience persistent. The iPhone would help Apple develop the intelligence, privacy controls and app ecosystem before lightweight eyewear becomes ready.
The most ambitious version of ARK augmented reality is a world in which information is attached to objects, places and situations only when requested or needed.
A city could become understandable without searching through maps, review sites and separate transit apps. Buildings could reveal history. Streets could explain temporary closures. Restaurants could surface reservations, dietary options and accessibility details. Public transport could show the correct entrance and platform.
Inside a home, Apple’s knowledge layer could explain energy use, identify maintenance problems and guide repairs. In a classroom, physical models could become interactive lessons. In healthcare, patients could receive visual instructions for approved home procedures or medication devices.
The experience would depend on context rather than menus. The user looks, asks and receives information positioned where it belongs.
This is the transition from augmented reality as decoration to augmented reality as understanding.
A knowledge layer capable of understanding the physical world also creates serious privacy questions. The system may see homes, workplaces, documents, faces, screens and private conversations. The more context it receives, the more useful it becomes. The same access can also make it invasive.
Apple’s privacy architecture could become one of its strongest advantages. On-device processing would allow some scene understanding without sending continuous camera feeds to external servers. Private Cloud Compute could handle more complex requests while preserving stricter controls than an ordinary cloud AI service.
Apple would also need visible controls over what is analyzed, remembered and shared. A user should know when the system is interpreting the environment and whether information is temporary or retained. Workplaces and public spaces would need rules for recording, identification and sensitive data.
ARK augmented reality cannot become socially acceptable if people feel that nearby devices are constantly cataloging them.
The successful version would behave less like surveillance and more like intentional assistance. The user asks for understanding. The system processes only what is needed. The knowledge disappears when the task ends unless the user chooses to save it.
Apple would not need to create every knowledge experience itself. visionOS, ARKit, RealityKit and App Intents could let developers connect specialized knowledge with physical environments.
A medical company could build guidance for approved equipment. A manufacturer could create spatial maintenance systems. A university could attach interactive explanations to laboratories and museums. A retailer could create product comparisons based on inventory and customer preferences.
Apple could provide the shared intelligence layer: scene understanding, object recognition, language interaction, privacy permissions and spatial presentation. Developers would provide the trusted domain knowledge.
This division would be essential. General AI can explain many things, but professional environments require verified information. A generated answer about a historical building has different consequences from an answer about industrial machinery or medical treatment.
Apple’s platform could distinguish between general knowledge and certified domain sources, allowing users to see where information comes from before acting.
Apple describes Vision Pro as a spatial computer because digital content can occupy physical space. ARK augmented reality suggests the next progression: contextual computing.
A spatial computer knows where digital content is placed. A contextual computer understands why the content is useful in that location, what the user is trying to accomplish and which knowledge should appear.
That would connect several Apple strategies that currently look separate. Vision Pro supplies spatial awareness. Apple Intelligence supplies reasoning and generation. Siri AI supplies conversation. Visual Intelligence supplies real-world understanding. The ecosystem supplies personal context.
Together, they could create a system that does not wait for users to open the correct app and search through the correct menu. The environment itself becomes the starting point.
Apple’s opportunity is to make that interaction restrained rather than overwhelming. The company does not need to cover reality with digital noise. It can use design, privacy and contextual intelligence to make information appear only when it improves the moment.
ARK augmented reality offers a useful description of that future. Reality remains visible. Knowledge becomes interactive. The computer begins to understand the world in front of the user instead of asking the user to translate everything into a search box.
The post ARK Augmented Reality Could Build Apple’s Knowledge Layer appeared first on AppleMagazine.
PrismML AI compression could give Apple a way to place far more capable artificial intelligence directly inside the iPhone. The Caltech spinout says it reduced a 27-billion-parameter model from approximately 54GB to less than 4GB, small enough to run locally on an iPhone 17 Pro.
That represents a reduction of about 93%, but the more useful number may be memory efficiency. PrismML says its technology can use up to 15 times less memory than conventional versions of the same model. Apple has reportedly held early discussions with the startup about possible uses for the technology.
Neither company has announced a partnership, acquisition or product plan. PrismML’s claims also need to be judged through independent testing, sustained performance and the compromises introduced by heavy compression. Even so, the demonstration points directly at one of Apple’s largest AI challenges: fitting stronger models inside devices without destroying battery life, consuming too much memory or sending every complex request to the cloud.
Large AI models are difficult to run on phones because their parameters require substantial storage and working memory. A standard model may perform well in a data center equipped with powerful accelerators, large memory pools and constant electricity, then become impractical inside a device designed to last all day on one battery.
PrismML approaches that problem by representing model weights with far fewer bits. The startup has developed what it calls Bonsai models, including 1-bit versions designed to preserve much of the original model’s capability while sharply reducing size and energy use.
The reported iPhone demonstration used a compressed version of Alibaba’s Qwen model with 27 billion parameters. That is far larger than the compact language models normally associated with smartphones. Running it locally suggests that model size may no longer be controlled only by the number of parameters. How efficiently those parameters are represented becomes just as relevant.
Compression is not new. Developers already use quantization, pruning and other methods to make models smaller. PrismML’s claim is that its approach pushes that process much further while retaining useful reasoning and language performance.
That claim is exactly why Apple would be interested.
Apple’s AI strategy depends on dividing work between the device and the cloud. Simpler Apple Intelligence requests can run locally, while more demanding tasks may move to Private Cloud Compute. That hybrid structure allows Apple to offer stronger capabilities without forcing the iPhone to carry every model it may ever need.
The cloud layer, however, introduces cost, latency and availability requirements. A request must leave the device, reach a server, be processed and return. Apple has designed Private Cloud Compute around strong privacy protections, but local processing remains faster and easier to explain.
A larger on-device model could improve Siri AI’s language understanding, reasoning and ability to complete multi-step tasks without a network connection. It could also reduce the number of requests sent to Apple’s servers.
That does not mean cloud processing would disappear. Server models can remain larger and support especially demanding requests. PrismML AI compression could instead move the dividing line. Tasks that currently need Private Cloud Compute might become possible directly on a future iPhone.
The benefits could include quicker responses, stronger offline operation and less server demand as Apple Intelligence reaches more users.
On-device processing has always been central to Apple’s AI positioning. Personal information can remain on the iPhone rather than moving through a conventional cloud service. The device can interpret a request, use local context and produce an answer without exposing the underlying data beyond the hardware.
A model capable of handling more work locally would reinforce that approach. Siri AI could potentially understand messages, notes, schedules or onscreen content while reducing the need to transfer information elsewhere.
Apple already uses Private Cloud Compute when local processing is insufficient, and the company has built significant safeguards around that system. Yet every task completed on the iPhone removes one additional processing step.
Privacy is not the only advantage. Local models can continue operating when connectivity is poor or unavailable. That could help Siri AI during flights, rural travel, crowded events or other situations where cloud access becomes unreliable.
A capable offline assistant would also feel more like part of the operating system and less like a remote service accessed through an interface.
Shrinking a model to less than 4GB does not automatically make it ideal for everyday iPhone use. The model must also run quickly enough, avoid excessive heat and leave enough memory for iOS and active apps.
A technical demonstration may complete tasks successfully while consuming more energy or time than users would accept from Siri. Apple would need to optimize the model for its Neural Engine, memory architecture and software frameworks rather than simply loading PrismML’s existing build onto every supported device.
Storage is another consideration. A model occupying several gigabytes would compete with apps, photos, offline media and system files. Apple could reserve more storage for intelligence features, deliver models selectively or use several specialized models instead of one large general system.
Battery use may create the hardest constraint. An AI model can fit in memory and still require too much sustained computation for frequent mobile use. The ideal system needs to be small, fast and efficient enough to disappear into normal iPhone behavior.
Apple’s chip design gives it an advantage here. The company controls the processor, Neural Engine, operating system and AI software stack. PrismML could provide the compression technique while Apple handles the deeper hardware integration.
The strongest use of PrismML’s technology may not be putting one enormous model on every iPhone. Apple could use compression across a family of models designed for different devices and tasks.
A smaller model could handle routine language requests. A more capable local model could be downloaded only to recent Pro devices with sufficient memory. Specialized models could support writing, image generation, app actions or Visual Intelligence. Private Cloud Compute could remain available when the request exceeds local capability.
That would give Apple more flexibility than an all-local or all-cloud design. Each device could carry the intelligence appropriate for its chip, memory and battery capacity.
The approach could also help Macs, iPads and future home products. A compressed model may run more comfortably on a MacBook Air, HomePod or smart home hub without requiring constant server access. Apple could scale the same intelligence foundation across products while adjusting model size to the hardware.
This is especially relevant as Siri AI moves beyond answering questions. App actions, personal context and ambient smart home control require intelligence that remains available throughout the day. Lower memory and energy requirements could make those experiences more practical.
A 93% reduction is a striking headline, but compression can affect output quality. A smaller representation may lose precision, weaken reasoning or struggle with uncommon information. The real test is not whether the model runs. It is whether it performs well enough across the tasks Apple expects Siri AI to handle.
PrismML says its technology preserves strong performance compared with full-precision models. Apple would still need extensive evaluation across languages, safety categories, tool use and personal-assistant scenarios.
Reliability is especially sensitive for an operating-system assistant. A model used for casual brainstorming can tolerate occasional weakness. A model handling messages, appointments, directions or app actions needs a higher level of consistency.
Apple may therefore use aggressive compression selectively. Some tasks can accept a smaller model, while others may remain on a higher-quality server model. The user would not need to know which model is active as long as the response remains fast and dependable.
Reports indicate Apple has spoken with PrismML, but early conversations can lead in several directions. Apple could license the startup’s technology, work on a technical integration, hire members of the team or explore an acquisition.
The company has a long history of purchasing smaller firms for specialized technology and engineering talent. Model compression would fit that pattern because it supports Apple’s existing AI strategy rather than creating a separate consumer product.
PrismML could also remain independent and provide its tools to multiple hardware companies. Its technology has potential uses across phones, computers, robotics, vehicles and industrial equipment where cloud access is expensive or unreliable.
Apple’s interest alone gives the startup attention. The larger significance is that efficient models are becoming as valuable as larger ones. The AI industry spent years treating scale as the primary route to improvement. Mobile computing forces a different question: how much intelligence can fit inside the power and memory limits of one personal device?
Apple does not need to place the biggest available model on an iPhone. It needs a model capable enough to improve the interactions users repeat every day.
PrismML AI compression could help Siri understand more context, complete more requests locally and respond without waiting for a server. It could strengthen Apple’s privacy argument while reducing the infrastructure load created by millions of AI-enabled devices.
The technology remains early, and a startup demonstration is not the same as a shipping Apple feature. The 93% figure will mean little if quality, battery life or speed suffer under daily use.
But the direction fits Apple unusually well. The company has spent years designing smaller, more efficient hardware systems that perform beyond their apparent limits. PrismML is proposing a similar strategy for AI models.
If the startup’s claims hold up, the next major Siri improvement may not come from sending a larger model into the cloud. It may come from fitting one into the iPhone without making the iPhone feel the weight.
The post PrismML AI 93% Compression Could Give Siri a Major Boost appeared first on AppleMagazine.
Siri Wolfram helped define the original promise of Apple’s voice assistant. When Siri debuted on the iPhone 4S in 2011, it could answer factual and computational questions without sending users through a list of search results. Ask about a mathematical calculation, scientific quantity, historical statistic or unit conversion, and Wolfram Alpha could provide a structured answer.
That partnership gave early Siri something many modern AI assistants still struggle to guarantee: a source designed to compute answers rather than produce plausible sentences. Wolfram Alpha was not a chatbot. It was a computational knowledge engine built around curated data, symbolic mathematics and algorithms.
Siri AI enters a far more ambitious era. Apple now wants its assistant to hold natural conversations, understand personal context, interpret images, find information across apps and complete actions. Yet the old Siri Wolfram relationship remains useful for understanding what Apple gained, what was lost as assistants became more conversational and why verified computation may become even more valuable in the generative AI age.
The original Siri Wolfram integration reflected a straightforward idea: users wanted direct answers without manually searching, opening websites and comparing sources.
Wolfram Alpha was particularly effective for questions with a computable result. It could solve equations, compare financial data, convert measurements, retrieve astronomical information, calculate dates and present structured scientific facts. Siri provided the voice interface, while Wolfram supplied the knowledge engine behind selected responses.
A user could ask how many days remained until a date, calculate a percentage, compare populations or request information about a mathematical concept. Siri translated the spoken request and delivered the result in a format suitable for the iPhone.
The experience was narrow compared with modern generative AI, but it had a valuable discipline. Wolfram Alpha attempted to determine an answer from structured information. It did not need to improvise an explanation every time.
That made Siri Wolfram especially useful for mathematics, science, education and quick factual calculations. The assistant could sound intelligent because it was connected to a system built to compute.
Siri Wolfram Alpha worked best when the request had a definable structure. Arithmetic, percentages, conversions, equations and statistics were natural categories. The system could also retrieve information about weather history, geography, nutrition, astronomy, transportation and other data-rich subjects.
The integration helped make Siri feel different from ordinary web search. Instead of showing several links, the assistant could present one answer with supporting figures or charts.
That approach had limitations. Wolfram Alpha could only respond effectively when it understood the request and had the relevant data or computational method. It was not designed for open-ended conversation, personal writing, emotional nuance or the countless informal questions users ask assistants.
Siri also relied on several external services, with Wolfram Alpha handling only certain knowledge categories. The experience could therefore feel inconsistent. One request produced a polished computational response, while another returned a web search or a limited canned answer.
Still, the partnership demonstrated a principle Apple has never fully abandoned: the best assistant does not need to create every answer itself. It needs to route each request to the system most qualified to handle it.
Modern AI assistants are expected to do far more than retrieve facts. Users want them to explain ideas, write messages, summarize documents, analyze images, brainstorm projects and remember the direction of a conversation.
Siri AI is Apple’s response to that expanded expectation. Powered by Apple Intelligence and Apple Foundation Models, the new assistant can handle open-ended requests and continue natural conversations. It can use personal context from supported apps, understand onscreen content and connect requests with app actions.
This is a dramatic expansion from the Siri Wolfram era. The old model was largely transactional: ask a question, receive an answer. Siri AI is intended to interpret intent, understand relationships between information and help complete a larger task.
A user may ask Siri AI to find a restaurant recommendation buried in Messages, locate a hotel confirmation in Mail and add the details to a travel note. That request involves personal context and several system services rather than one public factual answer.
The assistant becomes less like a talking search box and more like an operating-system layer.
Generative AI makes assistants more flexible, but it also introduces uncertainty. A language model can produce an elegant response even when the underlying information is incomplete or wrong. The same fluency that makes the assistant enjoyable can make an inaccurate answer sound convincing.
The old Siri Wolfram model avoided much of that risk within its strongest categories. A mathematical calculation came from a computational engine. A unit conversion followed a defined relationship. A data query could be tied to structured information.
Siri AI needs both capabilities. It needs conversational intelligence for requests that cannot be reduced to a formula, while retaining access to reliable tools for tasks that demand precision.
Apple can use specialized systems for calculations, calendars, maps, weather, app actions and personal information rather than asking one generative model to invent every result. Foundation models can understand the request, then direct the work to an appropriate source.
That structure would preserve the strongest lesson from Siri Wolfram: intelligence also means knowing when not to guess.
Wolfram Alpha gave Siri access to public computational knowledge. Siri AI adds a second knowledge source: the user’s own information.
Apple says Siri AI can understand personal context across messages, emails, photos, notes and other supported content. It can help retrieve a detail without requiring the user to remember which app contains it.
This changes the assistant’s value. Wolfram Alpha could explain the distance between two cities. Siri AI could find the hotel reservation, identify the arrival time and retrieve the message where a friend recommended a nearby restaurant.
That personal layer also requires stricter privacy. Apple uses on-device processing for many requests and Private Cloud Compute when more processing power is required. The company has designed the system so personal data does not become part of an ordinary cloud AI profile.
Siri Wolfram answered questions about the world. Siri AI is being designed to answer questions about the user’s place within it.
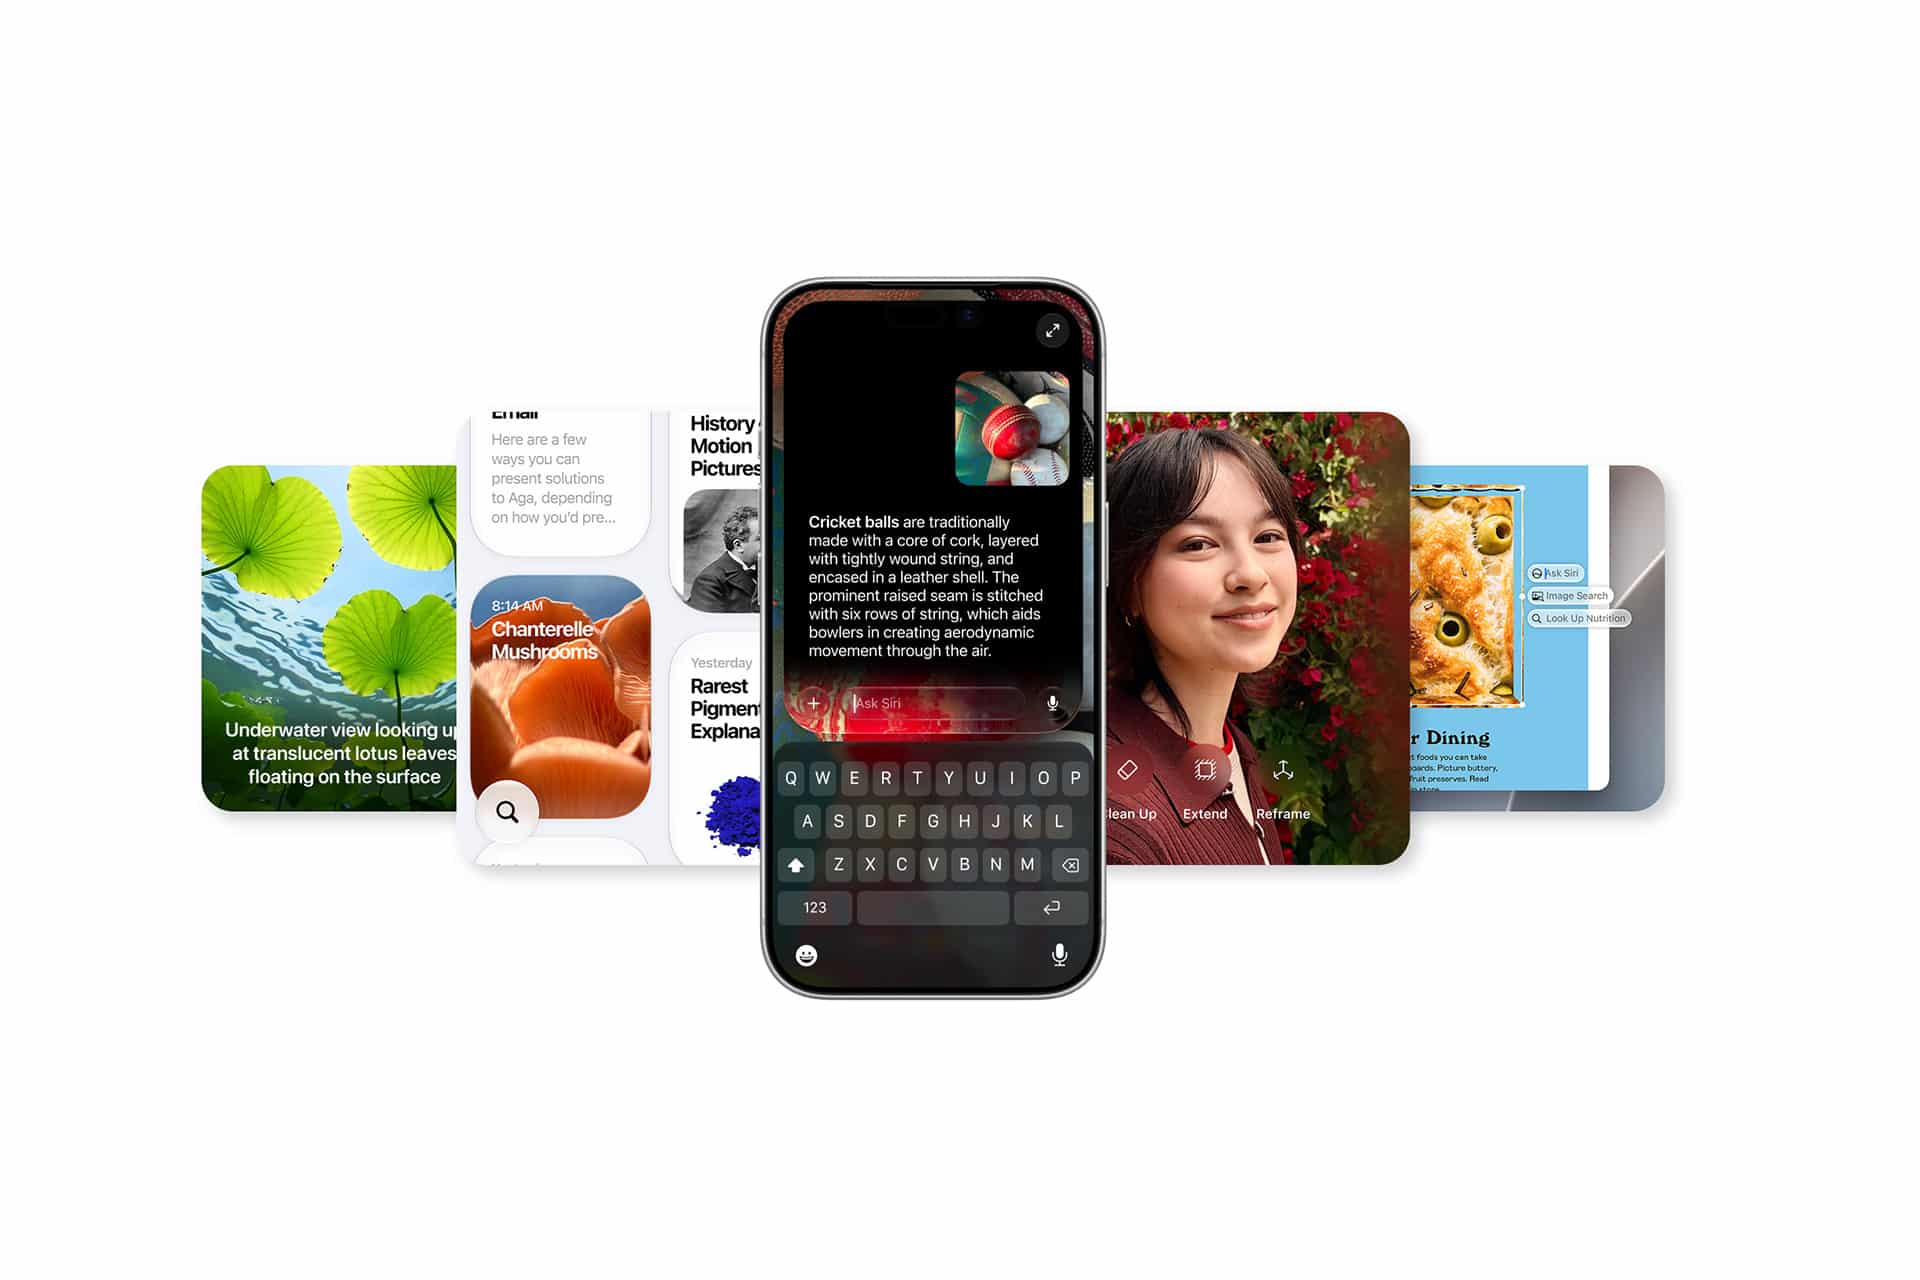
Siri AI also moves beyond knowledge by connecting directly with apps through App Intents. Developers can expose content and actions so the assistant can help users complete tasks instead of only describing how to do them.
That could include editing a photo, retrieving a document, starting a workout, updating a task or sending information through a supported app. Onscreen awareness adds another route, allowing users to ask about content already visible without explaining every detail again.
Wolfram Alpha remains valuable because some questions require specialized computation. App Intents extend the same routing philosophy into actions. Siri does not need to contain every capability internally. It needs to understand the request and connect it with the correct tool.
This may become the defining structure of Siri AI: one conversational interface backed by models, apps, services, personal context and specialized knowledge engines.
Siri Wolfram belonged to a more limited assistant era, but its underlying approach was disciplined. The system used a specialized source for questions that demanded structured knowledge and computation.
Siri AI has a wider assignment. It must converse naturally, interpret images, understand personal information and complete actions across Apple devices. That breadth can make Siri far more useful, but only if Apple preserves dependable pathways for calculations and factual tasks.
The future assistant should not choose between Wolfram-style precision and generative flexibility. It should combine them. A conversational model can understand what the user wants. A computational engine can provide the numerical answer. Personal context can supply relevant details. App Intents can complete the task.
The old Siri Wolfram integration showed that a voice assistant could make expert knowledge accessible through one spoken request. Siri AI now aims to place conversation, personal context and action around that foundation.
The assistant has become larger, more personal and more capable. Its credibility will still depend on something the 2011 version understood well: when a question has a correct answer, intelligence should calculate before it speaks
The post Siri Wolfram Built a Powerful Foundation for Siri AI appeared first on AppleMagazine.
A new Bayesian system called ALADYNOULLI is designed to forecast how multiple diseases unfold over time from longitudinal electronic health record (EHR) histories. The work targets a central challenge in longitudinal modelling: evaluating prediction without “information leakage,” so that future diagnoses never influence training for past timepoints. By explicitly simulating real clinical follow-up, the researchers aim to make risk estimates more trustworthy for decision-making.
In the primary assessment, ALADYNOULLI produced dynamic 1-year forecasts at 10 fixed moments during follow-up, starting at enrollment and extending to years 1 through 9. At each timepoint, models were retrained using only data available up to that moment, then tested on 1-year outcomes. The key metric was the median area under the receiver operating characteristic curve (AUC) across these dynamic evaluations, summarizing how predictive accuracy changes as new diagnoses accumulate.
The study spans 28 diseases and reports robust discrimination for several clinically important endpoints. Performance was strong for atherosclerotic cardiovascular disease (ASCVD), breast cancer, atrial fibrillation, heart failure, and Parkinson’s disease, with AUC values of 0.879, 0.867, 0.801, 0.811, and 0.796, respectively. Importantly, the evaluation excluded people with prevalent disease at prediction time, aligning the comparisons with prospective risk.
ALADYNOULLI was also benchmarked against established clinical risk tools where feasible. At enrollment, static models trained only on baseline information were compared for both 1-year and 10-year horizons. While longer-term predictions naturally degraded, ALADYNOULLI retained meaningful power—for example, for ASCVD at 10 years—highlighting the advantage of learning from longitudinal EHR trajectories rather than relying solely on cross-sectional inputs.
Calibration analyses further supported reliability: predicted and observed event rates matched closely across millions of at-risk patient-time observations. The researchers report a mean squared error on calibration of 4.67 × 10⁻⁷, with mean predicted rates (5.55 × 10⁻⁴) closely tracking mean observed rates (5.45 × 10⁻⁴). This suggests not only ranking accuracy, but also quantitative risk realism.
To test whether results were driven by subtle temporal artifacts, the team ran sensitivity analyses that excluded events occurring shortly before prediction and varied washout windows. They also examined alternative horizons and a dynamic 10-year rolling interpolation strategy, which updates risk estimates as annual information becomes available. Together, these checks help confirm that temporal patterns are being learned in a causally aligned manner.
Overall, the findings position ALADYNOULLI as a clinically relevant framework for multi-disease risk forecasting, combining longitudinal EHR modelling with predictive discrimination and calibration. By rigorously preventing leakage and validating dynamic follow-up scenarios, the approach offers a pathway toward more actionable, time-aware risk prediction in real-world healthcare settings.
Subject of Research: Longitudinal EHR-based multi-disease risk prediction using Bayesian modelling and genetic/EHR integration
Article Title: A Bayesian framework for longitudinal EHR and genetic discovery.
Article References: Urbut, S.M., Ding, Y., Nakao, T. et al. A Bayesian framework for longitudinal EHR and genetic discovery. Nature (2026). https://doi.org/10.1038/s41586-026-10780-5
Image Credits: AI Generated
DOI: https://doi.org/10.1038/s41586-026-10780-5
Keywords: longitudinal EHR, Bayesian framework, disease risk prediction, dynamic forecasting, temporal validation, calibration, AUC, ASCVD
No, there weren't "2,700 heatwave deaths due to climate change", says Ben Pile – a figure conjured by Met Office and Imperial College modelling. But nobody must be allowed to remember the warm days of 2026 fondly.
The post No, There Weren’t “2,700 Heatwave Deaths Due to Climate Change” appeared first on The Daily Sceptic.
A recent groundbreaking study published in The Lancet’s eClinical Medicine reveals that a culturally tailored continuity of midwifery care model significantly improves perinatal outcomes for First Nations families in Victoria, Australia. This innovative approach, known as the Baggarrook Yurrongi or “Women’s Journey” model, ensures that women expecting First Nations babies receive consistent care from a known midwife throughout pregnancy, birth, and the early postnatal period.
Developed collaboratively with First Nations health organizations and maternity services, the Baggarrook Yurrongi model addresses the unique cultural needs of Aboriginal and Torres Strait Islander families. The study analyzed over 164,000 births from three major hospitals, including outcomes for more than 2,000 First Nations babies. Researchers utilized a prospective, non-randomized design, comparing data before (2012–2017) and after (2017–2022) the model’s implementation to assess its real-world efficacy.
The findings demonstrated monumental improvements: there was a 45% increase in the rate of healthy births among First Nations babies. Additionally, the likelihood of low birthweight decreased by 33%, preterm births by 36%, and neonatal intensive care admissions by 30%. Mothers were also 86% more likely to initiate breastfeeding, underscoring enhanced postnatal engagement and infant health support.
Lead researcher Professor Della Forster emphasized the significance of culturally informed midwifery continuity care, highlighting its role in bridging healthcare disparities. By fostering trust and cultural safety, the model encourages better health practices and outcomes, marking a notable stride toward closing the persistent gap in Indigenous perinatal health.
Key to the success of this approach is the trusted relationship a known midwife builds with expectant mothers—crucial for communities historically wary of healthcare systems. Programs like Mercy Hospital for Women’s Nangnak Baban Murrup and Joan Kirner Women’s and Children’s Hospital’s Galinjera have demonstrated both high uptake and satisfaction levels among clients and midwives alike, indicating sustainable integration into standard maternity care.
Clinical Midwife Specialist Evelyn Burns remarked that this continuity of care model profoundly impacts women’s confidence and connection during pregnancy. The study’s robust dataset and positive qualitative feedback from both families and clinicians provide compelling evidence for broader adoption across Australian maternity services.
This research not only validates the efficacy of culturally tailored care models but advocates for their expansion nationwide to ensure equitable and effective maternity healthcare for all First Nations families. The findings represent a pivotal shift in perinatal care paradigms, blending cultural competence with clinical excellence to improve long-term maternal and infant health outcomes.
Subject of Research: People
Article Title: The effect of culturally tailored continuity of midwifery care on perinatal outcomes for women having a first Nations baby in Victoria, Australia: a prospective non-randomised translational study
News Publication Date: 24-Jun-2026
Web References: https://www.thelancet.com/journals/eclinm/article/PIIS2589-5370(26)00281-6/fulltext
References: 10.1016/j.eclinm.2026.104028
Image Credits: La Trobe University
Keywords: Health care, First Nations, midwifery continuity, perinatal outcomes, culturally tailored care
In a groundbreaking advancement in neurological research, scientists have unveiled a novel animal model that elucidates the complex pathophysiology of CADASIL—a hereditary cerebral small vessel disease responsible for recurrent strokes and progressive cognitive decline. This innovative model leverages the unique advantages of zebrafish, an emerging organism in biomedical investigations, to faithfully replicate cardinal features of CADASIL that have eluded previous studies relying on traditional rodent systems.
CADASIL, an acronym for cerebral autosomal dominant arteriopathy with subcortical infarcts and leukoencephalopathy, is a debilitating inherited condition characterized by the deterioration of the brain’s microvasculature. This deterioration precipitates repetitive ischemic strokes and gradually destroys white matter integrity, culminating in premature dementia. Despite recognition of mutations in the NOTCH3 gene as the underlying genetic cause, the molecular mechanisms by which these mutations accelerate vascular damage and neurological decline remain inadequately understood, stalling the development of effective therapeutic interventions.
The limitations of current animal models have largely impeded progress in CADASIL research. While mouse models reproduce some pathological features, they fall short of mimicking critical clinical aspects such as notable cognitive impairment, brain atrophy, and hallmark white matter lesions observed in patients. Seeking to overcome these barriers, a research team at Chiba University in Japan strategically harnessed the zebrafish system to create a genetically engineered model expressing the CADASIL-associated NOTCH3 mutation p.C680S. This approach taps into zebrafish’s translational potential due to their genetic tractability, transparent embryos, and highly conserved neurological architecture.
Over a meticulously designed longitudinal study, the zebrafish harboring the NOTCH3 mutation were followed through key developmental milestones. Utilizing live cerebral blood flow imaging, behavioral assays to assess memory and learning, advanced magnetic resonance imaging for detecting brain structural changes, and molecular profiling techniques, the researchers captured a multidimensional portrait of disease progression. Notably, at approximately 11 months, mutant zebrafish exhibited initial declines in cerebral perfusion, a precursor to subsequent neurological dysfunction.
At 14 months, behavioral testing revealed a marked deterioration in learning capacity, with significant deficits in working memory emerging by 17 months, mirroring the temporal pattern of cognitive decline in human CADASIL patients. Structural brain assessments detected tissue loss predominantly in the cerebral regions analogous to those affected by the human disease. Electron microscopy further substantiated the model’s fidelity by identifying granular osmiophilic material deposits—abnormal protein aggregates universally recognized as a pathological hallmark of CADASIL.
Delving deeper into the molecular underpinnings, the team uncovered a pronounced reduction in type IV collagen expression surrounding cerebral vasculature in the mutant zebrafish. Type IV collagen is a vital component of the basement membrane, providing structural integrity, tensile strength, and resilience to blood vessels. The deficiency of this crucial extracellular matrix protein likely destabilizes the vascular basement membrane, rendering the vasculature susceptible to damage and disruption.
This reduction in type IV collagen offers a compelling mechanistic link between NOTCH3 mutations and microvascular fragility, providing a fresh perspective on the molecular etiology of CADASIL. The findings suggest that therapeutic strategies aimed at restoring or preserving type IV collagen integrity may hold promise for halting or reversing vascular degeneration in patients afflicted with this disease.
Highlighting the scientific significance of this work, Professor Motoyuki Itoh remarked that their study opens new avenues for exploring the interplay between genetic mutations and extracellular matrix components in age-related cerebrovascular disorders. The zebrafish model thereby stands as a versatile platform for dissecting disease mechanisms and screening potential therapeutics in a cost-effective and expedited manner.
Furthermore, the successful recapitulation of progressive vascular and neurological symptoms in this model sets the stage for the generation of future zebrafish lines harboring diverse CADASIL mutations. Such developments will expand the research toolkit, facilitating nuanced investigations into genotype-phenotype correlations and accelerating the translation of laboratory findings to clinical applications.
Beyond CADASIL, this work underscores the broader utility of zebrafish in neurodegenerative disease research. Their rapid development, amenability to high-resolution imaging, and genetic manipulability position them as invaluable in vivo models for unraveling the complexities of brain aging and dementia.
The implications of this breakthrough resonate profoundly for patients and families affected by CADASIL, particularly in East Asia where certain gene mutations are highly prevalent. The zebrafish model not only advances scientific understanding but also injects hope for the discovery of effective treatments that have, until now, remained elusive.
Looking ahead, collaborative efforts integrating zebrafish modeling with molecular genetics, pharmacology, and clinical studies promise to accelerate the pace of therapeutic innovation. This pioneering study marks a paradigm shift, showcasing how thoughtful adoption of non-traditional model organisms can surmount longstanding challenges in understanding human neurological disease.
As research continues to unravel the intricate biology of CADASIL and related disorders, it is anticipated that the zebrafish will play an increasingly central role in drug discovery pipelines, offering a window into disease processes and a testbed for novel interventions aimed at preserving brain health and function in aging populations.
The integrated research conducted by the team at Chiba University exemplifies the power of interdisciplinary collaboration, combining expertise in molecular biology, neuroscience, imaging technology, and animal modeling to break new ground in a previously intractable field.
This compelling advance heralds a new chapter in neurovascular research, with the zebrafish emerging not only as a model organism but as a beacon of hope for unlocking the secrets of devastating genetic brain diseases like CADASIL.
Subject of Research: Animals
Article Title: Age-dependent vascular and neurological characteristics of CADASIL are recapitulated in Notch3 mutant zebrafish, implicating a role for type IV collagen in disease progression
News Publication Date: 3-Jun-2026
Web References:
http://doi.org/10.1186/s40478-026-02333-8
https://www.cn.chiba-u.jp/en/news/
References:
DOI: 10.1186/s40478-026-02333-8
Image Credits:
Professor Motoyuki Itoh from Chiba University, Japan
Keywords: CADASIL, NOTCH3 mutation, zebrafish model, cerebral small vessel disease, type IV collagen, vascular basement membrane, neurodegeneration, cerebral blood flow, cognitive decline, genetic modeling, MRI, neuropathology
In an era where environmental pollutants increasingly threaten public health, breakthrough scientific methodologies are emerging to decipher the complex puzzle of chemical exposures in everyday life. The U.S. Environmental Protection Agency (EPA), through its innovative Exposure Forecasting (ExpoCast) project, has unveiled a suite of high-throughput novel approaches that promise to revolutionize our understanding of human exposure to hazardous substances. These new approach methodologies integrate cutting-edge computational power, biomonitoring data, and machine learning to clarify how chemicals enter and navigate the human body via different exposure pathways.
At the core of this scientific leap is the urgent need to move beyond traditional, labor-intensive measures of exposure assessment. Conventional methods, reliant on direct environmental sampling or biomarker tracking alone, often provide fragmented or delayed insights. ExpoCast’s high-throughput frameworks address this by enabling the rapid processing of vast chemical datasets and synthesizing multifaceted exposure routes—dermal contact, inhalation, and ingestion—into cohesive predictive models. This integration forms the backbone of a new era in toxicological science, one that could empower preventive public health strategies with unprecedented accuracy and speed.
The advanced computational techniques deployed in this research pivot on two pivotal innovations. First, the ability to infer chemical intake directly from metabolite measurements represents a quantum leap in exposure science. Metabolites—the biochemical footprints left by toxicants within the body—offer a window into the internal chemical burden of an individual. This invertible analytic approach not only isolates the true extent of chemical accumulation but also contextualizes it within the dynamic processes of metabolism and excretion. Such resolution provides critical clues for both risk characterization and regulatory evaluation.
Complementing this metabolite-centric analysis are high-throughput models that simulate multi-pathway exposures. Unlike prior assessments that treated exposure routes in isolation, these models encapsulate the reality of simultaneous, overlapping chemical encounters encountered in everyday environments. By integrating data across air, dust, water, and dietary matrices, the models generate comprehensive exposure profiles that reflect the true cumulative burden experienced by populations. This holistic perspective marks a paradigm shift in exposure science, with far-reaching implications for epidemiological research and environmental policy.
Another cornerstone of the ExpoCast project’s success lies in its deployment of sophisticated machine learning (ML) algorithms to bridge pervasive data gaps. Chemical exposure data are notoriously incomplete, especially for emerging contaminants and complex mixtures. The machine learning methods exploit chemical structures and existing information repositories to predict missing values, refine exposure estimates, and identify likely high-exposure scenarios. Through these predictive analytics, the EPA’s approach dramatically enhances the resolution and reliability of exposure assessments without the untenable demands of large-scale physical sampling.
The strength of coupling high-throughput analytics with ML-based data gap filling is evident in a recently published case study application that specifically targets indoor environments. Indoor settings are recognized as critical exposure venues given the amount of time individuals spend inside homes, workplaces, and public buildings. In this case study, researchers synchronized biomarker findings from human subjects with media-specific chemical concentration measurements—dust, indoor air, and surface residues—to validate the accuracy and applicability of their models. The congruence observed underscores the potential of these next-generation methodologies to accurately capture exposure nuances in real-world scenarios.
Delving into the technicalities, the approach of inferring chemical intake from biomarker data involves mechanistic, pharmacokinetic models. These models simulate the absorption, distribution, metabolism, and elimination (ADME) of chemicals, allowing reverse calculation from measured metabolite concentrations back to estimated exposure doses. Integrating population variability and uncertainty quantification within these models further refines predictions, supporting more nuanced risk assessments that reflect real human diversity and exposure complexities.
High-throughput exposure models, meanwhile, employ automated workflows powered by large chemical libraries, exposure factor databases, and physiological parameters. These workflows rapidly generate exposure estimates across thousands of chemicals and scenarios, facilitating prioritization in regulatory contexts. The incorporation of multi-pathway assessments elevates these models beyond simple single-route frameworks, capturing interactive effects such as dermal absorption following inhaled volatilization, or ingestion arising from hand-to-mouth transfer of settled dust.
Machine learning strategies, spanning supervised and unsupervised techniques, utilize features derived from chemical structure descriptors, physicochemical properties, and known exposure pathways to fill data voids. These models can predict exposure likelihood, magnitude, and temporal patterns with quantifiable confidence. Importantly, the EPA team employed interpretability-focused ML algorithms to ensure that the models’ decision-making processes remain transparent to toxicologists and risk assessors, a critical factor for regulatory acceptance and scientific scrutiny.
Together, these novel methodologies embody a systems-level approach to understanding chemical exposures that integrates biological, environmental, and computational sciences. They represent a shift from descriptive monitoring to predictive and mechanistically informed exposure science, capable of anticipating emerging public health threats before widespread harm occurs. Such anticipatory capacity aligns with modern needs for proactive environmental health management amid ever-expanding chemical use.
The implications extend beyond academia or regulatory agencies. Public health practitioners, clinicians, and community advocates can leverage these insights to better understand exposure disparities, tailor interventions, and inform vulnerable populations. For instance, accurately predicting exposure levels in indoor environments helps prioritize remediation or behavior modification strategies for those disproportionately impacted by chemical pollutants, such as children or individuals in lower socioeconomic strata.
From an innovation standpoint, the ExpoCast project exemplifies the power of integrating novel in silico tools with empirical biomonitoring, fostering a virtuous cycle of model refinement and real-world validation. This iterative process ensures that computational predictions remain grounded in biological realities, enhancing confidence in exposure and risk evaluations. Furthermore, as chemical inventories expand and new compounds emerge, these scalable, automated methodologies will be indispensable for keeping pace with the evolving regulatory landscape.
The broader environmental science community stands to benefit from adopting similar high-throughput, machine-learning-enabled approaches. The generalizability of these methodologies means they can be adapted for global chemical monitoring programs, occupational health assessments, and ecosystem exposure analyses. Cross-disciplinary collaboration will be critical to extend these tools and harmonize data frameworks, advancing a unified, internationally coordinated approach to chemical safety.
In conclusion, the EPA’s ExpoCast-driven advancements represent a milestone in exposure science, knitting together innovative analytical methods to unravel the complexities of human-chemical interactions. By harnessing metabolite-informed intake reconstruction, multi-pathway exposure modeling, and machine learning-based data gap filling, the project paves the way for more accurate, timely, and insightful exposure assessments. This transformative toolkit holds promise to enhance chemical risk management, protect public health, and guide sustainable environmental stewardship in an increasingly chemical-dependent world.
The research outlined in the recent publication epitomizes the potential of high-throughput new approach methodologies to revolutionize exposure science across diverse settings—from homes and workplaces to broader communities. Continued development, validation, and deployment of such integrative frameworks will be paramount in confronting the escalating challenges posed by chemical exposures in the 21st century.
Subject of Research:
Development and application of high-throughput new approach methodologies for complex chemical exposure assessment, involving biomarker inference, multi-pathway exposure modeling, and machine learning-driven data gap filling.
Article Title:
Case study application of high-throughput new approach methodologies for exposure to the interpretation of matched biomarker and indoor media measurements.
Article References:
Jacketti, M.A., Biryol, D., Setzer, R.W. et al. Case study application of high-throughput new approach methodologies for exposure to the interpretation of matched biomarker and indoor media measurements. J Expo Sci Environ Epidemiol (2026). https://doi.org/10.1038/s41370-026-00926-y
Image Credits: AI Generated
DOI: 21 June 2026
Flood-Related Surface Collapse at Osuga Valles, Mars: Unveiling the Dynamics of Martian Geomorphology
Recent research published in Communications Earth & Environment has spotlighted a remarkable phenomenon occurring on Mars — flood-related surface collapses in the Osuga Valles region. This discovery marks a transformative step in our understanding of Martian geomorphological activity, revealing dynamic processes previously undetected on the Red Planet. The comprehensive study led by Naor et al. deploys advanced remote sensing and modeling techniques to decipher the mechanisms behind these collapses, providing a fresh perspective on Mars’s hydrological past and present.
Osuga Valles, located in the northern hemisphere of Mars, has long intrigued planetary scientists due to its complex valley networks and evidence hinting at ancient water activity. The new findings reveal that these valleys are not merely relics of a bygone era but continue to undergo morphologic changes influenced by episodic flooding events. These floods, possibly triggered by subsurface ice melting or transient atmospheric phenomena, induce sudden collapses on the surface, reshaping the landscape at scales previously underestimated.
The investigation is centered around detailed analysis of high-resolution imagery combined with digital elevation models captured by Mars orbiters. These datasets allowed the researchers to identify distinct collapse features characterized by disrupted terrain, steep scarps, and chaotic blocky deposits. The spatial distribution and morphology indicate that these collapses originated from floodwaters undermining subsurface deposits, triggering a rapid failure of overlying strata.
What makes the Osuga Valles surface collapses particularly compelling is their implication for current Martian hydrology. The collapse events are believed to be linked to relatively recent flood episodes, suggesting the presence of liquid water or brines beneath the Martian surface. This challenges the longstanding notion of Mars as an entirely arid world and paves the way for hypotheses about transient hydrological cycles persisting in specific locales and under certain environmental conditions.
Moreover, the tectonic setting of the Osuga Valles region seems to facilitate these collapses. The valley system’s structural configuration, inclusive of fractures and faults, creates zones of mechanical weakness. When these structural features interface with floodwaters infiltrating subsurface layers, they act as conduits potentiating the collapse process. Thus, the interplay between geology and hydrology emerges as a critical driver of surface dynamics on Mars.
The authors also explore analogs from terrestrial environments—places where flooding induces surface collapse, such as in karst terrains or volcanic regions with subglacial lakes—to better interpret the Martian data. These Earth analogs provide a fertile framework for understanding how subsurface voids or weakened materials collapse under hydraulic pressure, refining our conceptual models applicable to Mars.
Advanced computational fluid dynamics simulations performed in the study reveal that the hydraulic pressures generated by transient floods are sufficient to disrupt sediment cohesion and trigger mass wasting events. The models incorporate variable sediment porosities, ice content, and fracture permeability, emphasizing how subtle changes in subsurface conditions can culminate in massive geomorphic transformations. This underscores the sensitivity of Martian surface processes to inundation events, even if these are limited in time and spatial extent.
In addition, the researchers analyzed mineralogical data from spectrometers aboard orbiters, detecting possible hydrated minerals and salts that corroborate the interaction between water and subsurface sediment. This mineralogical evidence supports the hypothesis of localized aqueous alteration driven by flood events, contributing to ongoing soil and sediment evolution in Osuga Valles.
The implications of these findings extend beyond geology and planetary science to astrobiology. The presence of liquid water, even transiently, opens up potential niches for microbial life or preserves biosignatures in subsurface refuges. Flood-related collapses could expose freshly altered materials, creating accessible targets for future rover missions endeavoring to seek signs of life or past habitability.
Technological advancements in orbital imaging and data analysis have thus unlocked a new era in Martian surface exploration. This study leverages these capabilities, illustrating how multidisciplinary approaches integrating geomorphology, hydrology, geochemistry, and computational modeling can unravel complex planetary phenomena. The Osuga Valles floods and collapses exemplify the dynamic and evolving nature of Mars, still shaped by aqueous forces despite its overall cold and dry climate.
Looking forward, these discoveries necessitate a revision in mission planning and surface hazard assessments. Understanding flood-related collapses aids in predicting surface stability and potential geomorphic hazards affecting landers or rovers. Moreover, unraveling the hydrologic cycles underlying these collapses could inform in situ resource utilization strategies, potentially enabling human exploration by identifying water reservoirs.
Furthermore, this research revitalizes the debate about Mars’s climatic variability and the possibility of episodic warming events facilitating surface liquid water. Such events might arise from volcanic outgassing, orbital shifts, or impact heating, temporarily altering atmospheric and subsurface conditions to create flood-triggering scenarios. Consequently, Osuga Valles may serve as a natural laboratory to study these transient climatic phenomena.
In summary, the study by Naor et al. dramatically expands our understanding of Martian surface processes by revealing active, flood-related collapses in Osuga Valles. By decoding the intricate linkages between subsurface hydrology, geological structure, and surface dynamics, it paints a picture of Mars as a planet where water still plays a crucial role in shaping landscapes. This breakthrough invites a new generation of explorations targeted at unraveling the mysteries of Mars’s watery past and its intermittent present.
The knowledge gained from these investigations not only transforms planetary science but also enriches comparative planetology, emphasizing how terrestrial analogs can illuminate extraterrestrial environments. As we decode Mars’s dynamic surface, the paradigm shifts from a static, desiccated world to one punctuated by active, fluid-driven geomorphology. The dynamic interplay between floods and collapses in Osuga Valles is a testament to this evolving narrative—a promise for thrilling discoveries yet to come.
Subject of Research: Flood-related surface collapses and geomorphologic processes on Mars, specifically in the Osuga Valles region.
Article Title: Flood-related surface collapse at Osuga Valles, Mars.
Article References:
Naor, R., Gulick, V.C., Spurling, R. et al. Flood-related surface collapse at Osuga Valles, Mars. Communications Earth & Environment (2026). https://doi.org/10.1038/s43247-026-03683-w
Image Credits: AI Generated
DOI: https://doi.org/10.1038/s43247-026-03683-w
Keywords: Mars geomorphology, flood-related collapse, Osuga Valles, Martian hydrology, subsurface water, geomorphic dynamics, remote sensing, planetary geology
Scientists Warn: Eastern and Southern Asian Gymnosperms Face Imminent Extinction Amid Accelerating Climate Change
The botanical world stands on the edge of a crisis as groundbreaking research exposes the severe vulnerability of gymnosperms inhabiting Eastern and Southern Asia. A study published recently in Communications Earth & Environment projects a grim future for these ancient plant species, contriving to predict their potential extinction driven by rapid, anthropogenic climate shifts. Gymnosperms, a critical group of seed-producing plants including pines, cycads, and ginkgos, have thrived on Earth for millions of years, yet they now face an unprecedented existential threat.
The research team, led by environmental scientists Tang C.Q., Matsui T., and Shitara T., delved deep into the combined effects of rising temperature, shifting precipitation patterns, and increased frequency of extreme weather events on gymnosperm populations. Their models integrate climate projections with species-distribution data, revealing that the traditionally temperate and subtropical niches occupied by these gymnosperms will dramatically shrink by the middle of the 21st century. The researchers underscored that this decline is not uniform; rather, certain species endemic to specific mountainous or coastal ecosystems display alarmingly higher risk profiles.
Gymnosperms perform indispensable ecological functions, including carbon sequestration, habitat provision, and soil stabilization. Their dwindling numbers could initiate cascading environmental consequences in Asia’s biodiverse forests. The botanical group’s deep-rooted historical presence has allowed ecosystems to flourish through millennia; however, current climate trends disrupt the intricate balance of these habitats at a speed too fast for evolutionary adaptation or migration to compensate.
The research methodology involved coupling high-resolution climate modeling with phylogenetic analysis of gymnosperms. By mapping physiological tolerances and reproductive traits against future climate scenarios simulated under various Representative Concentration Pathways (RCPs), the study offers one of the most comprehensive assessments to date. Crucially, it highlights that while some gymnosperm species maintain a degree of resilience due to wider ecological amplitude, many are specialists confined to narrow environmental parameters and thereby disproportionately susceptible.
Tang and colleagues emphasize the intricate relationship between temperature increases and drought incidence in the region, noting that these stressors synergistically impair gymnosperm vitality. Water stress impacts photosynthetic efficiency, disrupts nutrient uptake, and elevates susceptibility to pests and diseases. In marginalized microhabitats or high-altitude refugia, these effects intensify, leading to localized extirpations that can spiral into broader population collapses over time.
The implications extend beyond botanical loss; gymnosperms constitute foundational species in many forest ecosystems, affiliate with mycorrhizal fungi essential for nutrient cycling, and provide resources for myriad animal taxa. The potential disappearance of these plants risks triggering ethological and trophic-level shifts, reducing ecosystem resilience to further climate perturbations. Furthermore, economically important species used for timber, traditional medicine, and cultural practices face sharp declines, posing socioeconomic challenges.
This research also serves as a dire warning against complacency in regional conservation strategies. Protected areas alone may prove insufficient if climatic envelopes shift beyond the reach of current reserves. The scientists advocate for integrated approaches, including assisted migration, ex situ conservation, and the establishment of ecological corridors to facilitate natural dispersal. Prioritizing gymnosperms with limited dispersal ability and narrow ecological niches is urgent to formulate responsive management frameworks.
The study explores the genetic diversity patterns across gymnosperm populations to evaluate adaptive capacity. Low genetic variability combined with rapid environmental changes diminishes resilience, constraining evolutionary potential. Loss of phylogenetic diversity risks undermining ecosystem functions more severely than numerical species losses alone, as more distinct lineages harbor unique functional traits critical for ecosystem stability.
Researchers also discuss phenotype plasticity and reproductive timing alterations in response to shifting climate variables. Disruptions in phenology—such as mismatches in pollination timing or seed maturation cycles—further complicate species survival trajectories. These dynamics, observed empirically in several regional species, underscore the complex interplay of biotic responses to multifaceted climate stressors.
The comprehensive data synthesis provided by Tang et al. highlights key geographic hotspots where gymnosperm extinction risk concentrates. Mountain ranges and isolated forest patches in Eastern China, Vietnam, and parts of the Himalayas emerge as critical areas for intensified conservation actions. In contrast, some upland refuges might preserve pockets of gymnosperm diversity, warranting prioritized protection and monitoring.
The projected losses loom as one of the most significant biodiversity crises in plant history within this region. The consequences for carbon dynamics depend on how these gymnosperm populations, which often function as carbon reservoirs, respond to climate change. The decline of such reservoirs exacerbates atmospheric CO2 accumulation, amplifying global warming in a feedback loop.
This study further calls for robust interdisciplinary collaboration between climatologists, ecologists, foresters, and policymakers to devise adaptive strategies addressing these challenges. Integrating remote sensing, long-term ecological monitoring, and community-based conservation initiatives could bolster efforts to safeguard remaining gymnosperm populations.
In conclusion, this sobering new evidence underscores the urgent need for both mitigating climate change drivers and innovating species-specific conservation measures. By illuminating the precarious status of Eastern and Southern Asian gymnosperms, Tang and colleagues have provided an essential scientific foundation that demands immediate international attention and action. Failing to act risks erasing a vital part of Earth’s botanical heritage, with irreversible ramifications for ecosystems and human societies alike.
Subject of Research: Extinction risk of Eastern and Southern Asian gymnosperms under climate change.
Article Title: Eastern and southern Asian gymnosperms are doomed to extinction under climate change.
Article References:
Tang, C.Q., Matsui, T., Shitara, T. et al. Eastern and southern Asian gymnosperms are doomed to extinction under climate change. Commun Earth Environ (2026). https://doi.org/10.1038/s43247-026-03759-7
Image Credits: AI Generated
Spinal cord injury (SCI) represents one of the most devastating neurological conditions, profoundly disrupting sensory, motor, and autonomic functions below the level of injury. Its consequences extend far beyond mere physical impairment, encompassing a complex web of psychological and social challenges that pose a substantial burden on patients and their caregivers. Among the myriad complications that arise following SCI, the loss of voluntary control over bladder function remains particularly debilitating, undermining patient autonomy, quality of life, and dignity. The intricate interplay of neural pathways governing lower urinary tract function becomes severely compromised, leading to neurogenic bladder dysfunction that is intricately linked with heightened risks of urinary tract infections, renal damage, and incontinence.
For decades, researchers have relied extensively on animal models to unravel the pathophysiological underpinnings of SCI and its associated comorbidities. These preclinical platforms have proven indispensable in dissecting the cellular and molecular cascades triggered by spinal trauma, enabling the identification of potential therapeutic targets. Through controlled experimental conditions, scientists have been able to mimic various types of SCI lesions, from contusions to complete transections, affording nuanced insights into injury severity and plasticity mechanisms. Moreover, animal models facilitate the rigorous testing of novel interventions — ranging from pharmacological agents to neuromodulatory devices — that aim to restore neural circuits or promote regeneration within the damaged spinal cord.
Despite these advancements and the critical role that animal experimentation has played, a persistent and contentious debate surrounds the translational effectiveness of these models. The stark reality is that many promising therapeutic strategies that yielded encouraging results in animals have failed to replicate similar benefits in human clinical trials. This translational gap underscores the biological and physiological differences between species, as well as the complexity of accurately reproducing the heterogeneity and chronicity of human SCI in simpler model organisms. Ethical considerations also compound the urgency for innovation, fueling a global momentum toward reducing reliance on animal studies where feasible and developing alternative methodological approaches.
In the evolving landscape of biomedical research, technological progress is fostering the emergence of cutting-edge in vitro and in silico models that promise to complement or potentially supplant traditional animal-based experiments. Organoids, microfluidic systems, and advanced computational simulations are gaining traction as sophisticated tools capable of recapitulating key elements of spinal cord architecture and function. These platforms aspire not only to reduce animal use but also to offer greater experimental control and reproducibility, potentially accelerating the pipeline from bench to bedside. Importantly, regulatory agencies are increasingly acknowledging and supporting these innovative approaches, embedding them within frameworks that ensure safety and efficacy without compromising ethical standards.
A nuanced understanding of neuro-urological dysfunction post-SCI exemplifies the complexity of this translational challenge. The control of bladder function is regulated by an intricate network involving supraspinal centers, spinal interneurons, and peripheral autonomic pathways. Following SCI, this orchestration is disrupted, with varying patterns of dysfunction depending on the lesion level and severity. Animal models, ranging from rodents to large mammals, capture distinct aspects of these patterns and have been pivotal in characterizing mechanisms like detrusor overactivity, sphincter dyssynergia, and altered afferent signaling. However, clinical phenotypes observed in humans often present additional layers of intricacy that are not fully paralleled in animal studies, highlighting the necessity for enhanced model fidelity.
Within experimental contexts, the choice of animal species and injury paradigms is driven by the specific research question being addressed. Rodents, primarily rats and mice, are favored for their genetic tractability, well-established behavioral assays, and cost-effectiveness. Larger mammalian models such as cats, dogs, and non-human primates offer advantages in anatomical and physiological similarity to humans but involve substantial ethical and logistical challenges. Each model carries inherent limitations in terms of reproducing chronic injury states, co-morbid conditions, and the psychosocial dimensions of SCI, factors that have contributed to translational discrepancies in therapeutic development.
Advances in imaging technologies, electrophysiological monitoring, and biomarker identification have supplemented animal research by enabling more precise phenotyping of SCI and its neuro-urological consequences. Functional MRI, calcium imaging, and optogenetics provide unprecedented views into spinal cord circuitry and its plastic adaptations, facilitating the assessment of intervention efficacy at multiple neurobiological scales. Nonetheless, integrating these sophisticated methods across species and in translational studies demands rigorous standardization and validation to ensure data comparability and clinical relevance.
Contemporary therapeutic strategies emerging from animal research encompass pharmacological modulators targeting neurotransmitter systems, stem cell transplantation to replace lost or damaged neurons, and bioengineering approaches aimed at bridging lesion gaps or providing scaffolding for axonal regrowth. Neuromodulation techniques such as electrical stimulation of sacral nerves or the spinal cord itself have shown promise in restoring partial bladder control, with a handful of such technologies transitioning into clinical trials. These advances underscore the indispensable role of preclinical models in pioneering interventions that address both the neurogenic bladder and the broader spectrum of SCI-induced disability.
Looking ahead, the field stands at a crossroads, poised between longstanding reliance on animal experimentation and the transformative potential of emerging modeling strategies. While animal models remain critical for certain studies, the integration of alternative approaches is anticipated to accelerate in the coming decade. Such a paradigm shift will depend not only on technological innovations but also on a collaborative ecosystem involving scientists, clinicians, regulatory bodies, and patient advocacy groups to harmonize research priorities and ethical considerations.
Indeed, the question of whether animal models will retain their central role in neuro-urological SCI research by 2035 reflects broader themes in biomedical research ethics, experimental rigor, and translational success. A hybridized methodology that combines animal models with advanced in vitro systems and computational models may offer the most fruitful path forward, marrying the biological relevance of whole organisms with the precision and scalability of engineered platforms. This integrative approach could foster more effective therapies for SCI patients suffering from bladder dysfunction, reducing the human and economic toll of this challenging condition.
Crucially, patient-centered outcomes must guide research priorities, ensuring that innovations translate into tangible improvements in bladder control, autonomy, and quality of life. The intersection of neurobiology and urology demands interdisciplinary collaboration and sustained investment in technologies that can simulate the complex neurogenic bladder environment. Such efforts will define the scientific landscape of SCI research, promising new horizons in repair and rehabilitation.
Regulatory frameworks will also play a pivotal role in steering the future of SCI research methodologies. Agencies are increasingly promoting the 3Rs principle—replacement, reduction, and refinement of animal use—with heightened scrutiny on the predictive validity of animal models. Enhanced guidelines supporting alternative models could incentivize their adoption and facilitate expedited regulatory approval for novel therapeutics. This dynamic will likely reshape both academic and industry research strategies in neuro-urology.
In sum, while animal models have undeniably been cornerstones of SCI neuro-urological research, the field is undergoing a fundamental transformation informed by ethical imperatives, scientific rigour, and technological innovation. The trajectory toward 2035 suggests a diminishing but not extinguished role for animal experimentation, coexisting with advances that enhance the resolution and relevance of preclinical research. This evolution holds promise to one day liberate SCI patients from the grip of neurogenic bladder dysfunction, restoring dignity and function through precision medicine grounded in robust scientific inquiry.
The road ahead is both challenging and exhilarating, promising breakthroughs borne from an unprecedented synergy of traditional biological models and revolutionary engineering and computational tools. As neuroscience and urology converge on the frontier of spinal cord repair, the legacy of animal research endures—not as a relic but as a foundational pillar supporting the ascent toward a future where SCI is a treatable rather than a life-altering diagnosis.
Subject of Research: Animal models of spinal cord injury in neuro-urological research
Article Title: Animal models of spinal cord injury in neuro-urological research
Article References:
Giannotti, A., Aguinaga, D.M., Ferreira, A. et al. Animal models of spinal cord injury in neuro-urological research. Nat Rev Urol (2026). https://doi.org/10.1038/s41585-026-01163-6
Image Credits: AI Generated
In a groundbreaking advancement that could revolutionize cancer prognosis and treatment, a team of researchers led by Liu, X., Dai, F., and Dai, J., has unveiled a sophisticated multimodal multitask deep learning system for grading management in non-small cell lung cancer (NSCLC). Published recently in Nature Communications, this innovative approach integrates diverse data modalities through an advanced artificial intelligence framework, demonstrating unprecedented accuracy and efficiency in tumor grading and patient stratification—key factors in tailoring personalized therapies and improving patient outcomes.
Non-small cell lung cancer remains one of the leading causes of cancer-related mortality worldwide, largely due to its heterogeneity and the challenge of precise tumor grading. Traditional grading methods rely heavily on histopathological analysis, which, while indispensable, faces limitations in capturing the complex biological and morphological variations across patients. This novel multimodal multitask network leverages deep learning’s capacity to extract nuanced features across multiple data types, including histology images, radiographic scans, and molecular profiles, effectively capturing the multidimensional nature of the disease.
The core innovation of this system lies in its multitask learning architecture, which simultaneously addresses multiple clinical endpoints—tumor grading, staging, and survival prediction—within a unified model. This approach contrasts with previous single-task models that focus on one predictive target, often neglecting the interdependencies among clinically significant tasks. By jointly optimizing these objectives, the model enhances its robustness and clinical utility, improving prognostic accuracy and enabling more informed decision-making.
From a technical perspective, the deep learning model employs convolutional neural networks (CNNs) tailored to each data modality. For imaging data, sophisticated CNN architectures with residual connections enable hierarchical feature extraction, while genomic and proteomic data are processed via fully connected layers, integrated through fusion mechanisms within the network. Crucially, the system employs attention mechanisms that dynamically weigh contributions from each data source, ensuring that the most relevant features guide the tumor grading process. This multimodal fusion enhances interpretability, as clinicians can trace back which data aspects influence the model’s predictions.
The training dataset comprises an extensive cohort of NSCLC patients, encompassing thousands of digitized histopathology slides, CT images, and matched molecular data. The researchers implemented rigorous preprocessing pipelines to normalize and augment the data, addressing variability inherent in clinical datasets. Importantly, domain adaptation techniques were employed to mitigate batch effects and imaging protocol heterogeneity, ensuring the model’s generalizability across different clinical settings and patient populations.
Performance metrics reported in the study underscore the system’s superiority over conventional grading methods and previous AI models. With an area under the receiver operating characteristic curve (AUC-ROC) exceeding 0.90 for tumor grading tasks, the model exhibits remarkable sensitivity and specificity. Notably, survival prediction tasks achieved similarly high accuracy, enabling stratification of patients into risk categories with potential to guide treatment intensification or de-escalation.
In addition to diagnostic accuracy, the system’s design emphasizes clinical workflow integration. The researchers developed an interactive platform allowing pathologists and oncologists to visualize model outputs alongside raw data, fostering collaborative interpretation. This interface incorporates uncertainty quantification and confidence scores, aiding clinicians in evaluating prediction reliability and assimilating AI-driven insights with clinical judgment.
The researchers also addressed ethical and regulatory considerations critical for clinical deployment. Data privacy was preserved through federated learning techniques during model training, circumventing the need for centralized data storage and enabling multi-institutional collaboration without compromising patient confidentiality. Moreover, the model’s transparent architecture and interpretability features facilitate compliance with emerging AI governance frameworks and regulatory approvals.
Beyond the immediate clinical implications, this study exemplifies the transformative potential of deep learning for precision medicine. By capturing tumor heterogeneity through multimodal data fusion, it paves the way for dynamic tumor characterization that adapts to evolving cancer biology over time, potentially informing adaptive therapy paradigms. Furthermore, the model’s multitask structure could be extended to other malignancies or complex diseases characterized by multifactorial phenotypes.
The authors highlight several avenues for future research, including prospective clinical trials to assess real-world efficacy and impact on treatment outcomes. Plans to incorporate longitudinal patient data hold promise for modeling disease progression and therapy resistance. Additionally, incorporating emerging data modalities such as circulating tumor DNA and spatial transcriptomics could further refine the grading system’s sensitivity and specificity.
In summary, this landmark study ushers in a new era of AI-driven oncology, where deep learning models not only automate grading but also synthesize heterogeneous clinical data to empower personalized management in NSCLC. By bridging computational innovation and clinical applicability, it stands to significantly enhance diagnostic precision, treatment planning, and ultimately patient survival in a notoriously challenging cancer type.
As research continues to unravel the complexities of NSCLC, such sophisticated AI frameworks represent vital tools in the quest to deliver more effective, individualized care. The collaborative effort showcased by Liu, Dai, and colleagues sets a compelling precedent for harnessing multimodal data integration and multitask deep learning to tackle other pressing challenges in oncology and beyond.
Subject of Research: Multimodal multitask deep learning for tumor grading and management in non-small cell lung cancer
Article Title: Multimodal multitask deep learning for grading management system in non-small cell lung cancer
Article References: Liu, X., Dai, F., Dai, J. et al. Multimodal multitask deep learning for grading management system in non-small cell lung cancer. Nat Commun (2026). https://doi.org/10.1038/s41467-026-74474-2
Image Credits: AI Generated
In an unprecedented advancement for neurodegenerative disease research, a team led by Busquets, Li, Syed, and colleagues has unveiled iSCORE-PD, an innovative isogenic stem cell repository designed explicitly to accelerate Parkinson’s disease studies. Published in Nature Communications in 2026, this comprehensive collection represents a pivotal leap toward resolving the complex pathophysiology of Parkinson’s, a condition affecting millions worldwide yet still eluding curative therapies. The iSCORE-PD platform promises to redefine experimental paradigms by providing scientists with genetically matched cellular models that mirror the intricate genetic underpinnings of Parkinson’s disease.
Parkinson’s disease is characterized primarily by the progressive loss of dopaminergic neurons in the substantia nigra pars compacta, leading to debilitating motor symptoms such as tremors, rigidity, and bradykinesia, alongside a spectrum of non-motor complications. Despite extensive research, there remains a conspicuous gap between clinical observations and mechanistic understanding at the cellular and molecular levels. Existing animal models and conventional stem cell lines often fall short in recapitulating the exact human pathology. The iSCORE-PD initiative addresses this deficiency head-on by harnessing isogenic stem cell lines, which are genetically identical except for defined Parkinson’s-relevant mutations, thus enabling unprecedented control over genetic variables.
The technical foundation of iSCORE-PD relies on advanced genome editing methodologies, most notably CRISPR/Cas9 technology. By precisely introducing or correcting mutations in key genes implicated in Parkinson’s pathogenesis such as SNCA, LRRK2, PINK1, and PARKIN, researchers have generated isogenic pairs of induced pluripotent stem cells (iPSCs). These iPSC lines can subsequently be differentiated into dopaminergic neurons or other relevant cell types, facilitating side-by-side comparisons that isolate the effects of specific genetic alterations without the confounding noise of inter-individual genetic variability.
One of the remarkable features of the iSCORE-PD collection is its extensive genomic validation pipeline. Whole genome sequencing and transcriptomic analyses are systematically employed to ensure the integrity and authenticity of the edited lines, confirming that off-target effects are minimized and that the genetic landscape conforms precisely to intended edits. This meticulous validation is crucial for downstream experiments intending to dissect subtle cellular phenotypes attributable to Parkinson’s mutations with a high degree of confidence.
The availability of these isogenic cell lines dramatically enhances the fidelity of disease modeling. Scientists can now observe, in real time and within a human cellular context, the cascade of pathological events triggered by individual mutations. For instance, iSCORE-PD lines harboring the G2019S mutation in LRRK2 have already demonstrated distinct lysosomal dysfunction and mitochondrial impairment, hallmarks of Parkinson’s-related neurodegeneration. These insights provide vital clues about the molecular mechanisms that underpin neuronal vulnerability and death.
Beyond mechanistic studies, iSCORE-PD serves as an invaluable platform for drug discovery and therapeutic screening. High-throughput assays conducted on these standardized cellular models allow for robust evaluation of candidate compounds’ efficacy and toxicity. The isogenic background ensures that drug responses can be directly attributed to genetic contributors and not extraneous genomic differences, thereby accelerating the identification of promising therapeutic leads with increased translational potential.
Moreover, the iSCORE-PD repository supports integrative omics approaches. By coupling proteomics, metabolomics, and epigenomic profiling with the genetically defined cell lines, researchers can generate comprehensive molecular atlases elucidating the multifaceted alterations engendered by Parkinson’s-associated mutations. Such data-rich resources augment our understanding of disease heterogeneity and may reveal novel biomarkers for early diagnosis and progression monitoring.
The initiative also pioneers robust methodologies for modeling non-cell autonomous effects in Parkinson’s pathology. By co-culturing isogenic dopaminergic neurons with glial cells or other brain cell types derived from similarly engineered iPSC lines, investigators can explore the cell–cell interactions and inflammatory pathways that contribute to disease propagation. These complex in vitro systems increasingly resemble the in vivo brain microenvironment, bridging translational gaps.
In addition to its scientific hinge, iSCORE-PD represents a significant step forward in reproducibility and collaborative science. By providing open-access to a rigorously characterized and genetically standardized stem cell collection, the project promotes harmonization of experimental models across laboratories worldwide. This standardization mitigates discrepancies often observed in Parkinson’s research due to genetic heterogeneity of patient-derived cells and disparate culture conditions.
Ethical considerations have been front and center in the development and dissemination of the iSCORE-PD lines. The team has implemented stringent protocols to ensure donor anonymity, informed consent, and compliance with international guidelines for stem cell research. This ethical diligence is fundamental to fostering public trust and enabling broad scientific utilization with responsibility.
The iSCORE-PD research consortium envisions future expansion of the collection to encompass additional mutations, gene variants, and epigenetic modifications implicated in Parkinson’s disease, thereby creating an ever-more comprehensive toolkit for the field. This evolving repository will facilitate the study of gene–environment interactions and provide models for the sporadic forms of Parkinson’s that constitute the majority of cases.
Importantly, the development of iSCORE-PD aligns synergistically with advances in single-cell sequencing and live-cell imaging technologies. These combined approaches empower real-time monitoring of neuronal dynamics, synaptic connectivity, and intracellular trafficking in disease-relevant contexts. Such capabilities promise to unravel the temporal progression of neuronal dysfunction in unprecedented detail.
The translational impact of iSCORE-PD extends beyond fundamental research, holding profound implications for personalized medicine. Patient-specific isogenic lines can be derived, enabling evaluation of individualized drug responses and prediction of disease progression trajectories. This precision medicine paradigm could revolutionize clinical management and therapeutic development for Parkinson’s patients.
Finally, iSCORE-PD serves as a testament to the power of interdisciplinary collaboration, integrating expertise in stem cell biology, genome editing, neuroscience, bioinformatics, and clinical neurology. This concerted effort exemplifies how cutting-edge technologies, when harnessed collectively, can illuminate complex diseases and hasten the arrival of effective treatments.
In sum, the iSCORE-PD isogenic stem cell collection stands as a groundbreaking resource that transforms the landscape of Parkinson’s disease research. By providing genetically precise, highly validated cellular models, it enables unparalleled mechanistic insights, drug discovery opportunities, and personalized medicine applications. As the Parkinson’s field grapples with its most urgent challenges, iSCORE-PD promises to be a beacon guiding innovative interventions and ultimately improving patient outcomes worldwide.
Subject of Research: Parkinson’s disease; isogenic stem cell models; neurodegeneration; genome editing; induced pluripotent stem cells.
Article Title: iSCORE-PD: an isogenic stem cell collection to research Parkinson’s disease.
Article References:
Busquets, O., Li, H., Syed, K.M. et al. iSCORE-PD: an isogenic stem cell collection to research Parkinson’s disease.
Nat Commun (2026). https://doi.org/10.1038/s41467-026-74355-8
Image Credits: AI Generated
