❌

Reading view

Researchers had 124 adults cut their email checking to three times a day — what dropped wasn’t their workload, it was their daily stress

How many times do you check your email on a normal workday? Be honest. Not the number you’d like to say, the real one, counting every quick glance at the phone and every tab you flick back to between actual tasks.

Some research suggests this little habit might have an effect on wellbeing and stress. 

A quick note before we go further: I’m a writer, not a psychologist or a clinician, and what follows is me reading and thinking about one study, not handing out advice. The research here is drawn from a particular group of people, so treat it as a useful clue about how attention and stress interact, not a rule about your life.

In 2014, Kostadin Kushlev, then a PhD candidate, and Elizabeth Dunn at the University of British Columbia ran a two-week field experiment to test something simple. Does checking email less often make you feel better? They published it the following year in Computers in Human Behavior as “Checking email less frequently reduces stress.”

They recruited 124 adults, about two-thirds of them students, the rest a mix of financial analysts, medical professionals and others. Over two weeks, each person spent one week checking email as often as they liked, and another week limited to three times a day. Which week came first was decided at random. So everyone was their own comparison, living both ways.

You might expect the finding to be about getting more done. Fewer interruptions, more output, that sort of thing. That isn’t what they measured, and it isn’t what jumped out.

What they found was that people felt calmer during the limited week. Participants reported significantly lower daily stress when they were checking less, and lower stress in turn predicted higher well-being across a range of measures. Kushlev put it as plainly as it can be put. “Our findings showed that people felt less stressed when they checked their email less often.”

It’s one two-week study of 124 mostly young people, so it’s a clue rather than a verdict, but the mechanism it points to has shown up in other workplace research too.

The stress relief didn’t come from clearing the inbox faster or replying the moment something landed. It came from checking less often, full stop. The authors point at attention fragmentation, the cost of constantly breaking off what you’re doing to glance at something else, not the speed of your replies.

I know that cost intimately, because I lose to it most days. A Slack message comes in while I’m writing. I tell myself I’ll just glance. I glance, I answer, I come back to the document, and then I sit there for a while staring at the half-finished sentence, trying to remember where I was going with it. The message took ten seconds. Getting back into the writing takes a lot longer.

I’ve built a small fortress against this, with mixed success. The phone goes in another room. I close every tab before I start. No social media open while I work. None of it makes me disciplined. The systems leak, I break my own rules, and some mornings the fortress is more of a fence. But the principle holds: the cost is the interruption itself, not whether the email was urgent.

There’s a wrinkle that makes the study more honest, not less. The people in the limited week mostly couldn’t actually hit three times a day. They checked a mean of about 4.7 times, well above the target, against a baseline of about 15 checks on a normal workday. Kushlev was upfront about it: “Most participants in our study found it quite difficult to check their email only a few times a day.”

So the lower stress showed up in people who tried and largely fell short. That’s encouraging, because most of us are going to fall short too. You don’t have to be a monk about it. Cutting from fifteen-odd checks toward five seems to do something, even if three stays out of reach. As Kushlev framed it, drawing on his own study, “people find it difficult to resist the temptation of checking email, and yet resisting this temptation reduces their stress.”

Kushlev says he changed his own habit after the study. He now checks email in chunks several times a day, rather than constantly responding to messages as they arrive. That’s the one lever from all of this I’ve actually pulled, and the one I plan on keeping — not three times a day, just in chunks, with the inbox shut in between, getting back to whatever I was supposed to be doing before the next glance.

If the low hum of being always-on has tipped into something heavier than email annoyance, a chat with a qualified therapist is worth far more than anything I can offer here.

The post Researchers had 124 adults cut their email checking to three times a day — what dropped wasn’t their workload, it was their daily stress appeared first on Space Daily.
  •  

In September 1969, a 100-kilogram space rock exploded in the sky above Murchison, Australia — and 50 years later, scientists analyzing dust grains buried inside the meteorite found particles between 5 and 7 billion years old, formed in the dying outer layers of stars that lived and died long before our Sun was born, in what remains the oldest solid material ever identified on the surface of the Earth

The Murchison meteorite is, by every available measure, one of the more scientifically valuable single rocks ever to fall on the planet. The fireball that delivered it streaked across the sky above the Goulburn Valley in southeastern Australia on a Sunday morning in September 1969, broke apart at high altitude, and scattered fragments across a roughly 35-square-kilometre area of farmland. One piece punched through the roof of a hay shed. The local dairy farmers who recovered most of the fragments over the following weeks sold the bulk of them to museums and universities, with the largest single collection now held by the Field Museum of Natural History in Chicago. Approximately 80 kilograms of the original 100-kilogram fall is currently held in scientific collections around the world. Over the subsequent five decades, Murchison has been examined more intensively than almost any other meteorite — yielding more than 70 distinct amino acids (including some that do not occur in any known terrestrial biology), sugars including ribose (the backbone of RNA), and several of the nucleobases that make up the building blocks of DNA. The rock has been at the centre of multiple revisions to scientific understanding of how organic chemistry distributes itself through the early solar system.

According to NBC News’s coverage of the 2020 Heck et al. paper on presolar grains in Murchison, the team published its dating results in the Proceedings of the National Academy of Sciences in January 2020. The analysis used a technique called cosmic-ray exposure dating, which Heck described with an unusually accessible analogy: cosmic rays — high-energy particles that constantly stream through the galaxy — interact with solid matter and produce new elements at a roughly constant rate. The longer a particle of matter has been drifting through space exposed to cosmic rays, the more of these new elements accumulate inside it. “I compare this with putting out a bucket in a rainstorm,” Heck told reporters at the time. “Assuming the rainfall is constant, the amount of water that accumulates in the bucket tells you how long it was exposed.” Applying this method to 40 large silicon-carbide grains extracted from the Murchison fragments, the Heck team was able to estimate how long each individual grain had been drifting through interstellar space before being incorporated into the asteroid that eventually fell to Earth.

What presolar grains actually are

The grains the Heck team dated are called presolar grains — solid particles that formed in the atmospheres of dying stars before the solar system existed, drifted through the interstellar medium for hundreds of millions or billions of years, and were then incorporated into the molecular cloud from which the Sun and planets eventually condensed. As reported in Sci.News’s coverage of the same paper, the typical formation environment for the silicon-carbide grains examined by the Heck team was the slowly-expanding atmosphere of an asymptotic giant branch (AGB) star — a red giant in the late stages of its evolution, shedding its outer layers into space at a rate of roughly one solar mass every hundred thousand years. The carbon, silicon, and other elements in the stellar atmosphere condense as the gas cools and expands, forming microscopic dust grains that are then carried outward by the stellar wind into the surrounding interstellar medium.

Most of these grains, once released into space, are eventually destroyed by some combination of supernova shock waves, radiation, and chemical reprocessing within the molecular clouds where new stars form. A small fraction survive intact for billions of years, drifting through the galaxy as part of the general inventory of interstellar dust. When a new solar system begins to form by gravitational collapse of a dense region of interstellar gas, this dust is incorporated into the early protoplanetary disc — and the heat and chemistry of solar system formation typically destroys or substantially alters most of it. The grains that survive intact through the entire formation process do so because they are extraordinarily durable (silicon carbide is one of the hardest materials in nature) and because they are quickly incorporated into the deep interiors of primitive asteroids that never undergo significant thermal processing. Murchison’s parent body was one such asteroid. The grains inside the Murchison fragments are, in a literal sense, time capsules from before the solar system existed.

The age distribution

The headline figure from the Heck team’s analysis — that the oldest grains are approximately 7 billion years old, predating the solar system by approximately 2.5 billion years — captures the extreme of the distribution rather than the average. Per ScienceDaily’s coverage of the Field Museum announcement, the full age distribution of the 40 grains was substantially more informative than the single extreme number suggests. Approximately 60 percent of the grains formed between 4.6 and 4.9 billion years ago — in the few hundred million years immediately preceding the formation of the solar system. Approximately 10 percent formed more than 5.6 billion years ago. A small number formed at the extreme end, around 7 billion years ago. Every grain examined was, by the cosmic-ray exposure dating, older than the 4.6-billion-year-old Sun. This is what made them presolar.

The distribution itself carries scientific weight beyond the individual grain ages. The clustering of a substantial fraction of grains in a narrow age band suggests that an unusual number of stars in the Milky Way galaxy formed, lived their full life cycles, and died during a specific epoch several billion years before the Sun ignited — a “burst” of star formation that produced an unusually large population of dying stars whose outflows seeded the surrounding interstellar medium with the dust that would later contribute to the formation of the solar system. The Heck team’s interpretation, drawing on the age distribution, is that this burst occurred approximately 7 billion years ago. The implication is that the Sun and the planets formed, several billion years later, from a galactic environment that had been substantially enriched with material from this earlier generation of stars.

Why no comparable material exists on Earth

As reported by Malay Mail’s coverage of the age distribution, the broader reason presolar grains can only be found in meteorites — never in any rock of terrestrial origin — is that every piece of solid material that contributed to Earth’s formation has subsequently been heated, melted, recrystallised, or otherwise reprocessed by the geological activity of the planet itself. Plate tectonics has churned the entire crust through the mantle and back at least once. Volcanism has melted and re-erupted vast quantities of material. Even the oldest rocks on Earth, found in places like the Acasta Gneiss Complex in northern Canada, are at most 4.0 to 4.2 billion years old — substantially younger than the planet itself, and far younger than the presolar grains preserved inside primitive meteorites.

The Murchison meteorite, in this respect, occupies a peculiar epistemological position. It is the closest available physical sample of the early solar system, but it is also a sample of the pre-solar-system galaxy that produced the early solar system. The grains inside it are older than anything that can be found by digging downward through the rocks of Earth, by any depth or any drilling technology. They are, in essence, a sample of the chemistry of the Milky Way at a moment several billion years before any of the familiar features of the current solar system existed. The fragments collected by Australian dairy farmers in 1969 and sent to museums in Chicago and elsewhere have turned out to contain, embedded in their carbonaceous matrix, a small but real sample of stardust from stars that finished burning before the Sun began.

The post In September 1969, a 100-kilogram space rock exploded in the sky above Murchison, Australia — and 50 years later, scientists analyzing dust grains buried inside the meteorite found particles between 5 and 7 billion years old, formed in the dying outer layers of stars that lived and died long before our Sun was born, in what remains the oldest solid material ever identified on the surface of the Earth appeared first on Space Daily.
  •  

By the end of this century, the United States is projected to have more than one million centenarians — people aged 100 or older — for the first time in human history, in a demographic shift driven by sharply falling mortality among nonagenarians, and some demographers now believe that a majority of children born today in low-mortality countries can reasonably expect to reach their hundredth birthday

In 1950, the United States Census Bureau estimated that approximately 2,300 Americans were aged 100 or older. The total population of the country at the time was approximately 152 million, which made centenarians one of the rarest possible demographic categories — approximately one in every 66,000 Americans had reached the age. By 1990, the centenarian count had risen to approximately 37,000. By 2020, it had reached approximately 92,000. By 2024, it had passed 101,000. The trajectory has been steep and accelerating, and the demographic shift now visible in the centenarian numbers is one of the larger long-term changes in the structure of the American population — a category that was statistically negligible at the end of World War II is now projected to become, within the lifetimes of most people reading this, a substantial demographic constituency in its own right.

According to the Pew Research Center’s January 2024 analysis of Census Bureau projections, the US centenarian population is projected to more than quadruple from approximately 101,000 in 2024 to approximately 422,000 by 2054 — meaning that within the next 30 years, the proportion of Americans aged 100 or older will rise from approximately 0.03 percent of the population to approximately 0.1 percent. This is the official Census base-case projection. Higher-end estimates developed by demographic researchers — including the MacArthur Foundation Research Network on an Aging Society — have projected substantially higher numbers under more optimistic mortality-improvement scenarios, with some estimates exceeding 1.8 million US centenarians by mid-century and substantially larger numbers by 2100. The range between the Census base case and the higher-end projections is large, and the actual outcome will depend on whether mortality improvements at older ages continue at recent rates, accelerate, or plateau.

What is driving the projected growth

The proximate driver of centenarian growth is not improving mortality among the young or middle-aged — those mortality rates are already very low and have only modest room to fall. The driver is sharply declining mortality among nonagenarians: people aged 90 to 99 who, in previous generations, would typically have died before reaching 100. The mortality rate among 90-year-olds has been falling steadily across developed countries for decades, with each successive cohort of nonagenarians surviving slightly longer than the previous one. The result is that the share of any given birth cohort that eventually reaches 100 has been rising, and the absolute number of centenarians is rising even faster because the population at risk (the 90-year-olds in the country) has also been growing rapidly.

Per a CEOWORLD analysis of the global centenarian surge, the same pattern is visible internationally. The United Nations estimated approximately 722,000 centenarians worldwide in 2024 and projects that the number will rise to approximately 4 million by 2054 — a nearly six-fold global increase in 30 years. By mid-century, the largest national centenarian populations are projected to be China (approximately 767,000), the United States (approximately 422,000), India, Japan, and Thailand, with several Southeast Asian countries and parts of southern Europe showing particularly rapid centenarian growth on a per-capita basis. Japan, currently the country with the world’s highest median age, is projected to have approximately 40 centenarians per 10,000 people by 2054 — meaning that roughly one in every 250 Japanese residents will be aged 100 or older. Thailand is projected to have an even higher ratio, at approximately 49 per 10,000.

The contested longer-term projections

The substantive disagreement among demographers is not about whether centenarian numbers will rise — that is now essentially settled — but about how far they will rise, and how soon a majority of births in low-mortality countries will produce people who eventually reach 100. The optimistic position, associated with the demographer James Vaupel and colleagues at the Max Planck Institute for Demographic Research, holds that life expectancy in the most advanced countries has been increasing by approximately three months per year for the past 150 years and shows no clear sign of slowing — and that this trajectory implies that the majority of children born in low-mortality countries today will live to see their hundredth birthday. The skeptical position, associated most prominently with the American demographer S. Jay Olshansky and his collaborators, holds that life expectancy gains are now slowing substantially in the United States and other developed countries, that the easy mortality reductions from infectious disease control, smoking declines, and cardiovascular medicine have largely been achieved, and that further gains will be substantially harder to obtain.

The empirical evidence for the slowdown position has become more visible in recent years. US life expectancy peaked at approximately 78.9 years in 2014 and then declined — partly because of the opioid crisis, partly because of rising obesity-related mortality, partly because of COVID-19 mortality during the pandemic, and partly because of slowing gains in cardiovascular medicine. The current US life expectancy of approximately 76 years is substantially below the trajectory that the Vaupel projections would have predicted. As covered by a foundational MacArthur Foundation Research Network paper on demographic forecasts for the United States in the 21st century, the higher-end centenarian projections depend on assuming that the recent slowdown is temporary and that the longer-run Vaupel-style trajectory will resume. Whether it does is one of the central empirical questions in contemporary demography, and the answer will substantially affect both the centenarian counts in 2054 and the much larger projections for 2100.

The maximum lifespan question

As reported by a 2021 Bayesian analysis published in Demographic Research by Michael Pearce and Adrian Raftery at the University of Washington, the related question of what the maximum human lifespan will reach by 2100 is approachable with statistical methods even where the underlying biology is uncertain. The Pearce-Raftery analysis modelled the existing distribution of supercentenarians (people aged 110 or older) and the projected growth of that population through the rest of the century, and estimated that there is greater than 99 percent probability that the current record human lifespan — Jeanne Calment of France, who died in 1997 at 122 years and 164 days — will be broken before 2100. They estimate an 89 percent probability that someone will reach age 126, a 44 percent probability that someone will reach 128, and a 13 percent probability that someone will reach 130. These projections are not predictions about the typical lifespan but about the extreme tail of the survival distribution, which depends on the same nonagenarian mortality declines that drive the centenarian numbers.

The deeper question that the centenarian projections raise is the relationship between living longer and living well. The available evidence on healthspan — the proportion of life spent in good health, rather than in disability or substantial decline — suggests that healthspan has been increasing more slowly than lifespan. The result is that the gap between the two has been widening: people are living longer, but with more years of substantial disability, more years of cognitive decline, and more years of dependence on caregivers and the healthcare system. The economic implications are substantial. The current pension systems, healthcare systems, and family structures of most developed countries were built around assumptions about average lifespan and the typical duration of post-retirement life that no longer hold. The institutional response, across most of the developed world, has been slower than the underlying demographic shift. Whether the eventual centenarians — including, possibly, a substantial fraction of the children born this year — will arrive at their hundredth birthdays in good health, in supported decline, or somewhere in between will depend on whether the gains of the coming decades are made primarily in extending lifespan or primarily in extending healthspan. The two trajectories produce very different futures.

The post By the end of this century, the United States is projected to have more than one million centenarians — people aged 100 or older — for the first time in human history, in a demographic shift driven by sharply falling mortality among nonagenarians, and some demographers now believe that a majority of children born today in low-mortality countries can reasonably expect to reach their hundredth birthday appeared first on Space Daily.
  •  

Thought of the day from Stoic philosopher Epictetus: “Some things are in our control and others not. Things in our control are opinion, pursuit, desire, aversion, and, in a word, whatever are our own actions. Things not in our control are body, property, reputation, command, and, in one word, whatever are not our own actions”

Imagine your flight is delayed three hours. Or someone leaves you a bad review that you think is unfair. Or a person you live with wakes up in a foul mood and you can feel it filling the kitchen.

The first reflex, at least mine, is to push back against the thing. To argue with the airline, draft the reply, try to fix the mood. To treat the situation as a problem I can solve if I just apply enough force.

I started reading Stoicism in earnest during a period of failure and a general search for meaning. Seneca’s line about how we waste time stayed with me as a durable impression from that whole reading rabbit-hole.

But the idea I keep coming back to, the one that has been most useful, is the one Epictetus opens his Enchiridion with:

“Some things are in our control and others not. Things in our control are opinion, pursuit, desire, aversion, and, in a word, whatever are our own actions. Things not in our control are body, property, reputation, command, and, in one word, whatever are not our own actions”. 

The handbook was compiled by his pupil Arrian from Epictetus’s teaching, but the thought is his, and modern readers tend to call it the dichotomy of control.

A note before I go further. I’m not a psychologist or a philosopher by training, just a reader who came to the Stoics during a rough stretch and kept reading. What follows is reflection on old ideas and a little modern research, not advice, and the psychology I mention is observational, drawn from particular groups of people rather than rules about you.

The easy misreading is to hear “big things versus small things,” as if Epictetus is telling you to sweat the little stuff and let the big stuff go. I don’t think that is the cut he’s making. The cut is between what is your own doing and what is not. Your judgments, your choices, your effort, your intentions sit on one side. Your body, your property, your reputation, your job title, the outcome of almost anything — all of that sits on the other.

The slightly uncomfortable part is how short the first list turns out to be once you’re strict about it. Almost everything I would naturally call “mine,” the result of my work, what people think of me, whether a plan succeeds, is not actually in my power. As the professor of philosophy, Massimo Pigliucci puts it, the idea “basically reminds us that our agency, our ability to change things, is far more limited than we normally think.” 

Years ago I tried to build a coffee business. It failed. And the part I didn’t understand until afterward was that the outcome was never really mine to control. Whether the business survived depended on the market, on timing, on a hundred things I couldn’t move no matter how hard I pushed. What was actually mine was the effort, the decisions, the work I put in each day. Those I could give fully.

The first time around I got this exactly backwards. I poured my anxiety into the outcome, the part I couldn’t touch, and the fear of failing followed me everywhere. When the thing I’d been dreading finally happened, the strange discovery was that the reality was lighter than the fear had been. Fearing it was worse than living it. I’m not romanticizing this, and I’m certainly not recommending failure as a teacher. But the dichotomy was sitting right there in the experience. The effort was mine. The result never was. Carrying the result as though it were mine just doubled the weight.

None of this is permission to stop caring or go limp. That’s the version of Stoicism that gets it wrong, the one that treats “let it go” as an excuse to do nothing. Epictetus is not saying don’t try. He’s saying try completely on the part that is yours, then release your grip on the part that isn’t. You act fully, then you stop demanding a particular result from the universe as the price of your peace.

So the freedom here is not the obvious kind. It isn’t getting more control over outcomes, more grip on the delayed flight or the bad review or the mood in the next room. It’s noticing, in the moment, which part of the thing is actually your own doing, giving that part everything, and setting down the rest.

These days, when a result I wanted slips away from me, I try to ask one plain question before I start fighting it: was this ever mine to decide? Often the answer is no. And there’s a real lightness in putting down a thing you were never holding up in the first place.

If any of this is landing closer to home than it is interesting, a good therapist or counsellor is worth far more than any old book or article, mine included.

The post Thought of the day from Stoic philosopher Epictetus: “Some things are in our control and others not. Things in our control are opinion, pursuit, desire, aversion, and, in a word, whatever are our own actions. Things not in our control are body, property, reputation, command, and, in one word, whatever are not our own actions” appeared first on Space Daily.

  •  

Quote by Neil deGrasse Tyson: “For me, I am driven by two main philosophies: know more today about the world than I knew yesterday and lessen the suffering of others. You’d be surprised how far that gets you.”

The self-help shelf in any bookshop is a monument to overcomplication. Forty-seven habits, twelve rules, seven levels, a morning routine that begins at half past four and involves cold water and a gratitude journal. I have read a depressing number of these, mostly in airports, and retained almost none of it past the departure gate.

Then Neil deGrasse Tyson, the astrophysicist, was asked on a Reddit thread in 2012 what drives him, and he gave an answer short enough to fit on the back of a receipt. Two philosophies, he said. Know more today about the world than you knew yesterday, and lessen the suffering of others. You would be surprised how far that gets you.

My first reaction was the one you are probably having. Lovely. Goes nicely on a mug. My second reaction, a few years later, was that the man had calmly described the only two things that have ever worked for me, and that the second one once stopped me making the stupidest decision of my career.

Know more today than you knew yesterday

The first one is the scientific method pointed at your own life, and it is far more modest than it sounds.

It does not ask you to be a genius, or to ever finish. It asks you to be slightly less wrong tonight than you were this morning. That is more or less the whole engine of science. Nobody in a serious lab is trying to be right in some final, permanent way. They are trying to be marginally less mistaken than the last person, write it down, and let someone else chip a bit further along.

The humility runs deeper than people outside science tend to assume, too. We have been studying gravity for three centuries and still only know Newton’s constant to three significant figures. Around ninety-five percent of the universe is made of things we have politely named dark matter and dark energy, mostly so we do not have to say out loud that we have very little idea what they are. The best-informed species on the only planet known to carry one spends most of its day confidently not knowing things.

I got this wrong for years in a particular way. I thought “know more” meant collect facts and deploy them to win. I was the man at the table with the correction loaded and ready. What I was doing was the precise opposite of the rule, because a person busy being right learns nothing. The truer version is duller and harder. Assume, every single day, that there is a fact you do not yet have. Above all about a person.

The cook I nearly sacked

That stops being abstract very quickly in a kitchen.

Years ago I had a line cook, a quiet lad called Tomas, who started arriving late. Ten minutes, then twenty, then a morning he missed altogether. In the economy of a busy kitchen that is close to a capital offence. The prep does not do itself, and one slow start poisons the entire service behind it. I had the conversation drafted in my head, the regretful, businesslike one that ends with a final pay packet. By the cold numbers, he had to go.

What stopped me was a flat, almost accidental question. I asked him, with no great warmth, what was actually going on. And it came out that his mother had been taken into a hospital on the far side of the city, that he was sitting with her until the small hours, and then walking ninety minutes to my door because the night buses did not connect and the fare, on a cook’s wages, was a genuine decision every morning.

None of that was visible from where I stood, which was the whole point. I had a full and confident model of Tomas, the unreliable cook, and it was missing the single fact that explained all of it. I knew less than I believed I did, which is the standard human condition and the exact thing the first rule is trying to beat out of you.

So I did something small. I shifted his start to the evening, which suited the kitchen anyway, and stopped docking him for the lost mornings. It cost me close to nothing. He stayed four years, became the steadiest pair of hands in the building, and covered for me more times than I can count when my own life later fell apart. You would be surprised, as the man said, how far that got me.

Lessen the suffering of others

People hear the second philosophy as the soft one. The charity bit, bolted on after the clever bit, to make the clever bit look kind. I think that is exactly the wrong way round.

They are the same engine. Knowing more about Tomas was worthless as trivia. Its only value was that it let me take a little weight off him at almost no cost to me. And easing what he carried was not me playing the saint. It was the most clear-headed thing I did that year, because it kept a good cook and bought a loyalty that no bonus on earth would have. Knowledge without the second philosophy is just cleverness, which is cold and gets you avoided at parties. Kindness without the first is good intentions fired blindfold, which mostly miss the target. You need the two of them aimed together.

That is what Tyson tucks into that last offhand line. He does not promise you enlightenment, or wealth, or a flat stomach by June. He promises only that two ordinary habits will carry you “surprisingly far,” which may be the single most honest sentence in the entire self-improvement trade. Nobody can tell you how far. You would be surprised. That is the whole claim, and it happens to be true.

I walked away from the restaurants a few years after Tomas, and I have since forgotten most of what I once knew about margins and stock rotation and the correct way to close down a kitchen at midnight. What stayed was the picture of a tired young man crossing a sleeping city on foot to stand at my stove, and the small, unheroic discovery that the cheapest thing I ever did, ask one question and move one shift, turned out to be the cleverest entry in the books. Two rules, typed into a website by a stargazer at his keyboard. They really will carry a person an absurd distance, though their author had the good manners not to say how far. He left you to walk it and find out.

The post Quote by Neil deGrasse Tyson: “For me, I am driven by two main philosophies: know more today about the world than I knew yesterday and lessen the suffering of others. You’d be surprised how far that gets you.” appeared first on Space Daily.
  •  

In 2026, wellbeing researchers suggested that simply asking people one question about how good their life is overall may be the clearest and most comparable way to measure wellbeing around the world

Can one question really tell you how a whole life is going? It sounds too simple. A life has work in it, and health, and the people you love, and the quiet sense of whether any of it means anything. Reducing all of that to a single number on a scale feels like measuring an ocean with a teaspoon.

And yet that is more or less what a group of wellbeing researchers argued in earlier this year. In a short reply published in Nature Human Behaviour, the editors of the World Happiness Report made the case that individual wellbeing is best captured “by single self-reports of one’s overall quality of life.” One question, asked directly. That’s the whole proposal.

A quick note before going further. I am not a psychologist, an economist, or a wellbeing researcher of any kind, so take what follows as one curious reader’s reading of a scholarly debate, not advice. The work here is observational social science, and a population-level pattern is never a verdict on how your own life is going.

The case for measuring everything

The argument the 2026 reply is pushing back against has obvious appeal. In 2025, Harvard’s Tyler J. VanderWeele and Baylor’s Byron R. Johnson published early results from the Global Flourishing Study, a survey of more than 200,000 people across 22 countries. Rather than asking one question, they built a composite index across five domains: happiness and life satisfaction, physical and mental health, meaning and purpose, character and virtue, and close social relationships.

You can see why. A person could be financially comfortable and lonely, or healthy and adrift. Stitch the domains together and you get a fuller picture. VanderWeele draws a distinction here between two ideas, and he is careful to hedge it. Wellbeing, he suggests, “might be viewed as all aspects of a person’s life are good as they pertain to that individual, whereas flourishing is all aspects of a person’s life are good, including the context and communities and environments in which that person lives.”

The composite view runs into a problem, though, and I have felt it personally. Ticking the boxes does not reliably move the overall sense of how life is going. 

What the single-item camp actually argues

So the counter-argument is not “wellbeing is simple.” It is closer to this: most of what gets bundled into a flourishing index is not wellbeing, it is the stuff that produces wellbeing. The 2026 authors put it carefully, with the hedge intact. In their view, “most of the individual factors that get combined in such an index are causes of wellbeing and not wellbeing itself.”

Health, money, relationships: on this reading, those are inputs. Ask about them and you are measuring the recipe, not the meal. Ask a person to rate their overall life, and the editors argue, “the resulting product is wellbeing, in other words, the quality of life as we experience it.” The person has already done the weighting in their head. They know how much the lonely-but-comfortable trade actually costs them, in a way no fixed formula across 200,000 strangers can.

This is not a fringe idea dreamed up to win an argument. It is how the global rankings already work. The World Happiness Report’s country ordering rests on a single life evaluation question, the Cantril ladder, which asks people to place their life on a 0 to 10 ladder. Gallup asks it of people in more than 140 countries.

Here is that question: 

“Please imagine a ladder with steps numbered from 0 at the bottom to 10 at the top. The top of the ladder represents the best possible life for you and the bottom of the ladder represents the worst possible life for you. On which step of the ladder would you say you personally feel you stand at this time?”

Closing thoughts

The single question dares to remove almost everything and trust the person to have done the math. There is something honest in that, and something that could go wrong.

But a tidy number can flatter or deceive. A bad week can drag it down; a sunny afternoon can lift it past what you’d say on reflection.

One ordinary evening I tried it on myself. Zero to ten, how good is your life, overall. I landed on a number quickly, which surprised me, and then immediately distrusted it, which surprised me less. The honest answer wasn’t the number. It was the half-minute of weighing that produced it, the things I added in and the things I quietly let go. The number was just where the weighing stopped. Maybe that is the whole point, and maybe it is the catch: the single question doesn’t simplify the life, it just forces you to do the arithmetic.

If any of this is landing closer to home than it is interesting, talking to a good therapist is worth far more than reading this article.

The post In 2026, wellbeing researchers suggested that simply asking people one question about how good their life is overall may be the clearest and most comparable way to measure wellbeing around the world appeared first on Space Daily.
  •  

Thought of the day from Taoist philosopher Lao Tzu: “To understand others is to have knowledge; to understand oneself is to be illumined.”

The line turns on a single word, and the word is doing more work than it first appears. To understand others is knowledge, something gathered and held. To understand oneself is something else, a state the original Chinese marks with the character ming (明). As Sandra Hill writes for Monkey Press, the character “can be translated as brightness, clarity, illumination, enlightenment.” It is built, fittingly, from the characters for sun (日) and moon (月). Knowledge of others is an accumulation. Self-knowledge, in this reading, is a light.

That distinction is the whole of the verse. Why has it survived twenty-five centuries, and does the gap it names between knowing others and knowing oneself hold up when modern researchers go looking for it?

The verse comes from Chapter 33 of the Tao Te Ching, the principal Taoist text traditionally attributed to Lao Tzu, the “Old Master” usually placed in the sixth century BC. Modern scholarship tends to treat the figure as semi-legendary and the authorship as uncertain, but the text itself, eighty-one chapters, has outlasted every argument about who wrote it.

Part of why the line travels so well is that it survives translation with its core intact. The Chinese reads 知人者智,自知者明. In the Gia-fu Feng and Jane English rendering, it becomes “Knowing others is wisdom; Knowing the self is enlightenment.”

Dwight Goddard, working in 1919, put it as “He who knows others is intelligent; he who understands himself is enlightened.” Stephen Mitchell’s 1995 version, a loose interpretive rendering rather than a literal translation, reads “Knowing others is intelligence; knowing yourself is true wisdom.” The vocabulary shifts across translations, but the underlying structure does not. Every version keeps the same two-part contrast: one kind of knowing pointed outward, a different kind pointed in.

Before going further, a note on register. We are writers reading across philosophy and psychology, not clinicians or credentialed researchers, and the studies below describe patterns across groups of people rather than verdicts about any individual reader.

The psychologist Tasha Eurich has spent years probing the kind of gap Lao Tzu names. In her account on the Blanchard LeaderChat podcast, “Our data reveals that 95 percent of people believe they are self-aware, but the real number is 12 to 15 percent.” Those figures come from her own studies rather than a settled cross-field consensus, so they are best read as one researcher’s finding, not a fixed law. The direction is the interesting part: most people are confident they see themselves clearly, and far fewer actually do.

There is an obvious objection to Lao Tzu’s hierarchy. Surely we have privileged access to our own minds. We can hear our own thoughts; we cannot hear anyone else’s. Shouldn’t self-knowledge be the easy half?

Well, some research suggests the privilege backfires. Psychologist Emily Pronin and Matthew Kugler studied what they call the introspection illusion. When assessing their own bias, participants weighed their introspective sense over the evidence of what they actually did, a generosity they did not extend to others. 

That is perhaps the obstacle the verse quietly implies. Knowing others, you have only their actions to go on, and actions are honest in a way intentions often are not. Knowing yourself, you have access to the running commentary, the reasons, the good intentions, and that flood of inside information is exactly what makes the view unreliable.

If any of this lands close to home, a qualified counsellor or therapist is a good person to talk it through with.

The post Thought of the day from Taoist philosopher Lao Tzu: “To understand others is to have knowledge; to understand oneself is to be illumined.” appeared first on Space Daily.
  •  

Over ten workdays, researchers sent employees on 15-minute lunchtime walks through a park, and afternoons changed — sharper concentration, less fatigue, with much of the lift carried by how genuinely people enjoyed the walk.

Most lunch breaks are not really breaks. A sandwich at the desk, the screen never quite off, an eye on the next message. The afternoon arrives already flat, and you spend it pushing a boulder that did not feel this heavy at ten in the morning. I suspect a lot of us know that particular afternoon flatness without ever connecting it to how we spent the forty minutes before it.

A small Finnish study made me think about that connection more carefully.

I am not a psychologist or any kind of clinician, so take this as one curious reader’s reading of one piece of research, not advice about what your body or your workday should do. What follows is a single intervention study with a modest number of people, and the findings are from a particular group, not settled laws about everyone.

What the study actually did

Organizational psychologist Marjaana Sianoja and colleagues asked Finnish knowledge workers to do something simple during their lunch breaks. One group took a slow 15-minute park walk; a comparison group did 15 minutes of relaxation exercises. They kept it up for 10 consecutive working days, and reported on their afternoon concentration, strain, and fatigue along the way. The park walk group had 51 people, the relaxation group 46.

The headline finding is the kind you might expect. The authors reported that “park walks at lunchtime were related to better concentration and less fatigue in the afternoon through enjoyment.” Fifteen minutes among trees, and the afternoon went a little better.

The part that surprised me

The interesting word in that finding is the last one. Through enjoyment.

That reorders things in my head. We tend to treat the activity as the active ingredient, as if a walk is a pill you swallow whether or not you taste it. The study suggests the enjoyment is doing a lot of the quiet work, and the walk is mostly a reliable way to produce some.

A separate line of research points the same direction. In an experience-sampling study, John Trougakos and colleagues found that the restorative value of a lunch break depends heavily on how freely it was chosen.

Why the distinction matters to me

This is where it stops being abstract. My weekday afternoons run from two different cafés, with a walk between blocks. When a sub-task is done, I pack up and move to the second café, and the walk in between is the seam. I did not start doing this for any measured productivity reason. I do it because moving lets the last task drain out of my head before the next one starts, and switching the room seems to switch something in me too.

What I notice is that I look forward to that walk. It is not a chore I have inserted to be virtuous. If someone scheduled it for me, made it mandatory, told me to log it, I think it would quietly stop working. The mechanism in the study and the reason my own version holds up seem to be the same one: the walk is the vehicle, the wanting-to-do-it is the engine.

The honest limits, and what I take from it

It is worth keeping the size of all this in proportion. Research from the same program found that lunch break activities did increase restoration and reduce fatigue, but the authors were candid that the effects seem weak, short-lived, and dependent on the season. Fifteen minutes in a park is probably not going to fix a job that grinds you down, and it was never going to.

What I take from it is smaller and more usable than a fix. Protect the break, and make it one you genuinely want. For me the strongest version of this has nothing to do with work at all: when I am home in Ireland, I walk alone with no music or podcast, and it is the closest thing I have to a practice. I tried meditation and it never stuck. The quiet walk, and solo golf, are my equivalent, and I think the reason they last is the same reason the study points at. I am not enduring them. I like them.

A break taken and a break enjoyed are not the same break. You can do all fifteen minutes, hit every step, and come back no lighter than you left. The walk gets the credit, but perhaps the enjoyment is what is actually carrying the load.

If  flat afternoons are part of something heavier than a dull lunch break, the kind of fatigue that does not lift, a good counsellor or therapist is worth more than any walk or any artic

The post Over ten workdays, researchers sent employees on 15-minute lunchtime walks through a park, and afternoons changed — sharper concentration, less fatigue, with much of the lift carried by how genuinely people enjoyed the walk. appeared first on Space Daily.
  •  

In 1974, psychologists found men were more likely to mistake fear for attraction after crossing a high, swaying suspension bridge

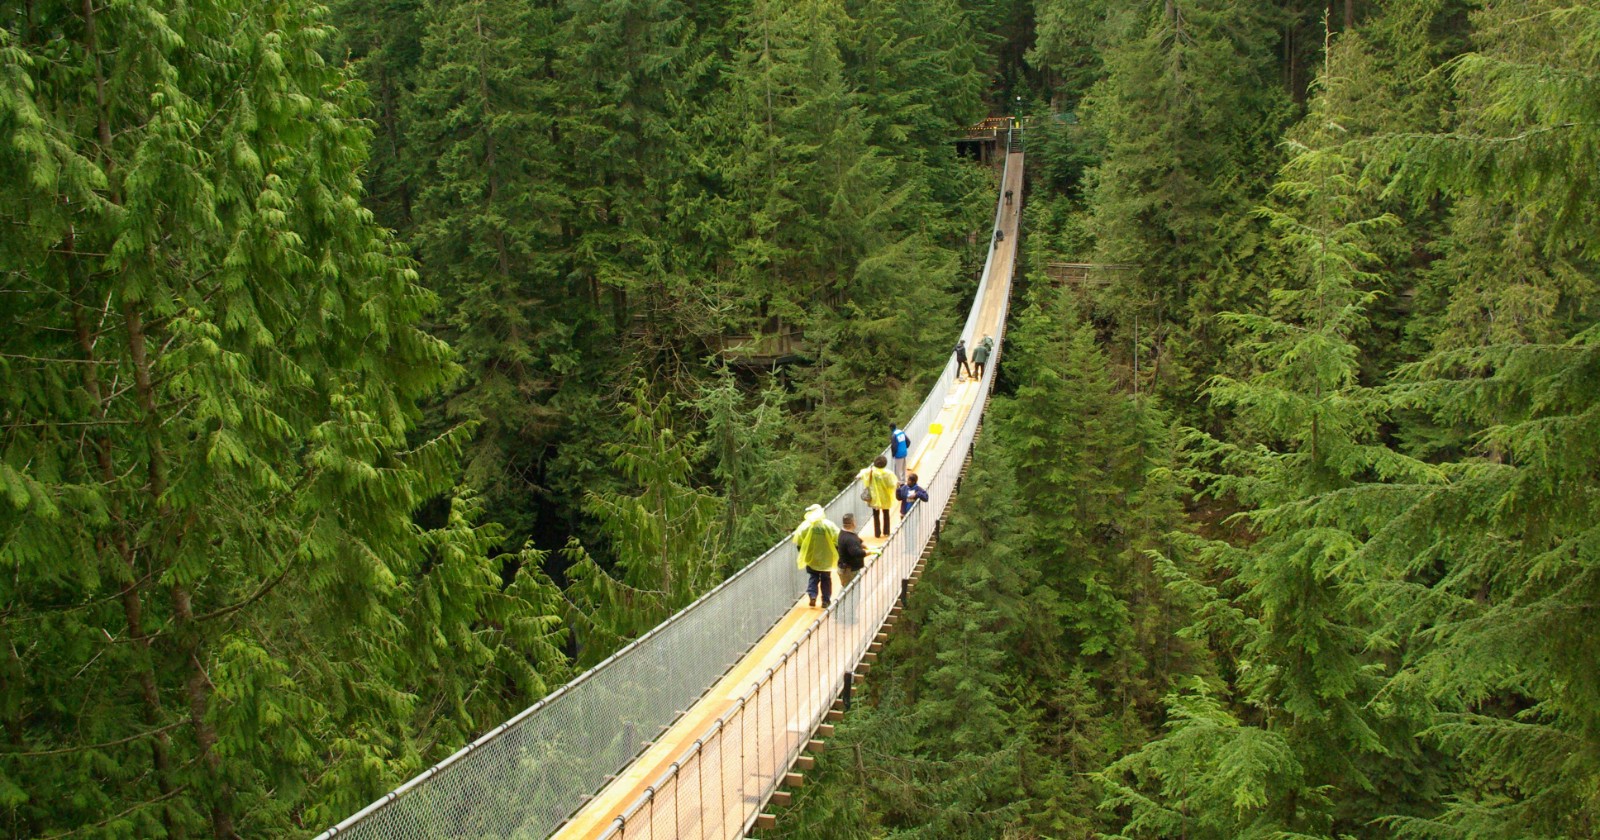
A long wood-and-cable suspension bridge stretching across a forested canyon, with small figures crossing it.

In 1974 two psychologists sent an attractive young woman to stand at the end of a bridge and stop men walking across. She asked each one to fill out a short questionnaire, then tore the corner off a sheet of paper, wrote down her name and phone number, and said he could call if he wanted to talk more about the study. The only thing that changed was which bridge the men had just crossed.

On a high, swaying footbridge, nine of the eighteen men who took her number later called. On a low, solid bridge nearby, only two of sixteen did. The men who had just been frightened were far more likely to phone a stranger, and Donald Dutton and Arthur Aron argued the reason was that they had felt their hearts pounding and read it, wrongly, as attraction.

Two bridges over the same river

The study ran over the Capilano River in North Vancouver, British Columbia. The frightening bridge was the Capilano Canyon Suspension Bridge, a five-foot-wide walkway of wooden boards strung from wire cables and stretched 450 feet across the canyon. It tilted and wobbled underfoot, its handrails were low cable, and it hung about 230 feet above rocks and shallow rapids. Roughly four in ten people crossing it gripped the rail and inched along.

The calm bridge sat upriver: a heavy cedar structure, wider and firmer, only about ten feet above a small stream, with high handrails and no sway. When the researchers later asked a separate group of men how frightened they felt crossing each one, the suspension-bridge group rated their own fear at 65 on a 100-point scale. The men on the solid bridge rated theirs at 3.

So the two groups began in very different physical states. One had a body still humming with adrenaline. The other did not. Everything that came after was designed to see whether that difference leaked into how the men responded to a woman.

What the interviewer measured

The interviewer told the men she was studying how scenery affects creativity, then asked each to write a short, dramatic story about an ambiguous picture of a woman. The stories were scored from one to five for sexual content by raters who did not know which bridge each man had been on. Men from the suspension bridge wrote stories with noticeably more sexual imagery, averaging 2.47 against 1.41 for the solid bridge.

The phone number was the second, blunter measure. The researchers reasoned that curiosity about the study should be about equal across both groups, so a difference in who actually called back would reflect a difference in interest in the woman herself. That is where the gap was widest: half the men from the suspension bridge called, against roughly one in eight from the solid bridge.

One detail mattered to the interpretation. When a male interviewer ran the same routine, the effect vanished. Men leaving the scary bridge wrote no racier stories and were no more likely to call him back. The arousal only seemed to redirect toward someone the men might plausibly be attracted to.

The check the authors built for themselves

A skeptic could object that the two bridges drew different kinds of people. The suspension bridge is a tourist attraction, so its visitors might be bolder, more out-of-town, or simply in a different mood than someone strolling a quiet park. Dutton and Aron raised that objection themselves, and ran a second version to answer it.

This time they kept only suspension-bridge visitors, comparing men stopped right after crossing with men from the same crowd approached at least ten minutes later, once their nerves had settled. The freshly rattled men again wrote more sexual stories and called more often: thirteen of twenty, against seven of twenty-three for those who had cooled down.

A third study moved indoors, where the researchers could control more. Eighty male university students were told they would receive an electric shock, some led to expect a strong jolt and some a mild one. A woman they believed was another participant sat nearby. Men braced for the painful shock reported more attraction to her and again produced more sexual imagery. Crucially, the boost came from anticipating their own shock, not from worrying about hers, which argued against the idea that they were simply moved by a woman in distress.

How much can two bridges really tell us?

The studies are vivid, but they are small and old, and the famous bridge experiment carries the usual hazards of research done in the wild. The groups were not randomly assigned; they sorted themselves by which bridge they chose to cross. The phone-call measure rested on a few dozen men, the kind of sample where a handful of decisions swings the result. And the whole design worked in one narrow direction only: a female interviewer and unaccompanied young men. It says nothing about anyone outside that setup.

The interpretation is also more contested than the tidy version suggests. Dutton and Aron leaned on the idea, drawn from earlier work by Stanley Schachter, that the body produces a wash of generic arousal and the mind looks around for a label to pin on it. On a swaying bridge, the nearest available label is the woman. But the authors themselves listed other readings of their data. Perhaps fear did not get relabeled as desire so much as loosen the brakes on feelings that were already there. Perhaps the link between fear and attraction is its own phenomenon rather than a special case of some grand rule about arousal. They could not rule those out, and which of those mechanisms is at work, if any, is not something a single field study could settle.

What survives is narrower than the headline but still striking: under the right conditions, a body stirred up by one cause can color a judgment about something else entirely. The bridge did not manufacture attraction out of nothing. It seems to have nudged men who were already inclined to notice a woman into noticing her a little more, and into reading their own pounding hearts as a reason.

That is the quiet, unsettling part of the finding. We tend to trust the feeling in our chest as a verdict about whoever is standing in front of us. Sometimes it is only a verdict about how high up we are.

The post In 1974, psychologists found men were more likely to mistake fear for attraction after crossing a high, swaying suspension bridge appeared first on Space Daily.
  •  

People who assembled a plain IKEA box would pay 63 percent more for it than people handed the same box already built, an overvaluation of their own labor that researchers named the IKEA effect

In a 2012 study, researchers handed some people a plain black storage box still in its flat-pack and let others inspect the same box already assembled. Then they asked everyone to name a price they would actually pay to keep it. The people who had built the box themselves bid an average of 78 cents. The people handed the finished box bid 48 cents. Same box, same parts, but the builders wanted it 63 percent more.

Michael Norton, Daniel Mochon and Dan Ariely called this the IKEA effect, after the Swedish furniture company whose products famously arrive with some assembly required. The short version of their finding is that labor leads to love: when people put their own effort into making something, they value the result more highly than anyone else does, sometimes absurdly so.

The origami people valued like a pro’s

The boxes showed the effect existed. A second experiment showed how large it could get. This time people folded an origami frog or crane from a single sheet of paper, with only an instruction diagram to guide them. Afterward they bid on their own creation, while a separate group of bystanders bid on those same paper frogs and cranes.

The builders valued their origami at about 23 cents. The bystanders, looking at the same lopsided results, would pay about 5 cents, treating them as close to worthless crumpled paper. The makers priced their work nearly five times higher than the market did.

The stranger comparison came next. The researchers had experienced origami folders make clean, well-crafted versions, and asked another group to bid on those. Outsiders valued the expert work at about 27 cents. The amateurs valued their own fumbling attempts at 23 cents. In their own eyes, in other words, their handiwork was worth almost as much as a professional’s, a gap so small it was not statistically meaningful.

To check that the builders were not simply overbidding to avoid losing something they had made, the researchers asked another set of folders to guess what the average student would pay for their creation. Those guesses came back about as high as their own bids. The makers did not just want to keep their origami. They genuinely seemed to believe other people would see the value too.

Effort only counts when the work is finished

If sheer effort were the whole story, then any labor should raise the price. The researchers found it did not. What mattered was completing the task.

In one experiment people built small Lego models, around a dozen pieces shaped like a helicopter, a bird, a dog or a duck. As expected, builders valued their own model more than an identical one built by a partner, bidding about twice as much for it. But a third group built a model and then took it apart again. For them the premium collapsed. Undoing the work erased the love, even though Lego is designed to be rebuilt in minutes and they could have reassembled it easily.

A final experiment made the same point from the other side. Some people assembled an IKEA box completely, while others were stopped two steps short of finishing. The finishers bid $1.46 for their box. Those left with an almost-complete box, all the pieces in hand, bid 59 cents, less than half as much. The boost came from crossing the finish line, not from the minutes of effort alone. And it held whether or not people described themselves as the do-it-yourself type.

Why a wobbly box feels more valuable

The researchers tested a few obvious explanations and set them aside. The premium was not simply about owning the thing, since the people who built and then dismantled a Lego model had handled and possessed it just as long as the builders, yet valued it less. It was not about customization either, because a standard IKEA box offers nothing to personalize.

What is left, they argued, is a mix of two older ideas. One is effort justification, the long-studied tendency to value what we have sweated over. The other is a sense of competence: finishing a task, even a trivial one, gives a small jolt of having shaped the world, and the finished object becomes proof of it. A crooked origami frog is not really worth 23 cents. But it is evidence that you made something, and that evidence feels valuable.

The authors trace the same instinct outside the lab. They open with the story of 1950s instant cake mixes, which reportedly sold poorly until manufacturers required cooks to add a fresh egg, restoring a little real labor to the box. They note the story probably had several causes, not one. But it rhymes with their results, as do the businesses that charge people to stuff their own teddy bears or harvest their own dinner on a farm.

What four small studies can and cannot show

The IKEA effect is real in these experiments, but it is worth being precise about their size. These were lab studies with modest numbers of mostly student participants, and the stakes were tiny. The products were boxes, paper frogs and Lego sets, and the prices ranged from a few cents to under two dollars. The researchers measured willingness to pay through bidding games, which approximate real purchasing but are not the same as walking into a store.

The authors are careful about reach. They flag that they used small-ticket items and that whether the effect holds for expensive purchases, a renovated kitchen or a self-built deck, was not something their data could answer. They suggest it might, pointing to homeowners who price their handmade brick walkway far above what any buyer will pay for it, but that is a reasonable guess, not a result.

The mechanism, too, is an argument rather than a settled fact. Effort justification and a feeling of competence fit the pattern, and the researchers ruled out a couple of rivals, but they say plainly that more work is needed to know exactly why building something makes us prize it. What the studies pin down is the pattern itself, and its limit: the glow comes only when the work succeeds. Effort that ends in a half-built box or a model torn back to pieces buys nothing.

That limit may be the most human part. We do not fall for our labor simply because it cost us something. We fall for it when it produces a thing we can hold up and call finished, however lopsided it turns out to be.

The post People who assembled a plain IKEA box would pay 63 percent more for it than people handed the same box already built, an overvaluation of their own labor that researchers named the IKEA effect appeared first on Space Daily.
  •  

We tend to blame burnout on simply doing too much, but some researchers argue it grows from six quieter mismatches — workload, control, reward, community, fairness and values — between a person and the job

For years I believed burnout was a simple equation. Too many hours in, not enough rest out, and eventually you hit the wall. It is a tidy theory, and in my experience mostly wrong.

The worst stretch I have ever had was not in finance. It came later, when I was running my own businesses, an online school. I felt hollowed out and a bit hopeless. I want to be honest about that: I was never formally diagnosed with anything, so I am not claiming a clinical label. But the feeling was real, and it did not track neatly with how busy I was. Some of my busiest weeks felt fine, while some of my lighter ones were unbearable.

Quick note before we go further. I am not a psychologist or a doctor, and nothing here is treatment advice. This is one writer reading the research and reflecting on it. The work I am leaning on is from a particular research team and describes patterns across groups of people, not a rule that fits every reader or every job.

Research helped me make sense of my own experience. Psychologists Christina Maslach and Michael Leiter argue that burnout has as much to do with job conditions as with personal factors, and that when there is a mismatch between a person and their job, the risk of burnout goes up. Their framework, sometimes called the areas of worklife model, points to six areas where fit can break down: workload, control, reward, community, fairness and values.

Here is what each one looks like up close.

1. Workload

This is the one we all reach for first, and it does matter. But the problem is rarely volume on its own. It is overload without recovery, or the wrong kind of demand arriving with too few resources to meet it.

Maslach and Leiter describe work overload as when “the job demands are too many, the hours are too long, and the resources to handle them are too few.”

Notice the third part. Two hard weeks with a good team and a clear finish line can feel energising, while two easy weeks with no support and no end in sight can flatten you.

2. Control

Having work to do is one thing; having no real say over how it gets done is another, and it may be the heavier load. Maslach and Leiter suggest a lack of control “is often a more serious issue for workers than workload per se.”

Their case for why is simple. “With the capacity to participate in decisions or to make choices, people can adjust” — without that capacity, even a reasonable workload starts to grind.

3. Reward

Reward is money, yes, but it is also recognition, the sense that the effort registered with someone. When you pour yourself into work and it disappears into a void, something quietly corrodes.

When I managed an adult language school, I learned you cannot manufacture engagement with perks or pep talks. The pizza Fridays and the motivational emails landed flat when the underlying work and the person did not fit.

Engagement showed up when people felt their effort actually counted for something, and no amount of catering could fake that.

4. Community

Work is a social place, and when the social fabric frays, it shows. Chronic conflict, isolation, a manager who plays favorites, a team that has stopped trusting each other.

Maslach and Leiter are blunt about one corrosive ingredient, writing that “Disrespectful behavior has no benefits at work.” A good community carries you through a brutal stretch; a poisoned one makes an easy job feel heavy.

5. Fairness

Fairness is the area people often cannot name but feel acutely. Decisions get made behind closed doors, or promotions follow politics rather than work, or two people end up held to different standards on the same behaviour.

The sting is not so much the unfair outcome itself as what it signals about whether you are seen and valued at all. Once you start reading the workplace as rigged, almost everything else gets harder to swallow.

6. Values

This is the gap between what you believe matters and what the job actually asks of you, day after day. It is the quietest of the six and, for me, the decisive one.

I left finance because the shape of the job was the problem, not the hours. No amount of yoga, kale or ten thousand daily steps was going to change that shape.

That was right for me and might well be a bad call for someone else. Plenty of people thrive in exactly the work I walked away from. The values mismatch is personal by definition, about the fit between this person and this job, not a verdict on the job itself.

Burnout as a fit problem

What changed for me was the reframe. Maslach and Leiter describe burnout not as a personal failing or a stamina deficit, but as a mismatch between the job and the person. And the mismatches stack. As Maslach put it in a 2018 talk, “The more the mismatches you have, the more likely we are to see a risk of burnout down the road, a year later, or two years later.”

Keep in mind that this is one influential model rather than the final word on burnout, but it is a useful lens.

The practical value of the six areas is that they give you something more precise to ask than “am I doing too much?” You can ask which one is actually off. Is it the workload, or is it that nobody noticed the workload? Is it the hours, or is it that the hours go toward something you no longer believe in? Naming the specific mismatch is more useful than the blanket prescription to do less, because doing less solves nothing for a values gap or a fairness problem.

If any of this is landing closer to home than it is interesting, talking to a qualified therapist or counsellor is worth far more than any article. There is no prize for white-knuckling through it alone.

The post We tend to blame burnout on simply doing too much, but some researchers argue it grows from six quieter mismatches — workload, control, reward, community, fairness and values — between a person and the job appeared first on Space Daily.
  •  

We keep asking whether humans can survive on Mars and skipping the more important question of whether we should go at all

A few months ago, I found myself deep in a conversation about Mars colonization timelines. The other person — a software engineer, genuinely enthusiastic, not naive about the engineering — was walking me through radiation shielding approaches, the habitability of lava tubes, the logistical case for SpaceX’s Starship architecture. It was fascinating. He clearly knew far more than I did about the technical specifics. But somewhere in the middle of it, a question started forming that I couldn’t quite place, until eventually I did: we hadn’t once asked whether any of this was a good idea.

We had been talking about how for an hour, and neither of us had said the word why.

That conversation has been sitting with me since. Not because the technical questions aren’t important — they’re genuinely hard, and the people working on them are doing serious work. But there is a gap between “this is technically possible” and “this is what we should do,” and that gap tends to close faster in the Mars discourse than it does almost anywhere else. The survival problem gets all the oxygen. The ethical one gets treated as settled — as if the answer to “should we go?” is obviously yes, and the only thing left to figure out is the radiation shielding.

I’m not a space scientist and I don’t have a strong stake in any particular answer here. What I do have is a persistent discomfort with how questions get framed — with the way the tractable problem has a tendency to absorb all the attention that the harder one deserves.

The question we’re not asking

The survival discourse is, in its way, extraordinary. Cosmic radiation at the Martian surface running at roughly six to seven chest X-rays per day under normal conditions — and significantly higher during transit and solar storm events. An atmosphere that amounts to about one percent of Earth’s. Temperatures swinging 70 degrees Celsius or more between day and night. The progressive bone density loss from low gravity that compounds across months into something that isn’t easily reversed. These are real problems, and the engineers working on them deserve the coverage they get. None of that is what I’m questioning.

What I’m questioning is the habit of treating “can we survive there?” as a proxy for “should we go?” — as though answering the first settles the second. It doesn’t. They are different questions that require different kinds of thinking, and we have, for the better part of a decade, let the excitement and tractability of the first crowd out serious engagement with the second.

The life question nobody wants to stop for

One of the more uncomfortable things I’ve come across in reading about this is the planetary protection question — specifically, the possibility that Mars might not be as empty as the colonization narrative tends to assume. The debate about whether Mars currently harbors microbial life, perhaps in briny subsurface water or in the recurring slope lineae that have been periodically interpreted as evidence of seasonal liquid water, remains genuinely open. No confirmed biology has been found. But “not yet confirmed” is not “not there,” and the question of what we would do if we found it — before or after we arrived — seems to get less serious treatment than it warrants.

NASA’s planetary protection guidelines exist precisely because this uncertainty is real. They were built around the concern that Earth microbes carried on spacecraft could contaminate Mars and compromise any future ability to find or study native life there — or vice versa. The protocols apply most strictly to robotic missions, which can be sterilized. They apply far less cleanly to humans, who exhale, shed skin cells, and carry an internal ecosystem of trillions of organisms that are not optional passengers. A crewed mission, by design, cannot be managed the same way a probe can.

What this means, if taken seriously, is that any crewed mission to Mars before we have higher confidence about the biological status of the planet carries a non-trivial risk of introducing an extinction event for whatever might be living there. Carl Sagan, who spent his career both advocating for space exploration and urging caution about it, made this point repeatedly — that introducing Earth organisms into a low-diversity Martian ecosystem, if one exists, could eliminate it entirely before we ever knew it was there. The argument has not aged out. If anything, growing scientific interest in Martian subsurface habitability has made it more pressing, not less.

We have spent years asking whether humans can survive on Mars. We have spent much less time asking what Mars might be surviving from, if we arrived.

The backup civilization argument and its hidden premises

The most common justification offered for Mars colonization at the level of civilizational stakes is the backup argument: a multi-planetary species is an insurance policy, and the cost of not going is existential risk to the entire human project. Stephen Hawking made this argument in his final years. Elon Musk has built it into the explicit ideological foundation of SpaceX’s long-term mission — a self-sustaining city on Mars as a hedge against collapse on Earth.

I find this argument more worth taking seriously than most critics give it credit for. The underlying concern about existential risk is real. The logic that a species concentrated on one planet is more vulnerable than one distributed across two is coherent. But the argument is doing more work than it usually admits, and some of its hidden premises deserve more scrutiny.

The most obvious one is timing. The existential threats most likely to end civilization on Earth in the foreseeable future — climate change, engineered pandemics, nuclear conflict, biodiversity collapse — are immediate relative to any realistic projection of a self-sustaining Martian colony. A genuinely self-sustaining Mars city, by most serious estimates, is generations away. The threats we are failing to address are not. If the backup civilization argument is meant to be taken literally as a response to existential risk, it would seem to require securing the primary civilization first — not as an alternative to Mars ambitions, but the sequencing matters considerably more than the discourse tends to acknowledge.

The governance question matters here too. The Mars colonization effort as it currently stands is being driven largely by the decisions of a very small number of extraordinarily wealthy individuals and their companies, operating mostly outside democratic institutions, international treaty frameworks, or any serious mechanism of public deliberation. The Outer Space Treaty of 1967 prohibits national sovereignty claims over celestial bodies, but it was not designed to address private colonization by corporations operating under whatever regulatory minimums they can find. The choices being made now — when to go, at what pace, under what protocols — will shape the terms of Mars activity for a very long time. The fact that those choices are being made by a small group of people with specific and concentrated interests seems like something a more serious public conversation would address.

What an honest accounting would require

I want to resist the easy conclusion here — the “we should never go” position that treats any Mars ambition as inherently reckless or hubristic. There are real arguments for human Mars exploration. The science alone — the geology of ancient riverbeds, the evidence of a once-warmer world, the complex chemistry of the regolith — has produced discoveries with no parallel in the history of planetary science, and there are legitimate cases that humans on the surface could accelerate that science in ways robots fundamentally cannot. I find the impulse to go, the sheer ambition of it, genuinely compelling on some level I can’t entirely defend rationally.

But I think we owe it to the question — and possibly to whatever might be living on that planet — to stop treating the survival problem as a substitute for the ethical one. An honest accounting would start with the life question: invest seriously in determining whether Mars is biologically empty before a crewed mission departs, and treat a positive finding as a real constraint on what comes next rather than a footnote to manage. It would include meaningful international deliberation about who gets to make these decisions, and why the current answer to that question is “the people with the most rockets.” It would take the backup civilization argument seriously enough to notice what it actually implies about sequencing and urgency on Earth.

The conversation I had a few months ago was a good one. The engineer was genuinely thoughtful, and I learned things I didn’t know. But I’ve been bothered, in the time since, by how naturally we both moved through the technical questions and how completely we both skipped the other kind. The “can we?” problem is captivating in a way the “should we?” problem never quite is. It has cleaner edges. It has milestones. It announces itself as progress.

The harder question doesn’t do any of that. It just sits there, waiting for the conversation to slow down enough to make room for it.

The post We keep asking whether humans can survive on Mars and skipping the more important question of whether we should go at all appeared first on Space Daily.

  •  

One of the biggest factors in whether a stranger finds you attractive may not be your face, your body, or your clothing — research suggests it is whether you appear to be enjoying yourself in the moment they first see you, with a smile substantially modifying how attractive you appear in the brief seconds when first impressions form

The face you walked into the room with this morning was being read, by every person who looked at you, in approximately one hundred milliseconds — about a tenth of a second, faster than any conscious thought. The reading was not primarily about the features that took your DNA twenty years to assemble. The bones of your face, the colour of your eyes, the shape of your jaw, the symmetry of your features — these all contributed to the judgement, but they were not, on the available evidence, the only ingredients of it. A substantial part of how attractive any individual stranger perceived you to be, in the brief moment before they had any other information about you, was almost certainly whether you appeared to be having a good time. A genuine smile, animated expression, and the visible signs of a person enjoying being where they are produce, in the moment of first impression, attractiveness boosts that can rival what carefully selected clothing, makeup, or grooming can plausibly achieve.

According to a 2014 paper by Jessika Golle, Fred Mast, and Janek Lobmaier published in Cognition and Emotion titled “Something to smile about: The interrelationship between attractiveness and emotional expression”, the social effect of smiling on stranger-rated attractiveness has been replicated across enough independent studies and across enough cultural contexts to be considered one of the more robust findings in social psychology. Smiling faces are rated more attractive than neutral faces of the same person, across both sexes, across multiple age ranges, and across essentially every population that has been examined. The neuroimaging literature has identified the underlying mechanism: when human observers see a smiling face, the medial orbitofrontal cortex — a region of the brain involved in reward processing and the assignment of positive value to stimuli — shows a substantially stronger response than when the same observer sees a neutral face. The smiling face is, in a literal sense, registering in the observer’s brain as more rewarding to look at.

What kind of smile actually works

The specific type of smile matters substantially. As reported by a peer-reviewed PMC review of smile research and the broader perception literature, the most extensively studied distinction in the smile literature is between what researchers call Duchenne smiles and non-Duchenne smiles. The Duchenne smile, named after the 19th-century French neurologist Guillaume Duchenne who first characterised it, activates two distinct sets of facial muscles: the zygomatic major, which pulls up the corners of the mouth, and the orbicularis oculi, which creates the small crinkles around the outer corners of the eyes. Both muscle activations occur involuntarily when a person is genuinely amused or pleased. The non-Duchenne smile activates only the mouth corners and is the kind of polite, social smile produced on demand for photographs or to acknowledge a casual greeting.

The two types of smile are perceived very differently by observers, even though most people cannot articulate exactly what the difference is when they see one. Duchenne smiles register as genuine, warm, trustworthy, and substantially more attractive. Non-Duchenne smiles register as polite at best, performative or insincere at worst, and produce far smaller boosts to attractiveness ratings. The discrimination is automatic and is operating in the observer’s brain at the level of unconscious pattern recognition rather than conscious analysis. This is the underlying reason why the standard advice to “smile more in photos” often produces mediocre results in practice: the smiles are non-Duchenne. The viewer’s brain registers the difference even when the viewer cannot consciously identify what is wrong with the expression.

Why the effect is so large

Per a 2023 study in Evolutionary Human Sciences examining how smiling expressions interact with facial features in attractiveness judgements, the magnitude of the smiling-on-attractiveness effect is large enough to substantially affect outcomes in real-world social contexts. Across studies, happy facial expressions consistently produce the highest attractiveness ratings of any expression tested; angry expressions produce the lowest. The effect appears in both sexes but is particularly pronounced for ratings of female faces, where smiling can shift attractiveness ratings by amounts comparable to the difference between an averagely-rated face and a substantially above-average face. Even male facial masculinity — which interacts in complex ways with attractiveness preferences — is moderated by smiling: smiling reduces the avoidance response some women show toward strongly masculinised male faces.

The evolutionary and social explanation for this effect is, in the relevant literature, fairly direct. A smile is one of the few human expressions that is broadly cross-cultural — recognised across nearly every population that has been tested — and that consistently signals friendliness, low threat, willingness to engage, and positive emotional state. For an observer making rapid social judgements about whether to approach a stranger, the smile is a substantial piece of information: it indicates that the encounter is likely to go well, that the person on the other side is in a positive frame of mind, and that initial overtures will probably be reciprocated. The attractiveness boost is, in this account, the observer’s brain doing what brains do — bundling the information about the smile into a single quick-summary judgement about whether this stranger is worth engaging with. The summary judgement, in shorthand, comes back as “attractive.”

What the framework does not claim

Intellectual honesty requires noting the limits of the smiling-as-attractiveness effect. The research does not show that smiling can substitute for every other physical or social factor in attractiveness ratings. As covered by a 2025 review at All About Psychology on the broader smile-attractiveness literature, static physical features — facial structure, body shape, height, age, grooming — still contribute substantially to first-impression attractiveness ratings, and the smile effect is best understood as a substantial modifier of these underlying factors rather than as a replacement for them. A smiling face is more attractive than the same face not smiling. A smiling person is generally more approachable than a neutral one. Whether the smiling person is, in absolute terms, more attractive than a non-smiling person with substantially different underlying physical features is a question the research does not consistently answer.

What the research does support is a more specific and more practically useful claim. For any given person, in any given moment, the version of that person who appears to be genuinely enjoying themselves is going to be perceived as more attractive than the same person looking flat, distracted, or unhappy. The variable that each individual has the most direct control over, in the seconds before a first impression forms, is not their face or their body — those are mostly fixed at the moment of the encounter. The variable that is actually within their control is their expression, their visible emotional state, the degree to which they appear genuinely engaged with what is happening around them. The research consistently suggests that this variable, despite being the one most readily modifiable, is one of the larger factors that the observer’s brain weights when assigning the first-impression attractiveness rating. Looking like a person who is glad to be where they are turns out to be, by every available measure, a substantial part of what other people are responding to when they form their first impression of you.

The post One of the biggest factors in whether a stranger finds you attractive may not be your face, your body, or your clothing — research suggests it is whether you appear to be enjoying yourself in the moment they first see you, with a smile substantially modifying how attractive you appear in the brief seconds when first impressions form appeared first on Space Daily.

  •  

The face you see in the mirror every morning is not the face other people see — when researchers show people two photos of themselves, most prefer the mirror-flipped version, while their friends and partners shown the same pair consistently pick the unflipped one, meaning the face you have grown to recognize as your own is essentially the reverse of the one the world has been seeing all along

The face you saw in the mirror this morning was not the face anyone else saw when they looked at you over breakfast. The two are related but not identical. Most human faces are slightly asymmetric — the eyes are at slightly different heights, the smile pulls more strongly on one side than the other, the hair parts on one side, freckles sit in specific positions that do not perfectly mirror across the vertical axis. When you look in a mirror, you see one version of your face, with left and right reversed relative to what other people see. When other people look at you, they see the opposite. You have, over the course of your life, become deeply familiar with one of these two versions. They have become familiar with the other. Neither version is wrong. Both are, however, surprisingly different from each other in ways that affect how each party perceives the same underlying face.

According to a 1977 paper by Theodore Mita, Marshall Dermer, and Jeffrey Knight published in the Journal of Personality and Social Psychology, the experimental setup that established this phenomenon was straightforward. The researchers took a frontal photograph of each of 37 women — undergraduate psychology students at the University of Wisconsin-Milwaukee — and printed each photograph twice: once as a true image (showing the face as a camera or another person would see it), and once as a mirror-flipped image (showing the face as the subject herself would see it in a bathroom mirror). The subjects were then shown the two versions side by side and asked which they preferred. The same pairs were shown to the subjects’ friends and lovers, who were asked the same question. The results, in both Study 1 and a subsequent Study 2, were striking and consistent. The subjects themselves preferred the mirror-flipped version of their own face. Their friends and lovers preferred the true version.

Why this happens

The mechanism underlying the effect is one of the better-established findings in social psychology: the mere-exposure effect, first proposed by the University of Michigan psychologist Robert Zajonc in 1968. As described in Gizmodo’s coverage of the mere-exposure mechanism behind the mirror preference, the mere-exposure effect is the phenomenon by which repeated exposure to a stimulus increases a person’s preference for that stimulus. The more often you encounter something, the more comfortable you become with it, and the more positively you evaluate it on subsequent encounters. The effect operates across an enormous range of contexts. People develop preferences for songs they have heard repeatedly, for faces they have seen frequently in public, for words that appear often in their reading, for foods they have eaten before. It does not require any explicit reasoning or evaluation; it works at the level of automatic familiarity processing.

The mirror-image preference is a particularly clean demonstration of the effect because the two stimuli being compared — the true image and the mirror image of the same person’s face — are objectively almost identical. The asymmetries are small. The lighting is the same. The expression is the same. The only difference is which side of the face is on which side of the photograph. The subject has, over the course of her life, spent many thousands of hours looking at one specific version. Her friends and lovers have spent many thousands of hours looking at the opposite version. When the two parties are then asked which version “looks more like” the person in question, or which version is more attractive, each party prefers the version they have been seeing all along. Neither is wrong. Each is simply applying the mere-exposure effect to the version of the face they have the most experience with.

What this implies about self-perception

Per the Mita et al. paper’s broader theoretical discussion, the finding has implications that extend well beyond the specific experimental setup. The general principle is that the version of yourself that you have internalised as canonical — the face you recognise as belonging to you, the face you adjust before going out, the face whose minor blemishes and asymmetries you have catalogued in detail — is a version that essentially nobody else has ever seen. Every photograph anyone else has ever taken of you. Every memory anyone else has formed of your face. Every impression you have made on a stranger across a room. All of these have been based on the opposite version of the face from the one you have been carrying around in your own head.

This is the underlying psychological mechanism behind the common experience of looking at a photograph of yourself and finding it subtly wrong. The face in the photograph is the true image — the version other people have been seeing all along — but it does not match the mirror image you have spent your life looking at. The mismatch produces the small but real sense of discomfort that most people experience when seeing themselves in photographs, particularly photographs they did not pose for and in which they had no opportunity to adjust their expression before the shutter clicked. The photographs are not unflattering. The photographs are accurate. Your face is mirroring back at you, several centimetres off from where you expected it to be.

The selfie problem

The modern environment has complicated the picture in ways that the Mita team could not have anticipated in 1977. As covered by Goody Feed’s analysis of how mirror-image preferences apply to selfie photography, most smartphone cameras now display selfies in the front-facing camera as a mirror image of the user — because that is what the user is accustomed to seeing — and then save the resulting photograph in one of two ways, depending on the phone model and the specific app being used. Some phones save the mirror-flipped version (the version the user saw in the viewfinder). Others save the true version (the version other people would see). The user is, accordingly, receiving inconsistent feedback about which version of their face is “really” them. A selfie that looked fine in the camera viewfinder may appear subtly wrong when reviewed afterwards, because the photo has been flipped to the true orientation. The same selfie viewed by a friend may look slightly strange to the user but entirely normal to the friend, who has been seeing that orientation of the face all along.

The broader implication, beyond the specific case of selfies, is that nearly every modern human is now navigating a world in which both versions of their own face are routinely available — the mirror version every morning in the bathroom, the true version in every photograph, video, and reflective non-mirror surface. The two versions are different enough that the brain registers the discrepancy. The version each person has learned to recognise as their own is, by all available evidence, the one that other people have not seen, except in the rare case of looking at the person directly while standing on the opposite side of a mirror. Everyone else has been seeing the other one. Your face, the one in your head, is essentially the reverse of the one the world has been looking at for as long as you have had it.

The post The face you see in the mirror every morning is not the face other people see — when researchers show people two photos of themselves, most prefer the mirror-flipped version, while their friends and partners shown the same pair consistently pick the unflipped one, meaning the face you have grown to recognize as your own is essentially the reverse of the one the world has been seeing all along appeared first on Space Daily.

  •  

Czech speleologists exploring a cave system in southern Albania in 2021 discovered the largest underground thermal lake ever found on Earth — a 138-metre-long body of warm water sitting 127 metres beneath the surface at the bottom of a 100-metre vertical abyss — large enough to fill more than three Olympic swimming pools, in complete darkness, that no human being had ever seen before

Somewhere beneath a mountain in southern Albania, in a region called Vromoner near the small town of Leskovik on the Greek border, a body of warm mineral water has been sitting in complete darkness for an indeterminate but very long time, with no human aware of its existence, no light reaching its surface, and no possibility of being entered by anyone except via a hundred-metre vertical drop through a limestone shaft. In 2021, a team of Czech speleologists became the first humans to make that drop. They were led by Marek Audy, a veteran Czech cave explorer who had spent several years investigating the underground hydrology of the Albanian-Greek mountain borderlands. The team had been tracking high-temperature springs and tall columns of steam that emerged from cracks in the surface limestone — the visible exhaust of a hidden hot-water system that had to be coming from somewhere below. Following the steam back to its source, the speleologists located a vertical shaft they later named Atmos, approximately a hundred metres deep, leading downward into a previously unmapped cavern. At the bottom of the shaft, in the darkness, was a thermal lake.

According to Radio Prague International’s coverage of the discovery and subsequent confirmation, the 2021 initial exploration produced a preliminary map of the cave system, drawn with the equipment the team had on hand at the time, that strongly suggested the underground lake was extraordinarily large. The team needed more precise instruments to confirm this. Mapping the full dimensions of a body of water in complete darkness, at the bottom of a hundred-metre vertical shaft, with limited working space and toxic hydrogen-sulphide air, required a mobile LIDAR scanner — a piece of equipment that the team did not own and could not initially afford. The Czech Neuron Foundation, a scientific funding organisation supported by private benefactors, provided approximately one million Czech crowns to purchase the necessary equipment. The expedition returned to the cave system in late 2024 with the LIDAR scanner and a team of 18 researchers. The measurements they took confirmed the lake’s full dimensions: 138.3 metres long, 42 metres wide, with a perimeter of 345 metres and a total volume of approximately 8,335 cubic metres of hot mineral water.

How big the lake actually is

The numbers translate into more intuitive comparisons that the team has used in subsequent communications. As reported by Euronews Albania’s coverage of the announcement, the lake’s volume is equivalent to approximately 3.5 Olympic-sized swimming pools. The cavern containing the lake is approximately three times the size of the main hall of the National Theatre in Prague. The previous record-holder for the world’s largest underground thermal lake was substantially smaller; the Lake Neuron measurements nearly double the previous record. The cavern is large enough that the LIDAR scanner had to be moved to multiple positions to capture the full geometry, and parts of the lake remain partially unexplored — the team plans to return with sonar equipment to measure the underwater portion of the cavern, which extends below the visible waterline and whose depth is not yet known.

The water itself is the unusual feature of the find. The lake is saturated with hydrogen sulphide — the gas responsible for the distinctive rotten-egg smell that hangs in the air throughout the cavern and that is toxic at high concentrations. The hydrogen sulphide, on contact with the atmosphere at the lake’s surface, oxidises into sulphuric acid. This is also why the cavern that contains the lake exists at all. Most caves in karst topography are formed by carbonic acid — slightly acidic rainwater dissolving limestone over millions of years. The Albanian cavern was formed by a fundamentally different process: sulphuric acid, generated by the oxidising hydrogen sulphide rising from the lake, has been gradually dissolving the limestone into soft gypsum from below. The technical term is sulphuric acid speleogenesis. It produces caves that are larger, more chemically active, and substantially more dangerous to explore than the carbonic-acid caves that dominate most karst regions.

What was down there before anyone got there

The lake is, in essential terms, an ecosystem operating in complete darkness, fuelled by chemistry rather than sunlight, sealed off from the surface biosphere for an unknown but presumably substantial period of time. As described in the Jerusalem Post’s coverage of the confirmed measurements, the researchers expect the lake to host extremophile microorganisms — bacteria and archaea adapted to high temperatures, no light, and high concentrations of hydrogen sulphide and dissolved minerals. Communities of this kind have been documented in other thermal and sulphurous cave systems, where they form the base of food webs that are entirely independent of photosynthesis, drawing their energy instead from chemical reactions between dissolved minerals and the surrounding water. Whether the Lake Neuron community contains microbial species new to science is a question the research team plans to investigate in subsequent expeditions.

The broader scientific significance of the find runs in several directions. The cave hydrology is connected, at some unknown depth, to the surface springs that originally led the speleologists to look for a hidden source. Mapping the connection between the underground lake and the surface water system will substantially improve hydrologists’ understanding of how groundwater moves through the karst terrain of the western Balkans. The presence of a previously unknown body of thermal water of this size raises questions about how many other comparable underground lakes might exist beneath similar mountain ranges around the world, where the geological conditions for sulphuric-acid speleogenesis are present but no surface evidence has yet been investigated. The Czech team’s discovery is, in technical terms, a sample of one — but it is a sample of one that is unusually large and that suggests the broader population may be larger than has previously been recognised.

The exploration itself

The story is also, separately, a story about contemporary speleology — a science that retains an unusually high proportion of physical risk and discovery for an activity that takes place in the 21st century. As covered by Monitor Magazine’s coverage of the team’s broader work, descending a hundred-metre vertical shaft in a karst cave system, breathing air contaminated with hydrogen sulphide, with no possibility of rescue if anything goes wrong, is not work that most scientific fields require their practitioners to do. The Czech speleological tradition, which has been mapping the underground of central and south-eastern Europe for several generations, sits at the intersection of mountaineering, scientific exploration, and a particular kind of physical patience that the broader scientific establishment has largely outgrown. Marek Audy and his team’s discovery of Lake Neuron is, by every available measure, the most significant single find of their careers. It is also a reminder that the planet still contains substantial unmapped territory, sitting in complete darkness beneath mountains that humans have lived alongside for thousands of years, waiting for someone to find a vertical shaft and decide to go down it.

The post Czech speleologists exploring a cave system in southern Albania in 2021 discovered the largest underground thermal lake ever found on Earth — a 138-metre-long body of warm water sitting 127 metres beneath the surface at the bottom of a 100-metre vertical abyss — large enough to fill more than three Olympic swimming pools, in complete darkness, that no human being had ever seen before appeared first on Space Daily.

  •  

A brain-computer interface has, for the first time, restored fluent everyday speech to a person who had lost it — a man with ALS who had not spoken aloud in years until a small implant from the BrainGate clinical trial began translating his attempts to speak directly into computer-synthesised words, in a result researchers reported in June 2026

Casey Harrell can now talk for twelve hours at a stretch. Two years ago, he could not talk at all. The ALS he was diagnosed with several years earlier had progressively destroyed the motor neurons controlling the muscles of his face and throat, leaving him with the symptoms doctors call dysarthria and, eventually, anarthria — the inability to speak intelligibly even with substantial effort. Harrell still knew what he wanted to say. The neural commands his brain was sending toward the muscles of his lips, tongue, jaw, and larynx were intact. The muscles themselves no longer responded. What the BrainGate clinical trial team at UC Davis did, in a July 2023 surgery that took several hours, was implant four small arrays of microelectrodes into the left precentral gyrus of Harrell’s brain — the region of the speech motor cortex that ordinarily sends those commands to those muscles. The arrays contain 256 electrodes between them. The electrodes record the firing patterns of individual neurons in real time. Machine-learning software running on a nearby computer translates the patterns into the words that Harrell, despite no longer being able to produce them with his mouth, is still trying to say.

According to UC Davis Health’s June 2026 announcement of the latest results, the system now operates at approximately 99 percent accuracy across a working vocabulary of 125,000 words — essentially every word an English-speaking adult would ordinarily need. Harrell’s average speaking rate via the device is approximately 56 words per minute, comparable to slow natural conversation. He has used the system at home, without researchers present, for more than 3,800 hours over a 400-day continuous-use period — averaging roughly five hours of daily use, with maximum single sessions of approximately twelve hours. He has produced more than 183,000 sentences and approximately two million words. His synthesised voice is modelled on recordings of his own pre-ALS voice. When he first heard it during the early trial phase, his own comment was: “It feels a lot like me.”

What changed between 2024 and 2026

The BrainGate team’s first publication on Harrell’s case, in the New England Journal of Medicine in August 2024, established that the basic approach worked — that brain activity recorded from the speech motor cortex could be decoded into fluent speech with high accuracy, in a setting with researchers present and a constrained working session. The June 2026 paper documents something fundamentally different: the same patient continuing to use the same system, but now in an independent home setting, operated by his own care team rather than by researchers, for thousands of hours over multiple years. As reported by ScienceAlert’s coverage of the latest results, this transition — from a proof-of-concept demonstration in a research lab to a sustained, independent communication tool used as part of daily life — is the genuinely novel achievement that the BrainGate team is reporting.

David Brandman, the UC Davis neurosurgeon who implanted the device and co-led the research, framed the shift directly: “For years, BCIs have been proof-of-concept devices that lived in highly controlled research labs. This work shows that we may have crossed a threshold, by empowering a person with paralysis to speak on his own terms.” The practical difference is substantial. A device that requires researchers to be physically present every time it is used can demonstrate scientific feasibility but cannot become part of a person’s actual life. A device that the patient’s regular home care team can connect every morning and disconnect every evening, with no specialist intervention required, can. Harrell has been doing the latter for two years.

What the system actually does

The fundamental insight underlying the BrainGate speech BCI is that the brain continues to send speech commands even after the muscles can no longer execute them. When Harrell attempts to speak, the neurons in his speech motor cortex fire in patterns that are essentially identical to the patterns they would have produced if he could still move his speech muscles normally. The implanted microelectrodes record those firing patterns from approximately 256 individual neurons. The decoding software, trained on Harrell’s specific neural signatures during initial calibration sessions, identifies which phonemes he is trying to produce and assembles them into words. Per The Next Web’s analysis of the BRAND platform that powers the decoding, the system uses a custom machine-learning architecture optimised for real-time speech reconstruction, with continuous adaptation to changes in the neural signal over time.

One of the more remarkable aspects of the system is its inclusion of a deliberate “privacy mode,” in which Harrell can disable data recording when he does not want his neural activity captured or used to train future versions of the decoder. The feature exists because the technology raises real concerns about the boundary between intended speech and unspoken thought. Brain-computer interfaces, by their nature, record neural activity that the user may not have chosen to externalise. The BrainGate team has been careful to design the system so that the user controls what gets recorded and what does not.

What this means for the broader field

The Harrell case is part of a broader convergence in the BCI field that has been gathering pace over the past several years. As covered by a Clinical Trials Arena analysis of the BCI clinical trial landscape, the BrainGate consortium — which has been running clinical trials of brain-computer interfaces since the early 2000s, and now spans Brown University, Massachusetts General Hospital, the VA, and UC Davis — is one of several parallel efforts working on the same general problem. Elon Musk’s Neuralink, Synchron, Paradromics, and the UCSF and Stanford BCI groups have all produced demonstrations of varying scope and ambition. The BrainGate Harrell case is, at present, the most extensively documented sustained-use BCI result in the published literature, but it sits within a broader trajectory in which the basic technology is moving from research curiosity to clinical reality.

For the approximately 30,000 Americans currently living with ALS, the practical implications of the Harrell case are limited in the short term. The technology remains experimental, requires invasive surgery, and is not yet commercially available outside the clinical trial setting. Scaling the approach to a second patient, a tenth patient, a hundredth patient will require substantial work on hardware durability, surgical standardisation, software adaptation across individual neural signatures, regulatory approval, and the long list of practical and economic questions that any new medical device must answer before becoming generally available. None of these are insurmountable. None of them are immediate. Harrell himself is now able to communicate, work, and participate in family and social life in ways that were not available to him two years ago. The question of how soon the same becomes true for other ALS patients, for stroke survivors with severe communication impairment, for people with locked-in syndrome, and for the broader population of patients with severe paralysis is now a question of engineering, manufacturing, and policy rather than of fundamental scientific possibility. The threshold the BrainGate team is now claiming to have crossed, in Brandman’s framing, is the one between proof-of-concept and tool. Whether the rest of the field follows, and how quickly, will define the next decade of BCI research.

The post A brain-computer interface has, for the first time, restored fluent everyday speech to a person who had lost it — a man with ALS who had not spoken aloud in years until a small implant from the BrainGate clinical trial began translating his attempts to speak directly into computer-synthesised words, in a result researchers reported in June 2026 appeared first on Space Daily.

  •  

Almost every encrypted secret being protected today — banking records, classified government cables — is expected to become readable within the next decade once quantum computers arrive, and intelligence agencies are already stockpiling that data, in a strategy called “harvest now, decrypt later”

Somewhere in a windowless data centre, in a country that may or may not be your own, a server is quietly storing a copy of every encrypted email you have ever sent, every banking transaction you have ever made, every encrypted message you have ever exchanged with a doctor or a lawyer or a lover — and is waiting, patiently, for the technology to arrive that will eventually let someone read all of it. The technology is quantum computing. The waiting period is, by most current estimates, somewhere between five and twenty years. The strategy is called “harvest now, decrypt later,” and it is now the explicit, publicly acknowledged practice of the signals intelligence agencies of every major industrial country, several non-state actors, and an unknown number of organised criminal groups. The encryption that currently secures essentially every digital communication on the planet — diplomatic cables, financial records, medical files, military communications, corporate intellectual property — was designed under the assumption that breaking it would take longer than the lifetime of the universe. It will, in fact, take however long it takes the quantum computing industry to build a machine with enough qubits. That timeline is no longer measured in cosmic units.

According to a detailed cryptographic analysis of the harvest-now-decrypt-later threat published in 2026, the US National Security Agency issued an unambiguous public assessment in August 2021: “Adversaries may be collecting encrypted data now, waiting for the day when quantum computers can decrypt it.” The UK’s National Cyber Security Centre made a similar statement in its 2023 Annual Review, noting that state actors are conducting data theft campaigns “for exploitation in years to come.” The Five Eyes intelligence-sharing alliance — comprising the US, UK, Canada, Australia, and New Zealand — has issued coordinated joint advisories on the same threat. The Cyber Threat Alliance released a report in February 2026 titled “Approaching Quantum Dawn,” documenting that the harvesting is now occurring at industrial scale and that the storage costs are entirely tractable for state-level actors operating on 10-to-20-year time horizons.

What is actually being attacked

The cryptographic vulnerability that quantum computers will expose is not, technically, all encryption. It is specifically the encryption that secures the initial exchange of keys between two parties who want to communicate securely — what cryptographers call asymmetric or public-key cryptography. The two dominant standards are RSA (named after Rivest, Shamir, and Adleman, the three MIT cryptographers who developed it in 1977) and ECC (Elliptic Curve Cryptography). Both depend, for their security, on mathematical problems that are easy to set up but extraordinarily hard to reverse — specifically, factoring very large numbers into their prime components (for RSA) and solving discrete logarithm problems on elliptic curves (for ECC). Classical computers would require approximately the lifetime of the universe, or longer, to solve these problems at the key sizes currently in commercial use.

As reported in a 2025 Federal Reserve Board paper examining post-quantum cryptography risks, Shor’s algorithm — a quantum algorithm developed by the mathematician Peter Shor in 1994 — would, on a sufficiently powerful quantum computer, solve both problems in hours rather than billions of years. The bulk encryption that actually protects the contents of messages, once the keys are exchanged, uses symmetric encryption (typically AES-256) that is substantially more quantum-resistant. Symmetric encryption is weakened by quantum computers but not broken in the same catastrophic way. The asymmetric key-exchange step is the choke point. Once a quantum computer can break the RSA or ECC key exchange that secured a TLS session in 2024, the entire contents of that session — captured and stored by an adversary at the time — can be decrypted retroactively.

What gets stored, and why

The practical implication is that any encrypted communication transmitted today, intercepted today, and stored today becomes readable when the threshold quantum computer exists. The damage from this is structural rather than fixable. As documented in the broader literature on harvest-now-decrypt-later attacks, you cannot patch a data breach that occurred five years ago. You cannot recall a diplomatic cable that an adversary intercepted in 2024 and stored in a data warehouse. You cannot retroactively encrypt the medical records, financial transactions, intellectual property, military communications, or industrial control system data that has already been captured. The damage is done at the moment of interception. The decryption is just the moment when the damage becomes legible.

This is why the harvesting is, by all available evidence, already extensive. State-level signals intelligence agencies have been bulk-collecting internet traffic for over a decade. The marginal cost of storing additional petabytes of encrypted data is small at state scale. The patience required — waiting 10 or 15 years for the decryption capability to mature — is structural rather than burdensome for actors operating on geopolitical time horizons. The Citi Institute’s January 2026 quantum threat report estimated that the cumulative cost of the eventual decryption events could reach into the trillions of dollars across the global economy, depending on what data turns out to have been harvested and how it is used.

The countermove

The defensive response is called post-quantum cryptography — the development and deployment of new encryption methods that are designed to be resistant to quantum attack. The US National Institute of Standards and Technology has been running a multi-year competition to identify the most promising algorithms, and finalised the first set of standards in 2024. The leading new key-exchange standard, CRYSTALS-Kyber, is based on mathematical problems involving lattices in high-dimensional spaces — problems that, by current understanding, are hard for both classical and quantum computers. Several major technology companies have already begun deploying post-quantum cryptography. Apple deployed it for iMessage in February 2024. Signal added it. Google has rolled it out across Chrome.

As covered in a March 2026 EnQuanta analysis of the NSA’s commercial migration deadlines, the US federal government has set transition deadlines that require all national-security systems to migrate to post-quantum cryptography by 2027, with the full commercial transition expected by 2033. The European Union has set similar timelines. The UK, Australia, Canada, Japan, and most other major industrial democracies are in the process of doing the same. The scale of the migration is substantial — essentially every digital system that uses RSA or ECC for key exchange will need to be updated — but the work is underway. The challenge is that the harvest-now-decrypt-later attack is not symmetric with the defence: even if every system in the world migrates to post-quantum cryptography tomorrow, the data that has already been collected in the past decade, encrypted with the now-vulnerable algorithms, will still become readable when the threshold quantum computer arrives. The migration protects future communications. It does not protect past ones.

The threshold itself remains uncertain. The most optimistic forecasts among cryptographers and quantum-computing researchers place the cryptographically relevant quantum computer somewhere in the 2030s. The most pessimistic place it in the 2040s. A May 2025 paper by Craig Gidney of Google Quantum AI substantially pulled the timeline forward by demonstrating that the qubit requirement for breaking RSA-2048 had dropped from his own 2019 estimate of approximately 20 million qubits to fewer than 1 million — a 95 percent reduction in hardware demand, driven by improvements in error correction and approximate modular arithmetic rather than by any new physics. The intelligence agencies that are already harvesting the encrypted traffic are not waiting to find out which forecast turns out to be correct. They are storing the data now and trusting that the decryption capability will arrive within the operational lifetime of whatever it is the data turns out to be relevant to. The cost of being wrong about the timing — by harvesting more data than they end up being able to decrypt — is small. The cost of being right and having no harvested data to decrypt is much larger. The arithmetic, from a signals-intelligence perspective, is straightforward. The encryption that protects the species’ digital life is on a deadline. The countdown started years ago.

The post Almost every encrypted secret being protected today — banking records, classified government cables — is expected to become readable within the next decade once quantum computers arrive, and intelligence agencies are already stockpiling that data, in a strategy called “harvest now, decrypt later” appeared first on Space Daily.

  •  

A seismic wave from Japan’s 2011 magnitude-9 earthquake travelled nearly 2,900 kilometres down to Earth’s core, bounced back to the surface 13 minutes later, and shifted the entire country eastward by roughly six millimetres at the same instant — in the first observation of its kind ever recorded

For 15 years after the 2011 Tohoku-Oki earthquake — among the most thoroughly instrumented natural disasters in history — a small anomaly in the GPS data sat unresolved in the archives. Approximately 15 minutes after the magnitude-9 main shock struck off the coast of northeastern Honshu, GPS stations distributed across the entirety of Japan registered a tiny but unambiguous step-like displacement to the east, of approximately five to six millimetres, occurring nearly simultaneously across the country. The shift was far too small to be felt by anyone, far too small to cause damage, and far too late to be attributable to the main rupture itself. It did not correspond to any known aftershock. It was reported in subsequent compilations of Tohoku data but was, for over a decade, an unexplained signal sitting in the corner of a vast dataset that researchers had not yet figured out how to interpret. On 18 June 2026, a team led by Sunyoung Park, an assistant professor of geophysical sciences at the University of Chicago, published a paper in Science proposing what they argue is the correct explanation. The shift, they conclude, was caused by a seismic wave that had travelled from the earthquake’s epicentre straight down through the Earth’s mantle, bounced off the outer core, returned to the surface, and arrived at Japan’s tectonic plate boundaries with enough residual energy to push the entire country a few millimetres eastward.

According to the University of Chicago’s announcement of the finding, the specific wave responsible is what seismologists call an ScS wave — a shear wave that travels downward from the earthquake’s source, reflects off the core-mantle boundary at approximately 2,890 kilometres depth, and returns to the surface as a shear wave. The reflection occurs because shear waves cannot propagate through liquids, and the Earth’s outer core is liquid iron and nickel. The wave bounces off the boundary the way a billiard ball bounces off a cushion. The round-trip travel time, for a wave originating at the depth of the Tohoku rupture, is approximately 13 minutes. When the wave returned to Japan, it arrived essentially simultaneously across the entire country — and it was strong enough, in the Park team’s interpretation, to trigger small additional slip on the already-stressed megathrust interfaces along Japan’s tectonic plate boundaries. The slip event itself, though only a few millimetres in displacement, released energy equivalent to approximately a magnitude-7.5 earthquake.

Why this had never been seen before

Seismologists have long known that large earthquakes generate seismic waves that travel throughout the planet’s interior and reflect off various internal boundaries. ScS waves, in particular, have been catalogued and studied for decades as a routine feature of the seismic record. What had not previously been observed was an ScS wave arriving back at the surface with enough energy to cause measurable, permanent ground displacement. As reported by Scientific American’s coverage of the Park study, the central reason is that ScS waves typically dissipate substantially during their long round-trip through the mantle — the deeper they travel, the more energy they lose to attenuation, and by the time they return to the surface, they are usually too weak to produce any detectable mechanical effect. The Tohoku event was different. The magnitude-9 main shock generated an ScS wave with a peak-to-peak amplitude exceeding one centimetre at Japan’s surface stations — a far stronger reflected wave than any previously recorded. The combination of unusually high amplitude and the synchronised arrival across a country already sitting on heavily stressed plate boundaries produced, in Park’s interpretation, the conditions for the wave to actually trigger small slip events along those boundaries.

The Park team spent substantial time ruling out alternative explanations before settling on the ScS-triggering interpretation. The possibility that the main shock had simply continued releasing energy for longer than thought could not account for a uniform shift across the entire country; the energy from the main rupture should have produced displacement concentrated near the epicentre and falling off with distance. The possibility of a submarine landslide triggered by the main shock could not explain the synchronised timing or the country-wide extent. The possibility of an unrecognised aftershock did not match any seismic record. Each alternative explanation could account for some features of the signal but not all of them. The ScS-triggered slip interpretation, in contrast, predicts exactly the geographic pattern, the synchronised timing, and the relationship to the main shock that the GPS data actually show.

What this means for seismic hazard

Per Science News’s coverage of the implications, the Park finding has substantive implications for how seismologists model the propagation of effects from large earthquakes. The traditional picture has held that the danger from a major earthquake is concentrated in the immediate vicinity of the rupture and in the aftershock sequence that follows. The new finding suggests that the influence of the largest earthquakes may extend much further, and through much deeper geological pathways, than this picture accommodates. A wave that travels 5,800 kilometres round-trip through the Earth’s interior, bounces off the core, returns to the surface, and triggers additional fault slip on the far side of the planet is operating on a different scale and through a different mechanism than the surface-wave aftershock pattern that has dominated seismic hazard modelling for the past century.

Park’s own framing of the finding, quoted in the University of Chicago announcement, is direct: “It’s striking because this is both an unprecedented length and area for a seismic event, and it is a previously unrecognised source of seismic hazard.” The practical implication is that the Tohoku event may have been triggering small slip events not only across Japan but potentially across other plate boundaries around the Pacific Rim that were exposed to the same returning ScS wave. Whether this kind of triggering will turn out to be a feature of all sufficiently large earthquakes, or whether it was specific to the unusual configuration of the Tohoku event, will require examination of GPS data from other recent magnitude-9 earthquakes — the 2004 Sumatra-Andaman event, the 1960 Valdivia event in Chile, the 1964 Alaska event, and the 2010 Chile event — to see whether comparable signals are detectable in the available data.

The deeper picture

As described in the abstract of the Park, Kanamori, and Rivera paper in Science, the finding fits within a longer scientific tradition of using large earthquakes as natural experiments on the structure of the Earth’s interior. Seismic waves from major events are, in practical terms, the only tool humans have for directly probing the structure of the planet beneath the relatively shallow depths accessible to drilling. The deepest hole ever drilled — the Kola Superdeep Borehole on Russia’s Kola Peninsula — reached approximately 12 kilometres before the heat and pressure exceeded the capacity of the drilling equipment. The Earth’s mantle begins at approximately 35 kilometres depth and continues to 2,890 kilometres. The outer core extends from there to 5,150 kilometres. The inner core sits beneath that, all the way to the planet’s centre at 6,371 kilometres. None of these layers has ever been directly sampled. Everything humans know about the structure of the planet beneath the upper crust has been inferred from seismic waves — their travel times, their reflections, their refractions, their changes in velocity as they pass through different layers — generated by earthquakes and recorded at the surface.

The 2011 Tohoku event, in retrospect, generated the largest and most thoroughly instrumented seismic dataset of any earthquake in human history. The five to six millimetres of country-wide eastward shift that nobody initially knew how to explain has now, 15 years later, been identified as the surface fingerprint of a wave that travelled deep enough to touch the boundary of the molten outer core and return. It is, in a substantive sense, the first time the species has directly witnessed the seismic interior of the planet reaching back up to nudge the surface. The signal is small. The implications are not.

The post A seismic wave from Japan’s 2011 magnitude-9 earthquake travelled nearly 2,900 kilometres down to Earth’s core, bounced back to the surface 13 minutes later, and shifted the entire country eastward by roughly six millimetres at the same instant — in the first observation of its kind ever recorded appeared first on Space Daily.

  •  

The dust in your home is not just dirt — it is a mixture of skin, fabric, pollen, soil, insects, microbes, smoke, and microscopic plastic, turning an ordinary windowsill into a quiet archive of what has entered the room

Look at a windowsill after a week without cleaning and you are looking at a material document. The grey film gathering there is not simply grime from outside. It is a composite, built layer by layer from everything that moves through the space: the people who live in it, the air that passes through, the products used, the seasons outside. Analysed carefully, household dust can be read almost like a log. Researchers have learned to do exactly that.

We are writers, not chemists or environmental scientists. What follows is a reading of several years of research into what dust is, not guidance on what to do about it.

What the mixture contains

House dust is usually described first in terms of skin. The figure most commonly cited is that humans shed something in the order of millions of skin cells per day — one widely cited estimate puts it at 500 million, with the outer layer renewing roughly every two to four weeks. Some of that settles. But the claim, still circulating widely, that household dust is mostly dead skin has been questioned by researchers who point out that skin cells account for a meaningful portion of the organic fraction, not the whole of the dust itself. The rest is a longer list.

Clothing and textiles contribute substantially. As fabric moves and wears, it releases fibres, and in homes with synthetic materials that means microscopic strands of polyester, nylon, acrylic and other polymers shed into the air and settle. Outdoor soil arrives on shoe soles and through ventilation. Pollen enters on clothing, on pets, through open windows; research published in Building and Environment found that indoor pollen loads track outdoor seasonal patterns closely, meaning the species composition of the dust in any given room shifts across the year. Insect fragments, particularly from dust mites and cockroaches, are present in most samples. Smoke particles, whether from cooking, candles, or outdoor air pollution tracked inside, add to the mix. Fungal spores, drawn in from outside, contribute to the biological fraction.

Then there is the microbial layer, which has attracted significant attention as sequencing technology has improved. A 2016 paper in PLOS One characterised the bacterial and fungal communities in indoor dust across a range of homes, finding that bacteria in indoor environments are largely derived from the inhabitants themselves, with genera including Staphylococcus, Streptococcus, Corynebacterium, and Lactobacillus dominating the profile. Fungi, by contrast, arrive mostly from outdoors, their community composition shifting with outdoor vegetation and season. The result is a microbial record that reflects both who lives in the space and what surrounds it.

The outdoor world inside

Around two-thirds of the material in household dust is estimated to originate outside, though this varies significantly by study, region, and building type. It is tracked in on shoes, carried in on air currents, attached to clothing, or brought in on pets. The remaining third is generated internally: by the bodies present, by the materials in the room, by whatever is cooked, burned, or sprayed. The ratio shifts in tightly sealed buildings and in homes with poor ventilation.

This outdoor contribution means dust is not simply a domestic record. It is also a local environmental one. Homes near high-traffic roads tend to carry higher loads of combustion particles and certain metals. Homes near agricultural land can carry pesticide residues. Seasonal pollen patterns are legible in indoor samples. In this sense the windowsill is not sealed off from the street outside; it is continuously receiving it.

The chemical accumulation

Dust also accumulates what is harder to see: the chemical load from consumer products in the home. Environmental chemist Miriam L. Diamond of the University of Toronto has described dust as holding a “long memory” of the contaminants introduced to a house. Flame retardants migrate off the foam in furniture and off electronics. Phthalates leach from vinyl flooring. Fragrance compounds shed from personal care products attach to airborne particles before settling. These compounds continue to accumulate in dust over time, and because homes are tightly sealed environments, the accumulation is persistent. Diamond has noted that dust from older homes can still carry traces of DDT and PCBs, banned in many countries for decades.

A 2016 analysis published in Environmental Science & Technology by Susanna D. Mitro of George Washington University and colleagues — including Robin E. Dodson of the Silent Spring Institute and Veena Singla of the Natural Resources Defense Council — reviewed more than two dozen dust studies covering 45 compounds. They found that ten compounds appear in 90 percent or more of US household dust samples, including phthalate plasticisers, flame retardants, and phenol preservatives from cosmetics. These are findings from that particular dataset, not universal claims about all households or all exposures. The health picture is genuinely uncertain: researchers have established that dust is a source of exposure to these substances, but determining the extent of any health risk requires more work, and for many of the compounds present, no clear safety thresholds have been set.

Microplastics have been found in indoor dust samples from across the world. A 2024 review in Indoor and Built Environment noted that synthetic textiles are among the primary sources, with polyester and polypropylene fibres dominant in most samples. The concentration varies by household, and the long-term health picture from microplastic inhalation and ingestion is still being established.

What the archive tells us

P. Lee Ferguson, an environmental chemist at Duke University, has described the chemical compounds measurable in household dust as covering only “the few to a hundred compounds that we know are in dust,” against a backdrop of tens of thousands to over a million compounds currently in commercial use. The full chemical archive in any given room is, in that sense, largely unread. Researchers using newer nontargeted mass spectrometry approaches are beginning to identify compounds that were not previously expected: surfactants from cleaning products, azo dyes from textiles, traces of dog flea treatments, and in some samples, cocaine. That last compound appears as a data point about what circulates in the built environment, not as moral commentary. It is a data point about what circulates in the built environment.

The more interesting point, in our reading of this body of work, is what the archive implies about ordinary domestic space. A room that appears clean is still accumulating. The material record builds whether or not anyone is paying attention to it. What settles on a windowsill over a week reflects the people inside, the objects they use, the plants flowering outside, the roads nearby, the products manufactured with compounds that were assumed to stay where they were put.

Dust is not usually studied for its own sake. Researchers study it because it is an unusually honest record of what surrounds us. It does not preserve memory in the way we think of memory. It preserves material presence: what arrived, what shed, what accumulated. Every ordinary surface is doing this, quietly, all the time.

The post The dust in your home is not just dirt — it is a mixture of skin, fabric, pollen, soil, insects, microbes, smoke, and microscopic plastic, turning an ordinary windowsill into a quiet archive of what has entered the room appeared first on Space Daily.

  •  

Thought of the day from Carl Jung: “Who looks outside, dreams; who looks inside, awakes”

I am not a psychologist or a therapist, and what follows is one writer reading Jung and a bit of modern research, not advice.

For most of my twenties I looked outside. There was a script, the one a lot of us absorb without noticing, where by thirty you are supposed to have the markers. Money, the right lifestyle, the proof that you have arrived.

I chased a fair bit of it.

I got the motorbike I had told myself I wanted for years, for instance. And the unglamorous truth: within a few months the bike was just my bike. The wanting did most of the work, and the having did almost none.

For me, this is the half of Jung’s line about dreaming. Looking outside, you are forever projecting the good feeling onto the next thing, and the next thing keeps arriving and going flat.

The modern research rhymes with this in a way I find hard to ignore. In a 1993 study, Tim Kasser and Richard Ryan found that people who placed relatively high importance on financial success relative to goals like self-acceptance and community tended to report lower wellbeing. A later meta-analysis by Helga Dittmar and colleagues pulled decades of this work together and found a strong focus on money and possessions sitting alongside lower personal wellbeing.

None of that proves the new bike made me unhappy. It didn’t. But the wanting-then-flattening cycle is real, and I had lived it before I read a single study about it.

Looking inside, and what Jung actually meant

The line itself is older and gentler than the self-help version of it suggests. Jung wrote it in a letter dated 22 October 1916, to a patient. It appears on page 33 of the first volume of his collected letters. In the passage Jung tells her that her vision will only clear when she can look into her own heart, and that as long as she keeps projecting her psychology onto other people she will never reach peace with herself.

That is the part I think people miss. The inward turn here is not navel-gazing. It is the opposite. It is pulling back the projections you have flung onto the world and the people in it, and seeing more clearly because of it. Waking, in Jung’s sense, is just looking at what is actually there instead of the dream you laid over the top of it.

The pivot Jung named in the middle of a life

Jung had a bigger frame around all this, the idea he called individuation. Put simply, he thought a life has two movements. The first half is outward: you build an ego, a career, a place in the world. The second half turns inward, toward wholeness and meaning. The Jungian analyst Murray Stein describes it this way: “The first half of life is dedicated to ego development; the second half of life is aimed at integration of the whole psyche to the degree possible in a given human life.” In his account the first-half personality is roughly in place by the mid-thirties, before the inward turn begins. Stein is careful to add that full individuation is never quite reached, and it is worth holding onto that. Keep in mind also, that this is a Jungian framework, a way of making sense of a life, not a settled law of human development.

I bring it up because I seem to be living the pivot in real time, and it has caught me off guard. I am thirty-five. I used to be allergic to stability. Now I genuinely want a quiet, ordinary life. I want to be back into my fitness. I have a leather workbench I never get to enough. Mostly I want less, not more, which is not the wanting I grew up with at all. I am not claiming any of this as expertise. I am just a generalist who read some Jung and felt seen.

What the inward turn looks like in an unglamorous week

The honest version of looking inside is not dramatic. It is not a retreat in the mountains. For me it is wanting less, an ordinary week with nothing to photograph, a walk with no podcast in my ears. I am not a meditator. These are my quieter equivalents, and most of them are small enough to sound like nothing.

One thing I want to be straight about: the inward look can surface things that are heavier than an article like this is built for. Jung’s letter was, after all, written to a grieving woman in treatment, not to someone tidying up their hobbies.

If turning inward stirs up grief, or a low that won’t lift, a qualified counsellor or therapist is worth more than any line of philosophy, mine or Jung’s.

The post Thought of the day from Carl Jung: “Who looks outside, dreams; who looks inside, awakes” appeared first on Space Daily.

  •  
❌