In a groundbreaking study that redefines our understanding of how language is encoded in the human brain, researchers have mapped the diverse landscape of neurons distributed across frontal and temporal cortical regions, revealing a complex yet lateralized neural architecture for human language processing. By leveraging advanced single-neuron recording techniques alongside sophisticated language models, the team has identified not just the locations but the nuanced encoding properties of neurons implicated in various linguistic computations. This work illuminates how language, a uniquely human faculty, is instantiated at the neuronal level with precision and regional specificity.
The study’s comprehensive neuronal recordings spanned key brain areas historically associated with language, including the frontal cortex, anterior temporal cortex, and posterior temporal cortex. These regions were chosen given their established roles in speech production and linguistic comprehension, as well as their demonstrated selective responses in prior localized brain imaging studies. Importantly, the neurons examined were broadly distributed across both hemispheres and these cortical regions, showcasing the widespread neural substrate involved in language tasks.
One of the seminal findings was that roughly half of the neurons, 289 out of 579, exhibited selective responsiveness to one or more linguistic features. Intriguingly, this selectivity was evenly distributed across the three cortical sites — frontal, anterior temporal, and posterior temporal — and did not significantly differ between the left and right hemispheres. This suggests a foundational neural scaffold where language-related computations recruit a multitude of neurons across large-scale networks rather than isolated hotspots, emphasizing distributed processing over modular localization.
However, beyond this broad distribution, the study uncovered striking lateralization and regional differentiation in the strength and informational content of neural modulation. Neurons within the left hemisphere exhibited significantly stronger modulation—quantified by their z-scored activity changes—in response to linguistic features compared to their right hemisphere counterparts. This enhanced sensitivity encompassed a range of linguistic elements, including lower-order features like pitch, underscoring the superior role of the left hemisphere in detailed linguistic encoding.
Further dissecting these lateralized effects across cortical regions revealed that the posterior temporal cortex showed the most pronounced difference in left-right modulation strength, significantly outperforming other areas. This aligns well with the notion that posterior temporal areas are central to decoding complex linguistic dependencies and syntactic structures, functions critical for fluent language comprehension and production.
Conversely, the prefrontal cortex displayed the strongest overall neuronal modulation to these language features, both in the left and right hemispheres, compared to temporal regions. This finding suggests a hierarchical and possibly integrative role for the frontal cortex in orchestrating language processing, perhaps linked to higher-order syntactic planning, working memory, or executive control mechanisms required for natural speech.
The neural predictivity analysis, leveraging embeddings from cutting-edge contextual language models, further corroborated the lateralized and regionalized pattern. Neural activity in the left anterior temporal cortex was most accurately predicted by these language model features, highlighting this region’s role in abstract linguistic representation and semantic integration during language tasks.
Methodologically, the study capitalized on the precise temporal resolution of single-neuron recording combined with sophisticated statistical analyses, including permutation and rank-sum tests, to quantify neuronal response selectivity and modulation. This rigorous approach afforded a fine-grained characterization of how individual neurons adapt their firing patterns to various syntactic and prosodic elements of language in real-time.
Collectively, these data challenge conventional notions that neural language processing is confined to narrowly defined “language centers.” Instead, the findings advocate for a model of language representation as a widely distributed but regionally specialized system with marked hemispheric dominance. This has profound implications for understanding the neural basis of language disorders, suggesting that therapeutic interventions might need to consider both distributed network integrity and hemispheric targeting.
Moreover, the study’s integration of naturalistic language models with neurophysiological data marks a pioneering step in computational neuroscience, bridging theoretical frameworks of language with tangible neural mechanisms. By showing how models trained solely on linguistic input can approximate neuronal responses, this research points toward a future where artificial intelligence and neuroscience synergistically unravel human cognition.
Importantly, the results underscore the unique neural architecture supporting language that has evolved in humans, outstripping earlier simplistic models focused on gross anatomical mapping. These advances set the stage for future investigations that might explore how these neuronal populations interact dynamically during complex language tasks such as conversation, narrative comprehension, or bilingual processing.
In conclusion, this landmark research paints a detailed, high-resolution portrait of the neuronal building blocks underpinning human language. It reveals an exquisitely lateralized and regionally differentiated system whereby distributed neurons collectively encode the multifaceted features of speech. Such insights not only deepen fundamental neuroscience but also hold promise for novel clinical interventions and computational linguistic advancements.
Subject of Research: Neuronal encoding of human language features across frontal and temporal cortical regions; lateralization and regional differentiation of linguistic processing in the brain.
Article Title: Mapping the neuronal building blocks of human language with language models.
Article References:
Cai, J., Kfir, Y., Jamali, M. et al. Mapping the neuronal building blocks of human language with language models. Nature (2026). https://doi.org/10.1038/s41586-026-10691-5
In the ever-evolving landscape of energy storage technologies, the lithium–sulfur (Li–S) battery stands out for its promise to deliver unmatched energy density and reduced costs compared to traditional lithium-ion batteries. However, progress toward commercial viability has been hampered by complex electrochemical challenges, particularly those involving interfacial charge transfer dynamics. A new study, recently published in Nature, unveils groundbreaking insights into the intricate reaction pathways occurring at solid–liquid interfaces within Li–S batteries, illuminating mechanisms that govern lithium sulfide deposition under realistic, lean electrolyte conditions.
The difficulty in understanding and controlling the conversion of lithium polysulfides (LiPSs) during battery cycling stems largely from the dynamic and highly concentrated nature of reactant distributions at the electrode–electrolyte interface. In these environments, the balance between surface-bound and dissolved species dictates the overall electrochemical performance. The new research deploys advanced in situ liquid-cell electron microscopy techniques to directly visualize these sophisticated concentration gradients, a feat that has eluded scientists due to the liquid phase’s complexity and the scales involved.
What emerges from this study is a revelation of concentration-driven phase segregation phenomena right at the interfacial layers, termed high-concentration interfacial layers (HCILs). These HCILs form as LiPSs aggregate in the immediate vicinity of the electrode surface during cycling, dramatically altering the local reaction environment. This segregation is not merely a passive occurrence; it actively directs charge-transfer dynamics by establishing competitive conditions between surface-mediated and solution-based pathways. The delicate interplay in these zones influences where and how lithium sulfide (Li₂S) nucleates and grows, directly impacting the battery’s capacity retention and cycling stability.
Complementing the microscopy observations, computational explorations using density functional theory (DFT) provide a molecular-level understanding of how LiPS clusters modify their electronic structure upon aggregation. The study identifies that the molecular geometries and orbital hybridizations evolve as LiPSs coalesce, resulting in enhanced electronic interactions that facilitate charge transfer through the concentrated clusters. This phenomenon fundamentally challenges previously held models which treated LiPS species largely as isolated entities, offering a new paradigm that accounts for collective behavior in highly concentrated solutions.
The practical implications of these mechanistic insights are far-reaching. By comprehending how HCILs govern interfacial reaction pathways, the researchers have engineered electrodes that strategically balance surface and solution reactions amidst high LiPS concentrations. These meticulously optimized electrodes enable impressive fast-charging capabilities—reaching rates up to 4 C with current densities of 26.8 mA cm⁻²—without compromising energy density, which itself surges beyond 400 Wh kg⁻¹. Such milestones represent a substantial leap forward in the achievable performance metrics for Li–S battery technology.
This study’s significance extends beyond the immediate Li–S chemistry, addressing a broader challenge in electrochemical energy conversion: capturing and controlling complex interfacial phenomena under dynamically varying concentrations. The in situ liquid-cell electron microscopy method establishes a powerful approach for observing reactive species and phase evolution directly in their native electrochemical environment. As such, it holds promise to transform research across a host of energy storage and catalysis systems where interfacial reactions dictate overall function.
Notably, this work also clarifies why lean electrolyte conditions—essential for practical high-energy devices—have historically been so difficult to optimize. The rich detail uncovered concerning phase segregation and charge transfer competition suggests that managing HCIL formation and stability may be the key to unlocking robust Li₂S deposition and dissolution cycles. Hence, this strategy could mitigate common pitfalls like cathode passivation and capacity fading, which have limited long-term operational viability.
The fusion of experimental visualization with robust theoretical modeling provides a comprehensive framework that future researchers and engineers can exploit to rationally design electrode interfaces. Moving past empirical trial-and-error, the ability to predict and control molecular aggregation behavior and its effects on electronic properties opens new avenues for tuning battery chemistry on an atomic scale. Such sophistication could accelerate the sustainable deployment of lithium–sulfur batteries within electric vehicles, grid storage, and portable electronics.
Moreover, the study emphasizes the profound impact of molecular-level phenomena on macroscopic performance metrics such as charging speed and energy density. By showing that the electrochemical environment at the nanoscale directly modulates reaction kinetics and phase evolution, this research bridges a critical knowledge gap between fundamental science and technological application. It highlights the necessity for integrated approaches combining real-time imaging, theoretical insight, and materials engineering.
Looking ahead, the insights gained are poised to influence material selection, electrolyte formulation, and cell architecture design. Tailoring these elements to favor desirable HCIL characteristics could lead to batteries that not only charge rapidly and store vast amounts of energy but also maintain stability over many cycles. Furthermore, the foundational principles elucidated may inspire innovations beyond lithium–sulfur systems, potentially transforming a range of emerging battery chemistries where interface complexity rules.
In conclusion, this remarkable study marks a pivotal advance in understanding and harnessing the subtleties of interfacial charge transfer within lithium–sulfur batteries. By unraveling the competitive reactions shaped by concentration gradients and molecular aggregation, it charts a pathway toward high-performance batteries ready for real-world demands. As energy storage solutions continue to underpin the clean energy transition, such elegant fusion of fundamental science and engineering innovation will be indispensable for propelling next-generation technologies.
Subject of Research: Charge transfer and reaction mechanisms at solid–liquid interfaces in lithium–sulfur batteries.
Article Title: Revealing competitive interfacial reactions in high-energy Li–S batteries.
A comprehensive new study published in JAMA Network Open has revealed pervasive exposure among pregnant individuals in the United States to multiple classes of environmental chemicals, highlighting critical concerns about their impact on fetal development. This groundbreaking longitudinal cohort investigation evaluated a large and ethnically diverse sample of U.S. pregnancies, systematically analyzing exposures to ten distinct categories of environmental pollutants. Many of these chemicals showed significant associations with measurable shifts in gestational age and reductions in birth weight-for-gestational age z-scores, parameters essential for assessing neonatal health and predicting long-term outcomes.
The research employed advanced biomonitoring techniques to quantify the presence of environmental toxicants including phthalates, alternative plasticizers, and polycyclic aromatic hydrocarbons (PAHs) in maternal biological samples during gestation. Phthalates and plasticizers are commonly used in consumer products and medical devices, yet their biochemical interactions during crucial windows of fetal development remain underappreciated. The study’s detailed exposure profiling allowed for unprecedented insights into how these compounds may disrupt endocrine functions or trigger inflammatory processes, potentially precipitating premature labor or impaired fetal growth.
One of the most striking findings was the widespread detection of phthalates and substitute plasticizers within this population, indicating ubiquitous contact despite regulatory efforts to limit their use. These chemicals, integral to plastics and personal care products, demonstrated compelling correlations with shortened gestation periods. Such alterations in gestational length can increase risks for adverse neonatal outcomes, including respiratory complications and neurodevelopmental disorders, underpinning the urgency to reassess public health policies concerning these ubiquitous agents.
Likewise, exposure to polycyclic aromatic hydrocarbons, a class of organic compounds generated through the incomplete combustion of organic matter including fossil fuels and tobacco, was found to be significantly linked with lower birth weight-for-gestational age z-scores. Lower birth weight relative to gestational age is a well-established risk factor for morbidity and mortality in infancy and has been implicated in chronic diseases later in life, such as cardiovascular disorders and diabetes. This association reaffirms concerns about air pollution-related health disparities during pregnancy.
The study’s robust methodology involved careful adjustment for confounding factors, such as maternal age, socioeconomic status, preexisting health conditions, and lifestyle habits, ensuring that the observed effects were primarily attributable to chemical exposures. Such meticulous analytical rigor strengthens causal inferences and enhances the generalizability of findings across the heterogeneous U.S. population.
Beyond the immediate neonatal impacts, the findings underscore the broader implication that gestational exposure to environmental chemicals may foreshadow developmental trajectories affecting cognitive function, metabolic programming, and immune competence. The data suggest a pressing need to incorporate environmental risk assessments into prenatal care and to advocate for more stringent regulation and replacement of harmful chemical additives in manufacturing and consumer goods.
Experts involved in the study emphasize the translational significance of these findings. Reducing prenatal exposure to harmful environmental agents, particularly those involved in plastic manufacturing and combustion byproducts, could be a modifiable risk factor to optimize pregnancy outcomes and subsequent child health. The research calls for collaborative efforts between scientists, clinicians, policymakers, and industry stakeholders to develop safer alternatives and to implement public health strategies aimed at exposure mitigation.
In addition to environmental monitoring, the study highlights the potential of biomarker-driven surveillance in clinical settings to identify at-risk pregnancies earlier. The adoption of such precision health approaches could enable timely interventions designed to minimize chemical-induced developmental insults and promote resilience in vulnerable populations.
Overall, this research project represents a pivotal contribution to reproductive environmental epidemiology, providing compelling evidence on how everyday chemical exposures reverberate at the earliest stages of human life. Such insights fuel the momentum toward integrating environmental considerations into obstetric practice and public health frameworks, ultimately aiming to safeguard the next generation from preventable neurodevelopmental and somatic diseases linked to toxic exposures.
The detailed chemical classes examined in this investigation span commonly encountered substances with diverse structural and functional properties, illuminating the pervasive nature of industrial and urban pollutants. The interdisciplinary approach combining toxicology, epidemiology, and molecular biology sets a new standard for environmental health research, encouraging future explorations into underlying biological mechanisms and potential gene-environment interactions.
As global urbanization and chemical manufacturing continue to expand, the relevance of these findings grows, underscoring an urgent collective responsibility to address environmental determinants of health from conception onwards. By spotlighting the critical window of gestation as vulnerable to chemical insults, this study not only informs clinical guidelines but also energizes advocacy for environmental justice, particularly in frequently marginalized communities disproportionately burdened by pollution exposure.
In summary, the research establishes a clear and compelling connection between gestational exposure to multiple classes of environmental chemicals—including phthalates, plasticizers, and hydrocarbons—and adverse birth outcomes such as shortened gestation and reduced fetal growth metrics. Addressing these exposures presents a tangible opportunity to improve neonatal health indicators and foster lifelong wellbeing, heralding a paradigm shift in how society approaches prenatal environmental risk.
Subject of Research: Gestational exposure to environmental chemicals and its impact on birth outcomes in U.S. pregnancies Article Title: [Not provided] News Publication Date: [Not provided] Web References: [Not provided] References: doi:10.1001/jamanetworkopen.2026.18883 Image Credits: [Not provided]
Keywords: Chemical pollution, Gestational age, Birth rates, Cohort studies, Pregnancy, United States population, Body weight, Hydrocarbons, Environmental health, Plastics, Human health, Obstetrics
In recent years, forests have emerged as pivotal players in global climate mitigation efforts, representing one of the most promising nature-based climate solutions available today. These ecosystems sequester approximately 31% of anthropogenic carbon dioxide emissions annually, providing a critical buffer against the accelerating pace of climate change. However, the reliability of forest carbon credit systems—mechanisms designed to monetize and incentivize carbon sequestration efforts—has come under intense scrutiny. A groundbreaking study published in the journal Biological Diversity unveils deep-rooted methodological flaws that cast profound doubt on the environmental integrity of current carbon credit frameworks, signaling a crisis of confidence across global carbon markets.
The rigorous analysis, spearheaded by environmental scientists from Yangtze University and Beijing Normal University, meticulously dissects the complex architecture of forest carbon credit systems and identifies four principal structural weaknesses that collectively undermine their trustworthiness. Foremost among these is the use of subjective assessments of additionality, a core concept requiring that credited emissions reductions would not have occurred in the absence of the project. Present carbon credit models predominantly rely on static historical baselines to calculate additionality, yet only an alarming 6% of REDD+ credits—credits allocated under the United Nations’ Reducing Emissions from Deforestation and Forest Degradation program—provide robust empirical evidence to substantiate genuine additional carbon mitigation.
Beyond the critical challenge of additionality, the permanence of carbon sequestration—signifying the long-term retention of carbon stock in forest biomass—is grossly overestimated by current standards. This overestimation is particularly precarious in light of escalating ecological disturbances linked to climate change including wildfires, prolonged droughts, pestilence outbreaks, and inadvertent carbon leakage where forest degradation shifts to unmonitored regions. The failure to appropriately incorporate these growing risks into permanence calculations means that many credited projects likely exaggerate their true contribution to climate mitigation, presenting an illusory picture of impact.
The study further reveals that leakage accounting—the assessment and adjustment for project-driven emissions displacement—is critically underdeveloped. Prevailing methodologies apply a modest average leakage deduction of only 7%, a figure that starkly contrasts with empirical findings suggesting leakage rates ranging from 10% to a staggering 70%. Such systemic under-accounting inflates the perceived net climate benefits of these forest projects, enabling an artificially optimistic valuation of carbon credits within international markets and undermining carbon trading integrity.
Compounding these shortcomings are the conspicuous omissions of biophysical impacts such as albedo and evapotranspiration effects in carbon accounting. Forest ecosystems substantially influence Earth’s energy balance through their reflectance properties and water cycling functions. Neglecting these elements obscures the true net climate impact, as alterations in surface albedo can significantly offset the cooling benefits gained from carbon sequestration, thereby diluting the overall effectiveness of forest-based interventions in climate regulation.
The collective failure to address these intertwined issues has deep ramifications not only for the credibility of carbon markets but also for biodiversity conservation and community well-being, which are often marginalized in project implementation. Insufficient local community involvement and opaque benefit-sharing arrangements risk alienating indigenous stakeholders, raising social equity concerns, and jeopardizing the sustainability and durability of mitigation efforts.
In response to these multifaceted challenges, the research team advocates for a transformative overhaul of forest carbon credit systems through a data-driven, science-based, and integrative accounting framework. Central to this reform is the replacement of static baselines with dynamic monitoring systems that leverage high-frequency remote sensing technologies alongside advanced machine learning algorithms. This approach enables objective, continuous, and quantitative assessments of additionality, dramatically enhancing transparency and scientific rigor in credit issuance.
Addressing permanence requires the establishment of a comprehensive three-tier risk management architecture comprised of prevention, buffering, and insurance mechanisms. This tiered system proactively mitigates disturbances by integrating biodiversity conservation as a mandatory compliance criterion rather than considering it a supplemental benefit, thus embedding ecosystem resilience at the heart of carbon project governance.
Transparency and standardization are equally emphasized through the call for stringent Monitoring, Reporting, and Verification (MRV) protocols. The use of cutting-edge technologies such as Light Detection and Ranging (LiDAR) and environmental DNA (eDNA) is prescribed to ensure precise biomass and biodiversity assessments. Additionally, mandatory disclosure of datasets and verification methodologies aims to foster independent third-party audits, enhancing accountability and stakeholder confidence in carbon accounting practices.
Sociopolitical dimensions are also addressed, with the framework highlighting the critical necessity of formalized community governance structures and the institutionalization of Free, Prior, and Informed Consent (FPIC) procedures. These mandates ensure that forest-dependent communities retain decision-making power and equitable access to the socioeconomic benefits derived from carbon sequestration projects, thereby reinforcing local stewardship and long-term project viability.
While the introduction of these rigorous standards is expected to contract the overall volume of carbon credits issued—reflecting a more conservative and realistic accounting of mitigation gains—the resultant credits will embody higher integrity and trustworthiness. This qualitative transformation is paramount for forest carbon credits to evolve from contested commodities susceptible to skepticism into robust and reliable assets underpinning credible global climate governance.
The implications of this research are profound. By embedding scientific rigor and standardized risk management, forest carbon credits can realize their full potential as durable climate mitigation tools while simultaneously safeguarding biodiversity and respecting community rights. This paradigm shift promises to restore confidence among stakeholders, catalyze more effective climate finance mechanisms, and advance global efforts to stabilize the Earth’s climate system.
Ultimately, this work underscores a crucial message: nature-based climate solutions like forests must be governed by scientifically sound and socially just frameworks. Only through such commitment to transparency, accuracy, and inclusivity can these natural assets deliver genuine and lasting contributions to the fight against climate change.
Subject of Research: Not applicable Article Title: Restoring Trust: Rebuilding the Forest Carbon Credit System Through Scientific Rigor News Publication Date: June 17, 2026 Web References: http://dx.doi.org/10.1002/bod2.70026 References: Chen, Xiaoqian, and Shaokun Li. 2026. “Restoring Trust: Rebuilding the Forest Carbon Credit System Through Scientific Rigor,” Biological Diversity: 1–5. Image Credits: Xiaoqian Chen, and Shaokun Li Keywords: Environmental sciences, Carbon emissions, Biodiversity conservation, Climate change mitigation, Risk management, Deforestation, Community ecology, Albedo, Resource policy, Environmental economics, Sustainable development, Land use, Climate change adaptation, Forestry, Carbon, Environmental policy, Environmental impact assessments, Environmental management, Remote sensing, Forest ecosystems
Most generative AI tools know less about R than languages like JavaScript and Python, thanks to how much training data is available for each. However, with a little extra setup, you can give a large language model (LLM) the knowledge it needs to improve its R skills.
Here are 10 ways to help generative AI write R code like a pro.
Use a coding agent
AI coding agents have more power, flexibility, and coding-focused tools than general-purpose chatbots.
Anthropic’s Claude Code and OpenAI’s Codex agents have versions that run in a terminal, IDE extensions, desktop and mobile apps, and other integrations.
R users may also be interested in Posit’s Posit Assistant, which is designed for data analysis in both R and Python. It needs less setup for R than general-purpose coding agents, and it has more built-in knowledge about data science, R package development, and Shiny apps. Plus, it can read objects in your R and Python environments by default, which can be useful in some situations (although perhaps not if you’re working with sensitive data). There are versions of Posit Assistant for RStudio, the Positron IDE, and the terminal. Setup info is here.
Note: Posit Assistant is not the same as the older Positron Assistant that was demo’d at last year’s posit::conf(). The older assistant will eventually be superceded by Posit Assistant. Posit Assistant comes pre-installed with RStudio but not pre-activated, so you don’t need to use it unless you want to.
Google’s original entry in this space, Gemini CLI, is being retired in favor of a new “Antigravity CLI” starting June 18.
There are other IDE platforms with built-in agents, including Cursor and Windsurf, and terminal + subscription coding agents such as Warp, which was open-sourced in April. However, I won’t be covering those here.
You may be limited at work by what your employer allows you to use, but you can still experiment on your own with public data — and then lobby for a new agent if a different one better meets your needs. Whatever you choose, though, moving to one of these from a web-based chatbot should produce better code.
“The shift from chatbot to agent is the most important change in how people use AI since ChatGPT launched,” says Ethan Mollick, co-director of the Wharton School’s Generative AI Labs at the University of Pennsylvania.
Set up CLAUDE.md, AGENTS.md, or GEMINI.md knowledge files
All the major coding agents look for knowledge files to load each time you start a session, and you can easily edit those files. The files can include things like your proficiency in various languages and how you like to document projects. For example, I tell my LLMs that I’d like a README.md in every project with info on how to use the project and technical info on how the project was coded.
Most coding tools let you have both an overarching main file that’s loaded into every session, and an additional file per project.
If you’re adding Claude or Codex to an existing code base, the /init slash command will create one of those .md project files after scanning and analyzing the code. You can also ask an LLM to interview you to create or add to one of those files.
Claude Code looks for a user-level main CLAUDE.md file at ~/.claude/CLAUDE.md and then a project-level file at ./CLAUDE.md or ./.claude/CLAUDE.md. The /memory slash command shows where those files are located. Codex uses AGENTS.md files. Antigravity docs say it looks for a main GEMINI.md file plus GEMINI.md and/or AGENTS.md files in your working directory.
Positron Assistant is set up to read AGENT.md, AGENTS.md, POSITRON.md, CLAUDE.md, GEMINI.md, and LLMS.txt in a workspace root directory, according to the docs. See the Positron docs for more on custom instructions.
Use agent skills
Agent skills can turn an LLM with questionable R knowledge into an expert that understand how you want it to write code. You can develop your own skills, work with your LLM to create skills, or download skills written by others. Claude even has a skill to help you build skills. This is one of the best ways to stop having to repeat the same instructions over and over. Instead, the LLM will “remember” what’s in your skills files by loading them when they’re needed.
What’s the difference between the knowledge .md files mentioned above and a skill? I like to think of CLAUDE.md or AGENTS.md files as important background info that’s always available, while skills are more specific instructions that are useful at certain times. Or, as Claude Opus 4.7 put it: “Skills are for triggered workflows (‘when user asks X, do Y’). A standing rule that applies to every project isn’t trigger-based; it’s a directive I should always follow.” Standing rules should go in CLAUDE.md.
“Create a skill when you keep pasting the same instructions, checklist, or multi-step procedure into chat, or when a section of CLAUDE.md has grown into a procedure rather than a fact,” according to Anthropic’s Claude Code docs. “Unlike CLAUDE.md content, a skill’s body loads only when it’s used, so long reference material costs almost nothing until you need it.” Only skill descriptions are loaded at the start of each session, so the LLM knows what skills are available.
Anthropic originally created skills for Claude in October 2025 and then published the concept as an open standard a couple of months later. Most coding agents now use them.
Anthropic has an easy-to-folllow guide to creating custom skills here if you want to try your hand at building your own.
Posit Assistant comes with several R-related skills built in and allows users to add more. You’ll find them here.
If you’re not using Posit Assistant, you can add Posit-developed skills to another coding agent. Posit published a GitHub repository with skills for creating R packages, Shiny apps, and Quarto documents; for creating and resolving GitHub pull requests; for open-source R and Python package releases; for code reviews (R, Python, JavaScript/TypeScript, SQL); and for creating architectural documentation for a codebase. Browse them all here.
Read and edit the skills you download
Skills are just a folder with one or more markdown text files that have a structured YAML header. That folder can include optional resources and scripts, too. Skill instruction files are easy to read and edit, so you can make sure they do what you want. Tweak them as desired.
For example, Claude helped me write my own customized R skill. Claude leans toward tidyverse packages, but there are other packages I like a lot, too, such data.table. I made sure the R skill knows my package preferences, and under what circumstances I prefer each.
If one of your preferred procedures changes, remember to update the associated skills. Or, ask an LLM to update it for you. Keeping skills up to date will make your coding agent more useful.
Keep your CLAUDE.md or AGENTS.md files updated, too. Maybe you started off with a CLAUDE.md file that said you’re an experienced Python programmer who is just learning R. Three months from now, you might want to update your R skill level. Or, perhaps you told an AGENTS.md file that you like thoroughly documented code, but now you’d prefer a lighter touch. You may want to have your coding agent go over those files with you from time to time and ask you about the main points and whether they need updating.
Use the btw R package and its MCP server
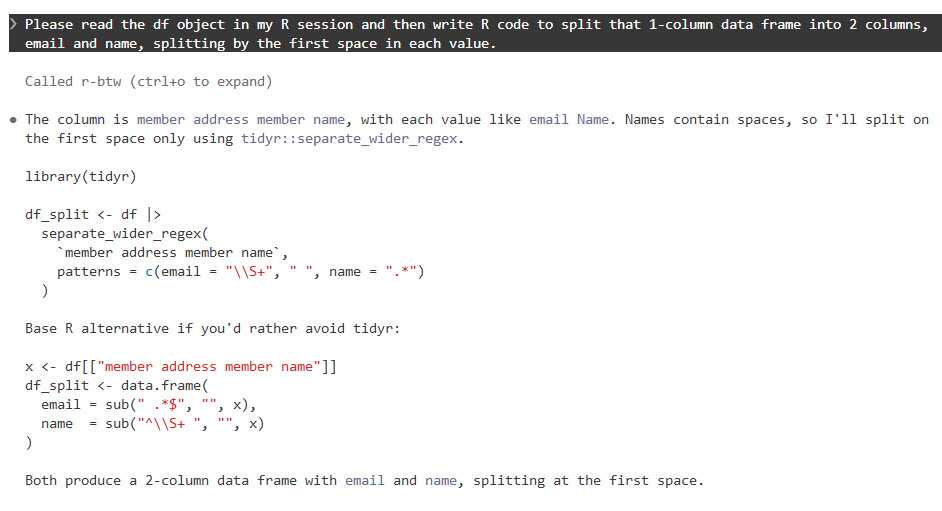
It’s frustrating when an LLM writes code based on an ancient R package version in its training data, or when it doesn’t know about a relatively recent package at all. btw solves this problem by letting your coding agent access info about all the R packages installed on your system. That means it can write code based on your specific R environment. Plus, btw lets an LLM access variables in your current R environment via a Model Context Protocol (MCP) server.
MCP servers are a standardized way for LLMs to access external data — in this case, your running R session (external doesn’t have to mean cloud). Like skills, MCP was created by Anthropic as an open standard and has since been adopted by most major AI platforms. The btw R package includes an MCP server, which you can install for Claude Code by running the following code in a terminal window (not R console).
claude mcp add -s "user" r-btw -- Rscript -e "btw::btw_mcp_server()"
btw comes with a lot of tools. It’s not a great idea to overload your LLM with tools it may never use. If you just want to register btw tools for accessing your R session and looking up package documentation, you can run a command like this instead:
To connect Claude Code to your open R session, you also need to run btw::btw_mcp_session()in every new R session. (I sometimes forget this part until I’m puzzled why Claude can’t read my R variables or even see what packages I have installed.)
You can see a demo of btw in this Posit video that compares Claude Code and Posit Assistant.
The btw R package lets Claude Code and other agents read objects in your R session.
Foundry
You don’t need to do this setup for Posit Assistant, since tools for accessing your R session and variables are built in.
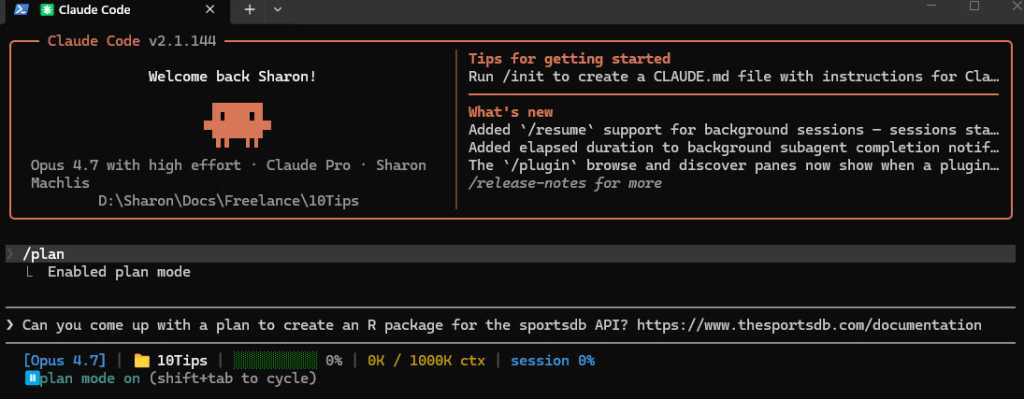
Use plan mode for your projects
I cannot stress this enough. Just as humans benefit from having a plan before starting to implement a project, LLMs benefit from working through a plan before beginning to generate code. Plus, it can be useful at times to “brainstorm” with an LLM about structures and features, ask it for alternatives, or even have another LLM review a plan before implementing it.
Anthropic advises starting with plan mode. “Letting Claude jump straight to coding can produce code that solves the wrong problem. Use plan mode to separate exploration from execution,” they wrote in a best practices doc.
Claude, Codex, Gemini, and Posit Assistant all have a plan mode in their CLI versions that can be activated with the /plan slash command.
Foundry
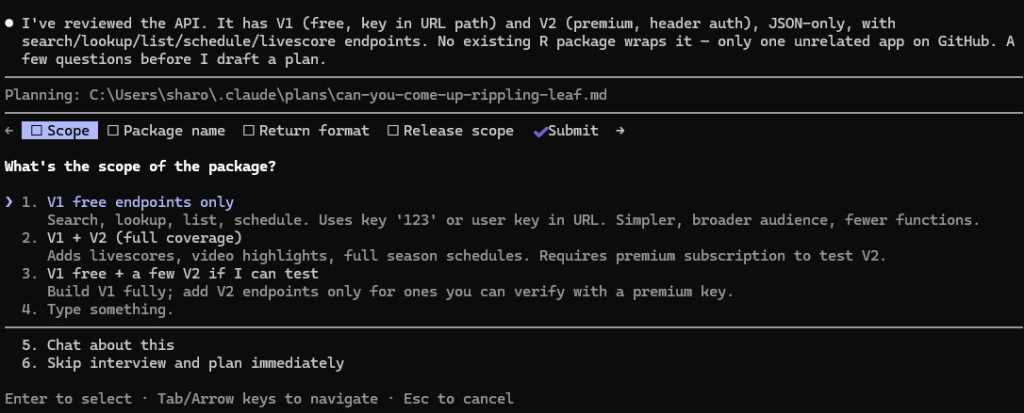
When in plan mode activated with /plan, Claude will often ask questions before coming up with its plan.
Foundry
Make sure your coding agent learns from its mistakes
This is one of the best tips I read first from Joe Amditis, associate director of operations at the Center for Cooperative Media at Montclair State University: If your coding agent makes a mistake and you work together to fix it, make sure to save that memory so it doesn’t make the same error again.
Your agent may have an auto memory system that’s supposed to do some of this (I’ve used Claude Code’s), but you can instruct any coding agent to keep a separate lessons learned file for each project, too, or ask it what’s the best way to ensure it doesn’t make the same error again. This isn’t a guarantee, any more than you can be assured an LLM will follow all the rules in a CLAUDE.md or AGENTS.md file or all the steps in a skill. But it has definitely cut down on my agents making the same errors over and over.
Have your agent write tests and do code reviews
Tests and code reviews done by a coding agent aren’t a substitute for a human checking that software works. Review an LLM’s results yourself any time a task is important! However, agent-generated tests are still a good way to head off some problems and cut down the time you spend as your LLM’s debugging partner. If you don’t know where to start to help your agent know how to test and review code, see Posit’s testing-r-packages and critical-code-reviewer skills. Your agent may also have built-in code review skills, such as Claude Code’s /code-review slash command.
Code review skills are available from many sources. For example, Sentry has a code review skill in its repository. Aimed specifically at its project’s needs, it can be a useful sample for similar skills. And superpowers is a popular set of general-purpose programming skills that’s billed as “a complete software development methodology for your coding agents, built on top of a set of composable skills and some initial instructions that make sure your agent uses them.” I don’t use superpowers, but a lot of other people clearly do given its more than 227,000 GitHub stars and 20,000 forks.
Another tip: Several experts suggest using a different LLM — maybe even from a different provider — to conduct a code review, since each model has its own strengths and weaknesses.
Don’t forget general prompting good habits
Whatever programming language you’re using, being clear will improve your outputs. Keep your requests targeted, and don’t expect the LLM to read your mind.
“Codex handles complex work better when you break it into smaller, focused steps,” OpenAI says in its developer docs. “Smaller tasks are easier for Codex to test and for you to review. If you’re not sure how to split a task up, ask Codex to propose a plan.”
“Take time to make your prompts as relevant as possible, just as you would when helping a new teammate scope a task,” Google advises in its Five Best Practices for Using AI Coding Assistants. “Consider what details you need to share for a person to succeed, and provide all those details to your AI tool.”
And, don’t load up your context window to the LLM’s published limit. Performance often degrades as you get close to the maximum token limit.
Take advantage of open LLMs, particularly if you have budget and token limits
Open-weight models — especially ones small enough to run on a desktop computer — may never rival frontier LLMs like Claude, GPT, or Gemini. But for a lot of R coding, they don’t need to.
To see how well an LLM can write R code, it should have the same kind of harness that Claude Code, Codex, or Posit Assistant gives larger LLMs. “The harness is the product,” argues Mallory Mejias at Sidecar, an AI education company. “The model is the engine inside it — important, but increasingly interchangeable.” I wouldn’t go that far, since I still find the LLM to be a critical piece of this equation, and models differ. But the same LLM will perform differently depending on the tools and context it has.
Posit recently added Google’s open-source Gemma 4 26B to Assistant’s existing options of larger, closed-source LLMs. “Up until this point, models of this size — small enough to run comfortably on high-end consumer laptops — were on our radar but not yet capable enough to drive an agent harness like Posit Assistant,” Posit senior software engineer Simon Couch wrote on the Posit blog. “This has changed in the last few months with releases like Gemma 4.” However, to use it in Posit Assistant in RStudio, you still need to run it through a Posit AI subscription, not locally. It uses 1/10 the budget that the same session with Claude Sonnet would consume.
Several projects can use Claude Code to run local LLMs. Ollama, open-source software for running LLMs locally, does this with the terminal command ollama launch claude --model , such as:
ollama launch claude --model gemma4:26b
The makers of Unsloth, an open-source framework for running and training models, say running local LLMs inside Claude Code can be very slow due to a cache invalidation issue. They say this can be fixed by adding "CLAUDE_CODE_ATTRIBUTION_HEADER" : "0" to ~/.claude/settings.json under “env”.
Unsloth can also use Claude Code to run local models, but it’s somewhat more involved to install and set up than Ollama. See this Unsloth tutorial.
Open-source coding agent Open Code runs LLMs from OpenAI, Anthropic, Google, Kimi, Alibaba’s Qwen, and others. I haven’t warmed up to it yet compared with commercially backed CLI tools I’ve tried, but it has 174,000 GitHub stars so clearly a lot of fans.
AI consultant Thomas Wiegold, who switched from Claude to Open Code, said “OpenCode covers everything I need for my daily workflow. It’s fast, the provider flexibility is genuinely useful rather than theoretical, and the TUI is better for extended sessions…. That said, I’m not going to pretend it’s all smooth sailing.” He noted some stability issues and a remote code execution vulnerability earlier this year.
Large language models remain imperfect and unpredictable tools, but they’re improving rapidly — as are the harnesses around them. Even frontier LLMs in commercial coding agents can ignore instructions at times and otherwise behave in unpleasantly surprising ways. However, you’ll vastly improve your chances of generating quality code if you use coding agents, take time to set them up with quality instructions, and remember good prompting techniques. Good luck!
—
Coding agent info
Claude Code – Anthropic’s coding agent is available in the terminal and as an IDE extension, a desktop app, mobile apps, Slack app, and a cloud version that can work directly in your repos on GitHub. Arguably the first breakthrough coding agent, it now includes an elegant remote-control option where you can start a session on your desktop and then continue it on a phone or tablet. While designed for Claude LLMs, you can use it to run local LLMs via tools like Ollama or Unsloth Studio. When using Claude models, it tends to offer less usage than other vendors’ options. Anthropic has posted the terminal version’s code on GitHub, with usage governed by Anthropic’s commercial terms of service. You can use Claude Code via API pay per use or as part of a Claude subscription.
Codex – OpenAI’s answer to Claude Code is available via terminal, app, IDE extension, or cloud, with integrations for GitHub, Slack, and Linear. The CLI tool is open source under an Apache license, available on GitHub, and works via API pay per use or as part of a ChatGPT subscription.
Posit Assistant – The Posit (formerly RStudio) coding agent is designed for data work in R and Python, although Posit senior software engineer Simon Couch told me it would do fine for programming work for other uses and in other languages. It is available for the RStudio IDE (via a Posit AI subscription in RStudio), Positron IDE, and as a stand-alone CLI terminal app, although the CLI tool currently doesn’t feel as full-featured as the IDE integrations (that may change). As of this writing, you can also use API keys from Anthropic, OpenAI, and Snowflake Cortex and a GitHub Copilot account in Positron. Posit Assistant is being updated quite frequenty, Couch told me. If you tested it a month or two ago, it has more capabilities now.
Antigravity CLI – Google’s terminal-based tool will be replacing the Gemini CLI for unpaid and Google One users this month. There’s also an Antigravity IDE, SDK, and platform for orchestrating multiple agents. One advantage of Antigravity: Google offers a free plan with access to Gemini 3.5 Flash, Gemini 3.1 Pro, Gemini 3 Flash, Claude Sonnet 4.6, Claude Opus 4.6, and gpt-oss-120b, and what it describes as “generous” but undefined weekly rate limits based on “the degree we have capacity.”
In a groundbreaking advancement that bridges the gap between biological intelligence and artificial systems, researchers at Oregon State University have engineered a light-sensitive device that not only detects visual stimuli but also bio-mimics the brain’s ability to store and modulate memories dynamically. Drawing direct inspiration from the complex workings of human neural processes, this pioneering approach integrates sensing, memory, and signal processing into a single phototransistor, a feat poised to revolutionize the future of neuromorphic computing.
Traditional artificial intelligence hardware architectures typically bifurcate these essential functions—detection, memory retention, and processing—forcing data to shuttle between distinct components. This separation not only introduces latency but significantly amplifies energy consumption. The novel phototransistor developed by the OSU team disrupts this paradigm by embedding memory capabilities precisely where sensory inputs occur, vastly improving computational efficiency and speed.
Central to this device’s innovation is its ability to mimic the neurochemical processes governing memory strength and decay in the human brain. Rather than storing information with fixed permanence, the phototransistor utilizes trapped electrical charges generated by incident light to represent memories, which can then be pharmacologically tuned—via electrical gate voltages—to either reinforce or weaken these stored traces over time. This dynamic modulation reproduces the adaptive nature of biological synapses and opens unprecedented avenues for creating AI systems that can ‘forget’ as well as ‘remember,’ essential for real-time learning and adaptation.
Structurally, the device marries an oxide semiconductor acting as the electronic transistor channel with an organic photosensitive layer responsible for absorbing photons and generating charge carriers. The organic layer traps a subset of these carriers, creating a persistent local electric field even after illumination ceases. This trapped charge influences electron flow through the semiconductor channel, effectively encoding a memory of prior light exposure.
A key technical breakthrough lies in the device’s gate-tunable interface: by adjusting the voltage applied to the transistor’s gate terminal, researchers can manipulate the spatial positioning of trapped charges relative to the conduction channel at a nanoscopic level. This precise control modulates the strength of electrical interaction, allowing for programmable decay times of the optoelectronic memory—ranging from seconds to considerably longer durations. Such flexibility is vital for neuromorphic systems requiring adjustable time constants for processing temporal patterns.
The implications of this technology extend beyond simple visual sensing. By localizing both sensing and adaptive memory functions, the phototransistor can serve as a foundational building block for advanced vision systems capable of real-time data processing with exceptional energy efficiency. This novel hardware approach offers substantial improvements over conventional sensors, which often offload processing to centralized units, incurring latency and energy penalties.
Neuromorphic computing, a field striving to emulate the architecture and operational principles of the brain, stands to gain significantly from this development. The device’s capacity to embody synapse-like plasticity within a phototransistor embodies a leap toward systems that do not merely compute but adapt, learn, and optimize autonomously. Furthermore, the integration of these functionalities at the hardware level paves the way for compact, scalable AI platforms potentially transformative for robotics, autonomous vehicles, and sensory-rich IoT devices.
The research team acknowledges that the trapped charges’ mobility within the device’s photosensitive layer marks a fundamental departure from fixed-charge memory devices. By enabling charge repositioning in response to externally applied voltages, the phototransistor achieves an unprecedented degree of control over memory retention timescales—a property rarely realized in optoelectronic components designed for AI applications.
From an energy perspective, co-localizing sensing and computation reduces data transfer bottlenecks traditionally plaguing AI processors. This attribute directly addresses pressing challenges in AI hardware, where escalating computational demands often collide with limitations in battery life and thermal management. As a result, the novel phototransistor aligns with broader efforts to develop sustainable, high-performance AI technologies.
Conceived through a multidisciplinary collaboration spanning electrical engineering and physical sciences at Oregon State University, the device’s development also underscores the growing convergence of materials science with computational intelligence. By synergizing metal oxide semiconductors with organic tetracene compounds, the team harnessed complementary material properties—robust electron transport with efficient light absorption—to realize the device’s multifunctional capabilities.
The National Science Foundation’s support, alongside the efforts of researchers including Larry Cheng, Ahasan Ullah, Tasnim Sarker, Xueqiao Zhang, Andrew Ensinger, Lizhong Chen, Roshell Lamug, and Oksana Ostroverkhova, culminated in the publication of their findings in the esteemed journal Advanced Functional Materials. The study not only charts new territory in optoelectronics but also sets the stage for transformative innovation in neuromorphic computing hardware.
As artificial intelligence increasingly demands systems capable of real-world adaptability and resource efficiency, innovations like this gate-tunable neuro-phototransistor epitomize the direction forward. By drawing directly from the brain’s principles of memory modulation and energy-efficient computation, the OSU team’s technology heralds a new era where AI devices can perceive, process, and remember in ways that approximate human cognition more closely than ever before.
Subject of Research: Not applicable
Article Title: Neuromodulator-Inspired Gate-Tunable Tetracene–Metal Oxide Phototransistor for Adaptive Optoelectronic Memory and Neuromorphic Computing
In a breakthrough that could reshape the future of sustainable materials and energy production, researchers at the University of Pittsburgh’s Swanson School of Engineering have unveiled a revolutionary method of producing high-quality graphite at significantly lower temperatures than those traditionally required. The pivotal discovery emerged unexpectedly in the laboratory of Professor Götz Veser, where ethane was pumped through molten metal heated to under 1,000 degrees Celsius. Contrary to expectations, the carbon byproduct that surfaced was not the usual mundane residue but a fluffy, high-grade graphite, a material that has become a cornerstone in advanced battery technologies.
Graphite, often hailed as “black gold,” particularly in contexts involving automotive and high-tech sectors, is indispensable for lithium-ion batteries that power electric vehicles and modern electronics. Currently, the industrial synthesis of such graphite is a notoriously energy-heavy process necessitating temperatures approaching 3,000 degrees Celsius. Moreover, the global supply chain is heavily dependent on China, which accounts for some 95 percent of battery-grade graphite production. This dependency presents significant challenges in energy efficiency, sustainability, and geopolitical autonomy.
The Pittsburgh team, led by Professor Veser and former PhD candidate Aime Laurent Twizerimana, along with Assistant Professor Mohammad Masnadi and PhD student Nader Sawtarie, recognized the urgent need for an energy-efficient and domestically viable alternative. Their research harnessed an underexplored catalytic method involving molten metals, a concept that traces its roots back nearly a century but remained largely unexploited in this context. Unlike conventional solid catalysts, molten metal catalysts offer a unique physical characteristic: their extreme density causes carbon to separate and float atop the molten medium, simplifying collection and preventing reactor clogging.
The process began as an effort to develop greener pathways for ethylene production by “cracking” ethane, a major component of natural gas abundant in Western Pennsylvania. Ethane cracking conventionally involves steam reforming, a technique plagued by continuous formation of carbon deposits that necessitate frequent shutdowns for maintenance. However, the molten metal catalysis technique demonstrated a cleaner and more efficient alternative, reducing energy input while producing valuable byproducts.
As Twizerimana delved deeper into his doctoral research, he noticed a curious variation in carbon morphology when different metals were employed. Some metals yielded a fluffy, distinct carbon arrangement rather than the dense deposits typically associated with ethane cracking. This observation spurred further analysis by Sawtarie, whose expertise in two-dimensional metals and graphene characterization was instrumental. Their collaboration revealed that this fluffy substance was, in fact, high-value graphite, matching or exceeding quality standards for battery applications.
This discovery not only offers a lower-temperature route for graphite synthesis but simultaneously generates hydrogen as a co-product. Hydrogen, widely recognized as a clean energy vector, complements the sustainability credentials of this novel process by providing an additional revenue stream and reducing reliance on fossil-fuel-based hydrogen production methods.
Revolutionizing a process that typically demands prolonged batch operations at scorching temperatures—often taking up to three weeks—this new method offers a continuous, scalable approach that could dramatically reduce carbon emissions and costs. While small-scale graphite production in the United States exists, it remains economically uncompetitive compared to Chinese imports. The Pittsburgh innovation aims to close this gap by delivering domestic, scalable, and cost-effective graphite synthesis.
Supported by the University of Pittsburgh’s Big Idea Center, which provides vital mentorship and resources for entrepreneurial ventures, the research team transitioned their laboratory success into a startup named Graphonos Materials. The startup’s disruptive technology captured the imagination of investors and judges alike, securing a $20,000 Aramco Innovator Prize at the prestigious Rice Business Plan Competition—an event often dubbed the “Super Bowl” of entrepreneurial pitch contests.
Beyond financial endorsements, these achievements underscore the market’s clear appetite for sustainable, low-cost graphite and the critical role such materials play in the clean energy transition. The team is currently advancing toward developing a fully integrated bench-scale system capable of producing kilograms of graphite per day. This milestone is a crucial stepping stone toward pilot-scale demonstrations and eventual commercialization, aligning with global efforts to localize critical materials supply chains and innovate energy-efficient manufacturing.
If realized at scale, the process promises dual environmental and economic benefits by transforming Western Pennsylvania’s ethane reserves into essential raw materials that undergird electric vehicles, renewable energy storage, and advanced electronics. It embodies a strategic pivot from traditional fossil fuel processing to value-added chemical production within a circular economy framework, contributing meaningfully to energy transition narratives.
As the demand for lithium-ion batteries accelerates worldwide, fueled by electrification policies and consumer preferences, the importance of sustainable graphite synthesis cannot be overstated. The Pittsburgh innovation leverages unique catalytic chemistry and materials science to disrupt entrenched production paradigms marked by extreme energy consumption and geopolitical bottlenecks.
Ultimately, this development is emblematic of how interdisciplinary research—melding chemical engineering, materials science, and entrepreneurship—can yield tangible solutions to pressing global challenges. By capturing the potential of molten metal catalysis, the Graphonos Materials team paves the way for greener, domestic production pathways that harmonize economic competitiveness with environmental stewardship.
Subject of Research:
Advanced molten metal catalytic process for low-temperature synthesis of battery-grade graphite and hydrogen co-production.
Article Title:
University of Pittsburgh Researchers Innovate Low-Temperature Molten Metal Catalysis to Produce Sustainable Battery-Grade Graphite
News Publication Date:
April 2024
Web References:
University of Pittsburgh Swanson School of Engineering Faculty Pages
In recent years, the global medical community has observed an alarming rise in the incidence of congenital hypothyroidism (CH), a condition characterized by insufficient thyroid hormone production in newborns. This endocrine disorder, if undiagnosed or untreated, can lead to profound developmental delays and intellectual disabilities. Against this backdrop, a landmark study published in Pediatric Research sheds new light on the long-term administration and cessation patterns of levothyroxine—a synthetic thyroid hormone replacement—in patients assumed to have CH. This nationwide cohort investigation, spanning over a decade, provides unprecedented insights into treatment paradigms and patient management on a population scale.
The study meticulously tracked levothyroxine usage across a broad demographic, encompassing thousands of newborns clinically suspected of congenital hypothyroidism. Using comprehensive health databases, researchers were able to delineate initiation rates, dosage adjustments, duration of therapy, and the critical junctures at which discontinuation occurs. They highlight how early diagnosis, often through neonatal screening programs, has revolutionized patient outcomes but also raised new questions regarding optimal treatment length and criteria for safely discontinuing therapy.
One of the foundational aspects explored in this investigation is the temporal trend of levothyroxine initiation. The data convincingly demonstrate a marked increase in the frequency of diagnoses and subsequent treatment initiation over the 10-year observation period. This escalation aligns with heightened screening sensitivity and revised diagnostic thresholds, suggesting that what was once considered atypical or borderline hypothyroidism is now more frequently targeted for intervention. Such shifts bring about complex clinical decisions around the balance between necessary hormone supplementation and potential overtreatment.
In delineating the course of levothyroxine administration, the study underscores that a significant subset of patients undergoes treatment discontinuation, reflecting evolving clinical judgments based on follow-up evaluations. These discontinuations often result from confirmatory testing that challenges the initial diagnosis or reveals transient hypothyroidism, a condition that resolves spontaneously without lifelong hormone dependency. Understanding when and how to discontinue therapy safely remains a cornerstone in preventing unnecessary treatment burden and its accompanying risks.
Moreover, the investigation probes into the demographic and clinical determinants influencing levothyroxine discontinuation. Variables such as age at diagnosis, initial thyroid function test results, and the presence of thyroid dysgenesis or dyshormonogenesis significantly sway therapeutic decisions. The study’s granular stratification reveals that patients with milder biochemical abnormalities or transient hypothyroidism are more likely to cease treatment within the first few years of life, emphasizing the importance of individualized care pathways.
Intriguingly, the analysis also touches upon the challenges in differentiating permanent congenital hypothyroidism from transient cases during the neonatal period. These diagnostic ambiguities are amplified by biochemical fluctuations, maternal thyroid conditions, and environmental factors such as exposure to iodine or goitrogens. The study’s extensive dataset allows for a nuanced understanding of these confounders, paving the way for refined diagnostic algorithms and personalized monitoring protocols.
The ramifications of sustained levothyroxine therapy extend beyond hormone replacement; they encompass metabolic, cardiovascular, and neurodevelopmental domains, especially if treatment is misaligned with the patient’s true thyroid status. Over-replacement can lead to iatrogenic thyrotoxicosis, while under-treatment perpetuates hypothyroid sequelae. This cohort study underscores the imperative for vigilant clinical and biochemical monitoring, leveraging advances in assay technologies and genetic profiling to tailor interventions precisely.
From a public health perspective, the rising levothyroxine use in presumed CH presents implications for healthcare resource allocation, long-term follow-up infrastructure, and parental counseling. National screening programs must adapt to integrate not only early detection but also robust tracking systems that ascertain treatment necessity, effectiveness, and safety over time. This study’s nationwide scope lends critical data to guide policy refinements and equity considerations in thyroid disease management.
Furthermore, the researchers advocate for a paradigm shift towards dynamic therapeutic frameworks, where treatment initiation is complemented by scheduled re-evaluations to determine the persistence of hypothyroidism. By promoting trial discontinuations under strict supervision, clinicians can limit unnecessary exposure to levothyroxine, thereby mitigating potential adverse effects and preserving health system sustainability.
Equally important, the study highlights gaps in current clinical guidelines, which often lack consensus on precise criteria for levothyroxine cessation. These ambiguities contribute to variability in practice and patient outcomes. The authors call for concerted efforts among endocrinologists, neonatologists, and healthcare policymakers to develop evidence-based protocols informed by longitudinal data such as theirs.
In terms of methodology, the utilization of expansive health claims and prescription data validates the reliability and real-world applicability of the findings. The analytical approach, employing survival analysis and multivariate regression modeling, unravels complex patterns of drug utilization and discontinuation, while adjusting for confounding factors. This rigorous epidemiological framework sets a benchmark for future pharmacoepidemiological research in pediatric endocrinology.
It is also noteworthy that the study addresses psychosocial dimensions indirectly, recognizing that parents and caregivers play pivotal roles in adherence and decision-making regarding levothyroxine therapy. Long-term treatment regimens can strain families emotionally and financially, underscoring the need for supportive care models and transparent communication strategies.
The implications of the rising incidence of CH—and correspondingly, levothyroxine use—also evoke considerations about environmental and genetic influences driving this trend. Although not the primary focus, the comprehensive data collected may inspire ancillary investigations into prenatal exposures, epigenetic modifications, and population-based genetic predispositions contributing to this public health challenge.
Ultimately, this landmark investigation by Kim, Woo, Lee, and colleagues portrays a nuanced portrait of levothyroxine use in presumed congenital hypothyroidism, emphasizing the dual imperatives of timely treatment and judicious discontinuation. Their ten-year nationwide cohort analysis unearths critical trends that will undoubtedly inform clinical practice, guideline development, and health policy designed to optimize outcomes for affected infants and children worldwide.
As pediatric endocrinology advances, the insights gleaned from this study serve as a timely reminder of the complexity underlying ostensibly straightforward diagnoses. The nuanced interplay between biochemical parameters, diagnostic certainty, patient heterogeneity, and long-term treatment strategies requires clinicians to balance evidence-based medicine with individualized care. This study not only contributes pivotal epidemiological evidence but also catalyzes a re-examination of management philosophies in congenital hypothyroidism.
In conclusion, the increasing incidence of congenital hypothyroidism and the corresponding escalation in levothyroxine use illuminate a critical area for continued research and healthcare innovation. The ten-year nationwide cohort study effectively captures the evolving landscape of diagnosis, treatment, and discontinuation, reinforcing the need for integrated multidisciplinary approaches. By fostering personalized medicine approaches grounded in large-scale data analysis, healthcare systems can aspire toward improved thyroid health in newborns and beyond.
Subject of Research: Use and discontinuation patterns of levothyroxine treatment in patients with presumed congenital hypothyroidism over ten years in a nationwide cohort.
Article Title: Levothyroxine use and discontinuation in presumed congenital hypothyroidism: a 10-year nationwide cohort study.
Article References:
Kim, S.Y., Woo, H.A., Lee, E.H. et al. Levothyroxine use and discontinuation in presumed congenital hypothyroidism: a 10-year nationwide cohort study. Pediatr Res (2026). https://doi.org/10.1038/s41390-026-05153-7
The global shift toward net-zero emissions has thrust hydrogen into the spotlight as a promising energy vector capable of decarbonizing sectors traditionally reliant on fossil fuels. Yet, as hydrogen technologies surge from concept to commercial reality, a critical question has emerged: can the insurance industry keep pace with the novel risks intrinsic to these systems? A compelling new article published in Engineering unveils the stark challenge facing insurers and innovators alike. It argues that the nascent nature of hydrogen processes and infrastructures presents a complex risk landscape that current insurance frameworks are ill-equipped to navigate, potentially impeding large-scale deployment needed to meet climate goals.
Central to the discourse is the intricate, multifaceted nature of hydrogen technologies, encompassing production, storage, transport, and utilization systems. Unlike mature renewable technologies such as wind and solar, hydrogen operations are fraught with unique hazards—including extreme flammability, material embrittlement due to hydrogen exposure, and elusive leakage risks—that conventional insurance models have yet to thoroughly address. This gap in risk assessment and management means that financial security mechanisms crucial for investment confidence remain underdeveloped, posing a significant barrier to scalable hydrogen adoption.
The article elucidates that hydrogen’s promise as a clean energy carrier depends not only on decarbonized production but also on scaling the entire value chain rapidly and reliably. However, these pioneering engineering systems entail a gamut of evolving operational risks. These span from property damages and equipment failures to worker safety concerns heightened by hydrogen’s explosive potential. Cybersecurity risks also arise given the increasing digitalization of energy assets, while governance challenges manifest through liability exposures of company directors as projects push technical boundaries. Furthermore, these uncertainties extend into supply chain fragility and performance shortfalls during system ramp-up phases, compounding insurers’ difficulties in crafting comprehensive coverage.
Drawing a parallel to renewable energy insurance markets, the authors observe how wind and solar have benefited from years of data accumulation, modeling refinement, and standardization efforts that underpin sophisticated insurance offerings. This data-driven maturation enables parametric insurance and warranties that safeguard against specific performance metrics and supply chain disruptions. Yet, hydrogen insurance remains embryonic, characterized by cautious underwriting and limited products chiefly targeted at niche applications rather than broad industrial deployment. This immaturity translates to cost premiums and coverage limitations that stall financing and project momentum.
To transcend these hurdles, the article emphasizes the critical need for structured data collection and robust risk characterization specific to hydrogen processes. Without granular operational insights and validated risk models, insurers default to conservative stances that restrict underwriting appetite. The authors champion innovative insurance instruments, notably parametric policies calibrated to predefined risk triggers, and performance warranties that hedge against technology underperformance. These solutions can lower uncertainty for investors and catalyze capital flow, but their success hinges on collaborative data-sharing and transparent risk communication between all stakeholders.
Importantly, the narrative draws attention to a strategic opportunity for insurers. Engagement with hydrogen not only mitigates climate-related portfolio risks but also opens access to a burgeoning industrial market driven by global net-zero ambitions. Nonetheless, disconnects persist between technology developers’ needs and insurers’ capabilities, underscoring the urgency for proactive, multi-stakeholder dialogue. Fostering early-stage collaboration among engineers, academia, private sector, and insurance providers is pivotal to co-design risk assessment methodologies, standardize certification regimes, and ultimately align insurance solutions with engineering innovation trails.
Academia is positioned as a critical catalyst in this ecosystem. Researchers can bridge the gap by aggregating operational data, refining risk models via simulations and real-world studies, and facilitating standardization efforts that underpin insurer confidence. Such integrative efforts advance both scientific understanding and commercial viability. Aligning insurance mechanisms with engineering innovation timelines ensures risk management is embedded from technology readiness level milestones onward, thus streamlining the pathway from pilot projects to full-scale industrial rollouts.
The article also highlights the financial repercussions of currently inadequate insurance coverage. High premiums and coverage gaps retard investment flows and engender hesitancy among financiers wary of unquantified risks. As hydrogen projects are capital-intensive with long development horizons, risk mitigation via comprehensive insurance is non-negotiable for unlocking broader investor appetite. Hence, the advancement of hydrogen insurance products is not merely a financial instrument but a keystone for sustainable market adoption and technological acceleration.
Furthermore, the article delves into technical challenges such as hydrogen’s propensity to induce embrittlement in metals, which degrades structural integrity over time and raises maintenance costs. Insurance models must incorporate such materials science insights to accurately price and cover long-term durability risks. Leakage detection and mitigation technologies also play a vital role in controlling operational hazards, with insurance frameworks incentivizing advancements in sensor deployment and safety protocols. These technological synergies between engineering and insurance amplify resilience and facilitate risk reduction.
In conclusion, the article contends that unlocking hydrogen’s potential as a linchpin of a net-zero future demands a paradigm shift in insurance thinking coupled with systemic collaboration. By gathering rigorous data, designing bespoke risk instruments, and fostering cross-sector partnerships, the insurance market can evolve to support hydrogen innovation robustly. This evolution will serve as the linchpin of investor confidence, enabling swift scale-up while safeguarding public and environmental safety. Without such advancements, the hydrogen economy risks stalling, imperiling global decarbonization trajectories.
The implications extend beyond risk transfer to the very architecture of hydrogen energy systems. Insurance integration informs engineering decisions, safety standards, and policy frameworks, creating a virtuous cycle that harmonizes technical innovation with financial viability. The authors’ clarion call is clear: accelerating the hydrogen transition mandates bridging the gap between emergent technology risks and insurance market readiness. Achieving this nexus will be transformative—not only for hydrogen but for the broader energy transition imperative writ large.
Subject of Research: Insurance frameworks and risk management for new hydrogen technologies and adapted hydrogen processes.
Article Title: Insurance for New and Adapted Hydrogen Processes
Drew Baglino spent nearly two decades building Tesla’s batteries, motors, and power electronics. Now the former Tesla SVP is quietly building the one home energy product Tesla talked up for years and never shipped: a residential heat pump.
His startup, Sadi Thermal Machines, is a direct bet on an idea Tesla floated openly in 2022 — before the company reoriented itself around humanoid robots and robotaxis.
A l’occasion des 50 ans de la loi L214 sur le bien-être animal, l’association éponyme a publié un rapport sur l’évolution et les enjeux des pratiques d’élevage en France. Brigitte Gothière, directrice et cofondatrice du groupe, a répondu à Sciences et Avenir. Elle souligne la multiplication de ces structures, la course à la production, et évoque des mesures pour sortir de ce modèle alimentaire.
Dans le lagon de Mayotte, chaque battement d’aileron raconte une histoire ancienne. Tortues centenaires, dauphins résidents et coraux architectes y composent un écosystème d’une précision presque scientifique, mais d’une beauté profondément poétique. Ici, la vie sous-marine semble respirer au...
Le dispositif Caniscol permet à des enfants en difficulté de lecture de lire en compagnie d’un chien, dans un cadre bienveillant et sans pression, loin des évaluations scolaires. Cette approche les aide à prendre confiance en eux, à mieux gérer leurs émotions et découvrir leur potentiel...
Sur l’île Sainte-Marguerite, écrin de verdure posé sur la Méditerranée face à Cannes, la cellule du Masque de Fer rappelle l’histoire d’un prisonnier dont l’identité reste l’un des plus grands mystères du royaume de France.
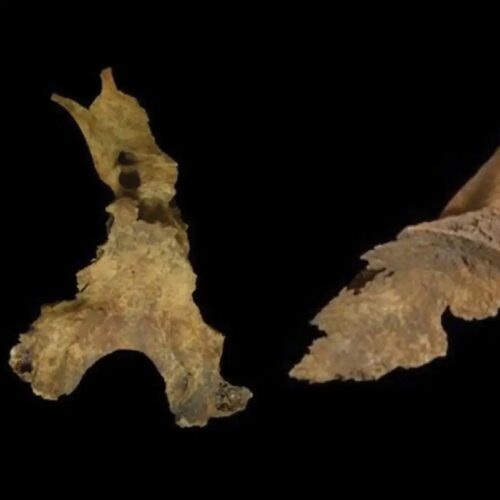
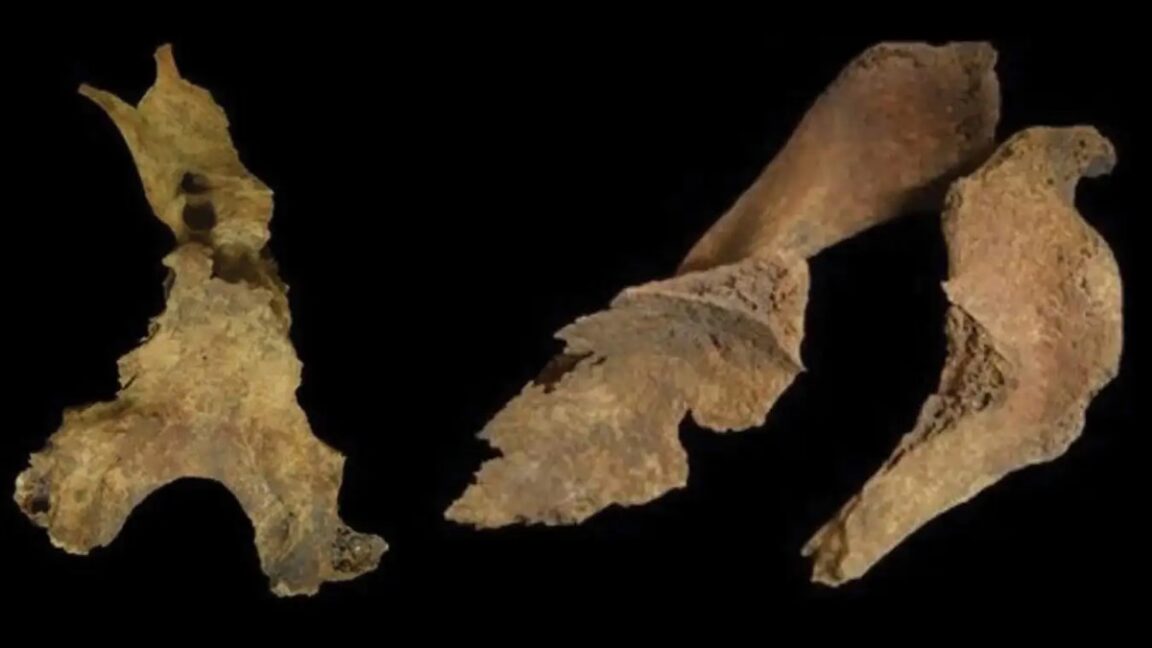
Archaeologists say bones unearthed from an Iron Ageburial in Scotland are revealing new insights into how human remains were interred in ancient Europe, in a region with scant evidence for mortuary practices in the archeological record.
Among the new findings, cuts within the skull of a woman’s 2,000-year-oldIron Age remains suggest the removal of her brain prior to burial, along with other evidence of mortuary processing.
“Manipulation of one skeleton, including the possible removal of the brain, fashioning of long bones into ‘tools’ and reassembly for burial, suggests complex mortuary processing,” write the authors of a new study published in the journal Antiquity.
Iron Age Remains
The study’s authors report that the woman’s remains, and those believed to have belonged to a teenage boy buried nearby, both had distant origins, adding to the intrigue. Archaeologists discovered the pair buried in a cairn in Sutherland’s Loch Borralie in northwest Scotland, a rare find in such well-preserved condition.
Due to Britain’s acidic peat soil, few Iron Age human remains have been recovered, leaving many questions about the inhabitants’ funerary practices. This particular corner of Scotland is an exception, with an environment better suited to preserving bone, offering a rare window into this mysterious period.
“To find bodies of this age so well preserved is rare, but to discover evidence of a funeral ritual we previously knew nothing about was such a surprise and very exciting,” said lead author Dr. Laura Castells Navarro.
Unusual Mortuary Practices
“The adult female displayed incisions on the inside of her cranium, suggesting her brain had been intentionally removed after death,” Castells Navarro continued. “We have no other comparison of this type of practice, but we know that the dead were curated and treated carefully in Iron Age Britain, so our understanding is that this bone modification is within that same tradition of care.”
The sharpened bones, which the archeologists suspected were used as tools, included humeri, ulna, and femur. Why Iron Age Britons would have engaged in such elaborate and unusual manipulation of skeletal remains eludes archaeologists, although they note that the care evident in reassembling her skeleton for burial suggests she commanded the respect and reverence of those who laid her to rest.
Analysis techniques used on the bones include isotope testing and DNA mapping, revealing a close kinship suspected to be that of maternal second cousins.
Iron Age Connections
More intriguing than their relationship is the evidence of the distance they had traveled, as isotopic analysis revealed that the pair had grown up 50 miles to the southeast. Genetics pushed this even further, revealing family connections beyond the mainland, spreading out in opposite directions. To the northeast, they had relatives 108 miles away on the Orkney Islands, while to the southwest, they had kin 140 miles away at Applecross.
Archaeologists interpret this to mean that Iron Age Britons were extremely mobile, traversing water in family groups.
“Our research shows that prehistoric maritime communities periodically moved around the north coast and Northern Isles of Scotland, possibly in small groups,” Dr. Castells Navarro said. “This movement allowed for the spread and maintenance of cultural practices and traditions.”
With individuals of shared kinship spread so far, researchers suggest these complex mortuary practices were likely shared across Iron Age Britain, adding an intriguing new wrinkle to our assessment of these ancient people.
“I think we can assume that the Iron Age dead were not forgotten,” Dr. Castells Navarro concluded, “and still had meaning to the living, with a continued interaction between the living and the dead across time and distance.”
Ryan Whalen covers science and technology for The Debrief. He holds an MA in History and a Master of Library and Information Science with a certificate in Data Science. He can be contacted at ryan@thedebrief.org, and follow him on Twitter @mdntwvlf.
Pour la première fois dans l'histoire, deux membres d'équipage américains d'un hélicoptère AH-64 Apache tombé en mer près des côtes d'Oman ont été secourus par un drone naval de la marine américaine. Une manœuvre qui pourrait bien changer la donne lors d’une opération de combat.
Very little is known about funerary practices in Iron Age Britain, since few human remains have survived. However, the environment in northwest Scotland is more conducive to preserving bone from that period. Archaeologists have previously noted evidence of postmortem manipulation of human remains, such as mummification, and of modifying human bones into tools or decorative artifacts. Now a new paper published in the journal Antiquity describes evidence of postmortem brain removal in remains from that region, as well as sharpened limb bones, possibly for use as tools.
The remains in question were found in 2000 at a burial cairn in Loch Borralie, near the most northwest tip of the Scottish mainland, after erosion revealed a human cranium. The excavated remains belonged to two individuals: one an adult female and the other a juvenile of (at the time) indeterminate sex; the cranium belonged to the latter. The authors of the new paper conducted a fresh osteoarchaeological analysis as well as multi-isotope and ancient DNA analysis. Radiocarbon dating of molar teeth from both sets of remains placed their deaths as occurring between 50 BCE and 70 CE.
In the case of the female individual, the authors noted an unusual break at the base of the cranium that likely occurred near the time of death. It's the kind of fracture that one gets from high-velocity impacts, including vehicular collisions, sporting accidents, falls, assaults, or even long-drop hanging. But the known forensic patterns observed in the aforementioned scenarios don't exactly match the pattern of the Iron Age cranium, leading the authors to conclude that it likely resulted from a targeted impact. They also noted perimortem fractures on both scapulae.
Water is one of the most common substances on Earth, but scientists have now discovered that it may have a surprising new use: storing electrical energy. Researchers at the Hamburg University of Technology in Germany have developed a new type of energy storage device that uses pure water as its main working ingredient. The technology […]
Quatre mois. C'est tout ce qu'il a fallu à une intelligence artificielle pour déchiffrer 32 763 manuscrits du Moyen Âge. Un exploit qui sidère les paléographes, habitués à consacrer des années entières à un seul document. Le projet CoMMa vient de réécrire les règles de l'archivage historique.

 Login