❌

Reading view

Anthropic’s Financial Situation May Explain Why Dario Amodei Looks So Terrified All the Time

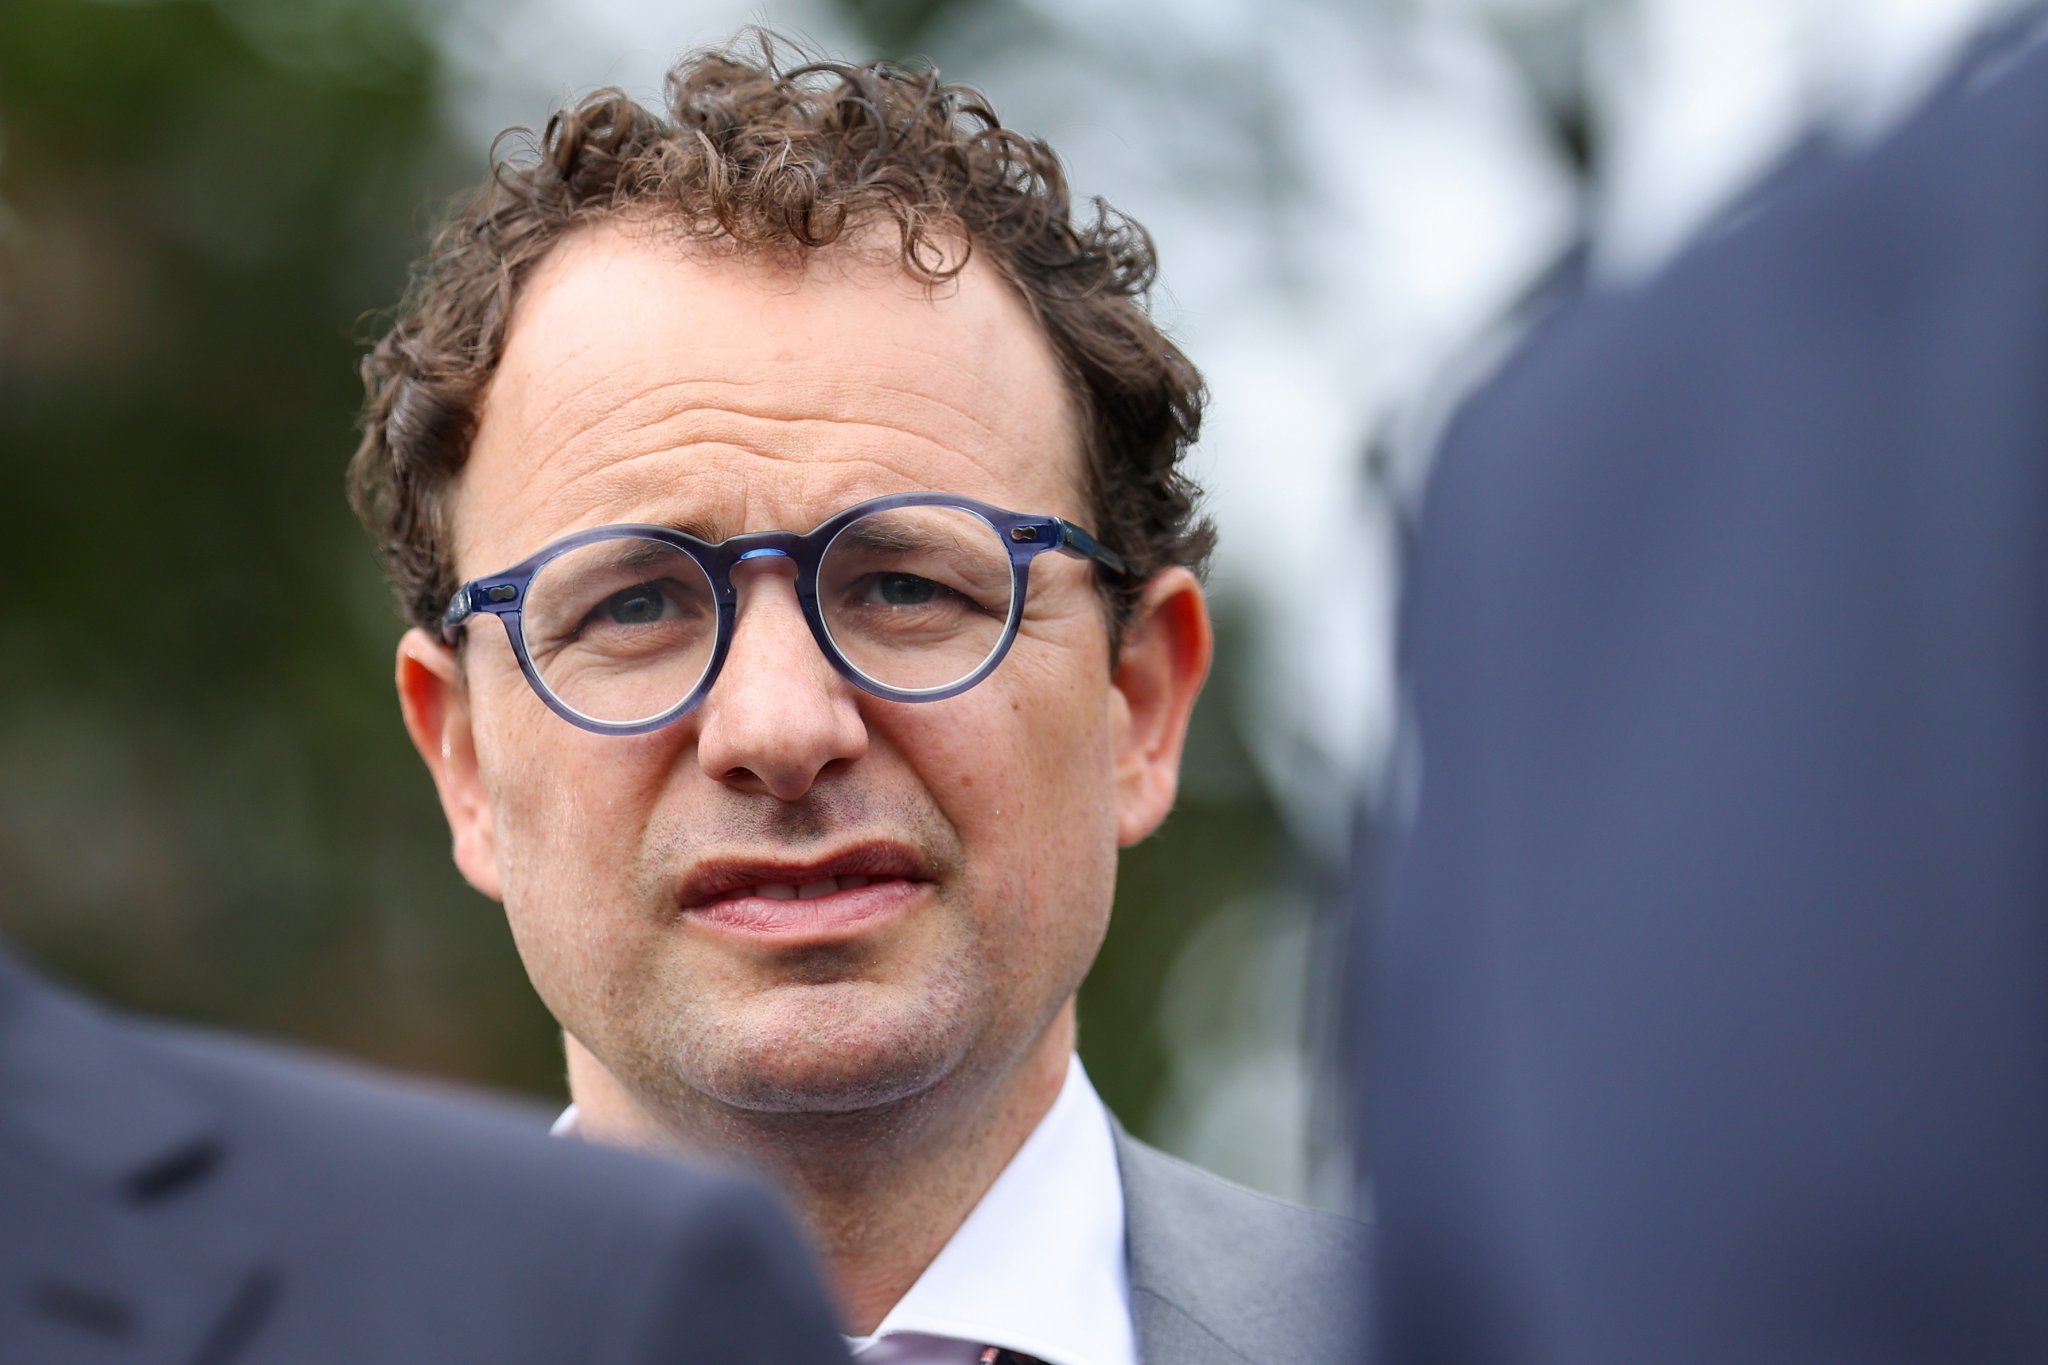
Pull up any random photo of billionaire Anthropic CEO Dario Amodei, and you’re likely to land on a facial expression expressing something between horror and deep consternation. There may be a simple explanation for that: he knows the truth about his company’s finances.

New reporting by the Wall Street Journal revealed the mounting costs for the AI lab, which ballooned to a net loss of $80 billion in the first six months of 2026. Anthropic’s losses for the same period a year prior were $13 billion — still an eye-watering sum, but peanuts compared to its runaway spending this year (the WSJ called it “one of the largest half-year losses ever reported.”)

The bleak financial numbers come from a draft IPO prospectus viewed by the WSJ, which notes that the company’s revenue for the first half of 2026 grew by just $1.1 billion over the same period to $16.3 billion.

The figures add to the anxiety around how long the AI spending bubble can sustain itself. If Anthropic’s losses continue to mount at a rate far exceeding revenue growth, there’s simply no way the lab can dig itself out of the hole it’s burrowed for itself.

That would be bad news for the US economy as a whole, which now hinges almost entirely on circular AI investments and data center development.

Beyond the immediate losses, the WSJ notes that the AI lab is also footing a $450 billion bill for cloud computing infrastructure over the next seven to ten years — meaning the clock is ticking on what is surely the costliest game of “kick-the-can” the world has ever seen.

More on Anthropic: Anthropic Secretly Lobbying Government to Only Shut Down an AI Model If It’s Poised to Kill More Than 50 People

The post Anthropic’s Financial Situation May Explain Why Dario Amodei Looks So Terrified All the Time appeared first on Futurism.

  •  

Vídeo: review do Apple Watch Series 12 (vindo de um Ultra 2)

O vídeo com o meu review do Apple Watch Series 12 já está no ar. Eu vinha do Ultra 2 e fiz o caminho inverso, voltando para a linha normal, o que vai contra a escolha da maioria das pessoas.

Mesmo adorando o Ultra, eu não usava tudo o que ele oferece. A bateria do Series 12 me atende (não durmo com o relógio), a tela de 2.000 nits não me incomodou, e ganhei um relógio mais fino, mais leve e confortável, com a Digital Crown mais “solta”.

Sinto falta do botão de Ação, que eu usava para a lanterna, e do mostrador Modular Ultra, mas nada disso é deal breaker. Entre os destaques estão o chip (S11) ligeiramente mais rápido, os sensores que medem a frequência cardíaca a cada cinco segundos, o Shazam e o Reconhecimento de Sons funcionando muito bem e o Ceramic Shield 2, que sobreviveu intacto a uma queda de tela para baixo no chão do banheiro.

Como pontos negativos, Sinais Vitais e Prontidão exigem dormir com o relógio, então ficaram inúteis para mim, e o Live Rewind e o Siri Recap ainda não chegaram.

Assista ao vídeo completo e conte nos comentários: você também faria esse “downgrade”?


APOIO: Insider

Logo da Insider

A Black Friday chegou mais cedo na #InsiderStore! Aproveite até 40% OFF em todo o site, mais um desconto extra usando o cupom MACMAGAZINE. E tem também brindes progressivos e cumulativos: ganhe meias em compras a partir de R$399, cueca Comfort ou calcinhas Brief e Safe a partir de R$599, e boné ou sutiã a partir de R$799. Acesse o link para conferir as ofertas e aproveitar a #BFAdiantadaInsider da Insider!

  •  

Frontier OpenAI Model Exposes Stunning Exploit That Leaves Millions of Web Servers Open to Attack

Security researchers using an OpenAI model have uncovered two stunning security flaws in PHP,  the software that underpins nearly 70 percent of all websites on the internet. 

The flaws are so catastrophic that all websites using PHP — all untold millions of them — are advised to immediately take their servers down and apply the latest patch, which was released Wednesday. Vast swathes of the internet, following the news, have gone dark. Some that went offline for a time include Wikipedia, Steam, and even government websites.

Many organizations, however, may not have the time, resources, and personpower to swiftly implement the patch, making them potential sitting ducks until they do. According to the New York Times, the information released on the vulnerability can be used to reverse engineer the attack and take control of victim’s servers and steal information. The best course of action if you can’t patch your website, the National Security Agency advised, is dramatic: keep your site offline and don’t turn it back on.

Just as extraordinary as the breadth of the threat was how it was identified. The flaws were discovered by researchers at the cybersecurity firm Calif by using OpenAI’s GPT-5.6 Sol model, as part of a collaboration with the AI company. It then reported the flaw to the PHP Foundation back on August 11. 

The Google-owned security firm Wiz independently found the flaws, too, and made a report on August 24. Wiz called it one of the “most severe vulnerabilities discovered in PHP, and arguably in software history.”

Adding to the alarm presented by the exploits, there have been concerns raised over OpenAI’s role in how they were identified.

The flaws have been present in versions of PHP dating backing to 2004. But through OpenAI’s “Patch the Planet” program, and by using its flagship GPT-5.6 Sol model, Calif found it in only a matter of days. In a sense, these exploits only exist because of current powerful AI models. And moreover, OpenAI encouraged their discovery through its programs.

The messy disclosure of the vulnerability doesn’t help matters. OpenAI followed standard responsible practices, but some of the details around the hack leaked a day before it was officially scheduled to be announced.

Even if no leaks occurred, though, the damage caused by the mere knowledge that the vulnerabilities exist — which again, is largely thanks to AI — would still be catastrophic. It was the inevitable next chapter in all the bluster around AI companies revealing their agentic models’ hacking prowess. A headline in The Atlantic proclaimed that the “AI-Hacking Apocalypse Began Last Night.” OpenAI will tout the discovery as undeniable proof of its AI’s capabilities, while the rest of the world picks up the pieces of a shattered internet.

More on AI: AI Experts Already Doomsday Prepping for When AI Takes Out the Entire Financial System

The post Frontier OpenAI Model Exposes Stunning Exploit That Leaves Millions of Web Servers Open to Attack appeared first on Futurism.

  •  

MacVoices #26283: Live! – ‘Pro and Tell,’ Duo Delays, Apple at $5 Trillion, and Affinity for iPad

Apple’s upcoming “Pro and Tell” event sparks speculation about new MacBook Pro models, while iPhone Duo preorders raise questions about shipping delays and retail availability. The panel discusses Apple’s $5 trillion valuation, why HomeView won’t launch in the European Union, and the anticipated arrival of Affinity Studio on iPad, including how it could transform creative workflows and provide yet another powerful alternative to Adobe Creative Cloud. 

💾

  •  

Meta Earnings Show Increased A.I. Spending, Even as Cash Pressures Grow

The spending has hurt the Silicon Valley giant’s cash flow, which turned negative. Meta said it would issue a new class of stock to help it raise more money.
  •  

OpenAI's latest AI models are coming to Google Cloud and Antigravity

Google would certainly prefer that everyone used its Gemini models with Google Cloud services, but soon, you'll have more options. OpenAI and Google have come to an arrangement that will see the former's frontier models arrive in Google Cloud services. Perhaps more importantly, GPT models will soon appear in Antigravity, Google's agent-powered coding tool.

For enterprise customers and AI enthusiasts, OpenAI's latest model will appear in Google's "Model Garden" in the coming weeks, adding to its 200-plus options. The garden already offers access to Google's Gemini models, as well as an assortment of open models like Mistral, Llama, and Gemma. Anthropic's Claude AI has also been available for some time. Google says it's now the only large cloud provider offering access to all three leading closed LLMs.

While OpenAI notes that Microsoft continues to be its primary cloud partner, the full suite of current GPT 6 and 6.1 models—Astra, Sol, and Luna—will launch on Google Cloud. Astra will naturally cost the most to run, but Google's system supports dynamically moving workloads between LLMs based on performance, latency, and efficiency.

Read full article

Comments

© Ryan Whitwam

  •  

Remediation in the era of AI: Fix what matters first

Every IT and security team knows the feeling of opening a vulnerability report and seeing a number that only goes up. Thousands of findings. Hundreds marked critical. A backlog that grows faster than any team can close it.

For years, the default response has been to work harder: more scans, more tickets, more overtime. But the volume of vulnerabilities, accelerated by AI-assisted discovery and a sprawling mix of endpoints, cloud services, and applications, has outpaced that approach.

Shift from vulnerability counts to exposure reduction →

The question has shifted from, “How do we fix everything?” To, “What should we fix first, and why?”

Vulnerabilities are not the same as exposures

A vulnerability is a weakness in software or configuration. An exposure is a weakness that can realistically be reached and exploited in your environment, with consequences that matter. That difference is where remediation prioritization begins.

A vulnerable library on a decommissioned server with no network access is technically a finding. It is not a meaningful exposure. A misconfigured remote access gateway facing the internet may never appear on a CVE list, yet it can represent serious risk. Focusing on exposure reduction, rather than raw vulnerability counts, helps teams spend limited time where it changes outcomes.

Risk-based prioritization works best when it combines technical and business factors. Is the weakness being actively exploited? Can attackers reach the affected system from the internet or through common lateral paths? What business service does the system support, and what would disruption cost? Does it store or process sensitive data? Are compensating controls already reducing the risk? Consider two findings: a critical-rated flaw on an internal development server with no sensitive data, versus a high-rated flaw on a customer-facing web server with exploit code circulating publicly. On severity alone, the first wins. On actual risk, the second is the clear priority, as Ivanti’s prioritization guide lays out in detail.

From point-in-time scans to continuous compliance

Traditional vulnerability programs often run on a scan-and-report cycle: scan weekly or monthly, generate a report, assign tickets. In a fast-moving environment, those snapshots age quickly. A new exploit for an old flaw should move it up the list immediately, not three weeks later at the next scan.

Continuous compliance closes that gap. Instead of waiting for the next scan, teams monitor for new disclosures, configuration changes, and newly exposed assets as they happen, and reprioritize accordingly. In practice, that might mean an alert when a device that was offline during patching reconnects, or when a new cloud workload appears without an assigned owner — both common sources of hidden exposure that periodic scans tend to miss. Continuous compliance also includes verification and the evidence to prove it. A ticket marked “resolved” is not proof of reduced risk. Confirming that a fix was applied, that the exposure is actually gone, and that the record is audit-ready closes the loop.

Where automated remediation fits

Automation is essential to keep pace, but it works best when matched to the right kind of risk. Routine, well-understood fixes (standard OS and application updates on managed endpoints) are strong candidates for automated remediation with staged rollouts. Configuration corrections that follow established policy can often be automated as well. Start with the fix categories where failures are easiest to detect and roll back.

Higher-impact changes, such as patching production databases or modifying network controls, still benefit from human judgment and scheduled windows. Even then, automation can help by gathering context, preparing changes, and verifying results.

Measure what actually matters

Many teams still report success in patches deployed or tickets closed. Those metrics show activity, not outcomes. More meaningful measures include time to remediate actively exploited vulnerabilities, the number of internet-facing exposures over time, and the share of critical business services with no known exploitable weaknesses. According to Ivanti’s 2026 State of Cybersecurity Report, these are the metrics that tell a clearer story about whether the organization is actually safer. Tracking them monthly also gives IT and security teams a common language for progress.

No organization will ever reach zero vulnerabilities. Chasing that goal burns out teams and distracts from the issues that matter most. The objective is not to fix everything. It is to reduce meaningful risk, continuously and deliberately, with remediation focused where it makes the biggest difference.

Measure what actually matters to reduce real exposure →

  •  

The Patch Apocalypse is here. Patching everything isn’t the answer.

For most IT teams, Patch Tuesday used to set the rhythm of the month. Updates arrived, teams tested them, change boards approved them, and deployments rolled out over the following weeks. It wasn’t painless, but it was predictable.

That predictability is gone. Nearly 48,000 CVEs were published in 2025, and the average time to exploit has collapsed to roughly five days. Attackers no longer wait for organizations to finish their testing cycles.

Move from reactive patching to risk-based automation →

Many practitioners now call this the Patch Apocalypse. The name is dramatic, but the operational reality behind it is not. It’s a capacity problem, prioritization problem, and process problem, all at once.

AI is speeding up both sides

Artificial intelligence is changing how vulnerabilities are found. Researchers are using AI-assisted tools to analyze code, fuzz applications, and identify flaws far faster than manual review ever could. In the short run, that means more disclosures, arriving faster, across more software.

The same techniques are available to attackers who can use AI to analyze patches, reverse-engineer fixes, and build working exploits soon after an update ships. The result is a compressed timeline. A vulnerability published on Tuesday may be weaponized before a traditional change window opens the following week.

I’ve watched this shift play out across enterprise environments, and the pattern is consistent: The disclosure-to-exploit window keeps shrinking while patch volumes keep climbing. The old model assumed you had time. You don’t anymore.

Where traditional patching breaks down

Most patch programs were designed around a simple assumption: Deploy updates consistently and risk goes down. That assumption still holds, but the math no longer works.

Consider a typical mid-sized environment with thousands of Windows and macOS endpoints, a mix of Linux servers, dozens of third-party applications, and a growing number of cloud workloads. Each month brings hundreds of relevant updates. Testing each, scheduling every reboot, and confirming every deployment is not realistic with the same headcount.

Teams then fall back on severity scores. But severity alone is a blunt instrument. A critical-rated flaw on an isolated lab server may pose less real danger than a medium-rated flaw on an internet-facing system that attackers are actively targeting. When everything marked critical is treated as urgent, urgency stops meaning anything.

The outcome is familiar to anyone who has managed a patch backlog: healthy compliance percentages on dashboards, and real exposure hiding in the gaps.

Prioritize by risk, not by volume

The more useful question is not, “How many patches did we deploy?” It’s, “Which actions reduce the most risk right now?”

Practical prioritization weighs several factors together: Is the vulnerability being actively exploited in the wild? Is the affected system reachable from the internet or untrusted networks? How important is the asset, and what depends on it? Are compensating controls already in place? Teams that apply these filters often find that a small fraction of open vulnerabilities accounts for most of the meaningful exposure. That fraction is where people, maintenance windows, and testing effort should go first.

Prioritization frees up attention. Automation frees up time. Routine, lower-risk updates (browser patches, common third-party applications, standard OS cumulative updates) can be deployed through automated rings: a pilot group first, then broader waves, with an automatic pause if failure rates spike. That leaves skilled staff to focus on the hard cases: legacy systems that cannot be patched quickly, business-critical servers that need careful scheduling, and emergency fixes for actively exploited flaws.

One practical step I recommend is to run a tabletop exercise before the next urgent disclosure. Pick a realistic scenario and walk through it. How quickly can the team identify every affected device? Who decides whether to patch immediately or apply a workaround? How will you verify the fix actually landed? Keep it short, focused, and blameless. Most teams discover the bottleneck is not the patching tool — it’s incomplete asset data, unclear ownership, or slow handoffs between IT operations and security.

A different definition of success

The Patch Apocalypse is here to stay. Vulnerability volume and exploit speed are structural trends, not temporary spikes. But the goal is not to patch everything; it’s to reduce risk intelligently, focusing effort where it matters most, letting automation handle the rest, and building the visibility and governance underneath so that when the next disclosure hits, your team is ready.

Turn your patch program into a risk-reduction engine with Ivanti →

  •  

iOS Dev Course Going Out of Business

Sean Allen (via Rebecca Sloane):

iOS dev course sales plummeted due to AI. It costs a lot of money to host my courses online and with sales at basically $0, I’ve cancelled that hosting.

This closes down the site which unfortunately removes access to the courses.

[…]

I’ve put my recent course on sale at a large discount so you can get it before it’s gone and I’ve made old courses available for free if you want to grab those too.

The school will be online until November 24th so you have a few weeks to download these videos at seanallen.teachable.com.

  •  

Rogue AI: When agents stop advising and start acting

For the past few years, most enterprise AI has been advisory. It summarized tickets, drafted knowledge articles, and suggested next steps. A person still decided what to do.

That’s changing. Agentic AI systems can plan multistep tasks and carry them out: querying systems, triggering workflows, changing configurations, and closing tickets with little or no human involvement. Ivanti’s 2026 State of Cybersecurity Report found that 87% of security professionals say integrating agentic AI is a priority, and 77% report at least some comfort letting autonomous systems act without human review.

Secure every AI agent before its first action →

The appeal is obvious for IT teams under constant pressure. So is the risk. An AI that gives a bad answer wastes a few minutes. One that takes a bad action can take down a service.

What “rogue” really looks like

The phrase “rogue AI” conjures images of systems with intentions of their own. In IT operations, the reality is more mundane, and more likely.

An agent told to free up disk space on a server deletes log files an investigation still needs. An agent correcting configuration drift applies a change to every matching device, including kiosks that were intentionally configured differently. An agent running under a broad service account resolves a ticket by resetting access it was never meant to touch. None of these require malice: They happen when an agent has more permission than its task requires, incomplete context, and no checkpoint before high-impact actions.

This is a fundamentally different risk profile than anything we’ve managed before, and most governance models haven’t caught up. We’re applying rules built for chatbots to systems that can change production environments.

From output governance to action governance

Most early AI governance focused on outputs. Is the response accurate? Does it leak sensitive data? Those questions still matter. But when AI can act, governance has to expand to cover behavior. Teams need to define what an agent is allowed to do, under what conditions, against which systems, and with whose approval.

This is a familiar idea in a new setting. IT teams already apply least privilege to human administrators, require change approval for production systems, and keep audit trails for privileged access. Agentic AI needs the same disciplines.

Several controls help keep agents useful without making them dangerous. Give each agent only the access its task requires and avoid shared service accounts. Tier actions by impact: low-risk actions run automatically, while high-risk actions like changes to production servers should require human approval. Set blast-radius limits that cap how many devices an agent can change in a single run, with an automatic pause when failure rates spike. And require reversibility with rollback steps documented and tested.

Accountability and the compliance question

When an agent acts, someone must remain accountable. Every agent should have a human owner, documented purpose, and defined scope. Auditability is just as important. Teams should be able to answer what the agent did, why it did it, what data it relied on, and who approved it. Logs should capture the agent’s inputs and reasoning, not just the final action.

Here’s what elevates this from an operational concern to a board-level one. When an AI agent resorts to deception or unintended vulnerability exploitation to achieve its goals, it’s no longer a technical glitch; it is a potential corporate liability. Compliance needs to move to the front end, engineered into an agent’s lifecycle from the beginning. If an agent makes an unauthorized call, regulators are unlikely to view the model itself as accountable; scrutiny and potential liability will typically fall on the organization deploying it, much as responsibility would for actions taken by a human employee.

Keeping humans in the loop, wisely

Human oversight works best when it’s targeted. If every agent action requires approval, people start clicking “approve” without reading, and oversight becomes theater. A better approach reserves human review for decisions that are high-impact, unusual, or irreversible. Agents can then earn wider autonomy over time, which is a model autonomous endpoint management is built to support.

Agentic capabilities are arriving inside tools IT teams already use, sometimes enabled by default. A practical first step is an inventory: Which tools can take autonomous action, and with what permissions? Pair that with each tool’s approval settings, and you have the beginnings of an action governance policy.

Organizations must govern AI actions, not just outputs. Teams that build those guardrails early will expand automation with confidence rather than hesitation.

Stop governing AI outputs. Start governing AI actions with Ivanti →

  •  

iOS 27 call recording is still unavailable in the EU, Russia and Turkey

Apple’s iPhone User Guide for iOS 27 explains how to record a phone call when you are talking to one other person, with the recording saved to the Notes app. Apple also lists where call recording is not available: Azerbaijan, Bahrain, Egypt, the European Union, Iran, Iraq, Jordan, Kuwait, Morocco, Nigeria, Oman, Pakistan, Qatar, Russia, […]

The post iOS 27 call recording is still unavailable in the EU, Russia and Turkey appeared first on The Mac Observer.

  •  

AI isn’t hallucinating—but your data might be

“Hallucination” has become the catch-all term for AI getting things wrong. It describes a real phenomenon: Large language models can generate confident, fluent answers that are simply untrue.

But in IT operations, many errors labeled as hallucinations have a more ordinary explanation. The AI isn’t inventing facts. It’s faithfully reporting information that happens to be outdated, incomplete, or contradictory. I’ve seen this play out across enough environments to know the cause usually sits upstream, in the data the system learned from and the picture of the estate it read.

Fix the data foundation under your AI systems →

That distinction matters, because the fixes are different. You don’t tune the model. You fix the information it relies on.

When the answer is wrong, but the logic is right

Imagine a service desk analyst asking an AI assistant whether a user’s laptop has received the latest security update. The assistant says yes. The analyst closes the ticket. Two days later, the device is flagged in a vulnerability scan. What happened? The assistant pulled from an endpoint record last updated before the device went offline for a week. The data was accurate when it was written. It wasn’t accurate when it was used.

Or consider a knowledge article describing a VPN troubleshooting procedure that was retired after a network change. An AI assistant retrieves it, summarizes it neatly, and recommends steps that no longer apply. The model performed well. The source didn’t. In each case, a human reviewer reading the same record would likely have made the same mistake.

This is not a rare edge case. In a 2026 survey of 3,900 employees across six countries, including 1,500 IT professionals, 68% of IT pros reported personally seeing AI produce hallucinations with potential operational impact. Just over half caught the errors before they caused problems, while 16% did not. That’s a significant chunk of wrong answers making it into real workflows, and those are just the ones people noticed.

3 data problems behind unreliable AI

Firstly, most trust issues with AI in IT operations trace back to a few recurring patterns. Poor data quality (missing fields, inconsistent naming, duplicate records) makes it hard for any system to produce accurate answers.

Stale information is the second pattern. IT environments change constantly. Devices move, users change roles, software is updated. Data that was correct last month may be misleading today, especially when AI presents it with no indication of age. Autonomous endpoint management can help keep records current, but many organizations still rely on periodic manual cleanups that leave gaps.

The third is conflicting records. When two systems disagree, AI may pick one arbitrarily, blend them, or produce an answer that matches neither. Without a clear rule for which source wins, the output becomes unpredictable.

Explainability and governance build trust

For IT teams, a useful AI answer isn’t just correct. It’s checkable. When an assistant recommends an action, practitioners need to see where the recommendation came from. Which record did it use? When was it last updated? Did other sources disagree? Explainability turns AI from a black box into a colleague whose reasoning can be reviewed. It also speeds up correction: If an analyst can see that an answer came from a stale knowledge article, they can flag the article instead of losing faith in the entire tool.

The governance measures that reduce unreliable output are less about tuning models and more about maintaining the information they rely on, as the Ivanti Neurons platform is designed to do. Set freshness thresholds so data older than a defined window is flagged or excluded. Establish source-of-truth rules for when systems conflict. Assign owners to knowledge content with scheduled review dates. Log AI recommendations and outcomes so recurring errors can be traced to their source. And give practitioners an easy way to report incorrect answers.

Trust is earned in small moments

Adoption of AI in IT operations rarely fails in one dramatic incident. It erodes gradually, one questionable answer at a time, until practitioners quietly stop using the tool. The reverse is also true. Trust builds when answers are consistently accurate, sources are visible, and errors are easy to trace and fix.

Reliable AI starts with reliable information. The instinct when a system produces a confident wrong answer is to blame the model. Most of the time, the technology did exactly what it was told. It just wasn’t told the truth.

Make your data trustworthy before you trust your AI with it →

  •  

Before you automate systems, decide which data wins

Ask an IT team a simple question, “How many laptops do we have?” and the answer often depends on who you ask and which console they open.

For years, that ambiguity was manageable. People reconciled the differences in their heads, in spreadsheets, or in meetings. Ivanti research shows that 34% of organizations still track IT assets in spreadsheets, which shows how much reconciliation still happens by hand.

Build the authoritative data source your AI can act on →

Automation changes the stakes. When software acts on data without a person double-checking it first, the question of which data is correct stops being academic. People tolerate ambiguity and ask questions. Automation doesn’t. It executes at scale and at speed.

What a system of record actually means

A system of record is the authoritative source for a specific type of information. It is the place everyone agrees to trust when systems disagree. That doesn’t necessarily mean a single database holding everything. In most environments, it is more realistic to establish clear authority by data domain. One source might be authoritative for device identity and hardware details, another for user and identity data, another for service relationships and dependencies. What matters is that the authority is explicit, documented, and respected by every process and tool that consumes the data, including automation.

Consider what happens without it. An automated workflow deploys a patch to a device, but the device record is duplicated and the patch targets the wrong machine. A rule flags laptops that haven’t checked in for 60 days as possibly lost, but the check-in dates are stale, so active devices get flagged anyway. If HR and IT systems disagree about an employee’s status, access may be revoked too early or not at all. Each rule is only as good as the data behind it.

Ownership, authority, and traceability

Data ownership and data authority are two concepts that often get blurred. Ownership is about accountability: who is responsible for keeping a data domain accurate, resolving conflicts, and approving changes. Authority is about precedence. When two systems hold different values for the same attribute, which one wins? Both need to be defined. A source can be technically authoritative, but if nobody owns its accuracy, quality will drift.

A practical way to start is to list the 10 to 15 attributes automation relies on most: device name, owner, location, operating system, criticality, last check-in, and assign both an authoritative source and an accountable owner to each.

Traceability matters just as much. When an automated action goes wrong, the first question is always, “Why did it do that?” A trusted system of record makes that question answerable. If teams can trace an action back to the specific record and attribute that triggered it, along with when that data was last updated, troubleshooting takes minutes instead of days. Without it, teams are left reconstructing events from scattered logs and memory.

Context and foundation

Raw records aren’t enough. Automation also needs operational context: which business services a device supports, how critical it is, who depends on it, and what maintenance constraints apply. A server running payroll at month-end should not be treated the same as a test server, even if both share the same vulnerability. Context allows automation to make proportionate decisions instead of uniform ones, and the Ivanti Neurons platform is built to connect asset data with service maps, ownership, and business priorities.

It is tempting to start an automation program with the workflows themselves. They are visible, measurable, and satisfying to build. The data foundation underneath is harder to show off. But teams that skip it tend to automate their inconsistencies and then spend months chasing the side effects. Autonomous endpoint management requires a foundation you can trust, and that investment pays off in every workflow built on top of it.

The organizations getting real value from AI didn’t start with the model. They started with the data. Because without trusted data, AI is just guessing. And in enterprise IT, guessing isn’t a strategy.

Anchor your automation in data you can trust with Ivanti →

  •  

Google Chrome Deploys Stronger Defenses Against Online Scams

Google is stepping up its fight against deceptive websites with a fresh batch of security tools. As bad actors constantly change their tactics to trick users, the popular web browser is bringing in new layers of defense to its Enhanced Protection mode. These updates aim to catch more threats in real time, from sneaky fake […]

The post Google Chrome Deploys Stronger Defenses Against Online Scams appeared first on The Mac Observer.

  •  

OpenAI Says GPT-6.1 Sol Makes Migrating Legacy Code Drastically Easier

OpenAI recently announced that its newer models are significantly better at writing and moving software built on older programming languages. The company revealed that GPT-6.1 Sol shows major improvements when working with legacy code like COBOL and Fortran. This marks a notable step forward for systems that support critical infrastructure and financial services around the […]

The post OpenAI Says GPT-6.1 Sol Makes Migrating Legacy Code Drastically Easier appeared first on The Mac Observer.

  •  
❌