Clever database, but can it run Doom?
For CIOs and CDOs heading into Microsoft Fabric and SQL Community Conference Europe, the main question is not which data technology sits at the center. It is whether the data platform improves revenue, productivity, and decision speed while creating a trusted foundation for AI at scale. That should drive the data strategy.
Enterprise AI is forcing companies to tackle a familiar problem, with data spread across ERP, CRM, operational systems, databases, applications, warehouses, and analytics platforms built over years. That was manageable for reporting and point-to-point integration. Copilots and agents raise the stakes because they need to reason across customers, orders, inventory, financial implications, operating constraints, permissions, and business rules at the same time.
That moves the discussion from architecture into CIO and CDO strategy. What outcomes are we trying to improve? What data and context are required? What needs to move versus connect? Where do Microsoft Fabric, Azure Databases, and other platforms fit? How will governance and authority follow the data? Where should the data be stored and what sovereignty or regulatory restrictions apply? And how will we measure results?
Microsoft is positioning its broader data platform around AI business value. That framing is useful when it translates into an operating strategy. As I wrote in Forbes about Microsoft Build in June, the next phase of AI depends less on the model and more on data readiness, governance, interoperability, and operational execution. The conference should give customers a closer view of how those pieces come together. The question for CIOs and CDOs is how that direction fits their existing data estate.
Many AI initiatives stall on data readiness rather than the model itself. The issue is not one statistic. It is the combination of fragmented data, inconsistent definitions, and the effort needed to prepare and govern information before AI can use it reliably.
Copilots and agents need trusted context around customers, financials, inventory, operations, permissions, and business rules. AI exposes existing weaknesses. Duplicate customers, poor product data, and inaccurate inventory become more consequential when AI is recommending or taking action. AI does not create the data quality problem; it makes the operating cost harder to ignore.
The goal is to make more of the existing data estate useful for AI without turning modernization into a wholesale rebuild.
For customers, the question is how Microsoft’s broad portfolio translates into architectural choices, including what should move, what should connect, and what can stay in place without limiting the result the business is trying to achieve.
Azure Databases support transactional and operational workloads, each with distinct performance and application requirements. Fabric provides a unified SaaS experience across data integration, engineering, analytics, real-time intelligence, data science, and business intelligence. Fabric IQ adds a semantic intelligence layer that provides shared business context for Copilot and agents. Some workloads may belong in Fabric, others in Azure Databases, and some on third-party platforms; moving them adds cost without creating enough business value.
The architecture should follow workload, data maturity, economics, and business value, not a single destination.
Microsoft’s broader data platform can connect systems of record and operational applications with analytics and AI. Azure Databases, Fabric, OneLake, Power BI, and governance can play different roles. What matters is whether those connections shorten the path from operational data to a decision, not how neatly the products line up.
A customer record may live in CRM, orders in ERP, inventory in operational databases, and demand models in an analytical environment. Fabric Real-Time Intelligence can add live events to that picture. A manufacturer can stream equipment events or production events, detect a developing issue, and alert teams while there is still time to change the outcome. The value comes from reasoning across that context so the business can understand what is happening, why it matters, and what action makes sense next.
I recently wrote in InfoWorld that trusted context is becoming the currency for enterprise AI. That is especially relevant here because once copilots and agents rely on enterprise data, then quality, permissions, lineage, and security become operating requirements, not background data issues.
Knowing inventory is 8,000 units is data. Knowing whether those units are available, committed elsewhere, in the wrong distribution center, or on quality hold is business context. As AI moves from answering questions to taking action, that context determines whether the result can be trusted.
Microsoft frames AI business value around growth, insight, and scale. Each needs an operating definition. Growth can mean new revenue, better customer responsiveness, or growing without adding cost at the same rate. Insight means combining context across Microsoft 365, Fabric, and operational systems to make better decisions faster. Scale means expanding AI without rebuilding governance for every use case.
A reusable data foundation can also reduce pipeline and management effort while improving decisions around pricing, inventory, customers, supply chain, and finance. Microsoft cites coverage of more than 100 standards. The practical question is whether AI can scale without risk and complexity growing at the same pace. For multinational or regulated organizations, that also includes where data is stored and processed and which sovereignty requirements apply.
Agentic workloads raise the bar. Organizations need to know what information informed a decision, who or what had authority to act, which policies applied, and how a wrong action can be reviewed or reversed.
That is where the data platform becomes part of what I describe as decision architecture. Context explains what is happening. Decision logic determines what should happen next. Authority defines what a person or agent can do. Orchestration coordinates systems and people. Execution completes the action and provides a path to review or reverse it. Trusted data feeds that architecture. Without trusted data, automation will be difficult to trust at scale.
Microsoft’s advantage may be its enterprise footprint. Azure Databases, Fabric, OneLake, Power BI, Microsoft 365, business applications, developer tools, identity, security, and partners touch many of the places where information is created and work gets done.
Most customers will keep data across multiple systems. Microsoft’s opportunity is to use that breadth to create a simpler path from data to workflow to business outcome without requiring everything to live in one place.
Customer proof points matter because data strategies can get abstract. The KPMG Australia example is useful because KymChat moved beyond an internal productivity tool into a client-facing offering, creating a path from internal AI investment to new business. Microsoft also reports that improvements to the data foundation increased KymChat search quality from 50% to 91%, with results delivered in under a second.
BMW Group provides a more recognizable operating example. Microsoft says Azure helped BMW make vehicle data delivery and analysis 10 times faster, cutting the lead time for engineering insights from days to hours or minutes. Audi adds an AI deployment example. It used Azure AI Foundry, Azure App Service, and Azure Cosmos DB to launch a secure HR assistant in two weeks and is extending the same framework to eight additional agents across the enterprise. Levi Strauss & Co. offers another angle. It consolidated nine ERP systems on Azure, reported a twofold improvement in latency and a 60% improvement in IOPS and now uses Fabric IQ for companywide cost reporting. These are the kinds of proof points that connect platform architecture to time, cost, productivity, and decision quality.
Microsoft sits in a market with Snowflake, AWS, Google Cloud, Oracle, and others, each with different strengths across infrastructure, databases, analytics, openness, and AI. Databricks also plays an important role, but the connection is different because Azure Databricks is provided as a first-party service directly on Azure. Most large enterprises will remain heterogeneous, making interoperability, cross-platform governance, and incremental modernization central to strategy.
The opportunity is to make Microsoft’s data platform useful across the mix of systems that customers already run. Most enterprises are not starting from a blank sheet, so the value is in helping them connect, govern, and modernize over time without forcing everything into one place.
This is where the conversation becomes most useful at the Microsoft Fabric and SQL Community Conference Europe. For CIOs and CDOs, an architecture diagram matters more when it is backed by a decision model. A useful data and AI strategy should work backward from the business outcome through five decisions.
That is how the data platform becomes enterprise strategy, tying architecture, governance, AI, and economics to operating outcomes and bringing business leaders into the discussion before the architecture is set.
Microsoft has many of the pieces required to connect enterprise data, analytics, and AI. Customers will keep looking for guidance on the roles of Azure Databases, Fabric, and the broader data platform, along with cost, licensing, migration, and governance across heterogeneous environments. They will also want more proof points from KPMG, BMW Group, Audi, and Levi Strauss & Co. that start with a business result.
That is where Microsoft’s positioning around a data platform for AI business value comes together. The value is in helping customers connect platform choices to better decisions, faster action, and measurable operating results.
After three decades in enterprise technology, I keep coming back to the same point. The technology is only part of the answer. For CIOs and CDOs, the harder part is deciding how the data platform fits into the way the business operates, how decisions get made, and where AI can improve the outcome. That is really the question behind how Microsoft connects your data across the enterprise. The conference should give customers a useful view of how Microsoft is bringing those pieces together and where that can create better business outcomes.

Postgres just turned 30. Over those three decades, I’ve watched it pick up hot standby replication, logical replication, asynchronous IO, just-in-time compilation, and dozens of other features built for enterprise workloads. Every one of them solved a real problem and raised the floor on what a DBA needs to know just to do the job well.
I don’t think most people outside this world fully register how much that floor has risen. In the early days, improvements were small and mostly about stability. Now, 30 years in, the focus is squarely on enterprise functionality, and that functionality comes with complexity attached. The more you build, the more there is to understand and manage, and that increases every year.
Most organizations treat a scaling database problem as a staffing problem. Hire enough DBAs and you’re covered. I think that’s the wrong way to look at it entirely.
It’s not far off from the old “too many cooks spoil the broth” problem. You don’t make better soup by adding cooks. You make better soup with a better chef. A 100-terabyte database with serious performance issues doesn’t get fixed by putting 10 DBAs on it instead of one. It gets fixed by someone who has seen that failure before and knows exactly where to look.
Experienced DBAs are expensive and hard to find, and the problem is only getting worse. A few years ago, it was IoT driving demand for time series expertise at scale. Now it’s AI, and organizations are building enormous databases to support retrieval pipelines and large language model (LLM) training, often without the experience on hand to run them safely.
Humans are unpredictable. We make assumptions. Sometimes, we think the process is getting in the way, so we take a shortcut around it. And we make mistakes because that’s simply human nature.
I don’t think that’s something we’re ever going to fully engineer away as long as a person is in the loop, and honestly, we want a person in the loop making the real decisions. So it becomes a balancing act. You have to understand the mistakes people tend to make, build the discipline to follow good processes consistently, and still know when a situation calls for judgment rather than a checklist.
I think this is where AI has earned its place. It’s not as a replacement for the DBA, but as something that follows a process more consistently than a person under pressure tends to.
Modern AI systems still have problems with hallucination and getting the full picture right. However, with the right guardrails, auditing, and tracking in place, they are able to follow the process very well. It is much easier for me to say, “Forget it, I know a shortcut, I’ll just push this through,” than it is for a well-constrained model to deviate from its instructions. As long as the instructions are clearly defined, LLMs tend to stick to them.
Another advantage worth naming is if an LLM is doing the diagnostic work, you can put much stronger gating around its ability to actually make changes. You can let it follow a tight, well-defined process to diagnose a problem while still requiring a human to approve anything that touches the live system, whether that’s creating an index, dropping one, or changing a configuration value.
That combination gets you to a solution far faster than the old way, using the model’s training plus whatever supplemental knowledge you feed it through retrieval-augmented generation (RAG), while keeping a person at the one point where it actually matters. Did the model get the diagnosis right? Does the proposed fix line up with the actual problem? That’s the question a human needs to answer before anything gets applied.
I am not sure we are far enough along the path as an industry to really know what we’re getting wrong. I am working through these questions myself right now, looking at autonomous agents for Postgres operations and where the real risk is.
What’s clear to me already is that strong guardrails matter in two places, not one. You need guardrails on the prompts so the model verifies its findings and doesn’t hallucinate into a bad recommendation. And you also need guardrails on what the model is actually allowed to do. Letting an agent create an index carries a manageable risk. Letting it truncate your orders table does not. Auditing matters just as much; when something does go wrong, you need to see exactly what happened and undo it. The fallback needs to stay in place until the industry broadly trusts these systems more than it trusts a human.
Picture a load spike that hits overnight, the kind where batch processing that normally runs fine suddenly does not. The old way means spending hours trawling logs, index stats, table stats, and query performance before you land on a likely cause and you can apply a fix.
Put an LLM on that same problem and the hours-long process compresses into minutes. It’s the same productivity shift we’ve already seen in software development, where an experienced user with the right skills and guardrails can get LLM output that matches or beats a junior developer’s work. The quality comes down to this process: Structure the work, define a clear spec, build the implementation plan, then verify each stage before moving on.
The same discipline applies to database operations. The worst thing you can do is rush in and say to the model, “This happened, go fix it.” You need to guide the tools properly to get good results from them. When it’s done right, it works.
A few things need to be true for this to scale across the enterprise. Frontier models already understand Postgres well, but they don’t know everything, so you need to feed them supplemental knowledge alongside that training. Full documentation matters here, so do internal runbooks. The process has to require the model to actually consult that material rather than coast on what it already knows.
I expect the same kind of structured skills that are common in AI-assisted development, the step-by-step approach to planning and verification, to show up specifically for Postgres operations. That will make the job easier for DBAs, and easier is what matters.
We’re probably not far from agents that sit and watch a Postgres instance around the clock and rarely need a human to step in. The slower part is trust. For example, look at how long it took people to actually believe AI-written code was any good. I would guess it is the same pattern here, but I don’t doubt for a second that we will get there.
In the meantime, you do not need to hand an LLM the keys to your database tomorrow. Start smaller and begin with read access to your monitoring data. It’s a low-risk place to start.
An agent watching constantly can catch the kind of slow, compounding anomaly that threshold-based alerting tends to miss, a gradual rise in IO alongside a gradual rise in memory, and flag it before it becomes the kind of outage that costs real money every hour it runs.
That’s not a small thing. The DBA shortage is not going away on its own, and waiting for the industry to fully trust autonomous agents before using AI at all is the same as falling behind. The teams that figure out where the human belongs in this process are the ones who’ll be ready when the rest of the industry catches up.
—
New Tech Forum provides a venue for technology leaders—including vendors and other outside contributors—to explore and discuss emerging enterprise technology in unprecedented depth and breadth. The selection is subjective, based on our pick of the technologies we believe to be important and of greatest interest to InfoWorld readers. InfoWorld does not accept marketing collateral for publication and reserves the right to edit all contributed content. Send all inquiries to doug_dineley@foundryco.com.

Entrusting mission-critical workloads in the cloud puts a lot of pressure on IT operations to build resilience into data infrastructure they don’t even own — to make sure that when an incident happens elsewhere, the lights stay on at home. Fortunately, savvy CIOs are learning they can architect their systems for resilience and high availability to keep mission-critical cloud workloads running when disaster strikes.
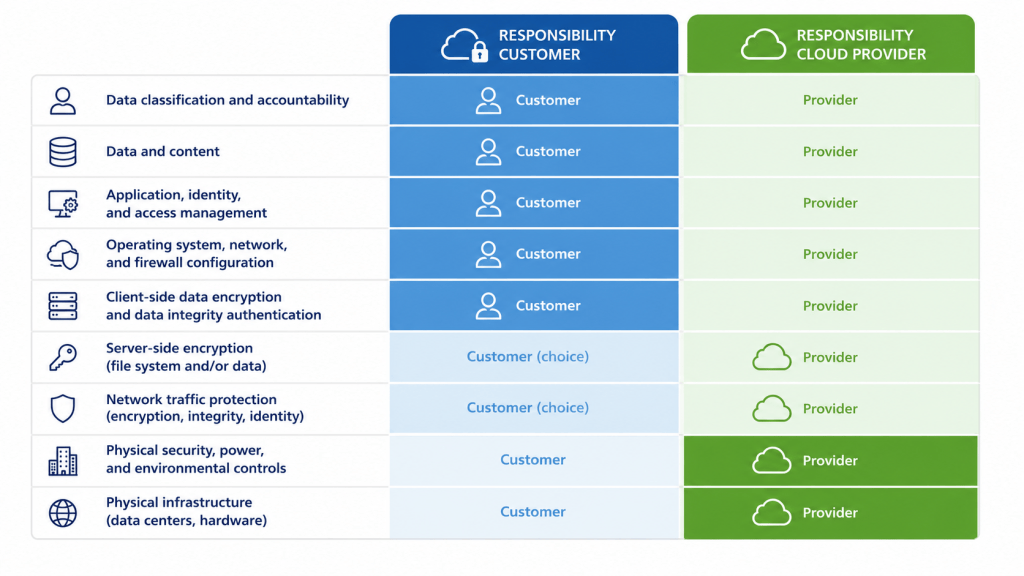
When designing for resilient, highly available cloud workloads it is critical to understand the details of your cloud provider’s service level agreement (SLA) and recognize that providers operate on a shared responsibility model. That means there are many things the provider is responsible for, but the workloads you’ve got running on their infrastructure are not among them. With that in mind, we’ll need to focus on three core goals essential to building and maintaining highly available, resilient cloud workloads:
Designing for application-level resilience and high availability is predicated on recognizing that everything fails. That’s not pessimism, but realism, and embracing this fact gives you a leg up in architecting resilient IT. Hardware breaks down, disasters occur, mistakes are made, software incompatibilities are common, and limits are exceeded that result in loss of service. There are four categories of failure that need to be taken into consideration when designing for resilience and high availability:
Having identified the primary challenges to maintaining service uptime and continuity, let’s explore an approach to achieving resilience through high availability, disaster recovery, and the process of continuous improvement.
High availability is often thought of as measured by “X Nines,” representing the percentage of time a service is operational over the course of a specified time frame, usually a year. Six nines of availability, for example, means that a service can be expected to run 99.9999% of the time, or 8759.99 hours out of 8760 in a year. That sounds good until a disaster happens. Then we shift to disaster recovery, or the ability to restore a service and its associated data quickly and correctly when things go wrong. Disaster recovery is often measured and evaluated by a recovery point objective (RPO), which is the maximum acceptable amount of data loss, and a recovery time objective (RTO), which is the maximum acceptable amount of time a service can be down.
By learning from our mistakes, incidents, and the ongoing process of testing, observing, and evaluating IT operations, we apply new information in the goal of continuous improvement to get peak performance out of our investments in IT. But because we’re addressing resilience and high availability in the context of workloads operating in the cloud, we should understand the shared responsibility model that most cloud service providers use. Details may differ from provider to provider, but the shared responsibility model of cloud services is your vendor’s statement of responsibility for maintaining its infrastructure and ability to deliver storage and compute capacity in a region and availability zone where you have a need. In return, you accept responsibility for the configuration, maintenance, availability and operation of the workloads you choose to run on your vendor’s cloud.

SIOS Technology
A cloud service provider will typically operate and maintain physical infrastructure in different areas around the world, with multiple availability zones in each area. Each availability zone will have one or more data centers with its own power, cooling, and other operational support. Data centers are typically located far enough from each other to minimize the chance that a natural or regional disaster will affect multiple data centers, but close enough that they can operate as a single, logical data center — thereby maximizing bandwidth and throughput, while minimizing latency. This is redundancy at scale that eliminates a single point of data center failure.
To build out or retrofit your infrastructure for application-level resilience and high availability, there are four things you must have: clustering, data replication, failover, and disaster recovery. Let’s look at each and how to architect for them.
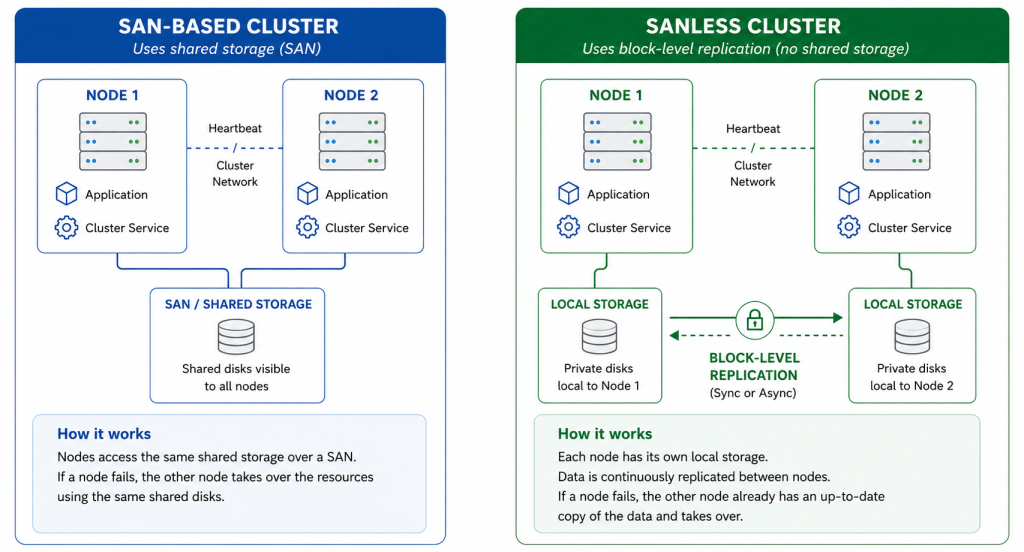
Clustering is the practice of connecting like and complementary systems to improve availability and reliability. Think of it as putting into practice the maxim “the whole is greater than the sum of its parts.” Traditionally, clustering was achieved using hardware, specifically storage area networks (SAN), to connect and support systems in a physical data center. However, in the cloud age, hardware-based clustering has proven to be expensive and inflexible. Software-based SANless clustering with products such as SIOS LifeKeeper delivers all the benefits of the traditional approach while also working better in cloud and hybrid environments.

SIOS Technology
SANless clusters enable the configuration of nodes based on the organization’s operational priorities and work easily for enterprises running geographically distributed data centers or cloud availability zones. Because SIOS LifeKeeper supports single-site, multi-site, cloud, or mixed environments, and affords real-time access to operational data during incidents requiring failover, it is ideal when mission-critical workloads are distributed across multiple providers. LifeKeeper clusters create redundancy and eliminate single points of failure, both of which are necessary for achieving high availability. For enterprises operating hybrid or multi-cloud infrastructure, this enables you to shift to secondary resources should your primary service experience an outage.
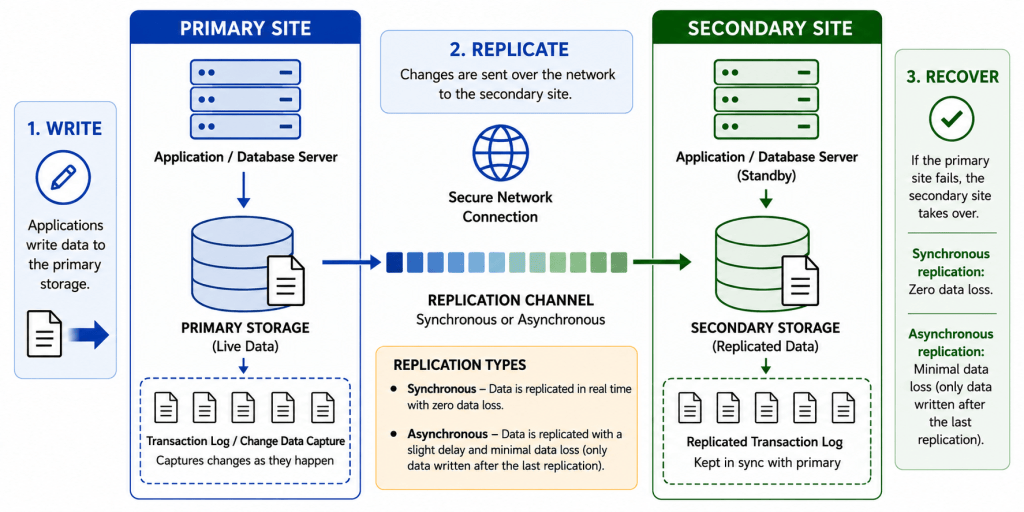
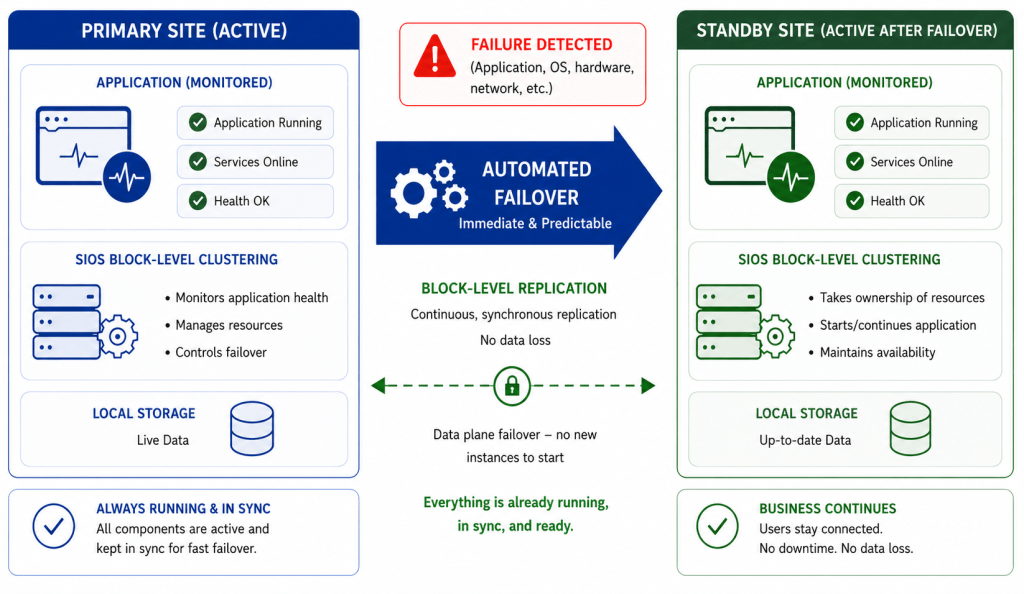
IT operations and your mission-critical applications rely on data, so it’s vital to keep data in sync between nodes in real time, whether synchronously or asynchronously, depending on the application. When working to achieve high availability, it’s important to monitor the health of infrastructure elements and the applications you’re running. This ensures that downtime affecting the application and any downstream dependencies is detected so that failover and recovery to a standby node can occur automatically. When everything is in sync and data replication is happening, this ensures complete readiness; there’s no need to rebuild a database or for any manual operations. And with SANless clusters using SIOS DataKeeper, this will happen across availability zones, regions, and to or from on-premises, cloud, or multi-cloud resources in hybrid environments.

SIOS Technology
What’s important here is that the software you use for SANless clustering be application aware. That’s SIOS LifeKeeper. Because high availability and resilience mean not just failing over to standby infrastructure resources, but for properly failing over mission-critical workloads (think SQL Server, SAP, Postgres, or industry-specific applications like Meditech), the software needs to understand how those applications work so that they can recover and restart cleanly. Otherwise, when failover occurs, there’s a good chance that workload is not going to be available, or it could be out of sync. When your software is application-aware, failover and recovery is fast and predictable with no API dependencies or last-minute provisioning.
With SIOS SANless application-aware clustering and replication in place, you can automate real-time failover and achieve the goal of high availability and resilience. Because we’ve chosen a software-based approach, failover occurs in the data plane, so there’s no need to spin up a new instance following an incident. Everything is already running, in sync, and ready. Furthermore, failover is immediate and it’s predictable. That is what you need when dealing with mission-critical workloads. Consider that many of the mission-critical applications you use were not designed to operate in the cloud, so even if your infrastructure is resilient, the application itself represents a single point of failure. Without replication, application monitoring, and real-time failover automation, you risk loss of revenue, security degradation, or worse.

SIOS Technology
Depending on the size of your enterprise and the industry in which it operates, an hour of downtime can cost $1 million or more, and 90% of organizations report costs of at least $300,000 per hour. Beyond that simple loss of revenue are soft costs associated with reputation damage, lost productivity, missed transactions, and more. Revenue protection is only part of the equation; it is about protecting the business.
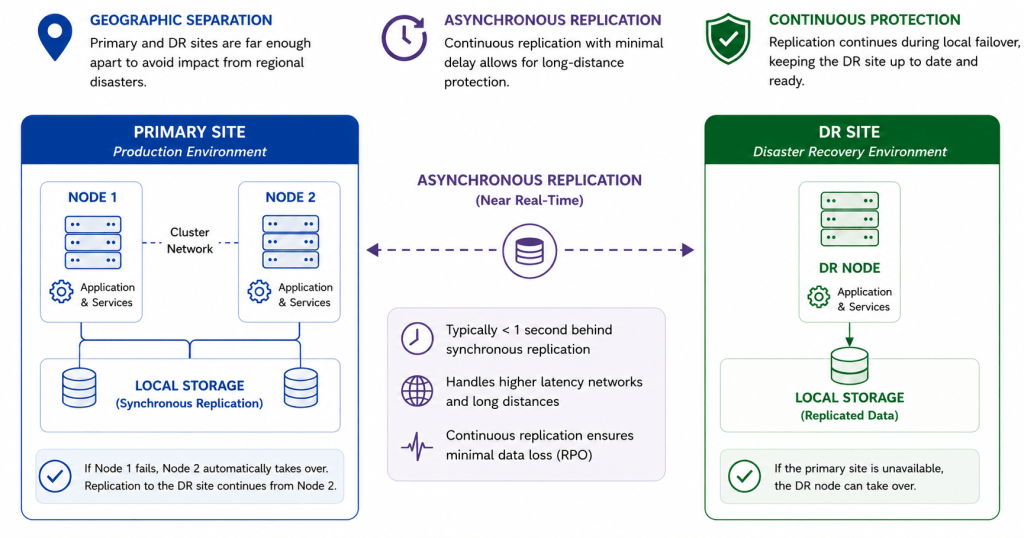
Any design for high availability and resilience must also take into consideration the risk of a non-IT disaster that disrupts operations. Natural disasters like fires, earthquakes, and floods, or disasters caused by humans like the accidental severing of a trunkline or an act of sabotage conspire to bring operations to a sudden halt. Clustering, replication, and failover all play into disaster recovery, but there are additional considerations that must be addressed. For disaster recovery (DR), you’re going to want geographic distance between your primary site and your DR site to minimize the risk that a regional event doesn’t affect both. That means you’re going to want asynchronous (or near real-time) data replication.

SIOS Technology
Asynchronous replication is typically only a second or less behind synchronous replication, so it is de facto real-time, but that delay allows you to replicate across higher-latency networks and across longer distances. And because replication is happening continuously, even if you have a local failover between node one and node two, replication to the DR node doesn’t stop. Instead, when node two comes online it becomes the source of the mirror replicating to the DR site and back to node one once it is restored.
Beyond the simplicity and cost advantages that come from taking a software-based approach to designing your cloud and hybrid infrastructure for high availability there is another big benefit. You are also better prepared to respond to the increased pressure on rapid implementation of software updates and security patches. No one wants to be the person responsible for taking too long to patch for a vulnerability, but every time you touch a system, you’re introducing the risk of error. That risk is greater when dealing with the cloud where you have less control over the underlying infrastructure, more abstraction, and a lot more moving parts.
In short, patches can break things as well as fix them. They have thus become a significant contributing factor as a cause of downtime. With SANless clusters you’re able to minimize that risk by enabling rolling updates, meaning you can patch a secondary server, verify that the patch didn’t break anything, and then patch the original server where the primary application is still running. If something does break on the secondary server, the primary is unaffected and you can quickly recover to the previous state while you figure out what went wrong. This simplifies the process of executing ad hoc patches and performing planned maintenance, mitigating the associated risks.
An investment in cloud and hybrid infrastructure and services doesn’t have to put IT operations at the mercy of a third party. With the right approach, you can design for high availability and resilience and keep your mission-critical workloads running in the cloud even when things outside of your control go wrong.
—
New Tech Forum provides a venue for technology leaders—including vendors and other outside contributors—to explore and discuss emerging enterprise technology in unprecedented depth and breadth. The selection is subjective, based on our pick of the technologies we believe to be important and of greatest interest to InfoWorld readers. InfoWorld does not accept marketing collateral for publication and reserves the right to edit all contributed content. Send all inquiries to doug_dineley@foundryco.com.

Microsoft is betting that the integration of HorizonDB, the cloud-native PostgreSQL alternative it is developing, with Azure will attract more enterprise AI and agentic workloads to its cloud services.
Enterprises may not be willing to take that bet.
It’s been nine months since Microsoft unveiled HorizonDB, but the service remains in public preview with no announced general availability date. Why put AI projects on hold waiting for HorizonDB to arrive, when AWS, Google, Databricks, Snowflake, and others already have production-ready PostgreSQL services positioned for the same AI workloads that Microsoft says it is building HorizonDB to handle?
AWS has had the longest head start. Aurora PostgreSQL became generally available in 2017 and has since evolved from a cloud-native PostgreSQL database into an AI-ready service with vector search and integrations with Amazon Bedrock. Similarly, Google’s AlloyDB, which followed in 2022, now includes AlloyDB AI with vector search, embeddings and model interaction for generative AI and agentic applications.
Databricks and Snowflake, too, have their own platform-centric services in the form of Lakebase, which became generally available on AWS and Azure this year, and Snowflake Postgres, which was made generally available in February 2026.
As the latecomer, when Microsoft pitched HorizonDB at Ignite in November 2025 it talked up its new architectural approach to cloud-native PostgreSQL, built around disaggregated compute and storage and a database-as-log design. The hyperscaler also positioned native vector search and deep integration with Foundry and Fabric as key differentiators for AI-heavy workloads.
Those architectural differences may not be compelling enough for CIOs to wait for HorizonDB to become generally available, though.
“Most enterprises with urgent needs will not wait. A long preview window creates uncertainty around SLAs, pricing, operational maturity, and roadmap confidence,” said David Linthicum, an independent cloud consultant.
And, said Stephanie Walter, practice lead of AI stack at Hyperframe Research, enterprises cannot build mission-critical production plans around an undefined GA date, regional footprint or support commitment.
Given the difficulty of unwinding a poor database choice, enterprises will approach unknown quantities with caution.
“Database platforms eventually become sticky control points. Once the database is connected to the rest of the application, analytics, AI, and governance stack, switching becomes a business transformation rather than just an infrastructure swap,” said Michael Ni, principal analyst at Constellation Research.
In the case of a cloud database, there’s also the unwelcome possibility of “huge egress fees” in case of change, said Bradley Shimmin, lead of the data and analytics practice at The Futurum Group.
All that uncertainty is likely to lead enterprises to restrict HorizonDB to experimental use cases for now, Shimmin added.
Analysts also questioned whether HorizonDB’s technical differences will show up in performance benchmarks.
Microsoft has said HorizonDB can deliver up to three times the throughput of open-source PostgreSQL, but makes no comparisons with rival offerings such as Aurora or AlloyDB that it will compete with, Walter said.
The bigger question, according to Igor Ikonnikov, advisory fellow at Info-Tech Research Group, is whether those performance advantages, still largely on paper, translate into a meaningful difference in production.
“A database with a better compute benchmark can still be more expensive once resilience and ecosystem costs are included,” Ikonnikov said.
The economics also point to another HorizonDB limitation, particularly for workloads that are not continuously running, said Advait Patel, senior site reliability engineer at Broadcom.
HorizonDB currently uses provisioned compute rather than a serverless, scale-to-zero model, meaning customers continue to incur compute charges while an instance is provisioned, even if its workload is intermittent or idle, Patel said.
There are developer considerations too.
HorizonDB’s PostgreSQL compatibility does not necessarily mean every existing PostgreSQL application will move cleanly as in its current form the database supports only an approved set of PostgreSQL extensions rather than arbitrary ones, Walter said.
For enterprises already deeply invested in Microsoft’s Azure ecosystem, those limitations may not be enough to rule out waiting for HorizonDB, Patel said: The chance to integrate the database with AI services and the wider Microsoft stack may outweigh immediate availability, he added.
That calculus also reflects how enterprises typically make database decisions in the first place: not by comparing databases in isolation, but by weighing how well they fit into the broader technology stack, including the cloud platform they have standardized on, Ikonnikov said.
For Azure shops, the choice may therefore be less about moving an existing workload away from Aurora or AlloyDB and more about whether a new Azure workload should start on Azure Database for PostgreSQL today or wait for HorizonDB when it becomes available, he said.
That may be an open question for some enterprises, said Devin Pratt, research director at IDC. “Plenty of organizations are still mid-decision, not locked in,” he said.
Microsoft still won’t say exactly when HorizonDB will launch, with Shireesh Thota, corporate vice president for Azure Databases at Microsoft, saying only, “General availability for Azure HorizonDB is currently targeted for the second half of 2026.”
That narrows it down to a period of a little over four months, including Microsoft’s FabCon and Ignite conferences — an eternity in AI.

Bending Spoons has snapped up Airtable to add to its portfolio of software companies, alongside AOL, Evernote, WeTransfer, Brightcove and Vimeo
Airtable made its name as a builder of low/no code database services, aimed particularly at non-technical staff, but is now one of many vendors facing financial difficulties in the face of the SaaS/AIpocalypse. The arrival of AI coding tools, which offer non-technical employees more flexible ways to build business applications, has hit demand for its services.
Bending Spoons bought Airtable in a deal it valued at just $1.285 billion, a far cry from the $11.7 billion Airtable was worth at its peak.
Bending Spoons has built its portfolio by buying once-successful companies like Airtable that have struggled to cope with newer, nimbler competitors or failed to adapt to emerging technologies. Bending Spoons takes these companies, cuts costs and markets them aggressively with the goal of returning them to profitability.
“Airtable is a pioneering brand reshaping how teams organize data and manage critical workflows. We’re committed to investing in Airtable for the long run, and doubling down on its core strength: bringing teams and workflows together in one flexible workspace. We plan to expand what can be done across the full spectrum of work and make Airtable even more valuable to customers at every scale,” said Luca Ferrari, Bending Spoons CEO and co-founder.
This article first appeared on InfoWorld.

AWS is finally adding native vector search to its managed NoSQL database DynamoDB, which is typically used to store high-volume operational and transactional data.
The update, according to analysts, removes complexity for development teams that are trying to maintain separate vector databases for a rapidly growing class of AI and agentic applications that rely on real-time access to operational and transactional data to improve the accuracy and relevance of their responses.
“This collapses a common two-database architecture into one operational data layer. Developers can update an item and its vector representation together, use familiar DynamoDB APIs, and avoid building a separate synchronization pipeline. That should materially shorten time-to-market for AI features built around existing DynamoDB data,” said Stephanie Walter, practice lead of the AI stack at HyperFRAME Research.
Prior to the update, enterprises using DynamoDB typically had to copy data into OpenSearch or another vector database, such as Pinecone and Weaviate, often using DynamoDB Streams or custom pipelines, which meant operating two data layers and managing embedding generation, backfills, retries, schema changes, security policies, and synchronization, Walter noted.
That dependence on two separate data layers, Walter pointed out, added to query latency and increased the risk of the vector index lagging behind the operational record.
Such delays, according to Ashish Chaturvedi, executive research leader at HFS Research, can have real consequences for AI agents: “If an agent is acting on what it retrieves, a synced-five-minutes-ago copy can mean a confident wrong action.”
Beyond improving data freshness, eliminating a separate vector database could also lower cloud and operational costs, Chaturvedi said: “Maintaining a second database meant paying at least $700 a month for a second database regardless of usage.”
For CIOs, those benefits combined could translate into lower total cost of ownership and simpler governance as enterprises scale AI applications, Chaturvedi added.
“It is a real consolidation for CIOs: fewer systems to secure, no pipelines to maintain, fresh data. Add to it usage-based cost, which means no standing minimums for idle infrastructure, even at trillion-vector scale,” Chaturvedi noted.
The architectural simplification could also make AI adoption easier for business leaders by eliminating the need to staff and govern a second data platform, said Michael Leone, principal analyst at Moor Insights & Strategy.
Native vector search capabilities have been gaining popularity over the past few years. Over the last three years, AWS has steadily expanded vector search across its database portfolio, adding support to Aurora PostgreSQL through pgvector, Amazon MemoryDB for Redis and Amazon DocumentDB as enterprise demand for generative AI applications has grown.
Rivals have followed a similar path, with MongoDB, Microsoft, Google Cloud, Oracle and Couchbase integrating native vector search into their databases to support retrieval-augmented generation (RAG), AI agents and other generative AI workloads.
These announcements themselves reflect a broader convergence in the database market since the rise of generative AI. While specialized vector databases have expanded beyond similarity search by adding SQL, NoSQL and operational database capabilities, mainstream operational databases have been embedding vector search and RAG capabilities into their core platforms, allowing enterprises to consolidate AI and transactional workloads on fewer data platforms.
AWS has not shared details on the rollout of DynamoDB’s native vector search capability, including its availability timeline or the AWS Regions where it will initially be offered.

Microsoft has had a narrow escape from total embarrassment: A security company uncovered a critical vulnerability that could have compromised all Azure Cosmos DB databases — both those of customers and Microsoft’s own.
Google subsidiary Wiz found a flaw in the database’s Gremlin API, usually used for storing and managing property graph data.
If bad actors had discovered it first, they could have exploited it to acquire what Wiz called the Cosmos Master Key, which would have enabled them to use the primary key of any Cosmos database, resulting in read and write access to any account. They would also have had access to a list of every database on the service, with identifiers such as subscription and tenant IDs.
Azure Cosmos DB is a NoSQL database that underpins Microsoft’s cloud services. It can be accessed through SDKs for framework such as Python, Node.js, Java, and .NET.
Wiz described how it discovered the vulnerability in a blog post. It disclosed details of the flaw to Microsoft in November 2025.
Microsoft deployed a hot fix within two days, but it took another eight months to re-engineer the infrastructure, removing the Cosmos Master Key and introducing new guardrails to Cosmos DB to prevent similar attacks.
It is not the first time Cosmos DB customers’ primary keys have been under threat: In 2021, Wiz found a flaw in data exploration tool Jupyter Notebook that could be exploited to access the database keys and other secrets.
This article first appeared on CSO.

Oracle on Tuesday described new EBCDIC character set compatibility features in Oracle AI Database for customers transitioning from legacy databases on IBM mainframes.
In its post, Oracle noted that EBCDIC compatibility has historically been one of the top technical challenges for enterprises re-platforming to use newer, ASCII-based databases while continuing to use proven legacy applications.
“Achieving this goal requires more than simply moving data. It requires preserving the EBCDIC compatibility on which existing applications depend,” wrote Michael Yau, VP for Oracle Database Globalization Engineering. The feature rollout “addresses two fundamental challenges of preserving EBCDIC compatibility: accurate character encoding conversion and preservation of EBCDIC binary ordering.”
He added: “These client character sets implement IBM Character Data Representation Architecture (CDRA) code page definitions, providing source-to-target character mappings that are compatible with IBM’s published standards. This enables accurate and predictable character encoding conversion during data migration and subsequent database client/server communication.”
Yao observed that this is important because these mainframe migrations can be very complex.
“Many legacy EBCDIC applications, such as those written in COBOL, implicitly rely on the EBCDIC binary ordering defined by IBM EBCDIC code pages. SQL predicates that compare character values, perform range searches, or sort query results often assume this ordering,” he wrote. “After migration to an ASCII-based Oracle AI Database character set, these same SQL statements can produce different results, not because the data changed, but because the database’s default binary ordering follows that of the ASCII-based database character set rather than the source EBCDIC code page.”
While consultants generally applauded the new features, some questioned whether this will simply shift enterprise dependency on IBM to dependency on Oracle.
Sanchit Vir Gogia, chief analyst at Greyhound Research, is one of the fans.
“Oracle has repaired one of the oldest silent faults in mainframe migration: EBCDIC ordering, the muscle memory of the legacy estate. Preserve the data and lose the ordering, and a query returns the wrong record while every dashboard stays green,” he said. “The application runs and the query completes. The answer is simply wrong.”
Gogia noted that the new feature is “not a modernization suite. It is a compatibility repair, narrow and genuinely useful, which CIOs who have bled on past migrations will read with equal parts relief and suspicion.”
AJ Thompson, CCO at UK IT consulting firm Northdoor, agreed that the Oracle announcement addresses a genuine technical barrier rather than just being a marketing gimmick, so it is worth taking seriously as a re-platforming enabler. “The two problems it solves, EBCDIC to ASCII character conversion and preserving EBCDIC binary sort ordering, have historically been real blockers for allowing COBOL to move away,” he said.
But, he cautioned, CIOs must also take resiliency challenges seriously. “Mainframes are not chosen primarily for character encoding, they are chosen for benefits like decades of proven uptime, IBM Z’s redundancy architecture, and workload isolation,” he pointed out.
“Oracle’s announcement solves a data compatibility problem, not a resilience or availability one. A client with genuinely mission-critical, zero-downtime workloads will still need convincing on the availability and disaster recovery side before moving [to the cloud], and Oracle’s own resilience claims would need scrutiny on their own merits, quite separate from this EBCDIC work.”
Mike Wilkes, enterprise CISO at Aikido Security, added that Oracle is leveraging IT desperation to squeeze long-term value from legacy systems.
“I have always believed that Oracle will own the very last white-knuckle-grip workloads that migrate from on-premises data centers into the cloud,” he said. “This announcement certainly demonstrates that they understand their position in the world of cloud service providers. They are not the biggest, they are not the oldest, and they are not the most technically advanced. But they do own the market share for the trailing edge of cloud adoption.”
He pointed out that the greatest barrier to cloud migration is not containerizing modern applications, it is the decades of business logic buried inside COBOL applications and EBCDIC-encoded data.
“Oracle’s EBCDIC compatibility features acknowledge a practical reality: organizations are not rewriting these systems from scratch,” he said. “If Oracle can reduce the cost, risk, and operational disruption associated with moving those workloads, the announcement represents meaningful value for IT teams that have been delaying modernization because the migration path was simply too complex or too expensive.”
Then again, Wilkes noted, there is the potential for increasing vendor lock-in.
“Compatibility layers almost always increase long-term dependence on the platform providing them,” he said. “Rather than eliminating legacy technology, they abstract it behind Oracle’s database and cloud ecosystem, making future migrations potentially more difficult. Enterprises should view these tools as transition accelerators rather than permanent architecture.”
Thus, he said, if they use the opportunity to gradually modernize applications and data models, there is substantial value, but if they simply relocate technical debt into Oracle Cloud, they may find that they have exchanged one form of legacy lock-in for another.
Matt Kimball, VP and principal analyst with Moor Insights & Strategy, also saw the Oracle move as a good one, but stressed that while it should make things easier for organizations, re-platforming still won’t be easy because EBCDIC migration isn’t just a character-conversion exercise. However, “Oracle’s built-in character-set support and EBCDIC collations move part of that compatibility burden into the database, making it easier to preserve existing application behavior,” he said.
Ishraq Khan, CEO of coding productivity tool vendor Kodezi, agreed.
“One of the biggest obstacles to leaving mainframes is decades of applications built around EBCDIC encoding and legacy data formats. If these compatibility features reduce the amount of code that needs to be rewritten, they can lower migration risk, cost, and implementation time,” Khan said. But, he added, organizations should also consider whether these features simply make migration easier, or make future moves more difficult.
This article originally appeared on CIO.com.

Oracle’s July 2026 Critical Patch Update, its largest ever, contains 1,449 new security patches spanning 32 product families, from Oracle Database and E-Business Suite to PeopleSoft, GoldenGate, Java SE, and Fusion Middleware.
Fusion Middleware was particularly hard hit, with new security patches for 355 security vulnerabilities, 219 of them remotely exploitable without authentication, meaning they can be exploited over a network without requiring user credentials. Ten of them scored a “perfect” 10.0 on the Common Vulnerability Scoring System (CVSS).
These included easily exploitable vulnerabilities allowing unauthenticated attackers with network access via HTTP to compromise Oracle Data Integrator, Oracle Access Manager, Oracle HTTP Server, Oracle Platform Security for Java, Oracle WebCenter Content, Service Delivery Platform, or Oracle Weblogic Server Proxy Plug-in,
No other products were found to have quite such extreme vulnerabilities, but there were plenty of others scoring almost as badly.
The most severe flaw Oracle patched in its flagship database product is CVE-2026-61211, a vulnerability in the RDBMS component’s DBMS_CLOUD package with a CVSS score of 9.9.
This easily exploitable vulnerability allows a low-privileged attacker having Execute DBMS_CLOUD privilege with network access via Oracle Net to compromise the RDBMS, Oracle said in the patch update statement. “While the vulnerability is in RDBMS, attacks may significantly impact additional products (scope change). Successful attacks of this vulnerability can result in takeover of RDBMS,” it warned.
The flaw affects Database Server versions 19.3 through 19.31 and 23.4.0 through 23.26.2.
Sanchit Vir Gogia, chief analyst at Greyhound Research, said the 9.9 score should be read as serious but conditional. Exposure depends on configuration, he said: On customer-managed databases, DBMS_CLOUD is absent until installed, and grants and network access lists determine the radius from there. “Where DBMS_CLOUD is broadly granted and reachable, the emergency is real and the window is seventy-two hours; where it is absent, the accelerated database wave will do.”
Vibhum Dubey, a cybersecurity researcher and red teamer, said the flaw stood out to him because it checks several boxes that concern defenders.
“Database servers often hold an organization’s most valuable data, so even if exploitation is not publicly observed yet, I don’t think this is the kind of issue you leave until the next routine maintenance window if your environment is exposed,” Dubey said.
A second Database Server flaw, CVE-2026-47040, affects Connection Manager in Oracle Net Services, is remotely exploitable without credentials. Oracle’s risk matrix lists six Database Product vulnerabilities in this cycle as reachable over a network with no authentication required, the statement added.
CVE-2026-7383, an OpenSSL-related TLS vulnerability, affects two products, Database Server and Autonomous Health Framework, since both bundle the same third-party component. Oracle’s advisory notes the Database Server patch for that CVE also resolves 19 related OpenSSL CVEs bundled into the same fix.
Oracle GoldenGate received 27 new patches, nine of which do not require authentication to exploit, including CVE-2026-2332, a flaw in the Big Data and Application Adapters component tied to Eclipse Jetty, the statement added.
There were also two critical flaws in Oracle’s TimesTen in-memory database.
The remainder of the release spans E-Business Suite, WebLogic Server, PeopleSoft, Siebel, JD Edwards, Communications, Retail Applications, Utilities Applications, MySQL, Solaris and VM VirtualBox.
Gogia said the volume itself marks a shift.
“At 1,449 patches, against 481 in April 2026 and 309 a year earlier, patch load has outgrown the queue built to hold it,” he said. He recommended a tiered response: “The reachable and the reported inside seventy-two hours, the trusted core inside ten days, the rest by risk before the October release.”
He also flagged a specific risk in how organizations might triage E-Business Suite. “Oracle’s advisory concedes that E-Business Suite exposure sits partly in underlying Database and Fusion Middleware versions outside the E-Business Suite matrix. The fastest way to mis-prioritise this release is to patch by product logo instead of trust boundary.”
The July release is the third quarterly Critical Patch Update of 2026, and the first since the introduction in May of the monthly Critical Security Patch Update program.
Gogia said Oracle has effectively layered a second cadence on top of the existing one rather than replacing it.
“Quarterly Critical Patch Updates remain and stay cumulative; monthly Critical Security Patch Updates now sit on top,” he said, adding that enterprise adoption of the new rhythm remains low because of “certification obligations, regression exposure and scarce specialist hours.”
Dubey made a similar point about organizational readiness: “In large enterprises, patching is rarely a technical problem. It is an operational one. Database administrators, application owners, infrastructure teams, business stakeholders, and change advisory boards all have to align.”
Niyati Daftary, principal analyst at Gartner, said the release underscores a broader shift in how patching is approached.
“Patching is no longer a race to remediate every vulnerability. It is a discipline of identifying the exposures that matter most and reducing business risk as efficiently as possible,” she said, adding that organizations should prioritize based on exposure, business impact and exploitability, starting with internet-facing assets and mission-critical systems.
Daftary pointed to continuous threat exposure management and adversarial exposure validation as increasingly relevant frameworks, since CVSS scores “measure theoretical severity rather than actual enterprise risk.” Patching alone will not be sufficient, Daftary said, and organizations should continue investing in defense in depth, including behavioral threat detection and incident response.
Oracle’s next cumulative Critical Patch Update will come on Oct. 20, 2026, with smaller Critical Security Patch Updates on Aug. 18 and Sept. 15.
This article first appeared on CSO.

Oracle is expanding its Cloud@Customer on-premises portfolio with a managed database offering that it says will enable enterprises to run databases, applications, and AI agents in their own data centers, helping CIOs modernize mid-sized workloads while meeting data residency, regulatory, and low-latency requirements.
The hybrid cloud offering, Base Database Cloud@Customer, combines existing database and infrastructure services such as the Base Database Service and Data Infrastructure Cloud@Customer X11 platform. It is designed for enterprises that do not need the scale of Exadata Cloud@Customer but still want their infrastructure and AI capabilities on-premises, managed by Oracle, the company said.
The Cloud@Customer X11 platform itself consists of two Oracle X11 compute servers and shared all-flash storage, offering up to 60 usable processor cores and 660 GB of memory per server, 47.2 TB of storage, and 10/25 GbE networking.
Analysts see the new offering filling a gap for enterprises that want the operational and economic benefits of the cloud but cannot send their data to a public cloud because of legal restrictions or technology limitations.
These enterprises, according to Ashish Chaturvedi, executive research leader at HFS Research, are likely to be in regulated industries such as financial services, healthcare, government, and defense that must comply with data residency requirements, or needing low-latency access from remote sites to operational databases.
The offering could also appeal to enterprises modernizing mid-sized workloads at remote locations or within individual business units that could never justify the investment in a full Exadata rack, said Amit Chandak, chief analytics officer at IT consulting firm Kanerika.
In all cases, Chaturvedi said, the appeal of the offering is its managed nature, which takes away the burden of looking after the underlying infrastructure.
Deployment and maintenance becomes easier too, said Michael Leone, principal analyst at Moor Strategy and Insights: “They get automation that mid-size teams rarely have the staff to build. Clustering, patching, standby databases, and backups arrive configured instead of hand-assembled because the offering is managed.”
The economics are equally compelling, Chaturvedi said. The pay-as-you-go pricing model, combined with online compute scaling, helps enterprises avoid overprovisioning and paying license fees for idle cores, which is a “classic waste” of fixed on-premises systems, he said.
Beyond the operational and economic benefits, the architecture of the new offering enables databases, applications, VMs, and AI agents to be collocated on the same platform, removing what Chaturvedi called “the single biggest blocker” to AI adoption in regulated environments: the need to keep private data behind the firewall.
“For a CIO in a regulated sector who wants to deploy AI agents but can’t let regulated data touch an external model API, that’s a real unlock,” Chaturvedi said.
More so because most AI offerings, at least in their present form and state, cannot guarantee sensitive data protection, said Igor Ikonnikov, advisory fellow at Info-Tech Research Group.
Even if Base Database Cloud@Customer turns out more expensive than fully cloud-based options, “It’s still attractive as it eliminates reputational and economic risk caused by possible AI-induced data leakage,” Ikonnikov said.
The offering’s consolidation of databases, applications, and AI agents will also simplify deployment of AI-based workflows, said Forrester principal analyst Noel Yuhanna. “It reduces stack complexity and helps accelerate development cycles, deliver real-time data, and eliminate data movement challenges.”
Despite those advantages, Chandak cautioned that the offering is unlikely to see broad adoption outside Oracle’s existing customer base: “If a company isn’t already on Oracle, the pull is weak. You don’t buy into Oracle’s database just to get this.”
Enterprises seeking similar hybrid cloud capabilities have no shortage of alternatives: AWS, Microsoft, Google Cloud, IBM, Dell Technologies, and HPE all offer combinations of on-premises infrastructure, cloud management, and AI services.
However, those alternatives typically require customers to integrate multiple software and hardware components rather than consume them as a single managed offering.
Oracle’s differentiation, although narrow, is hard to match, Chaturvedi said: “The vertical integration of database, engineered hardware, cloud management, high-availability architecture, and now private AI, all engineered together and delivered as a managed on-prem subscription should be genuinely convenient and attractive.”
The offering is compatible with Oracle AI Database 26ai and Oracle Database 19c in Enterprise Edition and Standard Edition configurations. It also supports Oracle Real Application Clusters, Oracle Data Guard, and Zero Data Loss Recovery Appliance through Oracle-managed cloud automation for high availability and disaster recovery, the company said.
Base Database Cloud@Customer is now generally available, Oracle said. It did not provide pricing.
This article first appeared on CIO.

Separating transactional databases from analytical systems was, until recently, considered good architecture. Now, as enterprises adopt AI agents that continuously read, reason over, and act on business data, data warehouse and database vendors are increasingly deciding that separation has become a liability.
Just weeks after Databricks unveiled its Lakehouse Transaction and Analytical Processing (LTAP) offering based on Neon Postgres to bring operational (OLTP) and analytical (OLAP) processing closer together, EnterpriseDB (EDB) has introduced converged analytics capabilities for its managed EDB Postgres AI database service with the same intent.
Both vendors are responding to the same pressure of enabling AI agents for enterprises to operate on fresh operational data without waiting for pipelines and replicas, but EDB argues its approach starts from a fundamentally different place.
“Databricks is building from the lakehouse outward, trying to pull transactional capability in through Lakebase,” said Max Romanenko, chief engineering officer at EDB, while “we’re building from the operational layer with Postgres, which is where enterprises already run their most critical workloads, and expanding from there.”
In contrast to Databricks’ lakehouse-centric LTAP, EDB keeps Postgres as the operational source of truth and uses Apache Iceberg as a shared catalog layer connecting Postgres with ClickHouse, WarehousePG, and Spark compute engines, Romanenko said.
In this way, operational data remains in Postgres while historical and tiered data is stored in Iceberg-managed object storage, allowing analytical engines to query the same data through a common catalog without requiring separate copies or ETL pipelines, he said.
That architectural distinction matters to EDB, according to Romanenko, because the vendor is targeting enterprises that want AI and analytics capabilities without moving sensitive data into a cloud-managed platform: “For us, it’s always been about the data sitting on infrastructure the customer owns and controls.”
EDB’s promotion of control “will resonate with CIOs focusing on sovereignty, regulated data, and hybrid deployment,” said Stephanie Walter, practice leader of AI stack at HyperFrame Research. “This should enable them to run AI and analytics closer to the data, on infrastructure that their enterprise controls, without creating yet another proprietary data estate.”
For Ashish Chaturvedi, leader of executive research at HFS Research, EDB’s approach in converged analytics will offer more predictable costs than Databricks LTAP for CIOs already struggling to manage their analytics and AI budgets.
EDB’s per-core pricing model can make costs easier to forecast than consumption-based cloud data platforms, where query volumes, AI workloads, and data processing demands can cause bills to fluctuate, Chaturvedi said.
But predictable bills are not necessarily lower bills, warned, Igor Ikonnikov, advisory fellow at Info-Tech Research Group. “The hardware requirements for high-speed operational data processing are higher and relatively more expensive compared to cheap lakehouse storage,” he said.
EDB’s architecture could also simplify data governance by reducing the number of platforms enterprises need to manage. Since operational, analytical, and AI workloads can access data through a common Postgres-Iceberg foundation, enterprises may be able to avoid deploying and governing multiple specialized data stores, and so have fewer systems to license and secure, according to Devin Pratt, research director at IDC.
EDB’s converged analytics could also simplify operations for developers and data engineering teams.
Its architecture reduces the number of systems developers must integrate and maintain, while eliminating much of the pipeline work traditionally required to move data between transactional and analytical systems, according to Walter.
And, said Pratt, “Zero-ETL means far less plumbing to build and break, so engineers spend their time creating value.”
EDB and Databricks are not the only ones pursuing converged analytics to support agentic systems and other applications needing immediate access to operational data, historical context, and governance controls.
Snowflake has been expanding support for operational workloads by embracing open table formats,and Microsoft has combined transactional and analytical services under a broader data architecture via its Fabric platform.
Converged analytics, though, was only one part of EDB’s update to its Postgres AI platform.
It has also made generally available what it calls an “agentic database” feature, designed to automate routine database administration tasks.
The system continuously monitors hundreds of operational and performance metrics, detects anomalies, recommends corrective actions, and, where enterprise policies permit, can automatically apply fixes, the company said.
These automated agents can help enterprises optimize and tune their databases up to 10 times faster, it said.
Walter remained skeptical: “It is more an evolution of autonomous database concepts than a wholly new category. Oracle and other database vendors have offered autonomous database capabilities for years.” Where EDB can differentiate itself, she said, is in extending those autonomous capabilities with AI-driven reasoning, automated remediation, and governance controls that allow enterprises to determine how much authority the system receives.

Model Context Protocol (MCP) has gained considerable momentum as a standard connector between LLM-powered tools and local systems, internal and external APIs, and data sources. From major clouds to devops tools, MCP servers are enabling powerful, AI-powered development and operations capabilities through natural language commands.
Nowhere is this more true than in the world of databases. Most major database platforms now support agentic access through MCP servers. Using an MCP server for databases, you and your AI agent proxies can perform lookups, create and update data, and perform administrative tasks without you having to write SQL by hand.
The MCP server could also guide your LLMs to write new code or build automations that align with your database schema, like its tables, structure, and fields, as well as embeddings, indexes, and metadata. It could also aid debugging by enabling faster queries to surface data issues or misconfigurations, along with plenty of other possible use cases.
Below, we’ll cover official MCP servers from some of the top platform options across major database styles. Though maturity varies, the MCP servers discussed below represent some of the best vendor-backed offerings available today across relational SQL, NoSQL, graph, vector, and data warehouse systems.
These servers can be used by any MCP-compatible tool, IDE, or agent, whether it’s Claude Code, Codex, Cursor, Gemini CLI, Google Antigravity, VS Code, Windsurf, or something else. Adding them is typically simple, often involving a lightweight JSON addition to your MCP configuration file.
MySQL and PostgreSQL are the world’s most widely-used open source databases. However, in both cases, there is no canonical MCP server—what we see are different MCP servers emerging across vendors. One of these vendors is Amazon Web Services (AWS), which offers official MCP servers for Amazon Aurora, its managed relational database service compatible with both MySQL and PostgreSQL.
According to the documentation on GitHub, the Amazon Aurora MySQL MCP Server can be used to convert natural language commands into MySQL-compatible SQL queries, which can then be executed against Aurora MySQL databases. Similarly, the Aurora Postgres MCP Server provides MCP tools for working on PostgreSQL databases. The Aurora DSQL MCP Server does the same for distributed Postgres databases.
AWS provides a growing portfolio of official MCP servers across its product line, including MCP servers for other Amazon database platforms like DynamoDB, ElastiCache, and Redshift. If you’re a heavy AWS shop and you want to enable LLM interactions with your data, these are sensible choices.
BigQuery is Google’s cloud-based data analytics platform, and a popular data source for AI applications. BigQuery users with API access configured can also utilize the BigQuery MCP Server to interact with the platform using MCP-compatible AI clients.
Using the remote BigQuery MCP Server, engineers can generate and execute queries on data sources, or return metadata on datasets, tables, and schema. This can be done with a simple natural language prompt like “List the datasets in project PROJECT_ID.” Results are filterable by region, data set ID, column name, and more.
As part of Google’s fully-managed, remote-hosted MCP portfolio, the BigQuery MCP Server provides some peace of mind regarding security, maintenance, and ease of use for distributed teams. The MCP tools are subject to some limitations, however, in terms of query result size, processing time, and other factors. If you’re using BigQuery and you want more agentic control, you’ll want to check this one out.
Another important database category includes platforms designed for keyword and semantic search. In this space, Elasticsearch is commonly deployed. Instead of providing a single MCP server, Elasticsearch provides the Elastic Agent Builder, which is a more comprehensive framework aimed at agentic workflows.
Using Elastic Agent Builder, you can chat with an agent to retrieve data context from Elasticsearch data and extend it into various environments. The Agent Builder itself includes an MCP server endpoint for programmability and exposing the agent to other clients.
Unlike others on this list, this is not a direct MCP interface to raw Elasticsearch APIs. Instead, it’s an interface that exposes skills from the agent platform. This should also not be confused with the Elasticsearch MCP Server, released in mid-2025, which has since been deprecated.
A possible downside of using this utility is that it includes an additional layer between your IDE or agent and the data you’re searching. The agent setup requires a higher subscription and takes additional steps to configure compared to other MCP servers.
That said, if you want an extensible common layer to interact with both Elasticsearch and external MCP servers, while centralizing responsibilities like permissions, this is an interesting proposition.
Graph databases are another key NoSQL database type these days, specializing in using nodes and edges to accelerate queries of highly interconnected data. Of these, Neo4j is a popular graph database option.
The Official MCP Server for Neo4j works with all kinds of Neo4j deployment (desktop, sandbox, self-managed, and the managed Neo4j Aura cloud service), and allows LLM-based clients to retrieve graph schema, execute read and write statements, execute graph algorithms, and more.
In addition, several other MCP servers for Neo4j are available from Neo4j Labs. These have specialized uses, such as generating Cypher queries from natural language, maintaining an in-memory graph database, modeling and visualizing graph, and interacting with the Neo4j Aura API.
The first MCP server for Neo4j was developed in December 2024. If you’re an avid Neo4j user and want to experiment with interacting with your graph databases in a chat-infused way, these stand as an interesting platform of servers.
Google’s MCP Toolbox for Databases is a notable MCP server because it’s a popular catch-all for various database types. Unlike the other entries on this list, this server connects LLMs not to a single managed database, but unifies LLM access to multiple systems. The open source utility ships with pre-built configurations for nearly 30 databases including PostgreSQL, MySQL, SQL Server, Oracle Database, MongoDB, Redis, Neo4j, and Snowflake, as well as the databases in Google Cloud.
Once you define data sources in a tools.yaml file, you can use MCP Toolbox to perform structured queries or semantic searches against databases directly from within an IDE or agentic client using plain English. MCP tools translate commands into actions like list_tables and execute_sql.
MCP Toolbox for Databases is mature, originally built as a generative AI utility and later re-worked for MCP-style workflows. It offers numerous download, configuration, and interaction methods.
If you’re using a variety of databases on Google Cloud and elsewhere and you want an “all-in-one” MCP server, MCP Toolbox for Databases is a great place to start.
MongoDB is the popular NoSQL document-oriented database. The creators of MongoDB have released an official MCP server that works with the open-source database as well as the company’s cloud-hosted MongoDB Atlas database platform.
The MongoDB MCP Server provides a number of tools to interact with MongoDB. You can query the database, return information on collections, create or remove collections or indexes, gather statistics on database usage, and more. Other tools enable MongoDB Atlas operations, like creating users or clusters, returning cluster data, and other functions.
The server’s tools are read-only by default but can be switched to allow write capabilities. It can be used locally, but also supports Streamable HTTP transport for remote servers, although that comes with greater security concerns.
For those using MongoDB and wanting to hook their AI-enabled IDE or CLI up with more automated powers, the official MongoDB MCP Server is worth checking out.
Among vector-native databases, Pinecone stands as a strong, widely used option with a well-designed API and comprehensive SDKs. The Pinecone MCP server extends this experience, allowing users to query its documentation and execute functionality via AI agents and AI-enabled IDEs.
To date, the Pinecone MCP server consists of nine MCP tools. These cover read-only actions, like knowledge gathering via the Pinecone official documentation and querying vector records, index metadata, configurations, and statistics. It also allows for write operations like updating records and creating new indexes.
Released in mid-2025, the Pinecone MCP server is one of the more complete early implementations, with easy configuration and installation.
For those using Pinecone who want to test new LLM-assisted workflows for creating indexes with embeddings, performing reranking, or testing results using natural language commands, the Pinecone MCP server is worth trying out.
An ultra-fast in-memory database, Redis is commonly used for caching, real-time analytics, and other latency-sensitive use cases. And as you might have guessed, the company behind the Redis database provides an official MCP server. The server allows read, query, and write capabilities.
Developers can use Redis MCP from an LLM client to perform high-level actions to analyze, reference, or embed Redis data and interact with the Redis server within their prompts. The documentation suggests some example prompts for common use cases, such as “Cache this item,” “How many keys does my database have?,” and “What is user:1’s email?”
Unlike other MCP servers, which only allow a slice of platform capabilities, Redis MCP offers full Redis support. This enables working with Redis constructs such as hashes, lists, sets, sorted sets, streams, and more, according to the GitHub repository.
One possible drawback is that Redis MCP has yet to support Streamable HTTP transport. Until this is developed, the server is constrained to local deployment. But for those seeking a local MCP server to work with Redis data, this is the best choice.
Snowflake is a cloud-hosted, AI-enabled data platform widely used in enterprise contexts for data warehousing, data analytics, and data engineering purposes. Compared to other data storage systems, Snowflake is unique in that it’s more fully managed and combines structured and non-structured data types.
The Snowflake MCP Server, available on GitHub, can be used to perform many of the standard Snowflake platform operations. This includes a “fuzzy” search of all records via Snowflake’s Cortex Search and structured data semantic lookups using Cortex Analyst.
Other abilities include object management operations like creating, updating, and deleting records. The server also can invoke other agentic-designed capabilities, like the ability to generate and execute SQL statements against back-end databases.
Snowflake MCP Server is well-thought-out and well-documented, with walkthroughs for various agent and deployment patterns. Those already building with Snowflake should find it complements the mechanics they already employ.
A longtime open-source favorite, PostgreSQL is one of the most popular and trusted object-relational SQL-based database systems. With an active open source community, Postgres has been maturing for decades. Given its open source nature, there isn’t a single “official” MCP server for the platform. Anthropic built an original reference implementation, but it’s now archived.
Instead, database platforms built on PostgreSQL provide different flavors of MCP servers, with a range of vendor neutrality and specificity. One notable option is the Supabase MCP Server, provided by Supabase, a cloud-based “back end as a service” and Postgres development platform.
Supabase MCP Server connects AI agents with Supabase projects, allowing engineers to issue natural language commands to manage tables, query data, get logs, fetch configuration information, and more. The Supabase MCP Server is pre-1.0 release and some features are still experimental.
If you’re an engineer using Supabase and looking for an MCP server to connect your AI assistant with your Postgres databases, this is a good tool to test out.
So far, we’ve reviewed official, vendor-backed MCP servers from some of the most-adopted managed databases. However, numerous MCP servers exist across other database platforms and types.
One MCP server that aggregates LLM access across various database types is DBHub, which works with MySQL, PostgreSQL, SQL Server, MariaDB, and SQLite. Developed by Bytebase, DBHub is described as a zero-dependency, token-efficient MCP server.
For SQL, the options are nearly endless. Official servers exist for Microsoft Azure SQL and DuckDB. PulseMCP catalogs more than 100 MCP servers for MySQL, although most are unofficial, solo-creator open source projects. Of these, one of the most starred is MCP Server for MySQL, developed by full-stack developer Ben Borla and optimized for Claude Code.
For Postgres, notable alternatives to Supabase include pgEdge Postgres MCP, Neon MCP server, and Postgres MCP Pro. For vector databases, others beyond Pinecone have been quick to adopt MCP as well, including Weaviate and Milvus.
Before diving into MCP servers for enterprise databases, it’s important to understand the security risks. For instance, prompt injection remains an unsolved problem, so it’s recommended to limit permissions for SQL statements.
To mitigate this, Supabase recommends enabling AI client settings that require manual approval for each tool call before execution. Experts also recommend assigning only the minimum permissions required and avoiding exposure of sensitive data like API credentials. Due diligence around authentication and authorization is especially important when hosting remote servers.
Lastly, to avoid shadow IT, it’s becoming common practice to catalog the internal MCP servers you use, even for experimental projects. For this, experts recommend an MCP registry that documents approved servers. An MCP registry improves both MCP server discovery and security awareness.

Licensing can be complicated, particularly when enterprises are forced to double-pay because the software they already own is only licensed for a specific environment, and moving it requires a whole different licensing model. Without proper portability rights, they need to make additional financial investments to run the same workloads in a different home.
AWS says its new Bring Your Own Media (BYOM) service eliminates this duplication. Customers can now reuse their existing Microsoft SQL Server media and licenses on Amazon Relational Database Service (RDS) with no additional licensing fees.
This means enterprises no longer have to justify workload migrations to the cloud against existing licensing commitments and infrastructure investments, AWS said.
“What used to be a licensing barrier between operational SQL Server data and agentic AI is now gone,” AWS data engineer Srikanth Katakam and product marketing manager Colleen Betik wrote in a blog post announcing the service.
To drive true value, agentic AI apps must have access to elastic GPU capacity as well as direct, low-latency access to the data they need to reason and make decisions. But, AWS argued, that can be difficult in self-managed data centers and on premises infrastructure with limited access to agentic AI cloud-native services. But a lot of enterprise data lives in Microsoft SQL Server, and until now customers have had to pay for a second license to use a fully managed cloud service like RDS.
Now, with BYOM on Amazon RDS for SQL Server, enterprises can reuse their existing SQL Server Enterprise Edition or Standard Edition licenses through a “lift-and-shift” model. This brings their data into a fully-managed environment.
According to the licensing distribution terms, enterprises must provide their licensed SQL Server Release to Manufacturing (RTM) media to Amazon RDS. They can then upload that media to Amazon S3 and launch BYOM instances. Enterprises must configure AWS License Manager to perform automatic instance tracking.
From there, RDS automates patching, backups, high availability, and monitoring, while providing direct access to agentic AI and analytics services native to AWS. The platform also reports vCPU usage to provide visibility into SQL Server license usage, Katakam and Betik wrote.
“You do not need to choose between protecting your SQL Server licensing investments and giving your data a path to the AWS analytics and agentic AI services redefining what’s possible in the cloud,” they said.
It’s important to note that this service is only available to enterprises with Microsoft Software Assurance (SA), an add-on which supports mobility and rehosting of existing licenses. Enterprises must verify that their SQL Server licenses comply with Microsoft’s licensing agreement, and that they have a SQL Server License (Standard or Enterprise) with SA. They also must submit a License Mobility Verification Form to Microsoft; it, in turn, will notify AWS once verification is complete.
AWS emphasized that enterprises remain responsible for compliance; it does not block operations if license limits are exceeded.
The advantage of this service, explained Mike Leone, principal analyst at Moor Insights & Strategy, is that enterprises can get a Microsoft SQL Server workload onto a managed AWS service without rewriting it for Aurora or paying for the license twice. This means they can modernize on their own schedule rather than being forced into rewrites before they’re ready.
“For a lot of shops, that control over timing is worth more than the license saving itself,” Leone said.
This also loosens Microsoft’s grip on enterprise workloads, because organizations finally have somewhere else to run SQL Server using licenses they already own, he noted. Realistically, their dependency shifts to AWS rather than disappearing entirely, as their data ends up living next to AWS’s AI services.
“For a lot of teams, that’s a trade they’re glad to make for the managed infrastructure and the AI tooling they get in return,” Leone said.
Yaz Palanichamy, a senior advisory analyst at Info-Tech Research Group, also pointed to significant improvements stemming from the migration. Notably, it allows organizations to transition away from static, linear, or reactive storage capabilities towards more dynamically intelligent environments.
“The key is to balance the unification of transactional data towards managed AI and machine learning pipelines,” he said.
The catch? Leone noted that enterprises now own the task of licensing compliance. Staying current on SA, the Microsoft maintenance contract that makes any of this legal, and the license mobility rules, “become your headache instead of something baked into the bill,” he said.
Furthermore, he added, lift-and-shift has a way of turning into “lift-and-forget” when enterprises move SQL Server as-is and never actually modernize, “so you end up carrying all the old baggage onto a shinier platform.”
Palanichamy also pointed to skyrocketing AWS costs, since operationalizing AI agents requires a considerable amount of data ingestion and querying. This can potentially be cost prohibitive on RDS for SQL Server.
“One aspect to consider would be the relative time to production value, so that enterprises can better handle the management of volatile AI workloads,” he said.
Although AWS frames licensing complexity as a roadblock to agentic AI, analysts say it’s really just one piece of the puzzle.
Organizations are not in an AI-ready state due to a number of factors, Palanichamy noted. This could be total cost of ownership (TCO)-related, a lack of appropriate acceptable use policies (AUPs), or concerns around security and compliance.
If and when enterprises are ready to adopt AI, they must perform thorough needs analysis/process optimization benchmarking exercises to determine what workflows could benefit from the technology, he said, and, conversely, flag workflows where AI could prove “an impediment or potential disservice.”
Leone also pointed out that moving SQL Server onto RDS doesn’t “magically make your data agent-ready,” nor does it make it smarter. The data proximity and managed plumbing are what actually support agents. Sitting data next to Bedrock and the rest of AWS’s AI services means builders “stop wasting time shipping the data around or building one-off integrations every time an agent needs it.”
Ultimately, though, licensing isn’t the real issue when it comes to AI; it’s more of a migration problem. The real roadblocks are messy data, questionable governance, and teams that aren’t ready to run it in production, and, Leone said, “no change to a license bill touches a single one of them.”

I’ve seen a lot of promising AI prototypes fall apart after launch. And it’s rarely because the model was bad. More often, the problem starts much earlier; teams treat the data layer like something they can figure out later.
They’ll spend weeks fine-tuning prompts, testing models and debating evaluation scores, then throw together the retrieval pipeline over a weekend and move on. At first, everything looks great in demos. But a few months later, the system gives outdated answers; the embeddings no longer match the source documents, and nobody fully understands what changed.
What started as an impressive prototype slowly becomes difficult to trust in production. The teams that avoid this tend to realize one thing early: Embedding pipelines are fundamentally a data engineering problem, not an entirely new AI discipline. It’s still ETL (Extract, Load, Transform) at its core, but with embeddings and vector stores as the destination instead of a warehouse.
Once you start looking at it that way, a lot of things become clearer. Problems like versioning, data freshness, lineage and retries stop feeling “AI-specific.” They’re data infrastructure problems we’ve already spent years learning how to solve.
Large language models are extraordinary reasoners trapped inside a time capsule. When training ends, the model’s knowledge is sealed. It does not know what your team decided in last quarter’s strategy review. It has never read the support ticket that came in this morning. It cannot find the clause buried on page 47 of your master service agreement. It’s brilliant, but blind to anything specific to your organization.
Layer on top of that a hard context window limit, a ceiling on how much text the model can process in a single interaction, and you have a clear problem: you cannot just hand it everything you own.
The answer the industry converged on is retrieval-augmented generation, or RAG. Instead of stuffing everything into the context window, you build a retrieval layer that fetches only the most relevant pieces of information at the moment a question is asked and passes just those to the model. That retrieval layer is powered by a vector database, and the process that populates it, which is taking raw documents and transforming them into searchable semantic representations, is what I mean when I say embedding pipeline.
Every team building an internal AI assistant, a smarter enterprise search tool, an automated customer support agent or a document Q&A system needs one. The question is not whether to build it. The question is whether you build it like a prototype or like infrastructure.
An embedding pipeline has three stages: ingestion, chunking and indexing. Here is what each one means and how I relate them to a typical ETL process.
Getting your raw content, PDFs, wiki pages, Word documents, database records, transcripts, out of wherever it lives and into the pipeline. This is ETL’s extract stage, almost verbatim.
I see teams cut corners here more than anywhere else, and it’s often where production systems first start to fail. A document gets updated, but the pipeline doesn’t pick it up. A file gets deleted, but its chunks remain in the index, still returning outdated answers months later. And because there’s no obvious error, no one reports it.
The fix is Change Data Capture (CDC). This maintains a manifest of every document you have ingested, a content hash and a timestamp. On each run, we compare sources against that manifest, re-ingest what changed, delete what is gone and treat your document the way you would treat any source table you are syncing incrementally.
Once your documents are in the pipeline, you cannot embed them whole. A 30-page technical report is too long to represent meaningfully as a single vector, and even if it were not, returning the entire report in response to a narrow question would bury the model in irrelevant context.
Chunking is the process of breaking each document into smaller pieces that are focused enough to embed accurately and retrieve precisely. This is ETL’s transform stage, and it deserves the same level of design discipline.
The most common mistake I see is treating chunk size as a default configuration option rather than a product decision. It is not. The right chunk size depends entirely on the nature of your content and the nature of your queries. Dense technical documentation needs finer granularity than a collection of FAQs. A legal contract with clause-level logic needs different treatment than a set of onboarding emails. What works for one document will actively degrade retrieval quality on another.
My strong preference is to treat your chunking configuration as a versioned pipeline parameter, not hardcoded logic. When you change it, and trust me, you will. You need to re-chunk in a controlled, observable way, compare retrieval quality before and after, and roll back if it degrades. That is just good transform-layer hygiene. It is no different from versioning a data cleaning rule or a field mapping.
The final stage is where chunked text gets converted into vectors and stored in a vector database where it can be searched by semantic similarity rather than keyword match.
In the conversion step, embedding is handled by a model specifically trained to turn text into dense numerical representations that encode meaning. Two chunks expressing the same idea in different words will produce vectors that cluster close together in that mathematical space. Two chunks discussing entirely different topics will sit far apart. When a user asks a question, the system embeds that question the same way, finds the chunks whose vectors are nearest, and returns them as context for the model to reason over.
That is a genuinely new capability. But the discipline around indexing is not. One data engineering principle I keep coming back to is versioning.
In embedding pipelines, every chunk in your index should be tagged with the embedding model name and version used to generate it, this is non-negotiable. Embedding models evolve, and vectors produced by different versions are not comparable in a reliable way. You cannot safely search across them as if they are interchangeable.
This exact problem shows up when teams upgrade embedding models mid-pipeline without a proper migration plan. You end up mixing vectors from different generations in the same index, and retrieval starts to degrade in ways that are hard to detect. The system just quietly begins returning subtly wrong answers.
I treat an embedding model upgrade the same way I treat a schema migration: Plan it explicitly, execute it in full and validate retrieval quality on a representative query set. The stakes are the same as any breaking change to your data model.
Once an embedding pipeline is running in production, the question shifts from “did it run” to “did it run correctly.” That distinction matters more here than in most pipelines, because failures are rarely loud because the index looks fine, queries return without errors and the system quietly surfaces wrong answers until someone notices the AI has stopped being useful.
The same observability discipline that makes any data pipeline trustworthy applies directly here. Once you treat embedding pipelines as production systems, you stop thinking in isolated steps and start thinking in signals. For example, chunk counts per document become a simple but powerful health check, a sudden drop is usually not a model issue, but a sign of broken ingestion or upstream parsing failures.
You also need a “golden set” of queries with known-good outputs. This runs after every pipeline change, much like data quality checks after a transformation. This is how you catch regressions that don’t show up as explicit failures.
On top of that, you can track lineage: Which embedding model version produced which chunks, and when each document was last ingested. That makes it possible to trace retrieval issues back to specific changes instead of guessing.
And finally, freshness becomes a first-class signal. If documents start going stale beyond an acceptable threshold, that should surface in monitoring long before users experience degraded results.
The metric that ties it all together is retrieval quality over time. Treat it like any other pipeline SLA, measured, tracked and owned.
Embedding pipelines definitely come with a lot of new language, new tools and a genuinely different capability in the semantic layer. But the funny thing is, the principles that actually make them reliable in production are not new at all.
We have versioning, freshness, quality checks and monitoring. These are problems data engineering has already spent years solving.
The real work is taking that same discipline and applying it to a pipeline that just happens to output vectors instead of rows in a table. Once you start seeing it that way, a lot of the chaos around AI systems becomes much easier to reason about.
That’s the difference between building a cool AI demo and building something people can actually depend on. One is a prototype, whereas the other is infrastructure.
This article is published as part of the Foundry Expert Contributor Network.
Want to join?