❌

Reading view

AWS bets that AI agents need an inbox, not another chat window

AWS is betting that AI agents need a different interface as they move beyond answering prompts and start working autonomously in the background.

The company has open-sourced Pizza Bot, a self-hosted application that gives users an inbox for managing work delegated to AI agents, with separate threads for ongoing tasks and a queue for work that is completed or needs human input, rather than keeping the management of agents restricted inside a conventional chat window.

The rationale, according to AWS, is that background agents do not always need a user’s attention while they work, and an inbox model will let users hand off longer-running tasks, return to them later, and see which jobs are complete or require intervention.

Under the hood

That approach is reflected in how the inbox organizes work with the help of an “All” tab that contains the history of each task or conversation, including the agent’s messages and work performed, the “Unread” tab that flags completed work that users have yet to review, and an “Action” tab that surfaces tasks paused while waiting for user input or approval.

The inbox interface also has a panel named Activity that shows users how an agent handled a particular task along with the transcript, AWS wrote in a blog post introducing Pizza Bot.

AWS’ inbox-oriented rationale also extends to Pizza Bot’s architecture.

It uses LangChain’s Deep Agents as the harness and LangGraph as the stateful runtime, with a combination of the two allowing an agent to checkpoint its progress as it works, preserving its messages, tool activity and current state so a task can be paused and resumed rather than being tied to a live chat session, the hyperscaler wrote.

Pizza Bot’s server sits on top of that stack, connecting the agent runtime with the user interface, skills, MCP servers and the model provider, with developers able to choose from Anthropic, OpenAI, Google Gemini and Amazon Bedrock, as well as local models through Ollama, it added.

As for its out-of-the-box capabilities, the application comes with skills for working with files, browsing the web and delegating tasks to specialist agents. Developers can also add existing Agent Skills and MCP servers to give the agents access to other tools and services, the hyperscaler wrote.

Enterprise integration could remain a hurdle

However, analysts were not too convinced that Pizza Bot’s out-of-the-box skills and support for existing tools will make its implementation easier for enterprises.

While the out-of-the-box capabilities and added support for existing skills saves enterprise teams the time to build the application, it leaves out the integration work required to make it work, said Bhupendra Chopra, chief revenue officer at IT consulting firm Kanerika.

“Integration is where most of the money in an enterprise agent deployment goes. A sales or finance team gets value from an agent when it can read and update CRM, email and ERP, and each of those systems needs a connector someone has to build, secure and maintain,” Chopra pointed out.

Pizza Bot’s integration could be further complicated by the application’s lack of support or any SLA, according to Manoj Chandra Jha, principal analyst at Nord-IQ Research. That means the integration and operational burden ultimately falls on enterprises, who would be responsible for running, securing and maintaining the open source software themselves, Jha said.

Rise in enterprise productivity likely

But for enterprises willing to take on that integration work, the inbox-oriented approach could improve productivity.

“It’s a meaningful shift because it changes the economics of delegating work to agents. A chat interface requires a person’s attention throughout the task, while an inbox brings them in only when their judgment is needed, much like how executives delegate work to their teams,” Chopra said.

“Coding agents have already demonstrated this model, where an engineer assigns an issue and reviews the resulting pull request. Pizza Bot extends that approach to tasks such as meeting preparation and follow-ups,” Chopra added.

Further, the analyst pointed out that the inbox-oriented approach could give enterprise teams a clearer window into how scheduled tasks perform.

“For scheduled tasks, having the results delivered as threads gives users a way to track what happened in the background and spot failures that might otherwise go unnoticed,” Chopra said.

Out of sight, out of mind

There are risks with this approach, however: “The inbox model can make bad work less visible. When somebody is watching an agent in a chat window, they can see it going off the rails,” said Phil Fersht, CEO of HFS Research.

In contrast, when hundreds of tasks are running quietly in the background, users may not see an agent making mistakes until the task is complete or an exception requires their attention, potentially making problems harder to catch early, Fersht said.

That reduced visibility can also create approval fatigue, according to Chopra.

“An agent sending back dozens of threads with multiple approval requests can condition users to approve them without reading them closely,” Chopra said.

There is also a risk in the delay between an agent preparing an action and a user approving it: “Information that was current when the agent paused may no longer be valid hours later, potentially resulting in an outdated CRM update or a meeting invite for a slot that is no longer available,” he said. “An assumption that might be caught in a live chat can go unchallenged as the agent continues building on it and consuming model resources. Scheduled runs can also add costs without anyone watching them in real time.”

Those disadvantages can be countered by designing processes with fewer, better-timed approval points, and verifying that the underlying data is still current before allowing an action to execute, he said.

Adoption likely to start with technical teams

Such tradeoffs are likely to shape where Pizza Bot gains traction.

“Adoption will likely be bottom-up, with individual technologists and small platform teams drawn to Pizza Bot’s control and standards-based design,” Jha said. “Risk-averse industries, especially ones in the regulated sectors, and business users with limited technical expertise, however, are likely to approach the application more cautiously,” he added.

That could leave Pizza Bot occupying a more targeted role in the enterprise, as a way for technical teams to experiment with asynchronous agents and new ways of delegating work, rather than an immediate replacement for the governed interfaces and managed services enterprises typically use for business-critical processes, he said.

This article first appeared on InfoWorld.

  •  

The complicated AI infrastructure market

There is a quiet war happening underneath the AI boom, and most people are not paying attention to the right front. While headlines focus on which model is winning, which startup is raising money, or which chatbot is gaining users, a parallel race is playing out in data centers and corporate boardrooms across the world. The race is for AI infrastructure: the GPU clusters, power contracts, cooling systems, networking fabric, orchestration tools, and inference services that make modern AI actually work. The companies fighting in that race are called neoclouds.

Understanding the importance of neoclouds matters for the same reason understanding cloud computing mattered in 2008. The companies that first saw the shift to cloud and positioned themselves around it correctly ended up controlling a massive layer of the technology industry. The same dynamics are playing out in AI infrastructure right now. But the neocloud market is more complicated than it looks. Not all of these companies do the same thing. Grouping them together as if they are all just GPU rental businesses misses the point entirely. The more useful way to understand the space is to recognize that neoclouds are evolving into four distinct categories, each with a different focus, a different customer, and a different role in the AI stack.

What a neocloud actually is

Before getting into categories, it helps to establish what the term means. A neocloud is a cloud infrastructure provider designed specifically for AI workloads. That sounds simple, but it covers a lot of ground. General-purpose hyperscalers like AWS, Azure, and Google Cloud were engineered to support a wide variety of workloads across many industries. They built architecture around flexibility, breadth of services, and broad enterprise appeal. Neoclouds took a different approach. They built around one mandate: make AI compute as fast, dense, and scalable as possible.

That means designing facilities around high power density, integrating fast interconnects between GPUs, investing in liquid cooling and energy-aware cooling, and building orchestration around tools like Kubernetes and Slurm that are purpose-built for distributed AI training. It also means competing aggressively for access to the latest Nvidia accelerators, because in AI infrastructure, GPU access is often the single most important competitive advantage a company can have.

The result is a fragmented but deeply competitive market. Some neoclouds are focused on physical capacity. Some are focused on making GPU compute accessible to developers. Some are building enterprise-grade infrastructure that can compete directly with hyperscalers in specific AI domains. And some are focused on one of the most important long-term bets in AI: inference. Let’s take a closer look at the four categories of neoclouds.

Full-stack AI infrastructure

The first and most prominent category is full-stack AI infrastructure providers. These companies are trying to become the AWS of the AI era, yet they are built from the ground up around GPUs rather than general-purpose compute. Their goal is to own as much of the AI infrastructure experience as possible: raw GPU clusters, networking, storage, orchestration, managed Kubernetes, Slurm scheduling, private clusters, enterprise support, training workloads, and inference services.

The companies in this space include CoreWeave, Nebius, Lambda, Crusoe, Nscale, and Fluidstack. CoreWeave has emerged as the clearest example of this category. It built its identity around massive GPU clusters optimized for large-scale AI training, paired with Kubernetes-native orchestration and enterprise contracts worth billions. Nebius took a different path, combining deep engineering expertise with a sovereign and European-oriented strategy while expanding heavily into US data centers. Lambda started as a developer and researcher-friendly GPU cloud for machine learning but has moved deliberately upmarket, adding superclusters and private cluster services.

Developer and self-serve GPU clouds

The second category is developer and self-serve GPU clouds. These platforms are not competing for billion-dollar enterprise contracts. They are competing for developers, startups, researchers, and smaller teams who need GPU access quickly without negotiating long-term deals. The product experience here is self-serve: pick a GPU, spin up an instance, deploy a model, run a notebook, test a workload, or launch a small cluster.

The brands that fit here include Vultr, Runpod, Civo, Lambda, and Together AI. Vultr brings GPU compute into a broader cloud platform with a global footprint and self-service deployment. Runpod has built a loyal developer following by keeping the experience simple and fast. Civo targets developers who prefer a Kubernetes-first environment. Lambda still offers strong self-serve GPU instances and 1-Click Clusters alongside its enterprise offerings. Together AI goes beyond raw GPU rental to combine inference, fine-tuning, model hosting, and dedicated clusters in one developer-accessible platform.

This category matters because not every AI team needs thousands of GPUs and a dedicated account manager. A lot of important work happens at the research bench, the startup prototype stage, and the individual developer level. These clouds serve that market, and they often grow into larger accounts as teams scale.

Inference-first AI clouds

The third and increasingly important category is inference-first AI clouds. Training gets the dramatic headlines, but inference is where AI products actually live. Every chatbot response, coding assistant completion, voice agent interaction, and image generation request is inference. And unlike training, which happens in bursts, inference runs all day, every day, for every user.

The companies to watch include Together AI, Groq, CoreWeave Inference, Nebius Token Factory, Crusoe Managed Inference, and Nscale Serverless Inference. Together AI has built one of the clearest inference-first platforms in the market, especially for open source and open-weight models, while also supporting fine-tuning and dedicated GPU clusters. Groq stands apart because its identity is tied to ultra-fast inference running on its own language processing unit (LPU) architecture, which inverts the traditional GPU paradigm. CoreWeave Inference extends CoreWeave’s infrastructure story into serverless and dedicated model-serving. Nebius Token Factory and Crusoe Managed Inference represent how full-stack players are adding inference layers to monetize their GPU capacity differently. Nscale Serverless Inference is Nscale’s move into on-demand model serving without infrastructure management.

What makes this category so compelling is the economic direction. As AI moves from a handful of large frontier labs into millions of production applications, the demand for inference infrastructure will likely dwarf training demand. Companies that control inference capacity may end up controlling the more durable long-term revenue stream.

Data-center and capacity-heavy players

The fourth category is the most physically grounded. These are the companies that are building and controlling the real estate of AI. This goes beyond GPU clouds in the traditional sense. These companies are acquiring land, securing power contracts, designing data centers, developing campuses, deploying high-density racks, and racing to control capacity that genuinely cannot be replicated quickly.

The brands that fit here include Fluidstack, Applied Digital, Core Scientific, Voltage Park, Crusoe, and Nscale. Some of these companies also offer cloud services, but their strategic advantage is fundamentally about commanding physical infrastructure. Fluidstack specializes in delivering large-scale custom GPU cluster capacity and custom data center solutions for enterprises and AI labs. Applied Digital provides hosting infrastructure for AI and high-performance computing at scale. Core Scientific transitioned from crypto-mining data centers into AI infrastructure. Voltage Park is focused on large-scale GPU capacity for AI and research organizations.

Crusoe and Nscale appear in this category as well as in others, which gets to the heart of one of the most important points about the neocloud market overall. These categories are not clean boxes. Companies routinely sit across multiple categories, and competitive pressure is pushing most of them to expand their scope. Crusoe is both a cloud provider and a data-center developer. Nscale is both a cloud platform and a major infrastructure builder. The companies that ultimately win may be those that can span the four categories most effectively.

Why the category framing matters

Understanding these categories is not just an academic exercise. It has real consequences for how companies make buying decisions, how investors evaluate the space, and how technology leaders think about AI infrastructure strategy.

A company focused on physical capacity is playing a fundamentally different game than one selling managed inference APIs. They may appear in the same technology articles and compete for some of the same headlines, but their economics, customer relationships, and long-term differentiation look very different. From an enterprise buyer perspective, understanding which layer you are actually buying from matters before you sign a contract. Some neoclouds are building long-term platform relationships. Others are offering capacity to fill an immediate gap. The category determines which is which.

The neocloud market is young, fast-moving, and genuinely complicated. New entrants, mergers and acquisitions, and platform expansion are all reshaping the landscape in real time. But the underlying logic remains constant. AI infrastructure is becoming a critical layer of the technology stack, and whoever controls that layer will have enormous influence over how AI gets built, deployed, and monetized.

The companies in this market are not all the same. Paying attention to what they actually do, rather than just what they call themselves, is how you separate the ones that will shape AI’s future from the ones that were simply first to send a press release.

  •  

How Microsoft connects your data across the enterprise

For CIOs and CDOs heading into Microsoft Fabric and SQL Community Conference Europe, the main question is not which data technology sits at the center. It is whether the data platform improves revenue, productivity, and decision speed while creating a trusted foundation for AI at scale. That should drive the data strategy.

Enterprise AI is forcing companies to tackle a familiar problem, with data spread across ERP, CRM, operational systems, databases, applications, warehouses, and analytics platforms built over years. That was manageable for reporting and point-to-point integration. Copilots and agents raise the stakes because they need to reason across customers, orders, inventory, financial implications, operating constraints, permissions, and business rules at the same time.

That moves the discussion from architecture into CIO and CDO strategy. What outcomes are we trying to improve? What data and context are required? What needs to move versus connect? Where do Microsoft Fabric, Azure Databases, and other platforms fit? How will governance and authority follow the data? Where should the data be stored and what sovereignty or regulatory restrictions apply? And how will we measure results?

Microsoft is positioning its broader data platform around AI business value. That framing is useful when it translates into an operating strategy. As I wrote in Forbes about Microsoft Build in June, the next phase of AI depends less on the model and more on data readiness, governance, interoperability, and operational execution. The conference should give customers a closer view of how those pieces come together. The question for CIOs and CDOs is how that direction fits their existing data estate.

The AI problem is usually a data problem

Many AI initiatives stall on data readiness rather than the model itself. The issue is not one statistic. It is the combination of fragmented data, inconsistent definitions, and the effort needed to prepare and govern information before AI can use it reliably.

Copilots and agents need trusted context around customers, financials, inventory, operations, permissions, and business rules. AI exposes existing weaknesses. Duplicate customers, poor product data, and inaccurate inventory become more consequential when AI is recommending or taking action. AI does not create the data quality problem; it makes the operating cost harder to ignore.

The goal is to make more of the existing data estate useful for AI without turning modernization into a wholesale rebuild.

Microsoft Fabric and Azure Databases play different roles

For customers, the question is how Microsoft’s broad portfolio translates into architectural choices, including what should move, what should connect, and what can stay in place without limiting the result the business is trying to achieve.

Azure Databases support transactional and operational workloads, each with distinct performance and application requirements. Fabric provides a unified SaaS experience across data integration, engineering, analytics, real-time intelligence, data science, and business intelligence. Fabric IQ adds a semantic intelligence layer that provides shared business context for Copilot and agents. Some workloads may belong in Fabric, others in Azure Databases, and some on third-party platforms; moving them adds cost without creating enough business value.

The architecture should follow workload, data maturity, economics, and business value, not a single destination.

Connected data has to improve the decision

Microsoft’s broader data platform can connect systems of record and operational applications with analytics and AI. Azure Databases, Fabric, OneLake, Power BI, and governance can play different roles. What matters is whether those connections shorten the path from operational data to a decision, not how neatly the products line up.

A customer record may live in CRM, orders in ERP, inventory in operational databases, and demand models in an analytical environment. Fabric Real-Time Intelligence can add live events to that picture. A manufacturer can stream equipment events or production events, detect a developing issue, and alert teams while there is still time to change the outcome. The value comes from reasoning across that context so the business can understand what is happening, why it matters, and what action makes sense next.

Trusted context turns data into AI business value

I recently wrote in InfoWorld that trusted context is becoming the currency for enterprise AI. That is especially relevant here because once copilots and agents rely on enterprise data, then quality, permissions, lineage, and security become operating requirements, not background data issues.

Knowing inventory is 8,000 units is data. Knowing whether those units are available, committed elsewhere, in the wrong distribution center, or on quality hold is business context. As AI moves from answering questions to taking action, that context determines whether the result can be trusted.

Microsoft frames AI business value around growth, insight, and scale. Each needs an operating definition. Growth can mean new revenue, better customer responsiveness, or growing without adding cost at the same rate. Insight means combining context across Microsoft 365, Fabric, and operational systems to make better decisions faster. Scale means expanding AI without rebuilding governance for every use case.

A reusable data foundation can also reduce pipeline and management effort while improving decisions around pricing, inventory, customers, supply chain, and finance. Microsoft cites coverage of more than 100 standards. The practical question is whether AI can scale without risk and complexity growing at the same pace. For multinational or regulated organizations, that also includes where data is stored and processed and which sovereignty requirements apply.

Agentic workloads raise the bar. Organizations need to know what information informed a decision, who or what had authority to act, which policies applied, and how a wrong action can be reviewed or reversed.

That is where the data platform becomes part of what I describe as decision architecture. Context explains what is happening. Decision logic determines what should happen next. Authority defines what a person or agent can do. Orchestration coordinates systems and people. Execution completes the action and provides a path to review or reverse it. Trusted data feeds that architecture. Without trusted data, automation will be difficult to trust at scale.

Microsoft’s breadth is most useful when it reduces complexity

Microsoft’s advantage may be its enterprise footprint. Azure Databases, Fabric, OneLake, Power BI, Microsoft 365, business applications, developer tools, identity, security, and partners touch many of the places where information is created and work gets done.

Most customers will keep data across multiple systems. Microsoft’s opportunity is to use that breadth to create a simpler path from data to workflow to business outcome without requiring everything to live in one place.

Customer proof points matter because data strategies can get abstract. The KPMG Australia example is useful because KymChat moved beyond an internal productivity tool into a client-facing offering, creating a path from internal AI investment to new business. Microsoft also reports that improvements to the data foundation increased KymChat search quality from 50% to 91%, with results delivered in under a second.

BMW Group provides a more recognizable operating example. Microsoft says Azure helped BMW make vehicle data delivery and analysis 10 times faster, cutting the lead time for engineering insights from days to hours or minutes. Audi adds an AI deployment example. It used Azure AI Foundry, Azure App Service, and Azure Cosmos DB to launch a secure HR assistant in two weeks and is extending the same framework to eight additional agents across the enterprise. Levi Strauss & Co. offers another angle. It consolidated nine ERP systems on Azure, reported a twofold improvement in latency and a 60% improvement in IOPS and now uses Fabric IQ for companywide cost reporting. These are the kinds of proof points that connect platform architecture to time, cost, productivity, and decision quality.

Interoperability matters across the enterprise estate

Microsoft sits in a market with Snowflake, AWS, Google Cloud, Oracle, and others, each with different strengths across infrastructure, databases, analytics, openness, and AI. Databricks also plays an important role, but the connection is different because Azure Databricks is provided as a first-party service directly on Azure. Most large enterprises will remain heterogeneous, making interoperability, cross-platform governance, and incremental modernization central to strategy.

The opportunity is to make Microsoft’s data platform useful across the mix of systems that customers already run. Most enterprises are not starting from a blank sheet, so the value is in helping them connect, govern, and modernize over time without forcing everything into one place.

CIO and CDO strategy should start with the business outcome

This is where the conversation becomes most useful at the Microsoft Fabric and SQL Community Conference Europe. For CIOs and CDOs, an architecture diagram matters more when it is backed by a decision model. A useful data and AI strategy should work backward from the business outcome through five decisions.

  1. Start with the business outcome. Define what needs to improve, including revenue, margin, productivity, customer experience, decision speed, working capital, or time to value. Let the technology choice follow the objective.
  2. Map the data and context required. Identify the operational, transactional, and analytical information, semantics, and business rules that influence the outcome.
  3. Decide what moves and what connects. Determine where Fabric, Azure Databases, and non-Microsoft platforms fit. Let workload, economics, and value drive modernization rather than a single destination.
  4. Design governance, authority, and economics together. Define how security, permissions, lineage, and controls span operational, analytical, and AI workloads, and identify opportunities to simplify pipeline, integration, and management efforts.
  5. Measure the operating result. Set KPIs before scaling. Technology adoption is not the outcome. CIOs and CDOs should know which business measures should change, by how much, and over what period.

That is how the data platform becomes enterprise strategy, tying architecture, governance, AI, and economics to operating outcomes and bringing business leaders into the discussion before the architecture is set.

What customers will still want to understand

Microsoft has many of the pieces required to connect enterprise data, analytics, and AI. Customers will keep looking for guidance on the roles of Azure Databases, Fabric, and the broader data platform, along with cost, licensing, migration, and governance across heterogeneous environments. They will also want more proof points from KPMG, BMW Group, Audi, and Levi Strauss & Co. that start with a business result.

That is where Microsoft’s positioning around a data platform for AI business value comes together. The value is in helping customers connect platform choices to better decisions, faster action, and measurable operating results.

After three decades in enterprise technology, I keep coming back to the same point. The technology is only part of the answer. For CIOs and CDOs, the harder part is deciding how the data platform fits into the way the business operates, how decisions get made, and where AI can improve the outcome. That is really the question behind how Microsoft connects your data across the enterprise. The conference should give customers a useful view of how Microsoft is bringing those pieces together and where that can create better business outcomes.

  •  

Cloud has a new bulk capacity market

For 15 years, public cloud providers have defined the industry for most enterprises: on-demand, automatically metered services delivered over the open internet that give developers immediate access to storage, databases, compute, application development platforms, and AI capabilities. That model remains dominant because it is simple, well-instrumented, and universally supported. Yet an adjacent reality has always existed. Large-scale, off-market capacity deals where technology companies with surplus GPUs, storage, and compute sold blocks of capacity in bulk to other firms under nondisclosure agreements were once common. Those were cloud transactions in substance, since you were using somebody else’s servers. However, they lacked the automation, metering, and governance that define public cloud services, and they operated entirely outside the frameworks enterprises rely on for budgeting, compliance, and accountability.

A shadow market becomes visible

These arrangements are now becoming more visible and more formalized. Some are even openly auctioned. Meta’s entrance into the cloud capacity space, essentially offering its excess compute infrastructure to outside buyers, represents the maturation of a market that has existed in back rooms for years. Large, multiyear capacity commitments are no longer whispered about during boardroom lunches. They are being announced, financed, and tracked by analysts. This shift is creating a distinct layer in the cloud landscape, one that sits between traditional hyperscalers and true private clouds, and one that enterprises can no longer afford to ignore.

The practical implication is that the cloud market you thought you understood now has a parallel track. When a large enterprise needs maximum GPU capacity for model training or inference, it has more options than a year ago, and those options come with genuinely different trade-offs. You can go to a hyperscaler and pay the published rate for metered GPU as a service, receiving a fully managed platform with all the tools, governance, and integration you need. Or you can reach out to a technology provider that happens to have idle or excess GPU capacity and negotiate a bulk deal at a fraction of the published rate. The first option provides predictability and depth of service. The second offers raw cost savings if you have the operational capability to handle less-managed infrastructure.

This bifurcation is muddying procurement decisions. The gap in pricing between bulk off-market capacity and public cloud offerings can be substantial. Some analysts cite differentials ranging from 10 to 100 times. But headline GPU rates are only part of the evaluation. Bulk deals tend to come with minimal metering, limited monitoring, and a do-it-yourself culture around incident response and optimization. You are, in effect, purchasing wholesale energy. It is robust and capable, but it requires your own wiring and maintenance. Organizations accustomed to the instrumentation and service-level agreements of hyperscalers may find such a different operational reality a bit jarring. Those with mature cloudops teams may find the economics compelling.

Who benefits and who adjusts

The hyperscale incumbents will not be displaced overnight. They offer the complete ecosystem, not just GPU frameworks but development tools, hundreds of managed services, identity, compliance, and integration layers that are genuinely difficult to replicate. However, they are now facing a market where customers with intensive computational needs can source raw GPU capacity from alternative suppliers, particularly for bursty or cost-sensitive workloads. This is not necessarily a threat to hyperscaler dominance, but it is a complication. The hyperscalers will likely respond through partnerships, capacity-coverage agreements, and possibly acquisitions of promising capacity players. Effectively, they will become customers of the same off-market ecosystem they once ignored.

The cloud market is adding a new axis of choice: managed breadth versus specialized efficiency. Enterprises will increasingly construct hybrid operating models, keeping steady-state, security-sensitive, and toolchain-dependent workloads on hyperscaler platforms while offloading cost-intensive training runs and elastic inference to bulk-capacity providers. This is not a binary choice. It is an expanding continuum of sourcing options that demands more sophisticated procurement and architecture planning.

How to take advantage

Know your actual workload cost before you negotiate. If your AI workloads are compute-intensive, model training-heavy, or require burst capacity at unpredictable intervals, the economics of bulk capacity deals can be compelling. Run a pilot that captures total cost of ownership, including data movement, integration effort, operational overhead, and potential downtime during self-managed troubleshooting before you assume bulk is simply cheaper. Compare fully loaded costs, not GPU-hour sticker prices.

Build portability into your AI stack from the start. Bulk-capacity providers often lack the governance, compliance tools, and model life-cycle management enterprises need. Mitigate this risk by standardizing on containerized inference runtimes, open model formats, and CI/CD pipelines capable of deploying across multiple targets. This type of discipline turns vendor diversity into negotiating leverage rather than operational liability. It also ensures you can shift workloads as capacity markets fluctuate.

Treat capacity sourcing as a strategic procurement function. Bulk cloud capacity is not a niche quirk. It is becoming a recognized market that rewards supply-chain thinking. Diversify your supplier base, negotiate multi-vendor commitments where possible, and develop a reserve strategy for critical workloads. Keep your hyperscaler relationship for reliability and breadth, but maintain at least one secondary capacity arrangement for cost-sensitive or elastic workloads. The enterprises that treat capacity as a variable asset, rather than a fixed infrastructure decision will be better positioned as this market continues to expand and formalize.

The cloud market is no longer a simple fork between public and private. A defined middle ground of negotiated bulk capacity is now attracting billions in investment and reshaping how AI infrastructure costs are allocated. Enterprises that understand this landscape and build flexible, portable architectures that can span it will capture more value from AI investments than those who default to the familiar hyperscaler menu alone.

  •  

Digital sovereignty sounds great until you try ditching your suppliers

After years of governments and tech vendors banging the digital sovereignty drum, most large organizations have concluded that true technological independence is beyond their reach. That's according to new research from Capgemini, which found that 59 percent of organizations regard complete digital sovereignty as unrealistic. Instead, two-thirds define it in terms of what the consultancy calls "resilient interdependence" – accepting continued reliance on outside technology providers while trying to ensure those dependencies do not threaten critical operations. It's a pragmatic conclusion, though perhaps not surprising given how thoroughly tangled those dependencies have become. Digital sovereignty broadly refers to an organization's ability to retain control over its data, infrastructure, software, and critical technology operations, including where they are hosted and whose laws govern them. Capgemini surveyed 1,300 business and technology executives in April 2026, covering companies with more than $1 billion in annual revenue and government departments with budgets above $1 billion. Its separate Digital Sovereignty Index, based on an analysis of 866 organizations, found that 86 percent had significant exposure to foreign or externally controlled supply chains. Across the research, just 14 percent reported end-to-end visibility into dependencies throughout their wider technology ecosystems. Getting out of those relationships isn't necessarily straightforward either. Some 36 percent said moving away from a critical technology provider would take more than a year, while another 10 percent said they had no viable alternative. That leaves organizations trying to work out how much independence they actually need, rather than rebuilding their entire technology stacks closer to home. European respondents appeared particularly receptive to that compromise. Three-quarters defined sovereignty in terms of resilient interdependence, compared with half of respondents in the US. The UK also tended to view sovereignty through the lens of risk: 56 percent of British respondents primarily associated it with resilience and risk mitigation. This doesn't mean the subject has disappeared from the corporate agenda: 93 percent of respondents said it had been discussed at board level, and 44 percent ranked it among their board's top priorities. AI is adding another dependency for those boards to worry about. Three-quarters of organizations identified AI as a key focus of their sovereignty efforts, ahead of cloud infrastructure, cybersecurity, data, and software. Money presents another problem. Just under half said they would pay extra for sovereign technology. Among those willing to do so, the acceptable premium averaged 23 percent. Perhaps the more uncomfortable finding concerns what happens when those carefully accepted dependencies actually fail. Among organizations that had recently suffered an operational disruption, just 42 percent had contingency plans in place. Almost two-thirds of US organizations were prepared, compared with slightly more than a third in Europe and Asia-Pacific. Capgemini argues the answer isn't complete technological independence, but deciding which systems and capabilities matter enough to keep under tighter control, while building alternatives and recovery plans around everything else. Given that one in 10 organizations cannot currently replace a critical provider at all, this may be less a philosophical embrace of interdependence than an acknowledgment of where the exits actually are. ®

  •  

How to keep your mission-critical cloud workloads running

Entrusting mission-critical workloads in the cloud puts a lot of pressure on IT operations to build resilience into data infrastructure they don’t even own — to make sure that when an incident happens elsewhere, the lights stay on at home. Fortunately, savvy CIOs are learning they can architect their systems for resilience and high availability to keep mission-critical cloud workloads running when disaster strikes.

When designing for resilient, highly available cloud workloads it is critical to understand the details of your cloud provider’s service level agreement (SLA) and recognize that providers operate on a shared responsibility model. That means there are many things the provider is responsible for, but the workloads you’ve got running on their infrastructure are not among them. With that in mind, we’ll need to focus on three core goals essential to building and maintaining highly available, resilient cloud workloads:

  1. Identify and eliminate single points of failure
  2. Close or mitigate conditions leading to recovery gaps, and
  3. Overcome operational complexity.

Remember, everything fails

Designing for application-level resilience and high availability is predicated on recognizing that everything fails. That’s not pessimism, but realism, and embracing this fact gives you a leg up in architecting resilient IT. Hardware breaks down, disasters occur, mistakes are made, software incompatibilities are common, and limits are exceeded that result in loss of service. There are four categories of failure that need to be taken into consideration when designing for resilience and high availability:

  1. Single point of failure: As the term suggests, this describes a non-redundant device, route, or point of connectivity that results in zero fault tolerance in the event of an incident involving that choke point.
  2. Excessive load: Exceeding the throughput or memory limits of a device or service can result in latency, service degradation, or failure affecting service level agreements (SLA) and service level objectives (SLO).
  3. Misconfigurations and bugs: Perhaps the most common source of failure, these breakdowns often occur during installation, maintenance, and patching leading to the incorrect execution of code.
  4. Shared fate: This type of failure is like non-redundant connectivity. When you rely on third-party services and there is an incident beyond your control affecting a partner, it can result in downtime or service degradation.

Having identified the primary challenges to maintaining service uptime and continuity, let’s explore an approach to achieving resilience through high availability, disaster recovery, and the process of continuous improvement.

Working toward continuous improvement

High availability is often thought of as measured by “X Nines,” representing the percentage of time a service is operational over the course of a specified time frame, usually a year. Six nines of availability, for example, means that a service can be expected to run 99.9999% of the time, or 8759.99 hours out of 8760 in a year. That sounds good until a disaster happens. Then we shift to disaster recovery, or the ability to restore a service and its associated data quickly and correctly when things go wrong. Disaster recovery is often measured and evaluated by a recovery point objective (RPO), which is the maximum acceptable amount of data loss, and a recovery time objective (RTO), which is the maximum acceptable amount of time a service can be down.

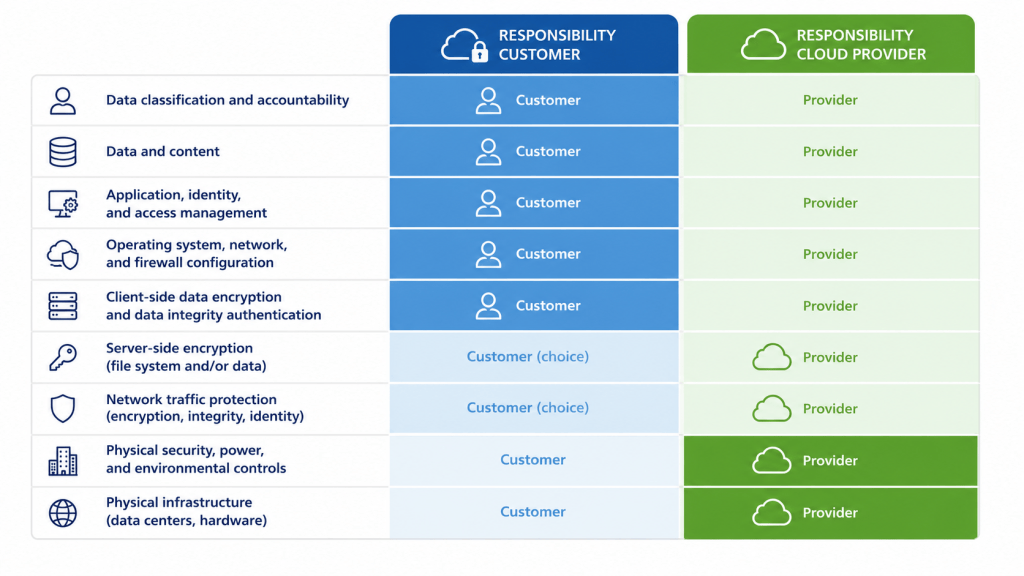
By learning from our mistakes, incidents, and the ongoing process of testing, observing, and evaluating IT operations, we apply new information in the goal of continuous improvement to get peak performance out of our investments in IT. But because we’re addressing resilience and high availability in the context of workloads operating in the cloud, we should understand the shared responsibility model that most cloud service providers use. Details may differ from provider to provider, but the shared responsibility model of cloud services is your vendor’s statement of responsibility for maintaining its infrastructure and ability to deliver storage and compute capacity in a region and availability zone where you have a need. In return, you accept responsibility for the configuration, maintenance, availability and operation of the workloads you choose to run on your vendor’s cloud.

Infoworld - Shared Responsibility

SIOS Technology

A cloud service provider will typically operate and maintain physical infrastructure in different areas around the world, with multiple availability zones in each area. Each availability zone will have one or more data centers with its own power, cooling, and other operational support. Data centers are typically located far enough from each other to minimize the chance that a natural or regional disaster will affect multiple data centers, but close enough that they can operate as a single, logical data center — thereby maximizing bandwidth and throughput, while minimizing latency. This is redundancy at scale that eliminates a single point of data center failure.

Designing for application high availability and disaster recovery

To build out or retrofit your infrastructure for application-level resilience and high availability, there are four things you must have: clustering, data replication, failover, and disaster recovery. Let’s look at each and how to architect for them.

Clustering

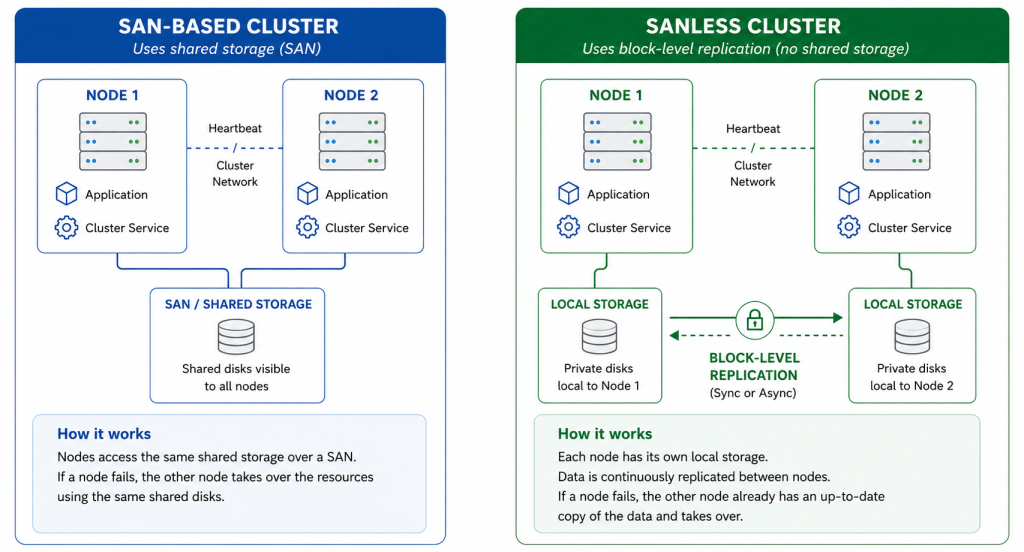
Clustering is the practice of connecting like and complementary systems to improve availability and reliability. Think of it as putting into practice the maxim “the whole is greater than the sum of its parts.” Traditionally, clustering was achieved using hardware, specifically storage area networks (SAN), to connect and support systems in a physical data center. However, in the cloud age, hardware-based clustering has proven to be expensive and inflexible. Software-based SANless clustering with products such as SIOS LifeKeeper delivers all the benefits of the traditional approach while also working better in cloud and hybrid environments.

Infoworld - SAN vs. SANless

SIOS Technology

SANless clusters enable the configuration of nodes based on the organization’s operational priorities and work easily for enterprises running geographically distributed data centers or cloud availability zones. Because SIOS LifeKeeper supports single-site, multi-site, cloud, or mixed environments, and affords real-time access to operational data during incidents requiring failover, it is ideal when mission-critical workloads are distributed across multiple providers. LifeKeeper clusters create redundancy and eliminate single points of failure, both of which are necessary for achieving high availability. For enterprises operating hybrid or multi-cloud infrastructure, this enables you to shift to secondary resources should your primary service experience an outage.

Data replication

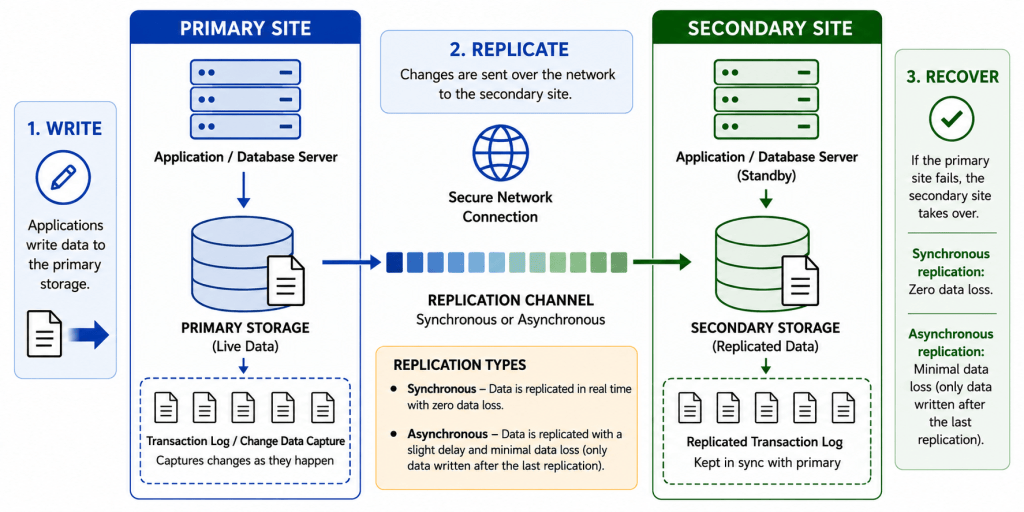
IT operations and your mission-critical applications rely on data, so it’s vital to keep data in sync between nodes in real time, whether synchronously or asynchronously, depending on the application. When working to achieve high availability, it’s important to monitor the health of infrastructure elements and the applications you’re running. This ensures that downtime affecting the application and any downstream dependencies is detected so that failover and recovery to a standby node can occur automatically. When everything is in sync and data replication is happening, this ensures complete readiness; there’s no need to rebuild a database or for any manual operations. And with SANless clusters using SIOS DataKeeper, this will happen across availability zones, regions, and to or from on-premises, cloud, or multi-cloud resources in hybrid environments.

Infoworld - Data Replication

SIOS Technology

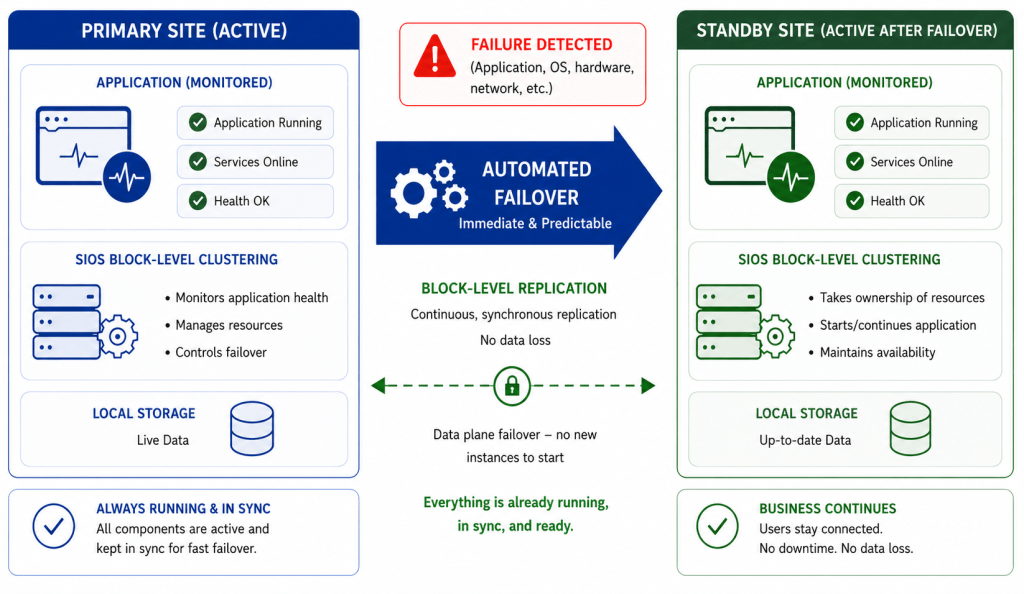
What’s important here is that the software you use for SANless clustering be application aware. That’s SIOS LifeKeeper. Because high availability and resilience mean not just failing over to standby infrastructure resources, but for properly failing over mission-critical workloads (think SQL Server, SAP, Postgres, or industry-specific applications like Meditech), the software needs to understand how those applications work so that they can recover and restart cleanly. Otherwise, when failover occurs, there’s a good chance that workload is not going to be available, or it could be out of sync. When your software is application-aware, failover and recovery is fast and predictable with no API dependencies or last-minute provisioning.

Failover

With SIOS SANless application-aware clustering and replication in place, you can automate real-time failover and achieve the goal of high availability and resilience. Because we’ve chosen a software-based approach, failover occurs in the data plane, so there’s no need to spin up a new instance following an incident. Everything is already running, in sync, and ready. Furthermore, failover is immediate and it’s predictable. That is what you need when dealing with mission-critical workloads. Consider that many of the mission-critical applications you use were not designed to operate in the cloud, so even if your infrastructure is resilient, the application itself represents a single point of failure. Without replication, application monitoring, and real-time failover automation, you risk loss of revenue, security degradation, or worse.

Infoworld - HA Clustering

SIOS Technology

Depending on the size of your enterprise and the industry in which it operates, an hour of downtime can cost $1 million or more, and 90% of organizations report costs of at least $300,000 per hour. Beyond that simple loss of revenue are soft costs associated with reputation damage, lost productivity, missed transactions, and more. Revenue protection is only part of the equation; it is about protecting the business.

Disaster recovery

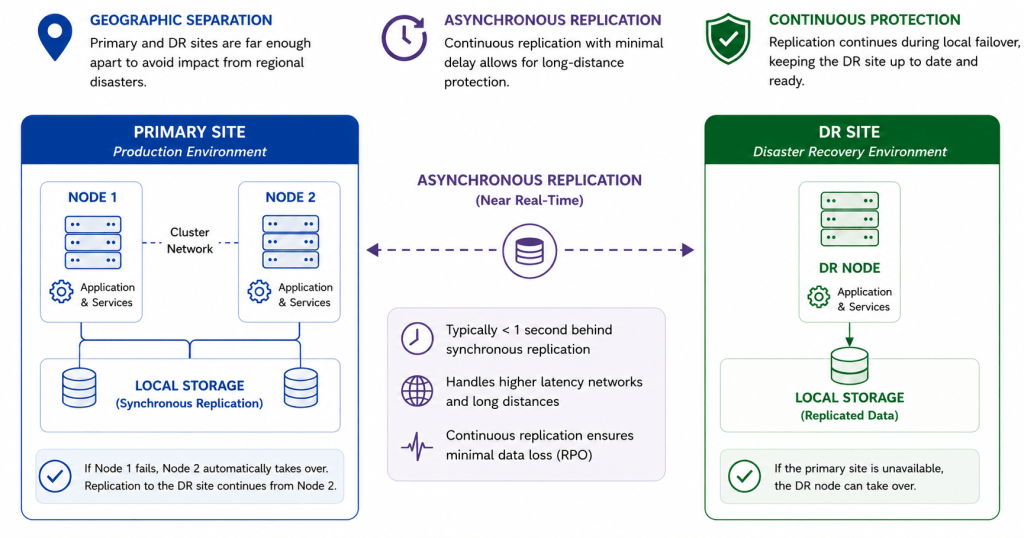
Any design for high availability and resilience must also take into consideration the risk of a non-IT disaster that disrupts operations. Natural disasters like fires, earthquakes, and floods, or disasters caused by humans like the accidental severing of a trunkline or an act of sabotage conspire to bring operations to a sudden halt. Clustering, replication, and failover all play into disaster recovery, but there are additional considerations that must be addressed. For disaster recovery (DR), you’re going to want geographic distance between your primary site and your DR site to minimize the risk that a regional event doesn’t affect both. That means you’re going to want asynchronous (or near real-time) data replication.

Infoworld - Disaster Recovery

SIOS Technology

Asynchronous replication is typically only a second or less behind synchronous replication, so it is de facto real-time, but that delay allows you to replicate across higher-latency networks and across longer distances. And because replication is happening continuously, even if you have a local failover between node one and node two, replication to the DR node doesn’t stop. Instead, when node two comes online it becomes the source of the mirror replicating to the DR site and back to node one once it is restored.

Patching and planned maintenance

Beyond the simplicity and cost advantages that come from taking a software-based approach to designing your cloud and hybrid infrastructure for high availability there is another big benefit. You are also better prepared to respond to the increased pressure on rapid implementation of software updates and security patches. No one wants to be the person responsible for taking too long to patch for a vulnerability, but every time you touch a system, you’re introducing the risk of error. That risk is greater when dealing with the cloud where you have less control over the underlying infrastructure, more abstraction, and a lot more moving parts.

In short, patches can break things as well as fix them. They have thus become a significant contributing factor as a cause of downtime. With SANless clusters you’re able to minimize that risk by enabling rolling updates, meaning you can patch a secondary server, verify that the patch didn’t break anything, and then patch the original server where the primary application is still running. If something does break on the secondary server, the primary is unaffected and you can quickly recover to the previous state while you figure out what went wrong. This simplifies the process of executing ad hoc patches and performing planned maintenance, mitigating the associated risks.

An investment in cloud and hybrid infrastructure and services doesn’t have to put IT operations at the mercy of a third party. With the right approach, you can design for high availability and resilience and keep your mission-critical workloads running in the cloud even when things outside of your control go wrong.

—

New Tech Forum provides a venue for technology leaders—including vendors and other outside contributors—to explore and discuss emerging enterprise technology in unprecedented depth and breadth. The selection is subjective, based on our pick of the technologies we believe to be important and of greatest interest to InfoWorld readers. InfoWorld does not accept marketing collateral for publication and reserves the right to edit all contributed content. Send all inquiries to doug_dineley@foundryco.com.

  •  

Microsoft almost gave away the keys to everyone’s Azure Cosmos DBs

Microsoft has had a narrow escape from total embarrassment: A security company uncovered a critical vulnerability that could have compromised all Azure Cosmos DB databases — both those of customers and Microsoft’s own.

Google subsidiary Wiz found a flaw in the database’s Gremlin API, usually used for storing and managing property graph data.

If bad actors had discovered it first, they could have exploited it to acquire what Wiz called the Cosmos Master Key, which would have enabled them to use the primary key of any Cosmos database, resulting in read and write access to any account. They would also have had access to a list of every database on the service, with identifiers such as subscription and tenant IDs.

Azure Cosmos DB is a NoSQL database that underpins Microsoft’s cloud services. It can be accessed through SDKs for framework such as Python, Node.js, Java, and .NET.

Wiz described how it discovered the vulnerability in a blog post. It disclosed details of the flaw to Microsoft in November 2025.

Microsoft deployed a hot fix within two days, but it took another eight months to re-engineer the infrastructure, removing the Cosmos Master Key and introducing new guardrails to Cosmos DB to prevent similar attacks.

It is not the first time Cosmos DB customers’ primary keys have been under threat: In 2021, Wiz found a flaw in data exploration tool Jupyter Notebook that could be exploited to access the database keys and other secrets.

This article first appeared on CSO.

  •  

Reselling unused cloud instances is no longer easy

A client called me last week with a problem I have been hearing about more often lately. They had made significant reserved instance commitments with a major cloud provider, overbuying for what they thought would be heavy AI training workloads. Now they were sitting on thousands of dollars in idle capacity every month. Their plan was simple: resell it to someone else. Except they couldn’t.

I have been doing cloud consulting for a long time, and this situation once had a straightforward solution. You went to the marketplace, listed your unused reservations, and found a buyer. The process was a bit clunky, but it worked. These days, the answer is far more complicated, and my client learned this the hard way.

AI has made this problem increasingly common. Companies initially committed to compute capacity based on ambitious training plans. Prototype projects were expected to scale, and inference workloads were projected to grow substantially. Then reality hit. Some projects did not materialize. Some models trained faster than expected. Some inference patterns were lighter than anticipated.

Many organizations now hold reserved capacity they can’t use, discard, or share without a complex, increasingly restricted process. This reality is something every company with significant cloud spend needs to clearly understand.

The history of cloud resale

There was once a functioning resale market for cloud reserved instances. AWS, for example, maintained a Reserved Instances Marketplace where companies that had purchased reserved capacity could sell those reservations to other AWS customers. This was a legitimate, AWS-sanctioned process. Companies would register as sellers, list their unused reservations with pricing and terms, and if a buyer appeared, the marketplace would facilitate the transaction.

The resale market was useful for companies that had overestimated their needs or whose business changes reduced their cloud consumption. Instead of simply absorbing the cost of unused commitments, they could recoup some of that investment by selling to other organizations with unmet demand. It created a secondary market that added liquidity to what was otherwise a rigid financial arrangement.

My client had some experience with this resale market a few years ago and assumed they could use it again. They were unpleasantly surprised to learn that the rules had changed.

AWS changes the rules

In January 2024, AWS implemented a significant policy change that effectively shut down the resale of EC2 Reserved Instances on its platform. AWS stopped allowing companies to resell their unused reserved capacity through the Reserved Instance Marketplace or any other official channel. If you have a reserved instance commitment with AWS, you are essentially stuck with it unless you can use it yourself or modify your reservation.

This change had a real impact on companies that had relied on resale as part of their cloud financial management strategy. It reduced flexibility and increased the risk of long-term reserved commitments. When I explained this AWS policy change to my client’s representatives, I could hear the frustration in their voices. They had made their commitment in good faith, carefully modeled their expected AI workloads, and now faced the reality that there was no easy exit.

The reasoning behind this change is not entirely clear, but AWS likely viewed capacity resales as something that complicated their billing and commitment models without providing enough benefit to the overall ecosystem. Regardless of the company’s reasons, the primary resale path for the largest cloud provider has been effectively closed.

What options still exist?

What can companies do now when they find themselves with reserved capacity they no longer need? The first possibility is to work directly with the cloud provider to modify or exchange the reservation if it is convertible. Some reservation types allow modifications, such as changing the instance type, region, or tenancy. This will not eliminate the commitment, but it may help companies better align their reservations with actual workload needs.

The second option is to use third-party brokers and marketplaces that operate independently of the cloud providers. Although AWS has shut down its official resale channel, brokers and marketplaces still facilitate resale arrangements for other cloud providers and for some AWS scenarios. These arrangements can be more complex and carry more risk, but they remain a possibility for companies determined to move unused capacity.

The third alternative is to optimize usage. Companies can invest in better utilization monitoring, workload placement, and automation to ensure that reserved capacity is used as efficiently as possible. This does not recover the money already spent, but it reduces future waste.

My client explored all three alternatives and found that each had significant limitations. Modifications were possible, but only within a narrow range. Third-party brokers were interested, but the process was opaque and uncertain. Optimization helped, but it could not eliminate the fundamental overcommitment they had already made.

The broader implications

Cloud commitments are more rigid than many enterprises initially realize because they lack a liquid market and because providers control modifications, transfers, or cancellations. Right now, I see this pattern most often in the AI space. Companies commit to massive amounts of compute for training and inference based on projections that rarely reflect the actual workloads. Then they are surprised to find themselves locked into payments. The AI boom has led to significant overcommitment because enterprises remain unaware that the resale mechanisms that once existed have been largely shut down.

This is why cloud financial management has become such an important discipline. Companies need to be far more thoughtful about how they commit to cloud resources, how they model their future consumption, and how they build flexibility into their cloud strategies. The days of assuming you can always resell your way out of an overcommitment are effectively over, at least with AWS.

For Azure and Google Cloud, the resale landscape is slightly different, but the same general principles apply. These providers have their own capacity transfer policies and, like AWS, those policies can change at any time. Companies should understand their options before making large, committed purchases and build contingency plans in case their actual usage diverges from their projections—or if resale policies change.

The bottom line is that reselling unused reserved cloud instances is far more complicated than it sounds. The market is not as open as it once was, the options are limited, and the providers themselves hold most of the cards. My client got burned, and I doubt they will be the only one. Companies that want to optimize their cloud spending should focus on accurate forecasting, thoughtful commitment sizing, and ongoing optimization rather than relying on resale as a safety valve. That approach worked at one point, but those days are largely gone.

  •  

Can Meta really compete in the cloud business?

Meta is reportedly planning a cloud business that would sell access to AI computing power and models, extending its internal infrastructure into a commercial service for outside developers and enterprises. Reuters, citing Bloomberg’s reporting, noted that the planned offering would allow customers to access AI models hosted on Meta’s infrastructure and pay based on usage, effectively positioning the company in the infrastructure-as-a-service and AI platform markets. On the surface, this seems like a logical next step. If you are already spending enormous amounts of money to build AI infrastructure, there is a natural temptation to ask whether some of that investment can be monetized beyond your own internal use.

I have seen this pattern before. A company builds sophisticated internal systems, recognizes their value, and then begins to imagine that becoming a cloud provider is simply a matter of exposing those capabilities to external customers. It sounds straightforward, especially given the excitement around AI and the demand for high-performance infrastructure. But cloud computing is not just another distribution model. It is not simply a matter of offering on-demand multitenant services and charging a fee. It is a deeply operational, trust-based business in a market that punishes companies that do not fully understand what enterprise customers require.

A crowded neocloud market

The first problem Meta faces is that this is not an open opportunity. The neocloud space, meaning purpose-built AI infrastructure delivered as a service, is already crowded and increasingly difficult to enter. Amazon, Microsoft, and Google dominate the conversation for obvious reasons. They have years of cloud operating experience, broad service portfolios, global reach, mature ecosystems, and deeply established enterprise relationships. Oracle remains a serious player as well, especially in enterprise applications, data platforms, and performance-sensitive workloads. IBM still matters in hybrid cloud, operations, and industries where governance and regulatory rigor remain central.

That list alone should give Meta pause. These companies are not just infrastructure vendors. They are experienced cloud operators. They have spent years building not only the underlying platforms, but also the native capabilities enterprises now expect by default. Those capabilities include security, governance, identity management, observability, support, compliance, billing controls, resilience planning, and integration with the broader enterprise technology estate. These are not secondary features. They are part of the core value proposition.

This is why late entry into the cloud market is so hard. A new provider is not just competing on price or capacity. It is competing against accumulated trust. Enterprises are not casual buyers. They are selecting long-term operating environments for applications, data, AI models, and business-critical processes. They want confidence that the provider understands how these services will be consumed, governed, and supported over time. Meta is entering a market where the incumbents already have a major head start on all of those fronts.

Harder than it looks

Over the years, I have had many technology companies come to me and say they wanted to reposition their technology in the cloud space, either as software as a service or infrastructure as a service. In the beginning, enthusiasm is always high. The technology is impressive. The market size looks attractive. The revenue models appear compelling. Investors love the story. Then we begin to walk through what it really means to operate as a cloud provider, and the optimism usually fades fast.

The questions become very practical and very uncomfortable. How will tenants be isolated? How will identity and access controls work across different kinds of customers? What governance models will be built in natively? How will workloads be monitored, optimized, and secured? What does support look like 24 hours a day, across regions, across industries, across compliance boundaries? How will outages be handled, communicated, and remediated? How will the platform integrate with existing customer tools for operations, policy management, and security response? How much investment will it take just to become credible before you even begin to differentiate?

Once companies fully understand the complexities, market dynamics, and the capital and execution required to compete even with secondary players, many of them back off. They realize that cloud technology is not a packaging exercise. It is a transformation in how a company designs, operates, supports, sells, and evolves technology. That is why I remain skeptical when any company assumes it can translate internal infrastructure excellence into external cloud success without a very long, disciplined commitment.

Meta’s market readiness

Of course, Meta is not lacking in financial resources. If any company can afford to spend aggressively in this space, it is Meta. The company has the capital to build infrastructure, absorb losses, hire experienced talent, and stay in the market long enough to make a serious attempt. I would never argue that Meta is too small or too poor to try. Quite the opposite. If there is any non-traditional entrant with the financial scale to force itself into the conversation, Meta would be high on the list.

But money does not erase complexity. It only gives you the chance to confront it. The real question is not whether Meta can afford to become a cloud provider. The question is whether Meta has what it takes to become an excellent cloud provider. Those are two very different things. Enterprises are not going to move meaningful workloads to a new platform simply because the company behind it is wealthy or technically famous. They are going to ask whether the provider understands enterprise consumption patterns, enterprise risk, enterprise governance, and enterprise operations.

That is where the challenge becomes much more serious. Meta has extensive experience running infrastructure for itself. That is valuable, but internal operating excellence is not the same thing as external service maturity. Running systems for your own workloads allows a high degree of control over architecture, standards, priorities, and operating assumptions. Running systems for paying customers requires flexibility, consistency, transparency, and support across a wide range of use cases that you do not control. Those are very different disciplines, and companies often underestimate the gap between them.

What exactly is Meta?

Another concern here is strategic clarity. Meta already has a complicated market identity. It is a social media company, an advertising platform company, a hardware company, an AI company, and still, in the minds of many, the company that spent billions pursuing the metaverse. If it now wants to be viewed as a serious cloud infrastructure provider, it will need to explain not only what it is offering, but why customers should believe this is a durable long-term commitment and not just another adjacent experiment.

That uncertainty can be damaging. Customers want stable providers with clear strategic intent. They do not want to architect important systems around a platform if they suspect the provider may lose interest, shift direction, or reframe the business after a few years of uneven results. Cloud computing requires patience, consistency, and deep customer orientation. It is not a market where strategic ambiguity helps.

This could become confusing for Meta internally as well. Building a true cloud business demands focus. It demands years of investment in areas that may not be glamorous but are absolutely necessary, such as governance, operations, controls, support frameworks, partner programs, and enterprise sales alignment. If the company is not willing to make those sacrifices fully and for the long term, the initiative will struggle.

  •  

AWS Continuum offers devs help with securing code

AI coding agents are making it easier than ever to produce software. Ensuring that software is secure before deployment is another matter — one that AWS thinks AI should help with too.

As enterprises adopt agentic development workflows, the volume of first-party code being created and modified is rising rapidly. Yet the process of validating vulnerabilities, determining whether they are exploitable, and fixing them often still depends on developers and security teams working through findings manually.

AWS is aiming to address that imbalance with Continuum, a new service designed to continuously discover, investigate, and remediate vulnerabilities in enterprise environments, whether the code is their own or from third parties.

Rather than simply generating alerts, the service is intended to help enterprises move findings through the entire remediation lifecycle, AWS VP of Security and Observability Chet Kapoor wrote in a blog post.

For first-party applications, Continuum can analyze code, validate whether vulnerabilities are exploitable, generate remediation recommendations, and propose fixes that can be reviewed through existing software development workflows, helping developers address security issues without requiring security teams to manually investigate every finding, Kapoor said.

Once users think Continuum has learned enough about their environment and understands their guardrails, they can put it in what AWS calls “enforce mode” to autonomously fix any code lapses, Kapoor said.

Continuum borrows some of its capabilities, penetration testing and code scanning features, from an existing service, Security Agent.

Other capabilities are all-new, including threat modeling, which is designed to automatically generate threat models from source code or design documents and output them in STRIDE format.

Keeping pace with AI-driven software development

Analysts see Continuum helping enterprise developer teams ship more secure code while keeping pace with AI coding tools.

“The harder problem is no longer just finding issues, it is knowing which ones are real, which ones matter in their environment, and which ones need to be fixed first,” said Akshat Tyagi, associate practice leader at HFS Research. “Traditional workflows built around dashboards and manual triage struggle with that volume. A dashboard can show the backlog, but it does not validate the finding, assess business impact, or help remediate it.”

Continuum’s value, according to Tyagi, “is not just more detection, but using AI to prioritize risk findings, suggest mitigations, and support faster action while keeping humans in control of high-risk decisions.”

Taking faster action is becoming increasingly important as attackers are gaining access to many of the same AI capabilities that enterprises are using to accelerate software development and security testing, according to Amit Chandak, chief analytics officer at IT consulting firm Kanerika. “The gap between a flaw being disclosed and a working exploit is shrinking rapidly from months to hours,” he said.

While Continuum may reduce repetitive work for developers and SREs, it could also create new responsibilities for CISOs around governance, oversight, testing, and maintaining guardrails for automated actions.

“Continuum changes the CISO’s role from managing findings to governing how findings are handled. The focus moves to setting rules: what can be automated, what needs human approval, and what level of risk is acceptable in production,” Tyagi said. “Staffing will shift too. There may be less manual triage, but more need for people who can review AI-generated fixes, set guardrails, and know when not to trust the system.”

Even so, Chandak does not expect the offering to lead to immediate headcount reductions, particularly given that Continuum is only available as a gated preview.

Continuum could change how CISOs measure work, Tyagi said: “Ticket count matters less. Better measures are how quickly real risks are validated and fixed, how many false positives are removed, and whether automation is reducing risk without causing new problems.”

Those same metrics could also become a yardstick for CISOs determining how much autonomy to give tools like Continuum, said Chandak. Most enterprises’ data and governance practices are not yet ready for fully autonomous remediation, said Chandak, adding that, “AWS’ graduated trust design, under which enterprises have the option of choosing the degree of autonomy, from human in the loop to fully automatic remediation, is an admission of that fact.”

Beyond first-party code

Continuum could also help CISOs with third-party code vulnerability analysis, where enterprises often have less visibility and control.

“Most third party vulnerability alerts are noise. A tool may flag a vulnerable library, but the real question is whether that vulnerable code is actually used in production. If Continuum can answer that, it helps teams focus on the few issues that matter,” Tyagi said. “This is especially useful for open-source and software supply chain risk, where enterprises depend on packages and hidden transitive dependencies they may not fully track. It also helps when no patch is available yet.”

However, he warned, Continuum might not offer a direct fix to third-party code: “You usually cannot patch third-party code yourself as you don’t own it, so remediation there means version pinning or compensating controls.”

  •  

Cloud at 20: How AWS shaped enterprise IT

It is tempting to date cloud computing from the launch of Amazon S3 in 2006 and the rise of infrastructure as a service (IaaS) that followed. That was certainly the moment the market changed in a visible, irreversible way. But the truth is that cloud began earlier, in the 1990s, when software as a service (SaaS), application hosting, managed services providers, and various forms of remote subscription computing started to reshape how enterprises thought about owning and operating technology. Even then, the core value proposition was familiar: Let someone else run the infrastructure, abstract the complexity, deliver capability as a service, and allow the business to consume only what it needs.

What AWS changed was the scale, accessibility, and precision of the execution. Amazon turned infrastructure into a programmable utility. It made compute and storage available in ways that were elastic, self-service, API-driven, and globally reachable. That was the breakthrough. Enterprises had outsourced pieces of technology before, but now they could rent raw infrastructure with unprecedented speed and flexibility. The launch of Amazon S3 was especially important because it provided a durable, scalable storage foundation that became one of the building blocks for modern digital business.

AWS changed everything

Technology markets are rarely transformed by the first company to think of an idea. They are transformed by the first company to make that idea operationally real, economically viable, and broadly consumable. AWS did exactly that. It built a model for infrastructure as a service that allowed enterprises, startups, and eventually governments to rethink the entire life cycle of IT delivery.

Looking back from 2026, it is difficult to remember how radical this concept once seemed. At the time, many enterprise leaders considered public cloud too risky, too immature, too uncontrolled, or simply too foreign for conventional IT governance. There were concerns about security, compliance, vendor dependency, performance, data residency, and reliability. Many of those concerns were valid. Early cloud adoption often ran ahead of cloud maturity, and many organizations discovered that moving quickly did not always mean moving wisely.

Still, the economics of agility overwhelmed the inertia of the old model. Provisioning that once took months could be done in minutes. Capital expenditure gave way, at least in part, to operating expenditure. Experimental workloads became easier to justify. Digital businesses could scale without building data centers first. AWS led that transition, and the rest of the industry followed, including competitors that helped mature the market.

Cloud’s strengths and liabilities

If the first decade of cloud was about acceleration, the second decade was about correction. Enterprises learned that cloud was not automatically cheaper, not automatically simpler, and not automatically better. It was better when used with discipline. It was more cost-effective when architected intelligently. It was more resilient when governance, operations, and security were designed into the system rather than added later.

This is when the industry grew up. We learned about cloud financial management because too many organizations assumed elasticity would control cost, only to discover that unused resources, poor workload placement, and fragmented accountability could drive spending far beyond expectations. We learned that public cloud could provide extraordinary innovation and reach, but also that not every workload belongs there. Latency, sovereignty, compliance constraints, legacy integration challenges, and predictable high-volume workloads all forced a more nuanced view.

We also learned about concentration risk. As enterprises standardized on a small number of hyperscalers, questions emerged around resilience, lock-in, and strategic dependency. The answer was never simplistic multicloud posturing for its own sake. It was architectural realism. Use the public cloud where it creates a clear advantage. Keep options open where business risk requires it. Understand portability, but do not romanticize it. In other words, cloud became less ideological and more practical.

Cloud is now an assumption

Perhaps the most important shift of all is that we no longer debate whether cloud is real or whether enterprises should use it. That argument is over. Cloud is baked into the cake. It is part of enterprise operating reality. The modern enterprise assumes on-demand infrastructure, platform services, automation pipelines, managed databases, identity fabrics, observability stacks, and globally distributed application delivery. Even when workloads remain on-premises or at the edge, they are often built, governed, or operated with cloud-native thinking.

This is maturity. Cloud is not a project or a trend. It is not even a strategy by itself. It is an enabling model that now underpins enterprise strategy. Businesses no longer ask whether to adopt cloud in the abstract. They ask how much cloud, which cloud services, under what governance model, at what cost profile, and in support of which business outcomes.

That may sound less exciting than the early days of disruption, but it is actually the mark of success. The most powerful technologies eventually disappear into standard practice. Electricity, networking, virtualization, and mobile platforms all went through this process. Cloud has done the same.

How cloud supports the AI race

As enterprises move aggressively into AI, cloud has entered another pivotal phase. AI is not replacing cloud. It is intensifying the importance of cloud while also changing how value is measured. Training, tuning, deploying, and governing AI systems require immense computational scale, specialized infrastructure, distributed data access, and operational consistency. Public cloud providers are well positioned to offer those capabilities, particularly with GPUs, AI platforms, managed model services, and data integration tools.

But this is not a repeat of the early cloud era. Enterprises are more sober now. They know the importance of cost, latency, and data gravity. They know that governance and accountability matter more in AI than perhaps anywhere else in modern IT. The role of cloud in the AI race is therefore foundational, but not absolute. Some AI workloads will run in public cloud. Some will be distributed across edge computing environments. Some will remain in private environments for reasons of sovereignty, economics, or control. The key is not to force a universal answer. The key is to create an architecture that aligns AI ambitions with operational reality.

Cloud should play the role it has gradually earned: not as a religion, but as a strategic utility. For AI, the cloud is where many enterprises will source scale, experimentation speed, global reach, and managed innovation. The winning organizations understand where cloud creates leverage and where other operating models make more sense.

Changing how enterprises think

The real story of the past 20 years is not just that AWS launched S3 and helped popularize infrastructure as a service. It is that cloud changed enterprise behavior. It normalized service consumption over asset ownership. It moved architecture toward abstraction, automation, and modularity. It forced IT organizations to broker capability rather than build everything from scratch. It redefined speed as a core competitive requirement.

And now, as AI becomes the next forcing function, cloud stands less as a novelty and more as the platform on which the next era will be built. That is a remarkable outcome for something that, in many ways, started with the old idea that computing could be delivered remotely on a subscription basis. We have been heading here for longer than many people realize. In the past two decades, led in large measure by AWS and the broader hyperscale movement it accelerated, cloud has evolved from a gamble to an indispensable foundation.

Hard to believe? Yes. But also inevitable in retrospect.

  •  

The GPU multitenancy mess

We’re seeing an interesting infrastructure tug of war today where GPU clouds are being pulled in two directions. For the economics of AI to work, the enterprise market needs to carve expensive hardware into smaller, shareable units and hand it to customers on demand, similar to how CPUs are doled in public cloud infrastructure. But the more the providers push GPUs to behave like elastic cloud infrastructure, the more they run into the reality that this GPU hardware was never built for safe multitenant use, fast fault recovery, or clean isolation between workloads. That tension is becoming one of the defining operational problems of the AI infrastructure market.

When a gamer launches Steam or the Epic Games Store on their laptop, they don’t have to worry about which GPU is being scheduled, how memory is going to be divided, or really any of the security boundaries or hardware assignment issues on their PC. For consumer PCs, these issues are not just hidden from view, they are irrelevant.

But for today’s IT teams managing GPU-driven AI workloads across distributed systems, those types of allocations and partitions need to be managed manually and carefully. This includes deciding which GPU to assign to each workload, how to divide memory, how to isolate tasks, and how to maximize utilization of this very expensive hardware. That’s why you heard so much about “Day 2” AI infrastructure themes around Nvidia’s GTC event this year.

The legacy hardware bottleneck

GPUs were originally developed to speed up graphic rendering and to perform local compute via shaders in service of graphical rendering. Their design assumes a trusted computing environment in which a single application controls the device. When a user runs an application on a GPU, it accelerates that particular workload.

But while GPUs are optimized for throughput, and therefore have thousands of simple cores designed to execute the same instruction over large datasets, this design paradigm creates several major technical limitations regarding context switching and memory isolation. GPUs were designed to produce pixels, not to run sensitive AI applications from multiple tenants using the same hardware.

As a result, GPU infrastructure today behaves less like elastic cloud infrastructure and more like carefully managed hardware appliances.

The partitioning paradox

Today’s AI infrastructure requires GPUs to behave like shared, elastic cloud resources. As inference workloads begin to outstrip large-scale training runs, the ability to slice and share expensive hardware among multiple tenants in real time while maintaining acceptable fault tolerance is no longer optional.

Hardware vendors have introduced new approaches to dividing GPUs into multiple isolated compute slices. Other frameworks approach partitioning through schedulers and container runtimes. But resource partitioning is just one slice of the overall GPU operations pie.

There is currently no widely adopted, cross-vendor operating model for achieving this safely at scale. Most providers are faced with either dedicating a single customer to a physical machine (thus wasting available capacity), or accepting the multi-tenancy security risks currently without a known solution. The current engineering challenge has moved from beneath the model layer and into the infrastructure layer. Success now relies on the ability to quickly launch new workloads and to rapidly contain hardware faults so that a single GPU failure does not bring down all workloads running on the server.

Untrusted code and tenants

The vast majority of current GPU programming models rely on the idea that the driver has complete control over memory protection and that no user will act maliciously. Unfortunately, that assumption completely falls apart in a cloud environment where one VM or container can leave behind data remnants in memory that another VM or container may access. Especially considering that how GPUs execute code is often completely opaque.

A single faulty workload or a single faulty driver failure in a shared GPU environment can also take down every workload (job) that was being run on the same server, increasing the amount of damage caused by an operational failure.

Currently, there are immature options for runtime inspection or behavioral auditing, limiting both visibility and control for security teams. GPU drivers provide a large attack surface and generally limited telemetry from the hardware. In these shared environments, embeddings, weights, prompts, and tokens are now all sensitive data points, creating significant blind spots for those attempting to protect intellectual property.

The high cost of cold starts

The real constraint in many GPU clouds is not model performance but operational efficiency. Right now GPU operations looks like 30 minute tenant spin-up times, 70% idle rates, and engineers continuously debugging infrastructure stacks. Today’s GPU clouds are stalled not due to inferior models, but because the infrastructure layer underpinning these clouds was never designed to support such a high degree of scale.

A 30 minute cold start is a fundamental limitation on the modern AI business model. Those GPU clouds that can spin up workloads in seconds will ultimately win against those that do not. Multitenancy is the only viable means of producing sufficient unit economics to make this very expensive hardware viable for the long term.

Bridging the orchestration gap

Platform teams are beginning to recognize that GPUs require a specialized operating layer between the hardware and workloads. Operators need a unified operating model that supports multiple hardware vendors and GPU models. Cloud providers need a method to safely slice and share servers among tenants, and to prevent cascading failures, while rapidly launching new workloads.

Enterprises are increasingly seeking to run sensitive AI applications with stronger isolation guarantees, and thus are turning to newer categories of software designed specifically to manage the “dirty work” of hardware orchestration.

The race to make GPUs more operational

Prior to Kubernetes standardizing container orchestration, the industry was constantly debating the efficiency of container scheduling and bin packing across clusters. Those operational concerns were eventually automated and incorporated into infrastructure layers that made the complexities invisible to the end user. 

A similar evolution is occurring around GPUs today. While platform teams continue to argue over placement strategies and memory tuning, these decisions will likely be automated within five to 10 years. As AI infrastructure evolves, the most valuable layer may not be the GPUs themselves but the operating layers that make them secure, elastic, and efficiently sharable. So the winners in the AI race won’t necessarily be just those with the most silicon, but those who have the best operating models for making that silicon secure and elastic.

—

New Tech Forum provides a venue for technology leaders—including vendors and other outside contributors—to explore and discuss emerging enterprise technology in unprecedented depth and breadth. The selection is subjective, based on our pick of the technologies we believe to be important and of greatest interest to InfoWorld readers. InfoWorld does not accept marketing collateral for publication and reserves the right to edit all contributed content. Send all inquiries to doug_dineley@foundryco.com.

  •  

AWS targets a longtime cloud migration blocker with SQL Server license portability

Licensing can be complicated, particularly when enterprises are forced to double-pay because the software they already own is only licensed for a specific environment, and moving it requires a whole different licensing model. Without proper portability rights, they need to make additional financial investments to run the same workloads in a different home.

AWS says its new Bring Your Own Media (BYOM) service eliminates this duplication. Customers can now reuse their existing Microsoft SQL Server media and licenses on Amazon Relational Database Service (RDS) with no additional licensing fees.

This means enterprises no longer have to justify workload migrations to the cloud against existing licensing commitments and infrastructure investments, AWS said.

“What used to be a licensing barrier between operational SQL Server data and agentic AI is now gone,” AWS data engineer Srikanth Katakam and product marketing manager Colleen Betik wrote in a blog post announcing the service.

Avoiding the double-licensing problem

To drive true value, agentic AI apps must have access to elastic GPU capacity as well as direct, low-latency access to the data they need to reason and make decisions. But, AWS argued, that can be difficult in self-managed data centers and on premises infrastructure with limited access to agentic AI cloud-native services. But a lot of enterprise data lives in Microsoft SQL Server, and until now customers have had to pay for a second license to use a fully managed cloud service like RDS.

Now, with BYOM on Amazon RDS for SQL Server, enterprises can reuse their existing SQL Server Enterprise Edition or Standard Edition licenses through a “lift-and-shift” model. This brings their data into a fully-managed environment.

According to the licensing distribution terms, enterprises must provide their licensed SQL Server Release to Manufacturing (RTM) media to Amazon RDS. They can then upload that media to Amazon S3 and launch BYOM instances. Enterprises must configure AWS License Manager to perform automatic instance tracking.

From there, RDS automates patching, backups, high availability, and monitoring, while providing direct access to agentic AI and analytics services native to AWS. The platform also reports vCPU usage to provide visibility into SQL Server license usage, Katakam and Betik wrote.

“You do not need to choose between protecting your SQL Server licensing investments and giving your data a path to the AWS analytics and agentic AI services redefining what’s possible in the cloud,” they said. 

It’s important to note that this service is only available to enterprises with Microsoft Software Assurance (SA), an add-on which supports mobility and rehosting of existing licenses. Enterprises must verify that their SQL Server licenses comply with Microsoft’s licensing agreement, and that they have a SQL Server License (Standard or Enterprise) with SA. They also must submit a License Mobility Verification Form to Microsoft; it, in turn, will notify AWS once verification is complete.

AWS emphasized that enterprises remain responsible for compliance; it does not block operations if license limits are exceeded.

More control over workloads, loosening Microsoft’s grip

The advantage of this service, explained Mike Leone, principal analyst at Moor Insights & Strategy, is that enterprises can get a Microsoft SQL Server workload onto a managed AWS service without rewriting it for Aurora or paying for the license twice. This means they can modernize on their own schedule rather than being forced into rewrites before they’re ready.

“For a lot of shops, that control over timing is worth more than the license saving itself,” Leone said.

This also loosens Microsoft’s grip on enterprise workloads, because organizations finally have somewhere else to run SQL Server using licenses they already own, he noted. Realistically, their dependency shifts to AWS rather than disappearing entirely, as their data ends up living next to AWS’s AI services.

“For a lot of teams, that’s a trade they’re glad to make for the managed infrastructure and the AI tooling they get in return,” Leone said.

Yaz Palanichamy, a senior advisory analyst at Info-Tech Research Group, also pointed to significant improvements stemming from the migration. Notably, it allows organizations to transition away from static, linear, or reactive storage capabilities towards more dynamically intelligent environments.

“The key is to balance the unification of transactional data towards managed AI and machine learning pipelines,” he said.

Enterprises take on new responsibilities

The catch? Leone noted that enterprises now own the task of licensing compliance. Staying current on SA, the Microsoft maintenance contract that makes any of this legal, and the license mobility rules, “become your headache instead of something baked into the bill,” he said.

Furthermore, he added, lift-and-shift has a way of turning into “lift-and-forget” when enterprises move SQL Server as-is and never actually modernize, “so you end up carrying all the old baggage onto a shinier platform.”

Palanichamy also pointed to skyrocketing AWS costs, since operationalizing AI agents requires a considerable amount of data ingestion and querying. This can potentially be cost prohibitive on RDS for SQL Server.

“One aspect to consider would be the relative time to production value, so that enterprises can better handle the management of volatile AI workloads,” he said.

Just one challenge in the AI race

Although AWS frames licensing complexity as a roadblock to agentic AI, analysts say it’s really just one piece of the puzzle.

Organizations are not in an AI-ready state due to a number of factors, Palanichamy noted. This could be total cost of ownership (TCO)-related, a lack of appropriate acceptable use policies (AUPs), or concerns around security and compliance.

If and when enterprises are ready to adopt AI, they must perform thorough needs analysis/process optimization benchmarking exercises to determine what workflows could benefit from the technology, he said, and, conversely, flag workflows where AI could prove “an impediment or potential disservice.”

Leone also pointed out that moving SQL Server onto RDS doesn’t “magically make your data agent-ready,” nor does it make it smarter. The data proximity and managed plumbing are what actually support agents. Sitting data next to Bedrock and the rest of AWS’s AI services means builders “stop wasting time shipping the data around or building one-off integrations every time an agent needs it.”

Ultimately, though, licensing isn’t the real issue when it comes to AI; it’s more of a migration problem. The real roadblocks are messy data, questionable governance, and teams that aren’t ready to run it in production, and, Leone said, “no change to a license bill touches a single one of them.”

  •  

Microsoft’s Web IQ aims to give enterprise AI agents real-time web intelligence

For the past two years, enterprises have focused on grounding AI systems in internal documents, databases and knowledge repositories. Microsoft now contends that the next challenge is giving those systems reliable access to the outside world as they move into production.

At its ongoing annual Build conference, Microsoft unveiled Web IQ, a new suite of AI-native APIs designed to connect AI agents and applications to real-time information from across the web, including web pages, news, images and videos.

The goal is to help developers build more accurate and context-aware AI systems while reducing the complexity of integrating web search, retrieval and grounding capabilities into enterprise applications, the company wrote in a blog post.

The APIs already underpins grounding for Microsoft Copilot and ChatGPT, and unlike traditional search APIs are designed to retrieve highly relevant information while minimizing token consumption, helping reduce both inference costs and response latency, Microsoft said.

Reducing the cost and complexity of web grounding

That focus on reducing inference costs and response latency to deliver Web IQ’s search capabilities will be valuable for CIOs and developers, said Phil Fersht, chief analyst at HFS Research.

“Developers have typically stitched this together themselves using search APIs, web scraping, retrieval-augmented generation, vector databases, custom ranking logic, crawling tools and separate orchestration layers. That works, but it is messy, brittle and expensive to maintain,” he said.

“The hard part is not just finding a web page. It is retrieving the right evidence, ranking it, selecting useful passages, reducing token waste, respecting publisher controls and doing all this fast enough for multi-step agents,” he added.

An agent running in production will typically run at least five or ten retrieval steps and in such scenarios latency and cost can become “ugly,” said Moor Insights and Strategy principal analyst Mike Leone.

“I’ve watched plenty of teams handle this by gluing a search API onto a model and hoping the model can sort through whatever HTML comes back, which isn’t ideal,” he said.

Simplifying development of applications

Beyond the infrastructure and cost advantages, Web IQ could also simplify the AI application building process developers, said Stephanie Walter, practice lead of the AI stack at HyperFrame Research.

“The value of Web IQ is that Microsoft is trying to make web grounding a reusable, agent-native service rather than a bespoke integration,” Walter said.

That reusability, Fersht said, will matter to CIOs as most enterprises do not want every development team rebuilding its own web grounding stack: “They need a common capability that is governed, scalable, low-latency and economically efficient.”

Still, Microsoft is not entering an untapped market and there are several offerings already available, including OpenAI web search, Google grounding, Perplexity APIs, Bing Search APIs, Azure AI Search, vector databases, and custom RAG pipelines.

However, Microsoft might have an advantage with IQ, despite Google’s strength in search and web-scale knowledge, OpenAI’s tooling push, and AWS’ Bedrock-data-service-partner integrations combo, Fersht said.

“Microsoft’s differentiation is that it can combine Bing’s global web index with Azure AI, Copilot, Foundry, Microsoft 365 and enterprise developer channels,” he said.

The other advantage is the existence of existing IQ offerings, such as Work IQ, Fabric IQ, and Foundry IQ, all of which are targeted towards adding more business context for agentic systems, Fersht added.

But uptake, Walter said, will depend on whether these integrations translate into better production outcomes.

Web IQ is currently available in limited access for select Azure customers. Enterprises can request access to Web IQ via their Microsoft account team or submit a form.

Beyond direct API access, developers can also configure the model-agnostic Web IQ as an MCP tool within Foundry IQ, a Microsoft spokesperson said.

  •  
❌