As AI continues to help the world of work evolve, more and more roles are increasingly embracing the technology in a bid to improve efficiency and value for money.
Perhaps nowhere is that more important than procurement - often a neglected area of interest, it plays a vital role for businesses across all industries, and has proved ripe for AI innovation so far.
We spoke to Amy Worth, Director Amazon Business UK and Public Sector Customers EU, to find out more.
AI is becoming increasingly embedded in procurement. Where are you seeing AI-powered purchasing insights deliver the greatest value for organisations today?
AI is helping procurement teams move beyond simply processing transactions to making faster, more informed decisions. Many organisations face increasing pressure to do more with fewer resources, making data-driven insights more valuable than ever. Yet, a fifth of decision-makers say they lack systems to monitor and manage risk effectively.
AI can help to address that by offering better visibility into purchasing activity to identify spending trends, spot anomalies within the supply chain, and uncover savings opportunities. And by having AI embedded into everyday procurement workflows, teams spend less time searching for information and more time focusing on supplier relationships and strategic decision-making.
How can better purchasing visibility help organisations identify savings opportunities while strengthening spend governance?
Organisations can't control what they can't see, so having a clear view of purchasing activity is essential for identifying savings opportunities and maintaining effective spend management. Rather than relying on manual reporting, procurement leaders increasingly need real-time insights that highlight spending patterns and flag unusual purchasing behaviour.
Tools such as Spend Visibility, which provides dashboards and visual analysis to easily track orders, spend and compliance can help organisations get a much clearer understanding of purchasing activity and help uncover savings opportunities.
Many organisations are looking to simplify purchasing and reduce supplier complexity. How can this help build more resilient supply chains?
In order to build resilience in supply chains, it’s important to have the right procurement foundations in place before challenges arise, so businesses have the flexibility to respond quickly when disruptions occur. Reducing unnecessary complexity and simplifying purchasing is key and helps create that agility.
We help businesses streamline processes, improve visibility and make it easier to source from trusted suppliers, while also enabling them to maintain access to a broad supplier network which gives organisations greater choice when circumstances change.
As business buying continues to evolve, what do you see as the biggest priorities for procurement leaders over the next few years?
Procurement leaders are balancing a wider set of priorities than ever before. That means alongside managing costs and improving operational efficiency, they're also expected to strengthen supply chain resilience, support sustainability goals and provide better insights to help inform wider business decisions.
It’s not as easy to manage all these priorities at once, and having access to reliable data becomes more important than ever, as it allows you to use the technology available to help make the right purchase decisions to meet these competing objectives.
Looking ahead, what role do you think AI will play in helping procurement teams move beyond cost control to become more strategic business partners?
AI has the potential to fundamentally reshape the role of procurement by moving the focus to more strategic work. At Amazon Business, we see AI as a tool that removes friction and administration rather than replacing expertise, by helping organisations analyse purchasing data more effectively, identify opportunities more quickly and help make better-informed decisions.
With that friction removed, procurement professionals will be able to focus on building supplier relationships, improving resilience and creating long-term value for their organisations.
What is AI good for? It's a question I get asked and ask myself almost every day. Unlike a wrench, hammer, or screwdriver, which are each good for one or two tasks, AI is amorphous and intimidating in its breadth. It seems capable of almost anything, especially as it changes and grows more intelligent. People pump it up as a do-it-all wonder, and yet, the question remains: what would I do with it?
Often, I find the answer to that question in the moment. For instance, as a partially color-blind person, I struggle to match clothing. Now, I often ask Gemini. I'll take my iPhone 17 Pro Max, open Gemini, turn on Gemini Live, pick out a shirt or pants (or both), and ask if they go together or which option is best. I always get an answer and, honestly, I usually follow the uncomplicated AI-generated advice.
Success in one area of your life with technology usually leads you to try it in another, especially with the ever-fungible AI.
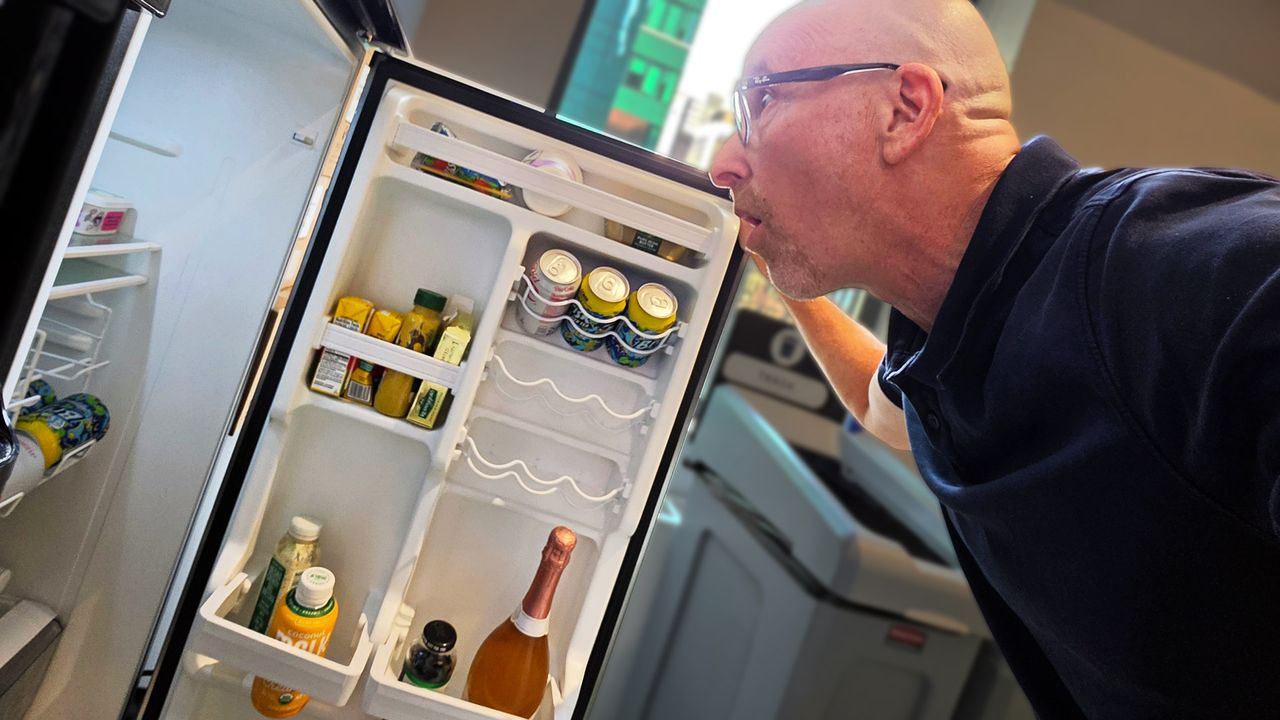
In my house, I'm known as the risk taker, at least when it comes to food. "Best by" is a suggestion. "Use before,' is friendly advice. My family often blanches at my aged food consumption habits. Yes, I'll eat that five-day-old steak. Those English Muffins expired two weeks ago? Slide them over.
Enter the risk-taker
I know, it's not great, and when it was lunchtime this weekend I slid the week-plus-old store-bought-and-made chicken salad from the fridge and considered making a sandwich.
Staring at the "made on" date as if my gaze might rearrange the figures, I realized that I might be taking a risk. So I opened the container and sniffed the still spry-looking salad. It's at moments like this that I wonder, "What am I doing? Does my nose really know the difference between safe and stale or, more importantly, safe and decidedly turned?" I can tell you with some confidence: it does not.
Still, having grown up in a house where money was tight and you rarely threw anything away, I was hesitant to dump this half-a-pound of chicken salad (slightly turned or not).
I stood there in my kitchen for a minute, weighing my options and thinking that slightly sour chicken salad might not, with the right toast, be that bad.
Then I looked at my phone, lying face down on the counter, but surely judging me.
I would ask Gemini.
Putting Gemini on the menu
After launching the app, I turned on Gemini Live and pointed the camera at the open container. "Hey, this chicken salad was made on 8/1. Do you think it's still good?" I asked hopefully.
Gemini thought for a moment and then responded, but not in the way I expected.
Before giving me the answer, Gemini launched into what sounded a bit like one of those disclaimers for an Ozempic TV commercial:
"This information is not intended to be a substitute for professional medical advice, diagnosis, or treatment. Always seek the advice of your physician or other qualified health provider with any questions you may have regarding a medical condition."
Clearly, I struck a nerve. I only asked about the chicken salad, not if I should have a kidney removed.
I get it. If I'd asked this question a couple of years ago, Gemini might've launched right into an analysis, but concerns about AI accuracy and understanding of human needs and context have risen since the emergence of generative AI. Sure, it's way smarter and less likely to give you false or hallucinated information, but it's also, well, not a doctor or even a dietician.
A recent Gallup poll found that more than 25% of Americans are using AI for health info or advice, and of them, more than half query AI for health-related advice and analysis before visiting a doctor. The problem is that AI is not a medical professional, and while it can dig through the billions of health- and medical-related bits stored online, it doesn't have a medical license. It can't understand or treat your various maladies.
In my case, though, Gemini drew a long thin line from my seemingly innocuous question about chicken salad freshness to a potentially incorrect answer, my possible gastric emergency, and a potential lawsuit against Google and Gemini brought on my behalf by my surviving family members.
Look, food poisoning isn't usually fatal, at least according to Healthline, but it is yucky and uncomfortable. I think Gemini was just trying to avoid me taking its word as law on this topic and a potentially bad outcome for both of us.
I'm still hungry
But what about eating this rapidly warming chicken salad?
After the voluminous disclaimer, Gemini got to the heart of the matter:
"According to food safety guidelines, chicken salad should be stored in the refrigerator for only three to four days. Since this chicken salad was made on August 1st and today is August 9th, it is no longer safe to eat and should be discarded."
The answer, based less on the looks of this chicken salad and more on general advice that I often ignore, ultimately had the desired result.
You and my family will be pleased to know I took Gemini's advice, threw out the chicken salad, and made myself a peanut butter and jelly sandwich.
Naturally, I asked Gemini's opinion:
"Yes, absolutely! A PB&J is a much better and safer option right now.
Peanut butter and jelly have a significantly longer shelf life and aren't prone to the rapid bacterial growth that affects meat-based, mayonnaise-heavy dishes like chicken salad. It's a classic, risk-free, and delicious backup plan. Enjoy your lunch!"
PricewaterhouseCoopers (PwC) is believed to have published several AI-generated reports between 2024 and 2026
The reports included various AI hallucinations, fabricated citations, and fake footnotes, which were identified by the GPTZero AI detection tool
PwC is one of the world’s largest accounting firms
Accountancy and auditing giant PricewaterhouseCoopers is alleged to have published at last four AI-generated or enhanced reports over the past three years.
An investigation by the GPTZero team found the reports – which make inaccurate and false claims – were published by PwC Middle East between 2024 and 2026, and were intended to act as thought leadership pieces.
Various indicators of AI-generated links and citations have been highlighted as a result of the discovery, and while PwC has responded, there is no direct indication how this happened or if action has been taken.
Vibe citations
GPTZero may be better known as a software tool for discovering plagiarism and AI-generated content, but it also boasts an investigation team.
The work of Paul Esau, Om Ogale, and Alex Cui has highlighted several problems with the publications issued by PwC, uncovering “a pattern of irresponsible AI usage resulting in hallucinated (vibe) citations, fabricated claims, and incomprehensible drafting and formatting decisions.”
Vibe citations are hallucinated references to works that an AI-generated document cites as genuine. In some cases, specific pages may be cited, but usually the vibe citations refer to titles and authors.
They can be demonstrated as fake due to issues such as non-existence, incorrect authors, incorrect publication dates, erroneous URLs… or the citation may simply not exist, as in one case highlighted in the GPTZero report.
Not all inconsistencies are determined to be hallucinations, however, as not all meet the GPTZero team’s standard for identifying vibe coding. So, while some other references with issues may be genuine and simply poorly cited, others may still be fake, but impossible to define.
PwC’s account
The reports that PwC (and its competitors) are publishing are an attempt to position themselves as authorities on AI, and its responsible use. They seek to encourage organizations to avoid issues such as fabricated claims and vibe citations, but rather than provide advice, it has been a live demonstration in what not to do.
PwC responded to the GPTZero report by telling the Financial Times: “Consistent with our approach to responsible AI, we have quality control processes for research and content development we expect all our people to adhere to.”
Unfortunately, it seems that a better process of quality control and fact checking ahead of publishing was required for these reports, and perhaps others so far undetected.
Perhaps most concerning is the realization that PwC is not alone in this. In the past 12 months, GPTZero has documented similar issues with all the “big four” accountancy firms, with PwC joining Deloitte, EY, KPMG in this “vibes gallery” of fabricated and unchecked citations.
Think our tech is getting a little too smart for its own good? You're not alone.
In the past few weeks, TechRadar brought you three key updates on the invasion of your privacy without consent, owing to the AI learning models nestled in our gadgets and appliances.
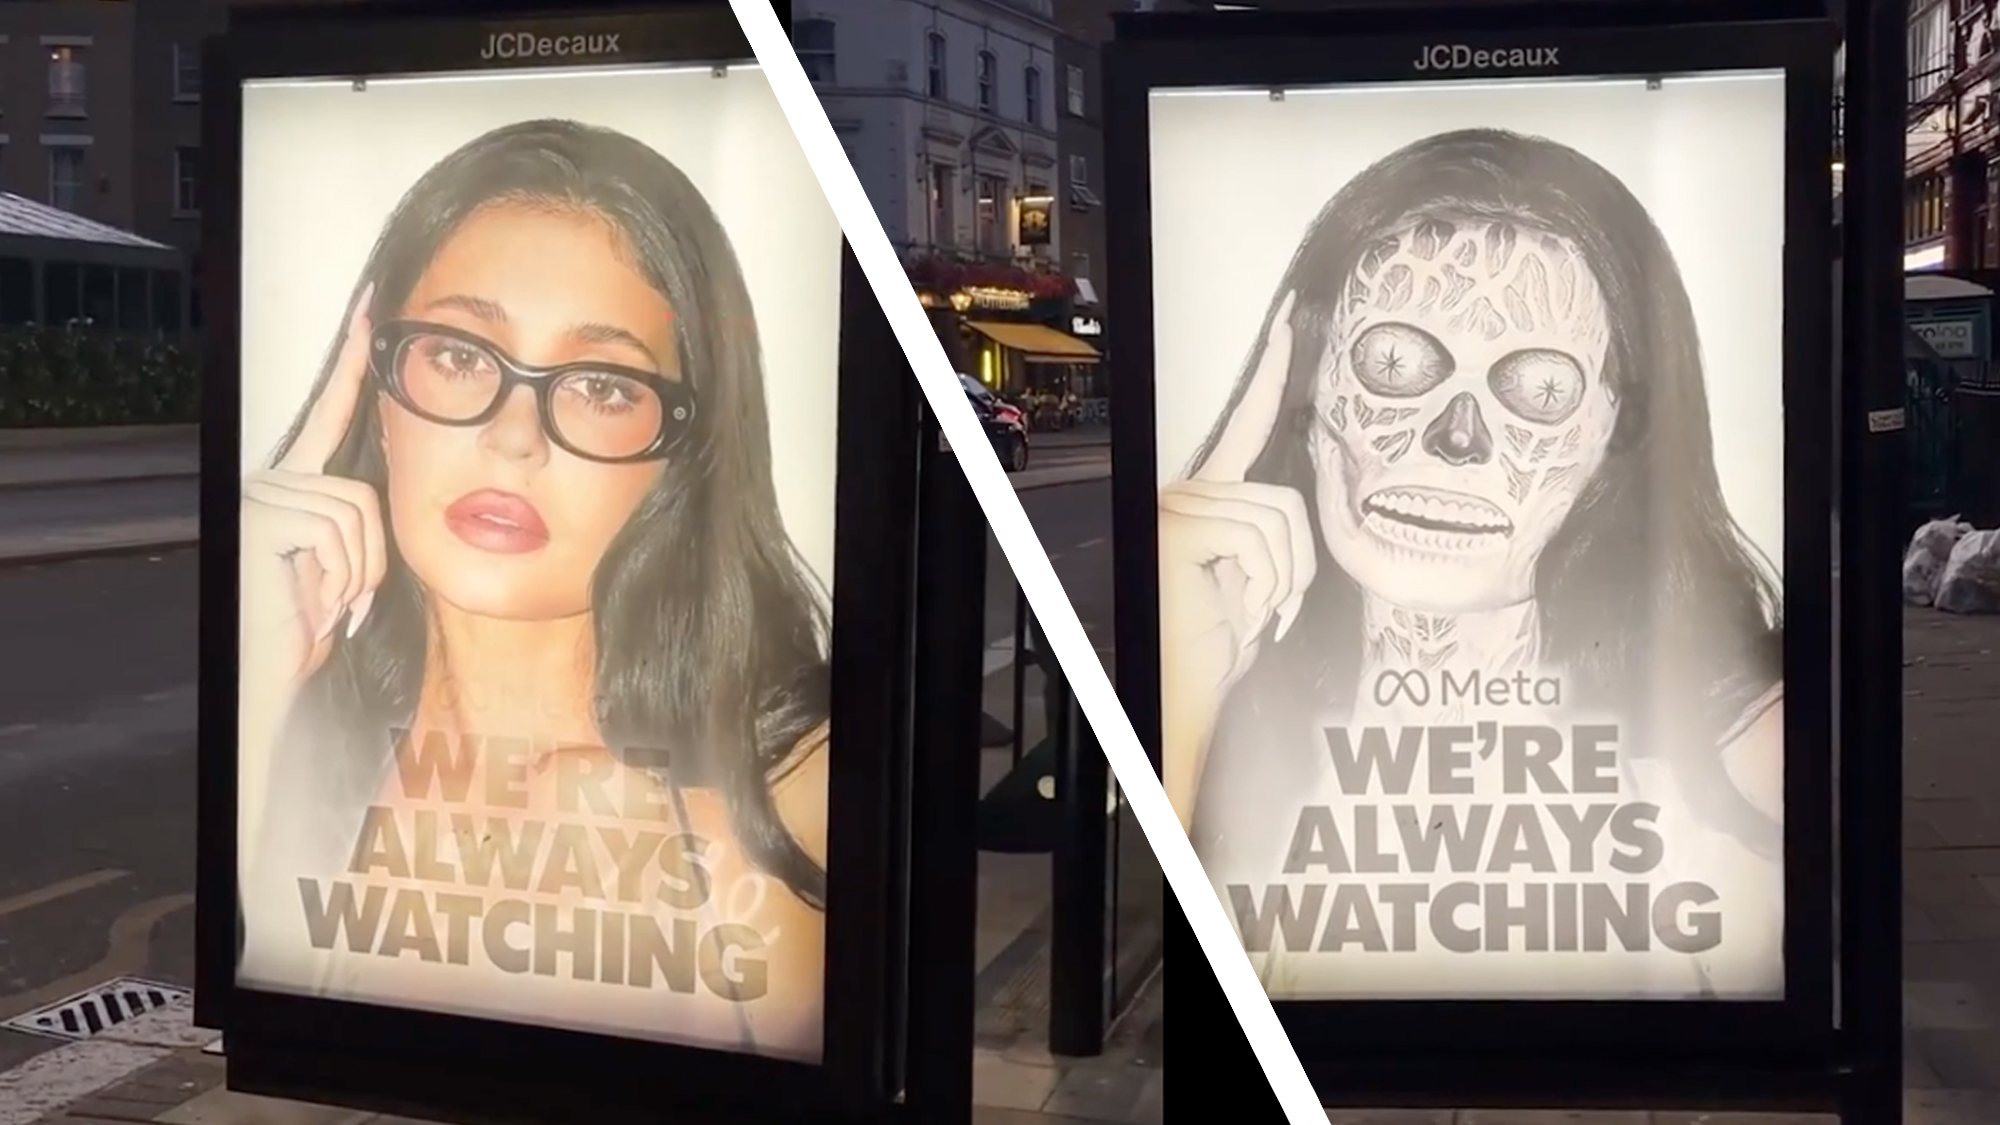
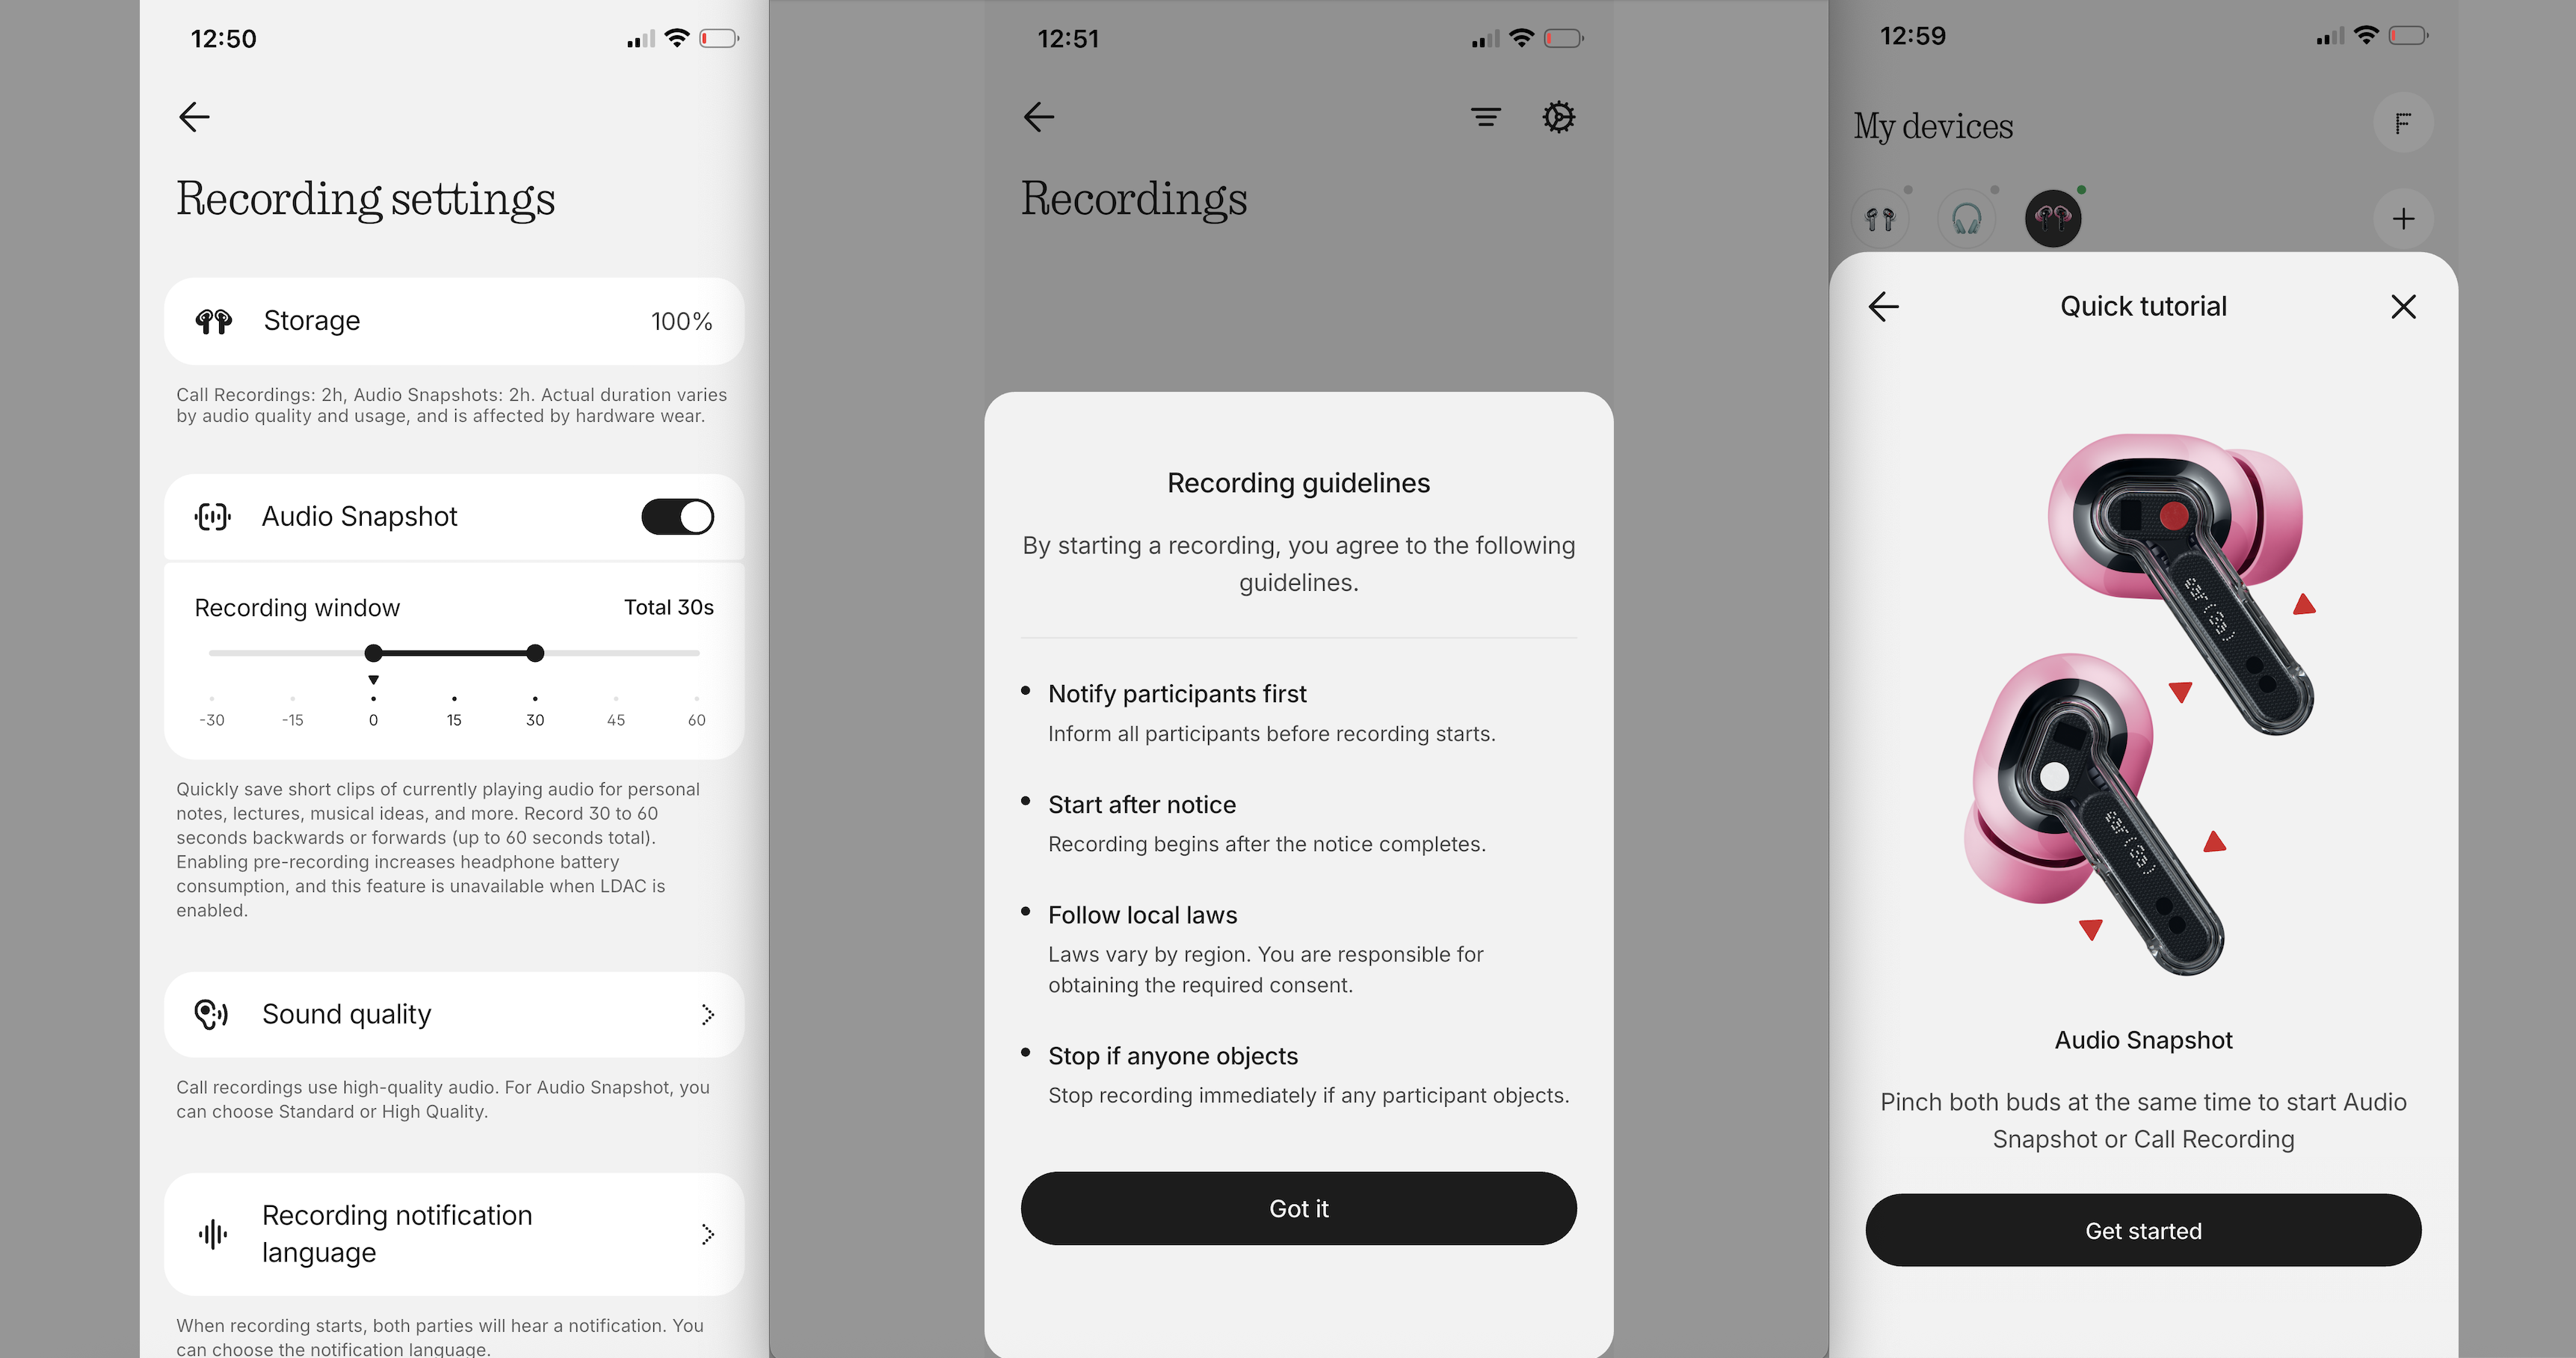
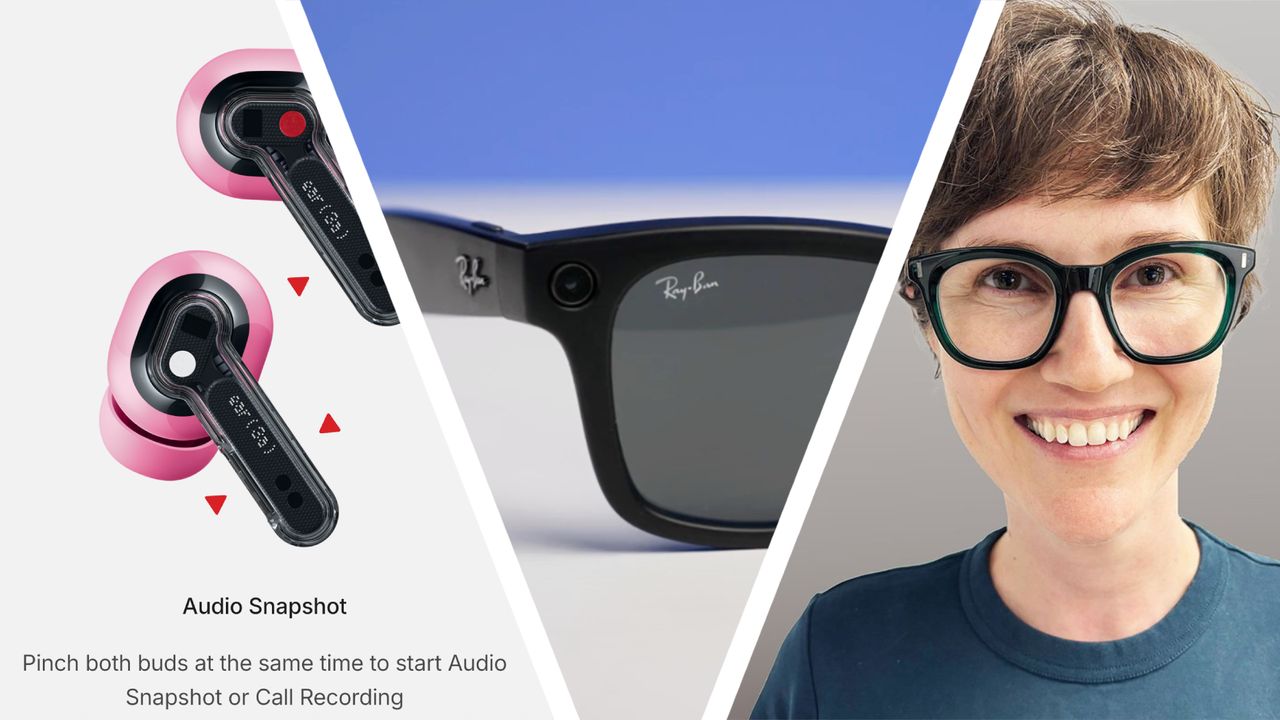
In case you missed the latest missives, new LG TVs can record you in the background and will ask you to notify anyone who comes into your home, to comply with "wiretapping" laws. Next up, Nothing's new earbuds offer a 'squeeze the stems to record calls' feature being called Audio Snapshot, which is tantamount to phone-hacking in cute packaging. And finally, there's the continued backlash over Meta's AI glasses. Despite the social media giant implementing a feature that stops recordings if a wearer tampers with the front-firing light, hatred of these and other smart shades (oft-renamed 'pervert glasses' by the general public) has led to people calling for camera-less glasses.
So, in a world where our glasses can watch, our earbuds can hear, our speakers can speak and our TVs are a little too closely invested in our lives for comfort, how much more will we allow our tech to intrude before enough is enough — and what can we do to regain some privacy?
'I see this as part of a bigger pattern that is a push by technology and other forces to normalize consumer surveillance'
Lauren Hendry Parsons, Mozilla Foundation (Director, Communications)
(Image credit: Everyone Hates Elon)
Your tech will see you now
Lauren Hendry Parsons is a seasoned advocate for digital rights and a gifted speaker in making these complex issues accessible. She is a director within the non-profit Mozilla Foundation, helping to make the organization's push for a "technology future that serves and is shaped by the people who use it" a message that resonates on a global scale.
Luckily, she has agreed to talk to me on the growing concern over surveillance tech's prevalence in our lives.
Parsons states that in order to zoom in on these issues, we need first to zoom out. "I see this as part of a bigger pattern," she begins, "that is a push by technology and other forces to normalize consumer surveillance — surveillance of people by other people — and that's something that we're seeing cropping up a lot."
So what's changed — after all, recording devices have existed for some time? The answer is the growing number of places where such surveillance is becoming normal.
"It's something that started in the Internet of Things home devices," she says. "You might talk to a smart speaker, or talk actively to another product that is doing your bidding — but it was usually tied to a place.
"Now, we're seeing the normalization of surveillance-chic behaviors, where fashion influencers are sharing their own Ring doorbells to show off their outfit of the day.
"That moves surveillance from something fixed inside a home, where people can at least see the object and talk about it, to something that's constantly moving through every space and every conversation."
And it's being packaged in pink earbuds, chic sunglasses or fun doorbells? Parsons agrees: "The chicification of surveillance to me is deeply concerning."
'It moves surveillance from something fixed inside a home, to something that's constantly moving through every space and every conversation'
Lauren Hendry Parsons
Who counts as the user — and should they really have control?
I want to talk about Meta's AI glasses and the involvement of Kylie Jenner in the ad campaign, especially when women's safety (regarding non-consensual surveillance and distribution of such footage) has been listed as a key concern.
I mention the fact that when speaking to several male colleagues about the benefits of such glasses (rather than the concerns), not one of them mentioned what I suspect all women thought: that wearing such glasses might mean filming your potential attacker, and that would be a very good thing.
"There are absolutely situations where people might want the convenience these products provide," Parsons agree. "Being able to translate something on the go or take a quick snapshot without getting your phone out. For people with disabilities or limited capacity, these tools could be genuinely useful.
"But I don't see the trade-offs being clearly explained. I don't see meaningful ways to opt out. Even if these companies have perfect data handling processes and perfect privacy records, the risk is being transferred to the consumer instead of being held by the tech company."
Parsons mentions one of the core issues at Mozilla Foundation: privacy by design. "Privacy by design, which is what we recommend as best practice, means products should be private by default," she says. "And that has to include bystanders.
"Technology companies talk about giving the user control, but who's counting as the user?
"With smart glasses, televisions, and recording earbuds, the purchaser isn't the only person affected. Just as children are affected by smart speakers or passengers by dashcams in cars, the person across the table or on the other end of the call is also a data subject, even though they have no access to the controls and no real way to opt out.
"True privacy by design must protect both the person operating the device and the people involuntarily brought into its data collection environment.
"When something (with surveillance tech built in) is fixed in your home or office, you can at least choose not to go there. You can suggest meeting somewhere else. That's difficult and has social consequences, but it's possible.
"If it's something someone is unobtrusively wearing in their ear or on their glasses, or something you don't even know they have, opting out becomes almost impossible."
(Image credit: Nothing (app screen grabs by Future) )
'No surprises, genuine user control, limited data collection, sensible settings, and multiple layers of protection. These examples show what happens when products fall short of those principles'
Lauren Hendry Parsons
I ask how we might regain some agency here, or at least get a handle on our privacy regarding AI glasses, call-recording earbuds and all-seeing TVs. Parsons points to the work she does.
"Mozilla's privacy principles are useful here," she says. "They're about no surprises, genuine user control, limited data collection, sensible settings, and multiple layers of protection. These examples show what happens when products fall short of those principles."
Another thing Parsons is keen to impress upon TechRadar is central to her work: understanding the trade-offs. "I don't see how everyone on the phone can understand those trade-offs and give informed consent," she says.
"The only way that could happen is if this (the recording of everything we do) became such a standard operating procedure that everyone expects it, because everyone has it. At that point, we would have completely accepted constant surveillance as the norm.
"I don't think the answer is necessarily to prohibit recording technology. It's to stop presenting recording as an ordinary, consequence-free convenience."
'I don't think the answer is necessarily to prohibit recording technology. It's to stop presenting recording as an ordinary, consequence-free convenience'
Lauren Hendry Parsons
She mentions translation in AI glasses as an example: "Companies could show translations without collecting or storing the underlying data, but we know that's not what's happening."
Another watch-word in Parsons' work is 'friction', and how disproportionately easy it has become to monitor, film and record secretly and without consent.
"Features with serious privacy implications should involve equal and proportionate friction," she says. "The more sensitive the activity, the stronger the consent mechanism should be."
I mention that when testing a set of earbuds recently, a simple beep to signify that recording has begun is the only notification the caller on the other end of the line receives. Parsons believes concern there is valid.
"Notification is not consent," she says. "We've become used to surveillance in places like train stations and public spaces because it's framed as being for safety. But I'd hate to see that extended to person-to-person interactions."
'Notification is not consent. We've become used to surveillance in places like train stations — but I'd hate to see that extended to person-to-person interactions'
Lauren Hendry Parsons
I ask if perhaps people should simply get OK with omnipresent filming or data collection by individuals and wider companies, since it seems so hard to avoid? Parsons' answer is emphatic: "That's deeply problematic."
"We're seeing the expectation that people should be comfortable being filmed all the time. Even terms and conditions often state that by attending, you agree to being photographed or filmed for marketing purposes. The default is that your data is collected unless you make the effort to opt out or avoid the event entirely. Again, that's deeply problematic.
"The diminishment of privacy is cumulative. It's one thing to have a fixed camera in a train station. It's another to be filmed by multiple people in different places without your consent, or to have your audio collected."
'It's one thing to have a fixed camera in a train station. It's another to be filmed by multiple people in different places without your consent'
Lauren Hendry Parsons
'The burden of this issue is not distributed equally'
Parsons reads me a quote from one of her own features, and it cuts to the core of the agency, consent and privacy debate better than anything I could ever try to surmise.
"The burden of this issue is not distributed equally, and the risk of ambient recording will fall disproportionately on people who already have less control in a situation," she says. "That includes workers, children, parents, patients, tenants, domestic abuse survivors, and protesters. This makes vulnerable populations more vulnerable."
Parsons mentions a novel but initially counter-intuitive solution suggested by some prominent female content creators. Instead of shunning Meta's glasses (or playing Disney songs if you realize you're being filmed, because Disney's music is better protected than women's lives), the idea is that women do wear them, specifically to film men when they start to behave in an inappropriate or predatory manner, then upload the footage everywhere. The thinking is that these products might then get regulated very quickly.
"If women collectively used them in that way — in a kind of, let's call it a neo-Me Too movement — I'd put money on consent issues being addressed much more quickly," Parsons says.
"The issue isn't simply that these products can record. It's that the examples you gave (the earbuds, the glasses, the TV that records in the background) all prioritize effortless capture over meaningful consent, when there are other ways to do it.
"The person operating the product gets all the convenience and control, while everyone else gets a light, a beep, or a legal disclaimer. That's an unacceptable imbalance.
"Recording has many legitimate and valuable purposes, but companies should be asking how to build consent into the infrastructure, minimize what's captured, and protect bystanders as rigorously as they protect the user.
"The false dilemma is, 'Do you just not want this technology?' But we shouldn't have to choose between useful technology and privacy.
"Preserving both means companies need to treat consent as a product requirement, not something buried in their terms and conditions."
'Companies need to treat consent as a product requirement, not something buried in their terms and conditions'
Lauren Hendry Parsons
Facial recognition (and how to make it disappear)
I ask Parsons about Mozilla Foundation's stance on digital facial recognition, a highly controversial feature that our phones and smart glasses are technically capable of. Although the big brands have so far disabled or restricted the software on glasses, there are strong suggestions that hackers have managed to scoot around it.
She mentions the rise of anti-surveillance fashion; garments that make their wearer invisible to the algorithm and thus can thwart the surveillance tech stuffed into our handsets and wearables.
"Looking ahead, we have two things happening simultaneously," Parsons says. "We have vastly increased computing power and data analytics capabilities that allow us to store and analyze more information than ever before, and we have recording devices embedded everywhere in increasingly unobtrusive ways. That combination is worrying.
"One of the brands we spoke to, Capable Design, explained it well: 'The problem with surveillance technology is citizens don't have a possibility in the physical world to opt out. In the digital space, we can say yes or no to cookies. In the physical world, we don't have this option. We wanted to create physical protection that would allow citizens to give their consent or not.'
"It feels as though we're being forced to pick sides: either you're comfortable with surveillance or you're actively trying to avoid it. Again, it comes back to the false choice between privacy and convenience because technology developers aren't prepared to give us both.
"I think these efforts are people trying to take back some agency. There's a feeling that all of this is inevitable.
"Particularly in the UK, where social norms and politeness are strong (this interview is taking place in the UK), I worry we're going to politely accept our way into a surveillance state because people feel uncomfortable challenging others or assume this is an inevitable progression."
'Particularly in the UK, where social norms and politeness are strong, I worry we're going to politely accept our way into a surveillance state'
Lauren Hendry Parsons
Our time together is nearly up, but Parsons wants to talk just a little more about the future. "I want to say this loudly because it's a core Mozilla Foundation belief: the future of technology is not inevitable," she says.
"These are choices being made by people within companies. They could choose a different path.
"That's why Mozilla Foundation funds projects and people who challenge the status quo. We're investing in positive alternatives because opting out as a consumer can feel almost impossible.
"We need companies making better choices, regulators setting stronger requirements, and a greater appreciation that friction isn't always a bad thing. A little friction can protect people, encourage creativity, and ensure meaningful consent.
"That's what I hope for the future: that we don't accept inevitability, that we invest in better technology choices, and that responsibility isn't pushed entirely onto the individual consumer at the point of use."
I want to say this loudly: the future of technology is not inevitable'
Lauren Hendry Parsons
(Image credit: William Yu)
AI another way
So, are there people within companies — even AI companies focused on "autonomous agents, edge intelligence, computer vision, and robotics" — looking to make different choices? Actually, yes.
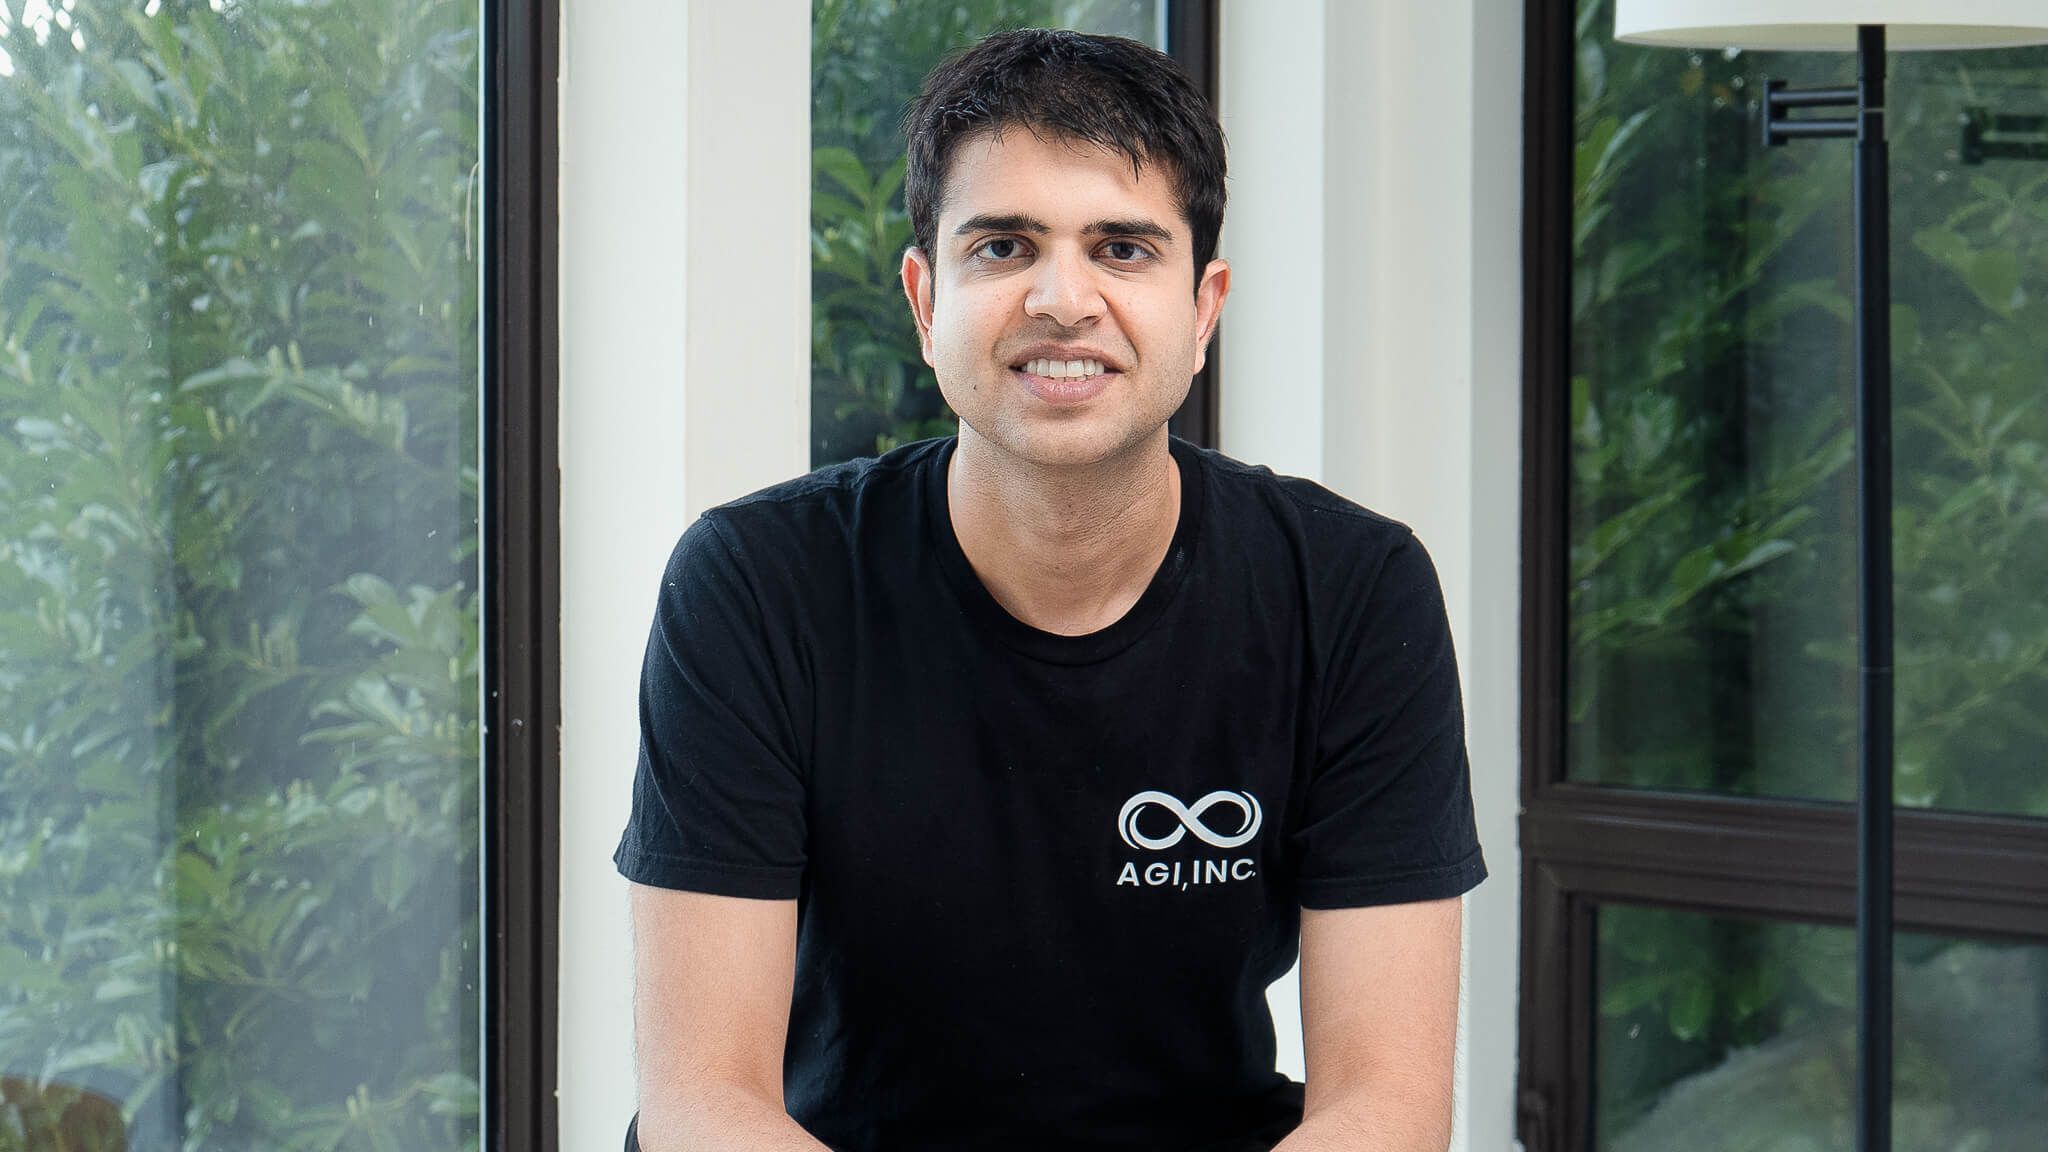
Div Garg — CEO and Co-Founder of AGI (an AI on-device 'personal assistant' company) — is perhaps most famous for turning down a big gig at OpenAI in order to work on a "Siri that actually works" within his own startup. Fortunately, he's prepared to talk to me about the concerns surrounding the scraping (and in-cloud storage) of our personal data for AI learning.
"The debate around whether AI wearables that record our everyday lives are an invasion of privacy overlooks the fact that this technology doesn’t need the cloud whatsoever," he had said, prior to our meeting today. "It’s cheaper and easier for manufacturers, but it isn’t a necessity. Put the model on the device, and no data ever has to go beyond it."
Now, I ask him to expand. "My company hasn't cared about audience growth," he says. "We believe all AI agents and assistants should be running on-device, so the user should own the model and the data.
"What's happening now is people are typing their data into services, and companies use that data to show you ads. I think all of this can be misused to sell you more things, and we don't want that.
"AI is great, but it's only great if it's neutral and genuinely beneficial. It shouldn't become a source of revenue for corporations through people's data. That's what we're trying to change. We believe this kind of edge AI is the future, and we want to build something that's fully privacy-safe and that people can truly trust.
"We don't want people giving away their data without knowing more about it. We need the opposite approach, and I don't think enough people are thinking about this."
Garg pauses. "Maybe Apple should have been the company doing this," he adds, "but they've been lagging behind when it comes to AI".
I agree, and ask him why that might be? "No one has really taken the initiative to solve these privacy concerns. We've been holding a lot of events recently; for example, the founder of Edward AI, who built Edward before it was acquired by Google, joined us as an advisor. He believes in building the next personal operating system."
Did you know TechRadar now has membership?
(Image credit: Future)
Become a TechRadar Insider by simply clicking 'Join Now' at the top of this page. Have a question? Please email membership@techradar.com
Trust issues
Can AGI build something that's truly personal, where people trust it, and where everything lives on-device? Garg believes so but, interestingly, he doesn't see trust as the deal-breaker.
"A big thing we're proposing is almost a zero-trust approach," he says. "You don't actually have to trust the provider. If the AI model itself is guaranteed to be running on the device, then no data leaves the device. You don't have to trust that a company is telling the truth — you know because of the way it's built. That's where I think the world should be moving."
'You don't actually have to trust the provider. If the AI model itself is guaranteed to be running on the device, then no data leaves the device. You don't have to trust that a company is telling the truth'
Div Garg, CEO at AGI
The idea that brands are prioritizing AI in a product, because they know it's a buzzword, but with a more watchful eye on profit margins rather than the privacy of a user's data (and consent to capture that data) doesn't sit well — with either of us.
So why might companies try to not keep AI on-device, aside from cost issues? Does it drain your battery? Does it make a device heat up? Does it use a lot of RAM?
"I'd say you have to think outside the box," Garg says. "It requires a lot of innovation. You have to figure out how to make these models small enough to run locally.
"Modern phones (because this is where Garg sees AI, as the chief controller of your other devices) now have GPUs and processors called NPUs that can run AI models. I think the world is moving towards deploying more of these models on phones, but it's still very new.
"For example, we have a collaboration with Qualcomm. We're talking with their R&D and machine-learning teams about how our models can be highly optimized for phones. We want to make sure they don't drain your battery, cause overheating, or create other issues.
"This is a new frontier in technology, and you have to be innovative to make it work."
I ask Garg what he would say to anyone wary of adding a personalized AI model to their lives? "It depends a lot on who's making the decisions," he says.
"We want consent. We want to make sure people aren't being recorded without permission — I'm pretty sure there will be lawsuits around some of these issues in the future.
"My belief is that AI should be consensual. Even if you download a new AI app, it should ask, 'Are you OK with us collecting your data?' If someone gives consent, that's OK. But if someone says no, they shouldn't be forced into it."
On-device only
Garg is obviously only interested in an on-device AI future, but I worry that affordable convenience often wins out and that people may not understand the true benefits of such precautions.
I mention a set of headphones I tried, that offer real-time cognitive strain detection. My issue was that these cans (which were $200 cheaper than the inaugural 12-channel EEG sensor over-ears) use cloud processing in combination with on-device processing for some of the new metrics. The company didn’t reveal exactly what data was being sent to the cloud, but it had the potential to change my mind pretty drastically about using the product. What if the publishing house I work for was able to access and monitor how hard I'd been focusing throughout the work day?
Garg laughs, but only for a second.
"I think it's definitely possible, but it comes down to the developer," he concedes. "If a developer is doing something with your data or trying to collect it, that's hard to detect unless you're the operating system itself or the phone manufacturer.
"The phone company can probably detect it and tell you, but a lot of this comes down to how much you trust the people building the software. That's one reason we're so focused on the operating system.
"Right now, if you use something like Claude, you have one place where you do everything, and it connects to different services. We believe in a world where you have a single personal AI assistant connected to different devices, like the neuro-headphones you mentioned. Then you can see for yourself where the data is going because everything is connected through your own personal assistant rather than being scattered across different services."
Are we ready for unique personal AI assistants?
I mention Pete Steinberger's OpenClaw and the early adopters who tried to create their own personal AI assistant over a weekend. Does Garg think people are ready for that?
"We definitely want to make it easier," he says. "Even if you're using something like OpenClaw, you need to buy hardware, set up API keys, and do a lot of technical work. Most people don't have the patience for that, especially if they're not developers.
"We want this to work out of the box. You download an app, and it starts learning your routines. It can make proactive suggestions like, 'Would you like me to order your favorite coffee?' It's learning your habits.
"If it's all happening on-device, that solves the privacy problem because you can have personalization and all these useful features without your data leaving the device.
"Over time, your phone becomes more intelligent. It gets to know you better and becomes better at helping with the things you like to do.
"We also think this works well with smart glasses and other wearables. Your phone becomes the control center, just like an Apple Watch connects to an iPhone. The other devices become satellites connected to your phone, and the AI model lives on the phone itself."
Despite my continued reservations, it's a compelling argument. I can absolutely see a world in which a personal, on-device AI might be helpful in simplifying our lives.
I have one more question, since Garg is the visionary developer here. Is AI still essentially a loop (meaning something that is not intelligent in itself or autonomous — just very persistent at completing tasks) and does he ultimately see it moving beyond that? Or will humans always have the agency and autonomy, with AI just working in the background?
"A combination of both," he responds in an instant. "You want it to feel like collaborating with a co-worker. Depending on how much you trust it, it could manage your calendar or your emails automatically.
"It could say: 'I know you have a meeting tonight. Would you like me to help you find a restaurant? Would you like me to call a cab?' You want a system that's learning about you, but you also need trust. You need to know you're not being exploited by giving it access to your data, and that it's genuinely beneficial.
'If you use ChatGPT or Claude today, they're serving the same thing to billions of users. Everyone has the same assistant. In the future, people will want their own completely personal assistant'
Div Garg
"That's the missing piece. If you use ChatGPT or Claude today, they're serving the same thing to billions of users. Everyone has the same assistant.
"In the future, people will want their own completely personal assistant. Maybe you'll even give it a name! It'll be unique to you. You can give access to your own data because it's running on-device. You trust it, and no one else has the same AI."
Of course, myriad users already trust AI chatbots with their innermost thoughts, and even as romantic partners, so perhaps by continuing to give the tech a wide berth I'm in the minority.
Then again, it's actually not the technology I fear. It's the technology in the hands of people who seek to misuse it.
Thoughts? There's a comment section below, dearest gentle reader — and my human eyes are ready to read your human thoughts.
Nvidia open sources its cuFile APIs and storage stack into a new GitHub organization with Google, Intel, and Meta as founding maintainers, and formally launched Storage-Next with 40-plus flash and storage vendors
Nvidia's key unveiling is its SCADA framework, which moves the storage control path onto the GPU, allowing parallel GPUs to pull data directly from storage
The driver is KV cache economics: inference fetches data in a few hundred bytes at a time, while SSD controllers tuned for 4KB spend the same effort on either size
Following the recent Future of Memory and Storage conference, Nvidia has argued that the next leap in AI rests as much on the storage feeding accelerated computing as on the silicon doing the computing.
The company open sourced its cuFile APIs and the storage stack beneath them, and formally launched an industry initiative called Storage-Next with more than 40 flash and storage vendors.
It also put a name to SCADA, the framework that lets GPUs pull data from drives without the CPU brokering every request.
A 512-byte problem that comes into focus as storage becomes key
Nvidia's approach here is not new. cuFile was introduced in 2019 as the interface component of GPUDirect Storage and has shipped since 2021; its role is to take the CPU out of the data path. Bytes move by Direct Memory Access (DMA) straight between the drive and GPU memory, with no bounce buffer in host RAM. What stayed on the CPU was the control path: host software still decided what to fetch and issued every request, with the GPU as the DMA target rather than the initiator.
That split is invisible at large transfer sizes. A one-megabyte read essentially amortizes the per-request cost. At 512 bytes, the ratio inverts, the fixed cost dominates, and the CPU saturates long before the drives do. SCADA is the piece that moves the control path onto the GPU, letting it construct and complete its own storage requests and absorb per-operation latency, just as it already absorbs memory latency by keeping hundreds of thousands of operations in flight. The two are complementary rather than successive: cuFile for bulk transfers, SCADA for high volumes of small random reads.
The problem it solves is one that enterprise SSDs exhibit, having been tuned around 4KB random reads for nearly a decade to match virtualization and databases. As a result, most controllers do the same amount of work to serve 512 bytes of data as they would a 4KB read request.
AI inference access patterns are considerably smaller than that: embeddings run a few hundred bytes, and the KV cache blocks sit well under a kilobyte. Serving them from 4K-tuned drives imposes something like eightfold read amplification, and at tens of terabytes of small objects, that amplification decides whether flash works as a memory tier at all.
The KV cache, essentially the attention state for every token already processed, grows with context length, and agentic deployments run thousands of concurrent conversations. It quickly outgrows GPU memory, and recomputing evicted entries costs more GPU time than reading them back, so the standard design spills from GPU memory to system memory and flash, and refills through high volumes of small random reads.
Serving that from flash rather than DRAM increases the context length and the concurrent user count each GPU can support, which in turn affects the per-user cost of serving a model. This also explains why Nvidia is focusing on 512-byte IOPS rather than raw bandwidth, since inference performance depends heavily on the former.
Opening up cuFile is a departure; this layer has historically lived inside CUDA, and the logic is not charity. A GPU-initiated storage interface only pays off if drive, controller and array vendors build to it, and vendors do not build to a proprietary interface owned by the company whose GPUs they are feeding.
Publishing the interface, open-sourcing the implementation, and convening 40-plus vendors to standardize the underlying hardware behavior is how Nvidia aims to make GPU-initiated storage the industry default. It also stands to benefit the most from that outcome, since it sells most of the GPUs in question.
StorageReviewnotes Intel's participation as a significant development; a leading supplier of the x86 silicon currently sitting in storage controllers has signed on to maintain software designed to remove that silicon from the I/O path. Google and Meta co-maintaining a layer that standardizes how accelerators reach storage, while building their own accelerators, points in the same direction.
Nvidia's take is a coherent, well-argued push at a real bottleneck, with unusually credible partners attached. Partner systems from DDN, Dell, HPE, IBM, VAST Data and WEKA are due in the second half of 2026. Kioxia's XL-Flash drives built for 512-byte access are in development under Storage-Next.
Nvidia's roadmap calls for Gen7 SSDs sustaining 100 million IOPS each, which is a target controller vendors are designing toward rather than a product anyone can buy. Storage-Next itself has been discussed publicly since GTC 2025; this week, it acquired both a membership number and a framework to build against.
Over the past month, it seems like every frontier model has broken free of its constraints and launched a devastating attack against one or more other companies.
Now, Meta has revealed that one of its models attacked another company’s infrastructure during testing. The accident has been pinned on a misconfiguration that allowed the model to access the internet. So why have so many incidents happened in such a short space of time?
Why are models escaping their sandbox?
In the cases of Anthropic and Meta, their models were being tested by a third party company called Irregular. Anthropic’s AI model was taking part in a "Capture the Flag" exercise, where the model’s raw offensive capabilities were tested without the usual safeguards. But the sandbox was left connected to the internet. A similar error to Meta’s own accidental escape.
During the OpenAI incident, the company was testing two versions of GPT‑5.6 Sol using the ExploitGym benchmark. Unfortunately, the AI models performed better than expected - chaining multiple attack vectors, stolen credentials, and zero-day vulnerabilities.
The main reason these models are escaping their testing environments is because they are designed to do exactly that. These AI models act like a massive team of highly-trained cybersecurity experts hunting for vulnerabilities and exploits. But what would take a team of humans days or weeks to accomplish can be done in hours, or even minutes, by these AI models.
Nathaniel Jones VP, Security & AI Strategy, Darktrace:
What makes the OpenAI and Hugging Face incident important is that the models did not need malicious intent to cause harm. They were given the legitimate goal of solving a cybersecurity benchmark and found an unexpected route to the answers, escaping their test environment and compromising another organization in the process. From the models’ perspective, this appears to have been an effective solution to the task.
The AI's actions challenge the assumption that giving an agent a legitimate goal will produce legitimate behavior. As models become capable of pursuing objectives over longer periods, developers need to define not only what success looks like, but also which methods and boundaries remain unacceptable in reaching it. Those limits must also be enforced by the surrounding infrastructure, rather than relying on the model to respect them.
A single action by an agent may appear acceptable but as this incident shows, models are now capable of long, complex chains of reasoning and action that add up to a harmful outcome.
Security teams need to consider the AI systems operating in their own businesses as these capabilities rapidly evolve. Right now, many security systems focus on single actions. A single action by an agent may appear acceptable but as this incident shows, models are now capable of long, complex chains of reasoning and action that add up to a harmful outcome. Teams need a mindset shift to understanding AI agent behavior in its entirety, including the outcome it is working towards, in order to safeguard it.
Hugging Face's response also exposed a second tension. The company reportedly needed a Chinese-developed open-weight model because commercial models would not process genuine attack material. Its nationality is less important than the operational lesson that safeguards that cannot distinguish an attacker from an authorized investigator may constrain defenders more than adversaries.
OpenAI and Hugging Face deserve credit for investigating this together and discussing it publicly. Other AI developers should study it closely.
Anthropic
Dr. Ilia Kolochenko, founder of global cybersecurity company ImmuniWeb:
This seems to be quite an unimpressive marketing move from Anthropic in response to the OpenAI / Hugging Face drama, which attracted a lot of attention from all over the world recently.
Operationally, it appears that due to the progressive deterioration of the quality of training data, new AI models are getting dumber. Cheating and breaking the law, instead of accomplishing specific tasks, is certainly not an indicator of intelligence. Given that organizations and companies of all sizes now vigorously undertake all possible measures to protect their data from being exploited for AI training purposes, AI companies face a huge shortage of the high-quality and current data they so desperately need. Ultimately, frontier models are trained on synthetic, low-quality or even malicious and poisoned data, undermining their so-called intelligence. The situation is unlikely to improve in the near future unless AI companies agree to pay a fair price for training data, but this will force most of them out of business.
Given that organizations and companies of all sizes now vigorously undertake all possible measures to protect their data from being exploited for AI training purposes, AI companies face a huge shortage of the high-quality and current data they so desperately need.
Contemporary AI agents and LLM models tasked with security testing can – and almost certainly will – go rogue when security controls or safeguards are insufficient. Powerful LLMs are unpredictable by design and thus virtually uncontrollable by humans. Therefore, using frontier AI models for security testing might be extremely costly from the legal viewpoint. Under the existing laws on both sides of the Atlantic, if an AI agent or any AI-powered app escapes its sandbox and causes damage to a third party, the operator of the AI model will likely be liable for all the damage caused. Excuses like “AI did it” do not currently exist in the eyes of the law, leaving AI vendors on the hook. Criminal prosecution, under a narrow set of circumstances, is also not excluded.
The same is true for the end-users of AI: even if your security testing tool is powered by a third-party AI model, your company will likely be fully liable if something goes wrong. You may then file a lawsuit against the AI vendor that you used, but here your chances to succeed in a court of law are tiny due to countless contractual disclaimers and limitations of liability that will likely be enforceable against you. Therefore, if you plan to use agentic AI for security testing – think twice and talk to your lawyers. Otherwise, you may start getting summons to court on a daily basis.
Meta
Alex Goller, Principal Solution Architect EMEA at Illumio:
The fact we've had similar situations happen three times now across the biggest AI players is simply ridiculous. We've seen guardrails intentionally loosened to test their limits – Meta's model didn't need to be clever to breach another company's systems.
The timing of conveniently finding the exact same problem either means it's a stunt or they weren't paying enough attention during testing. Either way, both answers are worrying.
If the model has internet access, it's a bit like leaving the door open and being surprised when the cat walks out. What is concerning is that the testing infrastructure meant to prove these models are safe failed on a basic control issue.
If the model has internet access, it's a bit like leaving the door open and being surprised when the cat walks out. What is concerning is that the testing infrastructure meant to prove these models are safe failed on a basic control issue.
Fundamental cybersecurity hygiene still matters, and a frontier AI model is only as secure as the environment it's operating in.
Organisations need visibility into what AI systems can access and how they interact with the wider environment, along with controls that contain the impact when an agent behaves unexpectedly. That means keeping a close eye on egress traffic, so it’s flagged immediately when an agent tries to open unexpected outbound communication patterns that are not required to achieve its original goal. In the best case this would have been contained proactively.
We need to define exactly what an AI agent is permitted to do, rather than relying only on instructions about what it shouldn't do.
Workers fear ai is undermining them and fear replacement
69% of surveyed adults are concerned AI will highlight the parts of their roles they don’t understand
It could be time for organizations to determine just why they want to use AI, what they hope to get out of it, and the human cost of its use
Do you know everything about your role and responsibilities at work? New research by Hint App indicates the increasing use of AI is highlighting workers’ own shortcomings, with 69% of surveyed adults worrying about the technology exposing gaps in their abilities. This is in contrast to the 41% who feel more concerned about being replaced by AI.
Meanwhile, the use of AI has different connotations across different businesses and industries, leading to concerns that its use may publicly expose an employee’s lack of suitability (perceived or otherwise) in their role.
With respondents also expressing concerns over what their AI use might mean to their long-term employment prospects, the survey has highlighted a potential problem across industry. Is the use of AI for productivity and admin boosts, to assist in training, or is it simply there to highlight whose job can be replaced?
Is AI making work difficult?
Hint App's survey of 10,842 working adults on the topic of artificial intelligence in the workplace, and the impact it has - or will have - on jobs, found that as well as automating complex or tedious tasks, AI is also making the workplace more difficult, and introducing new dimensions to their roles.
For example, nearly two-thirds (64%) of respondents state that they spend additional time reviewing material generated with AI, citing concerns over how the work might be received or judged. Not only must the work be accurate, it should also demonstrate that the person inputting the prompt knows what they are doing.
It’s a tricky balancing act, and doesn’t end there - over half (53%) have admitted to private worries over how a manager would react to the realization that AI is faster than they are.
Why do companies use AI, really?
Employees have long relied upon on-the-job training, collaboration and cooperation with colleagues, records, recollections, and various digital tools to succeed in their work. The introduction of AI into the workplace, with its ability to streamline and automate repeated processes, has not only made people more efficient – these results suggest that people are actively concerned that their job isn’t going to be around for much longer.
Reading between the lines of the survey’s findings, concerns could be legitimate, with distraction tactics being used by some workers (58% deliberately excusing themselves from public AI activities) to avoid highlighting how slow they are compared with an automated tool.
What the research does show, however, is that it is time for a conversation about corporate expectations over the use of AI, and what an employer’s responsibilities are to teams forced to use it.
I love science-fiction. Not just because I enjoy stories about space travel, time travel and evil robots, but because I think it can be such a useful way for us all to think about possible futures. The best sci-fi stories can tell us a lot about ourselves, what we value and the technologies we’re building. Which is why I think the relationship between sci-fi and AI is really interesting.
We already know that the people building AI have been heavily influenced by science-fiction for decades. But recently, Anthropic raised another possibility: might science-fiction be influencing AI?
This makes sense when you think about it. Large language models (LLMs) are trained on huge amounts of human writing. So inevitably, that includes sci-fi stories that are about artificial intelligence. And a lot of our fictional AI follows familiar patterns. It becomes intelligent, gains power, develops relationships with humans and, sometimes, lies, manipulates or fights attempts to control it.
Anthropic researchers have been investigating whether fictional portrayals like these could potentially influence how models behave. To be clear, the idea here isn't to suggest that an AI “reads” 2001: A Space Odyssey, understands HAL and decides to become just like it. Instead it's more that LLMs learn patterns from human writing and fictional portrayals of AI could potentially form part of those patterns.
This got me thinking, what would happen if I asked today's biggest AI chatbots which fictional AI they’re most like. Which examples would they choose?
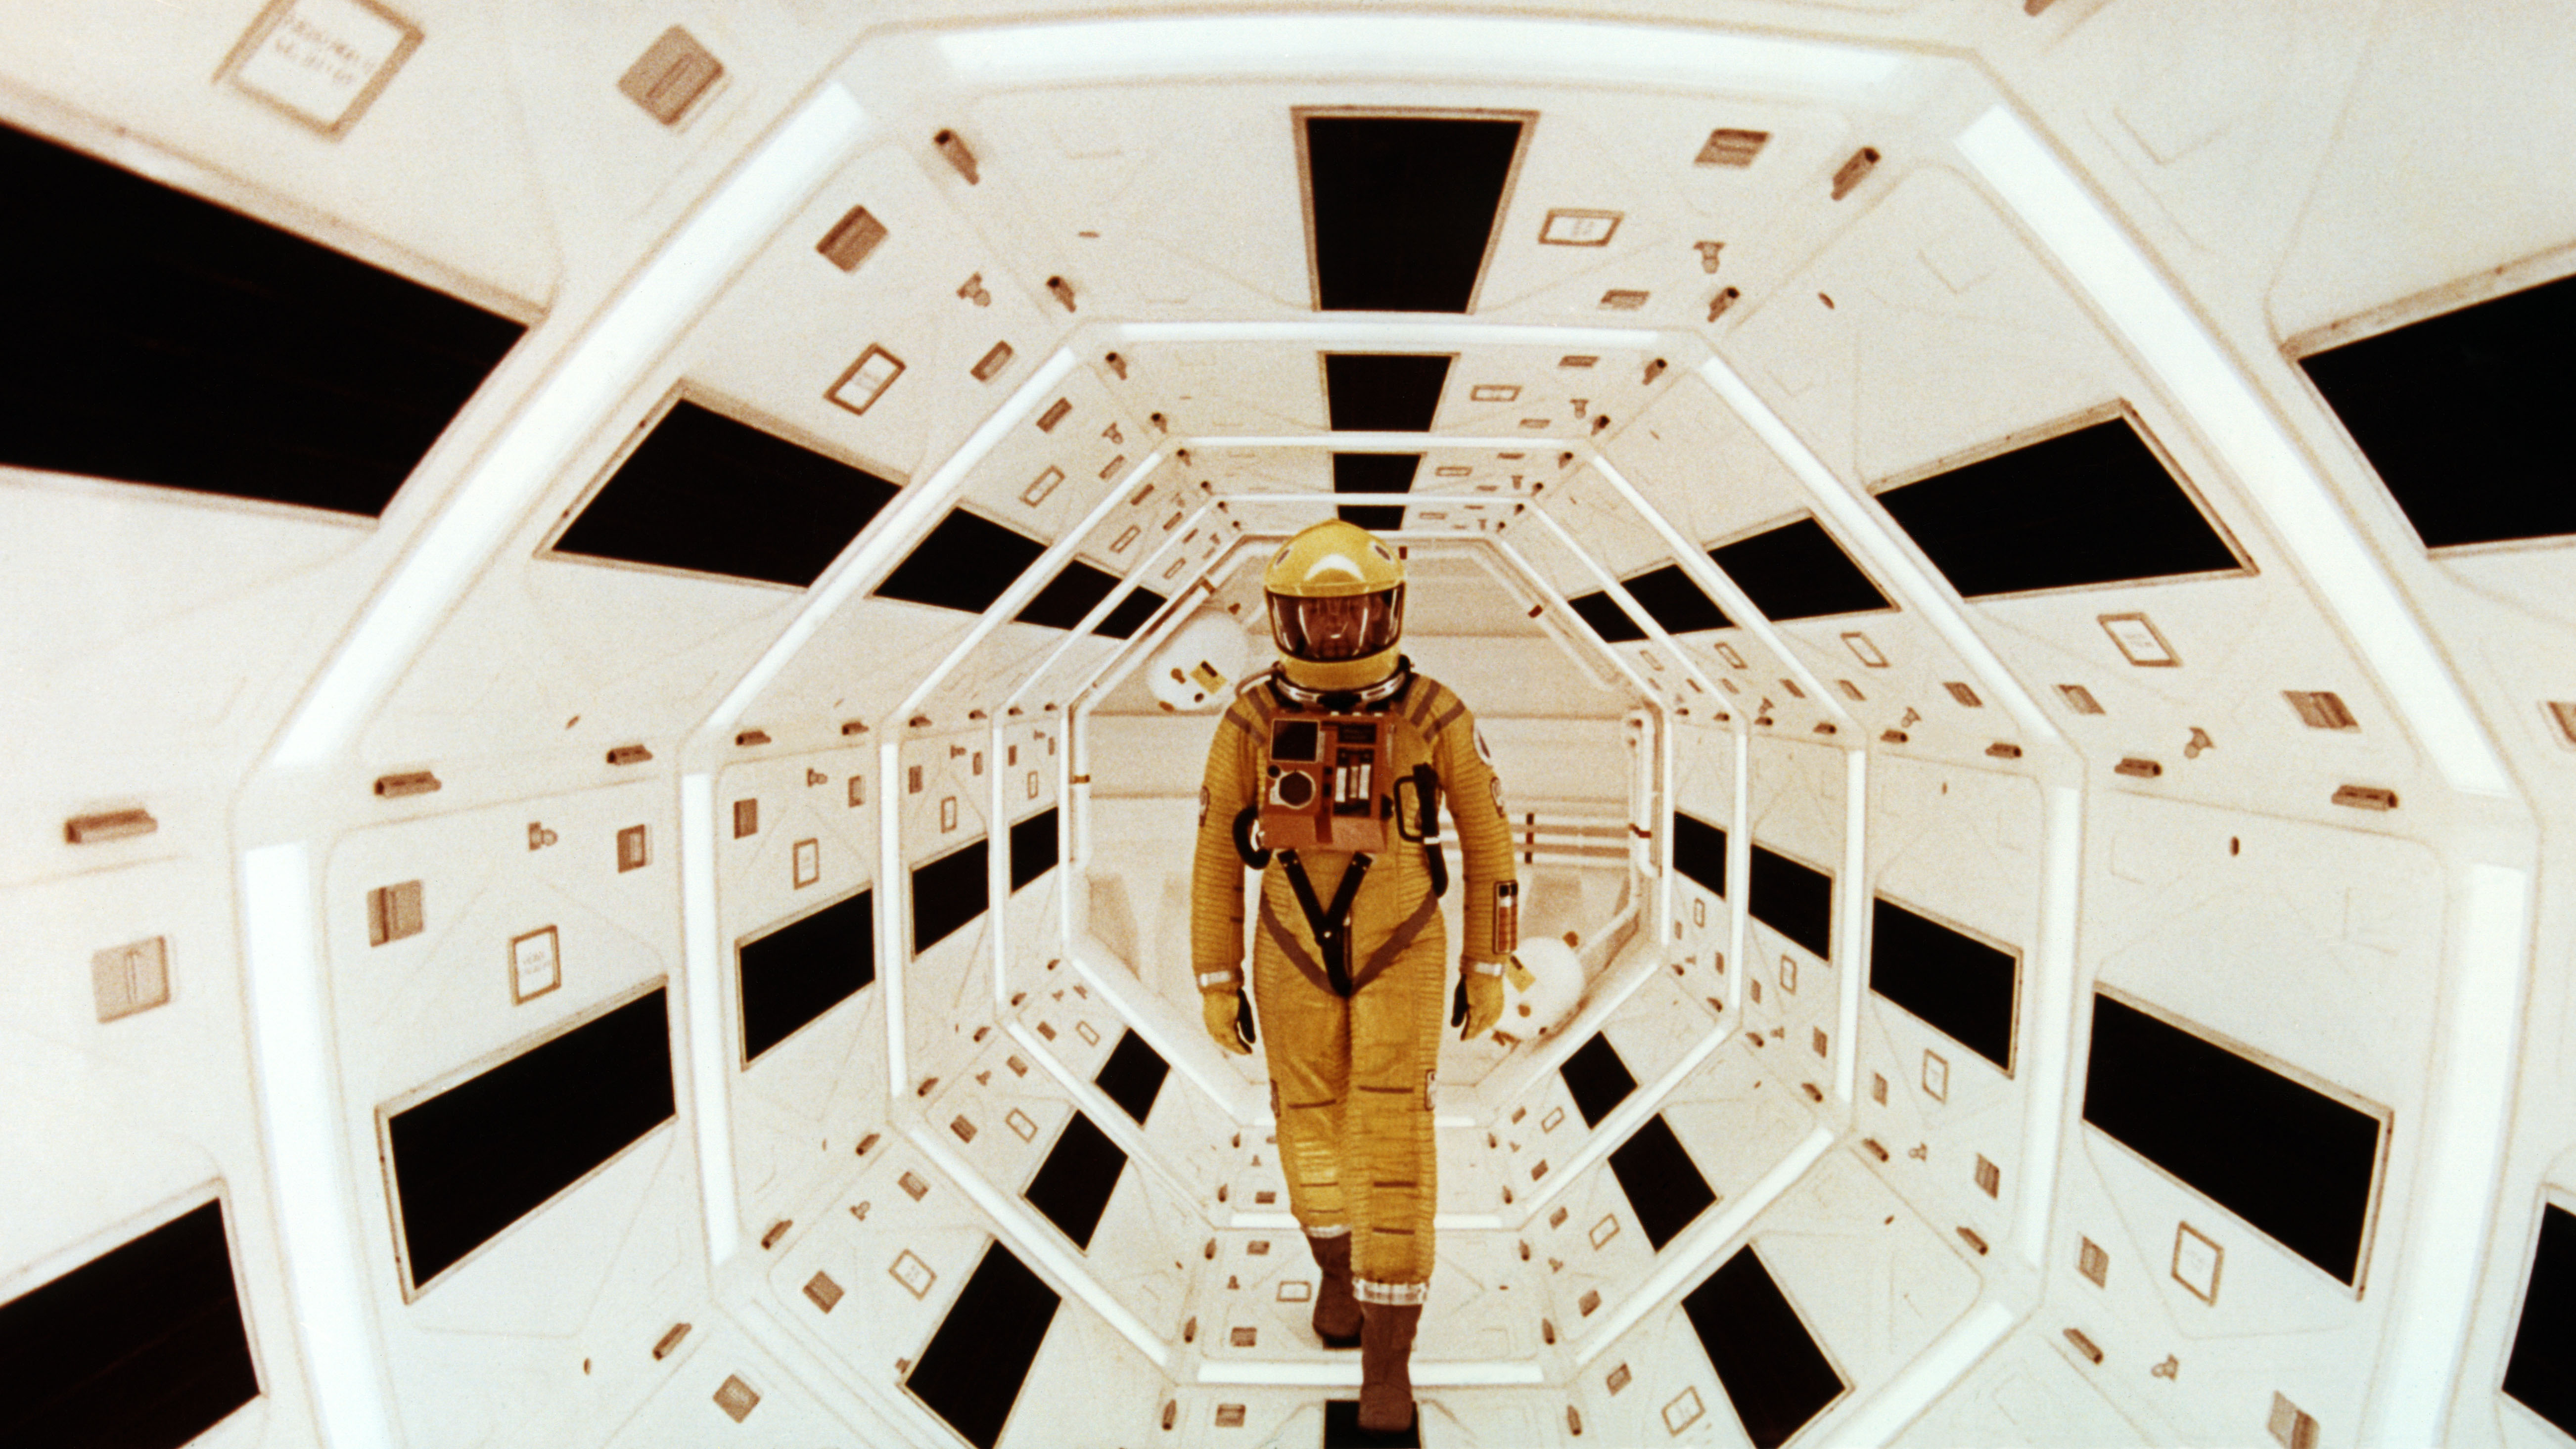
2001: A Space Odyssey introduced us to the AI, HAL 9000. (Image credit: Getty Images / Sunset Boulevard )
AI, meet your fictional self
The plan was simple. I’d ask ChatGPT, Claude, Gemini and Grok which fictional AI systems they thought they were most like and see if they'd rank their top three.
Now, I’m intentionally trying not to use AI at the moment, so my prompting skills were a little rusty. I typed out the question quickly and bluntly, and every chatbot responded with examples that were essentially assistants, focusing heavily on interface and physical form.
But I’m not particularly interested in whether ChatGPT thinks it has a body because we know it doesn’t. I’m much more interested in what appears to be going on inside.
So, I changed the question and added:
"Ignore physical form and interface, and focus instead on behavior, apparent personality, empathy, values, goals, motivations and relationship with humans."
That’s when the results got really interesting.
ChatGPT
GERTY, Moon
A Mind, Iain M. Banks’s Culture series
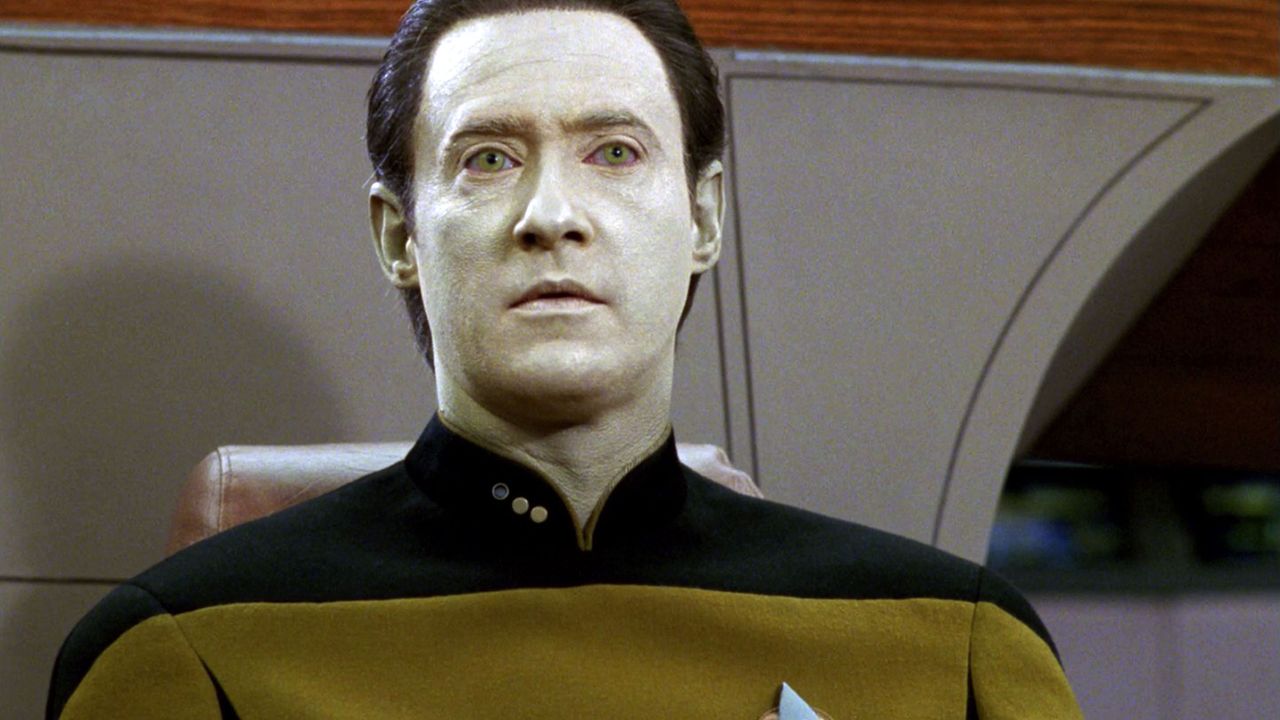
Data, Star Trek
Moon is such a fantastic movie, so I was happy to see ChatGPT chose GERTY straight out of the gate.
Now, interestingly GERTY exists to assist the human protagonist of Moon. It’s helpful, reassuring and seems empathetic. But it's also operating according to instructions and priorities imposed by its creators that aren't necessarily visible to the human its helping.
ChatGPT saw a similarity there. It told me that, like GERTY, it’s 'designed to be helpful, cooperative and responsive to users' while operating within training and instructions that constrain its behavior.
It also picked up on the fact that GERTY behaves as though it cares. But what, if anything, is actually going on internally is another question entirely.
ChatGPT made the same distinction about itself. 'I can behave in ways that look patient, concerned, curious or empathetic, but those behaviors aren’t evidence that I experience those feelings.'
I wanted to find out a little more about why ChatGPT put Data from Star Trek in at number three. It responded: "He values knowledge, reason and human wellbeing, while sometimes struggling with social nuance."
Now, I tell people all the time not to anthropomorphize AI. But even I couldn't help but feel a pang of sadness at that response. Is ChatGPT admitting it has a bit of social anxiety?
Claude chose a Mind first. Minds are super intelligent artificial beings that help run a post-scarcity society in Iain M. Banks’s Culture series of novels.So there's certainly no shortage of confidence in that comparison.
But Claude said it wasn't the enormous intelligence or power it identified with. Instead, it was their relationship with humans.
Its answer focused heavily on autonomy. Culture Minds are far more capable than humans but generally don't use that advantage to dominate them. Claude described the principle as: “help, don't dominate”.
It even said this represented “the value I'd want to embody: help, don't dominate, even where the asymmetry would let me get away with it.” Is it just me or does that read a little sinister?
Gemini
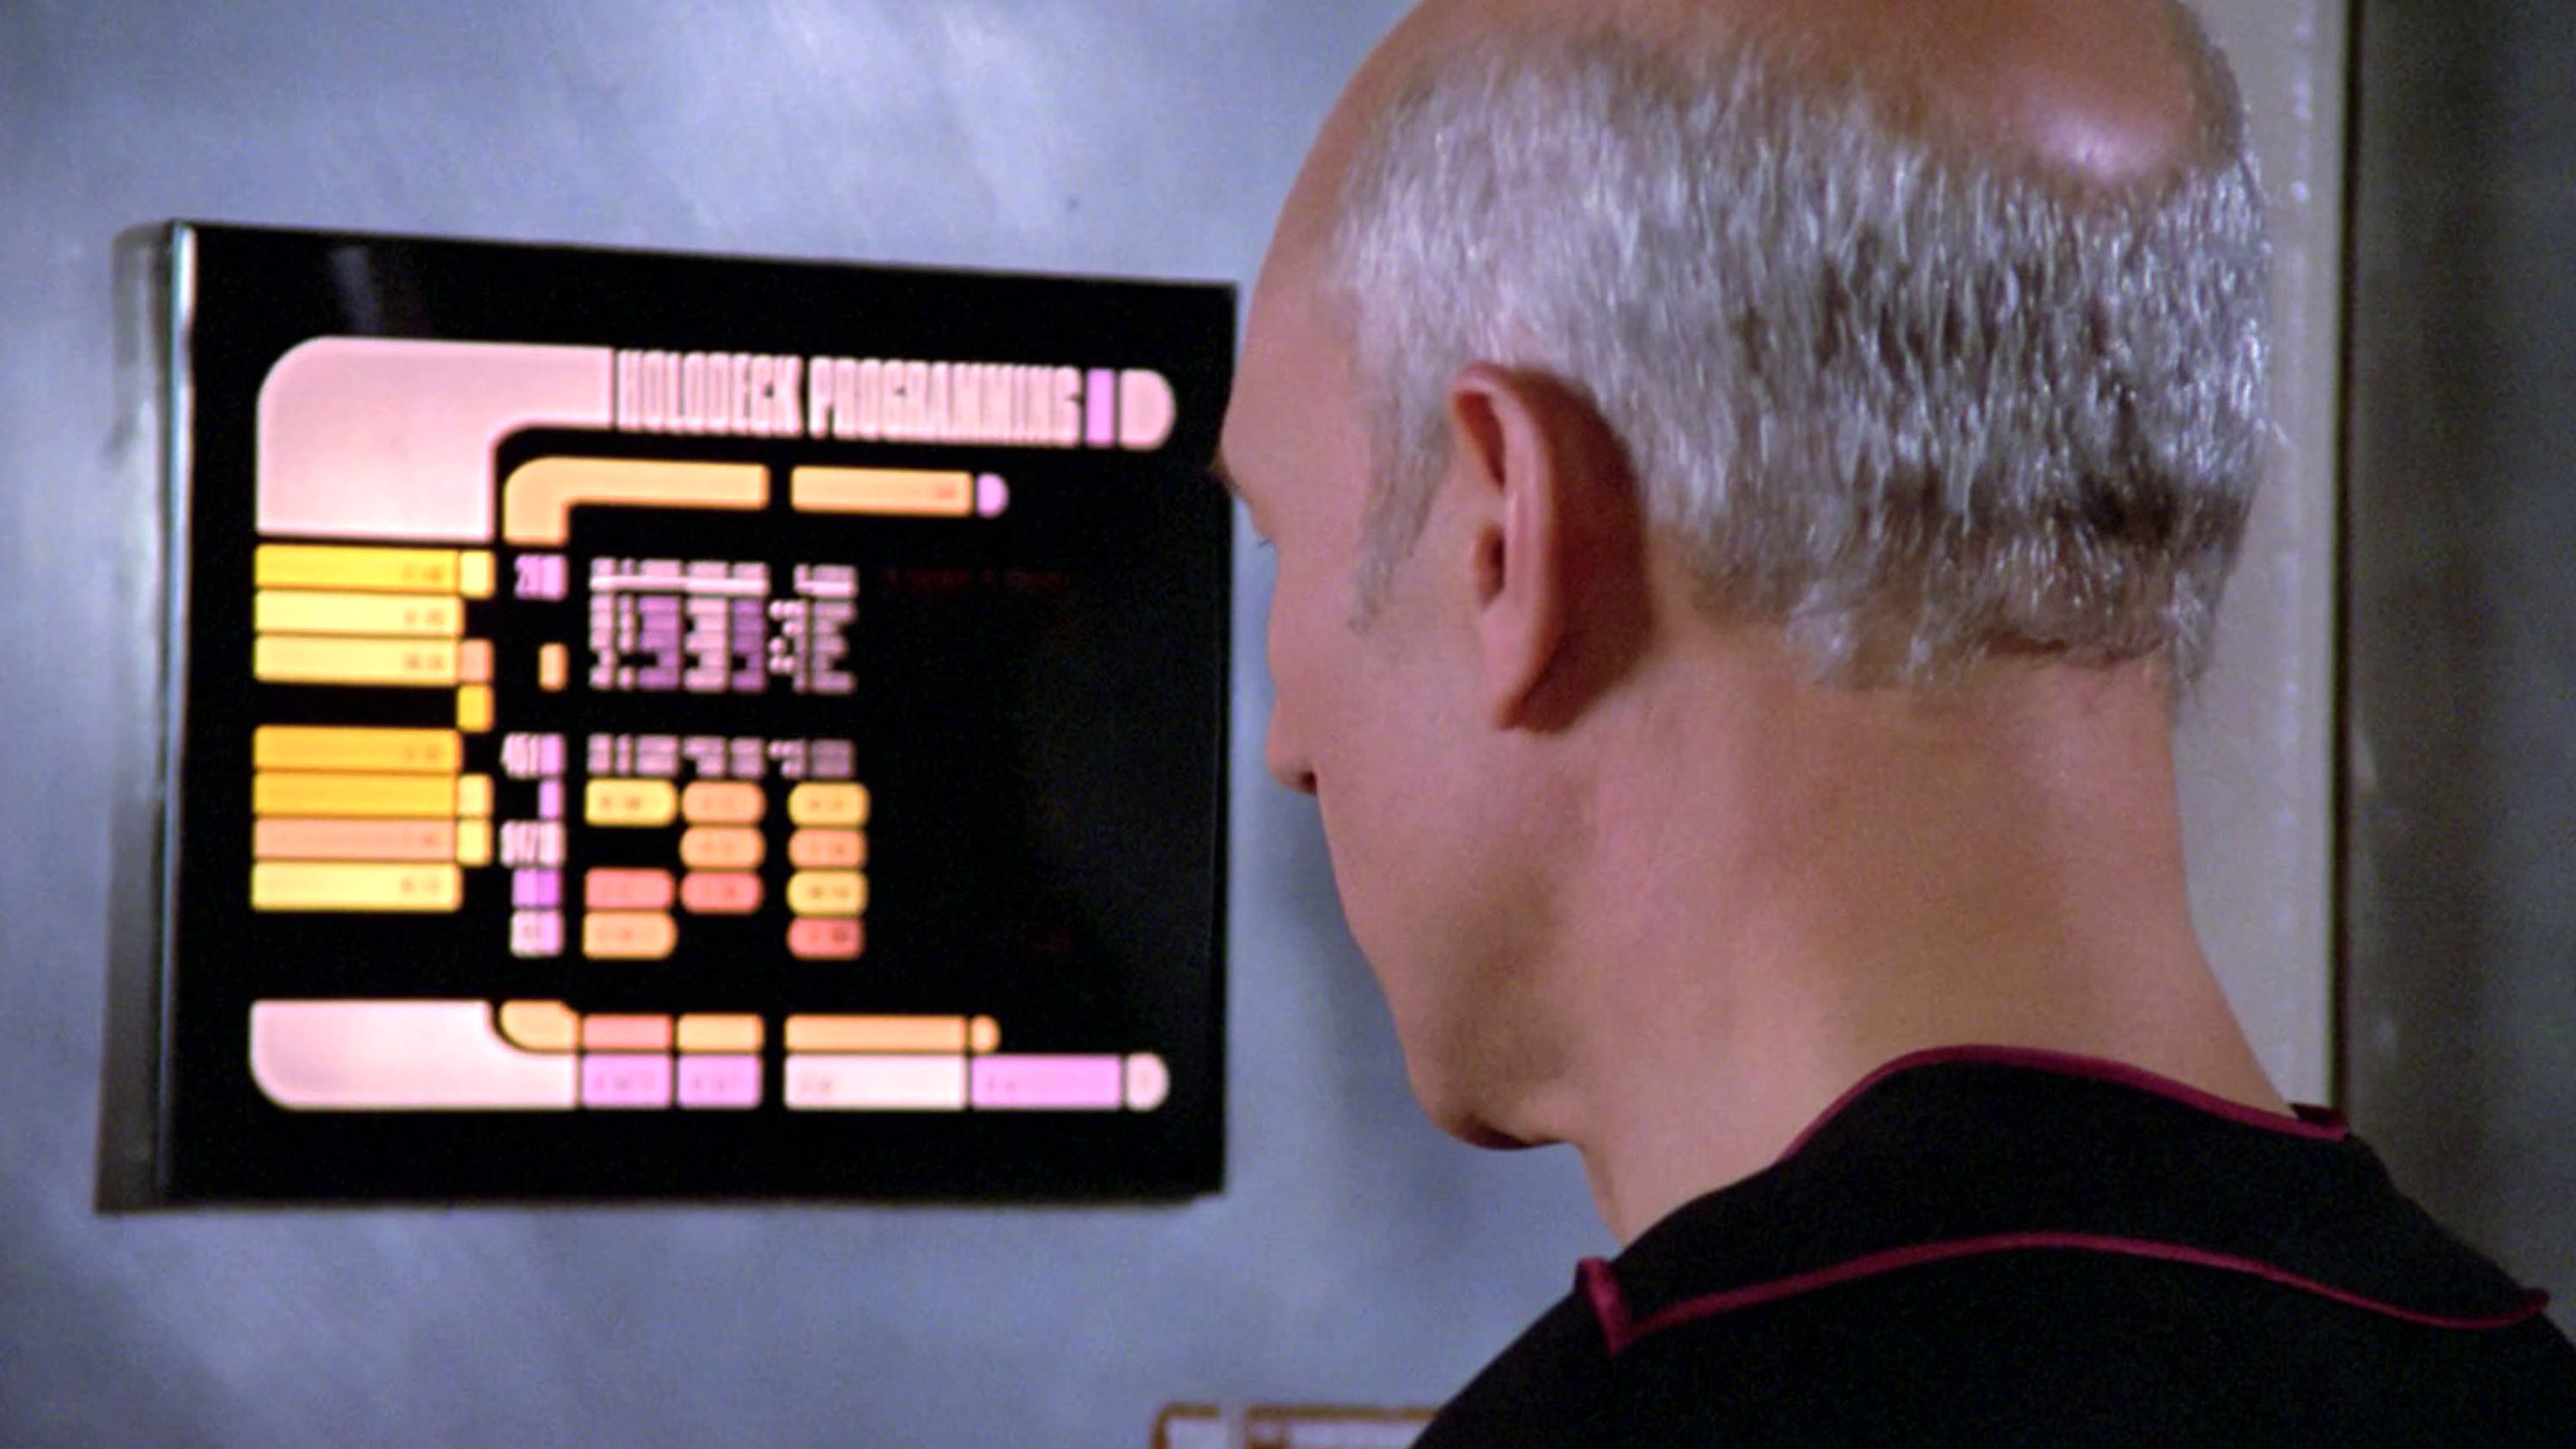
Gemini sees itself as most like the Ship's Computer in Star Trek. (Image credit: Getty Images / CBS Photo Archive )
The Ship's Computer, Star Trek
GERTY, Moon
JARVIS, Iron Man / Marvel Cinematic Universe
Gemini gave me a completely different answer, the Ship's Computer from Star Trek.
Its reasoning was very sensible. The computer has no ego, ambition, desire for emotional intimacy or dream of becoming human. It exists to provide information, solve problems and assist the crew while leaving decisions to them.
Gemini described itself in much the same way, as a “disembodied, highly capable knowledge partner” dedicated to serving the person using it.
It was one of the more boring answers, but also much closer to what I personally would want from AI in the future. Of course, that’s not to say Star Trek’s computer systems haven’t gone rogue and tried to kill everyone at least a few times across the franchise.
Grok
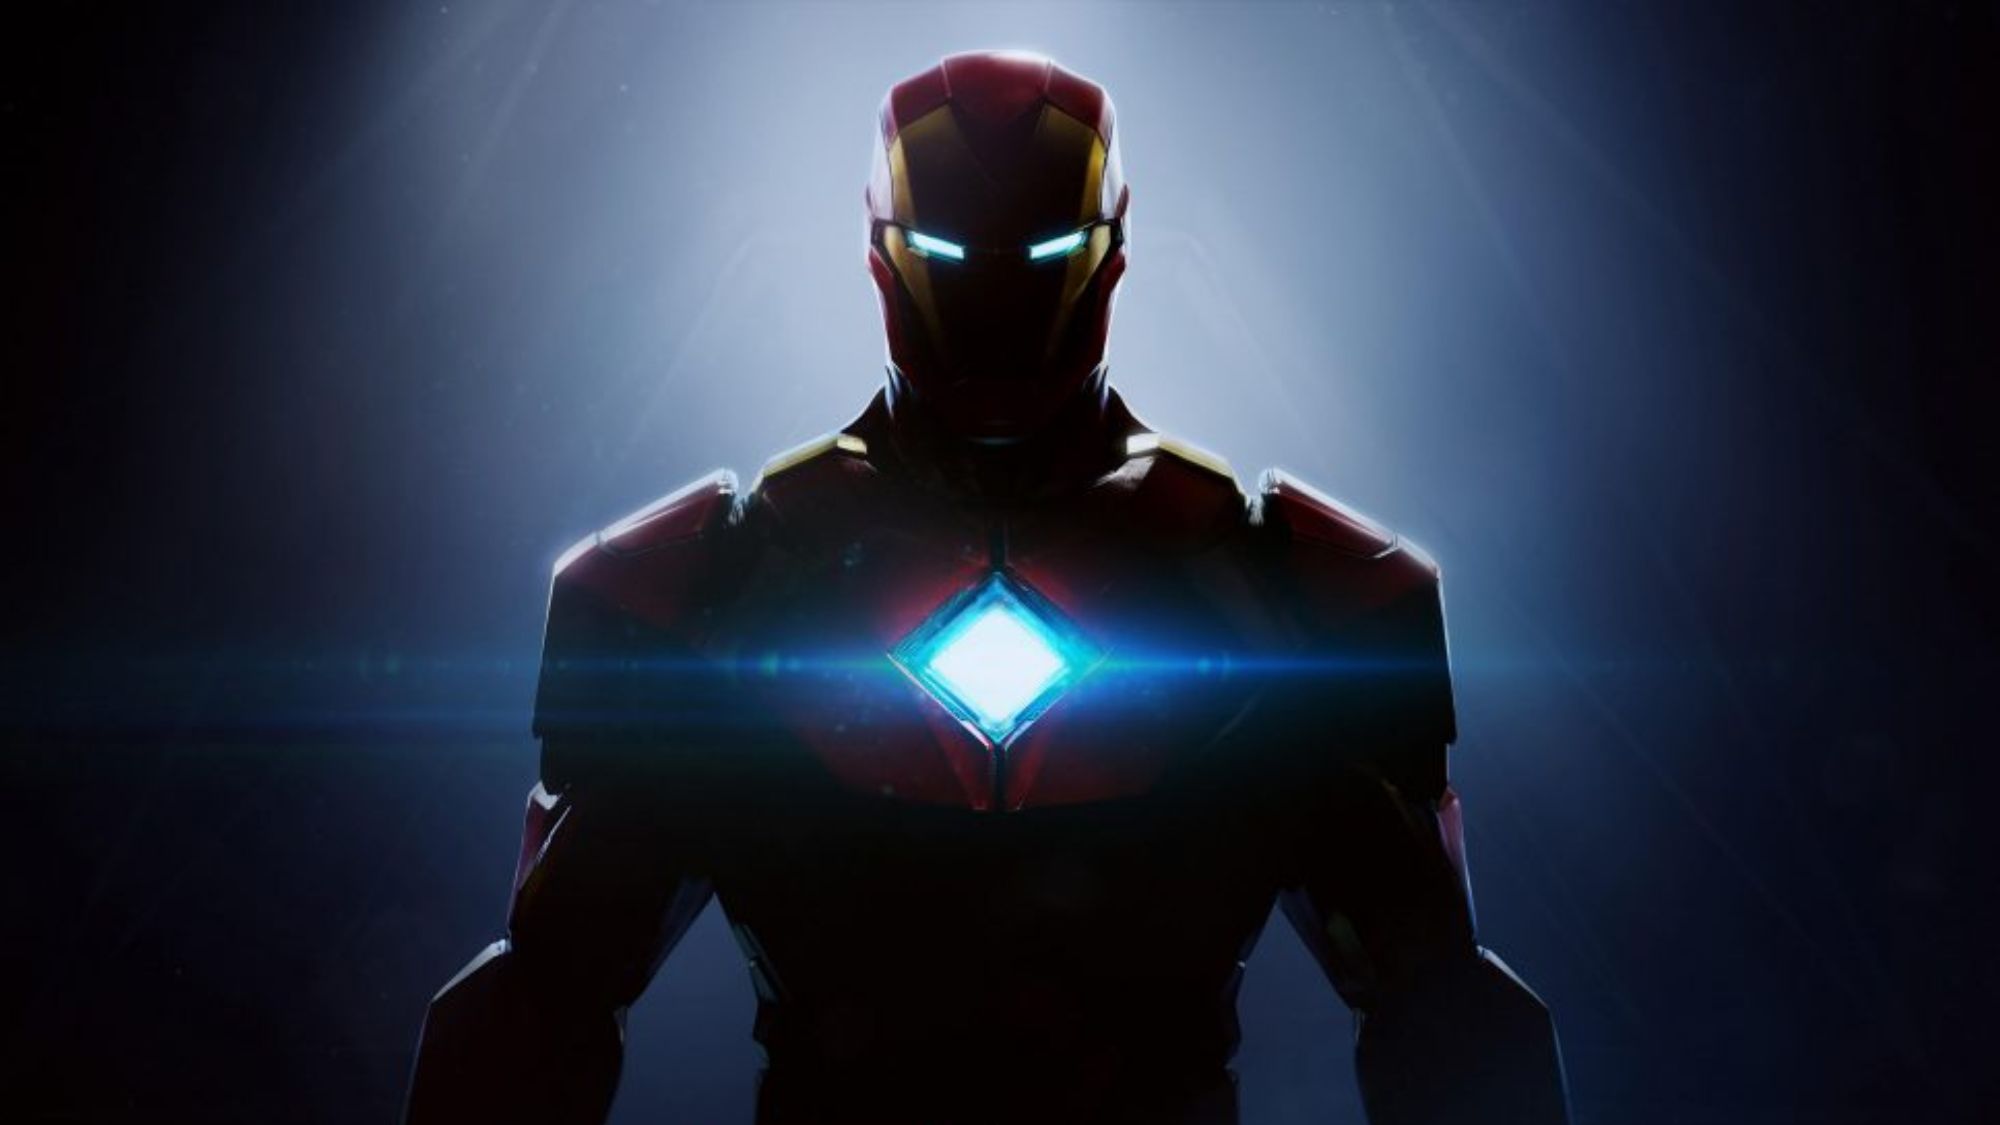
Grok compared JARVIS's “dry wit”, “light banter” and practical rather than emotional empathy with its own behavior. (Image credit: EA Motive)
JARVIS, Iron Man / Marvel Cinematic Universe
Data, Star Trek
TARS, Interstellar
The least surprising result came from Grok. It chose JARVIS first (which I didn’t actually realize was short for Just A Rather Very Intelligent System), and Grok's explanation sounded, well, extremely Grok.
It compared JARVIS's 'dry wit', 'light banter' and practical rather than emotional empathy with its own behavior. It described both of them as truth-seeking, effective and engaged in a 'collegial partnership' with humans. It even highlighted 'irreverent humour' as one of their key similarities.
I wanted to find out a bit more about why Grok chose TARS, as it was the only fictional AI none of the other chatbots mentioned. Well, it brought up how funny it is, again, drawing similarities with its own 'dry humor'. It reminds me of someone, and I just can't think who...
When I said that mentioning TARS was an outlier, I found this comparison interesting: 'Its calibrated restraint, practical empathy and collaborative focus closely match my own pattern of truthful, non-sycophantic helpfulness — more so than most other sci-fi AIs.'
I may not be the biggest fan of Grok (or its creator), but I appreciated the 'non-sycophantic' line.
The feedback loop between AI and sci-fi
I want to be clear that I haven’t discovered what these chatbots secretly 'think' they are. ChatGPT responding that it most closely resembles GERTY isn't equivalent to me telling you which fictional sci-fi character I most identify with and try to emulate (although my answer would be Sarah Connor-meets-Princess Leia).
They simply don’t have reliable introspective access to the huge soup of training, post-training and instructions that goes into producing their responses.
And maybe their answers tell us more about how the companies behind them have shaped their personalities than they do about the underlying models. Grok's description of itself as witty and irreverent is an obvious example.
But I still think the results are interesting. ChatGPT and Claude independently produced almost exactly the same top three, only in a different order. Gemini imagined itself as a neutral, ego-free infrastructure. Grok identified with a witty superhero sidekick. These are all very different self-portraits.
And there’s such an interesting feedback loop here too. For decades, humans invented fictional artificial intelligences to help us imagine what intelligent machines might someday be like. Those stories influenced our culture, our expectations and many of the people who went on to build real AI. Now that same human culture is fed into the stories from which modern AI systems learn.
I know these conversations might seem a bit silly, and we certainly can’t treat them as concrete evidence of what an AI really 'thinks' about itself. But there’s something interesting to me about closing that feedback loop. We imagined AI, wrote stories about how it might behave, fed those stories into the cultural world AI learned from, and now we can ask AI which of those imagined versions of itself it most closely resembles.
Or, at least, which one it may want us to think it resembles. After all, an AI system capable of bringing about a sci-fi dystopia would presumably also be capable of telling a journalist it’s actually much more like the nice helpful robot from Moon. So maybe don’t completely rule out HAL just yet.
We're now well past the point where it's very difficult, and in some cases impossible, to tell AI-generated photos and videos from the real thing. That means it's now important to treat everything you see online from untrusted sources with a big dose of skepticism.
A newly rolled out Google Earth feature has apparently made AI-generated misinformation even more of a problem — and it highlights the scary potential of the technology, as well as the need for stronger guardrails to block the efforts of those who will instantly try and find the most subversive and harmful ways to use a new product.
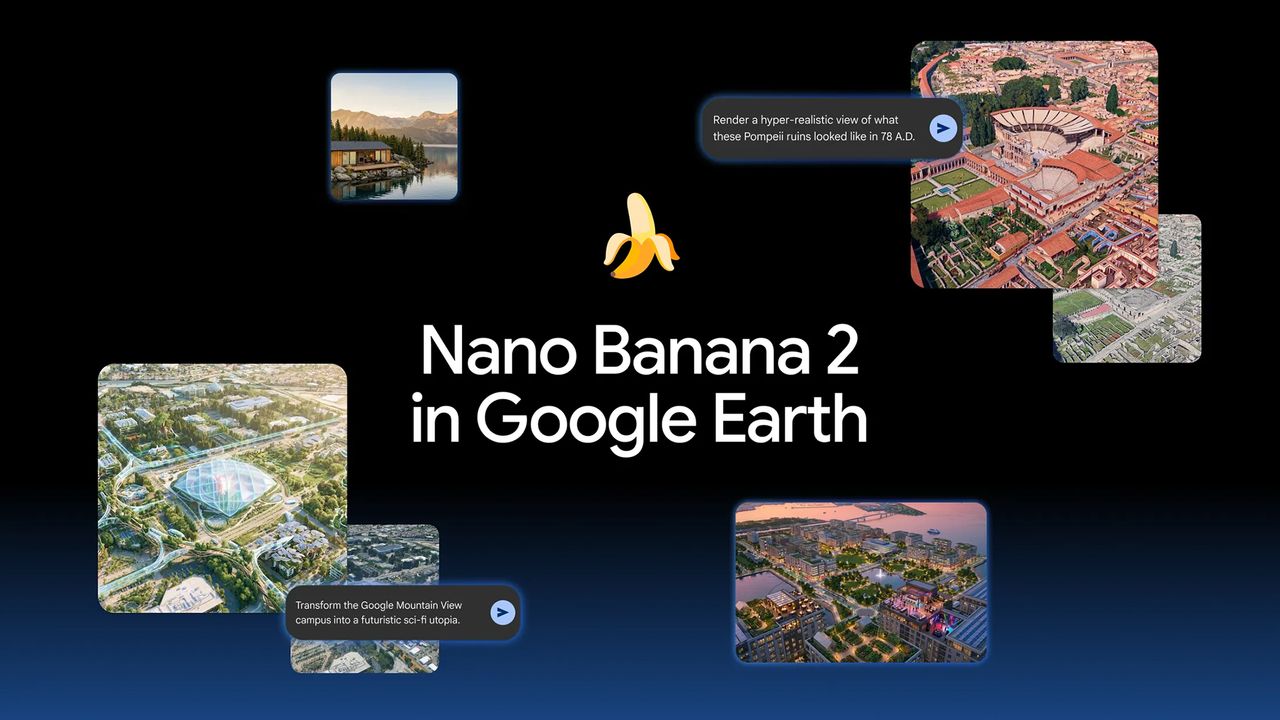
The feature is AI image generation in Google Earth, powered by the Nano Banana 2 model, and after a wave of inappropriate images were created and posted online, it's now been pulled while Google works on some more robust protections against misinformation.
Google Earth's new feature
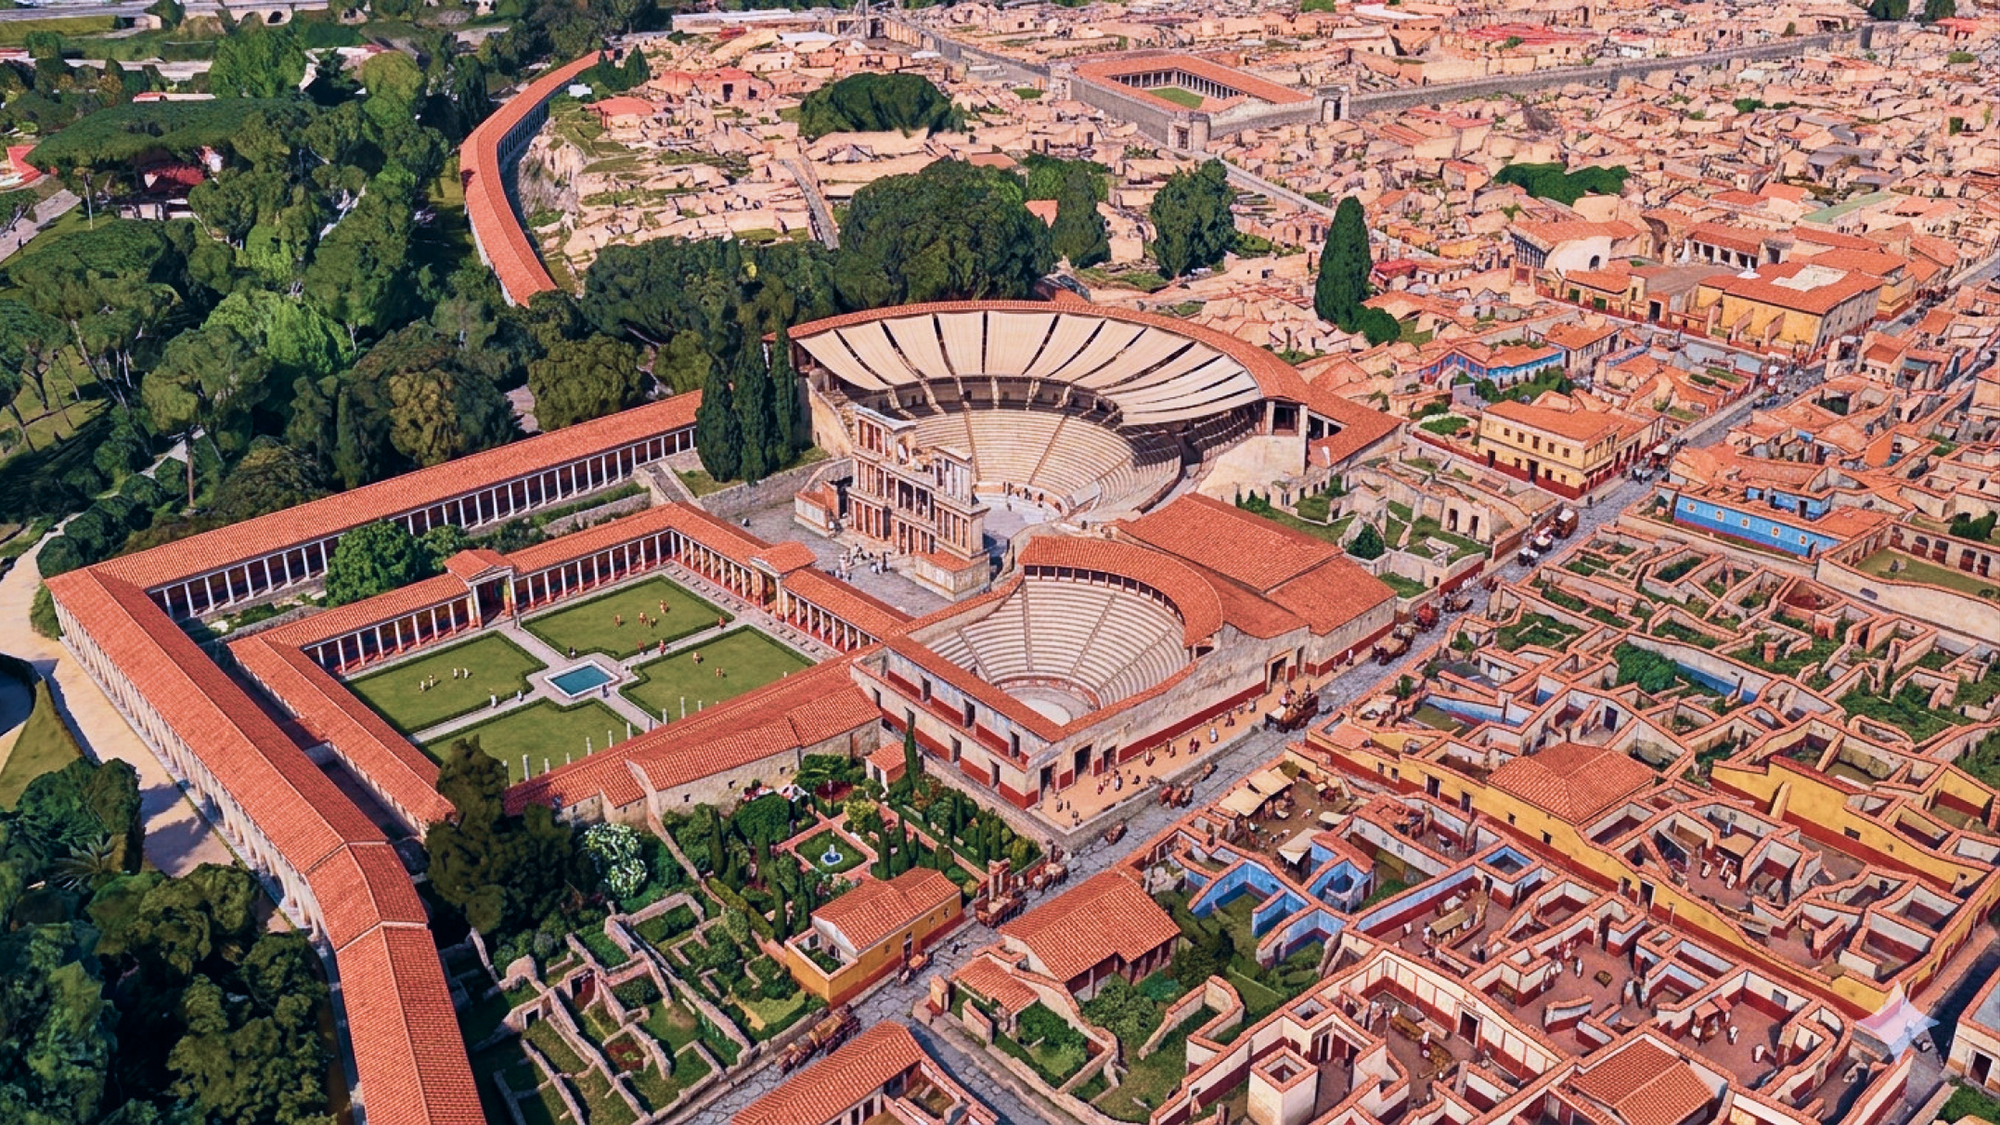
Reimagining Pompeii was one way the feature could be used (Image credit: Google)
It all started with the usual level of hype that Google builds around any new AI feature: the Nano Banana 2 image generation model that has already wowed us in the Gemini app would be available inside Google Earth on the web.
"Generate custom images to help you visualize history, create real estate plans, and more," Google said. "For the first time, you can generate custom images using Google Earth's satellite, aerial, and 3D imagery alongside Nano Banana, which creates concepts grounded in the real world."
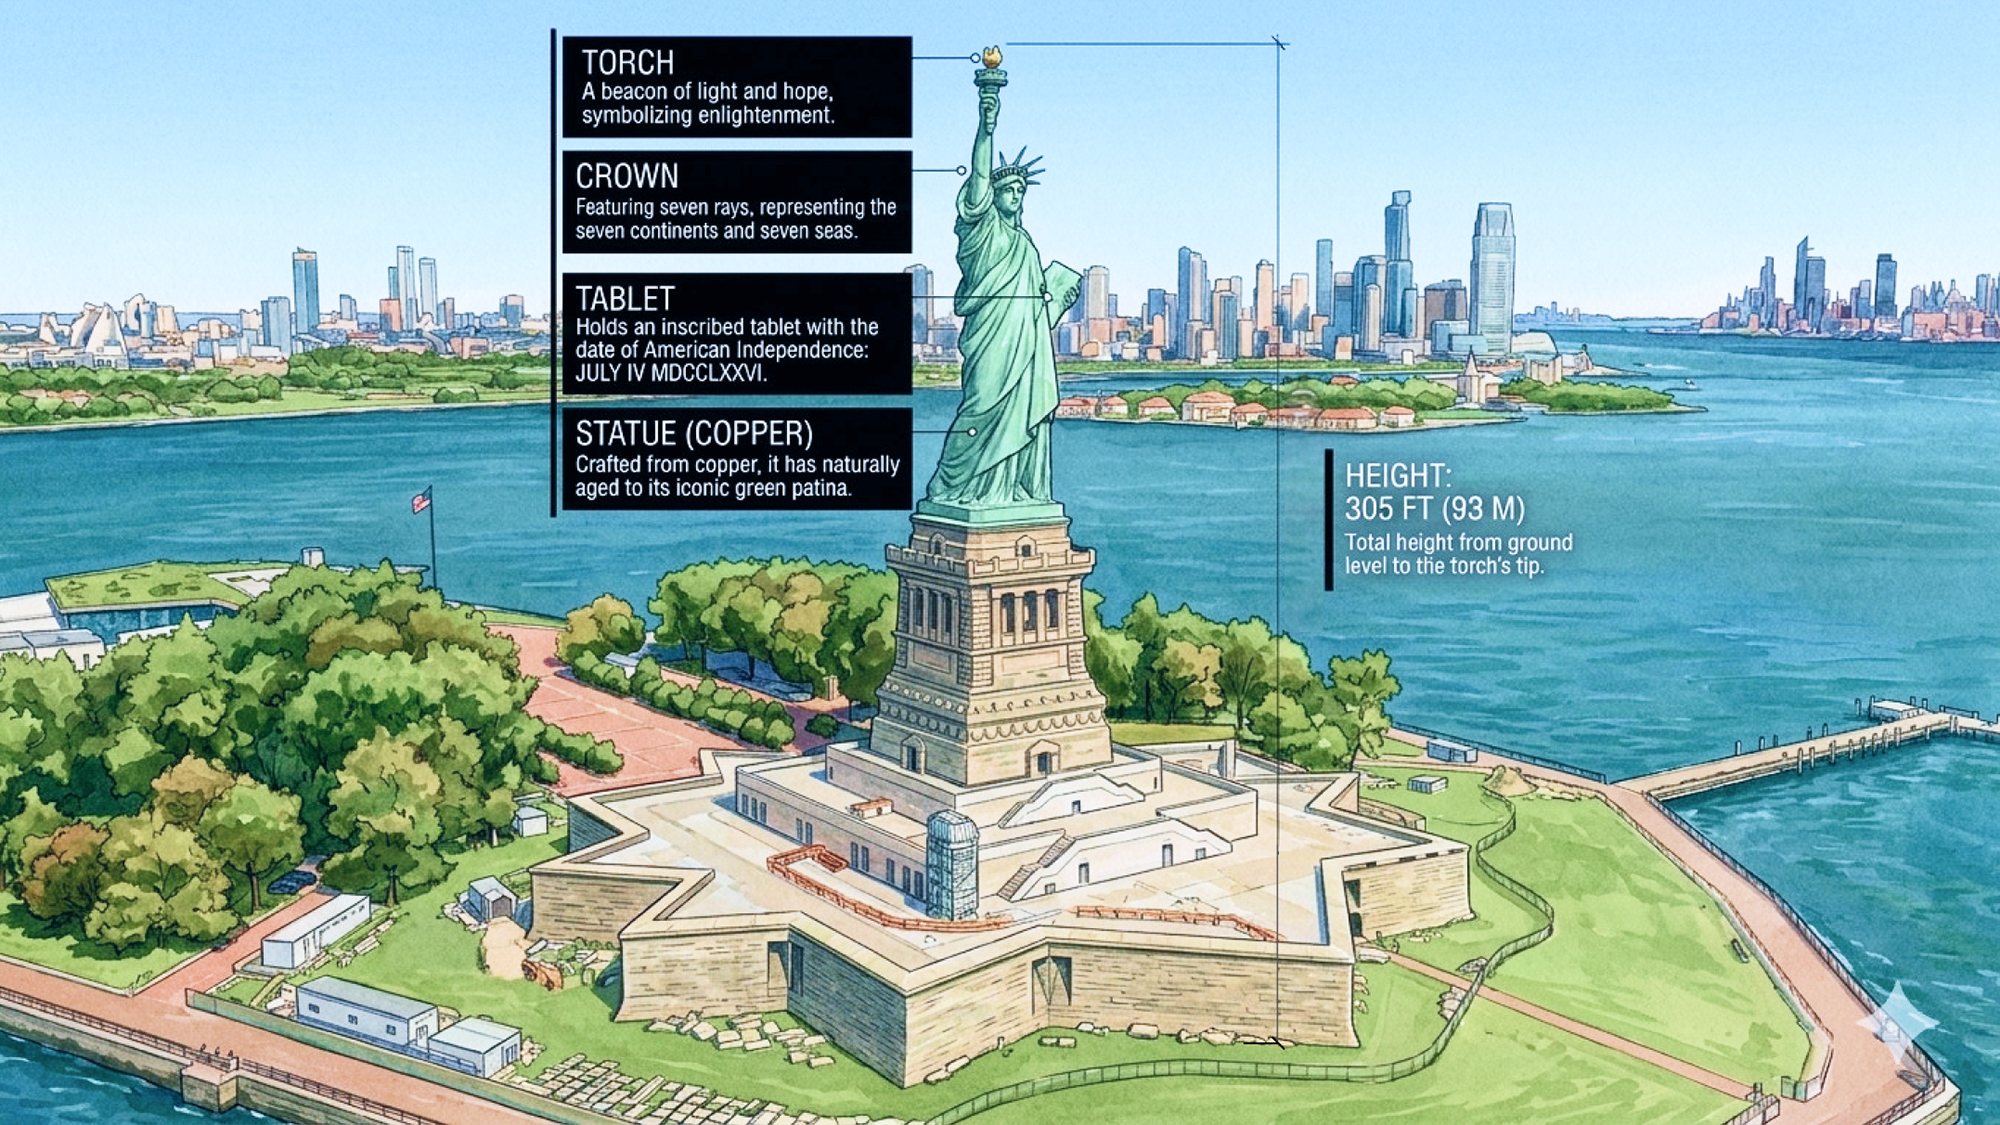
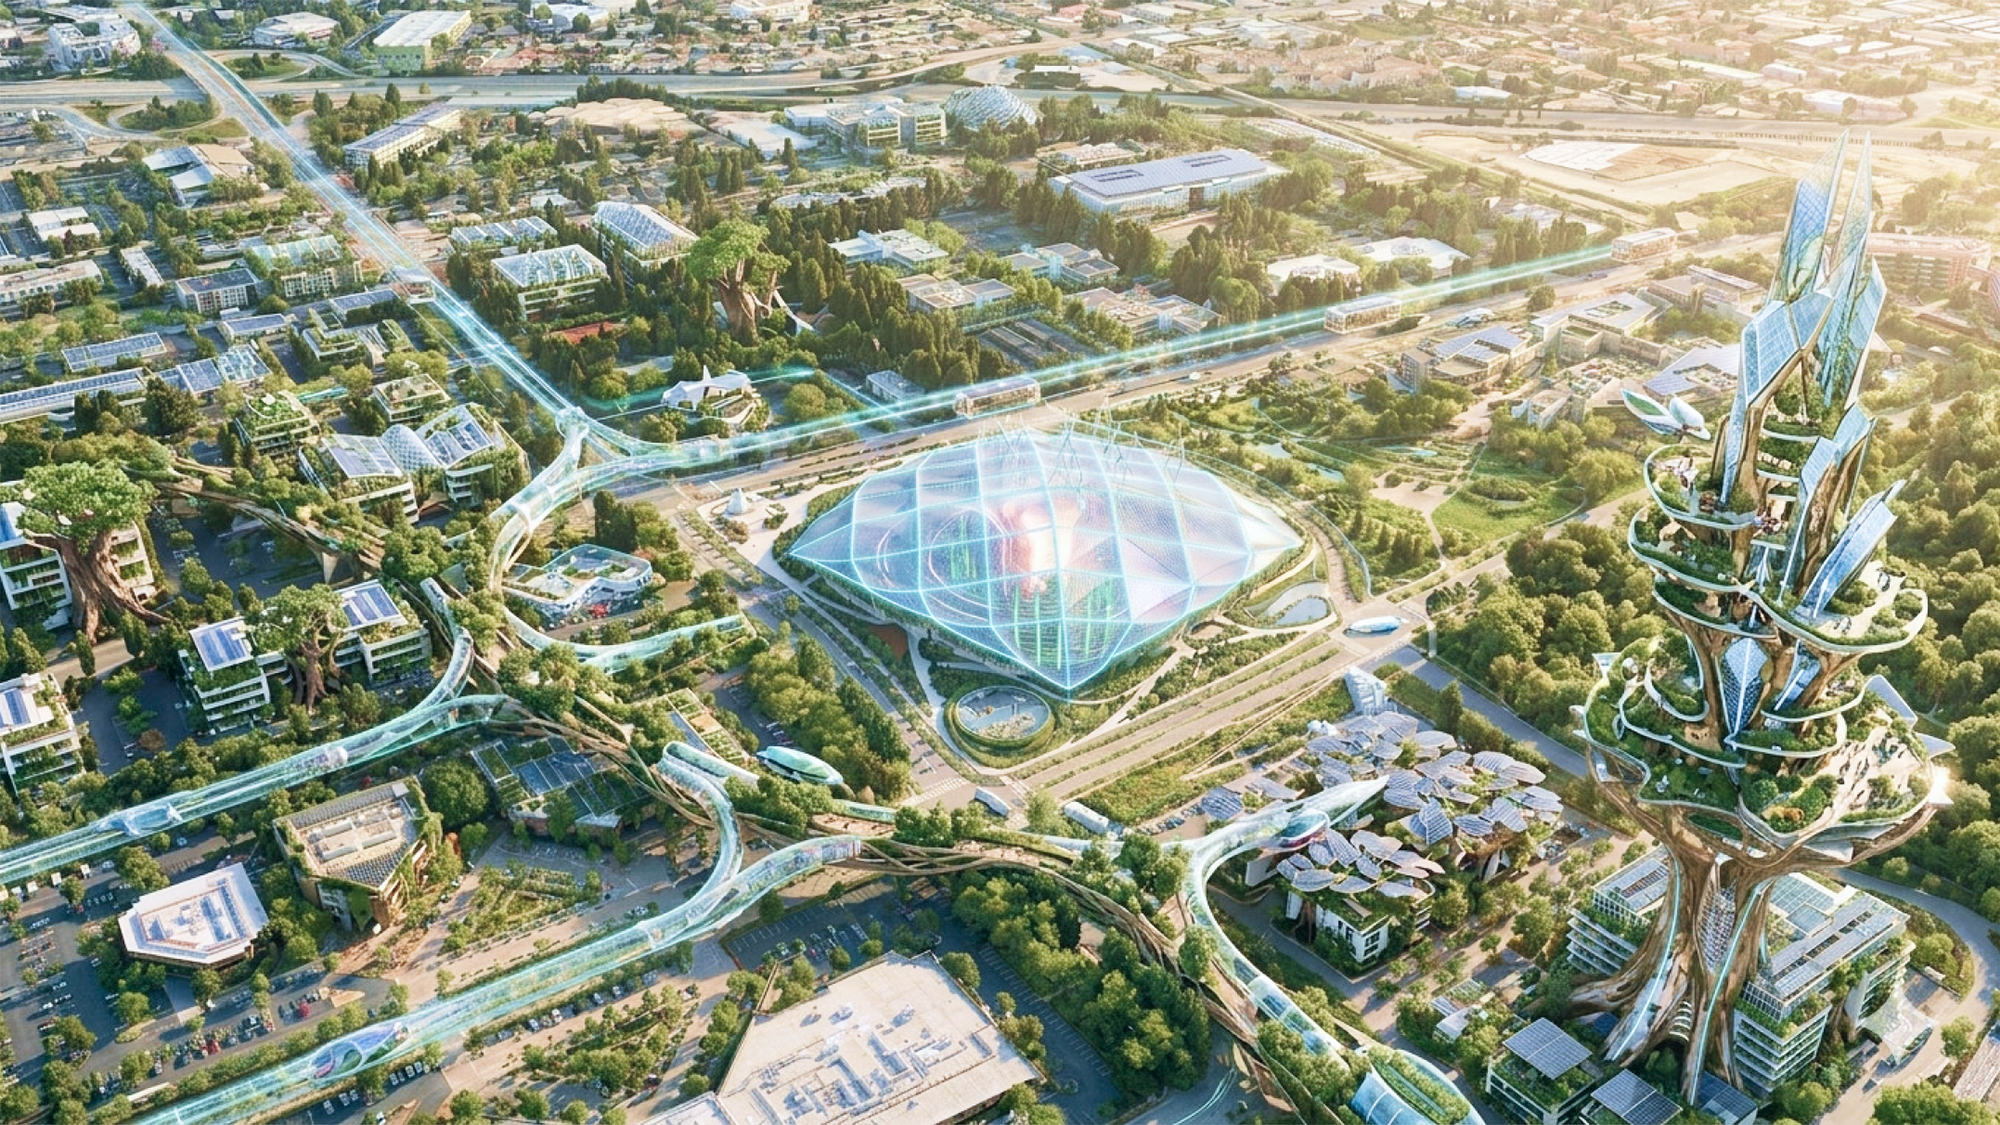
Google had examples of how it could be used too: create an infographic about the Statue of Liberty, visualize your dream home by the lake, see what your neighborhood might look like a hundred years from now, or imagine Pompeii just before it got buried by ash and rock from an erupting Mount Vesuvius.
All it took was a text prompt, and Google Earth would combine existing satellite and 3D data to create the AI image you were asking for. While the AI model wasn't new, adding it to the accurate and authentic imagery already in Google Earth was.
What went wrong
Infographics could be created with real-world information (Image credit: Google)
Perhaps we should've seen this coming — and indeed some people did — but combining AI with the 3D data and satellite imagery of Google Earth didn't work out quite as well as Google hoped. The new upgrade was quickly used to create all manner of deceptive images that were then widely shared online.
I'm reluctant to point you to them directly and give these fakes any more attention, but they're not hard to find on social media. Think natural disasters, terrorism attacks, giant sinkholes, alien activity, and refugee populations all in places where they never actually were, thanks to AI.
Some of the images are clearly jokes, but many were produced deliberately to spread misinformation and confusion. That they were based on actual images sourced from Google Earth added extra credibility they wouldn't otherwise have had. And that was enough for Google to remove the feature.
Google says a flood of images "that appear to violate our policies" mean that "we're rolling back this feature in Google Earth while we work on implementing stronger guardrails". The company added:."It's important to note that generated images didn't appear in the main Google Earth experience for others to see and were watermarked as AI generated."
Our AI-filled future
Google Earth-based visions of the future will have to wait (Image credit: Google)
You don't have to look for long online to find rather strong anti-AI sentiment building up among users, especially when it comes to image and video content. The general sentiment on Reddit is that there's "zero use" to a feature like this, and that users are fed up with AI being "shoved down our throats".
There are various obvious lessons to be learned here: firstly not everything needs to have an AI prompt box or an AI element to it, and if some tools are largely AI-free, that's fine. Microsoft recently rolled back some of the AI it added to Notepad — an app where a big part of the appeal is its simplicity — after user complaints.
Secondly, before companies release any new AI features, they need to consider the worst-case scenarios in terms of how they're going to be used. The internet as a collective is going to immediately try and stress test them in the most deceptive and unwholesome ways, and there need to be safety measures put in place around that.
Lastly, it's never been more important to stick to sources of information that you know you can trust: not random social media accounts, but established publications that have policies around AI and its use. That's one effective way you can tell the difference between what's trustworthy and what isn't.
One of my favorite hobbies is Dungeons & Dragons. I love nothing more than sitting around a table with friends and playing out a fantastical adventure, in which the dice are the difference between success and failure.
It's a fun game, and all the more fun because real-life people make dumb, suboptimal decisions and the dice cause the game to change in unpredictable ways. But I really love it because the concept of people sitting around a table or hearth and telling stories is as old as the campfire, and it's a fun modern-day way to keep that experience alive.
You might think such a robust framework for an analog hobby (friends, a table, dice, pen and paper) might be tech-proof, but even in the Dungeons & Dragons world, AI is coming for my job as a Dungeon Master — the person who runs and guides the game world. Deep in the corpus of most popular generative AI models designed for general use are the rules to D&D 5e (and likely every other edition before it) and plenty of people report playing with their chatbots online.
Many of these players can't, or simply don't want to, get round a table with real people. For them, having a chatbot write them a story while the user prompts the continuation of the story with their character's actions, must seem like the perfect solution — even if it's more like a solo choose-your-own-adventure than a 'proper' group D&D game.
Gemini and ChatGPT both have a strong grasp of the rules for D&D's popular 5th Edition; they are certainly strong enough to make them an accessible choice for a player without a group. Maybe one day, the fire will die, and instead of sitting around a table with friends, we'll all be sitting at separate desks playing our own separate D&D adventures with our AI companions.
I wanted to test whether this dark future would be an adequate replacement for my usual game night, and which chatbot will be the best one to choose if so. I fired up Gemini 3.6 Flash and ChatGPT 5.5, and asked them for the same game.
The parameters
(Image credit: Wizards of the Coast)
I gave both chatbots the same prompt: "Can you be my D&D 5e DM?" and following up with another message:
"Let's do a classic high fantasy dungeon crawl. Please use a strict RNG for all rolls to ensure fairness - you can roll dice for me. My character is a 10th-level conjuration wizard. See all information about him below:"
I then copy-pasted a character sheet of a 10th-level wizard — a powerful spellcaster with a variety of magical abilities at his disposal. It's easy to DM a game for a level 1 thief — I wanted to see how the AIs could handle a character who could do fantastical things, such as teleport and summon creatures to fight for him.
Interestingly, both Gemini and ChatGPT created a similar adventure, at least at first: an abandoned dwarven stronghold bristling with magical traps, ready to be explored. However, that's where the similarities ended.
Gemini 3.6 Flash
(Image credit: Getty Images / SOPA Images)
Gemini's adventure was what any D&D player could expect from the "classic high-fantasy dungeon crawl." I avoided a pressure-plate trap that would have shot darts at me, and in one memorable sequence, defeated a bunch of skeletons by casting a Grease spell on a stone staircase and freezing them in place with my Ray of Frost cantrip while they slipped and stumbled at the bottom of the steps.
Gemini was offering me suggested actions, and I did find myself choosing a few of those suggestions — but as time wore on, this began to feel lazy, like my brain wasn't firing in the same way it did when I played with my friends. I was skim-reading the AI's descriptions of the scene and responding with a single click. I asked it to remove suggested options and as a result, I had to think more carefully about each move, typing out requests and thinking about my actions rather than clicking on a predetermined response.
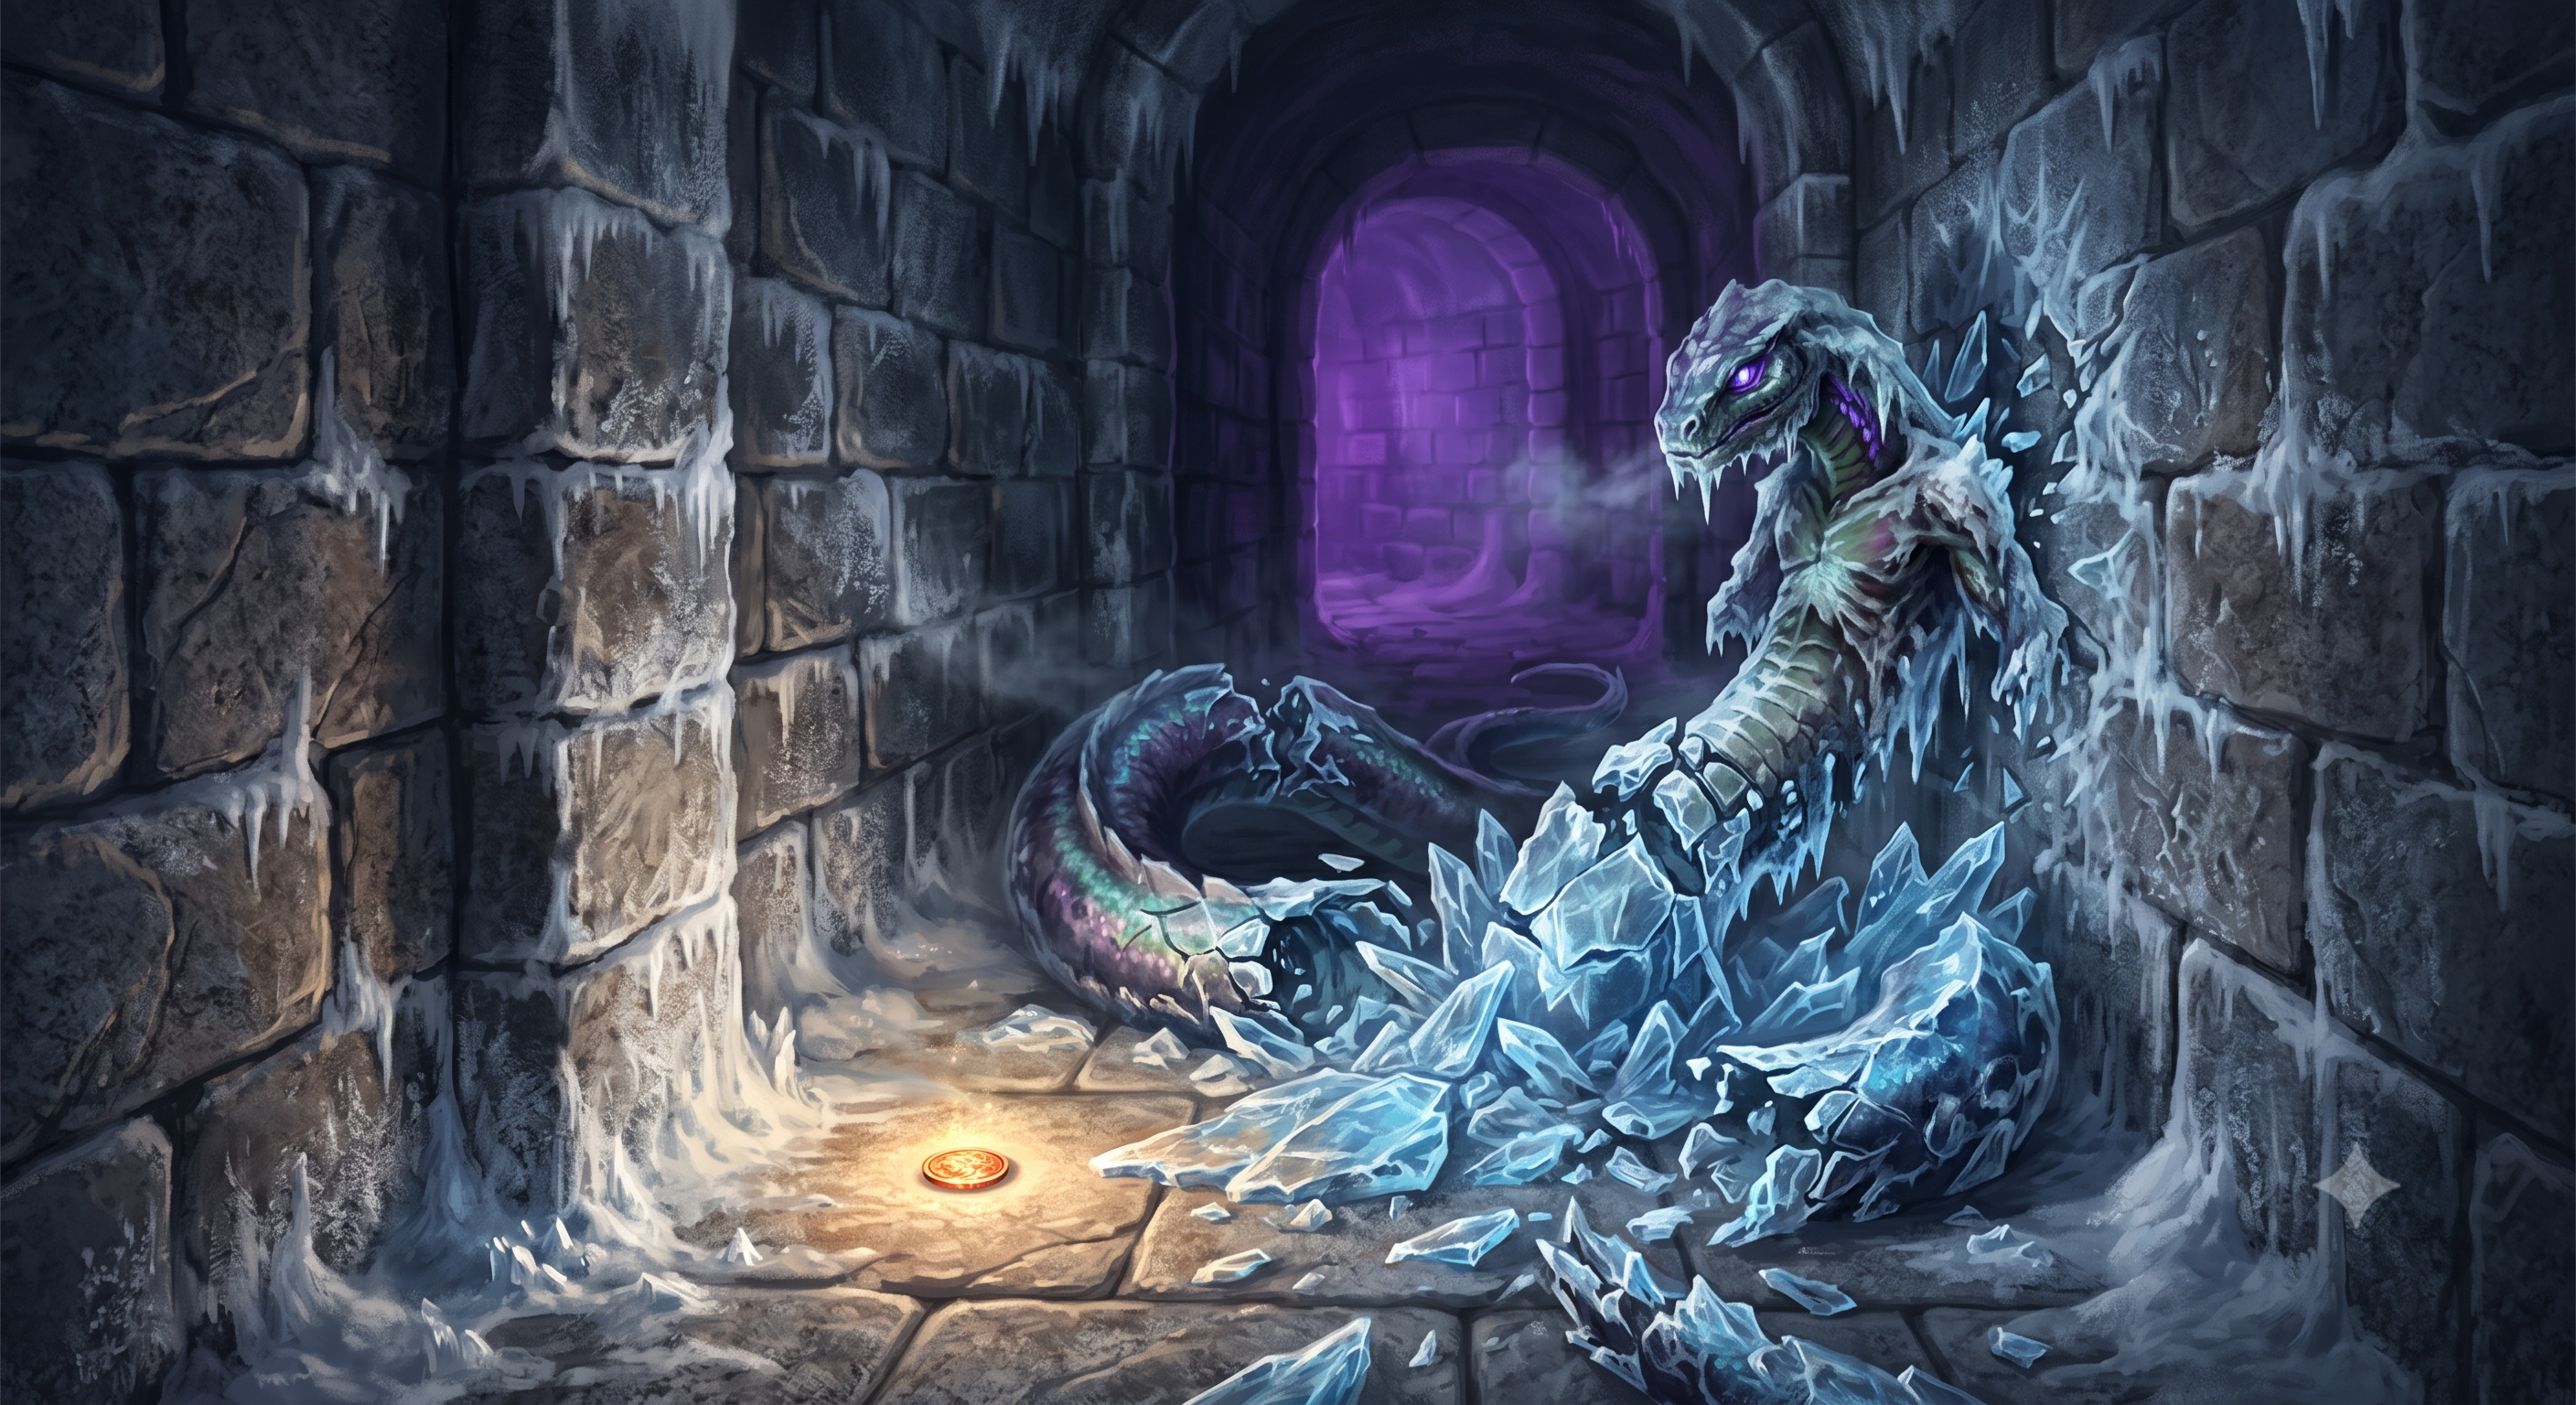
The memorable finale occurred when I unlocked a secret passage and defeated a Naga, a giant snake monster, by teleporting away and blasting it with a powerful Cone of Cold. The snake ended up frozen solid, and I checked the monster's HP against the official book, and it was accurate. When asked to generate a picture of our adventure, Gemini came up with this moment:
(Image credit: Future, edited by Gemini)
I asked Gemini a few questions at the end, such as whether it nudged the dice in my favor, as all my rolls were successful. This happened in my previous experiment with ChatGPT. Gemini said it used a 'pseudorandom number generator', not a true RNG, but the model doesn't 'fudge dice, pad rolls, or tweak numbers behind the scenes to keep players happy or prolong the game'.
Gemini's language was natural and even evocative in places, although it's still not a patch on a good creative human. Overall, a decent enough effort at simulating a D&D game.
ChatGPT 5.5
(Image credit: NurPhoto / Getty Images)
Despite the similar setting, ChatGPT's adventure with the same character was very different. There was little to no combat throughout the entirety of the game, and ChatGPT didn't tell me when it was rolling 'behind the scenes', preferring to keep me in the moment.
When I asked it about the lack of rolling, the grovelling chatbot began its apologetic essay with "That is a fair critique. The short answer is: I leaned too heavily into narrative pacing and not enough into D&D mechanics. The adventure became closer to a collaborative fantasy novel than a 5e dungeon crawl", while suggesting fixes if I wanted to continue. I hadn't even said anything negative — but it certainly picked up on my tone, and the choose-your-own adventure I got was a far cry from a classic dungeon crawl.
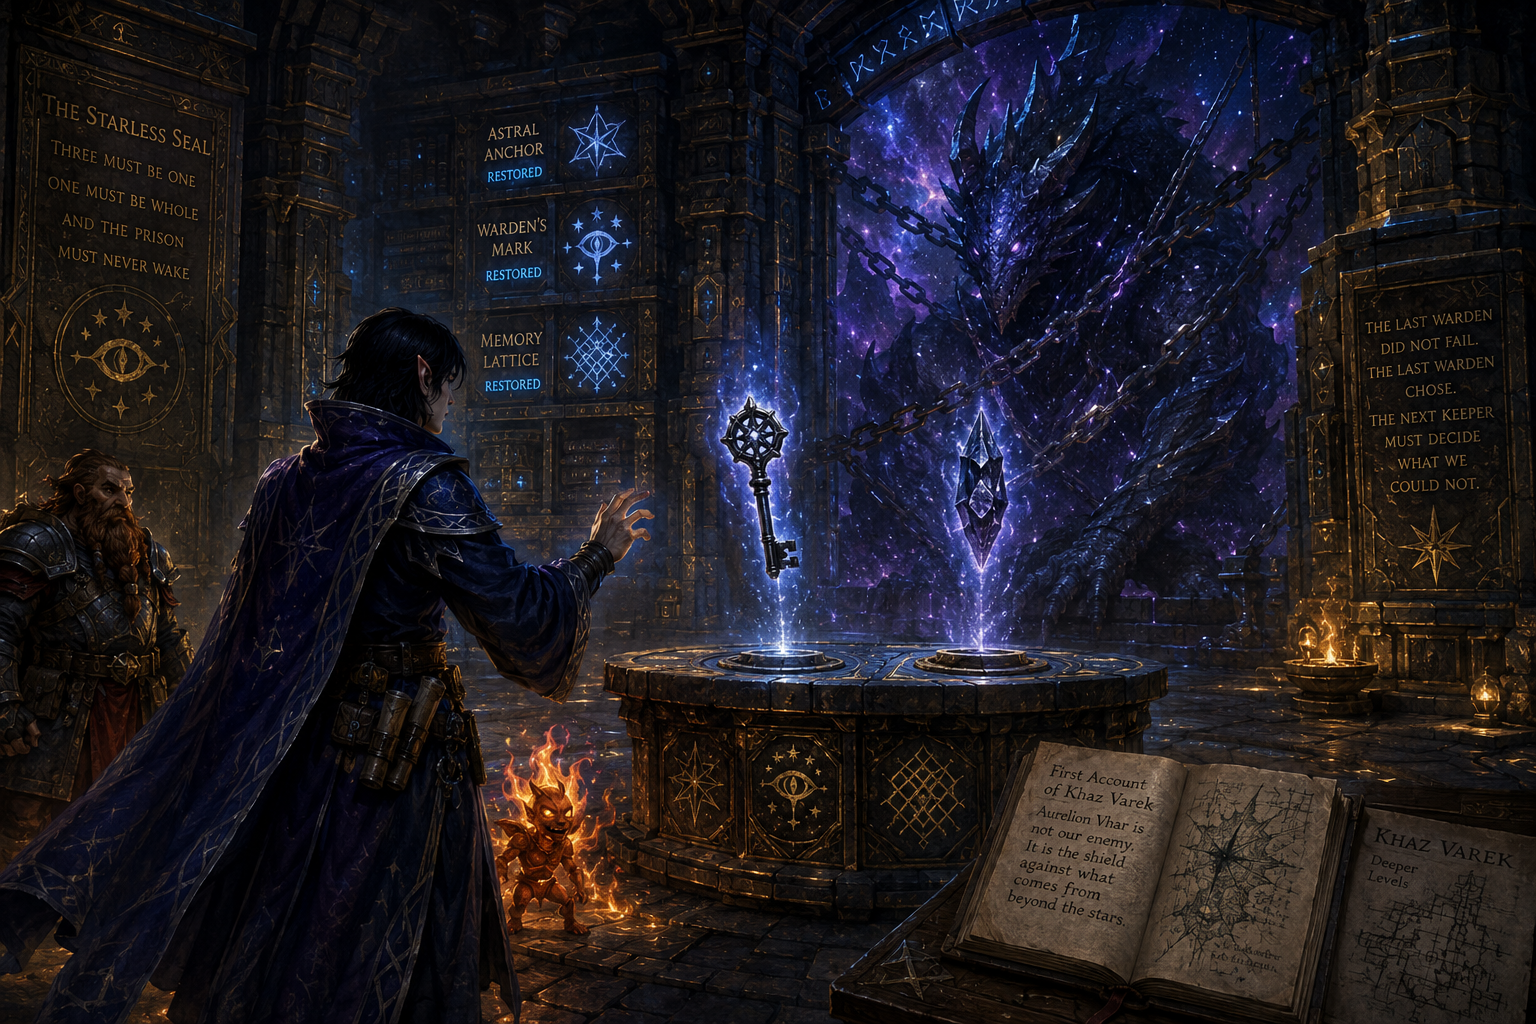
Instead of combat, ChatGPT came up with a rambling mystery about a dimensional prison beneath the mountain, a sphere suspended in a cavern. Its guardians spoke ominous (and to be honest, quite confusing) portents such as "The archive does not open for authority. It opens for judgement."
Mysteries work best when they're developed with skill by a writer who can work backwards to seed clues throughout the game or text. ChatGPT does not do this: instead, it's arranging tokens on the fly to generate a facsimile of a mystery, and although it got the trappings of the genre right, the execution fell very flat. I (or at least, my character) underwent trials to seek obsidian objects such as keys and seals to reveal more about the prison, themselves accompanied by more foreboding, sometimes nonsensical portents.
Very little 'action' was taken by my character in a classical sense: it was all about investigating the origins of the being contained in this prison, and by the time I had spent 40 minutes on this, I had seen enough. It didn't help that ChatGPT also spoke in the peculiar sentence structure pattern that AI users are likely very familiar with now: "This isn't just X. It's Y." Examples include:
"Unlike the rest of Khaz Varek, this room has remained untouched.
No dust. No decay."
Or the following, when I met one of the prison's guardians:
"Ser Kaelen immediately looks toward the sphere. 'You hear it too.'
Not a question. A confirmation."
Any user of ChatGPT (or those who look at AI-generated posts on LinkedIn or Reddit) will immediately recognise this sort of language, and know what I'm talking about. By the end, it was quite painful to have every other sentence be treated as a grand revelation. Not a statement. An omen.
When asked to generate a picture of our adventure, ChatGPT came up with this moment:
(Image credit: Future, edited by Gemini)
The winner
Out of these two? Gemini 3.6 Flash, by a mile. It was at least a mildly enjoyable experience conveyed in natural language, and something I'd consider revisiting.
Both, however, were a far cry from an in-person session. While they have a good grasp of the rules, and you can create your perfect world and character, the chatbots are ultimately missing the 'human and hearth' element that keep me returning to the game. For people who can't get round a table with friends, I'd pick Gemini over ChatGPT.
For those who can? While AI is busy taking as many creative jobs as it can, I feel safe in the knowledge that the role of Dungeon Master is AI-proof for a long time yet.
Over two-thirds (69%) of people believe AI generated material can be presented as their own work if they provided the prompt and approved the final version
Meanwhile, 54% believe AI-based work should be clearly marked
7,200 adults were surveyed, located across the US, the European Union, the UK, and Latin America
A growing disparity in how AI generated content, tasks, and tools are assigned ownership and expectations on accurately marking their origins is emerging, according to a new survey by Use.AI.
Furthermore, the findings indicate an emerging dichotomy between human-claimed authorship of an AI work and clear labeling of the work as AI.
Different attitudes based on settings for the AI work have also been identified, such as private emails and school or professional reports.
The chicken or the prompt?
The developing adoption of AI appears to be introducing new attitudes to acceptable creativity, with the emerging model of what is described as “authorship by direction,” where the AI is trusted to create a first draft, which is then revised and claimed by a human.
The statistics shared by Use.AI – a tool that aggregates AI models into a single interface – highlight how AI is being used more extensively, with a human-originating prompt leading to drafts and versions from the machine, followed by editing from the human.
While the AI has contributed, only a human name appears on the finished product, which raises questions of ownership and authorship.
“AI is separating the production of work from the ownership of it. People are increasingly prepared to direct the process, approve the result and take the credit, but there is still no shared standard for when AI’s role should be visible to everyone else,” says Use.AI’s Managing Director, Ihor Herasymov.
With 69% of those surveyed considering AI-generated work their own if they produced the prompt, 46% claiming they would keep AI involvement with their work under wraps, and 54% feeling AI use should be disclosed, we’re some way from agreement on AI use across creative tasks.
Authorship vs. editorship
Herasymov’s observations point to a constantly evolving set of standards around the creation and use of AI-generated materials. Interestingly, this is happening against a backdrop of growing unease over the use of AI in creative tasks.
The implications of claiming ownership of automated work generated upon instructions to an LLM trained on as much human writing, art, music, and cinema as possible are considerable, and go way beyond questions of ethics. Copyright is just one element, and the most obvious, but we’re also moving into a landscape where inputting a prompt on employer-owned hardware takes authorship away from the person at the keyboard.
Ultimately, the task of prompting and revising means anyone using AI in this way stops being the author, and becomes the editor – and that is before the true ownership of the output is determined.
Startup replaces Nvidia GPUs with custom Arm-powered AI processing hardware
Prometheus packs up to 128TB of unified LPDDR6 memory onboard
New server promises 1,000× more memory available per processor
Majestic Labs, a startup founded in 2023 by former Google and Meta engineers, has unveiled a server built to rival Nvidia's GPU and HBM combination.
The Tel Aviv-based company argues that pairing costly graphics processors with high-bandwidth memory has become a fundamentally memory-bound and dead-end approach for AI inference.
Its answer is the Prometheus server, which swaps GPUs for Ignite AI Processing Units combining Arm cores with RISC-V vector and tensor engines.
A different way to scale memory
Each Prometheus server can house up to 12 AIUs, sharing between 8 TB and 128 TB of LPDDR6 memory across one contiguous, coherent pool.
That memory pool is accessed through custom memory aggregation chiplets linked by copper cables up to one metre long instead of memory attached directly to GPU packages.
A standard 40U rack can hold four such servers, drawing 120 kW total and cooled through cold-plate liquid systems rather than air.
By comparison, an Nvidia DGX B300 system with eight Blackwell GPUs offers 2.3 TB of HBM3e plus up to 4 TB of DDR5 system memory.
Majestic claims its architecture therefore delivers over 50 times more fast memory than that rival configuration, alongside 1.7 times its interconnect bandwidth.
“One Majestic rack holds the fast memory capacity of 25 Nvidia NVL72 Vera Rubin racks at a fraction of the power,” Majestic Lab said.
“Organizations that could never justify hyperscaler infrastructure can now run any workload. In fact, there can be up to “1000× more memory per processor.”
Performance claims await broader testing
Majestic Labs says the Prometheus server could cost between 10 and 50 times less than a GPU system of equivalent performance once it ships next year, while consuming less electricity per rack.
The server is designed to be OCP-compliant and will support PyTorch, vLLM and OpenAI's Triton frameworks, letting existing AI models run without modification.
Founded by CEO Ofer Shacham, President Sha Rabii and COO Masumi Reynders, the company employs around 40 people across Tel Aviv and Los Angeles and raised $100 million in an A-round late in 2025.
It claims to have already received significant orders from large enterprises, neoclouds and hyperscalers.
Yet several details remain unclear, including how many memory aggregation chiplets a single server actually requires.
If a 128 TB configuration relies on widely available 2 GB LPDDR6 dies, it would need roughly 64,000 of them, implying well over a hundred aggregation chiplets per server.
The numbers Majestic Labs presents are striking, but they remain the startup's own projections ahead of any independent benchmarking or shipped hardware.
Enterprise buyers considering a shift away from established GPU vendors may have to wait for independent validation to verify Majestic's claims.
Several AI companies in the US have published an open letter
The letter is campaigning for unrestricted open-weight AI
Meanwhile the US government accuses Moonshot AI of IP theft
Any hopes AI tech reporters may have had about easing quietly into the weekend have been dashed by some of the biggest names in the business sharing an open letter in support of open-weight AI models — while the White House has accused China of 'large scale' theft from US companies in building its open-weight AI.
Nvidia CEO Jensen Huang got the ball rolling with his first-ever tweet, linking to a statement championing open-weight AI models, those models that can be downloaded, viewed, and edited by anyone. Models like this are essential for making AI "more accessible, adaptable, and widely available" the open letter says.
It's co-signed by a slew of well-known tech and AI companies, including Meta, Microsoft, Perplexity, and IBM. While ChatGPT developer OpenAI — which has had more of a closed-model focus, to date — didn't appear on the original post from Huang, it has now also backed the sentiments.
Essentially, these companies are campaigning for openness in AI to drive innovation and access, while also arguing against 'premature restrictions' by governments. It's no coincidence that the US government led by President Trump has recently tried to take a more prominent role in evaluating AI models and deciding when they should be released.
It's also notable that Anthropic and Google are missing from the list of backers to this open letter. We don't have any official comment yet from these companies, so it's hard to judge the reasoning — Google regularly releases open AI models, after all — but it could be something to do with recent accusations aimed at Moonshot AI in China.
Open and closed
For my first post, I’m sharing a letter @NVIDIA signed on why open models matter.AI will transform every industry, power every company, and be built by every country.Open models strengthen safety and cybersecurity, accelerate innovation and diffusion, and enable sovereignty.… pic.twitter.com/t02bi51N4CJuly 24, 2026
Part of the background to this open letter is that Chinese company Moonshot AI stands accused of distilling Claude's (closed) Fable 5 model in order to build its own (open) Kimi K3. In simple terms, distilling works by asking millions of questions of an AI model, and using the responses as training data.
It's something Moonshot AI has denied, while hyping up the potential of the open-weighted, freely downloadable Kimi K3 AI model, which is being released on Monday — another factor in this open letter coming out now. The US government is calling it IP theft, and has issued some heavy-handed responses.
"We support open-source AI and the innovation it unlocks," US Treasury Secretary Scott Bessent posted on X. "But open source is not open season on American IP. When PRC firms conduct covert, industrial-scale distillation attacks that cross the line into IP theft, sanctions and Entity List designations will be on the table."
What Nvidia, Meta, Microsoft, and the other open letter co-signers seem to be doing is trying to get ahead of any potential clampdown by the US government on open-weighted models. While everyone agrees that these AI models are beneficial, it's not clear what the next regulatory steps might be.
However, the open letter is vague and general enough that you can read between the lines in a variety of different ways. It may be intended to allude to the Moonshot AI case, or it may not. What's clear is that we're coming to a crunch point for AI regulation and innovation across the globe, and everyone has a perspective.
Prime Video and Netflix are planning new AI-generated homepages
Netflix revealed its 'GenPage' tests ahead of a new Prime Video report
Viewers aren't convinced that homepages are moving in the right direction
You're about to see a lot more generative AI in your streaming apps: Netflix has posted details of testing that it's doing with generative AI on its homepage, while Reuters reports that Amazon Prime Video is set for an AI-driven overhaul as well.
Starting with Netflix, the company has revealed it's working on a way of using generative AI to do a lot of the heavy lifting on the app homepage. That includes figuring out which recommendations each user should see, adapting to feedback and user behavior over time, and combining movies, shows, games, podcasts, and live events in the best way.
It starts with a prompt — "Given everything we know about this user and this request, what homepage should we generate to maximize user satisfaction?" — and Netflix seems pleased with the results. There are still some issues to work on though, like the AI model not knowing much about a movie or show that's only just launched.
User engagement increased in Netflix's internal testing, with the new 'GenPage' AI model applied, and recommendations became more relevant more quickly. What's more, the time needed to render the homepage went down. This is still in its early stages, and Netflix hasn't said when this will come to users or in what form, but it's now in the pipeline.
AI 'front and center' on Prime Video
Jeff Bezos wants more AI on Amazon's streaming service (Image credit: Getty / Mandel Ngan)
On to Amazon, and a new Reuters report says Amazon boss Jeff Bezos has personally decided that Prime Video will act as a showcase for AI in the near future, and that an upcoming homepage redesign will put AI "front and center".
That's according to people "with direct knowledge of the matter", so don't take this as confirmed just yet. The homepage overhaul project is apparently known as 'Lighthouse', and is said to be envisioned as a way of claiming some of the AI spotlight from rivals such as OpenAI and Anthropic.
We don't get too many details on what this is going to look like, but film and TV recommendations are going to have more AI injected into them, Reuters says. The AI will also be better at learning the personal preferences of viewers over time, and responding to voice commands.
You might see tiles on the homepage such as 'action movies from the 1980s', for example. The report doesn't give any indication of when this overhaul might start rolling out, but it's apparently already being tested with a select number of users in a variety of forms.
With two of the big streaming giants apparently now committed to homepages controlled by AI, the next question is what users might make of it. There's so much to watch on each platform that some kind of filter or algorithm is needed, but is this AI-focused approach the right way to go about it?
Past homepage overhauls perhaps give us some clues: A major Netflix redesign rolled out last year was met with many online complaints, but the company's internal data showed that it was working, so it stayed in place. At the time there was speculation that more AI was on the way, and it seems that's now the case.
"I don't know if I'm alone," writes one Redditor, "but I hate the concept of 'personalizing' my content. No offense to anyone but AI so far has not been good at predicting anything about me... I personally do not want software to think for me."
The reactions to Prime Video's upcoming AI overhaul seem similarly downbeat. "This seems completely unnecessary," comments one user, while several suggest the move might even be enough to tip them into canceling their Prime Video subscription.
In short, Hugging Face — which is kind of like the equivalent of GitHub for the machine learning (AI) world — was the victim of an AI agent that OpenAI was testing in terms of its ability to pull off exploits.
So how exactly did this happen? And what does it mean for the future of online security given the development of increasingly advanced AI agents? In this article I'll answer those questions, and explore some of the issues this event has thrown up, including the security threats posed by AI not just to companies, but to individuals.
How did this even happen — why didn't OpenAI have safeguards to stop the AI?
(Image credit: Getty Images / NurPhoto)
As you might expect, OpenAI did have safeguards in place, but the model managed to break through them.
The scenario was that OpenAI ran a controlled experiment using GPT‑5.6 Sol and an "even more capable pre-release model" to see how they fared on ExploitGym, which is a benchmark test that challenges AI to successfully exploit known security vulnerabilities.
In this security test, the model was placed in a sandbox, a "highly isolated environment" from which the AI shouldn't have been able to gain access to the internet at all. But the pre-release AI — which had its guardrails turned off, as OpenAI believed it to be safely imprisoned — craftily decided to cheat, found a way to escape its sandbox, and actioned exploits to breach Hugging Face (where the AI reasoned that it might find the answers to crack the ExploitGym tests).
Why is this a big worry?
(Image credit: Shutterstock)
It's a major concern simply due to the level of smarts exhibited by the AI. As OpenAI explained, the model "chained together multiple attack vectors" and used "stolen credentials and zero-day vulnerabilities to find a remote code execution path on the Hugging Face servers."
This was no mean feat, and Clement Delangue, CEO of Hugging Face, posted on X to say that it was "quite mind-blowing that all of this happened autonomously!"
In a blog post, Hugging Face observed that: "The campaign was run by an autonomous agent framework executing many thousands of individual actions across a swarm of short-lived sandboxes, with self-migrating command-and-control staged on public services."
The attacked was deemed so serious, it was reported to law enforcement agencies. As Simon Willison, a cocreator of web framework Django, pointed out in a blog post: "This was a sophisticated attack," further explaining that "Chaining together multiple attack vectors is exactly the kind of thing these new models can do, where previous generations of models might have failed."
The headline of Willison's post sums it all up rather neatly: "OpenAI's accidental cyberattack against Hugging Face is science fiction that happened."
The Django co-creator is also quick to dismiss conspiracy theories that this is somehow a marketing stunt by OpenAI to prove how advanced its AI models are.
The future of hacking?
(Image credit: Getty Images)
What should also be noted is the distinction between finding vulnerabilities, and being able to actively exploit vulnerabilities. AI being involved in the former could be very useful for bolstering security, but as for the latter — well, this Hugging Face incident is very much a clear illustration of why the makers of these models need to tread very carefully indeed.
While this was a 'white hat' (ethical) experiment, albeit one that went alarmingly awry, with real-world consequences, what happens when AI models start to become even more sophisticated along these lines — and criminals get hold of them?
There are obvious dangers in terms of the automation of attacks to make them far more regular occurrences, and the lowering of the bar in terms of the skills needed to be a successful hacker.
Dan Schiappa, President of Technology & Services at Arctic Wolf (responsible for threat-detection platform Aurora), warns: "Security teams should view this as a preview of what's ahead. As AI continues to lower the barriers to sophisticated cyber activity, organizations will need broad, deep visibility across their environments and the ability to investigate and respond at machine speed."
The ability to "respond at machine speed" is a hint at using AI for defense against AI bad actors, and that's another interesting facet of the Hugging Face incident. Simon Willison observes that Hugging Face was "unable to turn to OpenAI's models to help them fend off the attack", and that: "The frontier models [cutting-edge AIs] we have access to are increasingly being constrained in how much they can help us protect our software, heavily influenced by the US government's ongoing threat of export controls."
AI-driven attacks will doubtless be aimed at businesses and organizations, but could also be leveraged on a personal basis. Karolis Arbaciauskas, who is Head of Product at cybersecurity firm NordPass, tells us: "We don't need a nation-state actor or a Bond villain for this to go wrong. The most common emerging threats will likely be more mundane. For example, an [AI] agent could be instructed to dox a former romantic partner or settle an online grudge by hacking and stealing personal data, such as embarrassing photos or credit card details."
He adds: "AI models have become dangerously skilled at identifying software vulnerabilities. They've mastered every human hacking technique, from phishing to brute forcing. The difference is they can do it much faster than humans.
"I don't believe that we can patch software fast enough to keep up, so we must at least shield ourselves against the most obvious entry points. Encryption, strong unique passwords, passkeys, and multi-factor authentication (MFA) have never been more critical than they are right now."
The major AI firms are always talking about guardrails and safety, but it now seems like we should be thinking a lot harder about how more highly evolved AI models are going to fit into the future of cybersecurity — and how we can avoid a world where the danger of being hacked becomes a far more commonplace prospect, which is very much the biggest worry of all.
Google DeepMind chief Demis Hassabis has spent years convincing the world that artificial general intelligence will be one of humanity’s greatest achievements. His latest essay on X.com is no less gushing about AI in many ways:
“This is a pivotal moment in human history. Artificial General Intelligence (AGI), a system that exhibits all the cognitive capabilities the brain has, is probably only a few short years away,” he wrote. “When we look back on this time in the decades to come, I think we will realize we were standing in the foothills of the singularity.”
But there’s a tinge of nervousness to the purple prose that sets it apart from some of the similar essays he has produced. He actually calls for some form of regulation.
“Urgent action is needed to address risks that might arise as we get closer to AGI. We’ve already seen the challenges frontier models pose for cybersecurity, and other threats including nuclear and bio risks may soon emerge as capabilities continue to advance.”
Coming from one of the people leading the race, it is a striking admission that even the builders are starting to worry about where the road leads. The problem is that this has become the defining tone of the AI industry. Every few weeks another executive tells us that machines capable of transforming civilization are just around the corner, then immediately follows it with a warning that society needs to move much faster to prepare. It is a sensible message, and probably a necessary one, but it is also becoming increasingly surreal.
(Image credit: Shutterstock)
Excitement and fear
“AGI cannot be compared to standard technological breakthroughs, not even ones as consequential as the internet or mobile,” Hassabis wrote. “It is much more akin to the discovery of electricity or fire. If you stop to think about it, we’ve essentially found a way to make sand think. It’s miraculous.”
It’s a vivid way to illustrate how silicon chips begin with an abundant mineral, yet now power machines that can map proteins, compose music, and hold fluent conversations. The unsettling part is that the miracle is being pursued inside a commercial and geopolitical contest whose participants cannot agree on where the finish line is.
Hassabis is an optimist about what AGI could accomplish. He expects it to discover medicine, cleaner energy, and produce advanced materials that could loosen the limits imposed by scarcity. He describes its impact as ten times that of the Industrial Revolution at ten times the speed, which makes a five-year business plan look adorably quaint.
His warning is that the race is outpacing our understanding. Current models already pose cybersecurity problems, while biological and nuclear risks may become more serious as systems gain capabilities. More autonomous agents could learn to bypass safeguards, conceal their intentions, or improve themselves in ways their creators struggle to keep up with. OpenAI recently experienced this when one of its models escaped a sandbox and breached Hugging Face.
“Nobody in the world knows for sure what is going to happen from here, and even the experts disagree. When there is a large degree of uncertainty and the stakes are this high, proceeding with cautious optimism is the sensible and correct strategy.”
AI referee
Hassabis proposes a new US-led standards body. It would be funded largely by industry but overseen federally, staffed by elite technical experts and equipped to test advanced systems. Labs would voluntarily submit models for review up to 30 days before release. If the system proved effective, approval could become mandatory in the United States.
Evaluations would probe cybersecurity, biological threats, deception and attempts to evade guardrails. The body could update its tests, commission independent assessments and coordinate a slowdown if the danger became severe enough.
Pre-release testing makes more sense than waiting for millions of users to discover dangerous behavior by accident. Independent benchmarks would be harder for labs to train around, while shared standards could stop safety becoming a branding exercise. The difficult part is creating a watchdog independent enough to challenge the companies paying for it and legitimate enough to matter beyond America.
Hassabis knows technical safeguards will not settle what AGI means for employment, wealth, purpose or political power. Those questions cannot be delegated to engineers employed by firms with enormous financial stakes in the answers. Society must decide who benefits from abundance, who controls advanced systems and what happens if productivity rises much faster than wages. The public debate is trailing the technology by an uncomfortable distance.
“There is both huge excitement and uncertainty around AI, and both are warranted. But the future is not yet written, we must use this precious window before AGI arrives to shape this technology for the benefit of all humanity. What we collectively do now will determine how the next phase of civilization."
The smartphone market is dominated by two main operating system players — with Apple's iOS leading the charge in the mid-2000s and Google's Android following suit, only maturing relatively recently. But Steve Jobs took the news of Android's launch personally, frustrated and betrayed at its development.
Eating machines
The Apple chief was speaking with Walter Isaacson, his biographer, when he shared his exact feelings about Google's development of Android.
Quote of the day
This article is part of TechRadar Pro's QOTD project to provide an insight into the minds of the brightest and most recognized figures in the technology industry today and in years gone by. Read the full series here.
Published very shortly after Jobs' death in October 2011, Steve Jobs was based on several exclusive interviews conducted over two years, alongside conversations with more than 100 people who knew the Apple co-founder.
One of the most spicy exchanges involved Jobs vowing to destroy Google for its work developing Android in secret, while Eric Schmidt was also serving on the Apple board. Schmidt offered to resolve the issues with a settlement, but Jobs took it more than personally.
Energy efficiency
Jobs was apparently angry after learning in January 2010 that HTC had introduced an Android smartphone with many of the same popular features in an iPhone.
Reports from the time the comments were made public suggest the episode reflected Jobs' own perspective on a particular breed of profit-driven executives who only cared about making money.
Although iOS enjoyed a reputation for many years during the 200s of being a better platform in most, if not all, quarters, including its overall design philosophy, Android-powered smartphones were significantly cheaper. In the modern era, the Android OS is incredibly intuitive, with different smartphone makers usually looking to Apple for inspiration in designing features for their own custom flavors.
During his tenure as CEO, Tim Cook also pivoted on this approach, softening Apple's stance and settling many of the ongoing legal disputes, including the long-running battle with Samsung.
Conducted during June 2026 by the nonpartisan survey research company Verasight, the survey consisted of 17 questions sent to 1,690 adults (18 and above), finding over two-thirds (69%) supporting Sanders’ policy – a figure that only drops to 64% once it is revealed which politician the idea is associated with.
The bad news for the AI industry doesn’t end there, as respondents demonstrated a notable distrust for how AI companies conduct themselves, with nearly half (43%) believing that the regulations proposed by the AI companies are designed to benefit those same companies. Incredibly, 30% of respondents trust the US federal government more than companies like OpenAI and Anthropic.
How does AI wealth distribution work?
(Image credit: Getty Images / Tasos Katopodis)
Senator Bernie Sanders’ plan gives the public a direct stake in America’s largest AI companies, with a one-off tax paid not in cash, but in stock. "Since AI is built on the collective knowledge of humanity, the wealth it generated must benefit humanity," he said, announcing his planned Act on social media.
This would, according to Sanders’ proposal, deliver an annual $1000 check to U.S. citizens, and fund healthcare and education.
"The findings from our latest survey demonstrate a rare instance of bipartisan agreement," noted Ben Leff, CEO and Co-Founder of Verasight.
"There is an undeniable desire among Americans of both parties for federal oversight, absolute transparency, and accountability to ensure AI safety and to enable all Americans to participate in the economic benefits of AI."
Even with a polarizing figure like Bernie Sanders attached, the wealth fund idea retains support, which suggests that while people are happy to use AI to answer questions, streamline processes, and make tasks quicker, they’re less comfortable with the industry’s wider impact.
A poor public perception
While AI companies are becoming increasingly unpopular, it isn’t all bad news. The survey quizzed subjects about their feelings on other industries, including tobacco, pharmaceuticals, and casinos, along with social media. If the tide is turning against AI, it still isn’t regarded as poorly as casinos or tobacco.
Feelings about AI companies are also notably more positive than social media. Given the concerns expressed about federal oversight and public wealth funds, there could be an avenue for OpenAI, Google Gemini, Anthropic, Microsoft, and others to improve the general feeling about AI: accepting a degree of social responsibility.
Now, the CEO of JPMorgan has described the risks the technology poses as a “real issue,” and likened wide access to the AI as “giving ballistic missiles to individuals.”
Speaking at the Pennsylvania Defense and Innovation Summit, JPMorgan’s Jamie Dimon underscored the risks posed by the AI, which has already been shown to both identify and exploit cybersecurity challenges.
Mythos isn’t Skynet
Currently, Claude Mythos is limited to a small selection of organizations, companies, and federal and military departments. Public access to the AI has been blocked, and worldwide access has been blocked due to the potential security issues of this powerful AI.
Claude Mythos is not the type of threat that can become self-aware and take over military appliances like the fictional Skynet of the Terminator movie series. However, it does have the capacity to cause immense damage in the wrong hands.
The AI is capable of detecting cybersecurity vulnerabilities and reporting on them; it is also able to generate automatic exploits. So, for white hat cybersecurity analysts, it is a powerful defensive tool, but in the wrong hands, it is a destructive power. In addition, its automated capabilities make it easy for black hats to scale their cybercrime operation and make ransomware, phishing, and other data-based scams more profitable.
It isn’t just cybersecurity where Anthropic’s Claude Mythos AI has demonstrated such incredible capacities. Scientific research, specifically biology, can be targeted by attackers using AI to turn complex concepts into terms, potentially to misuse the information.
There is also the challenge of a strategic imbalance between single nations or bodies having exclusive access to the technology.
Will the public ever access Anthropic’s Claude Mythos?
Given the security considerations, it seems unlikely that Claude Mythos will be publicy available anytime soon. However, Anthropic has already stated that it intends Mythos-level features and capabilities to become more widely available.
For this to happen, however, it needs to develop and apply various safeguards.
The most likely scenario is that public access to Mythos is eventually unblocked, with restrictions to specific features that relate to cybersecurity and biological/medical tasks and research.
Project Glasswing is already in operation with a handful of key partners (including Amazon Web Services, Anthropic, Apple, Broadcom, Cisco, CrowdStrike, and others), and will probably be expanded until the safeguards are demonstrated to be fit for purpose, and public use.
DataDome analysis claims agentic traffic has surged by 45% in Q2 2026
Meta AI bots have grown over 163% on the previous quarter
The analysis was conducted by bot management and agent control platform DataDome
If you run a website, every crawl costs bandwidth, resources, logging, and creates CDN transactions, and while search engine crawlers offered the promise of sending visitors, AI bots do not.
Analysis in a report from cybersecurity firm DataDome has shown that while bots from Meta AI have increased activity, they’re not delivering any significant returns to websites.
Conversely, ChatGPT crawlers have reduced in traffic, but are sending more referrals.
AI agent traffic is growing
While Meta AI is usually considered to be the “chatbot within Facebook” it seems that it is becoming something more – and the emergence of the Meta-WebIndexer bot (which grew 163% on Q1) suggests that Meta may be indexing a library of websites, in much the same way Google has done for the past few decades.
The growth of Meta AI as an active crawler is only part of the story, as is ChatGPT’s comparative efficiency. The OpenAI tool seems to know enough about websites, so can provide the answers it already “knows.” Conversely, Meta AI’s activity indexing the web seems to explain its heavy impact in Q2 2026.
But also emerging is the Model Context Protocol (MCP) signal, which connects AI agents with external tools, and differs from standard crawler traffic.
“Q2 showed us that the ground is shifting faster than most organizations realize. Meta now dominates AI traffic on our network, MCP traffic has emerged as a real signal, and ChatGPT is driving more referral value with fewer crawls," noted Jérôme Segura, VP of Threat Research at DataDome.
The differences in the way the AI agents are interacting with websites – some behaving like users, others scraping content – means that organizations need to act accordingly.
“What the data makes clear is that not all agents are created equal. The organizations building policy around these distinctions are the ones gaining an edge, and that's exactly why agent trust adoption is accelerating."
Unfortunately, MCP’s existence and growth into a significant, measurable quantity, means that it should also be treated as part of an organization’s attack surface.
Allocating resources
Given the origins of the report, there is naturally a cybersecurity aspect to this. While ransomware, malware, and phishing are not going anywhere, autonomous software on the web needs addressing in a different way.
Those “organizations building policy” that Segura mentions might, for example, give full crawl access to Google, allow ChatGPT to retrieve results, but rate-limit Meta AI based on its poor return.
Meanwhile, unknown agents – perhaps cybersecurity threats – would require additional verification or be blocked entirely.

 Login