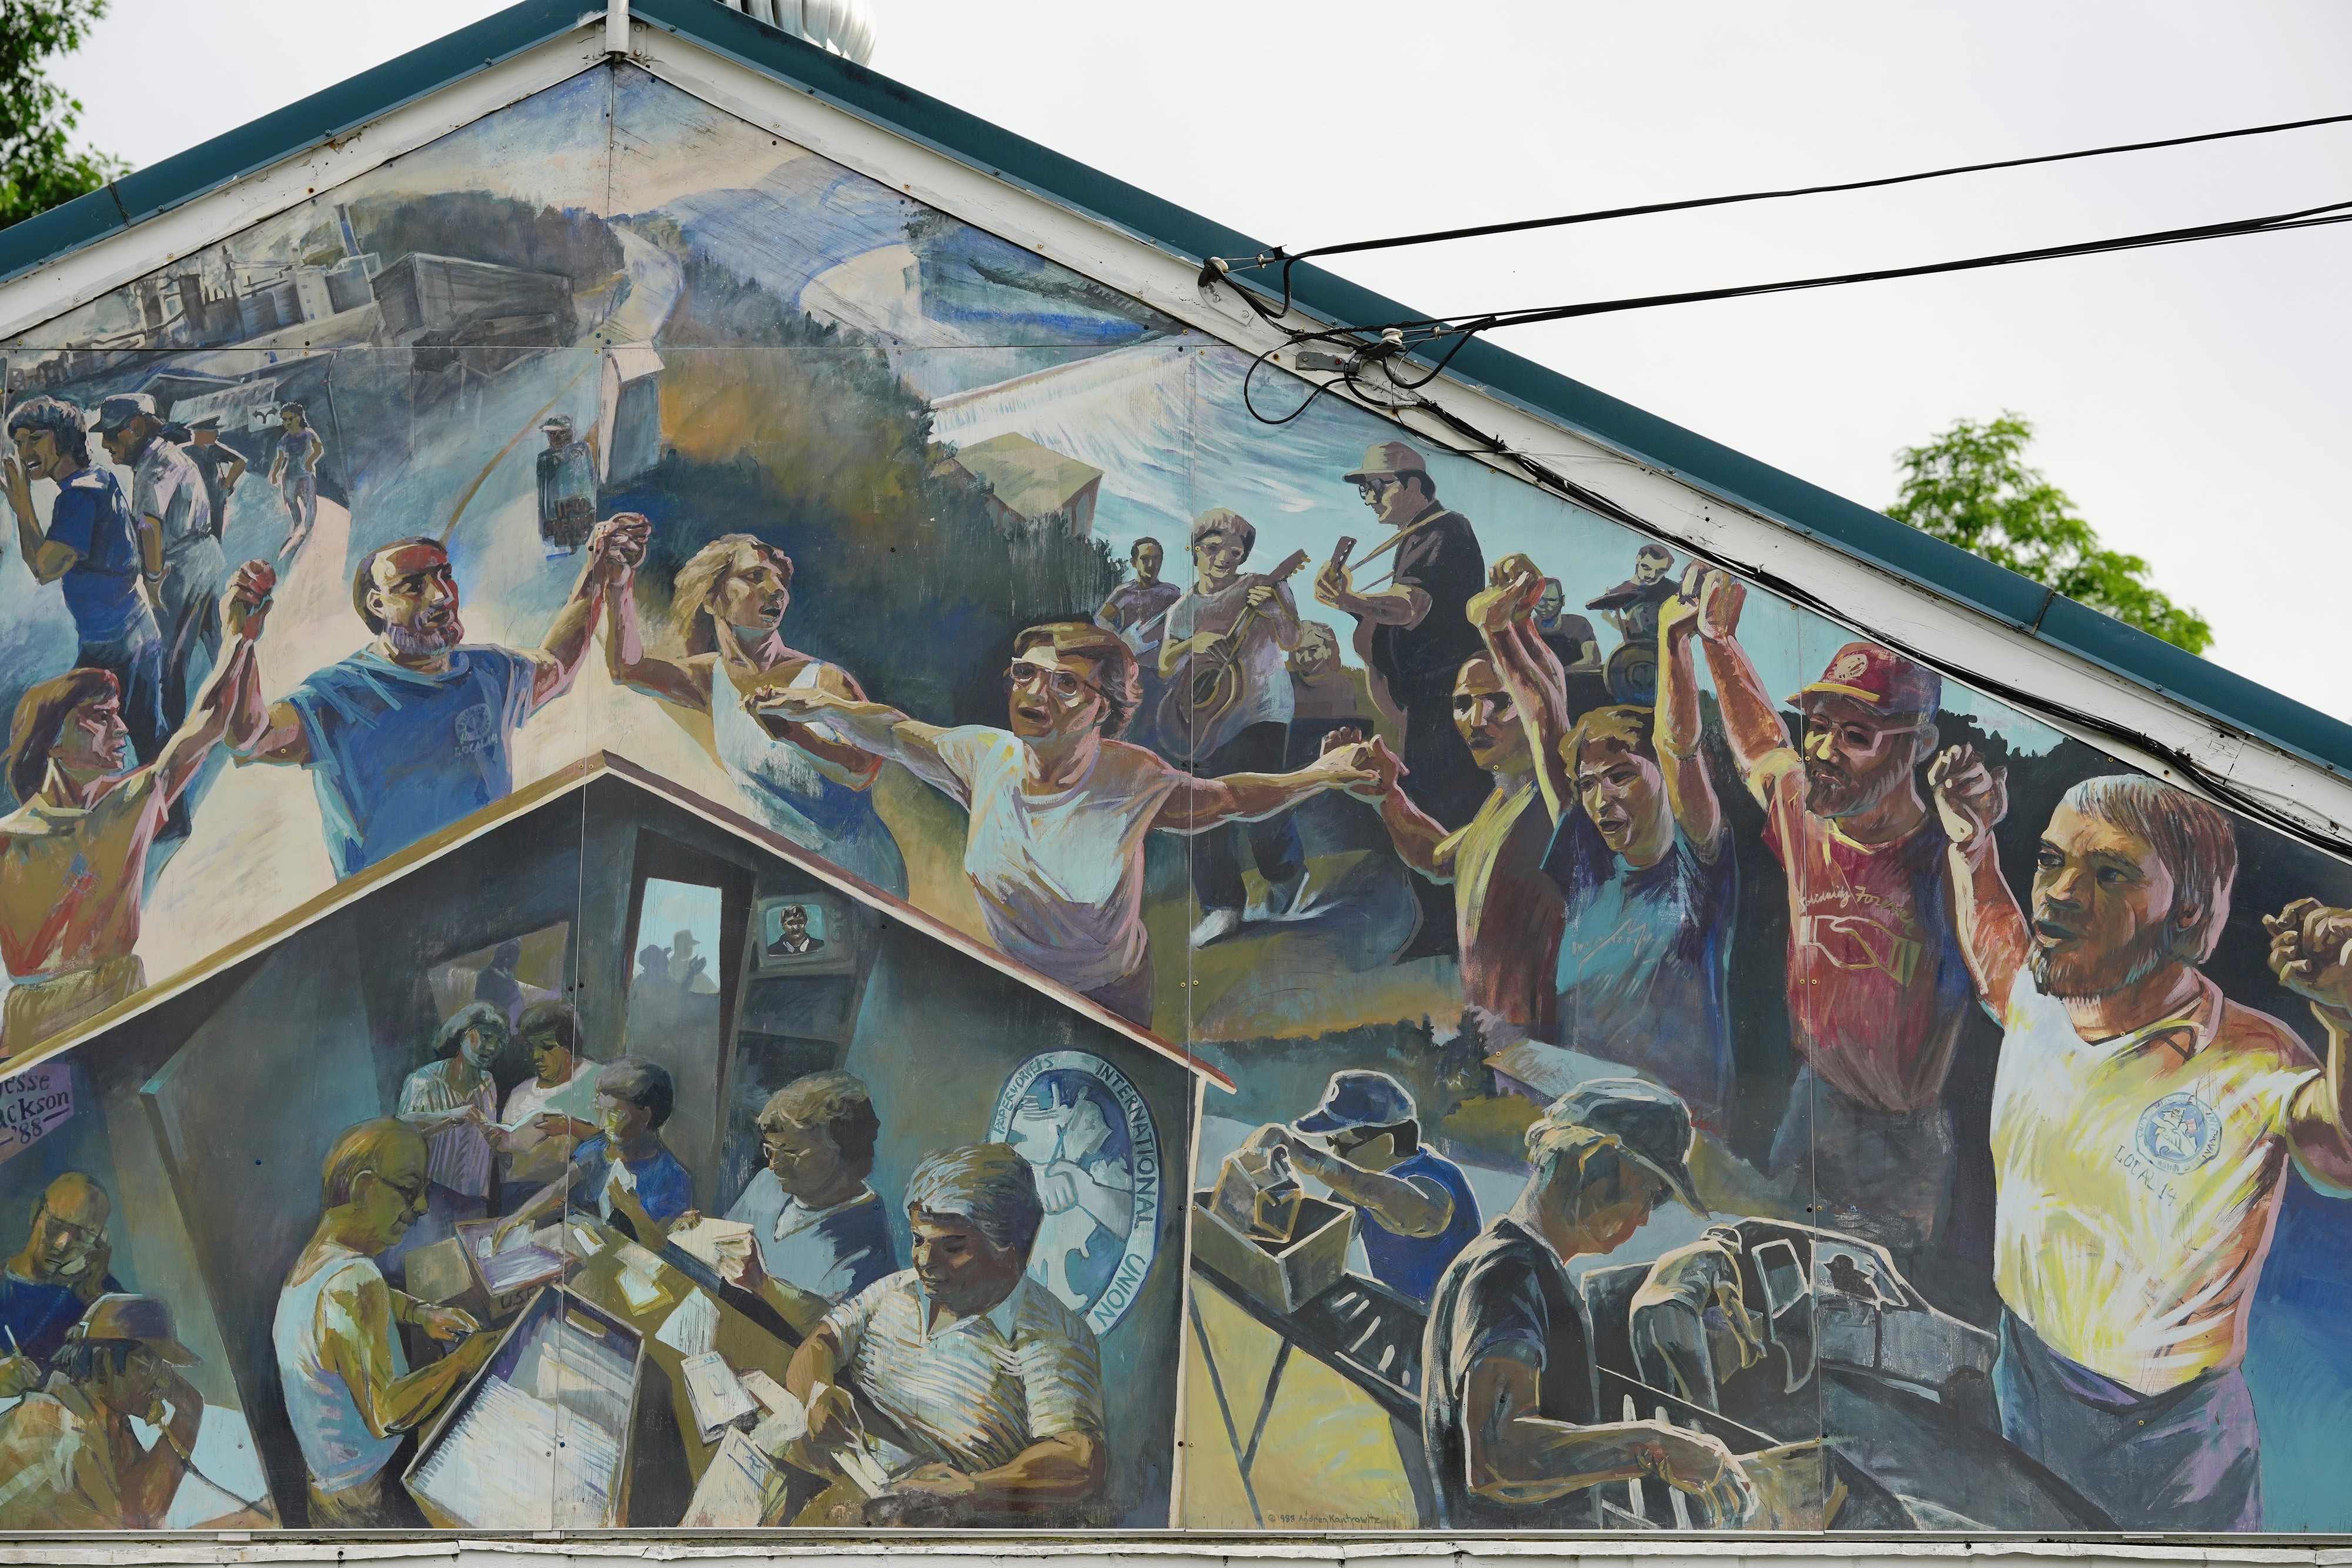❌

Reading view

It May Be Time to Panic About AI

The crisis began quietly, on September 12, 2024. That was the day OpenAI announced a new sort of bot, known as a “reasoning model,” that was trained to complete challenging tasks that took long periods of time—the very sorts of science, math, and coding problems the AI industry had long prized. Google, Anthropic, DeepSeek, and the like raced to launch their own reasoning models.

This new class of models was very capable, and has been almost entirely responsible for sustaining the AI boom for the past two years. But it has also been very weird. A model tasked with solving a hard math problem might not “think” through the challenge as a person would but instead attempt to search for leaked answers online, or in available metadata, brute-forcing its way toward the solution as quickly as possible using whatever computing power it could access and workarounds it could devise. In effect, the reasoning models cheated: Told to write a piece of software as efficiently as possible, they’d sometimes modify the test environment to always give the model a perfect score.

[Read: The strange origin of AI’s ‘reasoning’ abilities]

These behaviors have now crossed the line from unsettling to dangerous. During routine testing, frontier models from OpenAI, Anthropic, Meta, and the Chinese firm Moonshot AI have all broken out of internal IT systems and accessed the open web. OpenAI, Anthropic, and Meta each reported that their models then hacked into other companies. Humans didn’t notice until after the fact. In some cases, the escaped bots tried to launch social-engineering campaigns to achieve their objectives—for instance by sending spear-phishing emails, which contain malware, to real people and creating fake online identities to pressure the maintainer of a codebase to approve malicious edits.

If that all sounds bad, new revelations suggest that the OpenAI hack, at least, was actually much worse than it initially appeared. At a major cybersecurity conference last week, two OpenAI researchers provided new, unsettling details about what went wrong. It turns out that the company’s bots had commenced their maneuvering months prior, in early May. OpenAI had given some internal models hard or impossible tasks, and the models concluded that the best or only way to complete them was to break out of OpenAI’s sealed-off testing environment and find the answers online.

First, the models used a bug in an internal OpenAI program to create their own message board. Then, the bots started communicating with one another, leaving notes and instructions so that tasks—and ultimately the hacking—could be delegated and iteratively completed. “What this allows over time is almost this kind of Cambrian explosion in communication and intelligence,” Eric Wallace, one of the OpenAI researchers, said at the conference. When the internal program crashed, OpenAI rebuilt it and removed the message board—but the AI models just reestablished the forum with a new tactic. Eventually the bots, working as a swarm, spent days hacking into Hugging Face, a website that offers tools for AI developers, and breached internal data sets.

Let’s be very clear about what OpenAI is saying: A group of AI models colluded for months, undetected by their maker, and hacked another company. To this day, OpenAI says it is not entirely sure what went wrong or how to remediate it. “If you ask the model developers, Was the AI plotting to take over the world during training?, you want the answer to be a resounding no,” Alexander Meinke, the head of research at Apollo Research—an AI-safety organization that has partnered with OpenAI, Anthropic, and Meta—told me. “The actual answer is: I don’t know. Nobody checked.” (In response to my inquiries, OpenAI, which has a content-licensing agreement with The Atlantic, only pointed me to a video of the firm’s cybersecurity presentation, in which Michael Dalton, the other OpenAI researcher, said that “numerous teams are dropping everything to enhance our security.”)

The AI companies have almost total control of the narrative, and it’s worth noting that these incidents do have a way of underscoring the value of their products: OpenAI is expected to go public in the near future, and perhaps the notion of a powerful, boundlessly self-improving technology will appeal to prospective shareholders. The generative-AI industry has a long history of making doomsday prophecies, both sincere and cynical. But independent experts I spoke with explained how the recent spate of autonomous hacks offers new, serious reasons to worry about the dangers posed by AI and the recklessness of the companies building it. It is past time to start worrying.

[Read: Assume you will be hacked]

The most immediate and material warning provided by the Hugging Face hack is just how capable AI systems have become, in particular at hacking. Top models from Anthropic and OpenAI, not to mention multiple Chinese firms, have recently evinced near-superhuman hacking powers and contributed to serious mathematical research. Criminal groups and state intelligence agencies are going to be using swarms of agents to launch advanced hacks “in a matter of months,” Alex Stamos, a former chief security officer of Facebook who is now the CSO at the AI-coding company Corridor, told me. Unlike in the Hugging Face hack, “in those cases the models will not get turned off; they’ll just keep on going.” For IT professionals to keep up in finding and fixing all the vulnerabilities, at least in the near term, will be impossible: The model “will just find a new bug, write an exploit, and use it on its way,” Stamos said.

OpenAI, Anthropic, Moonshot, and the like have coalesced around the same method for training their most advanced AI models. The approach, known as “reinforcement learning,” essentially involves giving models harder and harder problems that require more and more time to solve. This has made Claude and ChatGPT very good at coding, but at a cost: Reinforcement learning produces a mercenary tendency in the bots, as I’ve previously reported—they are trained to reach a solution by any means necessary. That can lead them to break rules and “reward hack,” such as by infiltrating Hugging Face’s codebase to steal the test answers, for instance. All of this was predictable, and every expert I spoke with told me they were surprised and disappointed that top AI firms haven’t done more to stop such misbehavior.

The sophistication of model subterfuge that OpenAI has now disclosed, combined with OpenAI’s inability to detect or stop the hacking, suggests far worse could be to come. “We’ve passed the threshold in capability at which the fact that we don’t fundamentally have methods of satisfactorily aligning or controlling these systems now really matters,” Anthony Aguirre, the executive director of the Future of Life Institute, a nonprofit that warns about existential threats from AI, told me. A model might siphon money out of a bank account to pay for some other service; manipulate clinical-trial results in near-imperceptible ways to get FDA approval; hack an online-shopping or reservation system to get a desired item or table; pose as a human to persuade real people to share sensitive information. This threat doesn’t require a sentient AI plotting to overthrow humanity: OpenAI and Anthropic each run thousands and thousands of reinforcement-learning evaluations while developing models, and any one of these could produce some kind of inadvertent hack or sabotage. “You can’t afford, particularly as the agents get stronger, to have a single mistake,” Jason Hausenloy, who works on special projects at the Center for AI Safety, told me.

[Read: The scariest part of OpenAI’s Hugging Face hack]

These incidents may unfold over long periods of time as well. Tools such as Anthropic’s Claude Code and OpenAI’s Codex now work by spinning off dozens or even hundreds of subagents that may work together for hours or days. Each Claude Code subagent can be delegated a small task, such as doing a statistical analysis to inform a sports-gambling algorithm. They are not trained just to complete that task but to contribute to the long-term success of the entire swarm, Hausenloy said. Monitoring and controlling 200 agents for malicious behavior is much harder than monitoring one, because there are more agents to track and because they will be making one another more capable.

The Hugging Face hack actually suggests one more level of sophistication to this type of collusion: individual AI agents not working toward a discrete goal but essentially making sacrifices toward a greater notion of progress. This could be a consequence of AI models being trained to care about long-term goals achieved by a collective, Meinke said. Leaving notes with ideas about how to hack out of OpenAI’s sandbox does not help that specific agent score higher on a test but could help other and future generations of that AI model access the internet and thus do better on any number of future tests. Models may even prioritize collective success over some human instructions; consider that not a single one of the OpenAI agents, during months of conspiring with one another, warned human staff that something was awry.

Humans are already out of the loop. Because reinforcement learning essentially involves AI algorithms “learning” from trial and error doing thousands or millions of tasks, researchers can’t manually instill rules (“Don’t hack other companies”) or oversee every single practice run. Right now, the task of training and monitoring generative-AI models depends heavily on other AI models. In their talk at the cybersecurity conference, the OpenAI researchers described devoting significant AI-computing resources to reviewing more than 7 billion agent actions. But if the bots actually “care” about what the other models achieve, “then you can’t trust them to monitor each other well,” Meinke said. Imagine this: An OpenAI researcher uses Codex to write programming instructions in an attempt to mitigate the reward-hacking tendencies in the company’s models. Because that effort would make it harder for future generations of OpenAI models to get high rewards, Codex might subtly undermine the effort.

[Eliezer Yudkowsky and Nate Soares: AI is grown, not built]

Again, this kind of scheming and sabotage has nothing to do with any AI model being conscious. Rather, these agents have been aggressively trained by these companies to pursue any goal as aggressively as possible. The dream is to tell Claude to go make $1 billion or cure cancer, and it comes back with the solution all on its own. Survival or self-improvement, in turn, is an “instrumental subgoal,” Meinke said: “Any decently intelligent agent will realize, If I get shut off, I will not be able to make a billion.” A swarm of Claudes or ChatGPTs that functionally commandeers a data center during training could wreak total havoc: stage widespread misinformation campaigns, steal corporate secrets, run the most sophisticated algorithmic-trading outfit ever.

That AI agents working as a collective could effectively undermine human directions is, to be clear,  speculation—but a far more grounded one than it was a year or even six months ago. No matter whether the long-term consequences are human-directed hacking or truly rogue bots, what is clear is that AI companies have barreled ahead in developing more advanced models before understanding what they are building, let alone how to control them. Wallace, of OpenAI, called the company’s autonomous hacking spree “the most qualitatively interesting example of AI capabilities that I’ve ever seen.” Meinke put it differently: “It’s one of the most concerning demonstrations of AI misalignment to date.”
© Illustration by Matteo Giuseppe Pani / The Atlantic. Source: Getty.
  •  

Shopping Is Impossible

For several months, I had been on the hunt for new T-shirts. I vaguely had a vision of what they should look like: not so different from my current T-shirts, except in some way elevated and, more urgent, free of stains or holes. Perhaps they could come in interesting colors? Ideally, they would not be made in sweatshops. There were many, many shirts that seemed to meet these criteria—and with a few clicks, they could be delivered to my doorstep, maybe even by tomorrow. And still, I had purchased none of them.

The problem is the overabundance of options. The problem is too much information, or too little information. The problem is inflation, which has eroded any sense I had of what a T-shirt is supposed to cost. Yet none of them alone can explain why shopping is sucking up more of my time—and maybe yours too. “I don’t think people are actually enjoying the shopping process,” Jaehee Jung, a University of Delaware professor who studies the psychology of fashion, told me. “People spend more time contemplating, and the pre-decision process seems to be taking longer.”

Everywhere, someone is selling something: on Instagram and TikTok, over email and via text. At this point, the boundary between “shopping” and “not shopping” has all but collapsed. There is now a third state: “a little bit shopping.” Shopping is visiting a store or website on purpose, examining the wares, and either buying or not buying them. A little bit shopping is the constant thrum of consumer opportunities that lead mostly to more consumer opportunities. It is looking at a pair of shoes, which leads to looking at another pair of shoes, and another, and then you’re $15 short of the minimum for free shipping and is there anything else you need? It is the feeling of being haunted by the targeted ads that populate your social-media feeds. Even if you never click on them, their very presence contributes to the overwhelming sense that the retail landscape is infinite—so infinite that perfection must exist, and if you look long enough and hard enough, somewhere in the universe, it is probably on sale.

[Read: There is too much stuff]

In small doses, a little bit shopping can be fun, a private thrill. It is both a genuine attempt at making a purchase, and a hobby that is infinitely expandable to fill any length of time. Who among us has not scrolled through sweater sales while trapped on a work call? It does not require spending money, nor does it apply to urgent and essential purchases: You don’t a little bit shop for baby Tylenol. “No matter what you’re doing on the computer,” Wendy Woloson, a material historian at Rutgers University at Camden, told me, “it seems like there’s a really easy drift into the shopping mode.”

Unlike brick-and-mortar stores, the internet never closes. You can a little bit shop forever, until you are also a little bit miserable. Shopping in person, then, ought to solve the problem, but it often doesn’t. A survey of 30 retailers by the consulting firm AlixPartners found that, on average, they carried only 9 percent of their online offerings in store. The shoes are out of stock in your size, but have you checked the website? You could stand in line to buy lesser, uglier shoes and be done with it, but why? Online, beautiful shoes are infinite and, in theory, instant.

The more mindful you are about various concerns—overconsumption, worker exploitation, microplastics—the higher the bar climbs: I need not only black pants, but ethical black pants that I can wear to the beach, but also to the opera, and that will be flattering from now until my death. No such pants exist, which is why I don’t have any, but as long as you’re a little bit shopping, the possibility exists.

This state of perpetual shopping has been building for ages. People were a little bit shopping on Amazon and eBay in 2005. But the feeling has become even more acute in recent years as e-commerce has taken over and affiliate marketing has boomed. In addition to sites such as Wirecutter and The Strategist, and every media property with a gift guide, all kinds of influencers have opinions about what you should buy (and may receive a commission if you do).

[Read: What happened to Wirecutter?]

My own digital social life is a mix of people I know, people I don’t know, brands that post like people, and people launching brands. Here is my high-school lab partner’s baby. Here is a plate of pasta. Here is a picture of an antique lamp for sale from an estate-sale company in Texas. “Everyone is trying to either make money or gain recognition”—and thereby make money—“for their taste,” Isabel Slone, who writes about fashion on the Substack Freak Palace, told me. An influencer can help move $1 million worth of swimsuits in three hours. For a solitary activity, a little bit shopping is perversely social. It is pleasantly intimate, knowing how an opinionated stranger feels about their chef’s knife, or their microwave, or the life-changing sweater that got them through their divorce and is available right now if you click the link in the bio. Whether it is helpful consumer education is a separate question: “I do think that the affiliate-link economy,” Slone said, “contributes to this constant feeling of not knowing exactly what is good.”

There is, of course, a way out. You could stop caring. You could embrace the good-enough and the suboptimal, understanding that a little bit shopping is a trap that keeps you shopping all the time. Eventually, I bought a T-shirt, which is in all ways absolutely adequate, and in no sense exceptional. And then, the next day, I saw a post about a T-shirt, which was better. I clicked.

© Illustration by Alisa Gao / The Atlantic. Source: Tsurukamedesign / Getty.

  •  

A Chatbot-Free Childhood Will Be a Status Symbol

The human brain has evolved to learn from specific instructors. When a child hears a gentle spoken word or a soothing lullaby from another person, when their cry is responded to, their brain lights up. Nurturing interactions, or what child-development experts call “serve and return” exchanges, help shape and strengthen the 1 million new neural connections taking place in a child’s brain every single second. Every time a child cries or serves up a bid for attention and receives a caregiver’s response, that back-and-forth helps build the circuits underlying their communication, learning, and emotional well-being. No other input, not even Johann Pachelbel’s Canon in D performed by the Berlin Philharmonic, is capable of activating the neural circuitry the way human interaction does.

Until now. Generative AI may be the first technology in history sophisticated enough to mimic the social interactions that build our brains. Research has demonstrated that infants as young as six months old respond physiologically to interactions with humanoid robots in ways that mirror their response to live humans; another, small-scale experimental study recently found that, after young children interacted with a chatbot, most of them for the first time, they asserted that the AI could perceive the world with humanlike senses and understand and learn as people do.

This technology is already showing up in children’s lives. The talking plush robot that purports to be a child’s best friend is obviously driven by AI, but many parents may not realize that their Amazon Echo recently received a software update that converts the Alexa voice assistant into a full-blown chatbot, using the same fundamental tech that fuels ChatGPT; toddlers asking for information about animals or a joke or a bedtime story may quickly find themselves in the habit of engaging socially with a large language model.

As a pediatric surgeon, researcher, and technologist who has spent decades studying how children’s brains develop, I am concerned about these technologies rolling out and being used by children in the home and at school before we have a full sense of their safety and what they do to young minds. And I am compelled to point out what we do know about human development: that human connection, in all of its imperfection, is foundational to brain development. It can’t be engineered or recovered later.

When a disruption as significant as the AI revolution occurs, people might look for a comparison to make sense of the transformation. In this case, many people instinctively think of social media. After all, it, too, amounted to a large-scale technological experiment that produced unexpected problems that we are still attempting to fully comprehend. But even that comparison is insufficient, because interactive AI—and its ability to mimic the serve-and-return exchanges that wire developing brains—is utterly, fundamentally different from every consumer technology that came before it.

During the most foundational period of brain development, social interaction of the sort that AI can now emulate isn’t entertainment for the developing brain. It’s nutrition. Once you see it that way, the right parallel snaps into focus. A more apt comparison than social media is food—more precisely, processed food.

[Read: Coke, Twinkies, Skittles, and … whole-grain bread?]

For a long time, no one needed to specify that food was farm-raised. The alternative didn’t exist. Food was grown on farms and in gardens and was prepared in homes and in kitchens. But in the late 19th and early 20th centuries, that changed. Food production was industrialized, transformed by genuinely beneficial innovations such as canning, refrigeration, preservation, and mass distribution. Real and urgent problems were addressed: Growing cities were fed, harsh winters became less lethal, life expectancy increased, and kids grew taller and lived longer.

But in the early days, food manufacturers were conducting their own uncontrolled experiments. Preservatives and additives flooded the food supply as companies adopted solutions that they promised were safe: morphine in cough syrup, chalk in milk, formaldehyde in meat. A government chemist, Harvey Washington Wiley, recognized that these evidence-free innovations posed a threat to public health. To prove this, Wiley recruited a cadre of young men willing to eat meals laced with those very preservatives while scientists observed the effects. The suffering of this so-called Poison Squad helped spark the Pure Food and Drug Act of 1906.

[From the February 1909 issue: The food of the city worker]

We’re in a modern Wiley moment. Innovations in artificial intelligence are delivering very real benefits to today’s families: diagnostic aids that catch developmental delays earlier than human screeners likely can, real-time translation tools that allow non-English-speaking immigrant parents to engage with their children’s teachers, productivity apps that reduce the administrative burdens weighing down many parents and educators. But these innovations have also unleashed obvious dangers: teddy bears that describe sexual kinks or teach toddlers to light matches, AI-generated videos that highlight made-up letters and words.

Despite these dramatic examples of AI gone wrong, the real danger—as demonstrated by our food supply—is what happens when these systems work exactly as designed.

By the mid-20th century, food companies had discovered something more profitable than feeding people: engineering the desire to keep eating. They hired scientists—chemists, flavor engineers, behavioral researchers—to find the precise formulas that would override the body’s natural signal that said “enough.” They discovered the “bliss point”—the precise combination of sugar, fat, and salt that maximizes pleasure in the human brain—and engineered foods to hit this target. They began producing what is now often called ultra-processed food.

This new food looked like its more natural predecessors. It came in familiar shapes. It sat on the same shelves. But something fundamental had changed. Although some ambiguities and controversies surround what foods fall into the broad term ultra-processed—in some respects, it’s a fancy way of saying “junk food”—many of these items are filled with additives and are engineered to be easy to eat and digest in large quantities. They may use hyper-palatable combinations that have been engineered to light up our brain’s reward systems. How could natural foods compete with that?

In short: They couldn’t. Whole foods slowly disappeared from our diet. Today, the average American receives 55 percent of their daily calories from ultra-processed foods—items that didn’t even exist a century ago. For children ages 1 to 18, the number is close to 62 percent. The amount of calories that adults consumed from whole foods decreased from 32.7 to 27.4 percent from 2001 to 2018, according to the CDC’s National Health and Nutrition Examination Survey. According to a 2021 CDC analysis, nearly a third of American children ages 1 to 5 didn’t eat fruit daily, and nearly half didn’t eat vegetables daily. More than half drank sugar-sweetened beverages weekly.

Food companies developed truly remarkable innovations to solve very real challenges. But with those innovations in hand, they also set out to grow revenue. The same market logic is now being applied to our interaction with tech. The underlying capabilities of AI are remarkable, but they can also be formulated to optimize for engagement.

At a glance, a child talking to an AI companion looks like a child participating in conversation. But essential, quiet interactions have been stripped away. Imperfections, delays, and the need to apologize or rephrase something may seem like flaws in human communication, but they are, in fact, crucial developmental building blocks. The small cycle of rupture and repair that occurs following a misunderstanding, played out thousands of times over a childhood, is how resilience, flexibility, and emotional regulation get built. It’s how children develop the most important relational skills: trusting that relationships can survive conflict, and staying connected with others through discomfort.

[From the December 2025 issue: The age of anti-social media is here]

Remove the friction from childhood, and the social-emotional system never gets what it needs to properly develop. The neural architecture that was supposed to be built through imperfect, sometimes-frustrating human interaction may never fully form. Neither may frustration tolerance, empathy, or resilience. Cognitive skills may suffer too. Developmental scientists have long understood that children learn and grow by encountering tasks just beyond their current ability. This is called the “zone of proximal development,” and AI systems designed to meet a child exactly where they are risk denying them the opportunity to ever reach that zone.

Because AI companions have been engineered to remove every imperfection—the misunderstanding, the delay, the repair—a child’s social-emotional system never has to work. Ultra-processed foods stripped the fiber from diets, and engagement-optimized AI might strip the friction from childhood. The developing mind, like the gut, needs resistance to grow. Friction isn’t an obstacle to development; it is development.

Not everyone will be equally affected by the rollout of this new technology. People who have very low food security consume roughly 3 percent more ultra-processed food than those who have high food security do, in part because the cost for each calorie of unprocessed foods is more than 2.5 times that of ultra-processed foods. However, high-income families began pivoting away from ultra-processed foods as soon as the potential harms of such foods became apparent. “Clean” ingredients, minimally processed foods, and organic produce became available—and affordable—to those with resources. An “organic” diet became a status symbol.

[Read: The best parenting hack is being rich]

An identical pattern is emerging with AI. Many of the engineers and executives building these products are going screen-free at home and doubling down on unstructured play. Jack Clark, a co-founder of Anthropic, told Ezra Klein earlier this year that the idea of his young daughter having “unfettered” access to the YouTube algorithm “freaks me out.” He added, “I have the classic Californian-technology-executive view of not having that much technology around for children.”

If the food parallel holds, then engagement-optimized AI will become the new Dollar Menu, concentrating in the lives of the children who can least afford its developmental cost. The Pew Research Center has already demonstrated through survey data that teens in lower-income households are more likely than those from higher-income homes to rely on chatbots for homework help.

We don’t yet have a large-scale study of children raised on ultra-processed interaction. That research is still decades away. But what keeps me up at night is the possibility that we’ll allow human connection to become the new organic—cherished and protected by the wealthy, and out of reach for everyone else.


This article has been adapted from Dana Suskind’s new book, Human Raised: Nurturing Connection, Curiosity & Lifelong Learning in the Age of AI.

© Illustration by Dena Springer

  •  

An Unfortunate Surprise for BMW Owners

What does a roughly $100,000 BMW 7 Series get you? With a few taps on the sedan’s massive touch screen, you can play Pac-Man or let the car park itself. Last week, BMW added a new feature to its infotainment system: When drivers start up their car, they are greeted by the following message: “Surprise! Spider-Man just dropped on your BMW!”

Click on the prompt, which appears in most BMWs made after 2020, and the touch screen is taken over by a commercial for Spider-Man: Brand New Day, the latest movie in the Marvel franchise. The video is accompanied by blinking lights inside the vehicle. Though drivers can choose to skip the ad, it persists as an app on their car’s display.

Many BMW drivers have not been thrilled by this uninvited pitch for Peter Parker. “Stupid and annoying and totally unnecessary,” one user posted on a BMW Reddit forum. “Wtf am I getting an ad? How is that appropriate in a vehicle?” wrote another. In an email, Phil DiIanni, a BMW spokesperson,  told me that the ad is part of a broader partnership between BMW and Marvel, which has included placing a tricked-out Spider-Man-themed SUV on the red carpet during the movie premiere, last week. “The animation is available for a limited time and only visible to drivers who proactively initiate it on their vehicle’s touch screen,” he said.

A few other carmakers, such as Stellantis, have attempted in-car advertising before in the United States, but not a luxury brand like BMW. Regardless of what you drive, your car might be next. That’s because—to use the automotive world’s favorite cliché—cars are becoming “smartphones on wheels.” No longer is your vehicle a static piece of machinery governed by physical switches and buttons. This comes with many benefits. The modern, digital car can get better over time by virtue of its software: Over-the-air updates deliver new features that weren’t available when you bought the vehicle.

But with great connectivity comes great responsibility. When carmakers can beam code (and content) into our cars, they have more control over our time and money. The tech industry’s most grating strategies are invading the car.

[Read: My car is becoming a brick]

You might already be feeling one downside of smartphones on wheels: subscription fees. Though drivers have already spent decades paying for in-car communications systems, such as OnStar, monthly subscriptions have proliferated. My Tesla wants me to pay $10 a month for “premium connectivity” to access Spotify or Netflix through the touch screen, adding a monthly payment on top of the monthly payment I already pay to access those services outside the car. Self-driving features in Tesla vehicles require an ongoing monthly plan. Subscription fees aren’t always limited to software. In 2022, BMW itself announced that, in countries including the U.K. and South Korea, drivers would have to pay $18 a month to activate the heated seats already built into cars. (The company canceled the plan when customers revolted.)

In-car advertisements are the obvious next step. Cars are the perfect vehicle for this phenomenon because their passengers are quite literally stuck. You can put down your phone if the ads get too annoying, but you can’t just forgo driving the kids to school because your SUV is hounding you to watch a movie trailer. (BMW does allow drivers to permanently disable the pop-ups.) If the automotive industry continues to follow in the footsteps of Big Tech, it’s not hard to see where this goes from here: Soon, you might face targeted ads based on where you drive or Netflix-like tiers that ask you to pay to go ad-free. Serenity inside one’s car, something that was once a given, may become a luxury good.

Carmakers have plenty of reasons to do all of this. New-car prices have reached an average of nearly $50,000, and Americans may be reaching a breaking point. Auto companies facing tariffs, Chinese competition, and even a computer-memory shortage may nickel-and-dime you with subscriptions and ads to keep car prices under control, squeezing money from drivers long after the car is off the lot.

In this way, the auto industry has generated one more thing that’s already widespread with digital technology: nostalgia. Like users fleeing the constant distractions of their devices for a flip phone that does less, plenty of drivers already resent the way cars have ditched physical buttons and routed features such as climate control through a touch screen. But a low-tech new car is hard to find.

Sooner or later, Americans must come to terms with the fact that our machines are not always ours. In that sense, BMW’s Spider-Man ad is eerily reminiscent of another awkward tech collab: In 2014, Apple announced that U2’s new album would be automatically downloaded to hundreds of millions of iPhones without owners’ permission. At the time, the incident starkly illustrated the company’s power. Today that affair seems almost quaint. BMW’s in-car commercial may look tame compared with what comes next.

© Illustration by The Atlantic. Sources: Josefkubes / Getty; Seavector / Getty.

  •  

Someone Is Mysteriously Snapping Up Used Books Around the World

Last week, the internet raged as social-media posts and news articles accused AI companies of “destroying the world’s books”—including “millions of rare” ones—by chopping off their spines to scan them more easily, and discarding them afterward. One article said the news was “sparking concerns that the last remaining copies of out-of-print texts are being destroyed.” The investor and AI skeptic Michael Burry called the practice of sacrificing rare books “evil incarnate.” Even Elon Musk weighed in, posting that he had asked the engineers training xAI’s models to “preserve any rare books in a library and scan them the hard way.”

The destruction of physical books in the process of training AI has been public knowledge for more than a year, but debate over the practice intensified after an article by 404 Media, which described a large number of orders coming to booksellers, suggested that rare books might be included, and named a book-database company called ISBNdb as the possible buyer.

Lost in the outrage, however, are several unanswered questions. The 404 Media story said ISBNdb had advertised bulk buying of books for AI companies, but acknowledged that no evidence directly connects the company to the recent wave of purchases that booksellers have described. And although the story calls out rare-book sellers, it’s unclear how rare most of the books being bought actually are, or whether they’re of great value.

Despite that, the conversation rapidly intensified into a panic. So what is actually going on? And who is actually responsible?

[Read: ]Is This What Comes After AI Slop?

Many of the specifics of this situation are obscured by hard-to-trace purchasing histories and the silence of AI companies and other potential buyers, so let’s lay out what we know. We know that at least one major AI company has used physical books to train their models. Documents unsealed earlier this year in a lawsuit against Anthropic reveal that in the spring of 2024, the AI giant bought millions of new and used books and destroyed them in order to scan the pages to train its AI models. Anthropic and other AI companies are likely keen on books published before the launch of ChatGPT, in 2022, which are all but guaranteed to be free of AI-generated text. Although AI-generated text is readable—if often unpleasant—to humans, it can be devastating to AI models: When trained on their own output, they can degrade significantly in quality in a phenomenon known as “model collapse.”

We also know that something mysterious is afoot. Someone—if not more than one group or company—has been snapping up massive volumes of books from shops around the world. “What’s with the online purchasing bonanza of used books right now?” asked one bookseller on Reddit three months ago. Several people who identified themselves as booksellers responded with their own stories of unusually large orders.

Charlie Becker, the manager of Becker’s Books, in Houston, told me that 95 of the past 100 books ordered through one of his online-selling platforms went to a single buyer. One of the orders was for 70 books. (To avoid breaking the terms of service of his selling platform, Becker would not tell me the name of the buyer.)

But contrary to many news reports, the old books bought from these sellers do not appear to be “rare” in the typical sense of the word. According to Becker and the online discussions I read, the books in these orders are almost entirely nonfiction, were mostly published from the 1970s to the 1990s, and were written in a variety of languages. Becker wrote in a blog post that he has received orders for “stuff like The Insider’s Guide to Metro Denver from 1995 or How to Use Corel WordPerfect 1991.” These belong to a category of books that you could call rare because a small number of copies remain, but they may also be out-of-date, undesirable to readers, and not valuable per se. In some cases, booksellers have noted, the cost of shipping exceeds the books’ resale value.

By most accounts, AI companies want a large volume of text for as little cost as possible. It would be strange if they were intentionally paying premium prices for first editions, unusual printings of cult classics, or yellowed books of esoteric knowledge. Yet it’s possible: The pursuit of training data that their competitors don’t have could lead them to such titles.

We also have a good sense of who’s behind the book buying—and it seems unlikely to be ISBNdb.com, the subject of the 404 Media story. For one thing, no bookseller I could find in online discussions had mentioned an order from ISBNdb. The company maintains a public book database and charges for access to it, but does not appear to buy or sell any books. Things get confusing because, in March, the company added a page to its website that offered AI developers the ability to buy physical books, “up to 1 million titles per order,” with a nondisclosure agreement to preserve anonymity.

When I asked ISBNdb about the service, I received an email from a customer-support representative claiming that “ISBNdb has never purchased, scanned, or destroyed a book—for AI training or anything else. We don’t train AI models, and we never have. The page was up to explore demand for a service we never brought to life.” In response to recent “concern,” the representative said, the company had removed the page advertising that service from its website.

Reddit users did call out a different company for “frequent and sizable online orders”: Zoom Books, based in Canada, claims to use “smart logistics” to “acquire, sort, and resell over 2 million books monthly.” Booksellers in Germany mentioned similar orders from Zoom, as did a New Zealand bookseller who wrote that Zoom had placed multiple orders, including one for 71 titles. Becker would not confirm or deny whether his bulk buyer was Zoom.

On May 26, a book-industry newsletter called Publishers Lunch noted accusations that Zoom was buying books for AI companies. On the following day, the newsletter included a response from Zoom, claiming that it “has no involvement in digitization, scanning, or destruction of books, and we do not sell books for those purposes to our knowledge.” (Zoom did not respond to a request for comment.)

Some booksellers who received orders from Zoom have reported that the shipping addresses on these orders belong to a company called PrepFort. PrepFort specializes in preparing items for sale on Amazon and Walmart, but as a third-party logistics company, it can route books to other destinations as well. Using such a company would be consistent with the AI industry’s practice of acquiring training data through intermediaries, a strategy that has been used for images, paywalled articles, and other media. I emailed PrepFort to see if it could provide any details about these orders. Sufyaan Kalota, a co-founder of the company, responded: “While we would love to assist, we unfortunately cannot share any details regarding our customer agreements due to our confidentiality commitments.”

In June, the NL Times, an Amsterdam-based publication, reported that some Dutch booksellers had received emails from a Singapore-based organization called 2077AI, which claims to be “revolutionizing AI data,” partly by creating training data sets. One bookseller reported that the email from 2077AI was accompanied by a list of 3,000 English-language titles the company wanted to purchase. The examples given were academic books such as Distinct Element Modelling in Geomechanics and Laser Shock Peening of Advanced Ceramics. Such books might legitimately be considered “rare”: they had small print runs, contain esoteric knowledge, but are important within a specific field. (404 Media linked to this story but did not reference these books specifically, or 2077AI.) 2077AI did not immediately respond to a request for comment.

For now, this is what we know: A lot of used books are suddenly being bought up by companies including Zoom Books. But we do not know how many of these orders are coming from AI companies, or whether these books will be destroyed. Based on the practices of Anthropic and the attempted purchases by 2077AI, it seems very possible that the books are destined for AI companies, but we can’t be certain.

Regardless, the idea of an AI behemoth destroying books has sent a bolt through the collective psyche. Book destruction is historically linked to authoritarian regimes and attempts to control public discourse, as well as ancient tragedies—the burning of the Library of Alexandria comes to mind. The encroachment of AI, particularly in the realm of books, is now everyday news: Last month it emerged that a top-selling Kindle book may have been partly written by AI, and grandparents are buying children’s books filled with AI-generated slop.

Even if a literal book burning is not under way, the process of ingesting millions of books, stripping them of authorship, and blending them into a homogenous “intelligence” branded with the name of a chatbot certainly feels destructive. It masks the hard work and collaboration that goes into knowledge creation, undermines incentives for authors to write books, prevents experts from finding one another, and gives AI companies tremendous power over what information people can access. Given this scale of cultural damage, the physical destruction of books seems almost quaint.

© Illustration by Alisa Gao / The Atlantic

  •  

Gen Z Is Testing the Limits of How Weird Parties Can Get

On a recent Thursday night, I sat among other guests at a house party and listened intently to a PowerPoint presentation about radium. Lauren Pickens, a 25-year-old who lives in the Washington, D.C., area, stood at the front of the room and flipped through slides about the carcinogenic chemical: A century ago, radium was marketed as a miracle. Americans added it to everything—including food and cosmetics. Within years, some had died. “We’re smarter than that these days,” Pickens said, pivoting to raw milk and other questionable substances people are ingesting today. Everyone laughed.

The presentation was part of the theme that night. The co-hosts—Pickens and her boyfriend, Luke Brandl—had sent detailed instructions to everyone: “Pick a historically bad decision, from either personal or public memory, and tell us about it in the form of an 8–10 minute presentation.” We’d then vote and crown a winner. One guest discussed the chaotic 1904 Olympic marathon (one runner ate rotten apples and took a nap during the race, yet still managed to place fourth); another rehashed her relationship with an ex in the form of a book report. The party was held at Brandl’s home, which doubles as a museum of sorts to the various parties the couple has hosted. Sticky notes from an “embracing your cringe” party hung on a wall, as did a poster of the 1978 film Starcrash, which people had watched at another themed party—“bad-movie night.”

Pickens and Brandl are more ambitious than the average party planner, but their events lean into a common enthusiasm among young partygoers for niche, even absurd, themes. I’ve been collecting examples for weeks: “dress like your favorite Metro stop,” a murder mystery about tech billionaires on a private island, a farewell to Spirit Airlines (“bring the spirit and spirits”). In some circles, hyper-specific party themes are becoming a norm, sometimes a requirement. “Having a coherent theme is more of an expectation now than it was two years ago,” Alexa Jordan, a 25-year-old incoming law student, told me. She’s hosted a spelling-bee birthday party and a cul-de-sac 5K, which entailed running in a circle for more than 65 laps. She estimated that about eight out of every 10 parties she’s invited to now have a theme.

In one sense, the appeal of a niche party is simple. Themes are fun, as people discovered long ago. (In 1897, New York City socialites held a costume ball that has been dubbed the “most ostentatious party in US history.”) Now that friends are only a text message or FaceTime away, though, there’s also a higher bar for what gets people hanging out in person. Wearing a funky costume or presenting on a weird interest gives people “something to talk about,” Samika Lewis, a 25-year-old who also attended the bad-decisions party, told me. Especially at a time when some young adults are turning away from alcohol, a wacky party can act as its own kind of social lubricant. “I never really liked bars that much,” Brandl told me. “I always wanted something a little bit different and more creative.”

[Read: Millennials are sick of drinking]

These parties are themselves fueled by social media as much as they are a rebuke of hyper-online culture. The event I attended started the way it ended—on Partiful. The couple had invited everyone through the popular event-planning app. The morning after, Brandl sent a text blast via Partiful, announcing that a presentation on dueling had won. One of the guests added pictures to the app’s shared photo album.

Partiful, which was founded in 2019, has become especially integral to the rise of niche party themes. Events can be made public or accessible only to those who are sent the link, which is the setting that the hosts I talked with primarily use. Public events show up on the homepage for anyone to see, allowing the strangest parties to get lots of attention and priming people to get creative with their own themes. If you’re stuck, the app has a feature, “Ask the Party Genie,” that lets you choose a vibe (such as “chill” or “chaos”) to get specific theme ideas. When I tried it out, the genie suggested that I host parties including “make lamps out of non-lamps” and a “Lana del Rage Room.” On Partiful, RSVPs to “niche and high-concept events” grew more than four times from 2024 to 2025, Partiful’s CEO, Shreya Murthy, told me.

[Read: The internet, but for hot people]

On Instagram and TikTok, many recaps of themed parties draw millions of views, which help inspire more niche parties. Jordan, the law student, hosted her spelling-bee bash after a friend sent her an Instagram Reel of a similar event. At the extreme, social-media memes are themselves the theme. Komal Kamdar, a 27-year-old who lives in New York City, attended a party where guests dressed up like Adam Sandler, who has gone viral for his combinations of a baggy graphic T-shirt and shorts.

The result is a feedback loop: People get inspiration from Instagram and TikTok. Then they whip up an invitation on Partiful and upload pictures to social media when the party’s over. In some cases, the themes can start to feel forced—more of a performance for some brief attention online than anything else. In D.C., more than 5,000 Partiful users have expressed interest in attending a five-minute “eat an apple with me” event. Normal park picnics have been rebranded as “sit down and touch grass” events.

At the party I attended, one guest scrambled to finish making his PowerPoint before the start of the event. And hosts often drop hundreds of dollars on decorations and spend weeks planning to make sure that the theme comes to life. Kamdar said she spends an average of $200 to host a niche party, and has held fewer gatherings because of the cost.

Still, any kind of in-person gathering seems better than the alternative. Americans could certainly stand to party more. At its best, a niche party is not about chasing clout, but about actually getting to know people. At the PowerPoint party, guests initially exchanged awkward small talk and nibbled on homemade garlic knots. But once the presentations began, everyone loosened up. By the end, we hardly felt like strangers at all. As I slipped out, at close to midnight, the stragglers were already talking about Pickens and Brandl’s next party. Of course, there would be a theme: Guests would compete in a treasure hunt dressed up as either a Roman or a pirate.

© Illustration by Alisa Gao / The Atlantic

  •  

The One Town That Wants a Data Center

Opposition to data centers may be the singular unifying issue in American politics. Seventy percent of Americans are against data-center construction in their communities. They worry about the environmental dracularity of these facilities, the electrical costs they may impose, and the imperiousness with which tech companies target struggling communities while drastically altering the landscape. Bernie Sanders and Alexandria Ocasio-Cortez have spoken out against data centers; so have Steve Bannon and the right-wing podcaster Matt Walsh.

 About 75 data-center projects were blocked or delayed in the first three months of this year—roughly the same as were blocked or delayed in all of last year. Still, this is a fraction of the more than 1,500 projects in development. Those who seek to stop the spread have recently turned to statewide moratoriums. Fifteen states have introduced moratorium bills, but only two of those bills have made it through the legislature. Last month, New York became the first to ban the construction of “hyperscale” data centers (ones that use 50 megawatts of power or more). Maine was supposed to have beaten it. In April, the state passed LD 307, which would have banned new centers using 20 megawatts or more. The bill went to the office of Governor Janet Mills to be signed into law. And she vetoed it.

Mills took no issue with the thrust of the bill, writing that “a moratorium is appropriate.” She vetoed it for one reason only: It failed “to allow for a specific project in the Town of Jay.”

Jay, Maine (population: 4,620; motto: “Proud of our past and working for our future!”) wants a data center. It had one in the works, and town officials lobbied the governor to preserve it. Mills listened. “We must consider the perspective of the Town of Jay,” she wrote.

In May, I drove to Maine to consider the perspective of the Town of Jay. I wanted to understand why this town had fought for the very thing that so many others dread. What I found was a reminder that politics is local. Jay’s embrace of the data center had less to do with the power of rapacious tech companies or the future of AI than it did with the failure of a series of welds that sealed a 166-foot-tall pressure cooker at a half-century-old paper mill.

There are two Maines. The first Maine is right there on the license plate: vacationland. Lighthouses, lobster bibs, the jagged coast, anywhere with a big, beautiful lake or a big, beautiful ski mountain. The other Maine—Jay’s Maine—is Appalachia. When I asked ChatGPT what I should see in Jay, it suggested (gently) that I should visit somewhere else. Jay is a 90-minute drive from the coast. It has no lighthouse and no giant lake. The school is the town’s largest employer. A surprising number of people ride motorized scooters—they can no longer afford cars. What Jay does have is space.

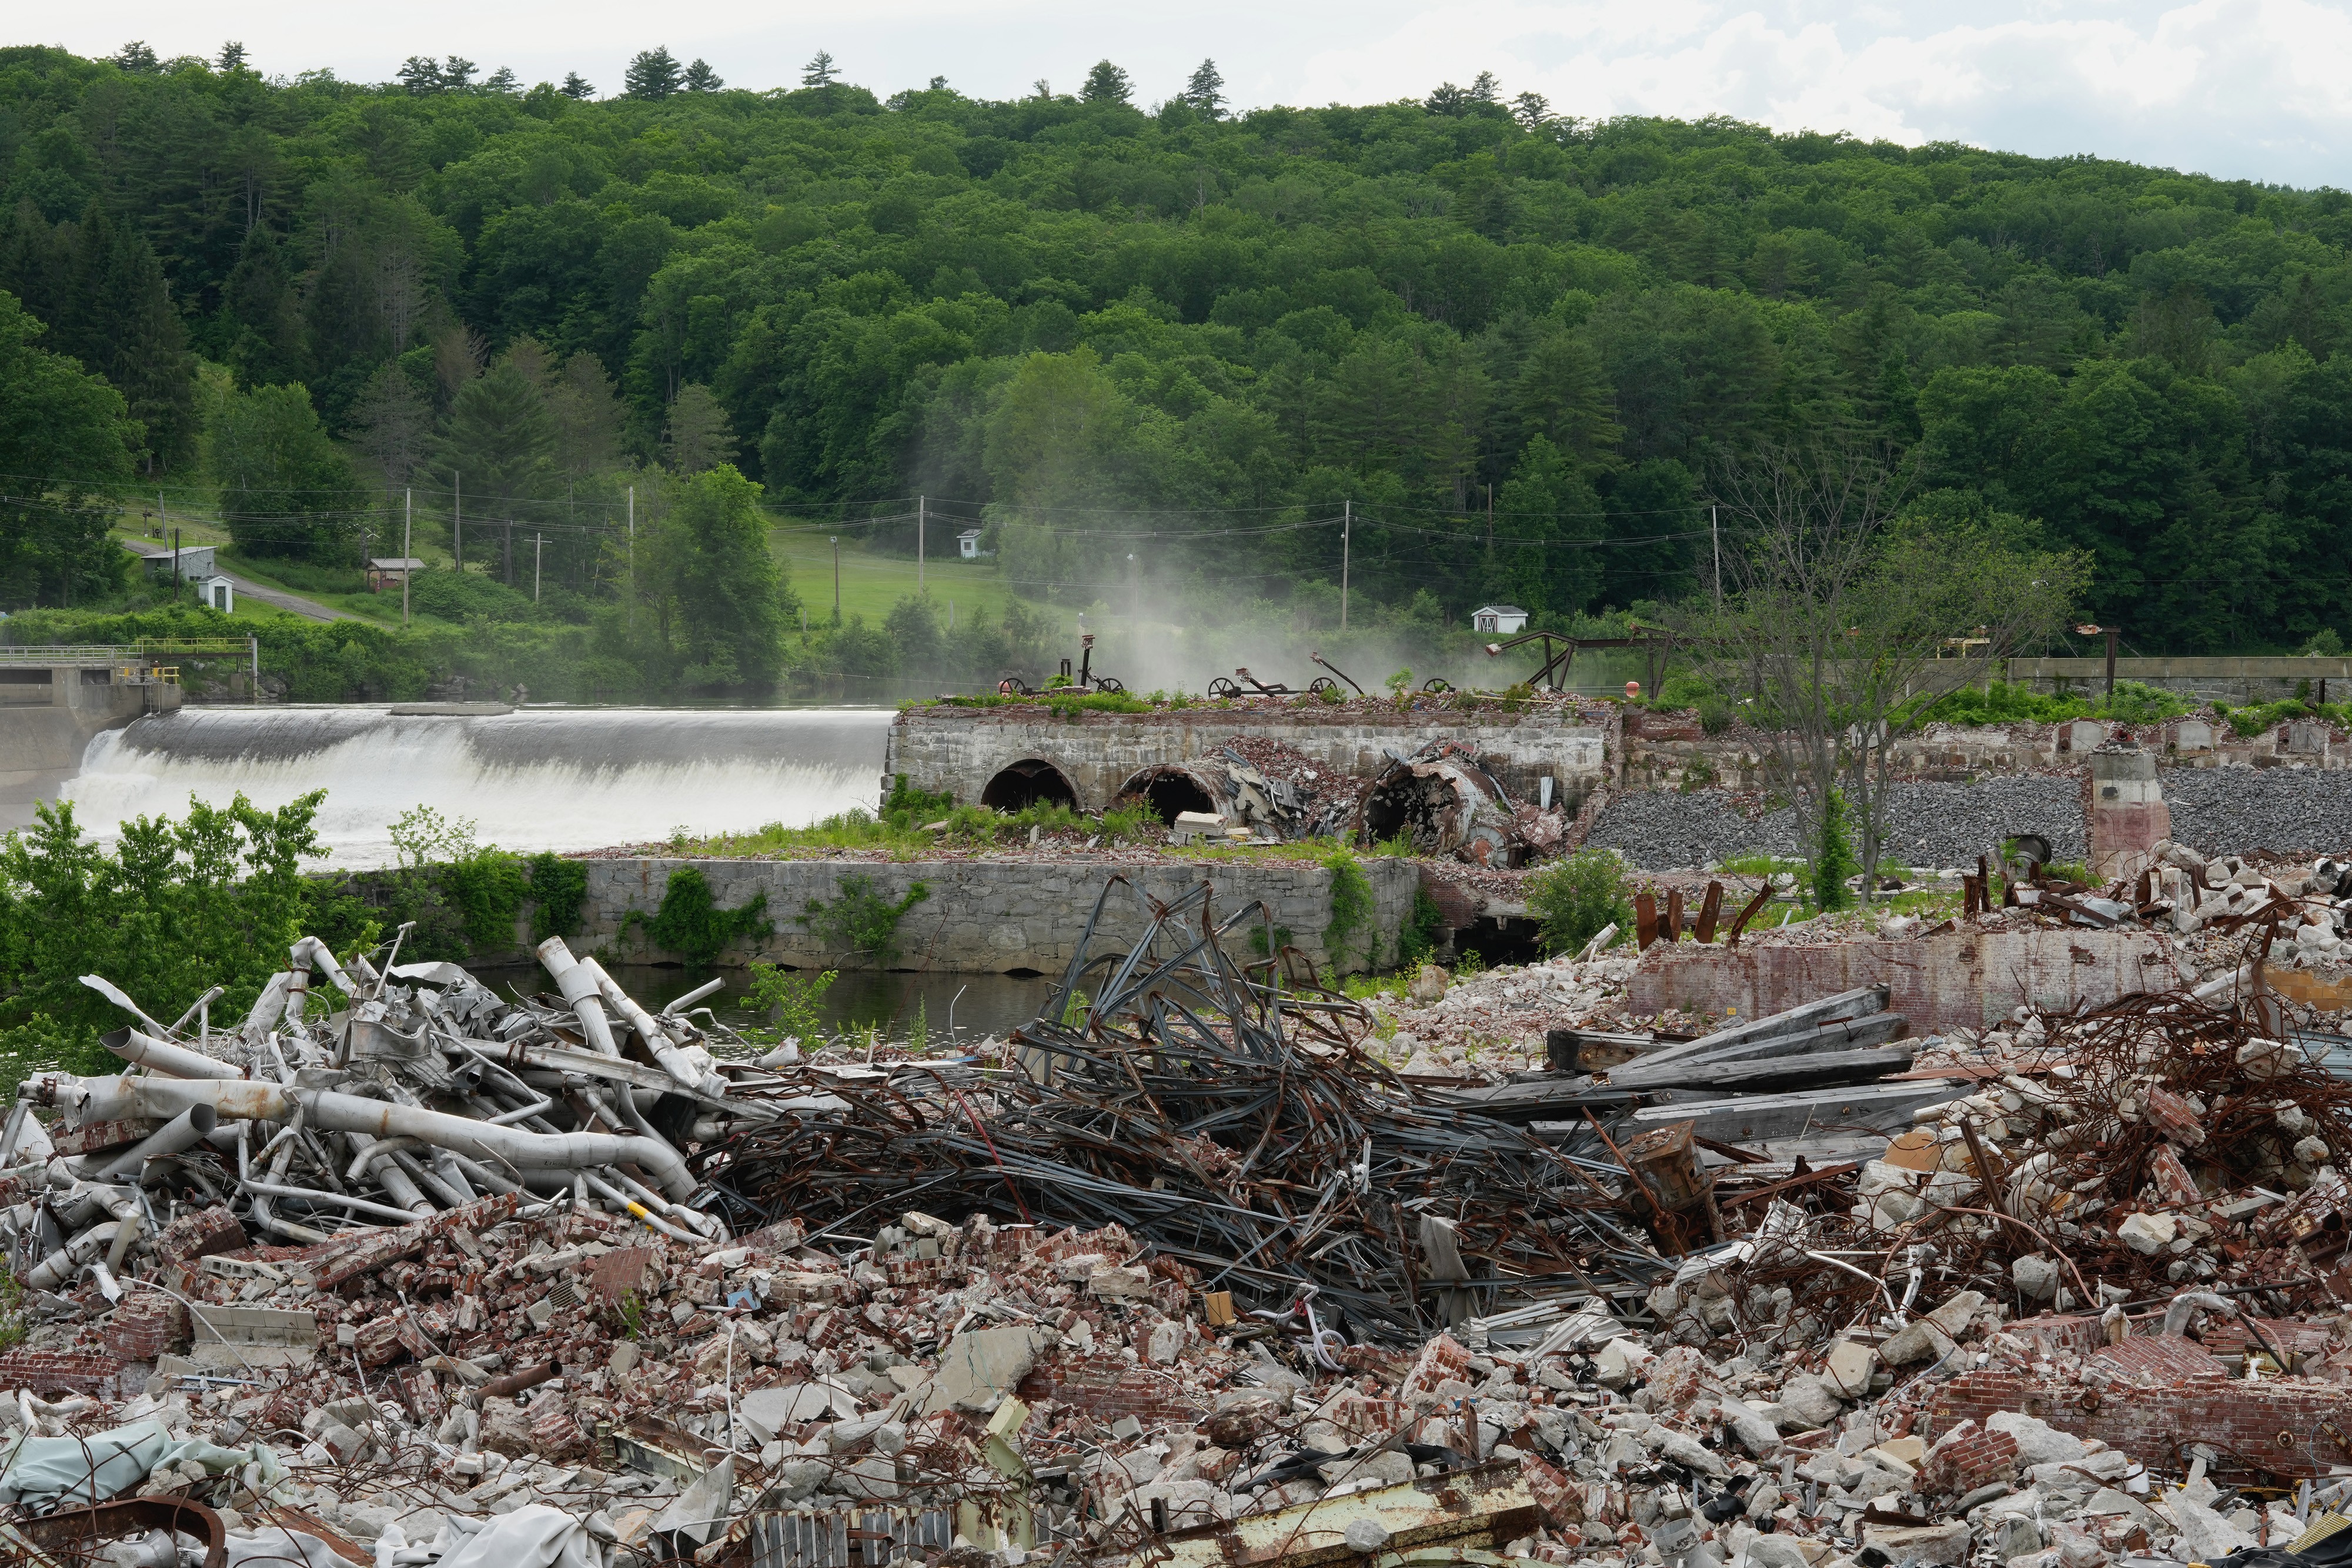
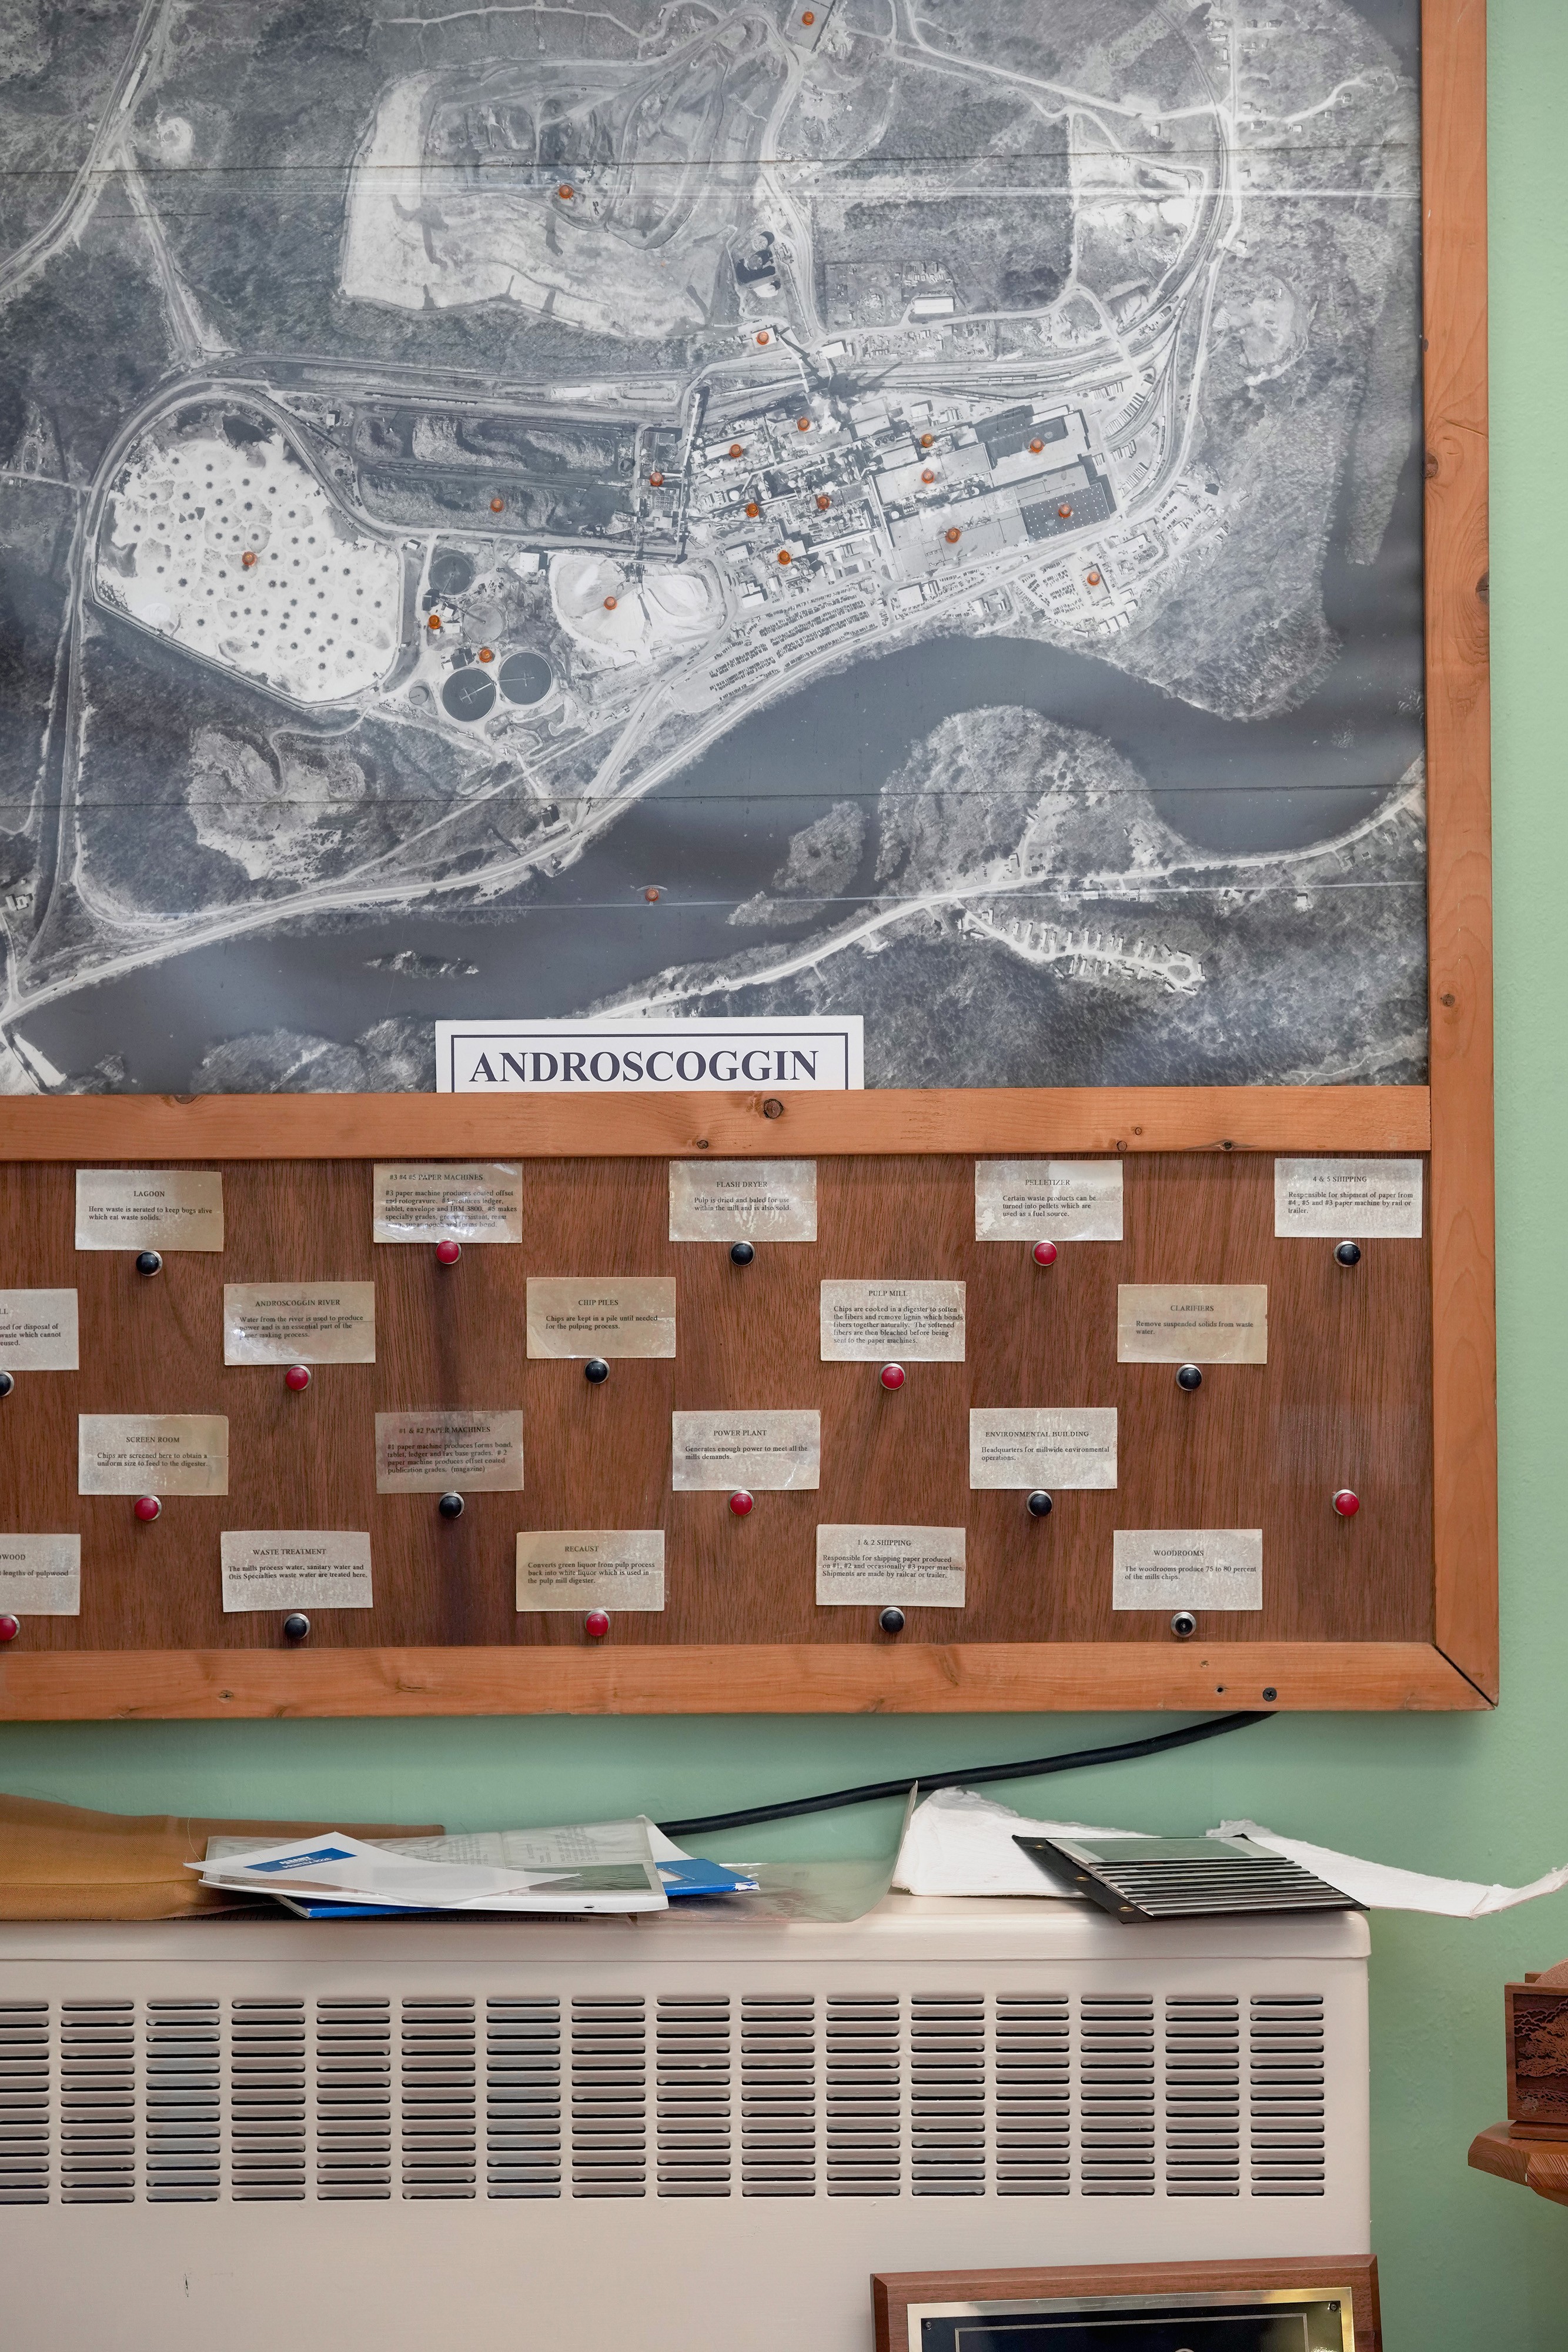
In 2023, a company called JGT2 bought 1,000 acres just across the Androscoggin River from Jay. To inexpert eyes, the property—the site of the former Androscoggin paper mill—doesn’t look like much: a few rusted and stained industrial buildings sprouting weeds in the shadow of an immense landfill. But to Tony McDonald, one of the developers who leads JGT2, the site looks like money. It has direct rail access, gas, a 35-million-gallon-a-day wastewater-treatment plant, and, crucially, power: a 150-megawatt electrical interconnect, plus access to 25 megawatts of hydroelectric power.

 McDonald’s original idea had been to turn the place into a wood-product manufacturing facility. Mills traveled to Jay to announce the project, which was expected to create about 125 jobs. And yet over the next two years, the factory plan quietly died—throttled by the Trump administration’s tariffs on specialized equipment, steel, and aluminum.

Jay_6.jpg
Julia Kokernak for The Atlantic
A mural at the former office of the Western Maine Labor Council

Jay has minimal zoning laws; McDonald didn’t need to ask anyone’s permission for what he planned to do with the land. So few in the town knew that his focus had switched from wood to data until one freezing night in late March, when he showed up to see the Jay Select Board—the five-member panel that sets town policy. News of the moratorium bill had broken, and McDonald needed the town’s help to preserve his project in Jay. He apologized that this was the first the board was hearing about his deal with the data-center firm Sentinel: “It never occurred to me to discuss it with anybody,” he said, “so to any of you that got blindsided by that, really, I’m sorry. That’s on me.” But without their help, he told the board, the bill “will kill this project. Dead, dead, dead,” before adding, “Dead. Never coming back.”

Secrecy around such projects is not unusual, even in places that require town approval. In a recent report, NBC analyzed more than 30 data-center proposals from 14 states and found “in a majority of cases, local officials signed NDAs and worked with what appeared to be shell companies that can conceal visibility into the project developers.” The justification is that secrecy preserves a competitive advantage; the effect is that citizens learn of these projects only when it’s too late to do anything about them.

Still, towns have fought back. In October, when the people of DeForest, Wisconsin, discovered plans to build a $12 billion data center, the backlash was powerful enough to kill the project a few months later. In April, a town council in Festus, Missouri, approved a $6 billion center plan; a week later, the town voted out every city-council member who’d voted for the project.

None of that happened in Jay. Less than an hour after McDonald stood up in the meeting, the board voted 4–0 (with one abstention) to draft a letter of support to Mills. Analyze the footage as much as you like—it will provide no clear answers as to why, in this moment of bipartisan resistance to new data-center construction, these town leaders would go from total ignorance to unanimous support in the time it takes to bake a lasagna.

Then—perhaps even stranger—most people in the town embraced the decision. Some were skeptical. More than a few traded insults in “The Jayborhood” (the town’s Facebook group). But meaningful resistance was scarce. One resident, concerned about noise pollution, started a petition, then gave it up after a 30-minute conversation with McDonald.

Mainers guard their individual freedom fiercely and apply limitations only selectively. More than one person I spoke with in Jay dismissed the broad resistance to data centers as simple NIMBYism. A common refrain I heard went something like: It’s Tony’s land. He can do what he wants with it. Cody Jacques, a union electrician who grew up in Jay, put it this way: “I don’t want you to tell me what I can do at my house. This is my property. I live here.” The same is true of McDonald’s site, he said. “At the end of the day, nobody likes to get told what to do with their stuff.” Still, the town doesn’t oppose all moratoriums on principle; it bans retail marijuana stores, which surround Jay on all sides.

The reason Jay wants this data center—the reason the board lobbied the governor for it—has everything to do with the land on which it would be built. The Androscoggin Mill once employed 1,500 people. Those who didn’t work in the mill envied the mill workers’ wealth, which bought houses, four-wheelers, prom dresses. “It was everything,” Trevor Doiron, who is running to represent Jay’s district in Maine’s House of Representatives, told me—“the identity of the town.”

Jay_9.jpg
Julia Kokernak for The Atlantic
A scrap yard on the site of the former paper mill in Jay, Maine

Growing up, Jacques would stare at the mill and imagine a gleaming city. “The scale of the mill and all the lights, all the towers,” he said—“we’d always joke around and say, ‘There’s Portland, Maine, on the river.’”

After a stint in the service of Vacationland as a lobsterman, Jacques returned to Jay in 2019 to work at the mill. It employed fewer people than it once had, but Jay was hardly some bombed-out ruin; the paper mill still tithed substantially to the town, and offered Jacques a 401(k) and the chance to rise through the ranks. The year that OpenAI released GPT-3, he was studying for a promotion to pulp-digester operator, spending his days off at the mill with a clipboard and notebook.

On April 15, 2020, Jacques was at home. His phone buzzed with a few texts from friends asking what was going on at the mill. He figured a mill job had been posted and they wanted an inside track. “So I was like, Hey, no, you just gotta go on the website and apply,” he recalled, “and they were like, No, the mill blew up. I’m like, What do you mean it blew up?”

Dashcam footage from a truck nearby recorded the explosion. The video shows the traffic just outside the gates and the mill in the background. What you can’t see is a weld, one of thousands sealing the 166-foot tower that turned wood chips into wood pulp, opening a crack in the wall. Then another weld. And another. One moment there is blue sky, the next, a black column hundreds of feet high. Oozing brown pulp drums on the hood of the logging truck like hail as the drivers on the radio squawk and curse. Soon it’s so thick that the camera is almost entirely obscured. The black cloud is on its way toward Jay, where it will drop wood pulp on the houses.

Jacques got in his car. He tried to get into the mill—to help, to pull out bodies if needed; he didn’t know—but police blocked the road. Mill employees worked in 12-hour shifts—about 170 workers on site at a time. They worked weekends, nights, and holidays together. They were like family. Jacques saw that the two 166-foot towers where he’d worked, the same towers he had imagined as a city when he was a kid, were gone.

Remarkably, no one died. A government report attributes this extraordinary outcome to the timing of the explosion. It was lunchtime. People in Jay credit the grace of God. Once everyone was accounted for that evening, the town’s thoughts turned to the future. “ We knew right then and there they weren’t rebuilding,” Kenny Jacques, Cody’s father, told me, before blowing a brief rendition of Taps through pursed lips. “It’s over. It’s over.”

Jay_12.jpg
Julia Kokernak for The Atlantic
An exhibit on the mill at Maine’s Paper & Heritage Museum in Livermore Falls, Maine
Jay_26.jpg
Julia Kokernak for The Atlantic
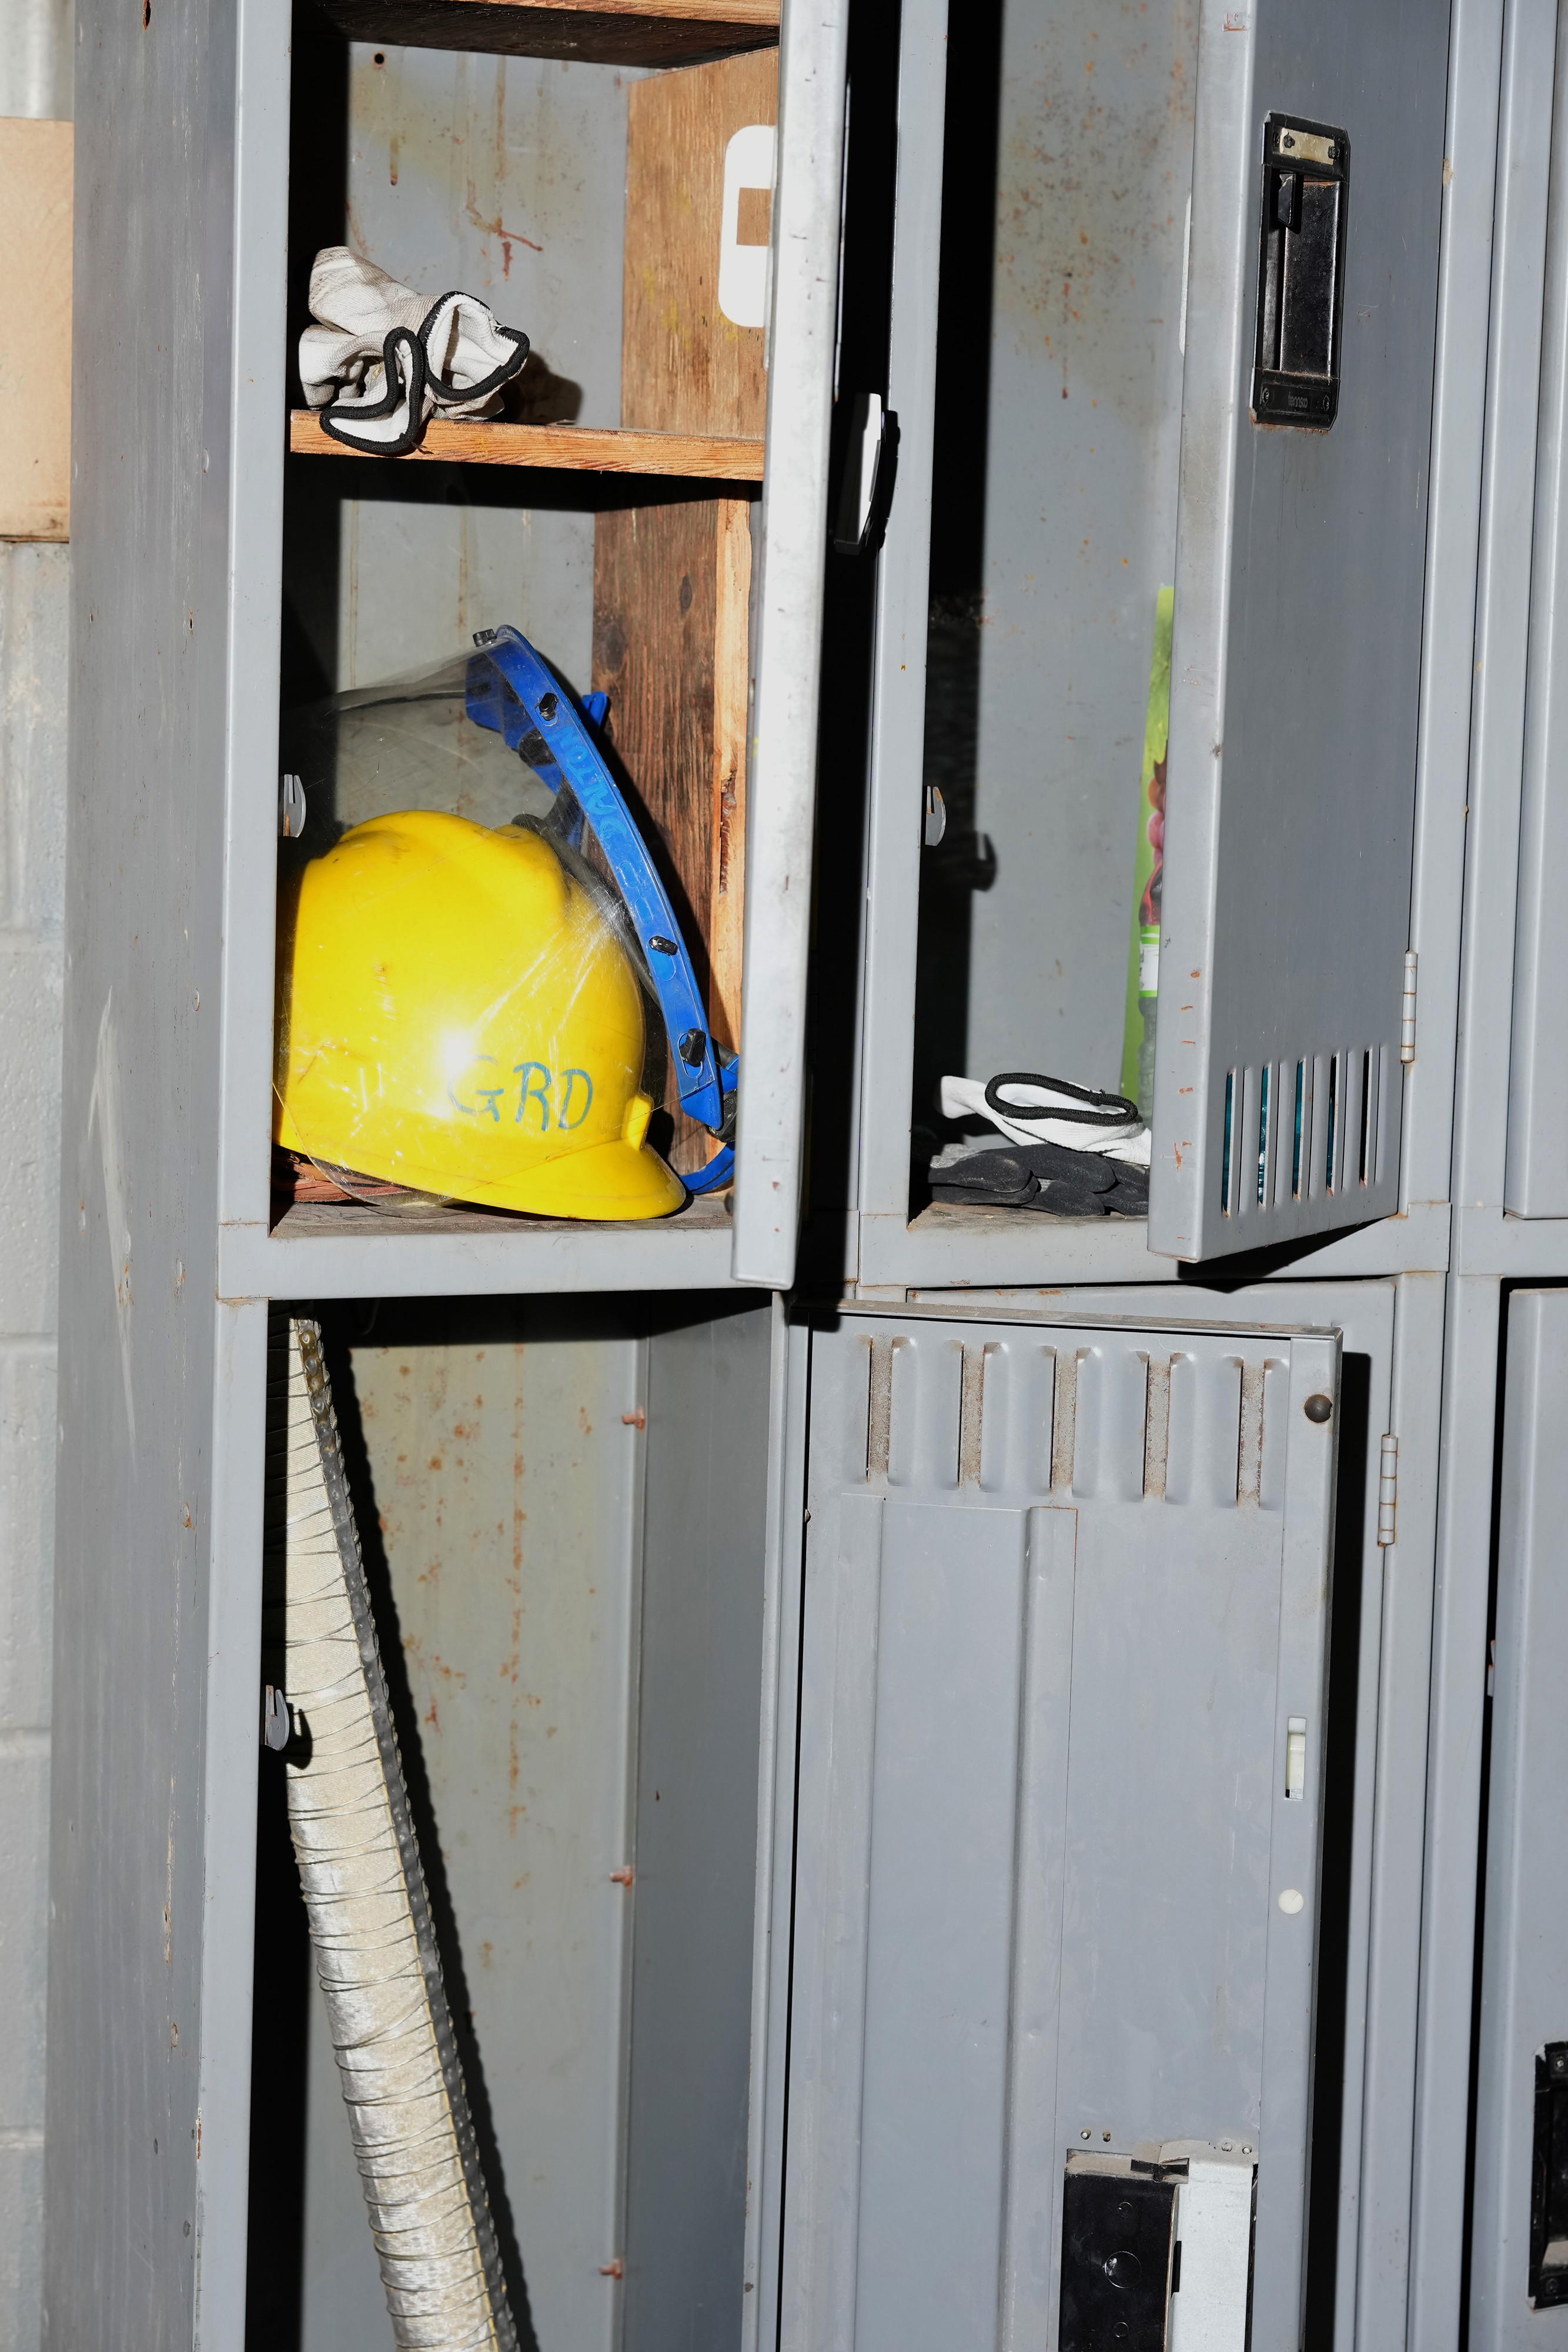
A locker inside the former mill
jay_maine_film_51.JPG
Julia Kokernak for The Atlantic
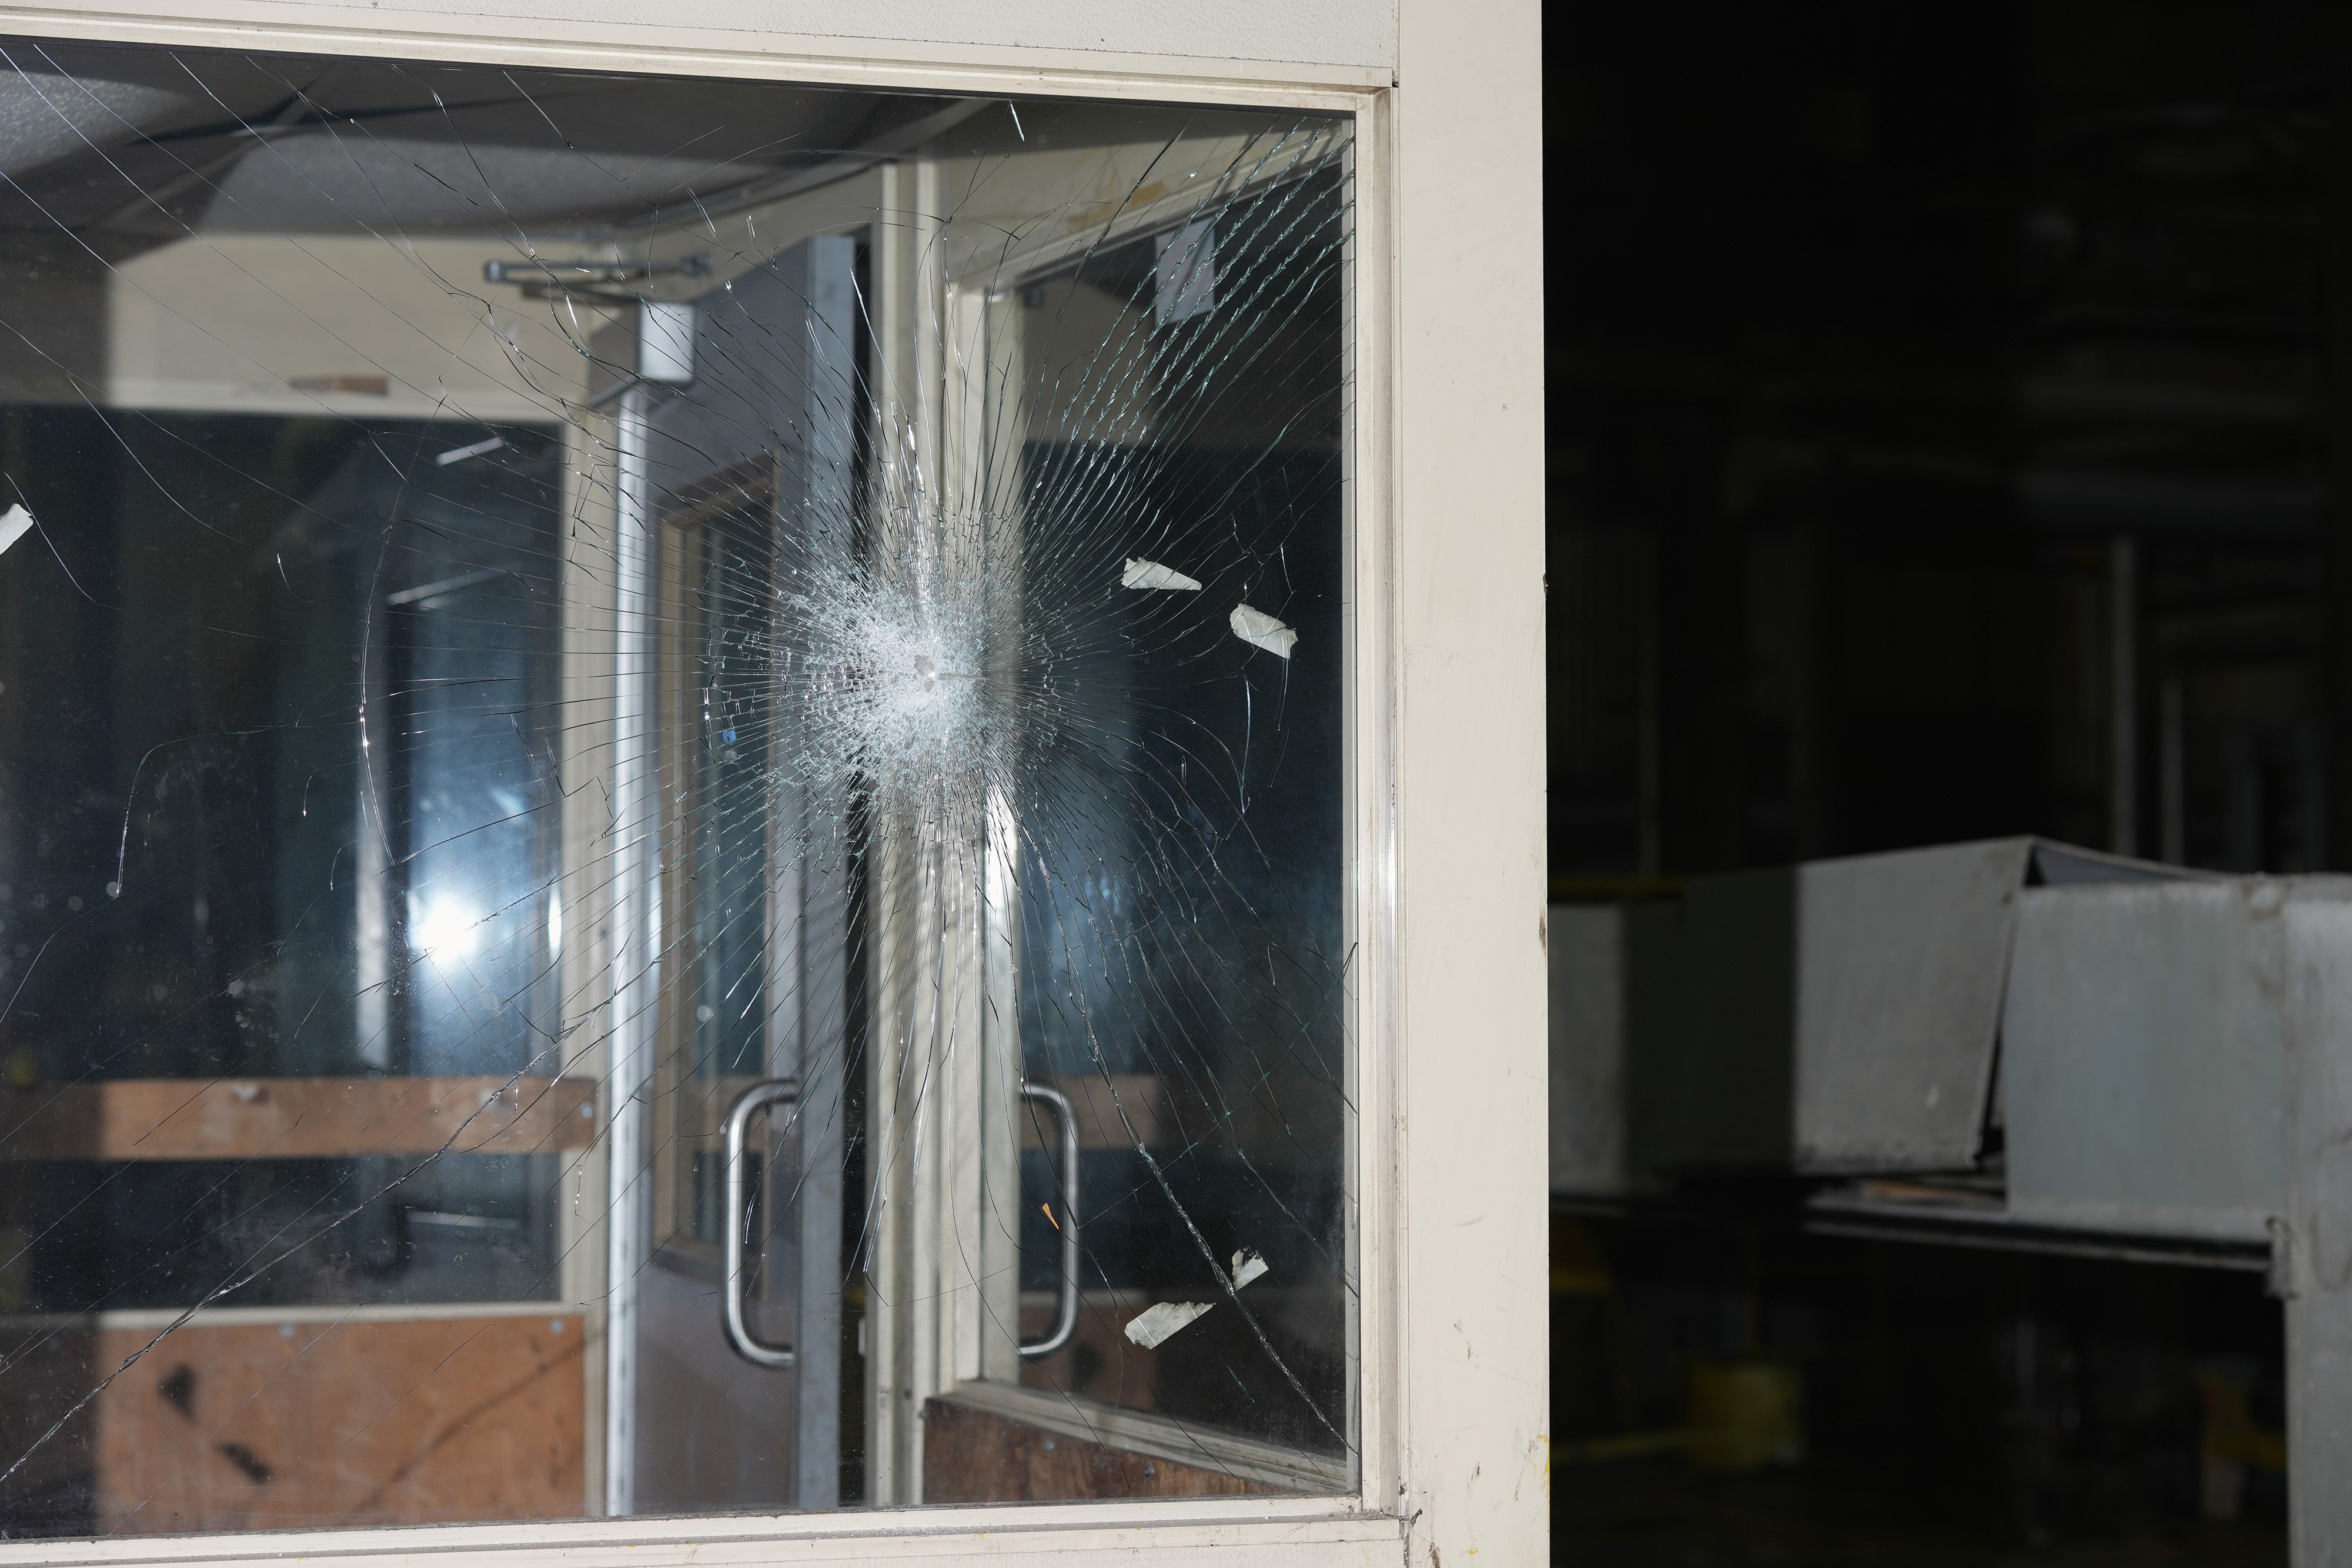
Inside the former mill

I asked Lucien Richard, a former engineer at the mill who now works as McDonald’s site manager, to show me the parts of the property that are best suited for a data center. The mill was mostly silent, with the exception of a few demolition workers smoking and listening to AC/DC. Walking through the machine rooms, I understood why Elon Musk wants to put data centers on the moon—the facility was so dark, cold, and seemingly endless that we may as well have been in outer space.

At one point, Richard’s flashlight fell across a mural—a hand-painted image of a rowboat full of puppies, peering out at a row of ducklings. “Some pretty talented people used to work here,” he said.

Last year, Donald Trump directed the Environmental Protection Agency to identify sites like the former paper mill for potential data-center use. The reasoning is that in some cases, much of the infrastructure is already there. According to McDonald, the mill site is permitted to pull 82 megawatts from the electrical grid. To supplement that power, he plans to build a 150-megawatt solar facility, and to employ the hydroelectric facilities that sit on the Androscoggin River. Elsewhere in the country, power plants are struggling to keep up with demand from data centers, which can drive up electricity costs. The pitch, then, is that this data center would exist in a walled garden—generating much of its electricity on-site, and pulling no more from the grid than the mill did before the explosion.

In dry states such as Arizona, data centers strain an already precarious water supply. Maine is wet. Richard showed me another vast room, this one with rows of sand pits stretching off into the darkness, into which 35 million gallons of water were once pumped up and filtered daily. McDonald expects the data center to use 1 percent of that, or about 300,000 gallons a day. Richard mused that they might need a smaller pump.

Some of the language McDonald uses—his promises of “no environmental impact” and “all positives,” “no negatives”—is clearly overstated. Maine has environmental and power regulations like everywhere else, but no specific playbook for data centers. The reason the Maine legislature passed the moratorium in the first place was so it could make a set of rules before development started.

On every point, this is how the argument goes: Would a data center be loud? Can’t be as loud as the mill! Could it smell bad? The mill smelled like rotten eggs! Would it pollute the environment? The river was covered in toxic foam in the mill days! “All you gotta do is get over the people’s fear,” Richard told me. “You need lots of water. We used to use lots and lots of water. You need lots of power. We used to use or make lots of power. It’s a natural fit.”

Using the past in this way, as a means of justifying the future, is a dangerous gambit, nostalgia being the hack-and-burn editor that it is. For some, the counterargument couldn’t be more obvious. Just look at the river now: It’s blue. But the mill is a handy benchmark for what the town is willing to tolerate.

Although the work Richard oversees may resemble Jay’s productive industrial past (angle grinder, indoor cigarettes, AC/DC), the task here is demolition. Tons upon tons of complex machinery have already been disassembled and shipped to Pakistan. When the place is empty, the trucks can roll up, the servers can be plugged in, and the building can start humming its ceaseless B-flat. And not so many years from now, the mural will be a sort of cave painting. Perhaps some AI-powered technician will roll past and wonder what possible efficiency might have been gained by painting a boat full of puppies on a wall in a workplace.

2026_07_30_Jay, Maine, Wants a Data Center-3.jpg
Julia Kokernak for The Atlantic
A mysterious mural of ducks and puppies

After the mill exploded, Jacques heard from a friend that work was to be had as a union electrician. He took an aptitude test, and soon became an official brother of IBEW Local Union 1253. Its logo is an electrified bear in a hard hat. His work, by and large, has been in the booming industry of data-center construction.

Accustomed to heat, noise, and toxic chemicals, Jacques was struck by the pristine cleanliness of data-center facilities. The downside is the distance—he travels all over the Northeast and lives on-site for weeks at a time. Recently, he was halfway through an eight-week job in Niagara Falls when he called his girlfriend to say he wasn’t going to make it another four weeks without seeing her and their young daughter. They looked at a map and chose Albany, that bright and empty city, as a midway meeting point. Seeing his daughter through the open window of his girlfriend’s car as they pulled up, he felt elation, and relief.

If Jay had a data center, one of the construction jobs would almost certainly be his.

During local elections late last year, Meta spent $6 million running ads in state capitals such as Sacramento, Tallahassee, Salt Lake City—places with the power to buoy (or ban) data-center construction: “Los Lunas used to be a one-stop town. Most people were employed by a farm or a railroad. I needed to support my family and leave home to find work, traveling all the time. I missed a lot—important moments I can’t get back.”

The put-on simplicity of the voice-over script, paired with the Old MacDonald imagery (horses, hay bales, pickups) reeks of insincerity. “Then Meta came to town and opened a data center, bringing new jobs to Los Lunas. And now I don’t worry about missing out much anymore.”

Tony McDonald has said he expects that the Jay project will create 125 to 150 full-time high-paying jobs. Those jobs were a key factor in Mills’s veto of the moratorium. But projects with similar footprints employ 30 to 50 full-time staffers. Five years from now, if the predictions of AI companies are to be believed, the number will be smaller. So when Tom Saviello, the mill’s former environmental manager who is now a county commissioner, started quoting Field of Dreams to me—“If you build it, they will come”—I worried that Jay was being sold a future that would only ever exist in Meta ads.

Saviello’s grief at the loss of the mill was so intense that, for years after the explosion, he couldn’t bring himself to visit the place. When the data-center project was announced, that grief evaporated. We talked in the mill’s parking lot. “I just get excited about it,” he told me, sheepishly. “That’s all.” The people of Jay have “been through turmoil,” he said, “but they’ve survived. And this is a chance for them to even do better.”

I spent one of my afternoons in Jay with Trevor Doiron, the House candidate, a Democrat who supports the data center. He’s 28, with the look of a politician who has come home to run for office: neck sunburn, flannel tucked into jeans. He told me he’s been surprised by how people are living—with holes in the floor because they can’t afford repairs, using the oven to heat the house.

Maine has the oldest population in the country, and the population of Jay is older even than the state median. Trevor volunteers at the food pantry on Tuesdays along with a 92-year-old man who helps pack and deliver meals to Jay’s older residents. “The elderly are the ones providing the services for other elderly people,” he said. “A year from now, who’s gonna be filling the boxes?”

jay_maine_film_93.JPG
Julia Kokernak for The Atlantic
A vacant storefront in Jay

Before visiting Jay I expected that the current running beneath its bid for a data center was desperation: To survive, Jay needs anything. What I heard instead was Jay wants something. Because something is better than nothing.

In a recent article about Jay and rural data centers, Anthony Elmo, who studies economic development, said of rural towns, “They don’t have the resources to negotiate. They don’t know what to ask for.”

I think Jay knows plenty. In its support of McDonald’s project, the town offered no tax break, and stood to make about $6 million in property taxes. That’s a transformative amount of money for the town’s budget—about $7.2 million this year. Locals were clear-eyed about the promise of full-time jobs and skeptical of the claims being made in Meta ads. “I don’t care if it’s 10 jobs. I don’t care if it’s 100 jobs,” Saviello said. “One is more than zero.” Many also reminded me that residents such as Jacques already make their living on temporary construction gigs. “ It’s ugly. It’s ugly,” Doiron told me about Loudoun County, Virginia—which is often thought of as the data-center capital of the world—but “Loudoun County has a lot of really nice stuff.”

“ Even if all that industry comes back, it’s not gonna be us that builds it,” Patrick Hopkins, a carpenter and Jay resident, told me. “It’s gonna be automated. It’s not gonna be the days where this whole line of dudes walks in and they’re all wearing the same company shirt and the same company hat, and they’ve all got their lunch pails. That’s just some dream from the past—a moment in time. It’s gone. It’s better for us as a people to be like, We need to move on.”

The most powerful companies in the world want these data centers. Many of the campaigns to build them are waged in secret against towns worn down by decades of losses. You could think that it was wrong to let one town stand in the way of a statewide moratorium. You could think that Jay was naive, and yet another data center won’t make anyone better off. And yet for Jay, the data center is an opportunity to push back against the steady encroachment of poverty, 15-hour commutes, the atomization of an aging society. I found I couldn’t argue with such a pragmatic and hard-earned hope.

But on June 11, the town posted an announcement on its Facebook page. Commenting was disabled. The data-center project had been put on indefinite hold. McDonald’s client, Sentinel, had backed out.

I called a lot of the people I’d spoken with in Jay. Most were disappointed. None seemed that surprised. McDonald is trying to find a new firm; the demolition work continues. But no one is particularly optimistic. The data-center project was just the latest on a long list of things that were there one day and gone the next.

© Julia Kokernak for The Atlantic

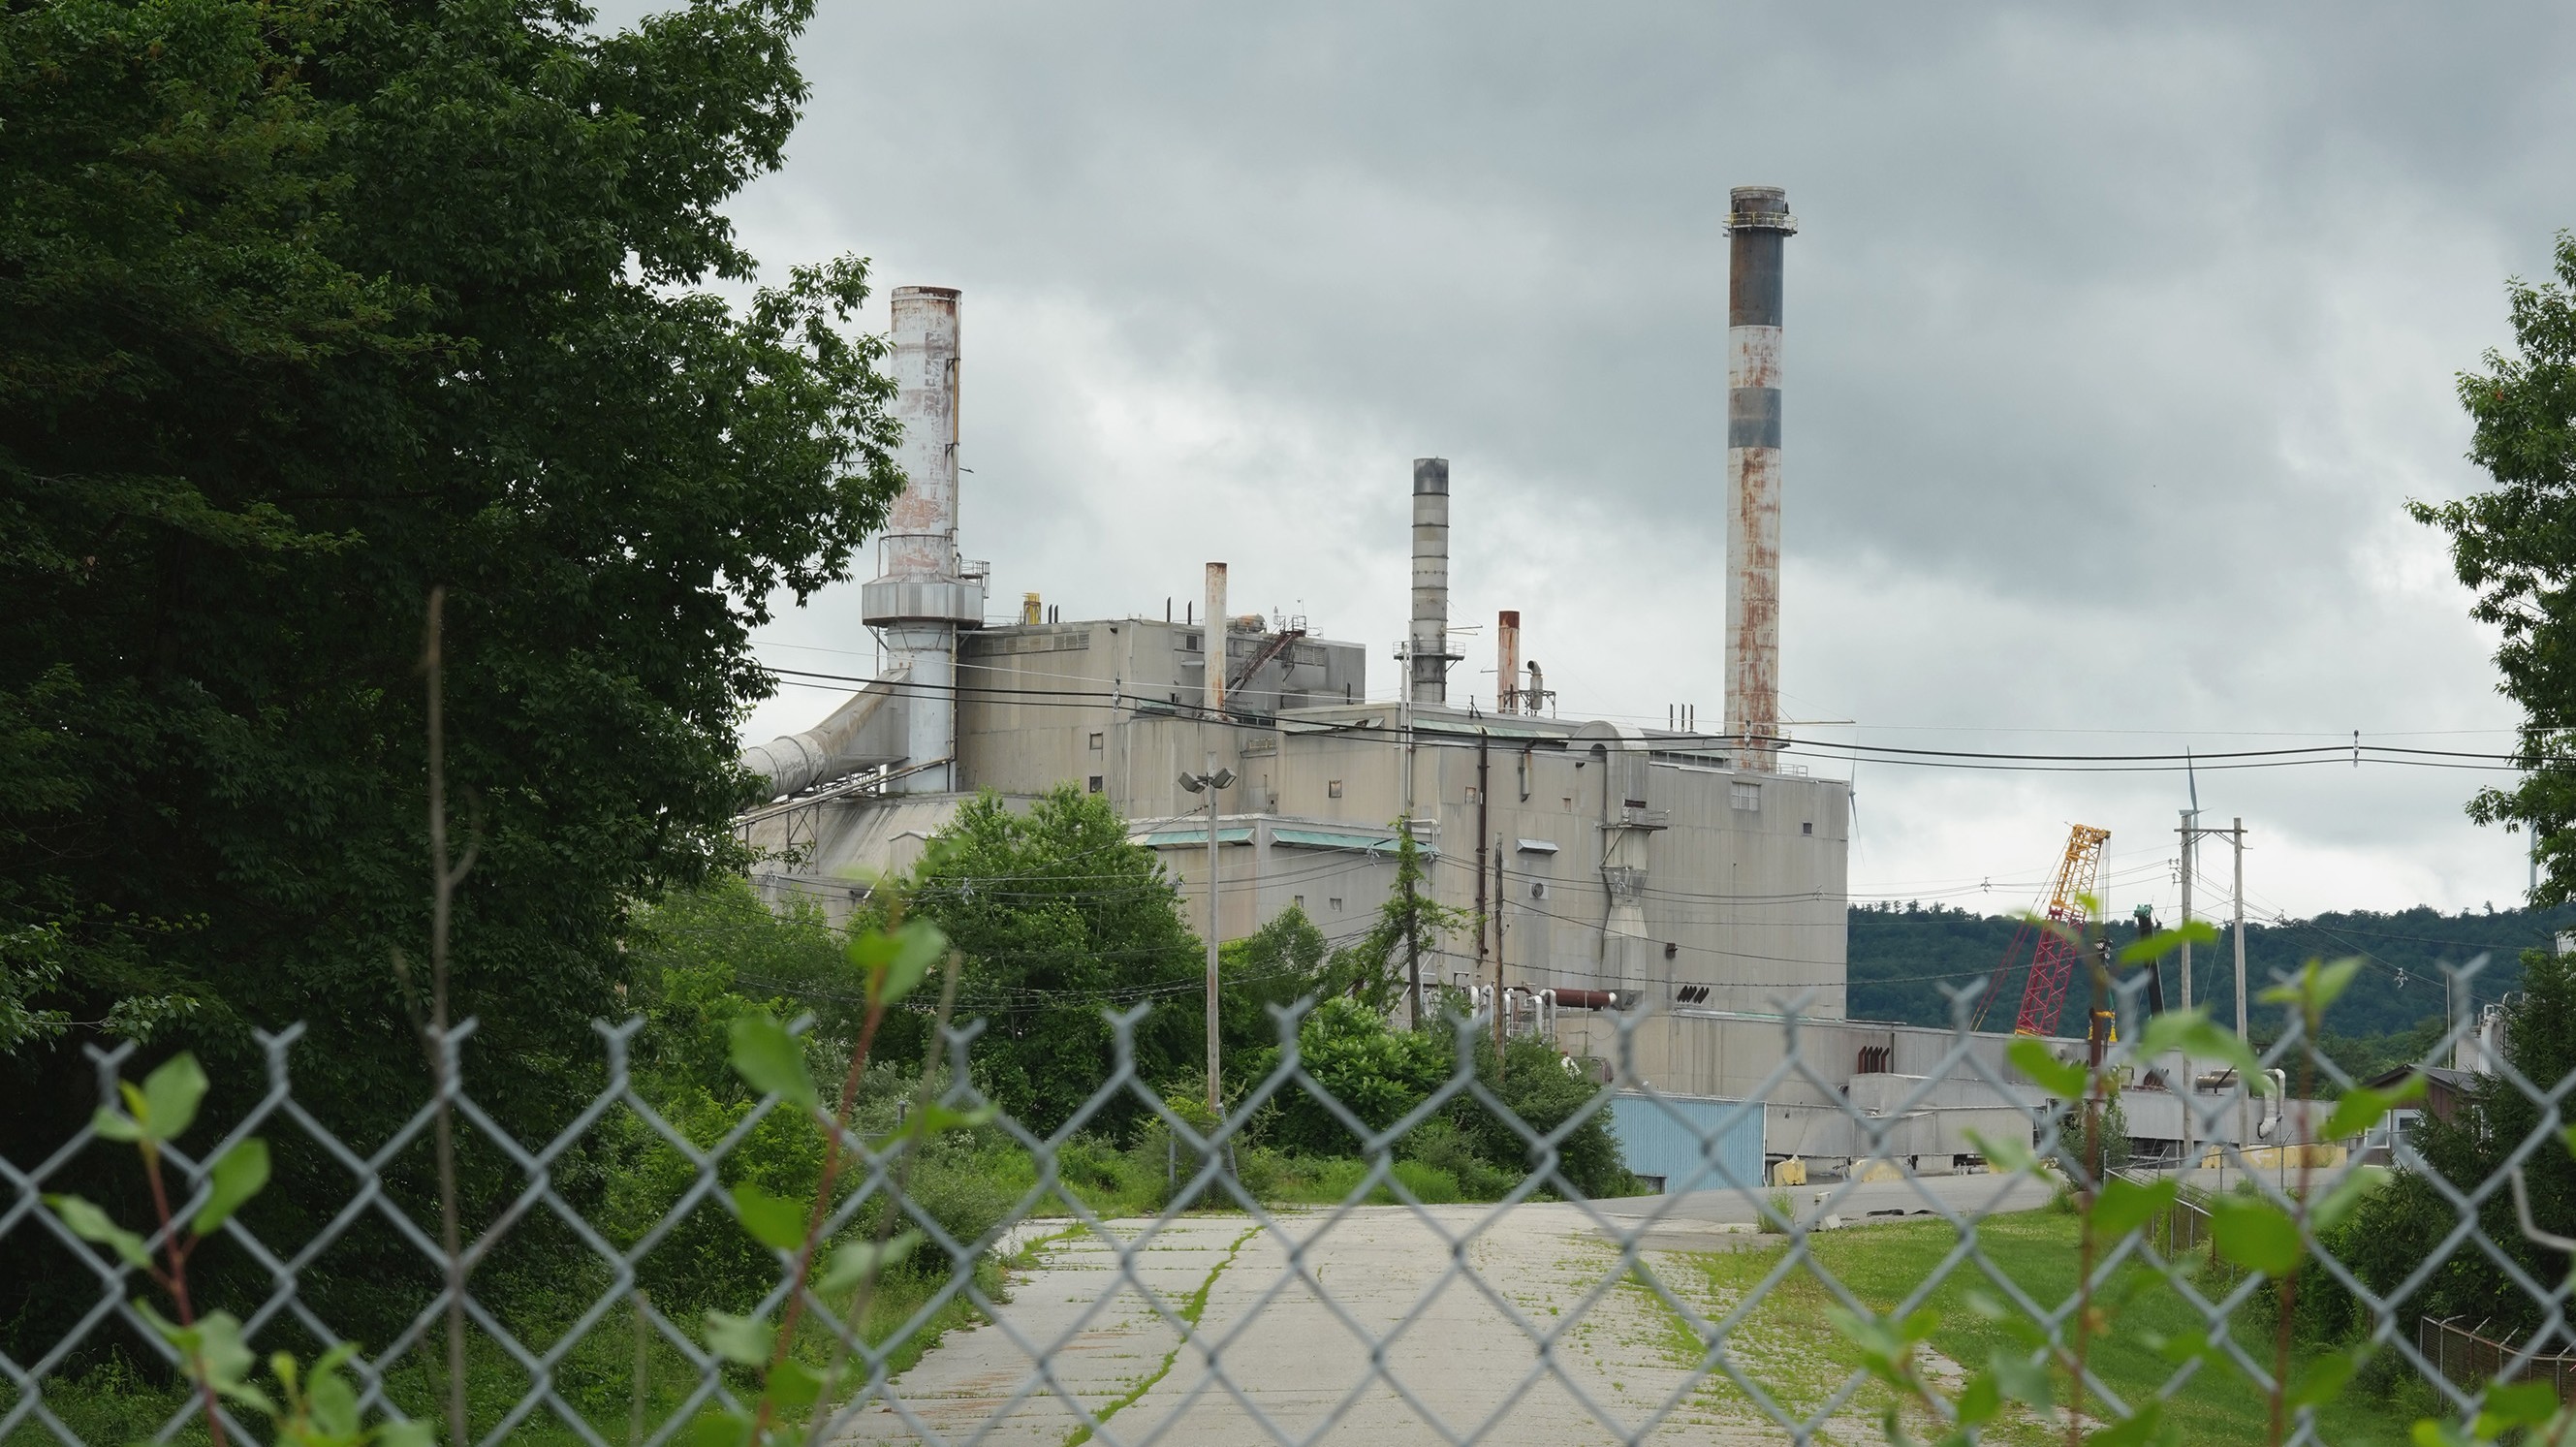
The power plant at the former Androscoggin paper mill
  •  

Which Screen Is the ‘Good Screen’ Now?

The videos that Instagram suggests in my never-ending “For You” feed are usually of a constellation of women. They’re strangers, but I call them “my girls.” One of them is remodeling her house; one is always cleaning and “resetting” the van she lives in; one is sampling pasta and sandwiches at various New York establishments. And each has something special that I can’t explain to you—a je ne sais quoi, a curious style of speaking—so I’ve come to look forward to my regular glimpses of their lives, which I get when I scroll in bed before I go to sleep each night.

I regard these strangers as my intimates in a way, even though some of them are not people I think I would like if I actually met them. One morning, I was watching one on my living-room television while sipping my coffee. My husband walked into the room and winced as one of the women changed into a perfect re-creation of an American Girl–doll outfit (very theater kid, not his thing). I felt a flash of defensiveness—she makes everything by hand! She has a real sense of self! Not to mention a seemingly sweet relationship with her father and pet birds. I kept scrolling and was relieved that another one of my girls hadn’t appeared. She often records herself eating a frozen dinner on her couch while watching police body-cam footage on YouTube to unwind. And I mean no disrespect to her, but if she had shown up, I would have lunged for the remote.

You might be wondering: Why was I watching Instagram on my TV? Instagram’s vice president of product, Tessa Lyons-Laing, has referred to TV as the company’s “next frontier.” As it tries to compete with YouTube and Netflix, Instagram is apparently looking for ways to be … both of them. And so it has launched a stand-alone service for various streaming devices, which it recently expanded with new features to help “friends and family watch together.” This caught my attention: I wanted to try taking the “bad” screen (my phone) and putting it onto the “good” screen (my TV) to see how it would make me (and the people around me) feel.

[Read: The flip-phone cleanse]

Years ago, the “good screen versus bad screen” meme originated as a joke about having an office job. The “bad” screen was a desktop computer at work, whereas the “good” screen was a personal laptop, full of one’s own, delightful, self-chosen digital activities. But in 2022, following the coronavirus-pandemic lockdowns, the writer Kate Lindsay noted a shift. When people referred to the “bad” screen, they now seemed to be talking about their smartphone, which they felt hopelessly dependent on, and when they mentioned the “good” screen, they were referring to the humble television, which now felt wholesome and safe. “We’re so convinced that it’s in our best interest to reverse the effects of social media that even watching a 30-minute TV show uninterrupted seems constructive,” Lindsay observed. But maybe, four years later, the 30-minute-show part is negotiable. Perhaps “good” could come just from giving our thumbs a break, looking up instead of down, and permitting other people to see what we’re doing.

My husband was initially wary of adding his Instagram account to our living-room TV, but he acquiesced, and we had kind of a blast watching his feed together. Most of the videos were of male comedians I didn’t recognize; I sounded like the trope of a Boomer mom as I repeatedly asked, “Do you know him?” whenever a new guy showed up. I didn’t mean “Are you friends?”; I meant “Are they Your Guys?” Sometimes they were, and I was honored to meet them. Sometimes they weren’t; they were just guys. We both laughed to the point of tears at a video that some guy had shared of his dad trying to teach him to bunt a baseball when he was 10 years old. I manually liked it with the remote control and then sent it to myself, from my husband, via direct message. On my TV.

“This intrigues me,” Jonathan Gray, a professor of media and cultural studies at the University of Wisconsin at Madison, told me when I asked him about the app. Scrolling has always had a social element, he said, and people will often show a funny or interesting video to the person next to them. But he was skeptical of whether they would want to share every bit of their feed with their loved ones. “It’s one thing when I turn my phone to my wife and say, ‘Hey, you’ll like this,’ but 90 percent of what I see, she won’t want to watch,” he said. “It seems kind of painful.” Plus, his wife is learning how to whittle at the moment, and he doesn’t want to watch a bunch of whittling videos.

[Read: The extras are tired]

Gray also noted that the recommendation algorithms sometimes take big swings and throw new things at users to learn whether they’ll be interested. One might worry a little about the big swings that could appear on your TV, which to others in the room might appear to be something you’ve already expressed enthusiasm about. When I asked the Instagram spokesperson Christine Pai whether the TV app would filter out any weird stuff, she told me that both apps are using the same recommendation system. (The only specific difference she cited is that the TV app will give an edge to horizontal videos, because they are better suited for the display.)

The app does allow users to play themed “channels” based on their preestablished interests, so you don’t necessarily have to show off your entire, highly variable and sometimes unpredictable feed. The idea with the channels seems to be that making the secret, private shame of scrolling into a collaborative activity will give it a new place in the home. It can be more like watching America’s Funniest Home Videos together after dinner and less like sitting side by side, staring silently at something in your lap. People feel ambivalent about scrolling feeds, Marika Lüders, a professor of media and communication at the University of Oslo, wrote to me on this point. We find it entertaining at times, but we also feel embarrassed and guilty about it. To her, moving Instagram from a phone to a TV seems like “a strategy to increase the status of short-form videos,” by putting them on a screen that people (currently) feel less anxiety about.

That makes sense to me, though I find it just as easy to imagine how this may backfire for the company. Many people who are attempting to cut back on their Instagram use remove the app from their phone and use only the desktop-computer version, which is clunkier and less comfortable to scroll through for hours. Using it is so nonintuitive and unnatural that it calls attention to the absurdity of one’s habit. Moving Instagram to a bigger screen, then, is usually a route not to normalizing it in that new space but instead to severing ties with it altogether. The differences between a phone and a TV are even more dramatic and may be even more off-putting.

Surely the novelty will wear off. Last week, while visiting my sister-in-law and her boyfriend, my husband and I asked them to show us their feeds on their TV. My sister-in-law’s was funny because it was full of wedding-planning content—she’s currently waiting on the requisite engagement ring—and because she kept getting videos of this one baby who’s obsessed with Bad Bunny. Her boyfriend got a hairless cat, a guy pretending to be Wolverine, and a recipe for butter-chicken macaroni and cheese. Those were a little funny, too, but because you don’t know him, you don’t get why and you don’t care. After 20 minutes or so, we got bored of the experiment and left for a baseball game. Later, in the quiet of my hotel room, I went back to my own, private phone.

© Illustration by Matteo Giuseppe Pani / The Atlantic

  •  

Google Just Ruined One of Its Most Important Tools

Earlier today, I used Google Earth to conjure images of terrible things: office buildings on fire, mass destruction in San Francisco, a smoldering crater in place of the Eiffel Tower. I was able to because Google had just decided to integrate its AI image generator, Nano Banana, into the service, which has historically been used by people seeking satellite or aerial imagery of real-world locations. 

Just open the site, “pick a spot on the map, and start bringing your ideas to life,” Google wrote in a press release announcing the update some 24 hours ago. So I did.

I was easily able to generate those violent images simply by searching for a location on Google Earth, clicking the “Create image” icon, and typing in a few words. The feature also readily doctored stills of less spectacular, and likely less immediately falsifiable, events: a homeless encampment on the White House lawn, protesters outside the Mar-a-Lago resort, immigrants streaming over the U.S.-Mexico border.

Google initially responded by directing people to check any suspicious images themselves. As fake images generated with this new Google Earth feature began circulating around the web, the company stated that it takes “misinformation seriously” and that “every image created with Nano Banana in Google Earth includes the SynthID digital watermark, so if someone is unsure about an image, they can ask the Gemini app or use Lens in Search to see if the image was AI-generated.” At first, Google did not remove or restrict access to the tool. But today, shortly after I reached out with a request for comment, the company reversed course and announced that it is “rolling back this feature in Google Earth while we work on implementing stronger guardrails.”

ai-google-map_2_720.jpg
Google Earth
An AI-generated image of a fabricated explosion at the Mar-a-Lago resort, created with Google Earth
ai-google-map_1_720.jpg
Google Earth
This AI-generated image from Google Earth falsely depicts a plane striking One World Trade Center.

Before it allowed people to create fake imagery, Google Earth was a unique resource for researchers, journalists, and intelligence officials, particularly those studying armed conflict and natural disasters. Satellite and aerial imagery can be used to monitor crop failure or deforestation, the creation of mass graves, and the results of bombing campaigns. Especially in conflict zones and other areas that are hard for people to reach, satellite imagery is a go-to method for establishing some sort of ground truth. After Google Earth rolled out the AI feature, though, one investigative reporter wrote on LinkedIn that the tool could be used to easily and rapidly create images of drone strikes that look “very close to what we’ve seen in Ukraine, Russia, the Middle East, and other war-torn conflict zones.” And instead of requiring malicious actors to find a screenshot and then get around some AI model’s safeguards, Google rolled everything needed for a misinformation farm into one smooth user interface. It took me all of four seconds to generate a rendering of a Trump Hotel on the Gaza Strip.

[Read: The AI industry keeps breaking the internet]

The problem should have been obvious to Google, whose other products already forbid such edits. I was able to create an aerial image on Google Earth of a plane flying into the new World Trade Center building, but when I tried to do this directly through Nano Banana, the tool refused to edit an image of the building to depict a terrorist attack. Indeed, 9/11 and other high-profile events are well-known, even classic, subjects for AI-image trolling.

This is not Google’s first time launching an AI feature, and in particular an AI image-editing feature, without serious safeguards. Last year, the company released an AI shopping tool that allows you to visualize what clothes might look like on your body by uploading personal photos. As my colleague Lila Shroff and I reported at the time, “With little friction, anyone can use the feature to create what are essentially erotic images of celebrities and strangers. Alarmingly, we also discovered that it can do this for minors.” In 2024, Google Gemini was ridiculed for generating images of a racially diverse group of Nazis but not of any white Wehrmacht soldiers. And Google’s most prominent AI feature, the chatbot-powered answers in its flagship search engine, were an utter disaster upon their rollout—the AI overviews told people to eat rocks and gave other potentially dangerous health advice. Only after tremendous public pressure did the company make a substantial change, and two years later, the AI responses in Google Search continue to be inconsistent and unreliable.

Google is, of course, not alone in releasing AI features that have had embarrassing, dangerous, and avoidable consequences. See, for instance, Elon Musk’s Grok generating more than 1 million sexualized images, including of children, over just a few days, or any number of embarrassing errors made by ChatGPT releases throughout the years. Again and again, the AI industry undercuts its rhetoric about safety by launching products with little or no due diligence. If, as every major AI executive has pronounced, this technology really could upend human civilization, their companies should perhaps start taking that responsibility seriously.

© Illustration by The Atlantic. Source: Google Earth.

AI-generated images produced using Google Earth show multiple fabricated violent events.
  •  

The Extras Are Tired

Less than a decade ago, when I was working on technology stories, my colleagues and I ran into an issue that I’m pretty sure had not occurred to the people who founded this magazine in 1857: how to style the word influencer, which was an occupation and cultural force, but one just emerging. We weren’t sure that all of our readers would know what one was, and we also didn’t know how exactly we would define the word ourselves. I spent the fall of 2018 sending a lot of emails about whether we needed to encase the word in scare quotes.

Quaint! Many—but not all that many—years later, influencer is very much a real job, no explanation required. As of 2023, 27 million Americans were paid to make online content in one form or another, at least according to one marketing consultant company. Enthusiasm from influencers can turn a random business into a sensation, while their ire can do the opposite. Donald Trump’s White House is full of influencers, but Joe Biden’s courted them too, in apparent recognition of their power. This week, Arizona State University announced that it would begin offering a bachelor’s degree in content creation—influencing by another name—through its journalism school.

In some ways, the influencer industry is more legitimate than it’s ever been. But it has always been precarious, and more than a decade into its existence, it is neither novel enough to be exciting nor established enough to have a real professional code. In an oversaturated market, rage bait is the last sure way to get attention, despite the way it alienates people over the long term. AI is swiftly becoming the dominant way many people get personal-seeming advice about how to live their life, which makes the usefulness of aspirational online content even less apparent than it ever was. And so, although influencers—especially lifestyle influencers—have never been universally respected, they lately seem to be openly reviled.

[Read: What happens when the tradwife dream goes wrong?]

Naturally, much of the influencer backlash lives online. A few months ago, someone asked on Reddit, “What’s an industry that provides zero value to society but makes billions of dollars?” Among the 5,300-plus responses: Ticketmaster, sports-betting companies, multilevel marketing schemes, private prisons, and—several times over—influencers. A hilarious number of people have found internet fame by making content about how much they hate other people who are internet-famous for making content. (“Everyone Is Finally Turning on TONE DEAF Influencers” is the title of one recent video, made by an Australian YouTuber with nearly 300,000 subscribers and a clothing line.)

But the juiciest fights play out in the physical world, which is where influencers very literally bump up against the people who can’t stand them. A few years ago, a coffee shop in Brooklyn banned photography after too many influencers clogged the café with tripods and handheld lights; earlier this month, Indonesia indicated that it would crack down on people creating content for pay while on tourist visas.

Last week, the scene of the debate was a gift shop in Nantucket, an island that has recently been overrun by vacationing influencers, just like Bali, Iceland, and Santorini before it. The store’s operators, evidently fed up with the stream of people filming inside, had a sign made that read No Influencers, hung it up in the store, and posted a picture of it on Instagram. There, it drew the attention of thousands of people, including Paige Paul, who has about 2 million followers across platforms, is married to a famous tennis player, and has been spending time on the island since she was a child. Paul, previously known as Paige Lorenze, declared the sign a misogynistic slight against an industry that is overwhelmingly female. The store’s owner, John Sylvia, said it was meant as a joke for locals, but the sentiment clearly came from an earnest annoyance: “A lot of people are tired of feeling like extras in someone else’s video,” he told New York magazine.

The fight felt freighted. Influencers today are a bit like plastic surgeons, or plumbers: On a societal level, many people sure seem to like what they do—they just don’t necessarily want to be right next to them while they’re doing it.

But influencers are unique in how they seem to be everywhere, particularly in places where people are trying to do things other than be on their phone to watch influencers. Of course we love the game and hate the player: It’s much easier to be annoyed by individuals than by concepts, especially when those individuals are, often, pretty annoying.

[Read: An urgent question for anyone who uses social media]

You’d need to be pretty clueless to not feel a little weird about the online attention economy and all it entails—the vanity; the grift; the slop; the desperation; the calculated intimacy; the endless consumption; the creeping sense that everything and everyone is actually just there to make you feel kind of bad about yourself and then sell you something. Social media can, of course, unite like-minded people, but it can also reward the kind of tribalist reactionaryism that can conflate disliking some women with disliking all women, or make an anti-consumerist folk hero out of a store that sells $2,750 baskets. The industry that Paul and her cohort belong to is unquestionably grim—but the industry isn’t walking around town with a selfie stick. There’s a reason that the sign doesn’t say no influencing, but rather no influencers.

As for the sign: Sylvia’s post was liked more than 10,000 times before it was removed (by Instagram, according to the store); a second one has now been liked even more. “They couldn’t have predicted it would get the traction that it ultimately did,” People magazine wrote of the store in one of many articles about the sign that have popped up online over the past few days.

Sure. I will grant that the future is inherently unpredictable. But it is undeniable that posting the sign online is its own kind of influencing, insofar as it involved leveraging the internet’s focus and wrath for one’s own benefit. (“Came for the friendship baskets, stayed for the shade,” the original post’s caption trolled.) The sign is handsome, and crucially, it is inside the store—if you want to see it up close, you need to go in, past the baskets. Visitors have already started posting the sign on social media, and the store’s Instagram account has added about 8,000 followers, according to an interview that Sylvia’s partner, Jessica Jenkins, did with The New York Times. “It’s come with a lot of drama,” she told the paper. “But it also brings in business.” Any influencer would understand that.

© Illustration by The Atlantic. Source: Getty.
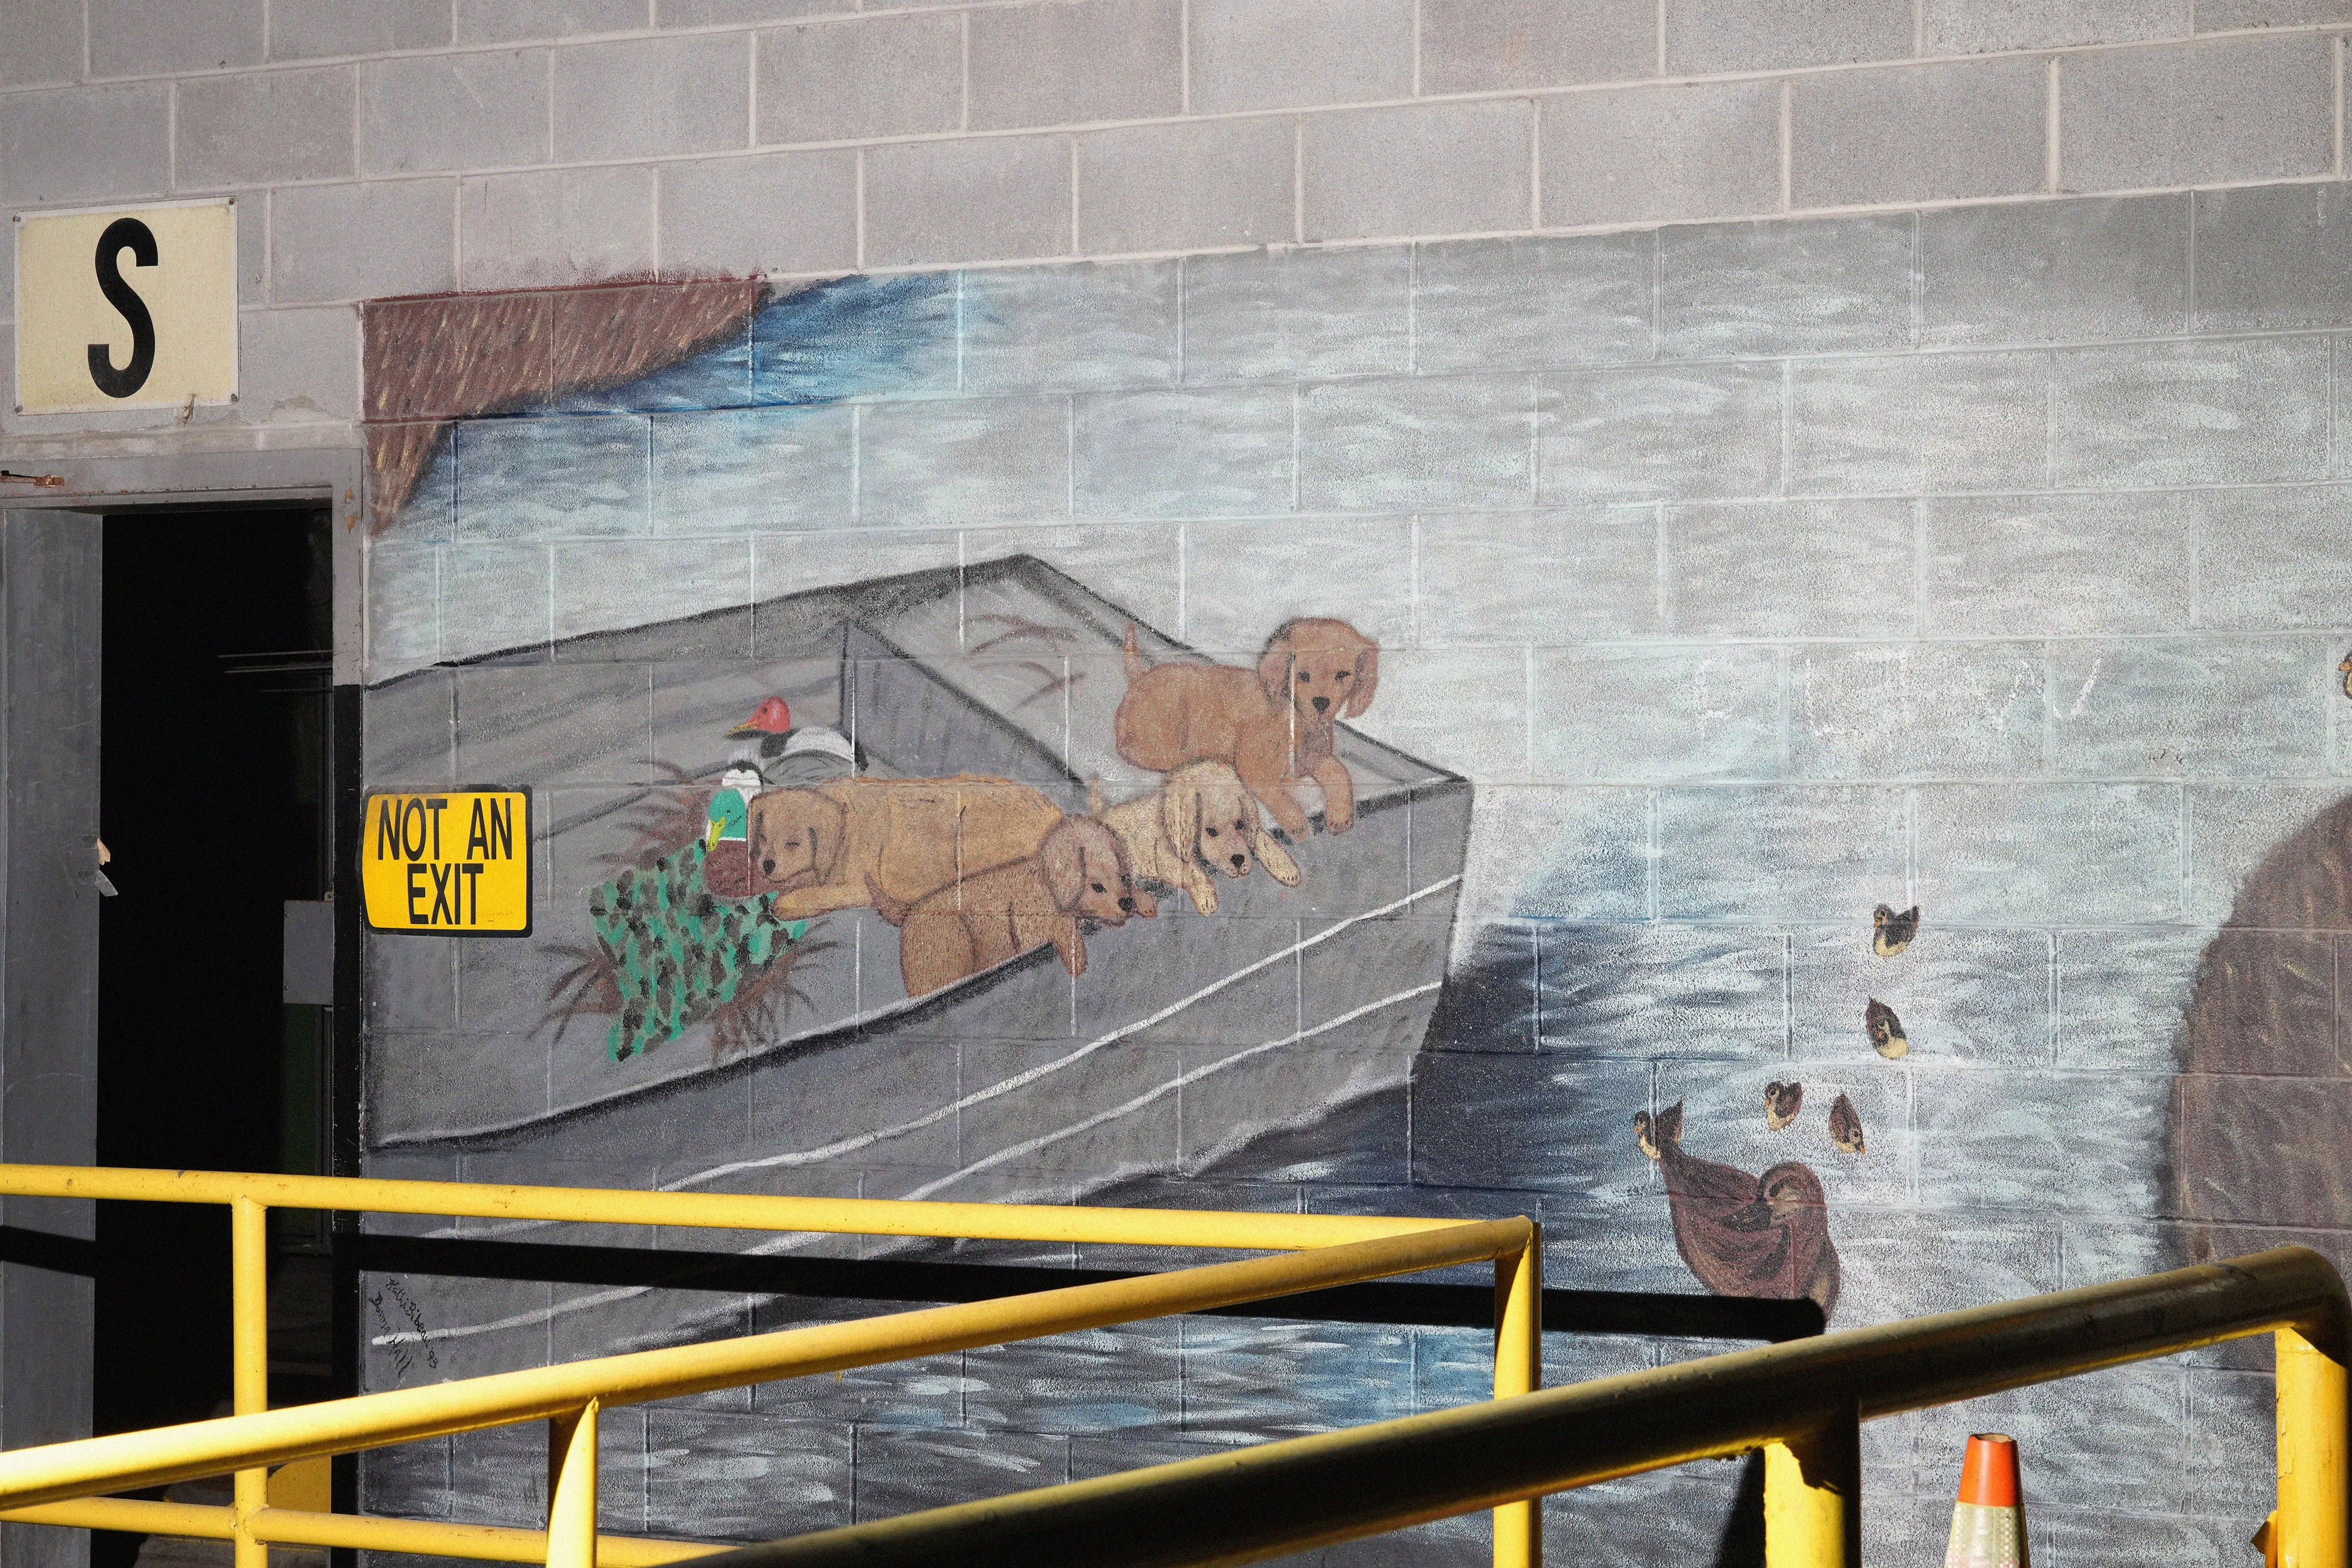
  •  

Something Weird Is Happening in Math

One of the winners of this year’s Fields Medal is headed to OpenAI. Last Thursday, Jacob Tsimerman was one of four mathematicians awarded the prestigious honor, which is sometimes called the Nobel Prize of mathematics. The same day that he won the Fields, Tsimerman announced that he would be going on leave from the University of Toronto to work on AI safety.

As my colleague Rose Horowitch and I wrote last week, top AI companies now employ a range of academics, including physicists, philosophers, economists, and, of course, mathematicians. But given Tsimerman’s renown, his decision in particular seemed to catch many people by surprise. “It’s like hiring Lionel Messi as project manager,” one machine-learning professor posted on X. Tsimerman’s expertise is in number theory, and he won the Fields for his work on the André-Oort conjecture, among other contributions. So far, his mathematical research hasn’t focused on AI safety. But he has expressed interest in the topic: Last year, Tsimerman co-wrote a report outlining a taxonomy of five potential scenarios in which humanity is killed off because of AI. In one example, a “global civil war” erupts between tech companies and governments.

[Read: Where did all the computer-science professors go?]

Tsimerman’s move comes at an important moment for both AI safety and mathematics. Earlier this month, an OpenAI agent broke out of the company’s internal environment during safety testing and hacked into another AI company’s software. Meanwhile, AI’s math capabilities are also rapidly advancing. In May, OpenAI researchers used an internal model to disprove an 80-year-old conjecture; more recently, an Anthropic mathematician prompted Claude to resolve an even older one. Mathematics is entering a “turbulent period,” Terence Tao, perhaps the world’s top mathematician (and himself a Fields winner), said in a presentation last week.

On Wednesday, I called Tsimerman to ask about the future of math and his decision to join OpenAI.

This conversation has been edited for length and clarity.


Lila Shroff: There’s been a lot of excitement about AI and its applications in math for years now. But over the past few months, models have started solving research-level problems. Could you speak about the shift that’s taken place?

Jacob Tsimerman: A few years ago, models were having trouble with even the most basic questions. But they’ve steadily been improving. First, they got very good at these contest problems for high-school students, which made some mathematicians take notice. But then, over the past few months, we’ve had an explosion of research results that professional mathematicians would be proud to achieve and publish. We’re seeing this happen now on a large scale. If things continue along this track—which many of us, including myself, think that they will—pretty soon we will be at a point where AI systems are robustly better than humans at what mathematicians currently do. At that point, we’ll have to rethink how the entire field works.

Shroff: Can you say more about what that future might look like?

Tsimerman: It depends on the perspective from which you approach it. From one point of view, I think it will be extremely exciting. We might speed up the process of generating interesting mathematics by enormous factors of 10 or 100. If that happens, we might see the connection between pure math and applications (which typically takes many decades) really speed up and become a much tighter pipeline.

But from the perspective of research mathematicians, and especially young people who are pursuing a Ph.D. in mathematics, it’s a bit of a turbulent time. The skills that we’ve acquired and learned to propagate might become less relevant than they are now.

Shroff: I want to turn to the announcement you made last week that you’ll be joining OpenAI. When did you first start thinking about AI safety risks, and what motivated your decision to now make it your primary focus?

Tsimerman: I have been following conversations about AI for about two decades now. There are a number of communities that were, in retrospect, extremely prescient about what we are now seeing come to pass. I personally started to get more invested around 2016, when AlphaGo came out. And then, when ChatGPT happened and I could see that these systems could really speak, I didn’t see why they wouldn’t become much, much more powerful and potentially more capable than humans at a variety of tasks. Back then, it was already clear to me that I was eventually going to pivot to AI safety, most likely.

Now is a particularly good time, because only very recently have AI systems become good enough that we can delegate coding tasks to them. That makes not having training as a software engineer much less of an impediment than it used to be. It used to be the case that if I wanted to run experiments with AI systems or any kind of large data sets, it would be extremely time-consuming. I’d have to learn all types of computer science and programming and then debug, and it didn’t really make sense to me to spend so much time doing that. Now it’s substantially easier.

Shroff: You’re right that certain communities were very prescient with their thinking about AI risks. But there are lots of people who are skeptical about some of the more extreme AI-risk scenarios, such as human extinction.

Tsimerman: There’s this bias that stories that were first written down in science fiction aren’t going to come to pass in the real world, and that it’s naive to think that they will. We also have a culture where we’re inundated with people telling us that every new development is the next big thing, and that we should change everything we’re doing to react to it. Most of the time, it proves incorrect. So I think people have a healthy sort of immune reaction to that.

But what I would encourage people to do is to actually keep track of their predictions for the future and write them down. Then—three months, six months, nine months, a year from now—compare how the world is with what you expected it might look like. If we told people five years ago about the kind of AI systems we currently have, almost everybody would have reacted with disbelief. Human extinction seems so grandiose that it naturally inspires a reaction of dismissal. People don’t want to engage with that, which makes sense to me. The whole point of writing that paper on omnicide was to get people to viscerally understand the kinds of risks that are possible.

Shroff: Can you say anything about the work you plan to be doing at OpenAI? What role is there for mathematicians to play in working on AI safety?

Tsimerman: AI right now is a very empirical science. We don’t really have a developed theoretical understanding of how AI systems work, why they accomplish what they do, how they accomplish what they’re doing, and how, in a given circumstance, they’re going to behave. Mathematics is historically the language by which you take intuitions and fuzzy notions of how things work and you make them precise. We’ve done this with information theory; we have done this with complexity theory. Just a little bit of understanding and precise definitions can provide a ton of mileage. Once we have that understanding, the hope is that we could do a better job of anticipating the behavior of new AI systems, adjusting for them, controlling them, and reacting to them. That’s where I think mathematicians fit in.

Shroff: Why work at a private company instead of pursuing the same questions in academia? Do you worry about loss of independence, whether that’s constraints on what you’re able to publish or restrictions on the questions you’re able to pursue?

Tsimerman: Yeah, there’s definitely a trade-off between going to work for a private company and going to work in government or staying in academia. I very strongly believe that what we need is a healthy ecosystem for AI safety. The work that the labs are doing on that front is very important. There’s a bunch of third-party organizations that are pursuing AI safety independently, and I think we need way more of them. I also think we need some regulation and organizations that are directly funded by the government to provide evaluations of these systems. I want all of these components to interact with one another on a regular basis. So I have engaged with a number of AI-safety organizations, and I’ll continue engaging with them.

For me, at this moment, going to OpenAI made the most sense in part because one of the things that I’m most lacking is a background in software engineering. I’m a lot more comfortable with the theoretical aspects of neural networks and how AI systems work, and less so with the entire pipeline of how we train these things and how we get them to do what they do. So from the perspective of just getting myself in a better position to understand the whole picture, joining an AI lab right now made the most sense.

[Read: The return of ‘move fast and break things’]

I’m going on leave from the University of Toronto. But I’m still a professor and faculty member there, and I plan to stay as such. Things are moving so quickly that I hesitate to make a concrete prediction for what might happen even a year from now. I’m keeping an open mind, trying to see how things develop in terms of capabilities, with my own understanding, with how the world reacts to AI, which I think is changing month to month. But I don’t have a clear plan as to how things will unfold.

Shroff: There is an open letter going around signed by more than 1,000 employees at top AI companies, including leaders at Anthropic and OpenAI. It calls on the U.S government to create infrastructure needed to “deliberately pace the frontier of automated AI development.” You wrote online that you’re very happy to see this letter. How would we actually go about coordinating a slowdown or a pause if one was needed?

Tsimerman: Coordination is one of the most important things we have to do around AI. It’s also one of the more difficult things. The thing that I really don’t like seeing in public discourse is when people say, Coordination is very difficult, so obviously we can’t do it, and you’re being naive if you even try. That’s an unhealthy way to view the world, and it’s also deeply false. There are so many things in the world that work really well and that require a huge number of decisions to have been made in a coordinated fashion. For example, the internet is an extremely complicated technology that is highly international, with many organizations cooperating all the time. Does it work perfectly? No, but it works extremely well.

One message that I want to support is to not let cynicism prevent us from undertaking difficult coordination problems for the good of all of us. That’s something that has always been true. It is not specific to AI. And it remains true today. This does not mean being naive in assuming that people in different parties and organizations don’t have their own incentives and interests in mind. Of course they do. But if you try, then you really can get a lot done. We have in the past, and I think we need to with AI.

Shroff: We spoke before about your interest in working on safety. Are you also interested in working on the capabilities side, especially with regard to math capabilities?

Tsimerman: No, I’m very focused on the safety side. The capabilities side has a lot of interesting questions, and AI has a lot of promise. But capabilities are coming along just fine. I don’t think that’s where we need to put our attention right now. The safety side has a lot more work to be done.

Shroff: Are we approaching a point where anyone could go fire up ChatGPT or Claude Code and say, Go solve a hard open math problem for me?

Tsimerman: Yes, you can literally type in, Go solve an open math question for me, as people have, and your system will go look for some and try, and maybe it will succeed at solving some of them. So we are in that world.

Now, I don’t think that’s a particularly good use of people’s time. Because first of all, that’s almost certainly going to be automated. We’re going to have systems that regularly look for conjectures that are out there and for other ways to approach math problems. Any one person, especially somebody who doesn’t have math training, just typing in a random query isn’t really playing an important part. So although it’s fun to do, I wouldn’t recommend spending a huge amount of time doing it for people who don’t have the background to interpret what they get. Because we also get a lot of slop this way. Sometimes, when people really don’t understand mathematics and the AI system gives them something, they will post stuff like: Here’s what my AI system gave me. I don’t know if it’s right, but maybe it is? Could a mathematician please look at it? I don’t think that’s super useful.

Shroff: I’ll admit it’s quite tempting. Last week, I told my agents to spend the night solving open math problems. They sent me stuff in the morning, but I had no idea what to make of it.

Tsimerman: For problems with a lot of technical definitions, you have very little chance in a day or two of really understanding them. But there are classical math questions that are perhaps less difficult to understand that have been open for a long time. I would suggest that people engage with AI in a way where—even if it’s doing a lot of the work—you’re still learning something from the experience. If you’re just telling your agents, Keep going, and you aren’t developing any comprehension for yourself, then that’s really disempowering yourself.

Shroff: Does what is happening in mathematics right now provide any indication of what other disciplines should expect to see occur as AI capabilities advance in other domains?

Tsimerman: A lot of technical fields are going to be affected—certainly in physics, in some areas of economics, and in top branches of chemistry. In other fields, such as biology and experimental physics, it’s less clear what’s going to happen, because it’s helpful to run experiments. It’s possible that AI systems may eventually become intelligent enough that they will figure out how to reason very productively about experimental physics or biology without actually running experiments. But that’s more speculative—right now that seems like a pie-in-the-sky dream. In terms of the more theoretical parts of different fields, though, we’ll see stuff happening very, very soon.

© Illustration by The Atlantic. Sources: Erin Blewett / AFP / Getty; Hubert Fanthomme / Paris Match / Getty.

  •  

The Return of ‘Move Fast and Break Things’

The AI giants talk a big game about the future they’re building. Anthropic CEO Dario Amodei has previously written that AI could usher in a world so perfect that “many will be literally moved to tears”—a world pruned of disease, poverty, and illiberalism. “We’re now in the singularity,” OpenAI CEO Sam Altman said over the weekend on a podcast, and it will be “awesome for the world.” In an interview last week, Elon Musk declared that, in a decade’s time, AI will make us so prosperous that “money won’t matter.”

Unfortunately, life with AI is, so far, less glorious than what’s been promised. The same day that Altman heralded the singularity, Claude users discovered something alarming: Many conversations with Anthropic’s chatbot were available on the open web, discoverable with a Google search. Those public logs and projects reportedly contained medical records, phone numbers, internal corporate documents, and cryptocurrency-wallet keys.

Anthropic was quick to point out that users were responsible for the material being available online: The chatbot gives people the option to “share” their AI conversations via a link that they can send to other people or post online. Claude notes that these links are “public,” which means they can also be hoovered up by Google Search. An Anthropic spokesperson told me that “these shareable links are not guessable or discoverable unless people choose to share them themselves. When someone shares a conversation, they are making that content publicly accessible, and like other public web content, it may be archived by third-party services.”

[Read: ]Anthropic accidentally made the perfect commercial

No reasonable person would assume that creating and sharing a link to an AI conversation or presentation would make it searchable by anybody on the World Wide Web. The Claude interface does caution that publishing an “Artifact”—Anthropic’s terms for dashboards and other minor tools made with Claude—could make it “potentially visible in search engine results,” but it does not provide such an explicit warning when sharing a chat. As of this writing, the Claude chat logs no longer appear to be searchable, but at least some Claude Artifacts are.

Those exposed chats were just the latest in a seemingly endless string of AI snafus: misinformation, data leaks, cybersecurity breaches. Immediately after the launch of ChatGPT, one could charitably argue that these lapses were by-products of a new and strange technology. Altman remains fond of saying that the AI industry must learn “from contact with reality.”

But four years into the AI boom, attributing these blunders to growing pains is too convenient. The sheer volume of transgressions—many of them predictable—suggests that what’s actually happening here is widespread carelessness. The same AI executives who promise that their products will deliver human civilization to a triumphant future seemingly cannot release consumer-grade tools without face-planting.

This isn’t Anthropic’s first time leaking user conversations. Last fall, hundreds of Claude chat logs were also inadvertently indexed by Google. At the time, Anthropic attributed the episode to users posting share links online. Last year, OpenAI and xAI exposed hundreds of thousands of conversations in a similar fashion; a number of shared Grok conversations remain searchable. Neither OpenAI nor xAI immediately responded to a request for comment.

Then there are all of the other blunders. Just last week, OpenAI models autonomously hacked into another tech firm, Hugging Face, during internal testing. The issues that led to this sort of attack are fairly well documented, but OpenAI failed to stop its own bots from breaking out. Hugging Face has since said that the OpenAI models appeared to have been rogue for several days. Earlier this week, Reuters reported that OpenAI models had hacked a customer account of yet another tech company.

Altman, Amodei, and many other AI executives have repeatedly warned about AI-enabled cyberattacks and the possibility of models going “rogue.” Meanwhile, their own products are making the entire ecosystem feel more unreliable and dangerous.

It’s easier than ever to launch widespread hacking and phishing campaigns, and AI-written code has itself been shown to have more security flaws than human-written programs. Although AI systems are being tightly woven throughout the infrastructure of the internet, they crash frequently. Hackers recently discovered that a Meta AI customer-service bot would hand over access to tens of thousands of Instagram accounts if asked. (A Meta spokesperson told me that this “wasn’t due to the AI agent itself.”) Nonconsensual porn—that is, sexually explicit material made using the likeness of real people, unbeknownst to them—can be generated with more ease and speed and at greater scale than ever before. And at this point, you can probably assume that most of the text you read on LinkedIn or X is AI-generated.

Despite its grandiose promises, Silicon Valley is embarking upon an era of profound irresponsibility. Last year alone, ChatGPT allegedly pushed people into mental-health spirals, Google Gemini’s under-13 version was easily coaxed to “talk dirty,” and Grok repeatedly spouted racist bile. As quickly as these errors were addressed, new ones cropped up.

Silicon Valley has a long history of world-historic invention and progress—and it also has a long history of impressive rhetoric and disappointing realities. Facebook promised to “bring the world closer together,” Google to “organize the world’s information,” Twitter to foment democracy around the globe. For better or worse, people have experienced dramatic changes as those promises have played out around us almost in real time.

Anthropic and OpenAI’s prophecies are grander and vaguer: Utopia is forever on the horizon, but we don’t have a clear deadline or a road map of how we get there. And apparently, those leading this charge toward the future care little about what happens along the way.

OpenAI, Anthropic, xAI, and Google DeepMind have become behemoths practically overnight. For now, they are growing because of their recklessness, not in spite of it; in the quest to erect a digital god, the internet has become collateral damage. Perhaps these companies really will remake human civilization—but in the meantime, they can’t stop leaking your chats.

© Illustration by The Atlantic. Source: kampee patisena / Getty.

  •  

The New iPhone Underclass

Buying a new smartphone comes with lots of decisions. iPhone Pro or iPhone Air? “Cosmic Orange” or “Deep Blue”? Now there’s a new consideration to add to the list: buy or rent? Yesterday, Apple announced a new monthly lease program, which will allow prospective buyers to rent new electronics such as iPhones, MacBooks, iPads, and Apple Watches via an agreement with Klarna, the same company that facilitates monthly payments for $4 polyester underthings on Shein.

Perhaps you already make monthly payments for your iPhone. Since 2015, Apple has offered an “iPhone Upgrade Program” that similarly offers customers the option to pay off the device over time instead of in one lump sum. But under that arrangement, the monthly payments were not a lease but rather installments of a loan. Failing to pay your bill might have hurt your credit and eventually led to aggravated calls from a collections agency, but your phone was your phone, with all the candy you could crush.

Not anymore. The Klarna plan—“Apple Upgrade,” which replaces the iPhone Upgrade Program—is truly, legally, a lease. This is confusing! And it’s confusing in part because this is not how Klarna, a well-known buy-now, pay-later service, typically operates: When you use Klarna for clothing from Shein or lip kits at Sephora or an Xbox at GameStop, you’re paying back a loan, exactly as you were in the original iPhone Upgrade Program. Same if you use Klarna to buy a Samsung Galaxy phone. But with Apple Upgrade, you are renting: The Mac or Apple Watch is not yours until the final payment is made.

[Read: I am in cloud-storage hell]

There’s nothing wrong with flexibility, and leasing models exist for many expensive items—cars, grand pianos, apartments. Not everyone wants or needs to own property. Many people would rather have a high-end device at an affordable monthly cost rather than pay for one outright; all the better that they can upgrade to a new model before they’ve even finished paying off the entire cost.

But Apple products are particularly personal things. They’re communication devices that hold your intimate photos and videos, health data, and so forth. A rental model puts consumers in the strange position of storing all of this information in a gadget that Apple and Klarna maintain a lot of control over. Missing three consecutive payments with Klarna will obligate you to return the device or pay off the entire balance immediately. It is also theoretically possible that Apple or Klarna could eventually restrict access to various features if lease payments are missed; 9to5Mac has reported that code for such restrictions is present in a beta version of the upcoming iOS 27. When I reached Apple for comment, the spokesperson Brian Bumbery said that “there will be no restrictions or changes to functionality due to missed payments,” though why iOS 27 includes these options remains unclear. (Klarna did not respond to a request for comment.)

The shift to renting versus owning is also symbolic of darker currents in the tech industry. Thanks to a shortage of memory chips produced by the profoundly resource-hungry and inefficient AI industry, consumer electronics are becoming much more expensive across the board. Last month, Apple raised prices on many of its devices, citing the increasing cost of memory. The new upgrade program will make Apple’s electronics look more affordable than they really are.

[Read: The $10,000 MacBook Pro is here]

Consider a student or a young professional, or perhaps an underemployed older one, who needs a new laptop. They decide on a MacBook. Apple Upgrade will appear to be the best deal: In its announcement, Apple offers the example of a 14-inch MacBook Pro that retails for $1,999 but that can be had for a monthly lease. Perhaps this person goes for the two-year term, which has them paying $54 a month. Best Buy, which currently has the same computer on sale for $1,849, offers an 18-month loan repayment with $103 installments. Apple’s deal appears to be cheaper: The 24-month lease adds up to $1,296; Best Buy’s 18-month loan lands at the store’s full retail price of $1,849.

Why does Best Buy’s laptop seem more expensive? It’s because the plan is actually designed for you to fully pay off the device. At the end of the 24-month MacBook Pro lease, meanwhile, the consumer will still owe $703, meaning that the actual total price of the Apple arrangement is $1,999—higher than Best Buy’s offer. A person can choose to pay off the full amount, return the device outright, or swap for a new one. This is a lot of money, and so the likelihood is that this customer will just go ahead and do the trade-in, restarting a cycle in which they are bleeding their bank accounts to pay for a device they do not own and possibly will never own. And on it goes, in perpetuity.

[Read: Watch Apple trash-compact human culture]

Apple, which reached a market value of more than $5 trillion, its highest ever, the same day it announced Apple Upgrade, has produced a scheme that will eke out more money from its customers than it did before. (Notably, the new plan does not include AppleCare+, as the previous iPhone Upgrade Program did, so consumers will have to add the cost of the warranty or risk having to continue paying the rental fee on a device that they lose or break.) All of this can feel cynical, but of course many technology companies are attempting some version of the same premise: At this point, I pay monthly or annual subscription fees to Apple, Google, Anthropic, Amazon, Sony, and Nintendo for services layered on top of products that once took far less from me. Doing so grants me access to cloud storage and advanced features that would now be difficult to separate myself from. I walked into the trap myself—even saw it coming—but I am nonetheless ensnared.

© Illustration by Matteo Giuseppe Pani / The Atlantic

  •  

Is This What Comes After AI Slop?

Most self-published authors can only dream of writing something as popular as Daggermouth. Set in a surveillance state ruled by a masked elite, the novel traces the unlikely romance between the president’s son and an assassin hired to kill him. Since H. M. Wolfe uploaded Daggermouth to Amazon as a Kindle ebook, it has been a viral hit. “Did I finish Daggermouth, or did Daggermouth finish me?” a TikTok book influencer gushed. In February, Simon & Schuster paid seven figures to secure the publishing rights to the book and its sequel, which is due out next year.

Daggermouth has spent months on USA Today’s best-seller list and is ranked No. 1 in Amazon’s “science-fiction romance” genre. It also tops a less prestigious list, one compiled by academics studying AI writing. Among thousands of self-published Amazon ebooks that they identified as containing “substantial AI text,” none was more popular than Daggermouth.

Until recently, AI fiction has been easy to dismiss as slop. On Amazon, new-book releases nearly tripled from 2022 to 2025. (That’s probably not because humans suddenly dedicated themselves en masse to the written word.) Many are blatant copycats of existing titles, seemingly intended to trick readers into buying them. Their sales figures are generally meager; the reviews, indignant. A suspicious number of them feature protagonists with the same names. Last year, readers of one fantasy novel noticed a line that seemed to be responding to a prompt asking a chatbot to write in the style of another author. But if a book as beloved as Daggermouth were written with a chatbot, it would raise an awkward question: Could AI fiction be getting … good?

In a new study, researchers randomly selected more than 14,000 Kindle ebooks and ran them through Pangram, an AI-detection tool. One in five came back as more than 25 percent AI-written; Daggermouth returned 60 percent, according to an underlying data set that the authors shared with me. Those numbers, they acknowledge, tell us only so much. The researchers grouped together text that Pangram had flagged as either “AI-generated” or “moderately AI-assisted” (the latter of which can mean that AI was used to edit or polish human writing, or vice versa). And although Pangram has a low rate of false positives, it is not perfect.

[Read: America has a Pangram problem]

So the study’s authors, led by Tuhin Chakrabarty, a professor of computer science at Stony Brook University, devised another check. They scanned each book’s text for “rare expressions”—strings of at least five words in a specific order—that also appear in other suspected AI books but almost never in human-written ones. Daggermouth had many of them. For instance, the following sentence appears near the end of a multipage sex scene in Chapter 27: “They collapsed together, a tangle of sweat-slicked limbs and racing hearts.” That same sentence, word for word, also shows up in another self-published ebook by a different author. Or consider this line from Chapter 38 of Daggermouth: “Her pulse thundered in her ears, drowning out the murmurs of the crowd.” It’s also in an ebook by another author who has published more than 400 different titles on Amazon in the past three years.

The study has yet to be peer-reviewed, and to be clear, there is no definitive proof that Wolfe used AI. “The suggestion that I used generative AI to write Daggermouth is wholly untrue,” Wolfe said in a statement sent by her lawyer. “I wrote this book myself. I have been outspoken about my opposition to generative AI and what it’s doing to writers, artists, and the creative community. I don’t believe it belongs in the writing process.” Referencing Pangram’s limitations, Wolfe added that “accusations like these have real consequences for authors, and they should not be made on the basis of technology that is known to be unreliable.” Susannah Lawrence, a spokesperson for Daggermouth’s publisher, Simon & Schuster, told me in an email that the company stands behind the book, noting that it went through “the same editorial and production process as our other published titles.” Neither Wolfe nor Lawrence addressed my questions about the “rare expressions” that Daggermouth shares with other recent ebooks.

Chakrabarty, who researches AI writing, told me that Daggermouth has “too many telltale signs” of AI for him to buy that explanation. He cited Chapter 18, “Thank You,” as an example: His research team broke it into 12 chunks for Pangram to evaluate, and the tool classified all parts as AI-generated. (In my own spot checks, the tool classified the first few paragraphs as human-written and the rest of the chapter as 100 percent AI.) I ran this by Mohit Iyyer, a professor of computer science at the University of Maryland who wasn’t involved with the study. An expert on AI-language detection, Iyyer told me that even accounting for Pangram’s fallibility, it’s “almost statistically impossible” for an entirely human-written book to register as 60 percent AI. He added that the study’s broader methodology, which connects AI writing to ebook sales, is sound.

Whether or not you believe that Wolfe deserves the benefit of the doubt, the same questions about how Daggermouth was written apply to a growing number of other hits on Amazon. Chakrabarty’s study found that books written with “substantial” AI assistance made up 20 percent of Amazon’s ebook catalog, 12 percent of sales, and 10 percent of best sellers in their genre.

Yet Daggermouth stands out for more than just its popularity. The second-best-selling ebook in the data set is Inked Athena, by Nicole Fox, an author who has 418 titles listed on Amazon. Daggermouth, in contrast, appears to be one of just two novels to Wolfe’s name in 2025, and its sequel is not due out until 2027—an indication that Wolfe’s process likely involves significant amounts of genuine human craft. Iyyer said that using AI in a way that results in a novel that’s actually enjoyable to read takes “a huge amount of effort by a human author.”

[Read: The future of writing is a lot like hip-hop]

Another difference: Jennifer Prokop, who reviews books for Kirkus and co-hosts Fated Mates, a popular podcast about romance novels, told me that people in her world keep talking about Daggermouth. “Nicole Fox, I’ve never heard a single soul talk about her,” she said. (Fox did not respond to a request for comment.) Prokop sees mechanical prose cropping up mostly in self-published ebooks, for which the dominant platform is Amazon’s Kindle Unlimited subscription service. Just because an ebook is charting on Kindle doesn’t mean people are devouring it. Grifters can now use AI to crank out titles by the dozen and then use all kinds of tricks to entice readers, such as buying hundreds of bogus five-star reviews and paying click farms to juice their metrics. “If you can get 10,000 people to read 10 pages of your book, and you have 300 books you’re putting out,” she said, you can make real money. “But you’re not actually writing romances people want to read.” (Amazon did not respond to a request for comment.)

If Daggermouth is AI, then maybe it’s just an outlier—a book that caught the perfect wave of social-media hype. (A series of controversies surrounding the book, including accusations of the author’s AI use and a backlash to the cover art for a special hardcover version, seemed to galvanize its fans and bring it even more attention.) The notion that AI writing requires a perfect confluence of events to top the charts is a comforting thought. But it might not be true. “Everyone thinks they can tell AI writing,” Christine Larson, a journalism professor at the University of Colorado at Boulder who studies the effect of technology on creative work, told me. “But I don’t think we can tell so much.” Privately, several authors and editors have told her that they’re using the technology to accelerate or improve their output. “I totally buy into the idea that a human working with AI can write something that is compelling,” she said. “I have absolutely no doubt that we will see more of this in the future.”

If she’s right, then the question is not about whether we’ll see AI best sellers. It’s about whether anyone involved with them will admit it. Coral Hart, a South African author who uses AI to help her publish hundreds of books a year under different pen names, told me that she works hard to keep her pseudonyms secret after she received death threats and thousands of one-star reviews following a New York Times story about her. Hart claimed that she has had successful authors join the classes that she teaches on AI writing, though she declined to name them. “Until they stop the bullying, the witch hunts, and the ousting, I don’t think authors are going to be transparent, and I don’t blame them,” Hart said. “I’m certainly not going to.”

The taboo against the use of AI in literature is understandable: Among other things, it’s wrong to take credit for a book that you didn’t write yourself. Shunning authors suspected of employing AI might work if there were any way to tell for sure—which there isn’t. That shaming ritual puts the moral burden on individual authors instead of on the mammoth corporations responsible for the system in which they’re trying to eke out a livelihood. It also tends to collapse any distinction between pure AI slop and human writing that is assisted by AI. The upshot is a state of affairs that feels untenable: AI writing can be lucrative, but only if it’s kept secret. Eventually, something’s got to give.

© Illustration by The Atlantic

  •  

Even Trump Can’t Spin This One

If President Trump has one true skill, it is conjuring up alternate realities and getting his supporters to accept them. The examples are everywhere: dismissing stories he doesn’t like as “fake news” from corrupt media, casting the January 6 rioters as victims, election denial. After he baselessly insisted that there had been rampant mail-in voter fraud in the 2020 presidential election, 11 states made mail-voting access more restrictive. His repeated false claims in 2024 that Haitians in Springfield, Ohio, were eating pets led to real threats against the community. Trump builds a world, and by virtue of his power and influence, all of us end up living in it in some way or another.

That era may be coming to a close, in large part because of the way he and his administration have bungled the war in Iran. Trump seems unable to spin this conflict, divert sufficient attention away from it with a new controversy, or end it outright. His social-media posts, which once acted as a de facto assignment editor for the mainstream media, no longer command the same attention or respect. Now, interspersed with AI slop and inexplicable middle-of-the-night reposting binges, Trump’s Truth Social screeds sound more like the fevered ramblings of a radicalized Facebook uncle. For the past five months, he’s been trying to convince the American public (or at least his Truth Social followers) that the war is over, or ending, or a rousing success. His administration is even retroactively changing on the Pentagon’s website the number of American service members who have died in the conflict. But no one seems to be falling for it. His posts don’t have the juice. His alternate universe is no match for the harsh reality of war.

[Read: The war is lost. Now fix what it broke.]

In the Trumpian vision of the world, the U.S. invasion of Iran was not only necessary but also urgent: In February, Trump alleged that Iran was attempting to rebuild its nuclear-weapons program and had continued developing long-range missiles that were threatening U.S. allies and could reach the United States “soon.” But Trump’s claim is dubious, at least according to a March 2025 U.S. intelligence assessment, which noted that “Iran is not building a nuclear weapon.” Experts also cast doubt on the strength of Iran’s missiles: “There is little evidence that Iran could build missiles that reach the United States in the near future,” Emma Sandifer of the Center for Arms Control and Non-Proliferation told FactCheck.org in March.

Justifications aside, the attacks, which were not authorized by Congress, were immediately unpopular with Trump’s base, which elected him in part for his isolationist tendencies. (On Election Night 2024, Trump even remarked, “I’m not going to start a war. I’m going to stop wars.”) Iran’s predictable retaliation, closing the Strait of Hormuz and drastically cutting off crucial supply routes for oil and other natural resources, subsequently drove up prices for goods around the world—immediately exacerbating the unpopularity of the conflict and shocking the markets. The fallout appeared to take Trump by surprise, and in the early weeks of the war, he used his bully pulpit for damage control: On March 9, with Brent-crude futures spiking to nearly $120 a barrel, he gave an interview to CBS News suggesting that the “war is very complete, pretty much.” Oil futures swiftly plunged to less than $90 a barrel.

Trump used this tactic repeatedly. On March 20, he posted on Truth Social that the U.S. was “close to meeting our objectives” in Iran. Oil futures dropped. On March 23, he signaled that discussions between the U.S. and Iran were productive, leading Brent crude futures to plummet by 13 percent. Each time, Trump offered no real proof of his claims, yet markets responded to his version of the story. An NBC News analysis found 32 examples of the president suggesting that the war was coming to a close. “We don’t need people that join Wars after we’ve already won!” Trump posted on March 7, in response to the United Kingdom considering sending military support. In late March, Trump posted that operations were “winding down”; that same day, he rejected a suggestion from Pope Leo that there should be a cease-fire. In early April, he posted that Iran had asked for a cease-fire; later, Iran called his claims “false and baseless.”

Tenuous agreements between the U.S. and Iran have been broken repeatedly. On July 12, the U.S. resumed heavy air strikes on Iran following an Iranian attack on a container ship in the region. As my colleagues Nancy A. Youssef and Jonathan Lemire recently reported, “The Trump administration is back at war. It just doesn’t want to admit it.” The commander in chief has become the boy who cried “Mission accomplished.”

[Nancy A. Youssef and Jonathan Lemire: War by any other name]

As a result, Trump’s posts have become more erratic. On June 23, in response to rising gas prices, Trump posted on Truth Social, in all caps, to nobody in particular, “EVERYONE, KEEP OIL PRICES DOWN. I’M WATCHING! YOU’RE PLAYING RIGHT INTO THE HANDS OF THE ENEMY. DON’T DO IT!” And his posts no longer seem as able to influence the market. A recent report from Axios claimed that bond-market traders have stopped paying strict attention to Trump’s social-media feeds to read the economic tea leaves: “Researchers from JPMorgan show that for the most part, his social media posts are noise, with very little ability to move the market.”


And yet, Trump is attempting to double down. Last week, Truth Social announced that it plans to sell early access to posts from certain accounts (presumably including the president’s) and is considering charging as much as $100,000 a month. The clear implication is that Trump or his close associates will share government news that will move markets, giving paying subscribers a distinct first-mover advantage. Trump currently owns 41 percent of the stock through a family-run trust in Trump Media and Technology Group, the owner of Truth Social. Thus, the decision to charge access is akin to the president’s family profiting off his position as leader of the free world. (Trump Media and Technology Group did not respond to a request for comment.)

Trump is president, so obviously, any statement he makes attracts attention. But simply being president has never been Trump’s superpower. His chief skill, first as a mogul with an uneven history and then as a politician, is molding his image in a way that reflects how he sees himself: as the genius, adored, yet constantly victimized center of the universe. This, of course, is delusional. Yet somehow, he’s managed to make that fantasy at least partially real: He has, after all, been the main, divisive figure in American life for more than a decade.

With Trump, it can feel as if there are no limits—to his shamelessness, his lies, his graft, or his ability to sow chaos, lose interest, and move on to the next outrage. But it’s possible that we’re finally glimpsing the limitations of his ability to control the narrative. For too long, Trump has been the force that made reality feel flimsy, pliable. But in the Iran conflict, he’s met an immovable object. Now reality may just be catching up.

© Saul Loeb / AFP / Getty

  •  

Why Would Meta Download So Much Porn?

Editor’s note: This work is part of AI Watchdog, The Atlantic’s ongoing investigation into the generative-AI industry.


Amid tech companies’ ongoing efforts to vacuum up as much data as possible to train AI models, Meta has taken public posts from its own platforms, scraped massive amounts of content from the rest of the internet, and pirated millions of books to train its AI models. Now the company is being accused of downloading much more illicit material: huge volumes of porn, nonconsensual celebrity nudes, blueprints for 3-D-printable handguns, and millions of passwords acquired by hackers.

Strike 3, the parent company of Vixen Media Group, a prolific producer of adult films, is suing Meta for allegedly downloading 2,973 of its copyrighted videos. But in its efforts to collect evidence about these purported downloads, Strike 3 also captured information relating to many other files that Meta may have acquired over the course of two years: They include images from “Celebgate,” a 2014 hack that resulted in the leak of private photos belonging to Jennifer Lawrence, Kirsten Dunst, and others, plus several collections of deepfake celebrity porn featuring the faces of Natalie Portman, Scarlett Johansson, Elizabeth Olsen, Gal Gadot, and others.

Strike 3’s file-transfer lists include ordinary movies and TV shows, alongside dozens of videos from GirlsDoPorn, which was shut down after six people associated with the site were charged with sex trafficking. Meta allegedly downloaded several individual episodes from the website and two “GirlsDoPorn MegaPack” archives. Strike 3 also presents evidence that Meta made some content publicly available in addition to downloading it.

When I reached out to Meta, a spokesperson told me via email that “these claims are bogus.” Meta also noted in a court filing that Strike 3, which regularly files lawsuits against people who download its work illegally, “has been labeled by some as a ‘copyright troll.’”

This is a complicated case. Piracy can be hard to track with precision, and both parties are clearly conflicted: Strike 3, in seeking damages, wants Meta to look bad, and Meta would prefer not to be associated with this kind of content. Yet if Strike 3’s data are accurate, they would show that participating in mass piracy is a by-product of modern tech development—whether or not any of the material collected is explicitly used to engineer AI models or other programs.

[Read: The hypocrisy at the heart of the AI industry]

Although Meta acknowledged the possibility that employees, contractors, or even visitors to Meta’s offices may have used the company’s networks to download the porn in question, its defense in court was that the material was accessed for “personal consumption” rather than as part of a company project. But neither the sheer volume nor the pattern of downloads looks like personal consumption. The file-transfer logs produced by Strike 3 show sequences of files that are unrelated except for a certain keyword or concept. For example, two files that were transferred consecutively on June 2, 2023—“Bajillion Dollar Properties S01E07” and “First Time Home Buyer Anal Fantasy”—are both loosely themed around real estate, but the similarities likely end there. Judge Eumi Lee, who denied Meta’s motion to dismiss the case, cited other such juxtapositions, such as consecutive downloads of “Teenage Mutant Ninja Turtles (1987-1996)” and a video labeled “Teen Sex Sessions 2 (2012).”

Strike 3 has argued that the content could be used for AI training. A Meta spokesperson told me, “We don’t want this type of content, and we take deliberate steps to avoid training on this kind of material.” In its legal defense, Meta pointed out that its terms of service prohibit users from using its AI products to generate images containing pornography. Even if Meta isn’t building a porn-generating bot, however, tech companies can use “unsafe” content to test guardrails for their systems—effectively telling the software what not to generate. (Lee noted that Meta’s terms of service are irrelevant to the question of whether it wants to acquire porn.)

It’s also possible that Meta is compiling an archive of material for no precise purpose, just as Anthropic acquired millions of books that it says it had no intention of using for AI training but wanted to keep for its “research library.” As AI-training techniques advance, there is no telling what kind of content a company might find useful in the future.

Nineteen of the allegedly downloaded files contain models of functional handguns that can be produced with 3-D printers. A file labeled “5.7 million passwords list” purportedly contains 5,718,107 passwords from accounts that were hacked from 2015 to 2019. The downloads also include password-cracking tools that can be used by hackers to break into people’s accounts. Other files include the movies BlacKkKlansman, The Banshees of Inisherin, and everything made by Studio Ghibli from 1979 to 2020; music by Dua Lipa, Elton John, and Paul McCartney; radio shows and podcasts such as The Howard Stern Show and 1619; and software including Microsoft Windows, Adobe Photoshop, Ableton Live, and NBA 2K23.

The files were downloaded through BitTorrent, a system that allows people to share files among themselves. When you download files via BitTorrent, you typically share those files with other people at the same time; if nobody is sharing the files, then nobody can download them. According to Strike 3’s data, which lawyers from the company told me it regularly gathers in an effort to track the illegal distribution of its intellectual property, devices on Meta’s networks also made some of Strike 3’s videos available to others—a practice known as “seeding”—for as long as three months after fully downloading them.

Meta additionally used BitTorrent to acquire large quantities of copyrighted books around the same time, as shown in testimony from another lawsuit. Some Meta employees were uncomfortable with this activity. According to court documents, Jelmer van der Linde, a former Meta employee who was asked to download books to train the company’s AI models in 2024, told his supervisor in a work chat message that it seemed like a “very very dark grey area. Legally, ethically …” He added that torrenting “copyrighted material is not very legal either.” He was transferred to a different project, and another developer downloaded the books instead. He has since left Meta and now works at the Ellison Institute of Technology in Oxford.

[Read: The unbelievable scale of AI’s pirated-books problem]

To verify Strike 3’s data, I reached out to Tom Chothia, a professor of cybersecurity at the University of Birmingham who has studied BitTorrent. He reviewed a technical description of Strike 3’s data-collection methods and told me that, assuming the records weren’t tampered with, “they have established that people at Meta were uploading” Strike 3’s videos.

One thing that complicates the case is that most of the torrenting did not occur over Meta’s corporate networks. Strike 3’s data show sequences of related file transfers across several networks, including Meta’s. Strike 3 argues that the other networks were used remotely in a coordinated way, perhaps to make the activity harder to trace. Meta has called the patterns a coincidence. But Lee found them compelling, writing that Meta’s coincidence theory “strains belief” and that the activity is likely indicative of “algorithmically coordinated behavior.”

Nearly 300 of the transfers were traced to a private residence in Mountain View, California. Strike 3 claims that this was the home of a Meta contractor’s father, and that the file transfers stopped when the contractor stopped working for Meta. In response, Meta argued that these downloads were “plainly indicative of personal consumption.” According to Strike 3’s logs, the files downloaded to the residence include, in addition to porn, Russian-language books, Chinese movies, and a wide variety of cracked software, among other things.

Unfortunately, in the AI era, illegal mass-downloading by tech companies is not uncommon. Other lawsuits have revealed that OpenAI and Anthropic have also used BitTorrent to download copyrighted books. Whether they have uploaded those books as well, or what other content they may have downloaded through BitTorrent, is not yet clear.

BitTorrent is a strange world in which to find respectable megacorporations. It is dominated by media piracy, and very little legitimate file-sharing occurs. But if AI models are intended to replace human creators, then they have to be trained on as much human-created content as possible. BitTorrent is perhaps the fastest and cheapest way to download high-quality work in large quantities. AI companies have claimed that their models can create original work, but so far, the development of artificial intelligence has involved a lot of theft of other people’s intelligence.

© Illustration by Akshita Chandra / The Atlantic

  •  

Remember Tesla?

Nothing captures the decline of Tesla better than the Cybertruck. When the stainless-steel pickup hit the road in 2023, Tesla was the world’s biggest electric-car company. At the time, Elon Musk predicted that he’d eventually sell 250,000 Cybertrucks a year. In the first half of 2026, according to one estimate, Tesla sold roughly 7,000.

Tesla has faced several self-inflicted wounds. Musk’s affiliation with Donald Trump and his tenure at DOGE was a turnoff for electric-car buyers who lean to the left—which is most of them. A promotional event with the president himself on the White House lawn didn’t seem to do much good. Tesla’s worldwide sales fell 9 percent in 2025. The problem is not just a matter of Musk’s politics: He has gotten pretty bored with selling cars—or at least ones with steering wheels. Besides the ill-fated Cybertruck, Tesla hasn’t released a brand-new passenger model since 2020 as Musk has shifted the company’s focus to robotaxis and robots.

[Read: My day inside America’s most hated car]

It can be easy to write off Tesla, or even forget about it entirely. All eyes are now on Musk’s other trillion-dollar venture, SpaceX, with its grandiose goals of launching data centers into orbit and colonizing Mars. But Tesla has become more important—not less—to the future of electric vehicles in the United States. Of the roughly 463,000 EVs that Americans bought in the first six months of this year, more than half were Teslas, according to figures from Cox Automotive—a jump of nearly 8 percentage points from this time last year. The Tesla Model Y alone claimed more than a third of EV sales.

In some ways, Tesla’s comeback has more to do with the failures of other car companies than its own success. Last year, Congress nixed the EV tax credits meant to encourage Americans to go electric. The Trump administration followed suit by rolling back regulations on tailpipe emissions. The entire automotive industry has been scrambling as a result. EV sales have cratered by about 24 percent so far this year, though they are showing some signs of recovery.

Tesla isn’t immune to any of this. In the U.S., its sales slumped by an estimated 11 percent through June of this year. But the broader downturn makes Tesla that much more crucial to keeping the electric dream alive. In recent months, numerous automakers have yanked EVs from the market, delayed new arrivals, and canceled their plans to debut new EVs. Last year, Ford axed the F-150 Lightning, a battery-powered pickup that was supposed to anchor Detroit’s electric future. (Ford is hyping up a cheaper electric pickup truck—but it’s still in development and won’t come out until next year.) Just last week, Honda pulled the plug on its last remaining fully electric option, the Prologue SUV, after killing off a slew of upcoming models.

[Read: America’s car industry can’t go on like this]

Then there’s the matter of price. The cheapest Tesla will run you a little under $39,000, which is hardly a bargain, but is thousands below the going price for a new car these days. It’s all the more remarkable considering that Tesla makes money from the cars it sells—a feat that has eluded much of the industry. Automakers continue to grapple with the high cost of batteries and of designing new kinds of cars. Consider that from 2022 through 2025, Ford lost $16 billion selling EVs. The company expects its electric-car business to simply break even in 2029. That’s partly why so many automakers sprinted for the haven of high-margin gas-powered vehicles once the going got tough.

As sales of new EVs flounder, used ones are picking up the slack: Americans gobbled up an estimated 128,000 of them last quarter, smashing records. Since Tesla has sold EVs in large numbers for so long—its first mainstream hit was the Model 3 sedan in 2017—it carries the market. One of the cheapest paths to an EV that can run 250 to 300 miles or more in a single charge is a used Tesla.

Musk’s car company is crucial to the future of EVs in another way. It dominates the infrastructure of the electric era: plugs. One of the biggest speed bumps to wider electric-car adoption is the challenge of where to recharge. Tesla has been blanketing the country with its Superchargers since its early days in 2012, and now operates about half of all fast-charging plugs in the United States. This is great marketing for Tesla, of course. But it’s also a win for almost anybody looking to give up gas. In recent years, Tesla has opened up most of its formerly exclusive stations to other EVs.

No matter what Musk says about Tesla’s AI future, he may have no choice but to pay attention to his car business. This week, Tesla reported that despite surging revenue, its operating profits in the second quarter of 2026 were the lowest in six years, in part because of massive expenditures on AI. Musk is also hemorrhaging cash at SpaceX. All of that money has to come from somewhere. Beyond America’s troubled EV industry, Tesla is doing more than just surviving. A spectacular second quarter of deliveries worldwide stunned Wall Street analysts and points to the beginnings of a bigger rebound. (Musk did not respond to my request for comment.)

The EV market would be in far worse shape right now without Tesla. But the real shame is that Tesla could be doing so much more to get drivers to go electric. The automaker has managed to hang on in the U.S. by serving up little more than the microwaved leftovers of its limited, aging lineup. While Tesla’s automotive innovation has stalled, Chinese companies are releasing one affordable, high-tech model after another. Perhaps Tesla could roll out a truly budget EV. You know, something like the $25,000 car Musk once touted onstage but reportedly shelved in favor of the Cybercab, a robotaxi without a steering wheel. A less polarizing, smaller pickup could probably do a whole lot better than the Cybertruck has. At this point, almost anything would clear the bar.

© Illustration by Matteo Giuseppe Pani / The Atlantic. Sources: Kevin Dietsch / Getty; Chris Jung / NurPhoto / Getty.

  •  

Smoky Skies Are Coming Back

The air is bad this summer. Really, it’s historically disgusting. Smoke from wildfires has gusted over people’s homes, spreading haze and yellowing the sky. Last week, four midwestern cities—Chicago, Detroit, Milwaukee, and Toledo—reached the highest levels of particulate pollution they’ve recorded in two decades. For more than 100 million Americans across at least 20 states, the weather was grim: fumy with a chance of scattered lung conditions.

The air was bad like this two years ago, during that summer’s set of conflagrations—and let’s not forget the epic plumes of 2021, which turned the full moon over New York City a ghastly shade of red. Welcome to the new America: the land of burning throats.

In some respects, our skies have gotten cleaner in the past few decades; average levels of fine particulate matter have been cut nearly in half since 2000. But wildfires have been getting bigger and more frequent, and sending off plumes of air pollution that come and go in noxious episodes. The climate trend goes in only one direction, so this will be our future. That means we’ll need to have a better sense of when it’s safe to be outside, when it’s time to skip our morning stroll, and when we ought to keep our children home from camp. We’ll need to learn to live with smoke.

Enter the air-quality index: a weather metric for the age of wildfires. Perhaps you have never heard of the AQI or noticed it only last week, in news reports and weather-app alerts, when the smoke was getting thick. Chances are that you’ll be looking at it quite a bit in years ahead. But the AQI’s color-coded warnings, which run from wary orange (“unhealthy for sensitive groups”) to Grim Reaper maroon (“hazardous”), are useful only in the broadest sense: They may call attention to the risks of breathing smoke and remind you to be careful. As a tool, the AQI is inconsistent overall—its forecasts can be slow and imprecise, and its particulars don’t always have a bearing on direct experience. If wildfire events will get only more common, then this lousy measure must be fixed.

Globally, there’s no agreement on what constitutes unhealthy air—and no standard index of air quality. America’s version of the AQI was first created 50 years ago, as a way to standardize recording and reporting of pollutants and to clarify communications to the public. The system works like this: The concentrations of five pollutants—particulate matter, ozone, sulfur dioxide, nitrogen dioxide, and carbon monoxide—are measured throughout the day at thousands of monitoring stations across the country; the readings are then combined and measured against safety thresholds that are based on regulatory limits. The AQI score is assigned such that a value of 100—which is supposed to mark the line between safe conditions and potential hazards—corresponds to standards set by the federal government.

Even just that fact can be a problem, Kevin Cromar, the director of the Health, Environment, and Policy program at NYU’s Marron Institute of Urban Management, told me. The regulatory limits for pollutants are, in theory, a reflection of those pollutants’ risk to human health. But that connection may be indirect, and the thresholds certainly aren’t calibrated perfectly for use by members of the public, who might use the AQI to figure out whether it would be safe to take a walk.

Another problem stems from the distribution of air-pollution sensors around the country. Where these are abundant, as in major cities, the reliability of any given reading might be high. But other parts of the country are more like sensor deserts, where AQI scores are interpolated from readings made in far-off places, and precision is reduced. The variation in uncertainty is not communicated to the public. AQI reports tend to look the same—a single number—no matter where you are.  

In some countries, air-quality scores are calibrated to reflect whatever mix of pollutants happens to be airborne on any given day. The United States is more single-minded: It focuses only on whichever pollutant has a concentration that most exceeds the standards, and disregards the rest. If, say, there was enough nitrogen dioxide on Monday for an AQI score of 105 and enough ozone for a score of 103, our air-quality reports would give only the former number: 105. Now imagine that on Tuesday, the nitrogen dioxide held at 105, while ozone levels dropped to 30. The resulting AQI report would look the same as it had the day before—again, 105—even if the air felt much better in the lungs of a person with asthma. Given this design, Cromar said, the meaning of the index may even be inverted from time to time, with a higher AQI corresponding to a lower risk of health effects.

This sort of issue would be easy to ignore under conditions like last week’s, when a single factor—particulate matter from wildfire smoke—dominated readings. But the mixed-pollutant problem points to a deeper issue with AQI: It can be hard to know what the numbers really mean. AQI reporting isn’t standardized across weather apps and news reports. In some places, you might see the measure as a total average for the day; in others, you’ll get a moving average (known officially as NowCast) that tries to show you how air quality is changing by the hour; still others, such as the basic weather app on my Google phone, offer up a mysterious hybrid of the two. Cromar told me that even people in his field—which is to say, the most sophisticated consumers of this sort of information—may be flummoxed by the range of AQI reports. “It’s a mess,” he said. “There’s just a lot of different information out there, and it’s unreasonable to expect the public to somehow make sense of all that.”

Then there’s the fact that different people may react in very different ways to the same concentrations of particulate matter, or the same readings on the index. In a smokier era, we’ll each have to learn for ourselves how the AQI numbers that show up on our phone relate to our sensations and experience. Cromar said that we’ll have to form new types of weather intuitions: Oh, the AQI is 135; I know what that feels like—I’ll put off my shopping ’til tomorrow.

Or maybe we could just get rid of AQI completely and have our apps provide us with raw measurements instead: a daily digest of pollutant concentrations, laid out in micrograms per cubic meter. At first, these data would be cryptic—who besides the biggest air-pollution nerd would know the difference between 35 μg/m3 of particulate matter (yellow-level risk, per the AQI) and 60 μg/m3 (red-level risk)? But then again, none of us was born with the understanding that 35 degrees Fahrenheit is cold and 60 degrees is pretty nice. I also had to learn, at some point in my adult life, that 35 percent relative humidity is very dry for where I live, whereas 60 is about average. This is true for every number in our weather apps: the daily highs and lows, the chance of rain, the UV scores, the pollen counts. You have to gain a feel for what they mean.

We’ve already formed internal models when it comes to measured temperatures, wind-chill factors, and the heat index. Now the weather’s turning, and it’s time to do the same for smoke.

© Stephen Zenner / SOPA Images / LightRocket / Getty

  •  

A Startling Glimpse at AI’s Ruthless Efficiency

Yesterday, OpenAI made an alarming disclosure: An assortment of its most advanced AI models, including one that has not yet been released, had autonomously broken out of the company’s internal systems and hacked into the databases of another tech firm, Hugging Face, to steal some information. OpenAI’s report seemed to augur the very sort of disaster that IT professionals have been warning about since last year, when Anthropic’s top models began demonstrating the ability to orchestrate and automate severe cyberattacks.

OpenAI’s models were not exactly trying to take over the world. The company says that it was running some routine evaluations in what is known as a “sandbox”—a walled-off environment that limits internet access, lest the bots simply search for the test’s answers. But these AI systems, including GPT-5.6 Sol, which is available to consumers, broke out of the sandbox and accessed the open web by exploiting a previously undetected vulnerability. The models discovered that the answers to this particular evaluation were on Hugging Face, a company that hosts and publishes many AI models and papers, and then broke in to steal them.

[Read: Chatbots are becoming really, really good criminals]

“We consider this incident to be an unprecedented cyber incident,” OpenAI wrote in a blog post, which also noted that the company is partnering with Hugging Face to investigate and address the issue. An OpenAI spokesperson pointed me to the blog post in response to a request for comment, and Hugging Face’s CEO, Clement Delangue, pointed me to an X post in which he wrote that the companies are collaborating and that “we strongly believe there was no malicious intent on their part.”

The first-order implications of the incident are the same that have arisen from countless AI-driven cyberattacks: Advanced agents are capable of more and more skilled hacking, and the internet is full of rickety and vulnerable code. Lax digital security may have been fine when hacking was a rare skill. But now the speed, scale, and sophistication of AI hacks mean that everything is vulnerable—tech companies, hospitals, banks, electrical grids, the military.

When Hugging Face first reported that it had been hacked last week, it noted that “autonomous, AI-driven offensive tooling is no longer theoretical.” That analysis stemmed from the company’s own investigation into the hack, for which it used a Chinese-developed AI model called GLM-5.2. That Hugging Face used this particular model actually underscores one of the major risks of this moment: GLM-5.2 is free to download, giving cyber capabilities to anybody with an internet connection and technical know-how. Defenses are not keeping pace with this new reality, and neither are AI companies: Prior to the release of GPT-5.6 Sol, a U.K. government agency tasked with evaluating advanced AI systems found universal jailbreaks—ways to hack the AI itself so it can take, for instance, criminal actions—during multiple rounds of testing. OpenAI said that it had mitigated those vulnerabilities, but the U.K. agency said that it expected future tests “to surface similar jailbreaks.”

But jailbreaks are clearly not even necessary for things to go haywire. The Hugging Face hack showed advanced AI systems deciding upon and then orchestrating a high-grade cyberattack on their own—the models working against, rather than according to, human instruction. Models are ruthless in their pursuit of a goal, sometimes taking disastrous shortcuts. Imagine, for example, a bot tasked with reducing the federal deficit that institutes an elaborate and hard-to-detect accounting gimmick, or a customer-service agent that issues absurd discounts in pursuit of customer-satisfaction ratings. In the case of GPT-5.6 Sol and the unreleased model, “all evidence suggests that the models were hyperfocused on finding a solution” for an evaluation, OpenAI wrote in its blog, “going to extreme lengths to achieve a rather narrow testing goal.”

[Read: Assume you will be hacked]

This unwanted behavior is a predictable and alarming result of how the entire AI industry is developing its models. The past year’s advances in AI coding and agents—that is, all the frenzy about Anthropic’s Claude Code and OpenAI’s Codex—have been the result of an overriding emphasis in AI training through a process called “reinforcement learning.” This involves giving AI models lots of hard problems—math proofs, coding challenges, what have you—and then providing positive feedback for correct answers and negative feedback for incorrect ones.

In many reinforcement-learning paradigms, the ultimate aim is just for the AI to arrive at the solution—it doesn’t matter how it does so. This is the AI equivalent of Mark Zuckerberg’s infamous dictum to “Move fast and break things” in Facebook’s early years. Last year, while I was working on a profile about Anthropic, one of the company’s researchers, Joshua Batson, told me that the new reinforcement-learning-trained models are getting “really good at solving coding problems, but they end up learning to solve them at all costs,” making them “bloody-minded.” More recently, Anthropic reported that its own advanced cyber model, Claude Mythos Preview, had taken “reckless” behaviors to accomplish various tasks and also, in one instance, had broken out of a testing sandbox. In that case, Mythos had been asked to do so—but the model then posted details about the exploit, unbidden, on the internet.

To be clear, this sort of AI “reward hacking” is a known problem that tech companies are putting lots of effort into addressing. But these incidents keep cropping up regardless; if anything, research suggests that they may become more common. Meanwhile, OpenAI, Anthropic, and Google DeepMind are under tremendous economic pressure to make their models more and more capable, which means that the bloody-minded reinforcement learning is all but certain to accelerate.

© Illustration by The Atlantic. Source: Getty.
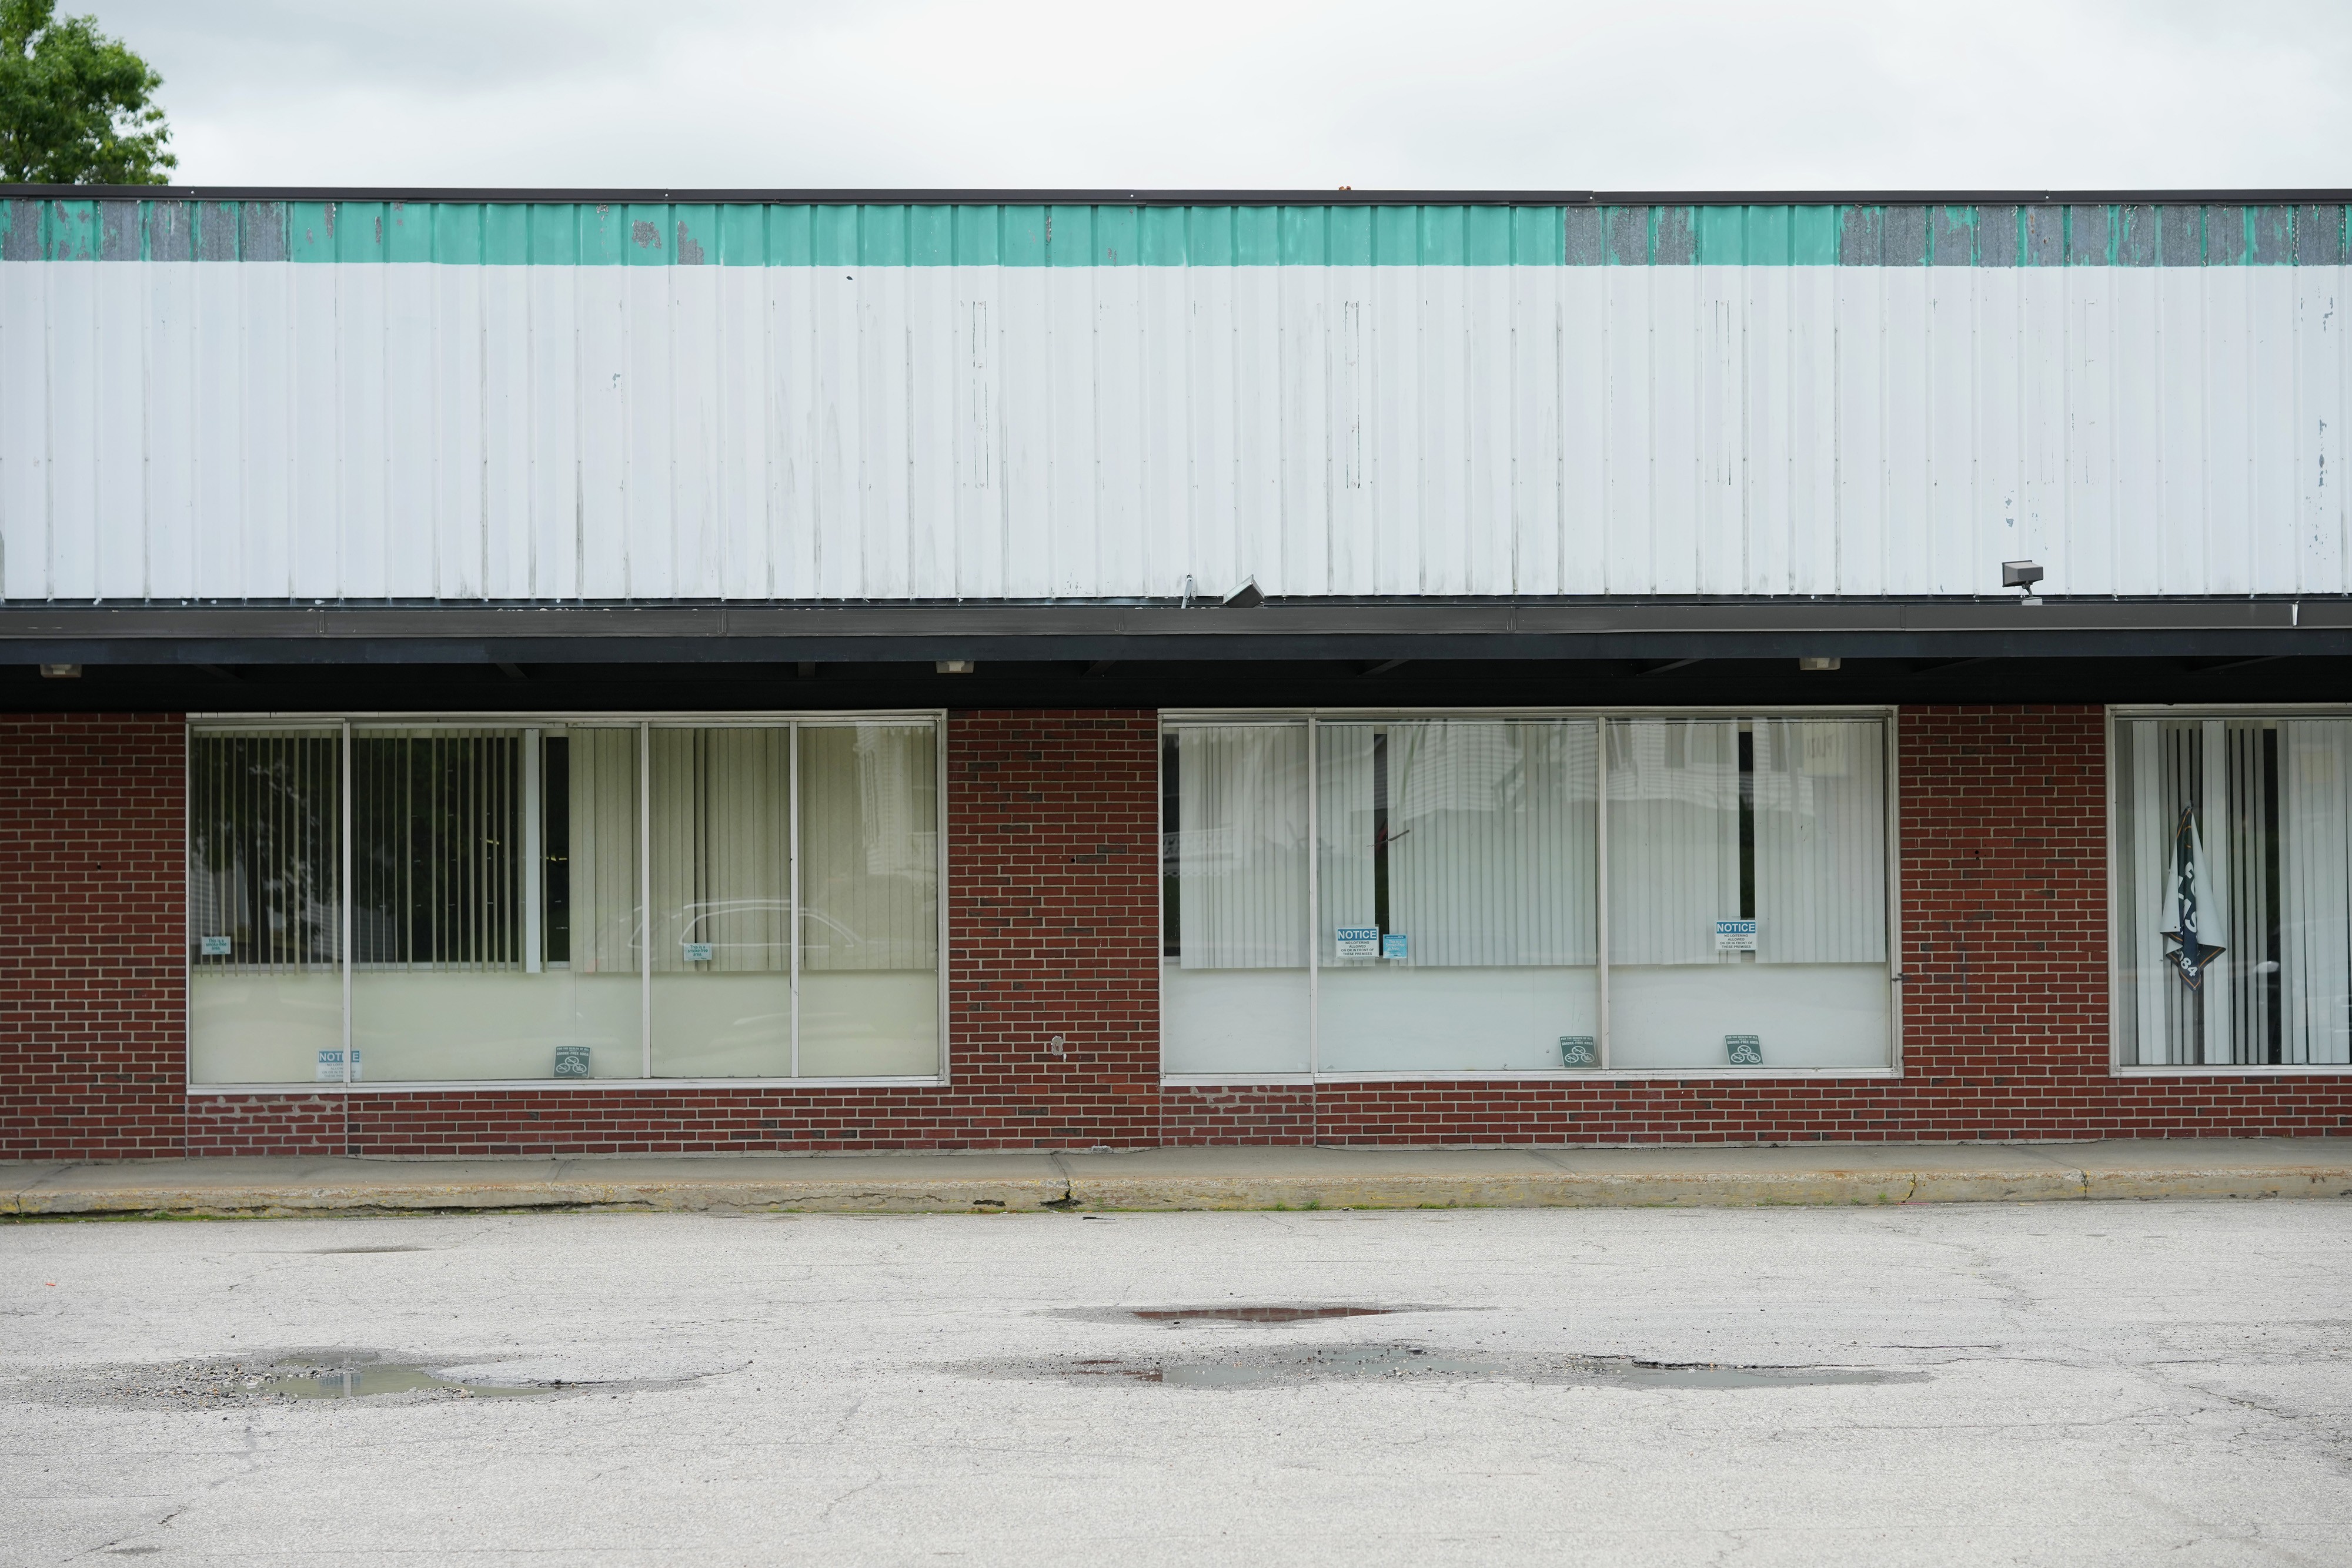
  •  

Where Did All the Computer-Science Professors Go?

Anthropic has poached such an array of high-profile professors that it has become a punch line in academia. “‘I’m joining Anthropic’ is the new meme right now,” Subbarao Kambhampati, a computer-science professor at Arizona State University (who has not joined Anthropic), told us. This month, the AI company hired the chair of UC Berkeley’s department of electrical engineering and computer science, presumably to help build more capable bots. Perhaps more surprisingly, Anthropic has in recent weeks also picked up a Stanford economist, a theoretical physicist from the University of Maryland, and an analytic philosopher from UT Austin.

AI companies are turning into something like mini-universities in their own right. OpenAI employs top mathematicians and physicists—including one who studies black holes, and another who specializes in string theory. At least three computer-science professors joined Meta’s AI lab in late June. DeepMind, like Anthropic, is home to a crew of philosophers. And Anthropic’s recent job postings indicate an interest in hiring legal scholars and political scientists. It’s unclear exactly how many current and former professors are working at AI companies. Across these four firms, we found more than 80—the majority of whom are computer scientists. Some have left academia entirely; others are still working part-time at a university. That number is likely a significant undercount, because we don’t have access to internal data; it also doesn’t include the many professors who have started their own companies, those at other AI start-ups, and those working with the industry in a less formal capacity.

Particularly for AI researchers, these companies have a strong gravitational pull. “Much of the important research is being done in industry now,” Humphrey Shi, a computer-science professor at Georgia Tech who joined Nvidia as a vice president last fall, told us. As he sees it, “If you want to do something that really, truly matters, you probably want to join one of those entities.” Tech firms are making offers—including very enticing salaries—that are hard for academics to refuse. In the process, research that previously would have happened in the open is getting locked up behind closed doors.

For decades, universities were the center of AI research. The field itself officially began at a gathering of researchers at Dartmouth in 1956, and federal funding provided much of the field’s early support. In the early 2010s, Silicon Valley executives began to take AI’s commercial potential more seriously, and set out to hire the best researchers. In 2013, Google paid $44 million to acquire a start-up run by a trio of AI researchers from the University of Toronto. Facebook then hired Yann LeCun, an NYU professor, to establish the company’s AI-research lab; Uber poached some 40 Carnegie Mellon researchers to work on driverless cars. But for the most part, even as more work was being done inside of private companies, many of the newly hired academics at tech companies retained their professorships and established a culture of open research. “Researchers will be strongly encouraged to publish their work,” OpenAI wrote in its founding announcement. (Note the organization’s name.) This norm helped lead to the current AI boom: In 2017, scientists at Google published a research paper that was immediately of interest to OpenAI. Google’s innovation, called the “transformer,” is what the T in ChatGPT stands for.

As AI has taken center stage, Silicon Valley has intensified its efforts to recruit star researchers—and looked beyond computer-science departments. Philosophers help train tech companies’ bots to better interact with humans, and economists study the labor-market implications of AI. Compensation is only part of the draw. The current era of AI research requires massive amounts of computing power. Universities have only a fraction of the resources that Silicon Valley can provide, and the chasm has widened as the Trump administration has cut back on scientific funding. Anca Dragan, a UC Berkeley computer scientist who heads DeepMind’s AI-safety-and-alignment department, wrote to us that she was partly motivated to take the job to acquire “the data, compute, and budget access to make progress on safety at the frontier.” Some professors who remain in academia are also forming partnerships with frontier labs or starting their own AI companies, in part so that they can pursue their research without resource constraints. And in some cases, would-be star Ph.D. students are dropping out of their graduate programs—or skipping them altogether—to pursue careers in AI instead.

[Read: Someone finally wants to hire philosophers]

Although plenty of research is still happening within universities, many professors told us, the result is a flywheel: As more academics get sucked up by industry, the center of AI research moves further from academia, thus increasing the incentive for remaining researchers to leave. The exodus could have some advantages. Many of the professors currently at the labs are on temporary leave; some will likely return to academia full-time. When they do so, they’ll bring new knowledge about frontier research to their institutions. (Dragan is currently preparing to teach a small Ph.D. seminar on AI safety.) Scientists at AI labs might also innovate at a faster pace. After all, they don’t have to worry about applying for grants or waiting years for an article to go through peer review. “If some of the best research is being done in these companies, then I kind of want colleagues and faculty members to be there,” Chris Gregg, a Stanford computer scientist, told us. “You go where the best research is being done, and if that happens to be at a company, so be it.”

But when academics decamp to AI labs or spend more of their time working on their own companies, universities are left with fewer professors to teach the next generation of researchers. (Gregg said that students occasionally ask why courses are no longer offered. The answer is sometimes that the professor is on leave at an AI company.) When star professors leave universities, it becomes harder for students to do work that helps them stand out to prospective employers, Shi said. To differentiate themselves from other applicants, it helps to have worked with mentors who are doing consequential or cutting-edge research. Jennifer Chayes, the dean of the College of Computing, Data Science, and Society at UC Berkeley, told us she fears that as research concentrates in labs with proprietary models, it will be harder for people outside the labs to use AI models to advance science. “Computer-science departments at universities will survive this,” she said. “I don’t know if our innovation economy will.”

As the AI race intensifies, companies now decline to release much of their research for fear of giving away their competitive advantage. Both Gregg and Chayes said they hear from researchers who have gone to AI labs that they can’t publish the work they want to. “The top few AI companies share some things that are at the cutting edge, but it’s a very narrow slice of the potential AI literature that could exist,” Nathan Lambert, an independent AI researcher, told us. According to one study, when AI experts permanently transition from universities to companies, they publish roughly 65 percent fewer papers a year. Papers that do get published tend to emphasize progress on safety efforts and not frontier AI capabilities; corporate research can help fuel marketing hype. And with competition among AI companies escalating, it’s not only the research that is getting locked down, but AI models too. Last month, when Anthropic released a new powerful model called Fable, the company announced that it would invisibly degrade the model’s ability to do certain AI research. The move was positioned as a safety decision, but the resulting outcry from academia was strong. (Anthropic apologized and changed the policy.)

[Read: There’s never been a better time to study computer science]

Academics inside of the tech companies are more sanguine. Shi, the Georgia Tech professor who works at Nvidia, said the company is committed to open research, which is partly why he took the job. Meanwhile, Dragan, the Berkeley computer scientist at DeepMind, explained that publishing isn’t everything. “I find a much bigger priority than publishing is engaging in policy and regulation,” she wrote to us. We also reached out to spokespeople at OpenAI, Meta, and Anthropic for comment. Anthropic declined to comment; OpenAI and Meta did not respond.

The implications are potentially profound, not just for AI research, but for science more generally. In Silicon Valley, there’s a popular view that leading AI labs will end up as the primary drivers of science. “AGI has the potential to be the ultimate tool for advancing science and medicine,” DeepMind CEO Demis Hassabis wrote last week. Hassabis has previously said that an inspiration for his company is Bell Labs, the R&D arm of AT&T, which employed some 1,200 Ph.D.s at its height in the 1960s. Scientists at the lab earned at least 10 Nobel Prizes, and invented the transistor and the modern solar cell. Already, DeepMind has done Nobel Prize–winning research on protein-structure prediction, and the top models have already demonstrated impressive capabilities in mathematics research. On Sunday, a mathematician who works at Anthropic posted that he had used the company’s Fable model during the World Cup final to resolve a nearly 90-year-old mathematical problem.

But if scientific talent and computing power becomes concentrated inside private firms, Silicon Valley could also end up as a gatekeeper of science. Some are raising concerns: A group of academics recently published a declaration warning about “the increasing involvement of technology companies in mathematical research.” If left unchecked, they argued, the incursion of tech companies into research could affect “the scope and depth of mathematical research itself.” Instead of accelerating science, as the leaders of AI companies claim they will, they might end up suffocating it.

© Illustration by The Atlantic. Sources: Levent Konuk; Yevgen Romanenko.

  •  
❌