❌

Normal view

In Minnesota, Words Matter More Than Rape

21 August 2026 at 15:00

Shiloh Hendrix got a $1,000 fine and 200 hours of community service for using a racial slur. The Somali man who filmed her had rape charges dropped "in the interest of justice". Only in Minnesota, says Steven Tucker.

The post In Minnesota, Words Matter More Than Rape appeared first on The Daily Sceptic.

Apple é alvo de processo por brecha na Retransmissão Privada do iCloud+

11 August 2026 at 17:15

Na semana passada, pesquisadores revelaram falhas de segurança nas configurações de proxy da Retransmissão Privada (Private Relay) do iCloud+, que também afetam navegadores baseados no WebKit que utilizam a API 1Application programming interface, ou interface de programação de aplicações. de proxy para privacidade, expondo o endereço IP dos assinantes do serviço. Pois bem, não demorou muito para que surgisse o primeiro processo relacionado ao caso.

A ação coletiva foi movida pelo escritório jurídico Clarkson, que você talvez lembre pelo envolvimento no processo sobre o adiamento dos recursos de inteligência artificial (IA) apresentados durante a WWDC24, o que resultou em um acordo o qual previu o pagamento de US$250 milhões a clientes em dezembro do ano passado.

Como sambemos, a Retransmissão Privada oferece proteção para ocultar o seu endereço IP e dificultar a ciência sobre os seus acessos na web por parte de provedores de internet e terceiros, direcionando o seu tráfego para duas camadas de proteção.

O novo caso menciona o problema na Retransmissão Privada que faz a sua barreira ser burlada nos iOS em qualquer site compatível com as Chaves-senha (Passkeys) — algo que acontece pois o dispositivo do usuário faz uma requisição web fora do próprio navegador sempre que o usuário faz login, ignorando o Private Relay — e acusa a Apple de publicidade enganosa, declarações falsas ou deturpadas e fraude.

[A Apple] sabia, ou deveria saber, que as declarações contestadas eram falsas, enganosas, fraudulentas e ilegais, no momento em que a ré fabricou, comercializou, anunciou, rotulou e vendeu as assinaturas [do iCloud+].

Convidada a comentar o caso pelo 9to5Mac, a Apple ainda não se pronunciou sobre o tema. Tim Giordano, um dos sócios do escritório, por outro lado, disse que a empresa traiu a confiança de usuários “expondo-os ao mesmo rastreamento, criação de perfis e segmentação sobre os quais a Apple os alertava”.

O texto completo da ação coletiva pode ser conferido nesse link [PDF].

Notas de rodapé

  • 1
    Application programming interface, ou interface de programação de aplicações.

Google Pixel 11 Pro XL Geekbench Scores Leak: Tensor G6 Shows Limited Performance Gains

11 August 2026 at 09:52

Google’s upcoming Pixel 11 Pro XL has reportedly appeared on Geekbench 7, revealing early performance details of the company’s next-generation Tensor G6 chipset. While the new processor is expected to bring improvements in efficiency and AI capabilities, the leaked benchmark results suggest that raw performance gains may be relatively modest compared with the previous-generation Tensor G5.

According to Igeekphone, the Pixel 11 Pro XL and other Pixel 11 series models are expected to be unveiled at Google’s annual Made by Google event on August 12. Ahead of the official announcement, benchmark information has provided the first look at the performance of Google’s upcoming flagship processor.

Tensor G6 Benchmark Results Revealed

The Geekbench 7 listing reportedly shows that the Google Pixel 11 Pro XL achieved:

  • Single-core score: 2,112 points
  • Multi-core score: 5,196 points

These results represent the first known real-world benchmark scores for the Tensor G6 chipset, which has previously appeared only through leaks and industry reports.

The benchmark listing also confirms that the tested device is equipped with:

  • 16GB RAM
  • Android 17 operating system

While benchmark results do not reveal every aspect of real-world performance, they provide an early indication of the processing capabilities of Google’s next flagship smartphone platform.

Tensor G6 Reportedly Uses Seven-Core Architecture

According to the Geekbench database information, the Tensor G6 appears to use a seven-core CPU architecture consisting of three core clusters.

The reported configuration includes:

  • Two cores clocked at 2.65GHz
  • Four cores clocked at 3.38GHz
  • One high-performance core clocked at 4.11GHz

The listing does not confirm whether the Tensor G6 is manufactured using a 2nm process technology, despite previous reports suggesting that Google could become one of the first smartphone manufacturers to adopt a 2nm Tensor chip.

Limited Improvement Compared with Tensor G5

Although the Tensor G6 represents a new generation of Google’s custom smartphone chipset, the leaked benchmark results suggest that the performance improvement may not be dramatic.

For comparison, the previous-generation Pixel 10 Pro’s Tensor G5 reportedly achieved:

  • Single-core score: 1,977 points
  • Multi-core score: 5,805 points

Compared with those numbers, the Tensor G6 appears to offer a small increase in single-core performance but a lower multi-core score in this early Geekbench test.

If the leaked results are accurate, the Pixel 11 Pro XL may not deliver a major upgrade in traditional computing performance. Instead, Google may continue focusing on areas where Tensor chips have historically stood out, such as artificial intelligence processing, photography enhancements, and software optimization.

Pixel 11 Standard Model Also Appeared in Benchmarks

The Pixel 11 series has previously appeared in Geekbench databases as well.

Earlier testing of the standard Pixel 11 model reportedly showed:

  • Single-core score: 875 points
  • Multi-core score: 2,657 points

That listing also indicated a seven-core Tensor G6 architecture, although the performance results were significantly lower than the Pixel 11 Pro XL benchmark.

Differences between models could be related to software optimization, testing conditions, clock speeds, or hardware configurations.

Google May Focus More on AI Features

Google’s Tensor processors have traditionally prioritized artificial intelligence and machine learning capabilities rather than competing directly with flagship chips from Qualcomm and Apple in raw benchmark performance.

The Tensor G6 is expected to bring improvements in areas such as:

  • AI-powered features
  • Computational photography
  • Voice processing
  • On-device machine learning
  • System efficiency

For Pixel users, these software-driven improvements may be more noticeable in daily use than benchmark score increases.

Pixel 11 Series Expected to Launch Alongside Pixel Watch 5

Google is expected to officially introduce the Pixel 11 series along with the Pixel Watch 5 during the upcoming Made by Google event on August 12.

The Pixel 11 lineup is expected to include multiple models, including:

  • Google Pixel 11
  • Google Pixel 11 Pro
  • Google Pixel 11 Pro XL

The Pixel 11 Pro XL is expected to serve as the top-tier model, featuring the largest display, highest memory configuration, and the most advanced camera system in the lineup.

Final Thoughts

The leaked Geekbench results for the Google Pixel 11 Pro XL suggest that the upcoming Tensor G6 chipset may deliver only moderate improvements in traditional processing power. While the move to a newer architecture and potential 2nm manufacturing process could improve efficiency, the benchmark numbers indicate that Google is not necessarily chasing the highest raw performance scores in the smartphone market.

Instead, the Pixel 11 series is likely to continue Google’s strategy of combining custom hardware with advanced AI software experiences. For potential buyers, the most important upgrades may come from new AI features, camera improvements, and software innovations rather than a major leap in benchmark performance.

The post Google Pixel 11 Pro XL Geekbench Scores Leak: Tensor G6 Shows Limited Performance Gains appeared first on IGeeKphone China Phone, Tablet PC, VR, RC Drone News, Reviews.

Meta’s local AI model prompts enterprises to rethink hardware-software cost trade-off

11 August 2026 at 02:38

Meta rolled out a new 30-billion-parameter AI model optimized to run on a PC or Mac with a single GPU on Monday, offering a way to run always-on agentic workflows locally rather than relying on the cloud.

The company has dubbed it Muse Glimmer. However, its hardware demands, including a GPU with a minimum of 24GB of VRAM, could make it difficult to justify for deployment at scale.

Although analysts and consultants agree that there is a tremendous enterprise appetite for running models locally, determining whether switching more systems from cloud to local makes fiscal sense is much more complex. 

The hardware costs are tricky to calculate even today, with the VRAM needed depending on the particular applications to be run. But the far bigger consideration is that there is no way to determine what RAM costs will look like over the next 12-18 months, and there is an identical lack of visibility into how cloud prices might increase during the same timeframe. 

That makes determining the better financial choice impossible.

Agents become capex, not opex

Noah Kenney, principal consultant at Digital 520, noted that since RAM costs have increased “exponentially” over the last 12 months, cloud AI providers are also going to have to increase their prices. Beyond that, IT needs to anticipate logistical issues; key questions to ask are, “How quickly can you scale? Can you even get the hardware?”

“Meta just made agents a capital expense instead of an operating one,” Kenney said. “For two years, enterprises have been trained to rent intelligence by the token from someone else’s data center. Muse Glimmer runs the agent on a GPU you own, on the desk, with the meter switched off. That is a direct shot at the business model that cloud AI vendors are built on, and it comes from the one player with no cloud API revenue to protect.”

In its post announcing the new model, Meta pointed out that it has aggressively slimmed it down to try to make it efficient and cost-effective. 

“At full precision, a 30-billion parameter model would require over 55 GB of memory — far more than any consumer GPU offers,” Meta said. “We use quantization techniques to compress the model’s weights to approximately 4-bit precision, shrinking the language model to under 20 GB. This leaves enough headroom for the model’s working memory, its KV cache, the perception encoder for image understanding, and the speculative decoding drafter to run simultaneously within a 24 GB or 32 GB envelope. We validated that this compression introduces minimal to no degradation on agentic tasks.”

More options for enterprises

Mike Wilkes, enterprise CISO at Aikido Security, said that Meta’s move is significant in that it starts to give enterprises more options. 

“The most important thing about Muse Glimmer is not that Meta has produced another capable model, it is that the economics and architecture of AI are beginning to move back toward the edge,” he said. “The financial comparison therefore becomes capital expenditure that can be amortized over several years versus an effectively perpetual per-token or per-request cloud operating expense.”

That means, he said, that an enterprise may rationally pay somewhat more for hardware if doing so gives it predictable AI costs, offline availability, control over model versions, freedom from sudden API pricing or access changes.

Independent cybersecurity and risk advisor Steven Eric Fisher also noted that the specs published by Meta don’t tell the full story.

The problem is that running locally versus in the cloud can generate a lengthy list of related expenses. 

“Agentic workloads [in the cloud] can amplify consumption through reasoning, retries, tool calls, context growth, and evaluation, while local deployment [also] introduces hardware, power, lifecycle, support, and utilization costs,” he said, adding that even the RAM requirements need a lot of context.

“Meta’s stated 24GB and 32GB memory targets demonstrate that Glimmer can be loaded and executed on comparatively accessible hardware, but that is not the same as having sufficient capacity for meaningful agentic workloads,” Fisher said, pointing out that once other factors are considered, practical memory requirements can move beyond the 32 GB available on an Nvidia RTX 5090 GPU.

“In enterprise terms, this still places Glimmer primarily in high-end developer, data science, or dedicated AI workstations rather than the standard corporate desktop or laptop,” he said.

Better ROI not guaranteed

Justin Greis, CEO of consulting firm Acceligence, agreed. 

“I wouldn’t assume that moving inference from the cloud to the endpoint automatically produces a lower total cost of ownership,” he said, noting that variable cloud costs would be traded for the price of  deployment, endpoint management, support, security, model updates, and potentially accelerated hardware refresh cycles for the local devices.

“Muse Glimmer is an important milestone because it makes local agentic AI technically viable. But technical viability and enterprise ROI are two different milestones,” Greis said. “I think Meta has crossed the first one. I do not think they have fully crossed the second one yet.”

However, Kenney argued that there are also other elements of the Meta rollout that make meaningful comparisons difficult. 

“It is worth remembering that the local model is quantized, compressed to roughly 4-bit precision, while the cloud APIs you are comparing against typically serve full-precision models, so this is not a pure apples-to-apples cost comparison,” he said. “The ROI question is not local versus cloud on price alone. It is also a question of whether a company is willing to use a quantized model for the specific task. A cheaper agent that needs more retries or human correction can erase its savings fast.”

In addition, a local model often neglects to include every service that a cloud provider typically delivers. 

“The cloud vendor was quietly handling updates, scaling, reliability, and security patching across your whole footprint. Bring the model in-house and every one of those becomes your problem, multiplied by every machine running it,” Kenney noted. “Most enterprises that consume AI as a service have no muscle for operating a fleet of local models, and that cost rarely gets adequate consideration in ROI conversations. The GPU is cheap. Patching a thousand of them is not.”

Sanchit Vir Gogia, chief analyst at Greyhound Research, also stressed that it can be difficult for IT to comprehensively anticipate the different cost variables. 

“Finance leaders are right to feel skeptical. An engine bought for one employee burns capital whether or not it runs. Meta has shown that a thirty-billion-parameter agent can run on a single machine, and that is a real engineering result. What it has not shown is that such an agent works reliably at enterprise scale, or that a fleet of them can be operated safely. Model fit and production fit are different claims. A laptop must still run the employee’s actual job,” Gogia said. “The economics turn on the incremental hardware premium, refresh timing and actual utilization, measured against the price of the remote inference being displaced.”

On the other hand, Arun Chandrasekaran, a distinguished VP analyst with Gartner, said that he found it “very interesting that they have decided to release a smaller model that operates on the edge” and especially liked Meta’s use of the popular Apache license. But he would have preferred that they had released more than just a model.

“Enterprise customers are asking for a car and Meta is delivering an engine,” Chandrasekaran said. “They should have built something more like a platform solution.”

Why I Founded Free Speech Press

9 August 2026 at 13:13

Self-censorship is rising and traditional publishers steer clear of controversial topics. Mike Fairclough explains why he has launched a new publishing venture – and why it matters now.

The post Why I Founded Free Speech Press appeared first on The Daily Sceptic.

Driver Denied Car Insurance Over “Jesus Loves You” Stickers

8 August 2026 at 17:00

A driver has been denied car insurance because he put 'Jesus loves you' stickers on his car, and is now planning legal action against his insurer, GoSkippy.

The post Driver Denied Car Insurance Over “Jesus Loves You” Stickers appeared first on The Daily Sceptic.

SpaceX Now Faces a Terrible Peril

6 August 2026 at 15:34

Investors were not impressed by SpaceX’s first-ever earnings report earlier this week. Shares dropped by more than ten percent, even after the company reported higher than expected revenue — comforting financial news which, unfortunately for CEO Elon Musk, was overshadowed by the venture’s massive AI spending.

The same day, SpaceX insiders, including employees and executives, got their first real opportunity to turn their holdings into cash after the total shares available for trading grew from around 639 million to 1.55 billion, a chunk of the stock valued at just over $100 billion being unlocked.

As Reuters put it, investors now faces an “irresistible opportunity to cash out.”

“This has to be the most talked-about lockup in the history of IPO lockups,” institutional ​brokerage firm R.F. Lafferty & Co CEO Robert Hackel told the agency. “You are going to see a lot of exits.”

It’s no wonder Musk’s rocket company is facing massive pressure this week. Shares are down more than 28 percent over the past month, currently hovering around $114, which is miles below its mid-June record high of $225.

SpaceX’s massive volatility briefly made Musk the world’s first trillionaire — only for him to lose that title once his rocket company’s stock came crashing back to Earth.

Its current share price is also low enough to keep an additional 455 million shares locked up, since it’s still south of its $135 IPO price, setting the stage for even more volatility if it were to claw itself back to that point.

Musk remaind steadfast in his ambitious vision for the company, from orbital data centers to a fleet of humanoid robots that would enable large scale manufacturing on the surface of the Moon.

During Tuesday’s earnings call, he admitted that his plans sound “totally nuts” and “super sci-fi right now,” but maintained that “it’s going to happen.”

Whether investors continue to buy into his vision, though, is anything but guaranteed. SpaceX’s success so far this year has largely been built on hype surrounding AI. The company was merged with Musk’s AI startup, xAI, bringing in plenty of new investors — but saddling it with billions of dollars in additional debt.

Its space ambitions hinge almost entirely on the success of Starship, a super-heavy launch platform that has yet to complete a single successful flight and landing.

SpaceX’s revenues, meanwhile, are heavily dependent on its Starlink satellite internet service. There’s certainly good news there, but the program also saw its average revenue per user drop over the last quarter, rattling investors.

In short, SpaceX’s path to profitability is inextricably linked to the belief that Musk’s sci-fi dreams can be turned into reality in a short enough time period that the dream won’t collapse in on itself.

“SpaceX wants to tell the story they’re the market leader,” The Westly Group founder Steve Westly told CNBC. “But people still have these questions: how quickly can they grow? How big are the costs going to be before this thing gets to profitability?”

More on SpaceX: SpaceX Achieves Its First Moon Landing by Accidentally Crashing Into It at 5,400 Miles Per Hour, Causing Huge Explosion and 60-Foot Crater

The post SpaceX Now Faces a Terrible Peril appeared first on Futurism.

SpaceX is set to acquire 130,000 acres of marshland in southern Louisiana

3 August 2026 at 15:41

SpaceX and the state of Louisiana are close to finalizing a deal for the launch company to acquire about 130,000 acres along the northern coast of the Gulf of Mexico.

There have been persistent rumors about such an agreement for months, but now The Times-Picayune | The New Orleans Advocate reports that Louisiana Gov. Jeff Landry is expected to announce the agreement later this month.

The deal would give SpaceX control of an 18-mile stretch of marshland southwest of Lafayette. The site, known as Pecan Island, became available as part of a legal settlement that resolves dozens of lawsuits that blame ExxonMobil for pollution and coastal land loss, the newspaper reports.

Read full article

Comments

© SpaceX

Falhas no WebKit podem revelar IP e DNS de usuários de navegadores proxy e da Retransmissão Privada do iCloud+

5 August 2026 at 14:32

Três brechas na configuração de proxy do WebKit, que também afetam a Retransmissão Privada (Private Relay) do iCloud+, foram descobertas, permitindo que o endereço IP de usuários da Apple seja exposto a terceiros. O comportamento afeta todos os navegadores para iOS que dependem de conexões proxy para ocultar o IP do iPhone.

A falha foi localizada pelos desenvolvedores Talal Haj Bakry e Tommy Mysk, fundadores do navegador com foco em privacidade Psylo. Eles explicaram como a exposição da informação do usuário ocorre em uma postagem no blog oficial de Mysk:

Navegadores baseados em WebKit no iOS e no macOS podem ser configurados para encaminhar todo o tráfego web por servidores proxy. […] Em teoria, toda conexão de rede iniciada por uma página deveria passar pelo proxy configurado, de modo que os sites enxergassem apenas o endereço IP do proxy. No entanto, descobrimos que três recursos do WebKit ignoram essa configuração e enviam tráfego diretamente do dispositivo.

As três ferramentas mencionadas ao longo do boletim incluem a pré-busca (prefetching) de DNS, que resolve o endereço pelo caminho normal de DNS do dispositivo em vez de pelo proxy, expondo os servidores DNS reais do usuário; o Related Origin Requests (ROR) do WebAuthn, que faz com que o serviço de credenciais do sistema busque, diretamente do dispositivo, um arquivo de validação hospedado no domínio de origem, expondo o endereço real do usuário; e o WebTransport, que ignora o proxy ao estabelecer uma conexão HTTP/3 direta.

No caso do Safari, o recurso Retransmissão Privada do iCloud+ também é afetado pela falha; embora projetado para ter dois servidores intermediários para o tráfego e as consultas de DNS, os recursos listados ocorrem fora desse mecanismo de proteção, expondo o usuário de qualquer maneira.

Isso afeta também navegadores que utilizam a API 1Application programming interface, ou interface de programação de aplicações. de proxy para privacidade, como o Onion, que foi alertado sobre o problema junto do Tor Project. O relatório pontua, no entanto, que a única exceção quanto à exposição desses dados com algum desses recursos é o nível de segurança “Silver” do Onion Browser, que desativa o WebTransport por meio do Modo de Isolamento (Lockdown Mode).

As conexões por VPN 2Virtual private network, ou rede privada virtual. não são afetadas pela falha de segurança, visto que o tráfego do dispositivo passa pelo túnel do provedor da rede privada virtual.

O relatório conclui informando que o problema foi resolvido na versão mais recente do Psylo, que desabilitou por ora o funcionamento do WebTransport e do WebAuthn, além de bloquear a dica de pré-busca de DNS.

via AppleInsider

Notas de rodapé

  • 1
    Application programming interface, ou interface de programação de aplicações.
  • 2
    Virtual private network, ou rede privada virtual.

NASA to Host Florida Event Celebrating American Air, Space Leadership

31 July 2026 at 22:08
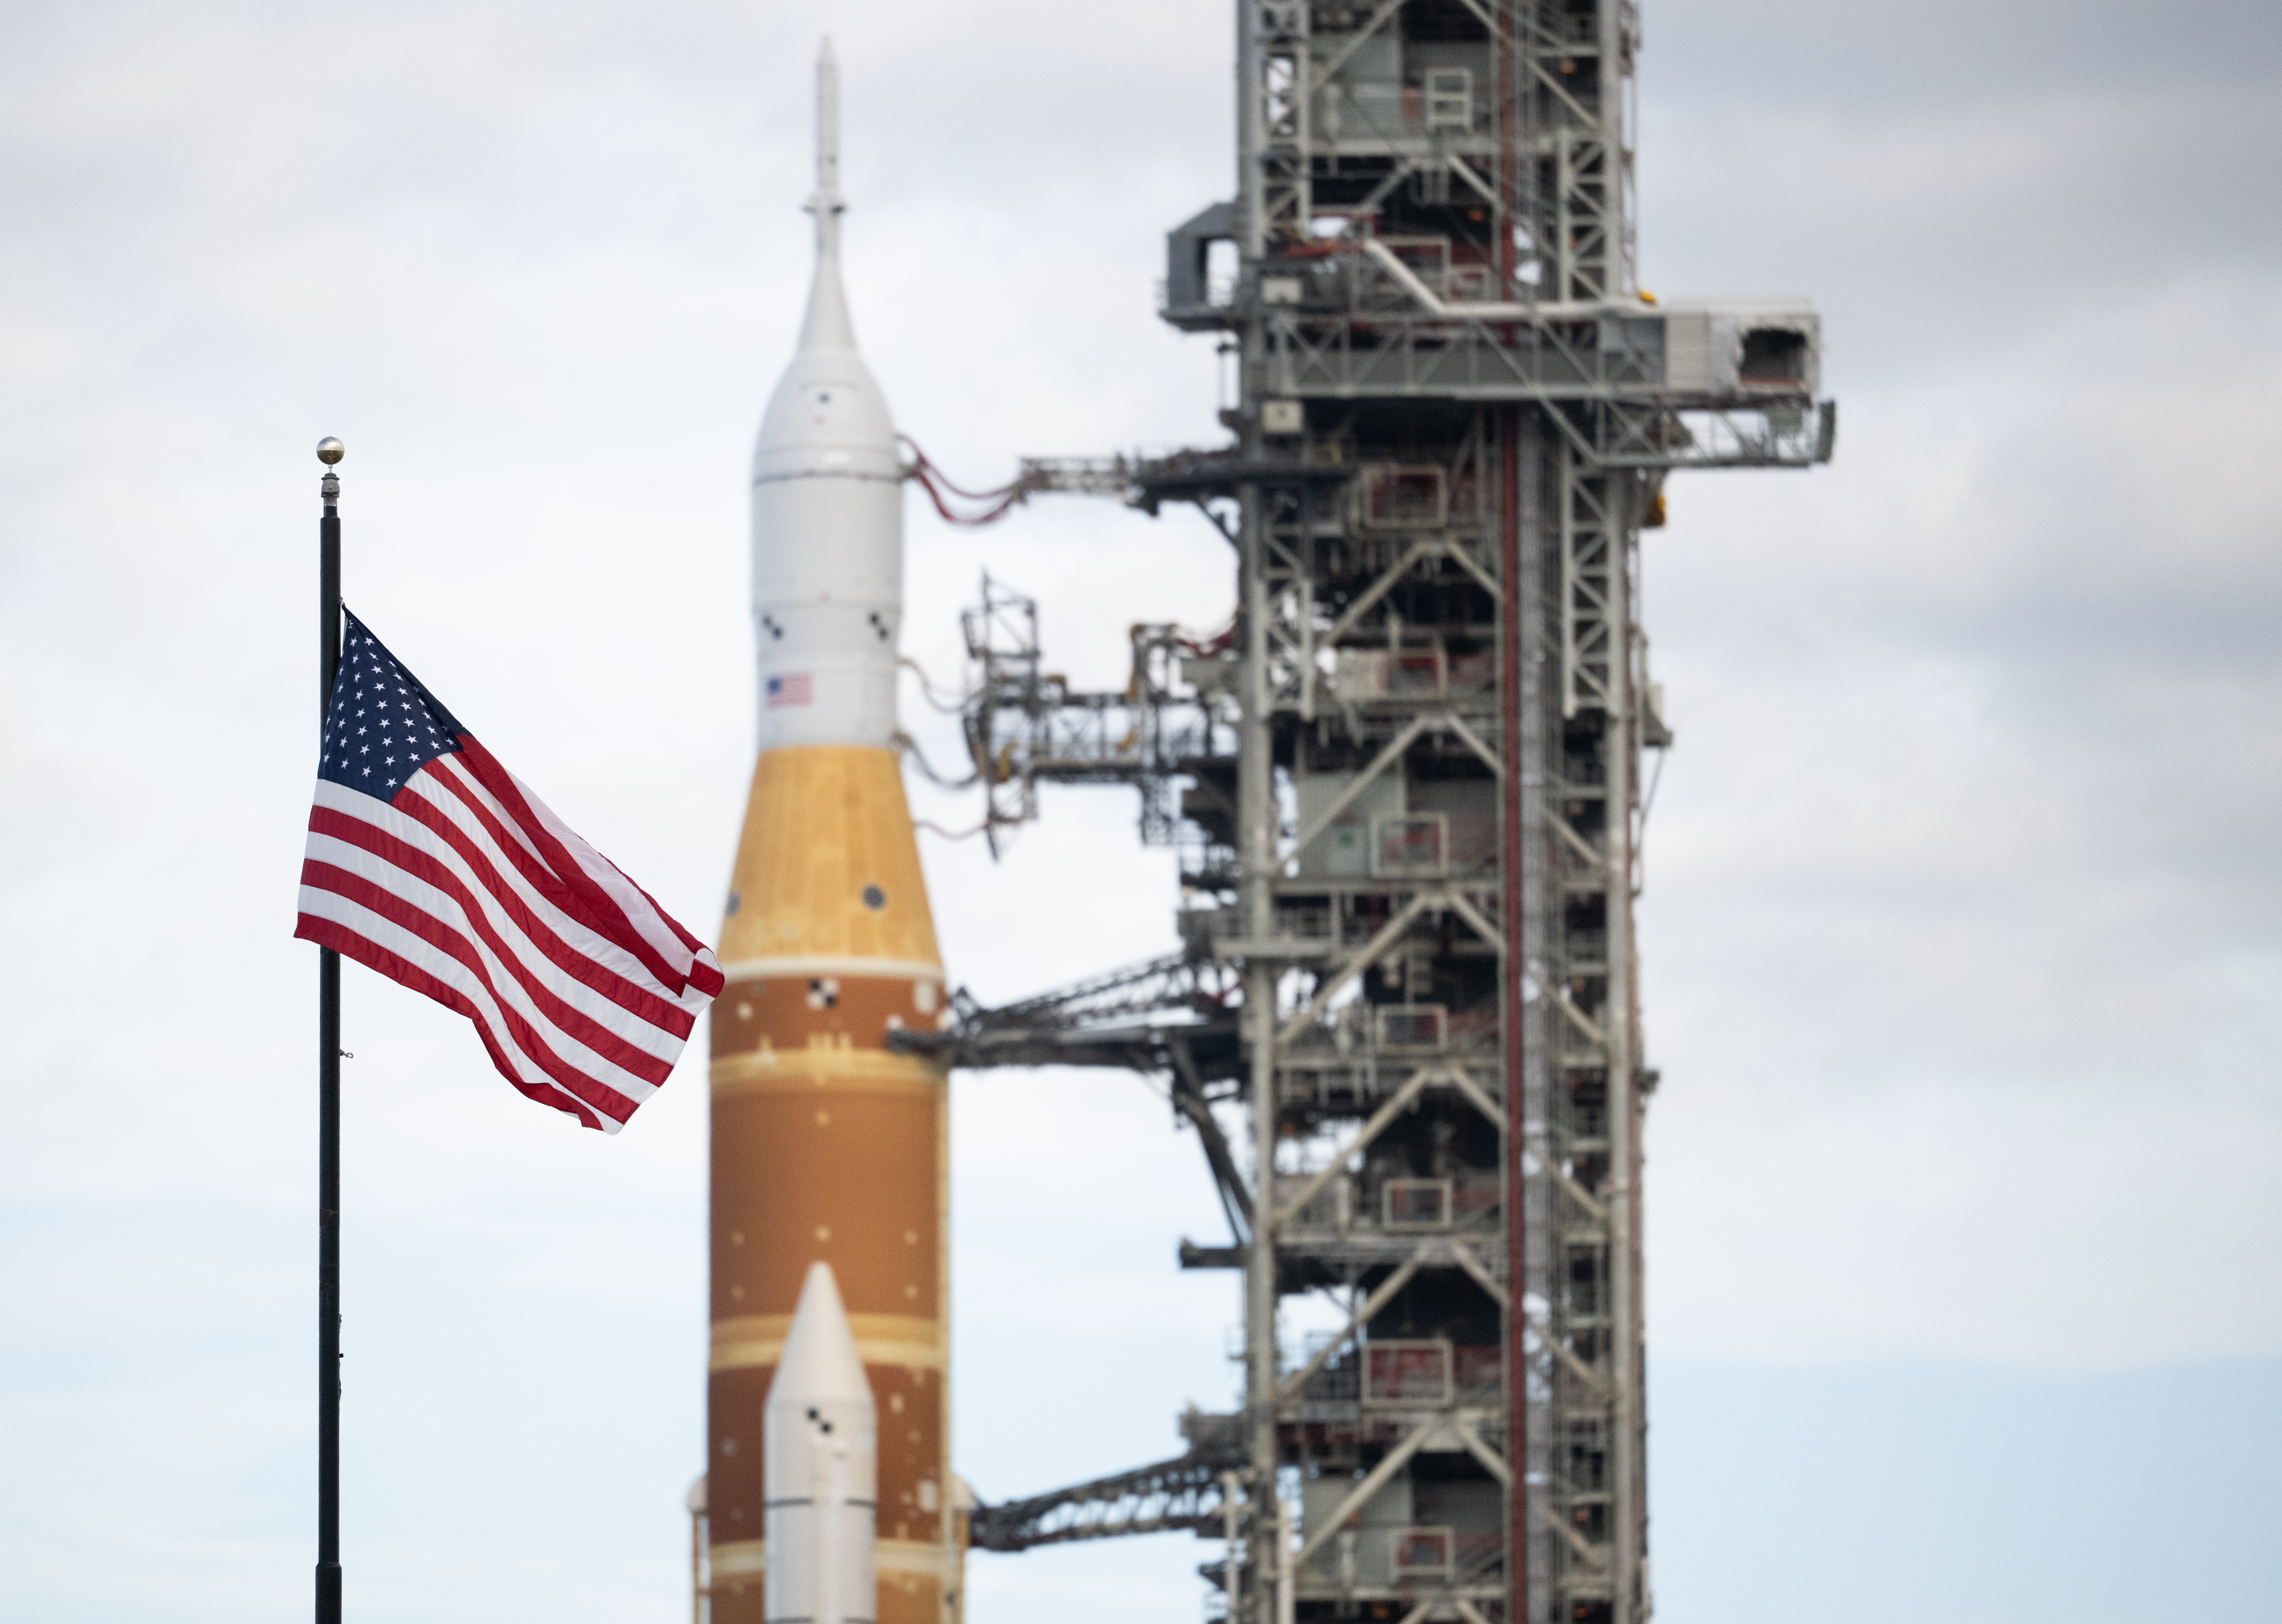
An American flag is seen in front of NASA’s SLS (Space Launch System) rocket and Orion spacecraft at NASA’s Kennedy Space Center in Florida on Jan. 17, 2026, ahead of the historic Artemis II test flight. NASA will host a news conference at NASA Kennedy on Friday, Aug. 14, to highlight American leadership in space and aviation.
Credit: NASA/Joel Kowsky

NASA will hold a news conference at 2:30 p.m. EDT, Friday, Aug. 14, live from the agency’s Kennedy Space Center in Florida, and media and digital creators are invited to attend in person.

The announcement, held in the XLV Hangar at the Shuttle Landing Facility, will preview a new event at NASA Kennedy later this year tied to America’s 250th anniversary, showcasing American leadership in aviation, space exploration, and emerging technologies while bringing together the public, industry leaders, innovators, and the next generation of explorers.

Participants include:

  • NASA Administrator Jared Isaacman
  • NASA leadership
  • Members of Congress

The agency will stream this news conference live through a variety of platforms:

https://www.nasa.gov/live

This event is open to U.S. media and digital creators. The request to attend must be received no later than 12 p.m. on Thursday, Aug. 6, to the Kennedy newsroom at: https://media.ksc.nasa.gov. NASA’s media accreditation policy is available online.

For more information about NASA’s missions, visit:

https://www.nasa.gov

-end-

George Alderman / Cheryl Warner
Headquarters, Washington
202-358-1600
george.a.alderman@nasa.gov / cheryl.m.warner@nasa.gov

Danielle Sempsrott
Kennedy Space Center, Fla.
321-298-8990
danielle.c.sempsrott@nasa.gov

Share

Details

Last Updated
Jul 31, 2026

The post NASA to Host Florida Event Celebrating American Air, Space Leadership appeared first on NASA Science.

NASA to Host Florida Event Celebrating American Air, Space Leadership

31 July 2026 at 22:08
An American flag is seen in front of NASA’s SLS (Space Launch System) rocket and Orion spacecraft at NASA’s Kennedy Space Center in Florida on Jan. 17, 2026, ahead of the historic Artemis II test flight. NASA will host a news conference at NASA Kennedy on Friday, Aug. 14, to highlight American leadership in space and aviation.
Credit: NASA/Joel Kowsky

NASA will hold a news conference at 2:30 p.m. EDT, Friday, Aug. 14, live from the agency’s Kennedy Space Center in Florida, and media and digital creators are invited to attend in person.

The announcement, held in the XLV Hangar at the Shuttle Landing Facility, will preview a new event at NASA Kennedy later this year tied to America’s 250th anniversary, showcasing American leadership in aviation, space exploration, and emerging technologies while bringing together the public, industry leaders, innovators, and the next generation of explorers.

Participants include:

  • NASA Administrator Jared Isaacman
  • NASA leadership
  • Members of Congress

The agency will stream this news conference live through a variety of platforms:

https://www.nasa.gov/live

This event is open to U.S. media and digital creators. The request to attend must be received no later than 12 p.m. on Thursday, Aug. 6, to the Kennedy newsroom at: https://media.ksc.nasa.gov. NASA’s media accreditation policy is available online.

For more information about NASA’s missions, visit:

https://www.nasa.gov

-end-

George Alderman / Cheryl Warner
Headquarters, Washington
202-358-1600
george.a.alderman@nasa.gov / cheryl.m.warner@nasa.gov

Danielle Sempsrott
Kennedy Space Center, Fla.
321-298-8990
danielle.c.sempsrott@nasa.gov

Share

Details

Last Updated
Jul 31, 2026

Rocket Report: New launch rule may limit environmental regulations, Falcon 9 to hit Moon

31 July 2026 at 11:30

Welcome to Edition 9.05 of the Rocket Report! It was a big week for launch contracts, with both Rocket Lab and SpaceX scoring sizable deals from the US military for their respective Electron and Falcon 9 rockets. The vehicles have been the workhorses for small and medium lift for the United States over the past decade and may remain so for some time. Also, there will be no Rocket Report next week, as I am traveling on assignment, and Stephen is taking a week off.

As always, we welcome reader submissions, and if you don't want to miss an issue, please subscribe using the box below (the form will not appear on AMP-enabled versions of the site). Each report will include information on small-, medium-, and heavy-lift rockets as well as a quick look ahead at the next three launches on the calendar.

Rocket Lab wins large Electron deal. Rocket Lab Corporation announced this week that it has been awarded its largest launch contract to date, a $266 million multi-launch contract with the US Space Force. Under the contract awarded by the US Space Force Space Systems Command, Rocket Lab will execute 12 suborbital launches, with up to six additional launches. The first launch of this contract is expected no earlier than the end of 2026.

Read full article

Comments

© Stoke Space

UK says the cloud is financial infrastructure

31 July 2026 at 10:00

Every cloud architect, every financial services executive, and frankly every enterprise CTO should be paying attention to what is going on in the United Kingdom right now. Britain has formally designated Microsoft, Google, Amazon Web Services, and Oracle as “critical third parties” to the financial sector, meaning they are now subject to direct oversight by UK financial regulators rather than being treated as distant infrastructure suppliers outside the regulatory perimeter.

The designations took effect on July 13, 2026, and the oversight will be carried out by the Bank of England, the Prudential Regulation Authority, and the Financial Conduct Authority. The point is straightforward. If these platforms underpin critical banking and financial operations, then their resilience is no longer just a procurement issue. It is now a matter of financial stability.

This is a bigger deal than many people understand. For years, enterprises have treated cloud platforms as outsourced technology providers. Regulators are now making a different argument. They are saying that when enough banks, insurers, payment firms, and market infrastructures depend on the same small group of cloud providers, those providers become systemic infrastructure whether they like the label or not. Reuters reported that the UK’s framework will bring requirements such as resilience testing, self-assessments, and incident reporting directly to these providers. In other words, this is not just more policy language. It is operational oversight aimed at the platforms themselves.

The first thing to understand is that this move is not anti-cloud. It is the opposite. It is an acknowledgment that cloud has become too important to remain lightly touched when it comes to systemic risk. Regulators are not trying to unwind cloud adoption in financial services. They are accepting the reality that core financial operations now depend on a concentrated set of external platforms. When that happens, the conversation changes from vendor management to infrastructure resilience.

Systemic cloud concentration

The market has spent years talking about cloud concentration risk as if it were some vague future concern. It is no longer abstract. The UK is acting because concentration at this level means that a disruption at one major provider can ripple across multiple institutions simultaneously. That is the core issue. It is not whether Microsoft, Google, Amazon, or Oracle are competent operators. In many cases, they are exceptionally good at what they do. The problem is that too much critical activity depends on too few shared platforms.

This is a concept many business and technology leaders still struggle to internalize. A single bank can do a fine job managing its own vendor exposure and still be part of a broader systemic vulnerability if every other bank is relying on the same provider, the same region, the same identity layer, or the same operational dependencies. Regulators are stepping in because the risk is collective, not just institutional. That is why this matters well beyond the UK. It provides a framework for thinking about cloud not as outsourced capacity, but as part of the plumbing of the financial system itself.

Regulators expand their reach

Traditionally, regulators focused on the bank, insurer, or market institution and expected that entity to manage the risks created by outside suppliers. That approach still exists, and financial institutions remain accountable for their own resilience. However, the UK now says that, in some cases, this indirect model is not enough. If a third party becomes critical enough, regulators want direct line of sight into that provider’s resilience posture as well. This is probably the most important architectural and policy signal in the entire move.

That changes the relationship between the financial sector and the cloud providers in a meaningful way. Direct oversight means cloud providers are increasingly being treated less like optional technology partners and more like essential utilities that support national economic confidence. Once that happens, architecture decisions start to carry a different weight. Decisions about control planes, failover models, identity dependencies, regional design, observability, and incident response are no longer just internal engineering choices. They become part of a broader resilience conversation that may now include regulators.

A lot of enterprises have been behind the curve. They built architectures under the assumption that the cloud was simply a faster and cheaper hosting model. It is not. At scale, cloud is shared critical infrastructure. The UK has now made that point explicit.

More scrutiny isn’t more safety

It’s tempting to read this and assume the problem has now been solved. It has not. Direct oversight of hyperscalers does not remove the responsibility of banks or other enterprises to architect well. In fact, it should push them to architect better. A regulated provider can still be a concentration point. A resilient platform can still be used in a fragile way. And a well-run cloud service can still become part of a badly designed dependency chain.

If you are in a regulated or highly sensitive industry, you should take this as a warning that resilience can no longer be treated as a side topic. You need to know exactly which services are business-critical, which control planes are shared, which identity systems create cross-platform dependencies, and how your recovery assumptions actually work in the real world. Most organizations are much weaker here than they believe.

The UK’s move should also force a hard conversation about operational transparency. If regulators are requiring incident reporting and resilience evidence from major providers, enterprises should be demanding clearer dependency mapping and better architectural visibility inside their own environments. You cannot build true resilience on top of assumptions and vendor slide decks.

The start of a much larger shift

The deeper message is that cloud is crossing a line from enterprise technology choice into national and sector-level infrastructure policy. Once a few governments and central regulators start treating cloud this way, the rest of the world tends to follow in some form. We have already seen comparable concern in Europe, and now the UK has made its own move with direct designations and direct oversight.

Architects, CIOs, and boards need to mature their thinking quickly. The conversation is no longer limited to feature depth, discounts, migration speed, or which provider has the best AI story this quarter. The conversation is now about resilience, concentration, transparency, control, and systemic dependency. Those are bigger issues, and they are not going away.

The UK is telling the market something very clearly. Microsoft, Google, Amazon, and Oracle are not just selling cloud services into the financial sector. They are becoming part of the infrastructure on which that sector depends. Once you understand that, everything changes, including how we architect for the future.

The platform team isn’t a cost center, it’s product infrastructure

31 July 2026 at 10:00

A few years ago, I sat in a postmortem that I still think about. We’d had a production incident where a routine deploy had quietly shipped with the wrong configuration, and it took us longer to notice and roll back than anyone was comfortable admitting. But when we traced the root cause, almost none of it was the feature code. It was the scaffolding around it: a Kubernetes manifest no longer matched our cluster, a CI pipeline whose green checkmark didn’t actually verify the thing we assumed it did, and a secrets-management step that three different services each did three different ways. The code itself had been fine for a week. Everything around the code is what failed us.

I have seen some version of that retro at nearly every company I’ve worked at over the last 15 years across a large IT services firm, a medical-device maker, a healthcare-technology company, a cloud-migration startup, and now a large SaaS platform. The names and the tech stacks changed. The pattern didn’t. Smart engineers spending a startling share of their week not on the problem they were hired to solve, but on the accidental complexity of shipping it.

For a long time, I assumed the answer was better documentation, or a stricter DevOps culture, or just hiring people who were more comfortable with YAML. I was wrong on all three counts. What actually changed my mind was reframing the problem entirely: the friction wasn’t a knowledge gap or a discipline gap. It was a product gap. Nobody owned the developer’s experience of shipping software the way a product manager owns a customer’s experience of using an app. And the discipline that closes that gap now has a name: platform engineering, which Gartner describes as having “emerged in response to this increasing cognitive load resulting from the complexity of modern software tools and architectures.” Gartner isn’t shy about how fast it’s spreading, either: the firm predicts that “by 2026, 80% of large software engineering organizations will establish platform engineering teams,” up from 45% in 2022. If that number is even close to right, the interesting question is no longer whether to build a platform team but whether you’ll build a good one.

The moment “DevOps” quietly stopped scaling

I want to be careful here, because “DevOps is dead” is a lazy headline and I don’t believe it. The principles behind DevOps include shared ownership, automation, and tight feedback loops. These are as right today as they were when the movement started.

What broke, in my experience, was the operating model. The original promise was “you build it, you run it.” Every team owns its own deployment, its own observability, its own on call. That works beautifully when you have a handful of teams and a shared oral tradition. It falls apart when you have 50 teams, because now you have 50 slightly different ways of doing the same undifferentiated work. 50 ways to define a service. 50 subtly wrong Kubernetes configurations. 50 on-call rotations paging fifty engineers about the same class of problem at 3 a.m.

The cognitive load of “run it yourself” grew faster than most teams could absorb. That framing of cognitive load as the thing you’re actually optimizing for comes from “Team Topologies,” a book that reshaped how I think about org design more than any purely technical text I’ve read. Its fourth principle is blunt about the limit: “Teams can only handle so much complexity before breaking down,” and “competent teams become ineffective when leaders keep adding to their plate without taking anything away.” That last line described my own teams so precisely it stung. “Team Topologies” also gave me the vocabulary I’d been missing. It names four fundamental team types, and it defines a platform team as “a grouping of other team types that provide a compelling internal product to accelerate delivery by stream-aligned teams”. Read that definition again: a compelling internal product. Not a shared-services desk, not a Terraform repo with a wiki. A product. That single word is the whole argument.

Treating the platform as a product changes everything

Here’s the shift that took me embarrassingly long to internalize: if the platform is a product, then developers are its customers, and you don’t get to tell your customers they’re holding it wrong.

That one reframing has downstream consequences that surprised me.

The first is that adoption has to be earned, not mandated. Early in my time working on internal tooling, I helped build a platform capability that we were quite proud of, and then we did what infrastructure teams love to do: we announced it, and assumed people would come. They didn’t. Teams routed around it, because the golden path we’d paved was, frankly, gravel. The lesson landed hard. A platform that developers have to be forced onto is not a platform, it’s a tax. When we went back and rebuilt it so that the paved path was genuinely the easiest path. This is the same instinct behind Backstage, the developer portal that was built at Spotify and is now a CNCF project; its own pitch is that it “restores order to your microservices and infrastructure” so product teams can ship quickly. Order you have to opt into isn’t order. The tool wins when choosing it is the lazy option.

The second consequence is that “self-service” has to mean what it says. It’s an overused word, so I hold it to the CNCF’s definition from its platforms white paper: “A platform should be self-serviceable. Users must be able to request and receive capabilities autonomously and automatically.” Autonomously and automatically. If a developer has to file a ticket and wait on my team to provision a database, I haven’t built a platform instead I’ve built a slower version of the help desk. The same white paper states the north star plainly: “An essential goal of a platform is to reduce the cognitive load on product teams.” I’ve started using that sentence as a litmus test. For any capability we’re tempted to add, I ask whether it removes load from a product team or quietly adds some. A surprising number of well-meaning platform features fail that test.

The third consequence is that you have to measure the platform the way you’d measure any product and resist measuring the things that only flatter the platform team. “How many clusters are we running” is an output my team cares about and nobody else does. The metrics that matter describe the developer’s lived experience, and the most durable set I know of comes from DORA, the long-running research program into software delivery performance. Its metrics have evolved from the original “four keys” have grown to five. The core throughput measures still ask exactly the right questions: change lead time (“the amount of time it takes for a change to go from committed to version control to deployed in production”), deployment frequency, and failed deployment recovery time, balanced against a change fail rate. I’ve found those double as a remarkably honest scorecard for a platform team, precisely because they refuse to reward busywork. You cannot game your way to a good lead time by shipping more internal tools nobody uses.

The fourth consequence is the hardest culturally: a platform product needs a roadmap, user research, and the willingness to say no. I’ve watched platform efforts collapse into a junk drawer of one-off requests, each reasonable on its own, that together add up to an incoherent pile of tools nobody can hold in their head. Saying no to a well-intentioned request is a product-management skill, and platform teams that never develop it end up rebuilding the very sprawl they were created to eliminate. The best platform leads I’ve worked with spend as much time talking to their internal users as any consumer-facing PM does.

What I’d tell my younger self

If I could go back to that retro years ago, I’d say a few things to the version of me who thought this was a documentation problem.

Start with the paved road, not the platform. You don’t need to build an internal developer portal in quarter one. You need to find the single most painful, most repeated piece of undifferentiated work is the distance between “here is my container” and “it is running safely in production”. Earn the next piece of scope by delivering that one well. Platforms that begin as grand architectures tend to die as grand architectures; the ones that survive start as one genuinely useful paved road that people choose on their own.

Resist the urge to abstract away everything. The goal of a good platform is not to hide Kubernetes so completely that no one understands what’s happening beneath them; that just trades one kind of fragility for another. The goal is to remove the toil while leaving the understanding intact. When the abstraction leaks you want engineers who can reason about what’s underneath, not a room full of people who only ever knew the buttons. I’ve paid for both mistakes: platforms too thin to help, and platforms so thick that an incident turned into an archaeology dig.

And treat “developer experience” as a first-class business metric, not a morale nicety. Every hour an engineer spends fighting the delivery pipeline is an hour not spent on the thing your customers actually pay you for. When I frame platform investment that way to leadership as reclaiming a meaningful fraction of my most expensive people’s time that’s when the conversation stops being about cost and starts being about leverage. It is genuinely one of the highest-return investments an engineering organization can make, and it almost never shows up as a line item that looks like one.

The platform team is not the group that keeps the lights on. It’s the group that decides how fast everyone else can move. Once I started treating it as the most important product my organization ships internally, almost every other decision got easier. I just wish it hadn’t taken me a missed release and a room full of frustrated engineers to see it.

This article is published as part of the Foundry Expert Contributor Network.
Want to join?

Experts warn current Starship heat shield tech is a "dead end" for rapid reuse

27 July 2026 at 19:34

SpaceX successfully launched its Starship vehicle on Friday and appeared to demonstrate important and credible steps toward fulfilling the massive rocket's immense promise. As soon as the vehicle's next flight, Starship could go orbital, begin delivering satellites into space, and potentially return to the launch site to be 'caught' by the tower.

All of this is impressive engineering on a gigantic scale. But despite the marked progress with the 13th test flight of Starship, one key issue—probably the key issue when it comes to Starship's future—remains unresolved.

This concerns Starship's heat shield, the roughly 18,000 ceramic tiles that protect the vehicle's underbelly during its fiery return through Earth's atmosphere. And some experts say SpaceX's current approach may not get Starship to its ultimate goal of flying frequently, at low cost.

Read full article

Comments

© SpaceX

SpaceX Stock Hammered After Starship Booster Fails in First Launch Since IPO

27 July 2026 at 19:19

Was SpaceX’s recent Starship flight test a success or a failure? Many are hailing it as a victory, but several of the megarocket’s booster’s engines failed after re-entry, causing it to explode.

SpaceX has had many similarly ambiguous tests before. But this was the first one since its much-hyped IPO earlier this summer — and it’s already clear that it wasn’t a convincing enough display to reverse the company’s fortunes on the stock market.

After hitting an all time low before the weekend and closing at $115, SpaceX shares endeavored to plummet even further on Monday, briefly dipping to $108.66 — a new nadir since going public — before stabilizing around $110. The new low is over 20 percent below its opening IPO price of $135, and less than half of its all time high of more than $225 per share.

It’s a sign of the scrutiny the company will be put through now that it’s a public entity, and comes despite certain predictions that a successful flight would help buoy the company’s shares. When Starship ran into trouble in the past, SpaceX mainly had to weather a storm of media coverage. Now, nervous investors represent yet another liability.

“One of the benefits of being private is that there wasn’t a market to weigh in on and evaluate business decisions,” David Meier, senior investment analyst at the Motley Fool, told The Washington Post.

“Being publicly traded means everything will be evaluated and information transmitted through market prices,” he added. “So every SpaceX launch, every Starlink decision and every xAI decision will be scrutinized by the market.”

Spaceflight, at least currently, isn’t an ideal match for the make-a-quick-buck capitalism that Musk extolls. SpaceX has never been profitable, losing $5 billion last year alone. As Starship’s woes illustrate, rocket development is messy and complicated; there’s no guarantee that progress will be linear, if there’s any made at all. Investors are essentially being asked to keep pouring money into an incredibly lengthy and expensive science experiment. 

Meanwhile, Musk has made outrageously lofty promises that SpaceX will eventually use Starship to deploy so many data centers in space that it’d create a “sentient sun,” and establish colonies on the Moon and eventually Mars. Every failure will be compared against those outsized benchmarks, which is almost certainly part of Musk’s enduring schtick.

The thirteenth test flight on Friday was a mixed-bag. The spacecraft’s upper stage successfully made its way to suborbital space and deployed a payload of Starlink internet satellites, which briefly went online before burning up as planned. This was a first for Starship, as previous tests only used dummies. Then the ship re-entered the atmosphere and landed in the Indian Ocean in one piece without exploding.

But the booster was a different story. Though it performed flawlessly on the journey up, only ten of out the thirteen engines fired up on its return to Earth, failing to slow the massive object down in time. Instead of making a planned “soft” splashdown, it slammed into the Gulf of Mexico and appeared to explode on impact.

On the one hand, the flight test validated that SpaceX is making progress with its latest V3 iteration of its spacecraft. In the first V3 flight test in May, the upper stage lost several of its engines on its way to space, and this time it didn’t. The upper stage also survived the splash down instead of exploding, with SpaceX engineers calling it Starship’s best reentry yet. 

But the failed booster landing is hard to overlook. Unless the booster is reliably recoverable, then Starship won’t be reusable, an indispensable part of making the behemoth vehicle an economically viable means to ferrying large payloads into orbit and beyond.

Most coverage around the recent test has been positive. Arguably, that makes it all the more concerning that the stock continues to perform so poorly.

“The future of the company is riding on the ability to make Starship work,”  Clayton Swope, deputy director of the Aerospace Security Project, told WaPo. “What they’re trying to do is switch to a freight train and get the economies of scale [of] something of that magnitude.”

More on SpaceX: SpaceX Investors in Meltdown Over All the Money They’ve Lost

The post SpaceX Stock Hammered After Starship Booster Fails in First Launch Since IPO appeared first on Futurism.

❌