❌

Normal view

Only Three Are Known To Exist: China’s Mysterious Eyeless Cave Snail

9 August 2026 at 12:22
Species of Erhaia Dijiang With a Scale Bar of 1 mmScientists have discovered China’s first known freshwater cave snail, an eyeless species so rare that only three living adults have been found. Deep inside a mountain cave in southwestern China, scientists found an animal that appears built for a world where sunlight never reaches. The tiny freshwater snail has no eyes, almost no color, and [...]

How Sri Lanka’s heirloom rice can preserve Indigenous farming and help manage disease

WASGAMUWA, Sri Lanka – Prior to the 1940s and the Green Revolution, Sri Lankan paddy farmers cultivated traditional rice, locally known as purana haal. These rice cultivars were resilient and known to possess various nutritional and medicinal properties yet were soon replaced by new improved rice varieties to obtain better quality and bigger yields. Karu Herath, an heirloom paddy farmer in the village of Dunuwila, bordering the Wasgamuwa National Park located within the Matale and Polonnaruwa districts, has cultivated heirloom paddy varieties for the past 27 years. He told Mongabay that fewer than 30 varieties remain out of the estimated 2,500 varieties of heirloom rice that once existed, a claim supported by rice researchers. According to researchers, many of these rice varieties are long-aged, tall and low-yielding. Therefore, traditional farmers would only cultivate them during one harvesting cycle, known as the Maha season, which runs from September through March. With the introduction of new, improved rice varieties and fertilizers after the 1940s, Sri Lanka lost much of its Indigenous rice varieties and traditional knowledge of Indigenous farming practices. Image courtesy of Pethum Bandara. Herath follows this practice and cultivates only during the monsoon season. “During the Yala season [May to August], when it’s dry, we let the soil recover and grow heirloom cereals and vegetables such as kurakkan [finger millet] and mung [mung bean],” he said. “This draws different nutrients and requires less water than rice. This was the traditional land use system, which was changed by British colonialists who…This article was originally published on Mongabay

Polish data center plans to send its waste heat to the neighbors

7 August 2026 at 16:16

As Europe swelters in a heatwave, residents probably don’t want to hear about ways to make their homes even hotter, but that’s what Polish property developer Citylink is talking about, with plans to dump waste heat from a new data center in Wrocław into the municipal district heating network.

Citylink is designing the data center so that heat from servers can be recovered instead of being dissipated via cooling systems — and as the data center grows, any increase in computing power will mean more energy available for recovery.

The collaboration with local power company Kogeneracja will provide “valuable experience in designing and operating modern data centers, with a particular focus on infrastructure dedicated to AI nodes,” said Michał Starybrat, development director at Citylink.

“The dynamic growth of the artificial intelligence and cloud technology markets generates unprecedented demand for computing power, this collaboration demonstrates how modern digital infrastructure can actively contribute to building the energy ecosystem of the future,” he added.

This type of initiative is not new. There have been similar projects in the UK and in New Zealand, but with warnings that data centers are contributing to the warming of the planet, there may well be a lot more organizations looking to deploy that excess heat more fruitfully in the future.

However, announcing it during a heatwave may not be the most politically sensitive approach to take.

This article first appeared on Network World.

Cloudflare wants to provide the operating system for the AI-first enterprise

7 August 2026 at 01:31

Traditional operating systems (OS) were built to manage hardware, files, apps, and users on a device, but Cloudflare says the agentic AI era requires a whole new format.

The company this week announced Cloudflare OS, which connects AI agents, enterprise data and context, internal systems, and workflows together in one secure workspace. It is open source and browser-based, sparing companies the need to build all-new infrastructure.

The OS is launching alongside several other new security, identity, spending, and user insight tools that Cloudflare has built for the AI-based workplace.

“Cloudflare OS isn’t a traditional desktop OS,” said Rita Kozlov, VP of product at Cloudflare. “It reimagines the workplace computing environment for AI.”

Open source OS runs in a browser

Cloudflare OS serves as a secure, AI-equipped workspace that is plugged into internal company systems. Available now through Cloudflare’s open source repository, it is accessible directly in a browser, and runs inside an enterprise’s Cloudflare account.

“It is a browser-based workspace that begins with a conversation,” Kozlov explained. Users can ask an agent to research, create slides, spreadsheets, and documents, build full-stack apps, or automate workflows without the need for a terminal. Those outputs are then shareable, but kept in isolated databases with access controls.

Enterprises will soon be able to access the OS directly through Cloudflare or via a “select group” of partners that will build tailored offerings on Cloudflare’s architecture, the company says. Because it is open source, organizational processes, internal system connections, and context aren’t locked into a vendor product or AI model provider. Customers can use whatever models they choose.

Cloudflare OS is built on Cloudflare Workers, Dynamic Workers, Durable Objects, and Access, the company’s zero trust network access (ZTNA) tool that verifies every user and request. Agents start with zero permissions by default and are only granted access to tools required for a specific task. Organizations configure their own Access policies, models, branding, skills, and integrations, Kozlov explained.

Governed connectors known as gatekeepers give admins control over what AI can see, what it can change, and when the system needs human sign-off. They can also control budgets, set rate limits, and delegate tasks to different models.

“Because agents act on people’s behalf and produce work others can access and modify, they require a new security model,” Kozlov said. Thus, Cloudflare OS tracks the resources an agent requires so the right access controls follow its work when it is shared.

Cloudflare initially built the OS for internal use, and employees “across every team” use it daily. Kozlov estimated that, over the last 30 days, internal users have used it to create more than 4,000 apps, automations, and tools. Over that same period, she claimed, the company’s sales team saved an estimated 10,000 hours by automating previously manual tasks like territory planning and proposal creation.

“We open sourced Cloudflare OS so any organization can build ‘Your Company OS,’” Kozlov said. Open source is critical because “you cannot put your company into software you do not own. Organizations need to be able to inspect the platform, customize it, connect their own systems, and make it their own,” she explained.

A more cohesive bundle

Cloudflare deserves credit for packaging Cloudflare OS as an operating system, noted tech analyst Carmi Levy.

“This very much is not Windows, macOS, or Linux, and it isn’t an operating system by its common definition,” he said. “But Cloudflare’s use of this terminology implies familiarity to enterprise IT buyers.”

This makes for an easier discussion as enterprises struggle to understand how to best incorporate AI-related platforms and workflows into infrastructure that wasn’t initially designed for it.

Microsoft has marketed the combination of its Azure, Entra, Fabric, Windows, and Microsoft 365 offerings as an operating system of sorts, but hasn’t pulled all the pieces into a common brand, Levy said. And Google’s Gemini, Workspace, Vertex AI, and Cloud Run are “circling similar territory.”

But, he noted, Cloudflare OS is “more cohesively bundled” and infrastructure-focused, offering a single pane of glass platform for buyers worried about stitching together otherwise disparate AI-aware networking pieces. The company recognizes that AI introduces new architectural realities such as inference and model routing “over and above” traditional OS core competencies.

“While competing offerings generally leave the infrastructure heavy lifting to enterprise decision-makers, Cloudflare is marketing itself as a single-source vendor, which potentially frees IT planners from having to integrate all the AI pieces on their own,” Levy said.

An infrastructure-first, application-agnostic approach means Cloudflare OS can coexist with whatever AI applications already exist in an enterprise, he said. It will “play nice” with OpenAI, Anthropic, Google, Microsoft, Meta, or open source layers, allowing employees to begin working in familiar workflows after sign-in.

“Its open-source architecture also minimizes the potential for vendor lock-in as enterprises gradually figure out how to evolve their stacks to align with new AI-era realities,” Levy said.

Managing identities and budgets for both humans and AI

As AI agents emerge across the enterprise, tracking their use can be challenging, causing problems from both a security and a spend standpoint. Along with Cloudflare OS, the company has launched a way to address this issue with its new Identity-Aware AI Gateway, now in beta.

Also integrated with Access, the offering gives admins visibility into what users (both human and AI) are requesting from AI models. It allows security teams to set up custom domains in front of their gateways and replace shared API keys by integrating with their identity provider, like Okta or Entra, and ZTNA infrastructure, Cloudflare explained.

Every request is tied to Access-verified identities, and enterprises can filter each user’s logs, analytics, and spend. IT teams can track redundancies, limit usage rates, and apply filters that strip out employee names, passwords, and other sensitive data before requests go to outside model providers.

A companion feature, AI Spend, tracks every user’s behavior over time to create a baseline of normal AI usage. When spending deviates from that pattern, the system alerts the IT team.

A new tab, User Insights, tracks cost and identifies over-spend caused by activities such as low cache-hit rates or oversized context windows. The capability scores sessions and compares them against account history using a 95th percentile session cost over the previous 30 days, Cloudflare product managers Ming Lu, Kenny Johnson, and Ayush Kumar explain in a blog post. Anything above 2x an account’s 95th percentile is a “strong candidate for anomalous behavior.”

For instance, one Cloudflare customer had an employee who left a rogue AI session running, generating a $30K bill. “User Insights helped them identify the problem and shut off access before the problem was further exacerbated,” Kozlov said.

Cloudflare is also building prompt classification functionality that sorts requests into categories such as coding or writing. This can help enterprises understand what AI is being used for.

“Once business traffic is separated from everything else, personal use becomes visible,” the project managers explained. “From the outside, someone running a side hustle on company time and someone quietly moving data out through a model look the same. Telling them apart is central to catching insider risk.”

Looking at the bigger picture

Identity-Aware AI Gateway and AI Spend address the visibility problem that has dogged so many recent AI deployments where enterprises failed to monitor usage, Levy noted. Projects “crashed and burned” as users unwittingly blew through token allocations.

These platforms provide single-point visibility into what is being used, how it’s being used, and where the potential lies for raising the productivity bar, he said. They overlay with existing models; in doing so, they enhance security with more precise control over resource allocations, and via automated anonymization protocols that prevent inadvertent sharing of sensitive data.

Ultimately, he said, vendors who free IT from having to independently assemble the pieces of their own AI implementations, and who assist them with answers to AI-specific questions, “will gain advantage over vendors that aren’t looking at the bigger picture.

This article originally appeared on CIO.com.

Can melting ice increase glacial hazards?

6 August 2026 at 12:00

Globally, about 1 billion people live near glaciers and depend on glacial water. As temperatures continue to climb due to global warming, glaciers can become unstable and hazardous to nearby communities. These communities risk exposure to a series of linked processes, like ice collapse, flooding, and landslides, which could have life-threatening consequences. Scientists call these events catastrophic glacier hazard chains, or CGHC. So, a team of scientists in China sought to understand the driving forces behind these dangerous phenomena. 

The team focused on a CGHC event that occurred in 2018 at the Sedongpu Glacier, located in the Eastern Himalayas. During this event, the glacier obstructed the flow of 30 million square meters (more than 300 million square feet) of the Yarlung Tsanpo River, one of the main rivers within the region. 

To reconstruct the event, the team observed satellite images of the Sedongpu glacier over time, using a process called remote sensing. They used the images to calculate ice volumes, glacier velocities, and glacier movement between 1961 and 2018, to determine the glacier’s long-term physical properties and how they changed over time. They found that from 1968 to 2013, the Sedongpu Glacier shrank, or retreated, by over 6 football fields. It also lost ice and water volume and increased its velocity.

The scientists also measured earthquake waves on the Earth’s surface, or seismicity, to characterize any downslope rock or debris movements caused by the glacial retreat. They measured seismicity across 11 different seismic stations within 580 kilometers (about 350 miles) of the glacier. Then, they used this data to identify 2 distinct phases of the CGHC event on Sedongpu Glacier: the ice-rock avalanche and the debris flow.

When the ice-rock avalanche occurred, the team detected noticeable increases in seismicity, suggesting it lasted over 30 seconds. During those 30 seconds, over 8 million cubic meters (more than 280 million cubic feet) of ice fell onto the main glacier. The team recorded even more increases in seismicity during the debris flow, which lasted nearly 5 minutes. The debris from the avalanche hit the main valley glacier at nearly 300 kilometers (200 miles) per hour.

The researchers combined these data to describe how the 2018 CGHC event unfolded. First, the backward movement and shrinkage of the glacier produced an unstable sheet of ice hanging over a cliff face. The steep slope and large cracks in the ice caused an ice-rock avalanche. Debris from the avalanche then accumulated on the main glacier, causing it to move faster. As the main valley glacier moved downslope, it picked up even more debris from the bottom and sides of the glacial valley. The melting ice also increased the glacier’s velocity, and its movement eventually transitioned into a debris flow, which obstructed the Yarlung Tsangpo River. 

In total, the CGHC event in the Sedongpu Glacier travelled over 10 kilometers (6 miles) and moved down in elevation for over 3 kilometers (about 2 miles) at a velocity of about 100 kilometers (about 70 miles) per hour. The glacier accumulated enough debris and ice to fill thousands of Olympic-sized swimming pools. Imagine what this could do to a nearby village!

It’s difficult for scientists to estimate when CGHC events will occur, but this team proposed several factors that could help predict them. These factors included the size of the ice-rock avalanche and the glacier velocity, as well as the occurrence of earthquakes, temperature changes, and the melting of the glacier’s underside. They stated that these factors can combine to create a domino effect that drives the CGHC process. They recommended consistent glacial monitoring as temperatures continue to climb, in the Himalayas and globally. 

The team concluded that understanding CGHC events can help scientists mitigate glacial hazards and keep people safe, especially in mountainous areas such as the Eastern Himalayas. They stated that their findings illustrate the dangerous processes behind glacial melting, but further research is needed to accurately assess those processes and ensure nearby communities remain safe.

The post Can melting ice increase glacial hazards? appeared first on Sciworthy.

Testing local weather knowledge in the Bolivian Altiplano

3 August 2026 at 12:00

In the Bolivian Altiplano, fewer Aymara farmers are relying on local weather knowledge to schedule farming tasks, like choosing the best dates to plant crops and predicting a frost or drought. At the same time, there is growing doubt about whether these traditional indicators remain relevant today in the context of rapid social, economic, and climatic changes. 

Farmers are struggling because the National Weather Service of Bolivia (SEHNAMI) fails to provide useful weather forecasts due to the geographical complexity of the Andes and a scarcity of weather stations. In addition, many farmers can’t access this information because SEHNAMI lacks local outreach programs to deliver reports directly to them. In a region with a weak technical forecasting system, local knowledge is a vital resource, but its use is declining.

Scientists in the past focused on preserving local weather knowledge or discussing how it might help communities adapt to climate change. However, very few researchers have scientifically validated local weather indicators, since doing so requires many years of historical meteorological data to establish statistical “skill” in local forecasting. 

Faced with this gap, researchers in the US and Bolivia recently set out to validate indigenous indicators in 2 Bolivian municipalities: Umala in the Central Altiplano and Ancoraimes in the Northern Altiplano. To do this, they paired each traditional weather sign with a measurable variable, like temperature, that could approximate it. This approach allowed them to directly compare traditional observations with scientific data.

The researchers wanted to determine whether traditional weather knowledge is still accurate and relevant under current conditions, since validating these methods would strengthen local knowledge and benefit the schools and policies that promote it. To test this, the researchers worked with 6 Aymara communities. First, they conducted workshops with local leaders and experts to compile a set of weather-forecast indicators. Then, they surveyed 95 farmers to rank the reliability of these indicators. 

Through discussions with these communities, the team identified 13 weather indicators in the Central region and 20 in the Northern region. These indicators included specific plants, animals, and physical factors like constellations or winds that the farmers used to decide when and where to plant crops, and to predict weather conditions for the next season. The researchers focused on 2 key indicators that the farmers ranked as most reliable: the presence or absence of moisture under rocks on the Fiesta de San Juan on June 24th, and the flowering patterns of specific plants, called Thola and Sank’ayu. The farmers used the San Juan indicator to predict whether the upcoming year would be rainy or dry, and the plants to determine the most favorable dates for planting to avoid agricultural risks like frosts.

Finally, the researchers compared forecasts based on these 2 signs with over 30 years of meteorological data from nearby weather stations. In both cases, they used the minimum daily temperature as the measurable way to represent these local signs scientifically. Their results showed that the minimum daily temperature on the Fiesta de San Juan could explain more than half (55.5%) of the changes in rainfall during the growing season. They also confirmed that severe frosts that “burned” Thola and Sank’ayuthe flowers were followed by periods without rain, validating the farmers’ strategy of delayed planting.

The researchers concluded that local weather indicators used by Aymara farmers are most reliable for seasonal planning, especially in predicting the start of the rainy season. They stated that this result helps legitimize traditional knowledge and empower the community. For example, these communities now hold regular meetings to discuss forecasts and share this information with their neighbors via WhatsApp groups. 

However, the team acknowledged that local knowledge was limited to short-term forecasting, as it only provided warnings a few hours in advance. Farmers need alerts several days in advance to effectively reduce their vulnerability to events such as frosts or hail. For this reason, the researchers suggested that the next step will be to co-produce forecasts by combining meteorological science with traditional knowledge.

The post Testing local weather knowledge in the Bolivian Altiplano appeared first on Sciworthy.

Marine Heatwaves Are Hiding Far More Heat Than Scientists Realized

Sunlight on SeagrassThe first study of its kind shows that ecosystems experience far more cumulative heat than standard measurements reveal. A marine heatwave may have an official beginning and end, but the warm water affecting an ecosystem often does not. Like a pot that continues absorbing heat over time, coastal waters can remain unusually warm for weeks [...]

Bentham Science Launches International Journal of Wireless and Communication Engineering Innovation

2 August 2026 at 06:24

Bentham Science Launches Two New Journals to Accelerate Research in Wireless Communications and Engineering

Bentham Science Publishers has announced the launch of two new peer-reviewed journals designed to capture the rapid transformation of modern technology: Wireless and Communication Letters and Current Engineering Letters and Reviews. Both publications are now open for manuscript submissions, offering researchers an international platform to share emerging discoveries in communication systems, engineering technologies, and interdisciplinary innovation. The launches arrive as advances in artificial intelligence, sixth-generation wireless networks, satellite systems, advanced materials, and sustainable engineering continue to reshape scientific research and industrial development.

Wireless and Communication Letters is focused on the technologies that enable today’s increasingly connected world. The journal will publish original letters, full-length research articles, comprehensive reviews, mini-reviews, and guest-edited thematic issues addressing both theoretical developments and practical applications. Its scope covers the complete communication chain, from antennas and radio-frequency hardware to signal processing, network architecture, cybersecurity, and intelligent software. By emphasizing the efficient dissemination of research, the journal aims to provide a rapid channel for findings that could influence the next generation of wireless infrastructure.

The technical challenges addressed by the journal are central to the future of digital connectivity. Fifth-generation networks have already introduced high-speed mobile broadband, ultra-reliable low-latency communication, and massive machine-type connectivity, but researchers are now investigating 6G systems capable of supporting even greater data rates, extremely precise sensing, and seamless integration with artificial intelligence. These systems may combine terahertz frequencies, reconfigurable intelligent surfaces, distributed antennas, edge computing, and advanced machine-learning algorithms. Such technologies require new approaches to spectrum allocation, energy efficiency, network coordination, and data security.

The journal also welcomes research on the Internet of Things and machine-to-machine communication, areas in which billions of sensors and devices are expected to exchange data with minimal human intervention. In these environments, communication protocols must operate reliably despite limited power, unpredictable radio conditions, and enormous numbers of connected nodes. Research into low-power wide-area networks, intelligent scheduling, network virtualization, and secure device authentication could help support applications ranging from industrial automation and smart cities to remote healthcare and environmental monitoring.

A further component of the journal’s scope involves the physical science of communication. Antenna design, electromagnetic propagation, microwave engineering, optical links, and satellite communication determine how information travels through real environments. Engineers must account for obstacles, atmospheric conditions, interference, polarization, bandwidth limitations, and the movement of users or spacecraft. Developments in compact antennas, beamforming, optical wireless communication, and satellite-terrestrial integration could improve connectivity in rural regions, disaster zones, transportation systems, and future space missions.

Wireless and Communication Letters is led by Editor-in-Chief Dr. Nasimuddin of the Antenna and Optical Department at the Institute for Infocomm Research in Singapore. Supported by an international editorial board, the journal states that it will apply a rigorous and objective peer-review process. This is particularly important in a field where theoretical claims must often be tested through simulations, prototypes, channel measurements, or performance comparisons. Research involving modulation, coding, information theory, cognitive radio, software-defined networking, artificial intelligence, privacy, and communication protocols will be considered within the journal’s broad technological remit.

Alongside the communications title, Bentham Science has introduced Current Engineering Letters and Reviews, an interdisciplinary journal intended to connect research across the full spectrum of engineering sciences. Announced on 3 August 2026, the journal will publish research articles, short communications, comprehensive reviews, mini-reviews, and thematic issues. Its mission is to bring together discoveries that are often separated into specialist fields, reflecting the reality that many modern technologies emerge from collaboration among mechanical, electrical, materials, chemical, biomedical, environmental, and computer engineers.

The new engineering journal will cover aerospace, civil, structural, transportation, manufacturing, energy, robotics, automation, nanotechnology, artificial intelligence, and digital engineering. It will also address sustainable engineering, renewable energy systems, smart materials, advanced manufacturing, and biomedical technologies. These subjects are increasingly connected: an electric vehicle, for example, depends simultaneously on materials science, power electronics, software, communications, manufacturing, and transportation engineering. An interdisciplinary publication can provide a forum for examining such systems as integrated technological platforms rather than isolated components.

The scientific importance of this approach is becoming more visible as engineers confront challenges involving climate change, resource efficiency, resilient infrastructure, and automation. Renewable energy systems require improved storage, power conversion, and grid management; smart materials can respond to changes in temperature, pressure, or electromagnetic fields; and artificial intelligence can optimize industrial processes by identifying patterns in large streams of sensor data. At the same time, engineering research must demonstrate reliability, scalability, safety, and economic feasibility if laboratory innovations are to produce measurable benefits in society and industry.

Both journals invite contributions from researchers, engineers, scientists, academics, and industry professionals worldwide. Bentham Science says that information about open-access policies, article processing charges, waiver eligibility, editorial policies, and complaints and appeals procedures is available through the respective journal websites. With their emphasis on rapid communication, technical rigor, and interdisciplinary exchange, the two publications seek to become new hubs for research at the intersection of connectivity, intelligent systems, sustainable technology, and engineering innovation.

Subject of Research: Wireless communications, communication engineering, interdisciplinary engineering research, emerging technologies, artificial intelligence, sustainable engineering, and advanced technological systems.

Article Title: Bentham Science Launches Two New Journals to Accelerate Research in Wireless Communications and Engineering

News Publication Date: 3 August 2026 (for the announcement of Current Engineering Letters and Reviews; no publication date is provided for Wireless and Communication Letters).

Keywords

Wireless communications, 5G, 6G, Internet of Things, satellite communications, antenna design, signal processing, artificial intelligence, engineering research, sustainable engineering, robotics, renewable energy, smart materials, advanced manufacturing.

Microsoft vows to make Windows 11 fly on 8GB RAM amid memory shortage — optimizations to reduce OS memory footprint have begun

Microsoft said that it’s planning to optimize Windows 11 for systems with 8GB of RAM and above as part of its promise to improve Windows 11 in March 2026. The company said in its latest update that the optimization is part of expanding its focus on operating system upgrades, which include a faster out-of-the-box experience, easier parental controls, and improved voice interactions.

While the official minimum specifications for Windows 11 sit at just 4GB of RAM, most PC builders advise getting at least 16GB if you want to have a smooth experience. In fact, Microsoft has previously recommended 32GB of RAM for Windows 11 for gamers, especially if they want a system that can handle games in the near future. Unfortunately, the RAMpocalypse has forced both users and manufacturers to stick with slower DDR4 memory and lower capacities. Some experts predict that the entry-level PC will disappear by 2028, and we’ve even seen some manufacturers, including Apple, reintroduce 8GB laptops just to hit a specific price point.

The resurgence of 8GB systems will likely deliver a bad experience for users who stick with Windows 11, which is the likely reason why Microsoft is pushing for the optimization of its operating system. If Windows 11 performs poorly on these systems, it could draw users towards macOS or Linux alternatives as they blame the operating system for underperforming on limited hardware. In fact, we’ve already seen this happen before — after Microsoft ended support for Windows 10, MacBooks saw an uptick in sales as users migrated towards macOS instead of going for Windows 11. SteamOS is also encouraging some gamers to ditch Windows, and Valve is working on a general release for the OS, which many say contains less bloat and is a bit snappier than what Microsoft offers.

The RAM shortage crisis, alongside increasing competition, is forcing Microsoft to do better with Windows 11. Hopefully, these optimizations arrive sooner and don’t introduce new bugs, allowing both new and existing users to get more out of their systems.

The Windows blog post also gave an update on what improvements the company has made to Windows 11 so far. This includes a better Windows Search experience, more Taskbar and Start customizations, a more responsive and reliable File Explorer, among others. Many of these changes are still in preview, though, so unless you’re part of the Windows Insider Program, you’ll have to wait a few more weeks to months before you can start enjoying these changes.

Valve funding port of Linux RADV Radeon Vulkan driver to Windows — cross-platform effort already runs 'Counter-Strike 2'

The Steam Machine helped grow the popularity of Linux gaming, including installations of Bazzite and other gaming-oriented Linux distributions. Valve seemingly doesn't want to stop its open-source development efforts anytime soon, and is now working on a port of the Mesa Radeon Vulkan driver (RADV) to Windows; It's already running Counter-Strike 2, according to developers at Collabora.

As cross-platform development is rather tricky, Valve opted to get a port of RADV to Windows going by way of sponsoring contractors at Collabora. In its blog post, Collabora explained the several hoops it had to jump through to accomplish this task.

With Windows 10 and WDDM 2.0, Microsoft improved the split between graphics drivers' userspace code (the vast majority of the driver itself) and the kernel-level portion that actually talks to the graphics card. This presented the opportunity to hook RADV to the AMD kernel card driver. That's easier said than done, however, as communication between those parts often carries non-standardized data that RADV needs to understand. And to understand the "conversation," it needs to be recorded and analyzed.

An earlier 2024 effort by Faith Ekstrand yielded a basic-but-valuable utility for logging WDDM 2.0 calls and reverse-engineering them to produce a basic RADV implementation. Out of both debugging necessity and as a development tool, Collabora built and expanded upon Ekstrand's work, improving the logger to the point where it can now fully analyze any Vulkan application that runs with AMD's official driver and dump all the data passing to the kernel.

After a lot of work getting to grips with how the AMD driver interacts with the kernel driver, including but not limited to reverse-engineering obscure data structures, the team made progress, and Windows RADV is now able to run some games, including Counter-Strike 2.

Despite the ongoing effort, Collabora explains that since user- and kernel-space driver are a matched pair, changes to those aren't guaranteed to be backwards-compatible, meaning that even a fully functional RADV could break at any point. For that reason, Collobora is requesting that AMD, Microsoft, or both provide a documented interface to the kernel driver or an intermediary compatibility layer.

AMD graphics driver development on Linux has coalesced around the Mesa Vulkan stack, with both company and community devs contributing to the RADV project. Over in the Windows world, the only option is AMD's proprietary driver, which can cause a lot of headaches when developing cross-platform games and applications.

AMD's Vulkan driver for Windows has developed a reputation for instability. Meanwhile, Linux RADV is generally praised for its stability and performance, sometimes running faster than the AMD Windows driver, especially on older cards. With a rapid development schedule, it also generally sees fixes and speed upticks often.

If at some point using RADV on Windows becomes viable, you'd be getting an arguably more stable, mature driver with active development. Games' graphical issues could become far easier to debug and patch thanks to the open nature of RADV, and studios developing with Linux in mind can target the one platform instead of two with different behaviors. Any developer or company can contribute to the project, too.

Furthermore, this lets Valve improve Windows compatibility layers, and any optimizations can be carried over to both operating systems. All told, this is likely one of the several moving parts to improve Linux — thus the Steam Deck, Steam Machine, and upcoming hardware — as a viable gaming platform. Even a future notion of gamers installing RADV on Windows to get a performance or stability boost isn't too far-fetched.

Additionally, RADV on Windows would also help keep discontinued cards usable, and given pricing right now, that certainly would be a good thing.

Windows NT 4.0 brought the Win95 UI to servers 30 years ago today — milestone unifying modern Windows OS hit RTM in the Pentium era

31 July 2026 at 10:00

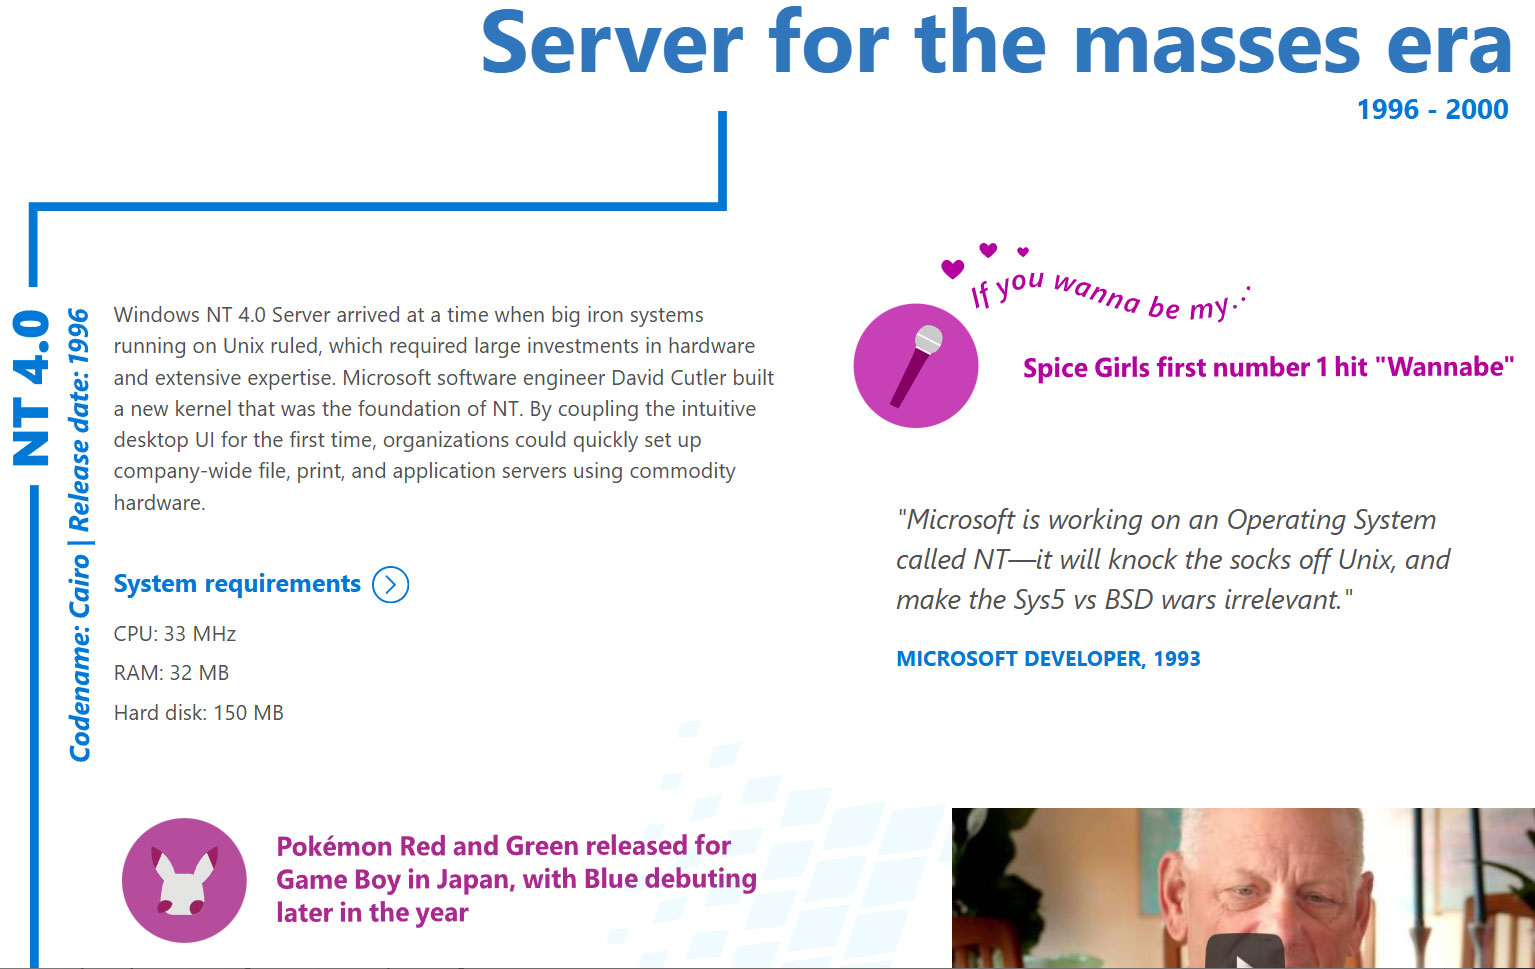
Microsoft released Windows NT 4.0 to manufacturing partners on July 31, 1996. Codename Cairo marked an important milestone in the history of Microsoft’s original server OS and would far outlive Microsoft’s original plans as enthusiasts and administrators clung to it, as older readers will be aware. Headlining features of NT 4.0, which made it a winner, include the melding of the intuitive new Windows 95 UI into the fully 32-bit enterprise OS. It was also notable for being the last version of NT to support Alpha, MIPS, or PowerPC CPU architectures.

Historical Windows NT timeline:

  • Windows NT Server 3.1 – in 1993, the first version of Windows NT also introduced NTFS
  • Windows NT Server 3.5 – in 1994, this update provided integrated support for Winsock and TCP/IP
  • Windows NT Server 3.51 - client/server support added in 1995
  • Windows NT 4.0 – in 1996, NT got the Windows 95 UI and the familiar My Computer, My Documents, and so on
  • Windows 2000 Server – the 5th NT release started a new naming scheme, introduced Active Directory, plus NTFS 3.0 with file system encryption
  • Followed by the more modern Server releases…

Windows NT 4.0

(Image credit: Microsoft)

After the initial Windows NT 4.0 release, Microsoft followed up with a version for embedded systems and its Terminal Server edition.

The Windows NT line was critical to Microsoft as it led the charge against dominant Unix server software ecosystems. Its first public release was in 1993, with version 3.1, but NT 4.0 coupled the underlying data server and personal workstation tooling with Win95 UI elements such as the Start Menu, Taskbar, Task Manager, and so on. It would also support new components like the cryptography API, DCOM, TAPI 2.0, and some DirectX (v2) features.

Despite all the new technology under the hood and the frills of the latest UI, Microsoft’s Windows NT 4.0 launched with remarkably low minimum requirements. Would-be users were recommended to install it on a PC with a CPU that ran at 33 MHz or better, had 32MB of RAM, SVGA graphics, and a hard disk with 256 MB capacity. This was in the Pentium / Pentium Pro era. NT 4.0 would become “the server for the masses,” boasted Microsoft on the OS’s 20th anniversary.

Another reason that NT 4.0 was so important is that it formed the foundation for the Windows XP release (2001), leaving the DOS-based 95, 98/SE, and Me versions of the consumer OS behind as archaic hybrids. In the half-decade between the release of NT 4.0 and XP, Microsoft had a lot of work to do, such as implementing Plug and Play, building out gaming tech, adding WDM drivers, and so on. Thankfully, PCs also grew in muscle, specs, and multimedia capabilities to make the larger and more demanding XP a big hit.

Windows XP landed with a core marketing line that it was “Built on NT technology,” which felt uncomfortable to read if you were from the camp that believed ‘NT’ was short for ‘New Technology.’

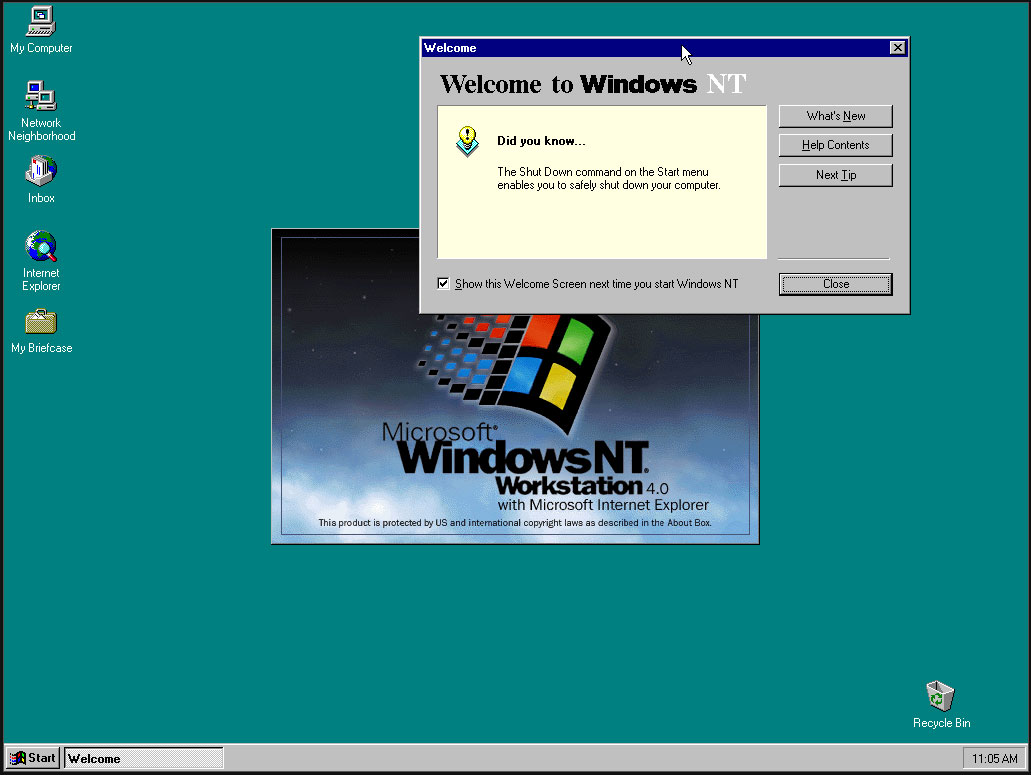
Windows NT 4.0 screenshots

(Image credit: Tom's Hardware)

It is pretty easy to find an old Cairo release online for retro machine tinkering. Those interested in a more casual poke around in NT 4.0 out of interest, curiosity, or nostalgia will find there are some online installs you can play with via a web browser.

What colors were prehistoric mammals?

30 July 2026 at 12:00

The spots on a leopard, the stripes on a zebra, and the mask on a raccoon are all types of coloration in mammal fur, referred to as pelage. Scientists have struggled for a long time to understand how these colorations evolved. A team of researchers recently discovered how to reconstruct the colors of ancient mammal fur using cell structures that contain the chemical pigment melanin, known as melanosomes. They hope to use this understanding of ancient mammal pelage to determine how they lived and what their environments were like.

To decipher the color of ancient mammal fur, the researchers constructed a statistical computer model to predict their fur colors based on the shape of their melanosomes. First, they needed to understand how the shapes of melanosomes control fur color in modern mammals. To measure the length and width of the modern melanosomes, the scientists used a beam of electrons like a flashlight to map them in great detail, a technique called scanning electron microscopy.

They measured the length and width of 2,615 melanosomes from the fur of 116 different living mammal species, including a Red Panda, a German Shepard, and one or more species of most types in the mammalian classification. Then they recorded the wavelengths of light reflected off each melanosome using a microspectrophotometer. These wavelengths represented the exact color of hair from each melanosome they measured. This means they now had a quantitative measurement of the color of each hair to compare with its corresponding melanosome length and width.

When they examined their data, the researchers found that spherical melanosomes produced brighter fur colors, like reds and oranges, while elongated melanosomes produced darker fur colors, like browns and grays. The researchers plotted the microspectrophotometric measurements for each melanosome as a graph showing how much light it absorbed across each possible wavelength, creating reflectance curves. Based on these data, the researchers used computer software to create a statistical model that could predict reflectance curves, and therefore color, from melanosome shape alone.

Once the researchers created a model, they needed to find fossilized mammal melanosomes to predict their fur color. Mammal fossils are rare, and pieces of cells are only preserved in the most immaculate fossil deposits. In fact, these researchers only found 6 fossils of this caliber, from Mesozoic rocks deposited around 250 million years ago, soon after mammals evolved. 

The fossils came from 2 world-renowned deposits in Northeastern China, the Yanliao and Jehol biotas. They selected 5 previously studied fossils from these locations, including 1 specimen of Megaconus mammaliaformis, 1 specimen of Vilevolodon diplomylos, 2 specimens from the group Docodonta, and 1 specimen from the group Eutheria. All of these animals were small, rodent-like mammals. The researchers also discovered a new species of tree-dwelling mammal, Arboroharamiya fuscus.

The scientists used scanning electron microscopy to measure a total of 2,159 fossilized melanosomes to refine their color predictions. The fossilized melanosomes were all slightly elongated spheres and had far fewer differences in shape than in modern mammals. The researchers used their model to predict reflectance curves based on the shapes of the fossil melanosomes to determine the ancient mammals’ colors. They found that all the extinct mammals they examined likely had dark brown fur without any color patterns.

Based on these findings, the researchers suggested that most, if not all, early mammals were nocturnal, like many dark-colored mammals today. They suggested that this nocturnal lifestyle probably helped them survive the meteorite impact that wiped out the dinosaurs 100 million years later. While dinosaurs were unable to survive in the post-impact wasteland, these smaller, dark-colored mammals were more resilient and thrived in the aftermath. As mammals filled the ecological roles left by the dinosaurs, they evolved new color patterns, some based solely on camouflage, and others on new factors, like sexual selection and visual communication.

The researchers concluded that their model can predict fossilized mammal colors and help determine how these ancient animals lived. Notably, their data suggest that mammals likely stayed small and nocturnal throughout the Mesozoic until the dinosaurs were gone. Future researchers could use similar methods to uncover exactly how mammals evolved the colors we see today. For example, studying mammals closer to the impact event could reveal if it took a long time to develop diverse fur patterns, or if they began before the dinosaurs’ demise. Ultimately, similar studies could help determine whether the extinction of dinosaurs was necessary for the rise of mammals.

The post What colors were prehistoric mammals? appeared first on Sciworthy.

Apple preps for a wearable AI revolution

29 July 2026 at 18:29

This fall, with watchOS 27, Apple Watch will finally get access to Siri AI with a software update that turns your wrist into the most widely-used wearable AI platform on Earth.

That’s not hyperbole. Siri AI on Apple Watch is arguably the most important feature to this year’s watchOS update. Though it didn’t get much attention at WWDC, the update also offers a preview into how Apple will wrap AI into its future smart glasses.

What to expect

One important caveat is to observe that Siri AI on Apple Watch still requires your Apple Intelligence-enabled iPhone to do the heavy lifting. The interaction is easy: tap the Digital Crown and Apple’s new glowing icon appears on screen (you’ll also find this in the App viewer). The experience looks identical across every Apple device — iPhone, iPad, Mac, Apple Watch, and Vision Pro — making the assistant feel like one consistent product rather than a different experience per device.

The Siri app lets you access all your past Siri conversations (unless you turn that feature off) and pick up an old conversation right where you left off. Conversation history syncs privately through iCloud, so you can start an exchange on your iPhone and continue it later from your wrist. You can also pin a conversation you expect to revisit.

You can also use Siri on the Apple Watch to ask questions, launch apps, or even get more complex responses, such as step counts on a specific day. It can also answer difficult and specific queries with detailed answers and can summon real-time information from the web.

Personal context is the real story

That’s key, of course, as it means the smartwatch on your wrist can help you access specific details from all your contextual information; it can get details from messages, emails, and notes, for instance. Or you might use it to find a number and call it, access your door code, or look up customer information for business — all without touching your phone.

One of Apple’s own examples demonstrates this well: Saying, “Show me photos from when I went to Spain,” results in precisely that. You can also ask follow-up questions and keep the conversational going naturally, rather than being confined to single, isolated commands.

Beyond personal data, the watch can also act in apps — get directions home, send an email, play a playlist, or even more specifically, “Play the song that Brandon sent me.”

Context runs deep. A new Call Context tool can proactively surface relevant information from across your apps when phoning a business or help locate a confirmation code from Mail while calling an airline. This arguably challenges a real pain point when speaking with providers and is a good illustration of Apple’s broader AI strategy: to use on-device intelligence to remove everyday friction without asking you to track down the information yourself.

Where we are, where it’s going

It’s frustrating that you still can’t use the Watch to remotely run applications on your Mac, iPhone, or iPad. What you can do is trigger Shortcuts that run on your iPhone: enable this first on your phone by selecting the Shortcut you want and switching on “Show on Apple Watch.” Once that’s done, you can run the Shortcut from your wrist, even by voice.

That’s useful now, but as more complex apps add Shortcuts support and App Intents become more widely adopted by developers, it should be easy to trigger genuinely complex, multi-stage tasks on your iPhone from your wrist.

It’s worth noting: early hands-on testing of the watchOS 27 beta has found Siri AI genuinely impressive on personal-context queries, but still buggy in places. This is very much a first-generation feature — promising, but not yet fully reliable.

Watch the developers

Developers are already beginning to experiment with the potential for wearable AI. One of the best current examples is Granola, which just launched a Watch app built specifically to take notes during in-person meetings away from a laptop. The idea is that you tap your wrist, the screen turns green and makes a sound to alert your companion(s) that it is recording and then you carry on as normal. Once the meeting stops, switch the app off and you’ll get polished notes with meeting summaries and action items provided to you.

The only reservation I have with Granola is the lack of documentation on privacy and data retention on the developer site. Tools like these will almost certainly become more private, more secure, and more prevalent once Apple’s on-device dictation APIs extend fully to watchOS.

That last thing is perhaps the most important as wearable AI emerges: the decisions Apple makes around watchOS and SiriAI will be foundational to its future wearable AI glasses products.

You can follow me on social media! Join me on BlueSky,  LinkedIn, Mastodon and subscribe to The Core.

Predicting microbial antibiotic resistance with AI

27 July 2026 at 12:00

Have you ever wondered how researchers use artificial intelligence (AI) in environmental science? Certain AI computer models can learn from scientific data and operate without manual programming, in a process called machine learning. Machine learning models can identify patterns in environmental datasets and help scientists assess public health risks linked to environmental conditions.

One well-known public health risk is the rise in antibiotic-resistant bacteria. These bacteria carry genes called antibiotic resistance genes that protect them from antibiotic medicines. As the number of these genes increases, the medicines become less effective, and diseases spread faster.

Agricultural soils are the largest reservoirs of antibiotic resistance genes, because manure from livestock like cows and pigs often contains leftover antibiotics fed to them. When used as fertilizer, this manure transfers antibiotics into the agricultural soil, where bacteria develop antibiotic resistance genes.

To better understand how antibiotic-resistant bacteria will affect global health in the future, scientists want to develop faster ways to detect antibiotic resistance genes. However, current methods of detection are slow and fail to predict future trends. To address this problem, a group of scientists from Algeria used machine learning models to predict the prevalence of antibiotic resistance genes in soil microbes under future climate scenarios, and to identify the key environmental drivers and high-risk areas.

​The team compiled existing microbial data from 3 public databases: the National Center for Biotechnology Information’s Sequence Read Archive, the Metagenomic Rapid Annotations using Subsystems Technology database, and the Joint Genome Institute’s Integrated Microbial Genomes & Microbiomes database. Their final dataset contained about 2,000 agricultural soil samples from 67 countries across 6 continents. These samples represented a wide range of soil characteristics, climate conditions, and different types of antibiotic resistance genes. 

They integrated the microbial dataset with climate data, including global temperature and precipitation measurements from WorldClim, and land use data, including crop types, irrigation systems, and livestock density from the European Space Agency Climate Change Initiative Land Cover maps. The researchers also included data on future climate projections for 2050 and 2070 from the World Climate Research Programme based on low, medium, and high global greenhouse gas emission scenarios. 

After preparing the datasets, the team set up 6 machine learning models that differ in terms of their data size, model complexity, analytical speed, and customization. These models included Light Gradient Boosting Machine (LightGBM), eXtreme Gradient Boosting (XGBoost), Random Forest (RF), Support Vector Machine (SVM), Deep Neural Network (DNN), and Logistic Regression (LR). 

They ran each model using different combinations of variables from their datasets, including soil properties, microbial community metrics, climate variables, and land use characteristics. To validate the models, the team separated the full dataset into 10 random subsets. They trained the models on 9 of the subsets, then recorded the result of the 10th subset. Each model repeated this process 10 times in a different order so that each subset was evaluated once in the results, using a technique known as stratified 10-fold cross-validation. The researchers scored each model on 5 performance metrics, including precision, sensitivity, and predictive power. Based on these results, they determined that LightGBM was the most accurate model. 

They found that the LightGBM model identified soil temperature as the strongest environmental predictor of antibiotic resistance genes. At soil temperatures above 18°C (about 64°F), the number of antibiotic resistance genes increased dramatically. The model also identified soil acidity, organic carbon content, moisture, and annual precipitation as influential variables, accounting for 71% of the increase in antibiotic resistance genes under future climate scenarios. Likewise, the LightGBM model predicted that the number of high-risk areas would increase by 35% under the high-emissions scenario, with South Asia, Sub-Saharan Africa, and Mediterranean Europe as the most vulnerable regions.

Based on the LightGBM model output, the team concluded that soil conditions will change to favor antibiotic resistance genes under all future climate scenarios. They also suggested that LightGBM is a fast and effective model for environmental predictions that could be used to assess other climate change risks such as natural disasters. They recommended that future researchers explore how to apply machine learning methods to early warning systems and utilize machine learning results in environmental management decisions. 

The post Predicting microbial antibiotic resistance with AI appeared first on Sciworthy.

Widespread Tropical Cyclones During the Late Paleozoic Ice Age

29 July 2026 at 14:26

A newly published study reports that tropical cyclones were far more common during the Late Paleozoic Ice Age than many climate reconstructions have suggested. Led by Yan, Macarewich, Jiang, and colleagues, the work appears in Nature Communications (2026) and reframes how Earth’s cold interval coexisted with warm-water storm systems.

The researchers investigated geological signatures linked to extreme marine events, combining stratigraphic evidence with climate-model constraints. Their goal was to distinguish ordinary seasonal variability from the kind of widespread, repeated disturbances that characterize tropical cyclone belts.

A key technical advance in the study is the integration of paleoclimate boundary conditions with storm-resolving dynamical reasoning. Instead of treating cyclone activity as a simple function of temperature alone, the team considered large-scale patterns that govern where warm oceans can persist long enough to power rotating storms.

The results point to an expanded region of conditions favorable for cyclogenesis. Even though the planet was globally in an ice-age mode, ocean–atmosphere coupling—driven by uneven heat storage, changing circulation, and shifting storm tracks—likely enabled tropical systems to form across parts of the tropics more frequently than expected.

The authors describe “widespread” activity, implying that cyclone impacts were not limited to rare episodes. This interpretation aligns with the idea that cooling did not fully suppress tropical cyclone energetics; rather, it altered the geography and intensity distribution of storm-prone environments.

Using the preserved sedimentary record, the study connects storm activity to repeated depositional pulses. Those pulses, they argue, reflect basin-scale disturbance rather than local weather anomalies, strengthening the case for frequent tropical cyclone events during this interval.

From a broader perspective, the findings have implications for how we understand resilience and feedbacks in past climates. If cyclones continued to thrive under ice-age background states, then tropical extremes may persist through major global reorganizations.

The study’s viral potential is clear: it challenges an intuitive narrative that “ice ages mean calm tropics,” and replaces it with a more nuanced picture in which warm-water dynamics and circulation shifts can sustain storminess despite global cooling.

Below are the details available from the provided text:

Subject of Research: Tropical cyclone activity during the Late Paleozoic Ice Age.

Article Title: Widespread tropical cyclone activity during the Late Paleozoic Ice Age.

Article References: Yan, Q., Macarewich, S., Jiang, N. et al. Widespread tropical cyclone activity during the Late Paleozoic Ice Age. Nat Commun (2026). https://doi.org/10.1038/s41467-026-75609-1

Image Credits: AI Generated

DOI: 10.1038/s41467-026-75609-1

❌